# Redd-Archiver
[](http://unlicense.org/)
[](https://www.python.org/downloads/)
[](https://www.postgresql.org/)
[]()
[]()
[]()
[](https://codeberg.org/19-84/redd-archiver)
[](https://gitgud.io/1984/redd-archiver)
> **⭐ If you find this project useful, please star the repo!** It helps others discover the tool and motivates continued development.
Transform compressed data dumps into browsable HTML archives with flexible deployment options. Redd-Archiver supports offline browsing via sorted index pages, full-text search with Docker deployment, or fully dynamic serving straight from PostgreSQL. Archives stay current with monthly incremental updates from Arctic Shift dumps. Features mobile-first design, multi-platform support, operator-selectable themes, and PostgreSQL full-text indexing.
**Supported Platforms**:
| Platform | Format | Status | Available Posts | Data |
|----------|--------|--------|----------------|------|
| **Reddit** | .zst JSON Lines (Pushshift/Arctic Shift) | ✅ Full support | 2.38B+ posts (40,029 subreddits; rolling — [monthly dumps](https://github.com/ArthurHeitmann/arctic_shift/blob/master/download_links.md) keep archives current) | [Download](https://academictorrents.com/details/3e3f64dee22dc304cdd2546254ca1f8e8ae542b4) |
| **Voat** | SQL dumps | ✅ Full support | 3.81M posts, 24.1M comments (22,637 subverses, complete archive) | [Download](https://archive.org/details/voat-archive-2021) |
| **Ruqqus** | .7z JSON Lines | ✅ Full support | 500K posts (6,217 guilds, complete archive) | [Download](https://archive.org/details/ruqqus-archive-2021) |
*Tracked content: **2.38B+ posts across 68,883 communities** (full Reddit dataset plus monthly Arctic Shift dumps via [incremental updates](docs/INCREMENTAL_UPDATES.md); Voat/Ruqqus complete archives)*
**Version 1.1 “Living Archive”** adds three serving modes, monthly incremental updates, 11 theme palettes, community metadata/wiki enrichment, and a major performance pass on top of 1.0's multi-platform archiving, REST API, and MCP server. See [CHANGELOG.md](CHANGELOG.md).
## 🧭 Serving Modes
One archive, three ways to serve it — the database is the canonical store, switch modes anytime:
| | **Static** | **Hybrid** (default) | **Dynamic** |
|---|---|---|---|
| Runtime requirements | Any web host | nginx + Flask + PostgreSQL | Flask + PostgreSQL |
| Full-text search / REST API | — | ✅ | ✅ |
| Dynamic filtering (`?flair=&min_score=&from=`) & `/all/` view | — | — | ✅ |
| Content live immediately after import | export step | export step | ✅ instantly |
| GitHub Pages / USB-stick / offline | ✅ | pages only | — |
```bash
# Static: export once, host anywhere
reddarc.py /data --subreddit privacy ... --output /var/www/html/
# Hybrid (current default): static pages + search server
docker compose up -d
# Dynamic: no export step, Flask renders pages from PostgreSQL
reddarc.py --import-only /data --subreddit privacy ...
REDDARCHIVER_SERVE_MODE=dynamic python search_server.py
```
## 🔄 Keep Archives Current (Incremental Updates)
Apply monthly [Arctic Shift](https://github.com/ArthurHeitmann/arctic_shift) dumps to an existing archive — only tracked subreddits are imported, re-runs are skipped by checksum, and scores refresh without altering preserved content:
```bash
# One month
reddarc.py --update RS_2026-01.zst --comments-file RC_2026-01.zst
# Or point at a downloaded monthly torrent (comments/ + submissions/ layout
# is auto-discovered) and apply every unprocessed month in order:
reddarc.py --update-all /data/monthly/reddit/
reddarc.py --update-status # audit what has been applied
```
## 🚀 Quick Start
**Archive internet history before it disappears** - Deploy in 2 minutes, no domain required.
**Try the live demo:** [Browse Example Archive →](https://online-archives.github.io/redd-archiver-example/)
**→ [QUICKSTART.md](QUICKSTART.md)** - Step-by-step deployment:
- **2 min**: Tor hidden service (no domain, no port forwarding, works behind CGNAT)
- **5 min**: Local testing (HTTP on localhost)
- **15 min**: Production HTTPS (automated Let's Encrypt)
**Why now?** Communities get banned, platforms shut down, discussions vanish. Start preserving today.
---
## Documentation
**→ First time here?** [QUICKSTART.md](QUICKSTART.md) - Deploy in 2-15 minutes
**→ Quick answers?** [FAQ](docs/FAQ.md) - Common questions answered in 30 seconds
**→ Need help?** [Troubleshooting](docs/TROUBLESHOOTING.md) - Fix common issues
**→ Using the API?** [API Reference](docs/API.md) - 30+ REST endpoints
**→ How it works?** [Architecture](ARCHITECTURE.md) - Technical deep-dive
**→ Deployment guides:**
- [Tor Hidden Service](docs/TOR_DEPLOYMENT.md) - .onion setup (2 min, no domain needed)
- [HTTPS Production](QUICKSTART.md#production-https-15-minutes) - Let's Encrypt SSL (15 min)
- [Static Hosting](docs/STATIC_DEPLOYMENT.md) - GitHub/Codeberg Pages (browse-only)
- [Docker Reference](docker/README.md) - Complete Docker guide
**→ Operations:**
- [Incremental Updates](docs/INCREMENTAL_UPDATES.md) - Keep archives current with monthly dumps
- [Performance](docs/PERFORMANCE.md) - Memory, storage, and tuning
- [Scaling](docs/SCALING.md) - Multi-instance deployments
- [Search Setup](docs/SEARCH.md) - Full-text search configuration
**→ Advanced:**
- [MCP Server](mcp_server/README.md) - AI integration (Claude Desktop/Code)
- [Scanner Tools](docs/SCANNER_TOOLS.md) - Data discovery utilities
- [Registry Setup](docs/REGISTRY_SETUP.md) - Instance leaderboard
- [Installation Guide](docs/INSTALLATION.md) - Platform-specific setup
- [Contributing](CONTRIBUTING.md) · [Security Policy](SECURITY.md) · [License](LICENSE)
---
## 🎯 Key Features
### 🌐 Multi-Platform Support
Archive content from multiple link aggregator platforms in a single unified archive:
| Platform | Format | CLI Flag | URL Prefix |
|----------|--------|----------|------------|
| **Reddit** | .zst JSON Lines | `--subreddit` | `/r/` |
| **Voat** | SQL dumps | `--subverse` | `/v/` |
| **Ruqqus** | .7z JSON Lines | `--guild` | `/g/` |
- **Automatic Detection**: Platform auto-detected from file extensions
- **Unified Search**: PostgreSQL FTS searches across all platforms
- **Mixed Archives**: Combine Reddit, Voat, and Ruqqus in single archive
### 🤖 MCP Server (AI Integration)
29 MCP tools auto-generated from OpenAPI for AI assistants:
- **Full Archive Access**: Query posts, comments, users, search via Claude Desktop or Claude Code
- **Token Overflow Prevention**: Built-in LLM guidance with field selection and truncation
- **5 MCP Resources**: Instant access to stats, top posts, subreddits, search help
- **Claude Code Ready**: Copy-paste configuration for immediate use
```json
{
"mcpServers": {
"reddarchiver": {
"command": "uv",
"args": ["--directory", "/path/to/mcp_server", "run", "python", "server.py"],
"env": { "REDDARCHIVER_API_URL": "http://localhost:5000" }
}
}
}
```
See [MCP Server Documentation](mcp_server/README.md) for complete setup guide.
### 📖 For Readers (offline, mobile, Tor)
- **📱 Mobile-First Design**: Responsive layout optimized for all devices with touch-friendly navigation
- **⚡ JavaScript Free**: Complete functionality without JS, pure CSS interactions — Tor-optimized, no external dependencies
- **📇 Offline Browsing Aids**: Per-letter title indexes (Ctrl+F-friendly), flair indexes, and an archive map page — search-like navigation with zero server
- **🔍 Full-Text Search (server deployments)**: PostgreSQL FTS with Google-style operators — keywords, subreddit, author, date, score
- **📰 Community Context**: Subreddit descriptions, rules, and wikis; Voat subverse metadata, user profiles, and flair
- **♿ Accessibility**: WCAG compliant — Lighthouse 100 accessibility score across page types
- **🚄 Performance**: ~13KB gzipped CSS, 3–32KB gzipped pages, Lighthouse 94–100, designed for low-bandwidth networks
### 🛠️ For Operators
- **🧭 Three Serving Modes**: static (host anywhere), hybrid (static + search server), dynamic (everything served live from PostgreSQL) — switch anytime, same database
- **🔄 Incremental Updates**: monthly dumps apply idempotently; archives stay current without rebuilds
- **🎨 Themes**: 11 palettes (default, sepia, nord, solarized, dracula, gruvbox, cyberpunk, midnight OLED, old-reddit, phosphor, high-contrast) via `--theme` / `REDDARCHIVER_THEME`, plus `--accent-color` and `--custom-css`; CSS-only dark/light mode follows system preference with a manual toggle
- **🗄️ PostgreSQL Backend**: streaming imports with constant memory; COPY protocol; resume from checkpoints
- **🚀 Deployment Options**: localhost/LAN (2 commands), HTTPS with automated Let's Encrypt (15 min), Tor hidden service (2 min, works behind CGNAT), HTTPS+Tor dual-mode, or GitHub/Codeberg Pages (static)
- **🔗 SEO Ready**: meta tags, XML sitemaps, structured data; `--precompress` + `gzip_static` for high-traffic static serving
- **🏆 Instance Registry**: leaderboard with completeness-weighted scoring for distributed archiving
### 🔬 For Researchers & AI
- **🌐 REST API v1**: 30+ endpoints — posts, comments, users, statistics, search, aggregations, batch and export (CSV/NDJSON) — with field selection and truncation controls
- **🤖 MCP Server**: 29 tools for Claude Desktop/Claude Code (see above)
- **📊 Rich Statistics**: analytics dashboard, per-community metrics, user activity summaries
---
## 📸 Screenshots
### Dashboard
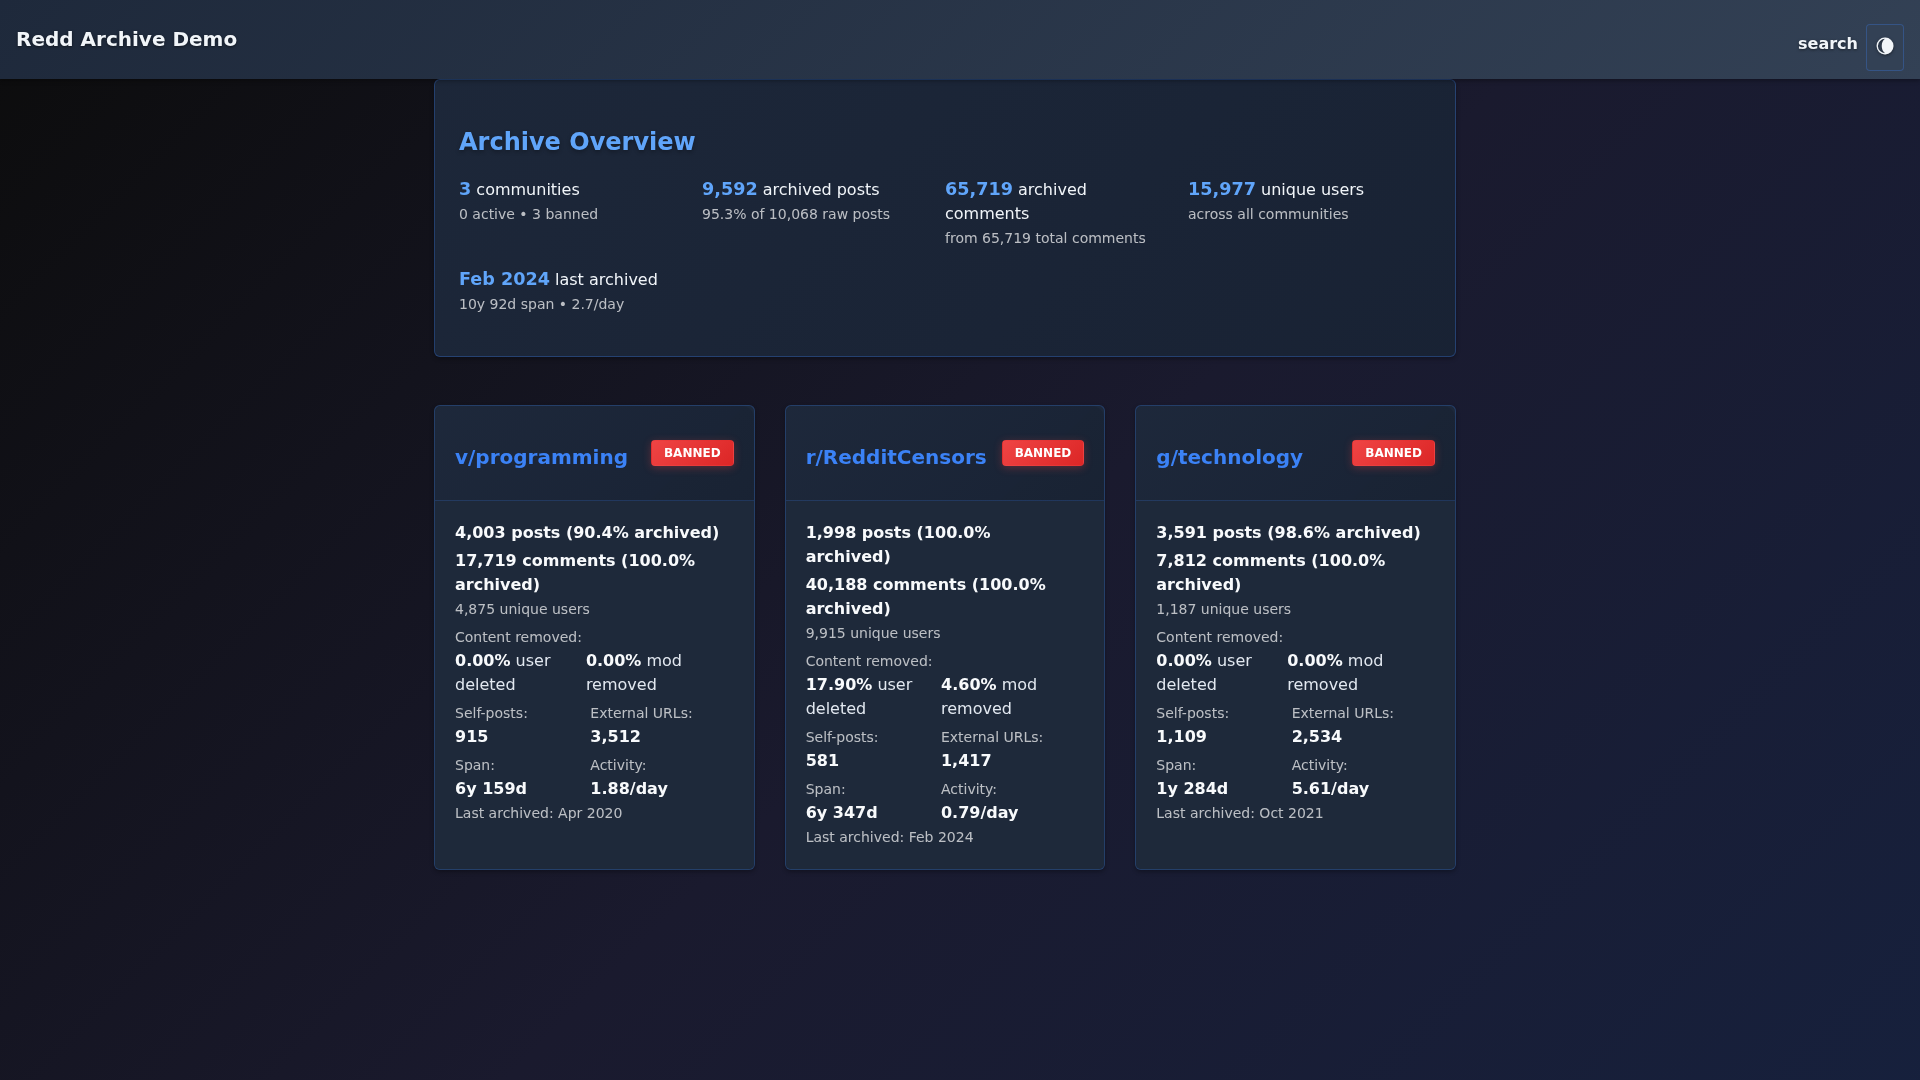
Main landing page showing archive overview with statistics for 9,592 posts across Reddit, Voat, and Ruqqus. Features customizable branding (site name, project URL), responsive cards, activity metrics, and content statistics. *(Works offline)*
### Subreddit Index
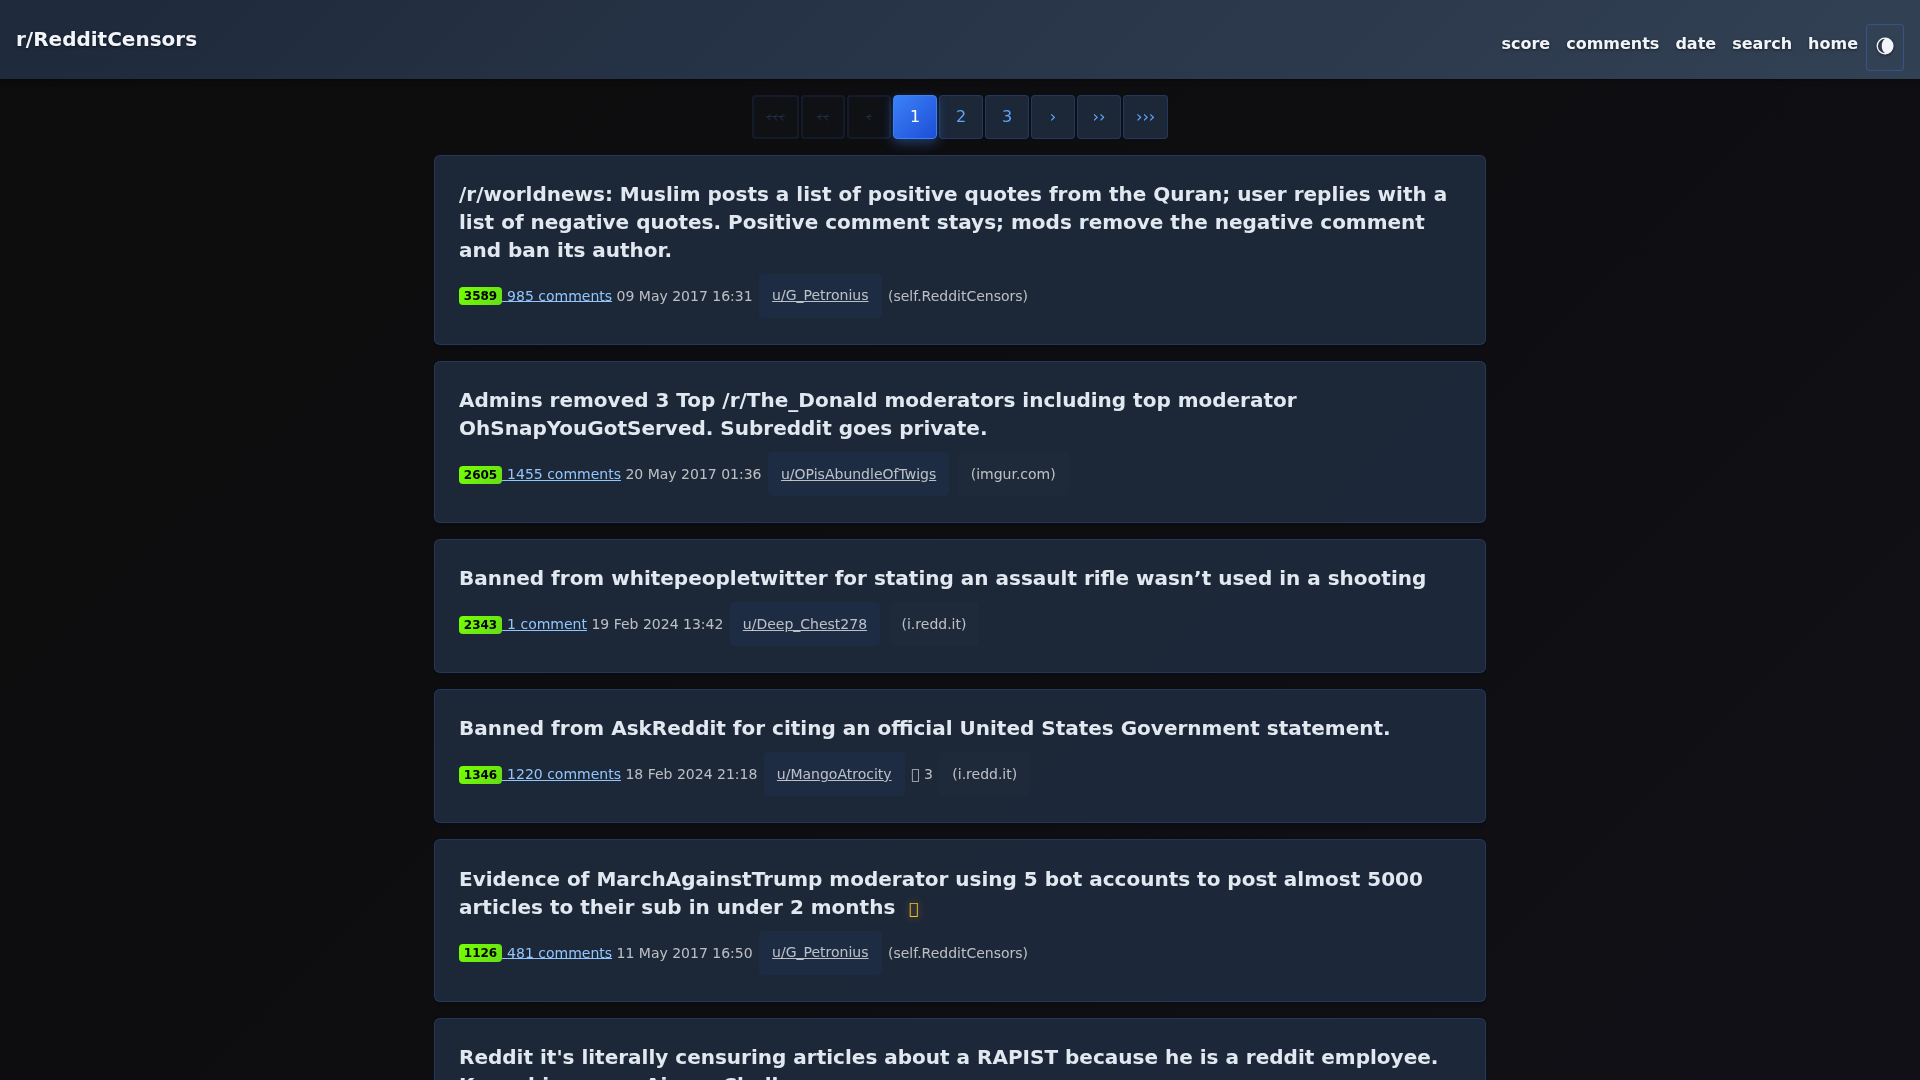
Post listing with sorting options (score, comments, date), pagination, and badge coloring. Includes navigation and theme toggle. *(Works offline - sorted by score/comments/date)*
### Post Page with Comments
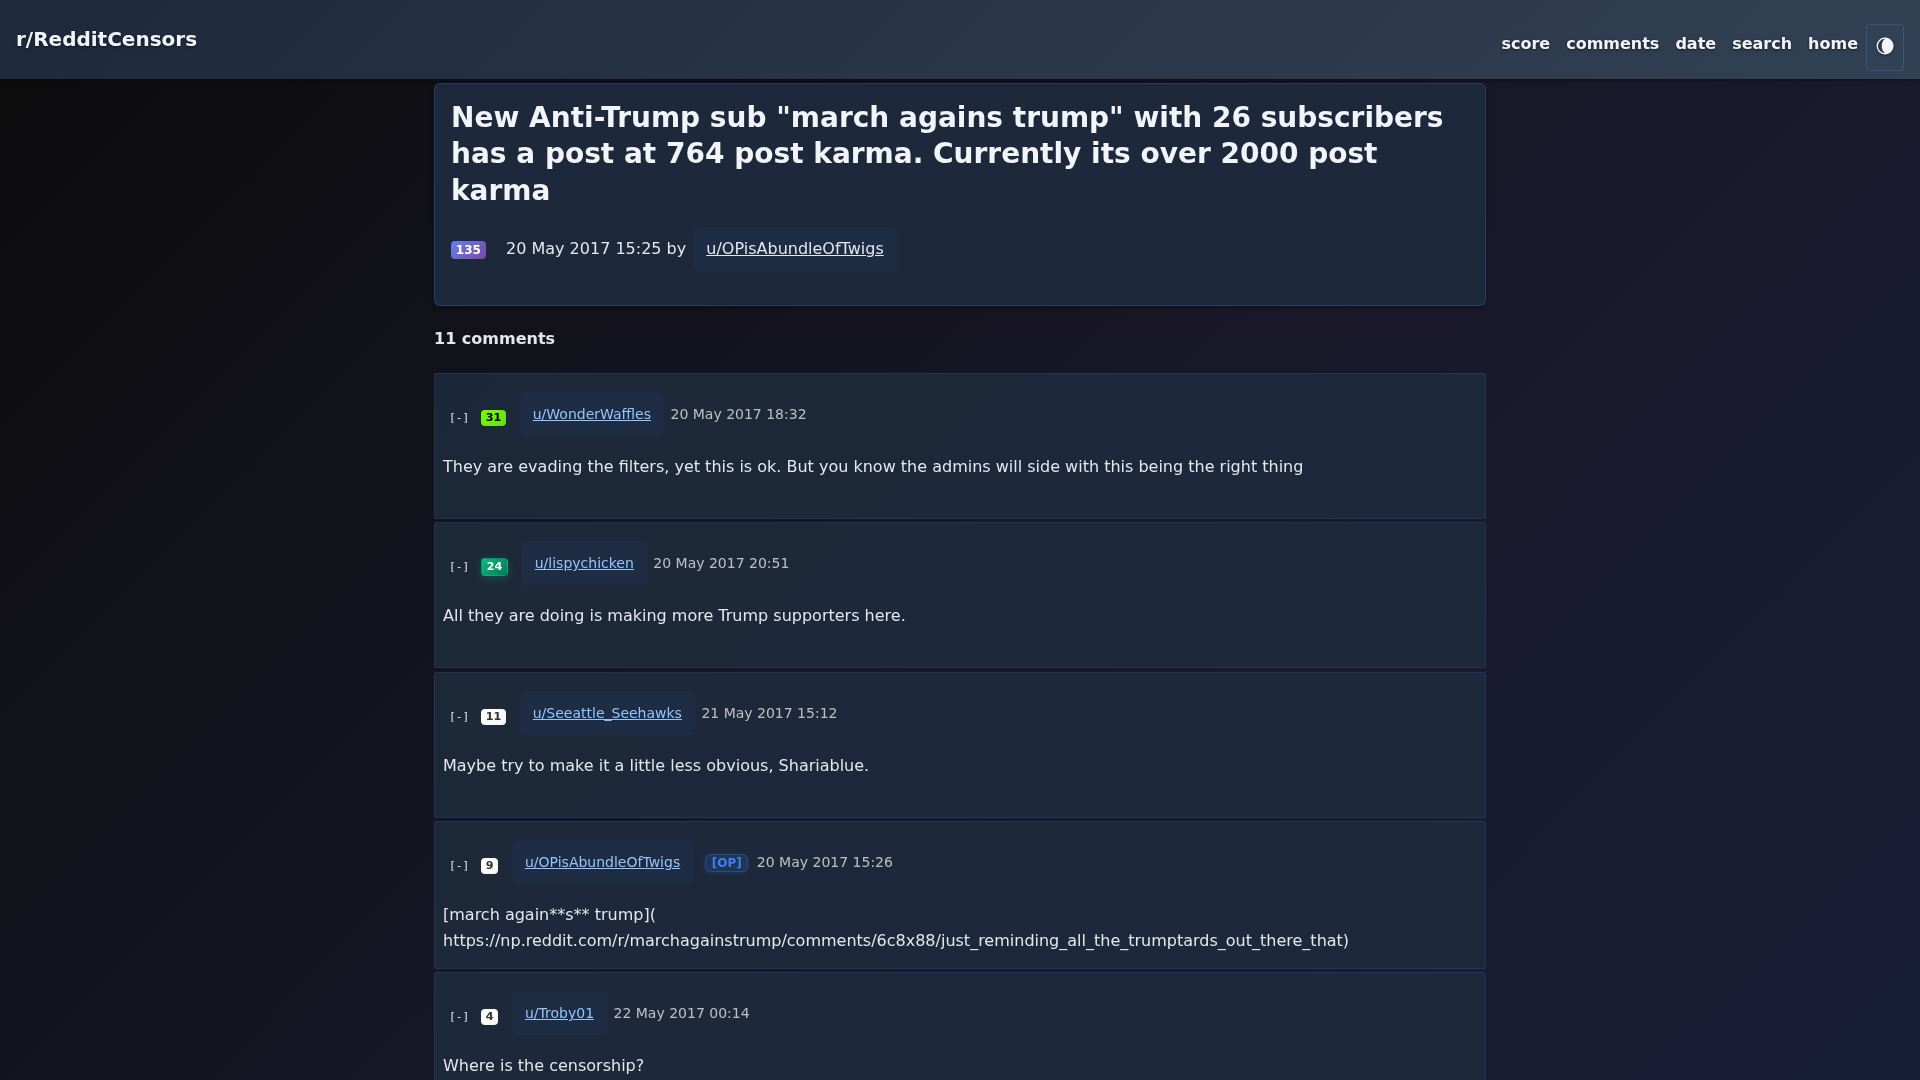
Individual post displaying nested comment threads with collapsible UI, user flair, and timestamps. Comments include anchor links for direct navigation from user pages. *(Works offline)*
### Mobile Responsive Design
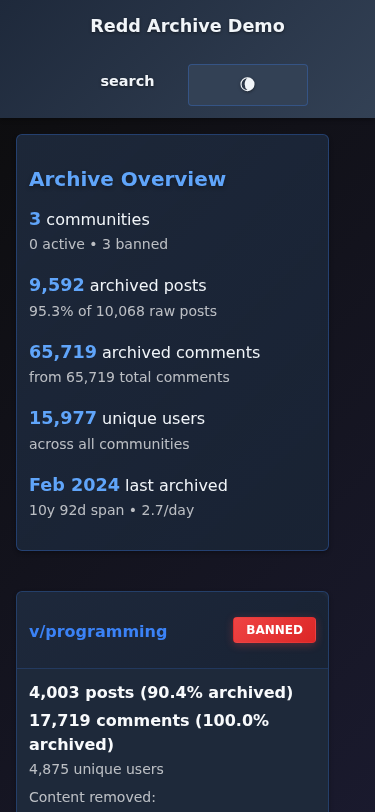
Fully optimized for mobile devices with touch-friendly navigation and responsive layout.
### Search Interface
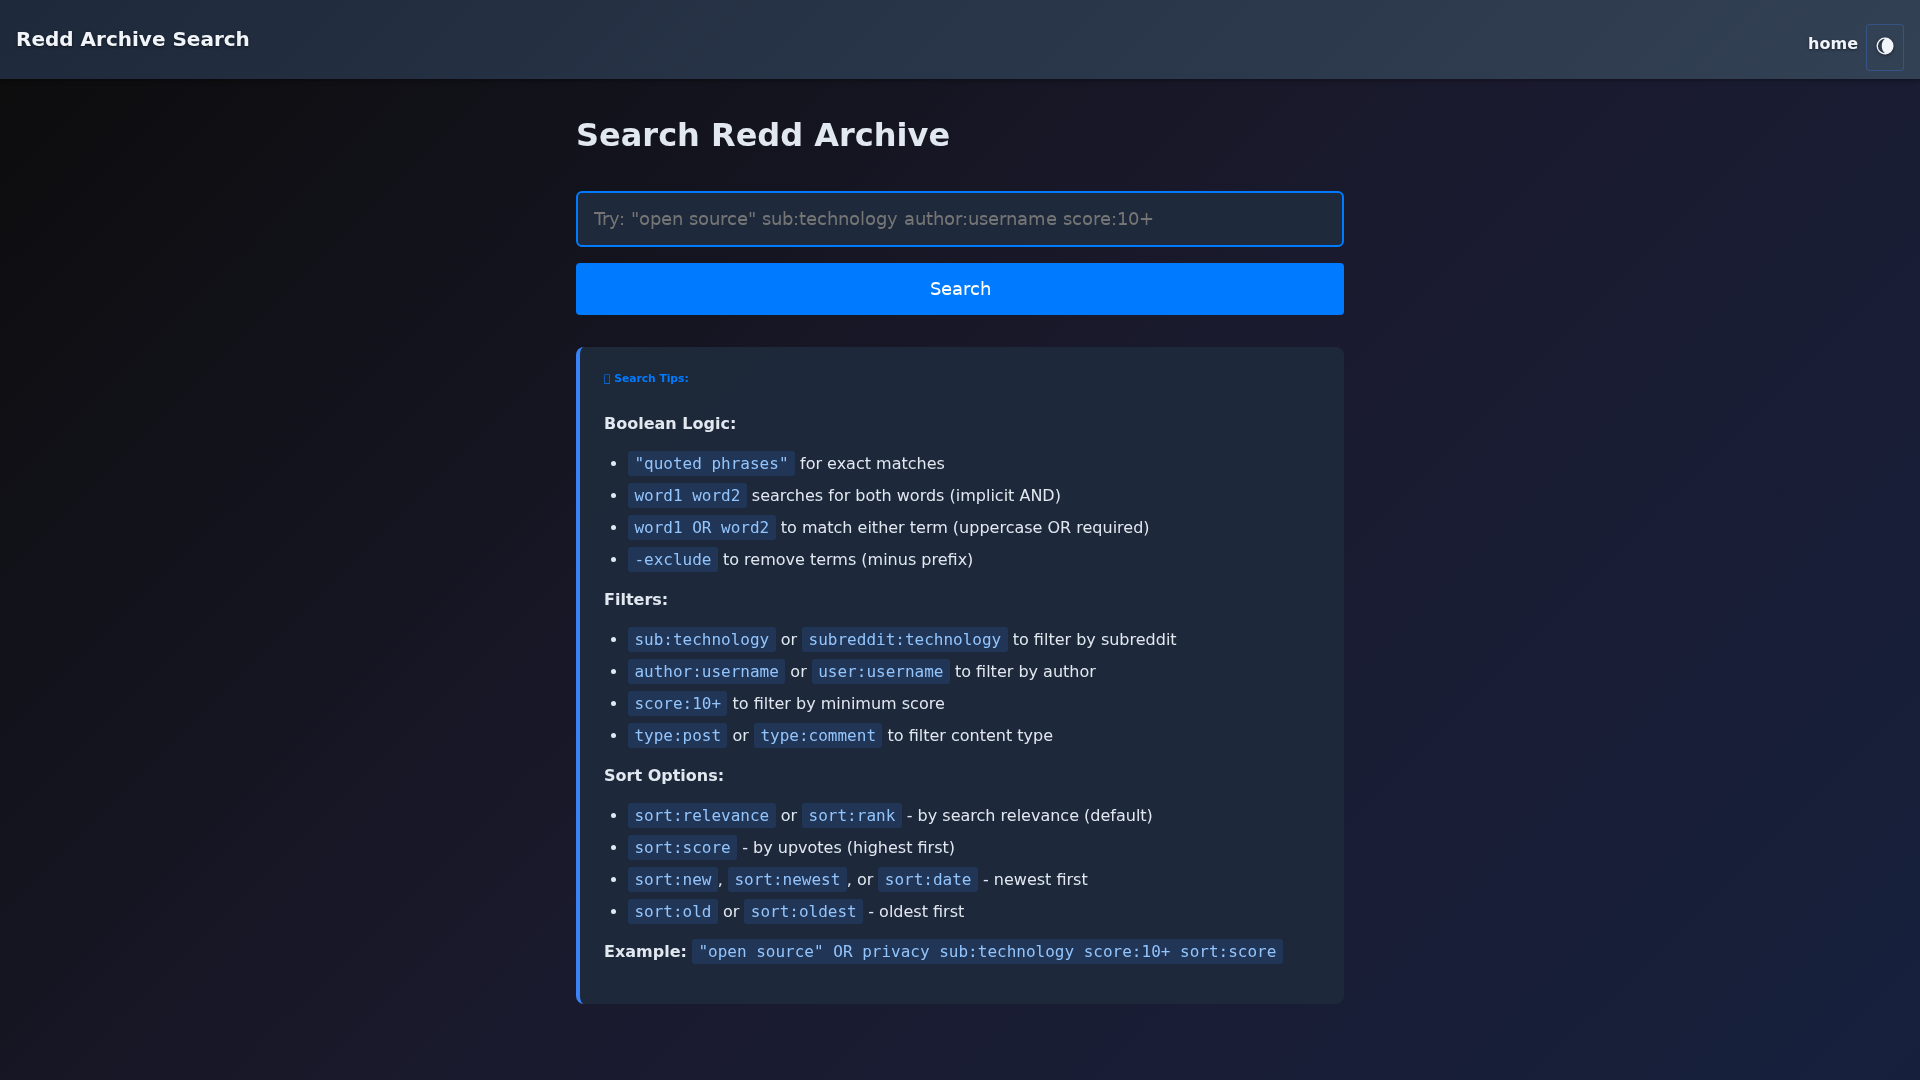
PostgreSQL full-text search with Google-style operators. Supports filtering by subreddit, author, date range, and score. *(Requires Docker deployment)*
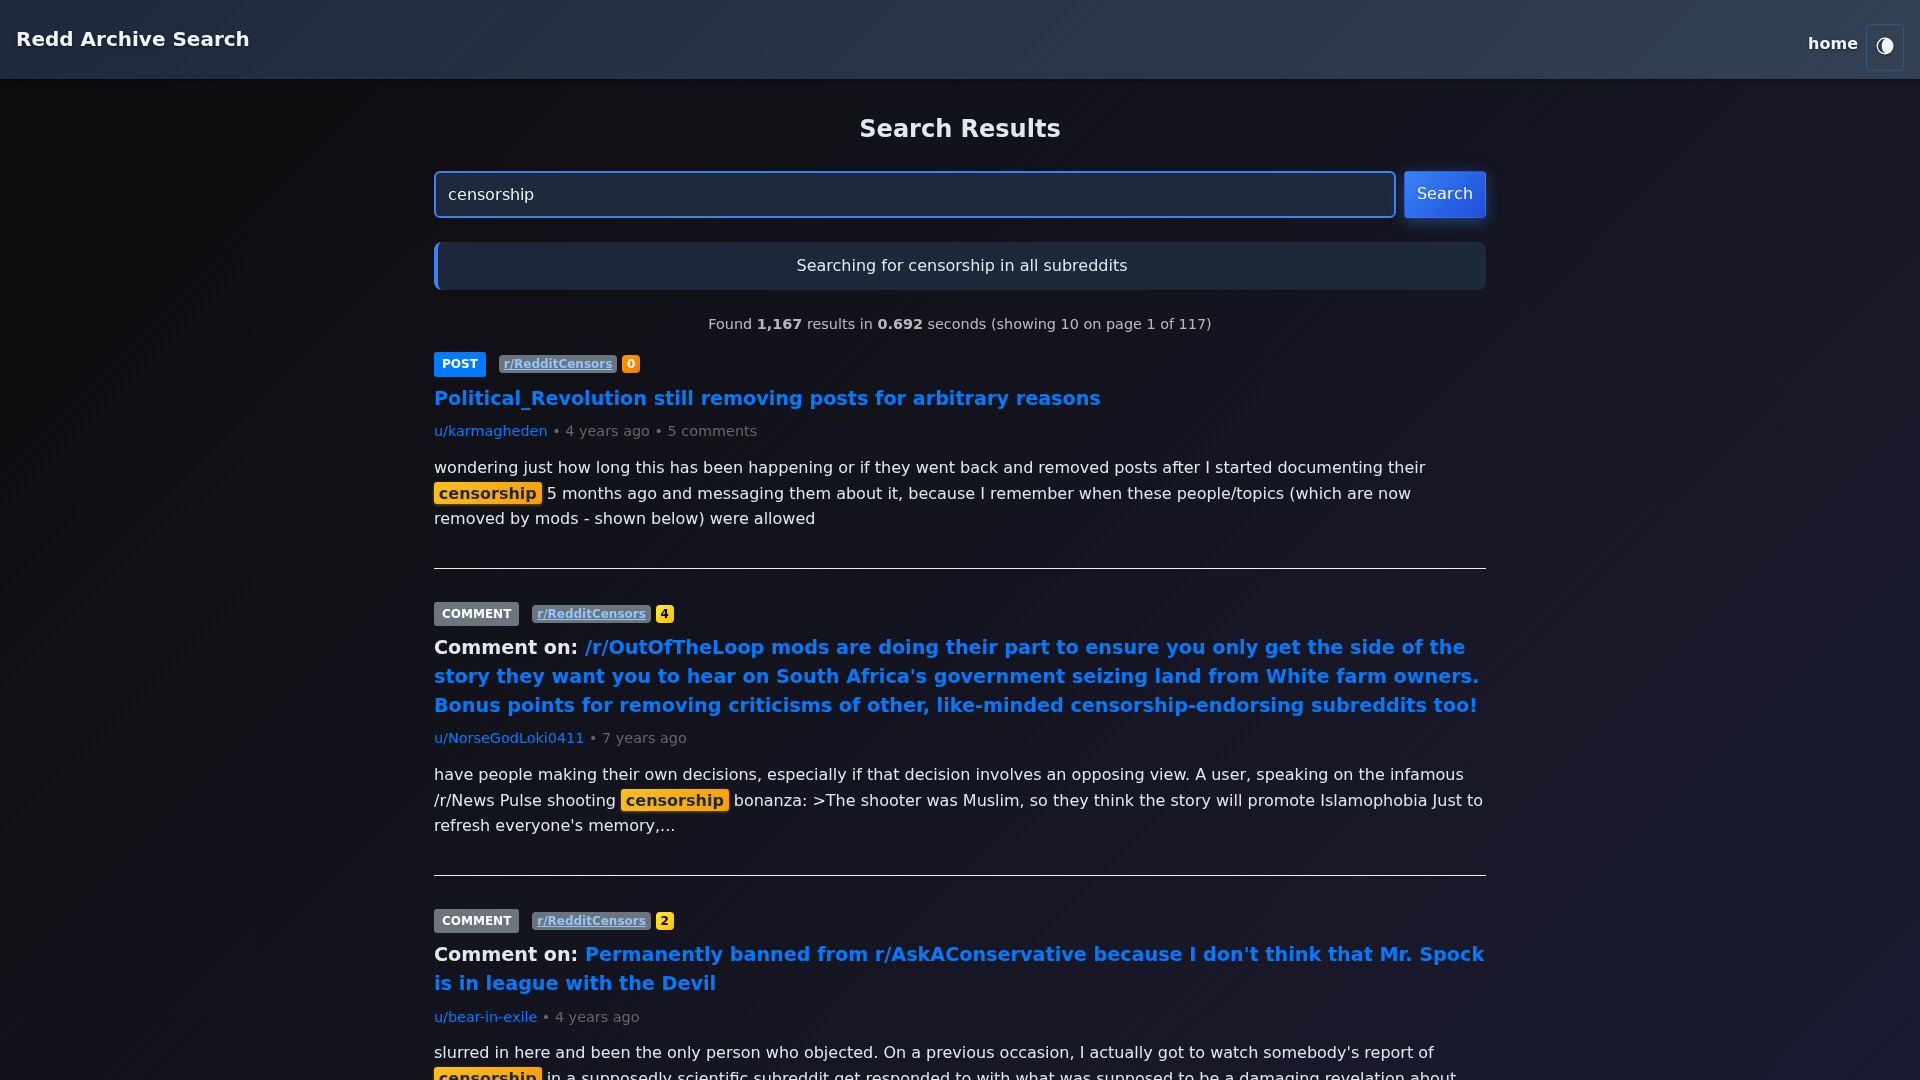
Search results with highlighted excerpts using PostgreSQL `ts_headline()`. Sub-second response times with GIN indexing. *(Server-based, Tor-compatible)*
### 🎨 Theme Gallery
All 11 palettes on the same post page (each ships dark **and** light variants; `--accent-color` re-tints any of them):
| | |
|:---:|:---:|
| 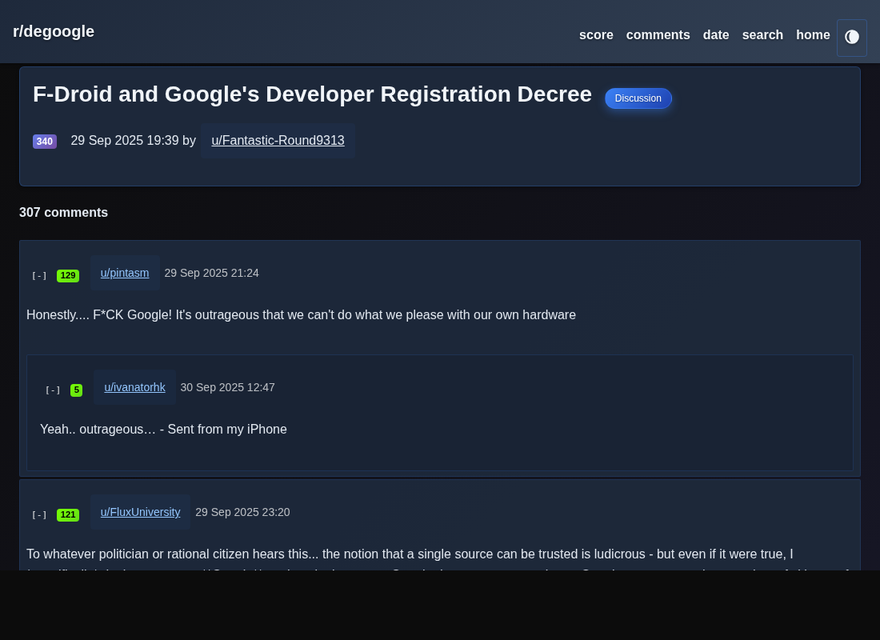 **default** | 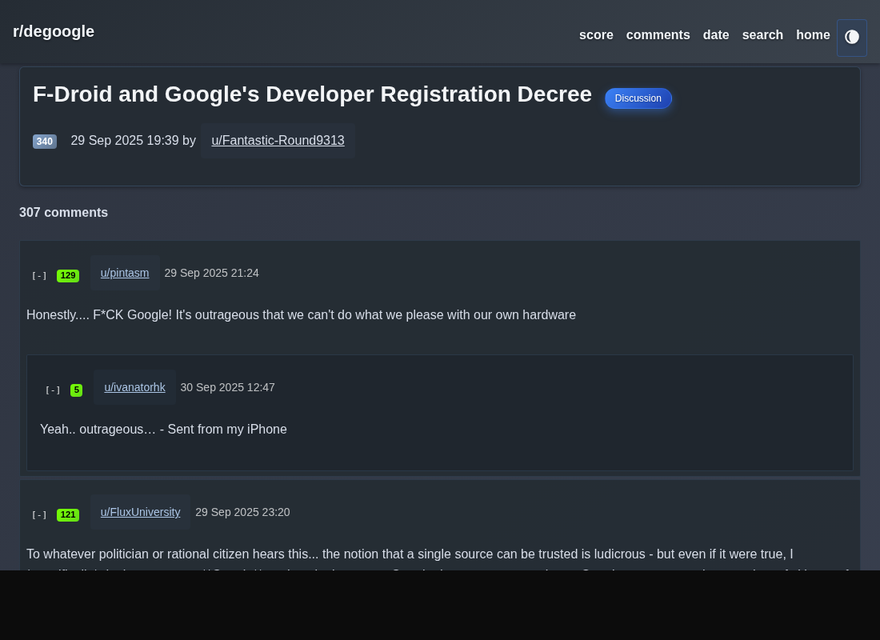 **nord** |
| 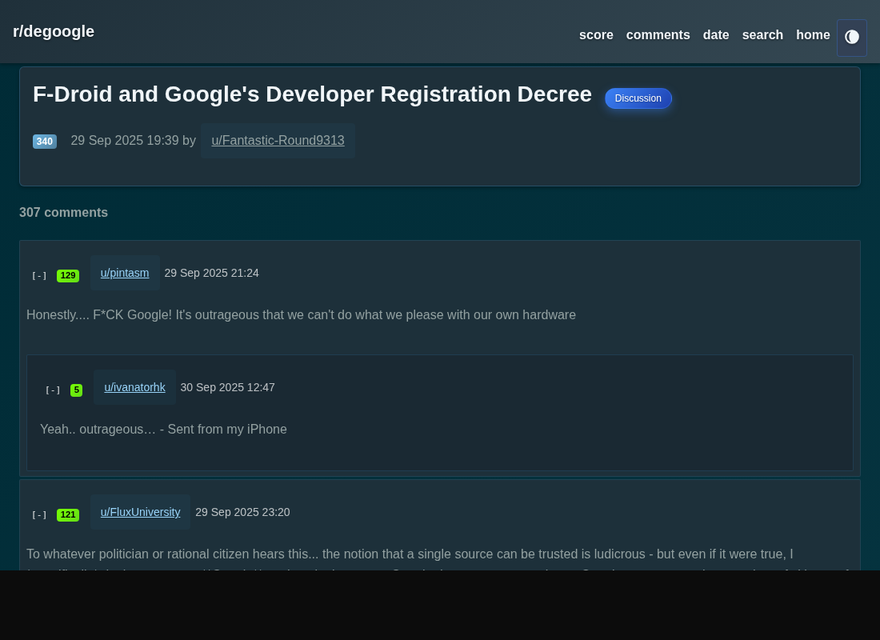 **solarized** | 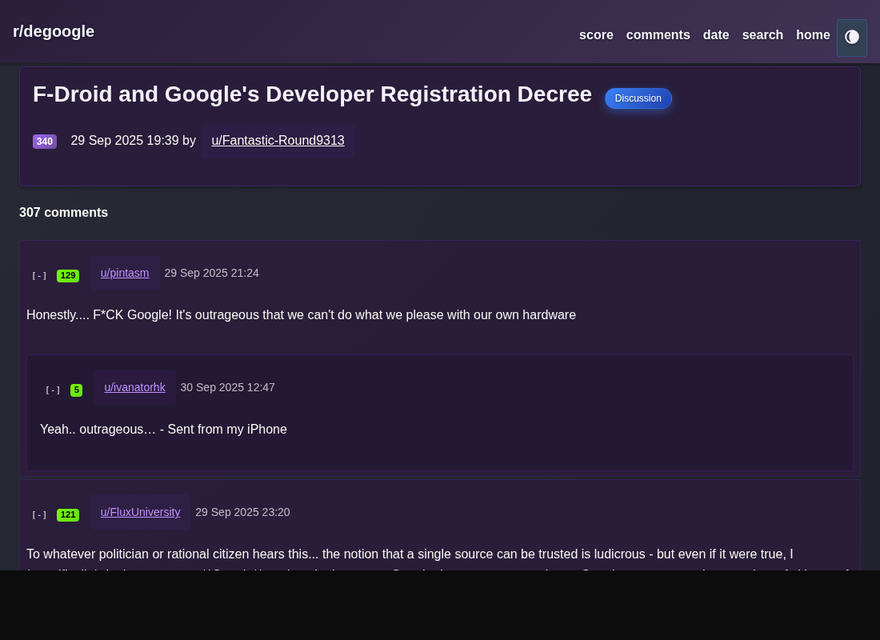 **dracula** |
| 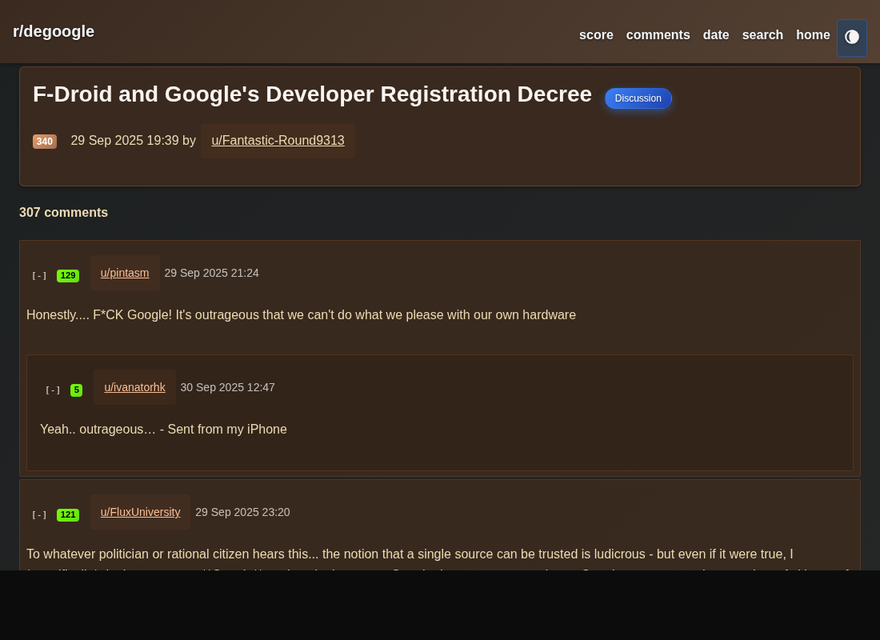 **gruvbox** | 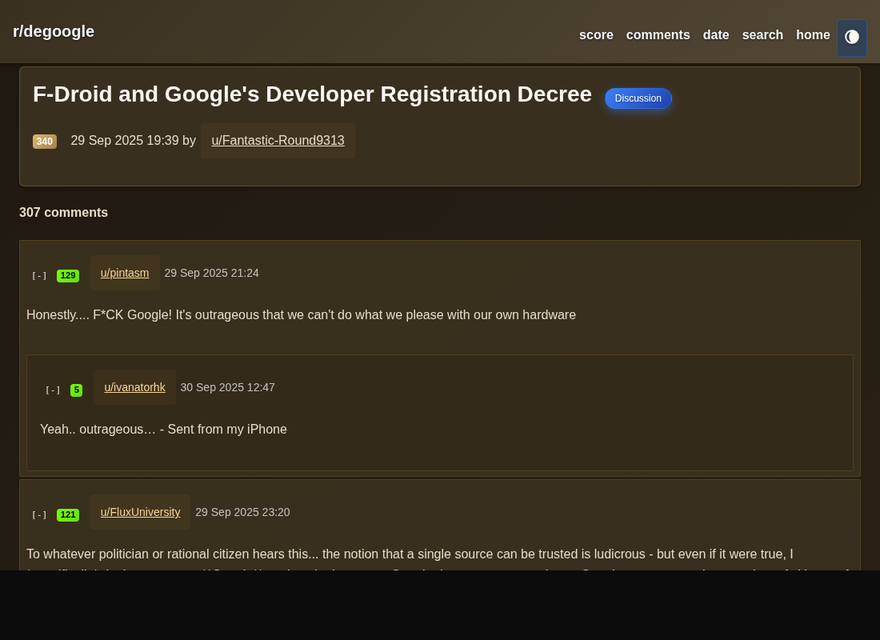 **sepia** |
| 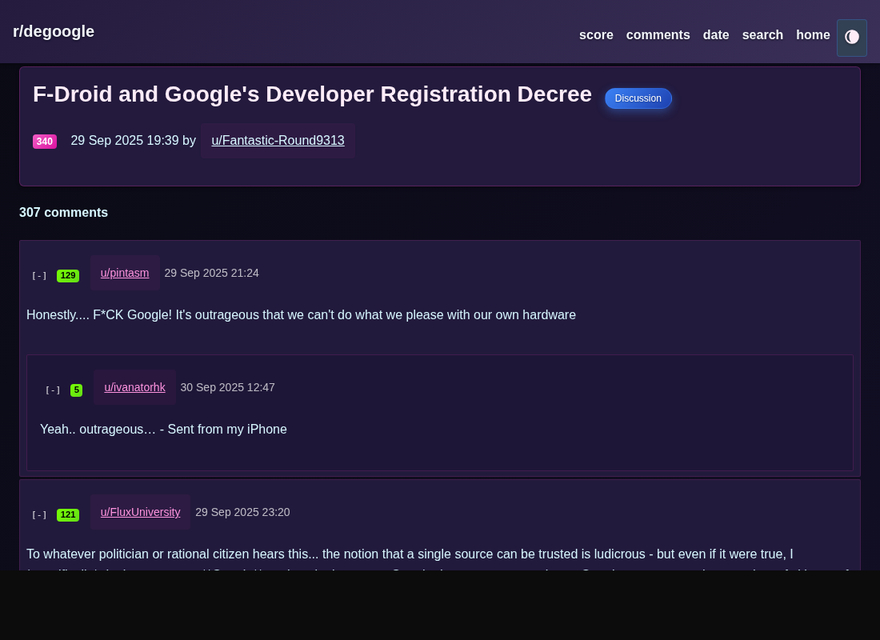 **cyberpunk** | 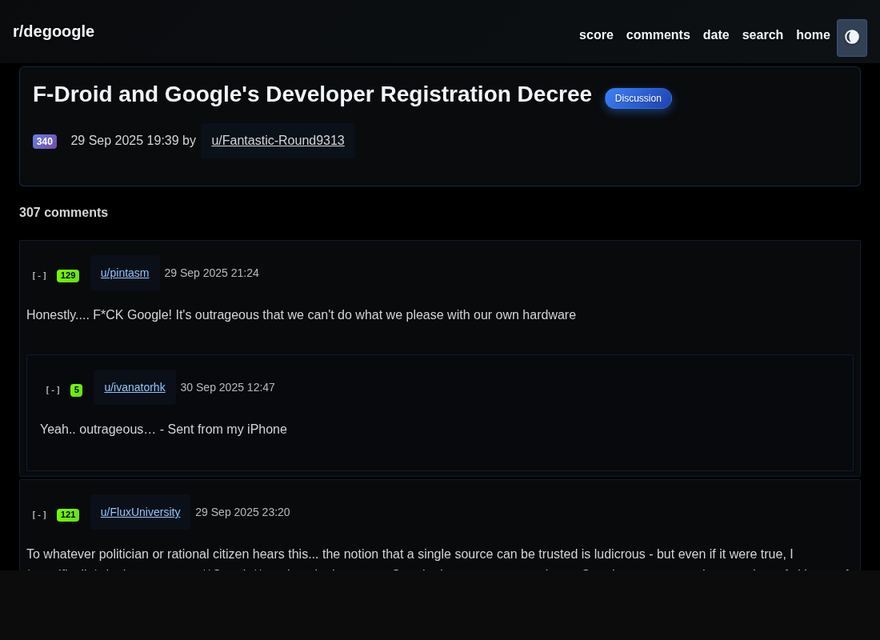 **midnight** (OLED) |
| 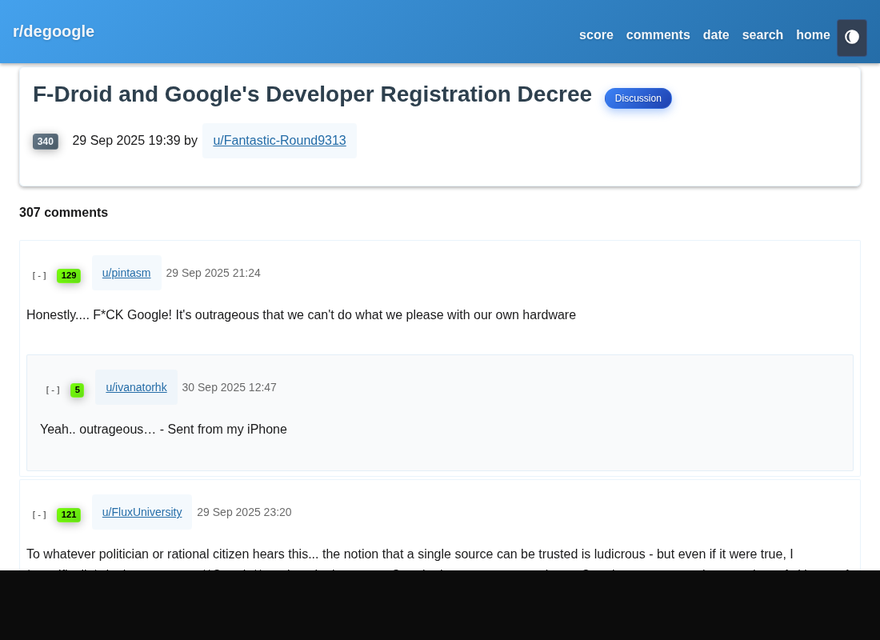 **old-reddit** | 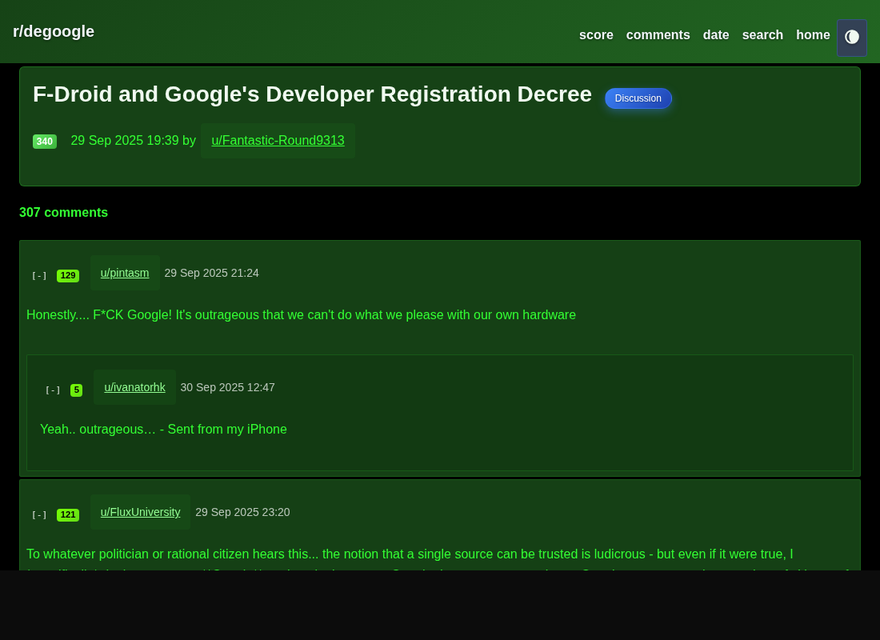 **phosphor** |
| 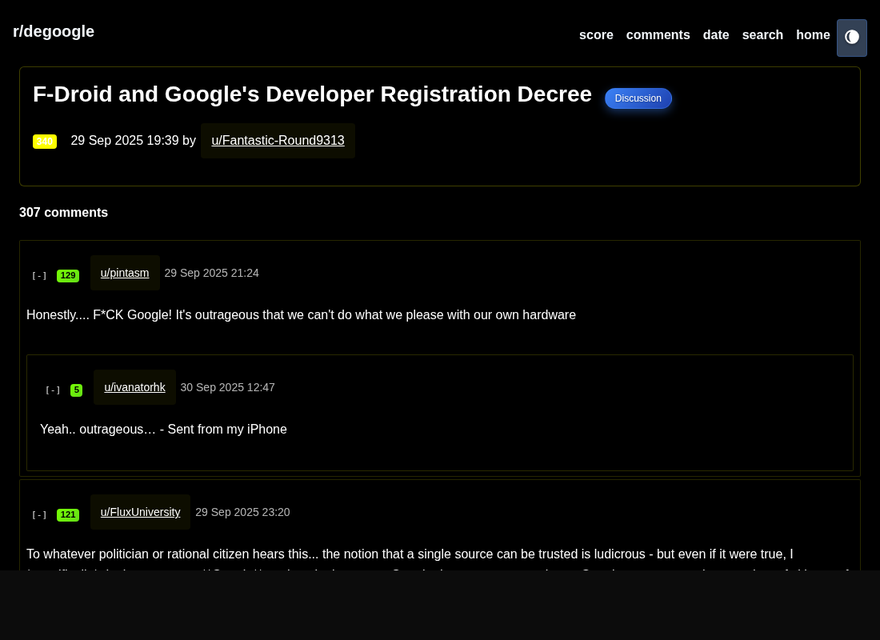 **high-contrast** | |
```bash
reddarc.py ... --theme nord # static export
REDDARCHIVER_THEME=nord search_server.py # dynamic mode
```
> **Sample Archive**: Multi-platform archive featuring programming and technology communities from Reddit, Voat, and Ruqqus · [See all screenshots →](screenshots/)
## 🛠️ Installation
**Prerequisites**: Python 3.10+, PostgreSQL 14+, 4GB+ RAM
**Quick Install** (Docker):
```bash
git clone https://github.com/19-84/redd-archiver.git
cd redd-archiver
# Create required directories
mkdir -p data output/.postgres-data logs tor-public
# Configure environment (IMPORTANT: change passwords!)
cp .env.example .env
nano .env # Edit POSTGRES_PASSWORD and DATABASE_URL
# Start services
docker compose up -d
# Generate archive (after downloading .zst files to data/)
docker compose exec reddarchiver-builder python reddarc.py /data \
--subreddit privacy \
--comments-file /data/privacy_comments.zst \
--submissions-file /data/privacy_submissions.zst \
--output /output/
```
**Detailed installation procedures** (Docker, Ubuntu/Debian, macOS, Windows WSL2):
- **[Installation Guide](docs/INSTALLATION.md)** - Platform-specific setup and troubleshooting
## 📊 Usage
**Quick workflow**: Download data → Run archive generator → Deploy
### Basic Example
```bash
# Docker (canonical): generate archive inside the builder container
docker compose up -d
docker compose exec reddarchiver-builder python reddarc.py /data \
--subreddit privacy \
--comments-file /data/privacy_comments.zst \
--submissions-file /data/privacy_submissions.zst \
--output /output/
# Access at http://localhost
# Local development (uv): same flags, host paths
export DATABASE_URL="postgresql://user:pass@localhost:5432/reddarchiver"
uv run python reddarc.py data/ --subreddit privacy \
--comments-file data/privacy_comments.zst \
--submissions-file data/privacy_submissions.zst --output output/
```
### Multi-Platform Support
- **Reddit**: `.zst` files from [Pushshift](https://academictorrents.com/details/3e3f64dee22dc304cdd2546254ca1f8e8ae542b4) (3.28TB, 2.38B posts)
- **Voat**: SQL dumps from [Archive.org](https://archive.org/details/voat-archive-2021) (15GB, 3.8M posts) - Use [pre-split files](tools/README_VOAT_SPLITTER.md) for 1000x speedup
- **Ruqqus**: `.7z` files from [Archive.org](https://archive.org/details/ruqqus-archive-2021) (752MB, 500K posts)
### Detailed Guides
- **[QUICKSTART.md](QUICKSTART.md)** - Step-by-step deployment (2-15 min)
- **[Scanner Tools](tools/README.md)** - Identify high-priority communities
- **[Installation Guide](docs/INSTALLATION.md)** - Detailed setup procedures
- **[Docker Deployment](docker/README.md)** - PostgreSQL, nginx, HTTPS, Tor in one compose file
**CLI options** and advanced workflows: See QUICKSTART.md for complete reference.
**Environment Variables:**
```bash
# Required
DATABASE_URL=postgresql://user:pass@host:5432/reddarchiver
# Serving (search server)
REDDARCHIVER_SERVE_MODE=dynamic # hybrid (default) | dynamic
REDDARCHIVER_THEME=nord # 11 palettes: default|sepia|high-contrast|nord|solarized|dracula|gruvbox|cyberpunk|midnight|old-reddit|phosphor
REDDARCHIVER_ACCENT_COLOR="#8b6914" # Accent override (hex), both modes
REDDARCHIVER_HTTP_CACHE_MAX_AGE=300 # Cache-Control/ETag for GET responses (0 disables)
REDDARCHIVER_LISTING_CACHE_TTL=300 # Listing count/stats cache (dynamic mode)
GUNICORN_WORKERS=8 # Override CPU-scaled worker count (Docker)
# Optional Performance Tuning (auto-detected if not set)
REDDARCHIVER_MAX_DB_CONNECTIONS=8 # Connection pool size
REDDARCHIVER_MAX_PARALLEL_WORKERS=4 # Parallel processing workers
REDDARCHIVER_USER_BATCH_SIZE=2000 # User page batch size
REDDARCHIVER_QUEUE_MAX_BATCHES=10 # Queue backpressure control
REDDARCHIVER_CHECKPOINT_INTERVAL=10 # Progress save frequency
REDDARCHIVER_USER_PAGE_WORKERS=4 # User page generation workers
```
## 🏗️ Architecture
**Modular PostgreSQL-backed design** with specialized HTML modules and multi-platform import support:
**Core Components:**
- `reddarc.py` - Main CLI entry point with platform auto-detection
- `core/` - PostgreSQL backend, streaming importers (Reddit/Voat/Ruqqus), incremental updates, HTML generation
- `api/` - REST API v1 with 30+ endpoints
- `mcp_server/` - MCP server for AI integration (29 tools)
- `dynamic_pages.py` - Flask page routes for dynamic serving mode
- `html_modules/` - 24 specialized modules (Jinja2 rendering, SEO, themes, statistics, CSS minification)
- `templates_jinja2/` - 27 Jinja2 templates with inheritance system
- `processing/` - Parallel user processing, batch optimization, statistics
- `monitoring/` - Performance tracking, auto-tuning, system optimization
**Key Features:**
- Streaming architecture with constant memory (4GB regardless of dataset size)
- PostgreSQL COPY protocol for 15K+ inserts/sec
- Keyset pagination for O(1) queries
- Resume capability with database checkpoints
- Multi-platform unified search with FTS GIN indexing
**Learn more**: [ARCHITECTURE.md](ARCHITECTURE.md) - Complete technical deep-dive
## 🌐 REST API & Search
**30+ REST API Endpoints** for programmatic access with MCP/AI optimization:
- **System** (5): Health checks, stats, schema, OpenAPI spec
- **Posts** (13): List, single, comments, context, tree, related, random, aggregate, batch
- **Comments** (7): List, single, random, aggregate, batch
- **Users** (8): Profiles, summary, activity, aggregate, batch
- **Subreddits** (4): List, statistics, summary
- **Search** (3): Full-text search with Google-style operators, query debugging
**AI-Optimized Features**: Field selection, truncation controls, export formats (CSV/NDJSON), batch endpoints, context endpoints. Rate limited to 100 req/min.
**PostgreSQL Full-Text Search**: Lightning-fast GIN-indexed search with relevance ranking, highlighted excerpts, and advanced filters (subreddit, author, date, score). Sub-second results for large datasets.
**Instance Registry**: Distributed leaderboard system for tracking archive instances. Configure metadata, automate scoring, group teams for coordinated archiving.
**Learn more**: [API Documentation](docs/API.md) · [Search Setup](docs/SEARCH.md) · [Registry Guide](docs/REGISTRY_SETUP.md)
## 🎯 Use Cases
### Research & Academia
- Studying online discourse and community dynamics
- Analyzing social movements and trends
- Preserving internet culture
### Community Archiving
- Backing up subreddits before potential removal
- Creating offline-accessible community resources
- Distributing knowledge repositories
### Investigation & Analysis
- Pattern analysis in deleted/removed content
- User behavior studies
- Content moderation research
---
## 🚨 Get Involved: Help Preserve Internet History
Internet content disappears every day. Communities get banned, platforms shut down, and valuable discussions vanish. **You can help prevent this.**
### 📥 Download & Mirror Data Now
**Don't wait for content to disappear.** Download these datasets today:
| Platform | Size | Posts | Download |
|----------|------|-------|----------|
| **Reddit** | 3.28TB | 2.38B posts | [Academic Torrents](https://academictorrents.com/details/3e3f64dee22dc304cdd2546254ca1f8e8ae542b4) · [Magnet Link](magnet:?xt=urn:btih:3e3f64dee22dc304cdd2546254ca1f8e8ae542b4&tr=https%3A%2F%2Facademictorrents.com%2Fannounce.php&tr=udp%3A%2F%2Ftracker.coppersurfer.tk%3A6969&tr=udp%3A%2F%2Ftracker.opentrackr.org%3A1337%2Fannounce) |
| **Voat** | ~15GB | 3.8M posts | [Archive.org](https://archive.org/details/voat-archive-2021) † |
| **Ruqqus** | ~752MB | 500K posts | [Archive.org](https://archive.org/details/ruqqus-archive-2021) ‡ |
† **Voat Performance Tip**: Use [pre-split files](tools/README_VOAT_SPLITTER.md) for 1000x faster imports (2-5 min vs 30+ min per subverse)
‡ **Ruqqus**: Docker image includes p7zip for automatic .7z decompression
**Every mirror matters.** Store locally, seed torrents, share with researchers. Be part of the preservation network.
### 🌐 Join the Registry: Deploy Your Instance
**Already running an archive?** Register it on our public leaderboard:
1. Deploy your instance ([Quick Start](QUICKSTART.md) - 2-15 minutes)
2. Submit via [Registry Template](.github/ISSUE_TEMPLATE/register-instance.yml)
3. Join coordinated preservation efforts with other teams
**Benefits**:
- Public visibility and traffic
- Coordinated archiving to avoid duplication
- Team collaboration opportunities
- Leaderboard recognition
👉 **[Register Your Instance Now →](.github/ISSUE_TEMPLATE/register-instance.yml)**
### 🆕 Submit New Data Sources
**Found a new platform dataset?** Help expand the archive network:
- Lemmy databases
- Hacker News archives
- Alternative Reddit archives
- Other link aggregator platforms
👉 **[Submit Data Source →](.github/ISSUE_TEMPLATE/submit-data-source.yml)**
**Why submit?**
- Makes data discoverable for other archivists
- Prevents duplicate preservation efforts
- Builds comprehensive multi-platform archive ecosystem
- Tracks data availability before platforms disappear
---
## 🤝 Contributing
We welcome contributions! Please see [CONTRIBUTING.md](CONTRIBUTING.md) for development guidelines, code structure, and testing procedures.
Key areas for contribution:
- PostgreSQL query optimizations
- Additional export formats
- Enhanced search features
- Documentation improvements
See our modular architecture (24 specialized HTML modules plus importer, API, and processing packages) for easy entry points to contribute.
---
## 📝 License
This is free and unencumbered software released into the public domain. See the [LICENSE](LICENSE) file (Unlicense) for details.
Anyone is free to copy, modify, publish, use, compile, sell, or distribute this software for any purpose, commercial or non-commercial, and by any means.
## 📦 Data Sources
This project leverages public datasets from the following sources:
- **[Pushshift](https://github.com/pushshift/api)** - Reddit data access and archival infrastructure
- **[Watchful1's PushshiftDumps](https://github.com/Watchful1/PushshiftDumps)** - Comprehensive data dump tools and torrent management
- **[Arctic Shift](https://github.com/ArthurHeitmann/arctic_shift)** - Making Reddit data accessible to researchers and the public
- **[Ruqqus Public Dataset](https://archive.org/details/ruqqus-public-dataset)** - 752 MB Ruqqus archive (comments and submissions)
- **[SearchVoat Archive](https://archive.org/details/searchvoat.co)** - 16.8 GB Voat.co complete backup
## 🙏 Acknowledgments
This project builds upon the work of several excellent archival projects:
- **[reddit-html-archiver](https://github.com/libertysoft3/reddit-html-archiver)** by libertysoft3 - Original inspiration and foundation for static HTML generation
- **[redarc](https://github.com/Yakabuff/redarc)** - Self-hosted Reddit archiving with PostgreSQL and full-text search
- **[red-arch](https://github.com/sys-nyx/red-arch)** - Static website generator for Reddit subreddit archives
- **[zst_blocks_format](https://github.com/ArthurHeitmann/zst_blocks_format)** - Efficient block-based compression format for processing large datasets
## 📧 Contact
- **GitHub Issues**: [Report bugs or request features](https://github.com/19-84/redd-archiver/issues)
- **GitHub Discussions**: [Ask questions or share ideas](https://github.com/19-84/redd-archiver/discussions)
- **Security Issues**: [Report via GitHub Security Advisories](https://github.com/19-84/redd-archiver/security/advisories/new)
## 💰 Support the Project
**Redd-Archiver was built by one person over 6 months** as a labor of love to preserve internet history before it disappears forever.
This isn't backed by a company or institution—just an individual committed to keeping valuable discussions accessible. Your support helps:
- Continue development and bug fixes
- Maintain documentation and support
- Cover infrastructure costs (servers, storage, bandwidth)
- Preserve more data sources and platforms
Every donation, no matter the size, helps keep this preservation effort alive.
Donation addresses (BTC / XMR)
### Bitcoin (BTC)
```
bc1q8wpdldnfqt3n9jh2n9qqmhg9awx20hxtz6qdl7
```
Scan to donate Bitcoin
### Monero (XMR)
```
42zJZJCqxyW8xhhWngXHjhYftaTXhPdXd9iJ2cMp9kiGGhKPmtHV746EknriN4TNqYR2e8hoaDwrMLfv7h1wXzizMzhkeQi
```
Scan to donate Monero
**Thank you for supporting internet archival efforts!** Every contribution helps maintain and improve this project.
---
This software is provided "as is" under the Unlicense. See [LICENSE](LICENSE) for details. Users are responsible for compliance with applicable laws and terms of service when processing data.