# LLM Wiki
**LLM Wiki turns a team's raw research folder into a reviewed, queryable, self-improving Obsidian wiki. Headless-first. Cites, doesn't guess.**
[](LICENSE)
[](https://modelcontextprotocol.io)
[](https://github.com/2233admin/obsidian-llm-wiki/wiki)
**Language**: English (this page) · [Español](README.es-ES.md) · [简体中文](docs/zh-CN/) — **Guide**: [English](docs/GUIDE.md) · [简体中文](docs/GUIDE.zh-CN.md) — **Wiki**: [Home](https://github.com/2233admin/obsidian-llm-wiki/wiki) · [Architecture](https://github.com/2233admin/obsidian-llm-wiki/wiki/Architecture) · [Rationale](https://github.com/2233admin/obsidian-llm-wiki/wiki/Rationale) · [FAQ](https://github.com/2233admin/obsidian-llm-wiki/wiki/FAQ)
You are reading this because your team has already lost knowledge.
Not because nobody wrote it down. They did: papers, meeting notes, repo findings, screenshots, agent answers. The problem is worse: the knowledge has no state. No source. No reviewer. No promotion path. No way to tell a draft from team truth.
LLM Wiki gives that mess a compiler pass:
```
capture -> compile -> ask -> file -> review -> promote
```
Put source material in `raw/`. Compile it into `wiki/` summaries, concept pages, backlinks, and contradiction reports. Ask agents cited questions. File useful answers into `00-Inbox/AI-Output/`. Promote only reviewed knowledge into decisions, architecture, and runbooks.
It is not an AI companion. It is a reviewed team memory compiler. Obsidian is the IDE, Git/Gitea review is the ledger, and MCP/CLI tools are the execution surface.
Inspired by [Andrej Karpathy's LLM Wiki](https://github.com/karpathy/llm-wiki). Markdown is the source of truth; the compiler turns structure into a graph; MCP exposes it.
---
## Quick start (Claude Code)
Inside any Claude Code session:
```
/plugin marketplace add 2233admin/obsidian-llm-wiki
/plugin install llmwiki@obsidian-llm-wiki
```
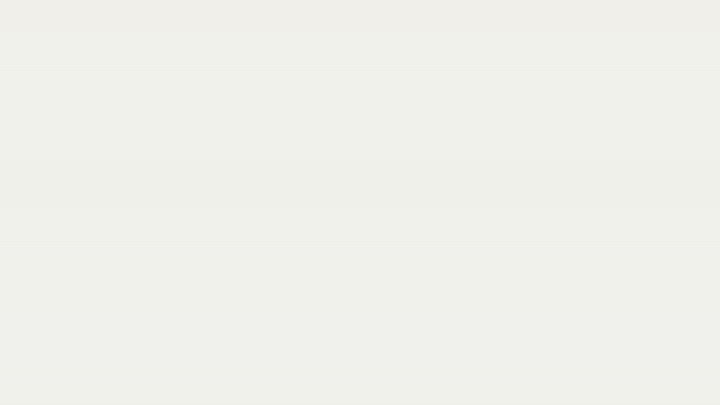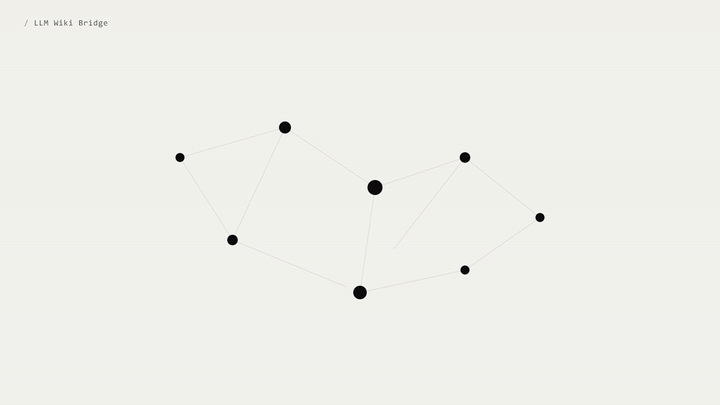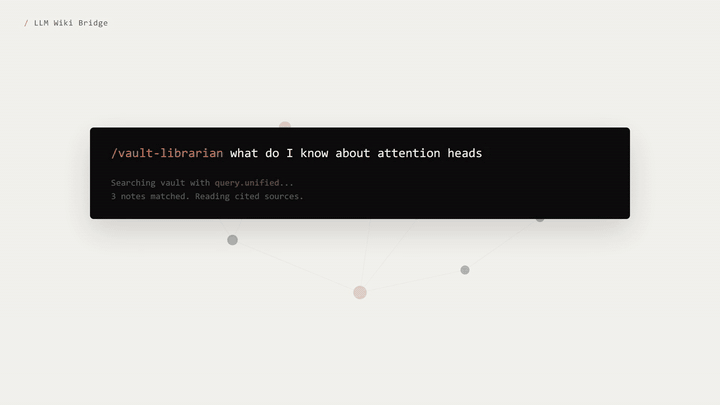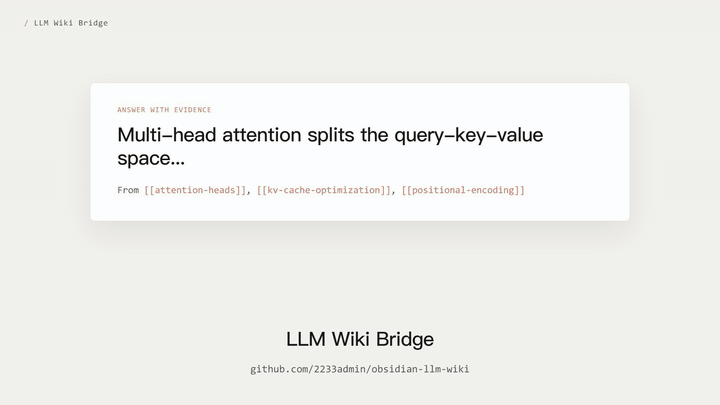
Claude Code asks for your vault path (an absolute path to your Obsidian vault or any folder of Markdown notes) and installs everything else. No clone, no build. You need Node.js 20.18.1+. The plugin ships the MCP server, all `/llmwiki:vault-*` knowledge-work roles, and the thinking/research commands. Try `/llmwiki:vault-librarian what do I know about `.
Update with `/plugin marketplace update obsidian-llm-wiki`, or turn on auto-update for the marketplace in `/plugin`. Change the vault with `/plugin configure llmwiki@obsidian-llm-wiki`.
### Other hosts (Codex / OpenCode / Gemini)
```bash
git clone --depth 1 -b plugin https://github.com/2233admin/obsidian-llm-wiki.git ~/.llmwiki
cd ~/.llmwiki && npm ci --omit=dev
```
Then register `node ~/.llmwiki/mcp-server/bundle.js` as an MCP server with `VAULT_MIND_VAULT_PATH` set to your vault, and link `~/.llmwiki/skills/*` into your host's skills directory. Update with `git pull && npm ci --omit=dev`. [docs/INSTALL.md](docs/INSTALL.md) has the exact config for each host, Windows commands, and uninstall.
### Install the Obsidian plugin
During beta, install [BRAT](https://github.com/TfTHacker/obsidian42-brat), choose
**Add a beta plugin**, and enter
`https://github.com/2233admin/obsidian-llm-wiki`. Enable **LLM Wiki** after BRAT
installs it. Once the plugin is accepted into Obsidian's Community Plugins
directory, install it there by searching for **LLM Wiki**.
Manual fallback: download `main.js`, `manifest.json`, and `styles.css` from a
plugin-version GitHub release and place them in
`/.obsidian/plugins/vault-mind-promote/`.
### Recall: keyword out of the box, semantic optional
Natural-language recall works with **zero setup**. The first `context.recall` /
`query.answer` against a fresh vault lazily indexes your notes (keyword: Postgres
full-text + trigram, no embeddings, no daemon), so an agent can ask questions
immediately — large vaults index in the background and sharpen as they finish.
**Semantic (vector) recall is an optional upgrade**: run [Ollama](https://ollama.com)
with `ollama pull bge-m3`, or point `VAULT_MIND_EMBED_URL` at any OpenAI-compatible
embedding endpoint and set `VAULT_MIND_EMBED_MODEL` and `VAULT_MIND_EMBED_DIMENSIONS`
for its model (Settings: `embeddings.endpoint`, `embeddings.model`, `embeddings.dimensions`). Recall answers tell you when semantic is off and how to turn
it on; keyword recall keeps working regardless.
---
## See the loop (5 minutes)
You can verify the compiler loop before wiring any agent host. This demo is local, report-only, and the compiler dry-run uses stub extraction, so it does not need an API key.
```bash
python compiler/compile.py examples/collab-vault/research-compiler --tier haiku --dry-run
python scripts/knowledge_health.py --vault examples/collab-vault --json
python scripts/llmwiki_doctor.py --vault examples/collab-vault --json
```
Then inspect the before/after:
| Step | Path |
|---|---|
| Raw source | `examples/collab-vault/research-compiler/raw/team-memory-os.md` |
| Compiled summary | `examples/collab-vault/research-compiler/wiki/summaries/team-memory-os.md` |
| Compiled concept | `examples/collab-vault/research-compiler/wiki/concepts/team-memory-os.md` |
| Filed AI output | `examples/collab-vault/00-Inbox/AI-Output/codex/project-setup-proposal.md` |
| Reviewed memory | `examples/collab-vault/20-Decisions/2026-05-16-gitea-reviewed-vault.md` |
That is the product: raw material becomes cited, inspectable, reviewable team memory.
---
## Works with
Any MCP-compatible host:
| Host | Install | Status |
|---|---|---|
| Claude Code | `/plugin install llmwiki@obsidian-llm-wiki` | primary target, fully exercised |
| Codex CLI | clone the `plugin` branch | smoke-tested |
| OpenCode | clone the `plugin` branch | smoke-tested |
| Gemini CLI | clone the `plugin` branch | smoke-tested |
Anything else speaking stdio MCP transport should work: the server is one `node .../mcp-server/bundle.js` command plus `VAULT_MIND_VAULT_PATH`. See [docs/INSTALL.md](docs/INSTALL.md).
---
## Example prompts
Cold start -- no vault context:
```
/vault-librarian what do I know about attention heads
```
Warm start -- specify a note you have:
```
/vault-librarian explain [[retrieval-augmented-generation]] in the context of my other notes on LLMs
```
Format-specific -- you want a list, not prose:
```
/vault-historian what decisions did I make about training data between January and March 2026
```
Iterate -- refine an answer:
```
/vault-curator find all orphan notes and stale notes in my vault that have not been updated in 90 days
```
---
## Compile, Query, Govern
| Loop | What happens | Durable path |
|---|---|---|
| Compile | Drop source material into `raw/`; run the compiler to produce summaries, concepts, backlinks, and contradiction reports. | `wiki/` |
| Query | Agents answer from cited vault notes and file useful drafts back into the inbox. | `00-Inbox/AI-Output//` |
| Govern | Humans review, promote, supersede, or discard candidate knowledge. Shared team memory moves through PR review. | `20-Decisions/`, `30-Architecture/`, `40-Runbooks/` |
See [docs/RESEARCH_COMPILER_LOOP.md](docs/RESEARCH_COMPILER_LOOP.md) for the standard operating loop.
---
## One settings and project control plane
LLM Wiki uses one host-neutral **Settings Platform** across MCP, the Python compiler/CLI, and the Obsidian control plane. Effective settings resolve in this order:
```text
session > workspace-project > vault > user-device > product default
```
Obsidian is a client of that platform, not a separate settings backend. Its plugin data keeps only presentation preferences, a machine-local device binding, and the reversible legacy-migration journal. Operational values belong to scoped Settings documents. Credentials are represented only by a **Secret Reference**; resolved secret values never enter snapshots, Project Hubs, plugin data, or durable vault knowledge.
The same control plane owns the default Agent model connection. `inherit` preserves existing env/YAML setups, `local` supports Ollama or another OpenAI-compatible endpoint without forwarding cloud credentials, and `cloud` resolves a device-local Secret Reference only for the model child process.
Projects use the stable identity `project/`. The repository checkout, vault path, Linear/GitHub item, and 5090/Orca task are bindings or projections of that Project, never replacements for its identity. The read-only `project.hub.get` operation assembles work, knowledge, Work Runs, effective settings, capability health, workspace health, and integration drift without becoming a new source of truth.
See [Settings and Obsidian control plane](docs/SETTINGS.md), [Agent Wiki toolchain](docs/AGENT_WIKI_TOOLCHAIN.md), [Project and state migrations](docs/MIGRATIONS.md), and the [capability inventory](docs/CAPABILITY_INVENTORY.md).
---
## Local Linear-style project management
LLM Wiki includes a local-first, Linear-style project management layer under `project.*`. It stores issues, comments, and dependencies as reviewable Markdown and derives Kanban, Canvas, and Bases views from them. Agents can create and update work items through MCP, while humans can inspect the same files and Git diffs.
Current work lives only under `01-Projects//issues/.md`; `10-Projects//docket/**` is retired. Project knowledge remains under `10-Projects//`, and the shared Project Registry record is `Projects/.md`. See [docs/LOCAL_PROJECTS.md](docs/LOCAL_PROJECTS.md).
## Obsidian visual layer
Project management can export native Obsidian views without requiring Obsidian to be running. Use `project.canvas.export` for `01-Projects//views/project-map.canvas`, and `project.base.export` for `01-Projects//views/issues.base`. Canvas gives a spatial project map; Bases gives a table dashboard over issue properties. Kanban remains the supported third-party read-side board adapter; Dataview and Tasks are optional advanced alternatives, not required dependencies.
The `obc` package remains the **Obsidian Broken Link Checker** compatibility and link-diagnostics capability. OBC is not the product name and does not own system settings; it consumes LLM Wiki Settings Platform snapshots like every other capability.
## Local NotebookLM-style ingest with ChubbySkills
LLM Wiki can now treat [chubbyguan/chubbyskills](https://github.com/chubbyguan/chubbyskills) as an optional local ingest pack. ChubbySkills handles platform capture and transcription for Douyin, Bilibili, Xiaohongshu, WeChat, X/Twitter, podcasts, YouTube, and more; LLM Wiki handles the local vault layer: search, citations, graph, Markdown memory, AI-Output review, and promotion.
Install LLM Wiki normally, then use `/chubbyskills` to plan which upstream capture skills to install and how to point them at the same vault. This makes the product shape closer to a local NotebookLM over your own saved feeds, without bundling heavy media dependencies into the MCP server. See [docs/CHUBBYSKILLS.md](docs/CHUBBYSKILLS.md).
LLM Wiki's MCP core deliberately supports two local ingest entrypoints instead of one scraper per platform:
| Entrypoint | Handles | Contract |
|---|---|---|
| `OPENCLI` | Web pages, articles, OpenCLI + BBX/browser-assisted captures, X/Weibo/Zhihu/WeChat/Xiaohongshu-style text surfaces. | Produce Markdown in the vault with source URL and capture metadata. |
| `MEDIA_TRANSCRIBE` | Audio/video parsing, download, subtitles, transcription, YouTube/Bilibili/Douyin/TikTok/Xiaohongshu/podcast-style media surfaces. | Produce transcript Markdown in the vault with media provenance. |
Use `ingest.link.preflight` before promising capture. It classifies the URL, routes it to `OPENCLI` or the media/transcribe toolchain, reports whether the provider is configured, and returns the honest next action. LLM Wiki only claims ingest success after Markdown lands in the vault and can be found by `vault.search` or `query.unified`. See [docs/INGEST.md](docs/INGEST.md). OpenTabs remains optional; the default install path should work with OpenCLI plus BBX/browser bridge.
## Source Registry Phase 1 {#source-registry-phase-1}
Use `source.register` when a URL or existing vault note should become a long-lived source before any heavy ingest runs. URL registration runs `ingest.link.preflight` and writes two vault-local artifacts only:
- `_llmwiki/source-registry.json` stores the machine index.
- `00-Inbox/Sources//.md` stores the human-readable Source Note.
- `10-Projects//sources//.md` is used when `project` is provided.
Phase 1 supports `inputType=url` and `inputType=vaultPath`. Reserved input types such as `filePath`, `directoryPath`, `repoPath`, and `text` are rejected until a later ingest-run layer exists. Use `source.list` and `source.get` to inspect registered sources.
## X/Twitter to Obsidian capture
LLM Wiki now ships an optional `/x-to-obsidian` skill adapted from [hemoouren/X-to-Obsidian-SKill](https://github.com/hemoouren/X-to-Obsidian-SKill/tree/main). It finds high-signal X/Twitter posts, saves them through the official Obsidian Web Clipper, and then lets LLM Wiki search and govern the clipped Markdown notes.
This lives in the skill layer, not the MCP server: browser automation and logged-in X access stay local, while `vault.search`, `query.unified`, `vault.writeAIOutput`, and `memory.handoff.write` handle the reviewable vault workflow after notes land. See [docs/X_TO_OBSIDIAN.md](docs/X_TO_OBSIDIAN.md).
## Markdown memory + Kanban boards (Phase 1)
LLM Wiki now has two memory layers:
| Layer | Path | Use |
|---|---|---|
| Lightweight KV | `_ai_memory.json` | Existing `memory.set/get/list/forget` API. Fast private key-value state, unchanged. |
| Markdown memory | vault notes | Visible, searchable handoff state that survives agent sessions and can be reviewed like any other note. |
Markdown memory is actor-scoped. `VAULT_MIND_ACTOR` selects the actor; if unset it falls back to `agent`.
| Scope | Directory |
|---|---|
| Project memory | `10-Projects//agents//memory/` |
| Fallback memory | `00-Inbox/Agent-Memory//` |
The MCP surface adds `memory.passport.get`, `memory.passport.upsert`, `memory.handoff.latest`, `memory.handoff.write`, `memory.session.save`, and `memory.session.list`. `passport.md`, `handoff.md`, and timestamped `sessions/*.md` are normal Markdown, so `vault.search` and `query.unified` can find them.
The `kanban` adapter is read-only in Phase 1. It indexes Obsidian Kanban plugin boards stored as Markdown with `kanban-plugin: board`, emits board summaries plus card results, and preserves lane, checked, archived, and block-id metadata. The default adapter list includes `kanban`; if you override adapters manually, include it explicitly:
Conversation decisions are the harder memory layer: when a session produces an architecture choice, technical tradeoff, rejected option, debug root cause, or project-state change, agents should capture it with `conversation.decision.capture` instead of leaving it buried in chat. Decisions land next to Markdown memory under `decisions/*.md`, include Summary/Decision/Why/Rejected Options/Constraints/Actions/References/Conversation Excerpts, and are searchable by `vault.search`, `query.unified`, `query.trace`, and `query.answer`. Do not store full transcripts by default; pass only selected `excerpts`.
MemPalace-style context stack is exposed through `context.*`: start a new agent session with `context.wakeup project= topic=`, use `context.recall` for a specific room/topic, and use `context.deep_search` when you need a heavier cited trace. This maps L0 to passport, L1 to handoff/sessions/decisions, L2 to topic recall, and L3 to full trace-backed search.
```bash
VAULT_MIND_ADAPTERS=filesystem,kanban
VAULT_MIND_KANBAN_GLOB='**/*.md'
```
## Knowledge roles, one MCP surface
Each `/vault-*` command is a knowledge-work role over the same MCP tool set. They are jobs in the pipeline, not product mascots.
| Name | What it does | Primary MCP tools |
|---|---|---|
| vault-librarian | reads, searches, cites from the vault | `vault.search`, `vault.read`, `vault.list` |
| vault-architect | compiles concept graph, suggests refactors | `vault.graph`, `vault.backlinks`, `compile.run` |
| vault-curator | finds orphans, dead links, duplicates, stale notes | `vault.lint`, `vault.searchByTag`, `vault.search` |
| vault-teacher | explains a note in context of its neighbors | `vault.backlinks`, `vault.read`, `vault.graph` |
| vault-historian | answers what you were thinking on date X | `vault.searchByFrontmatter`, `vault.stat`, `vault.search` |
| vault-janitor | proposes cleanups, dry-run by default | `vault.lint`, `vault.delete` (dry), `vault.rename` (dry) |
---
## Structured notes (v2.4.0)
Six tools that create AI-First notes with full frontmatter, wikilinks, and a "For future Claude" preamble — safe by default (`dryRun: true`).
| Tool | Creates | Key fields |
|---|---|---|
| `vault.daily` | `Daily/YYYY-MM-DD.md` | mood, energy, summary, tags |
| `vault.person` | `People/{name}.md` | role, company, relationship |
| `vault.project` | `Projects/{name}.md` | status, team (wikilinked), summary |
| `vault.decide` | `Decisions/YYYY-MM-DD--{slug}.md` | context, decision, rationale, consequences |
| `vault.meeting` | `Meetings/YYYY-MM-DD--{slug}.md` | attendees, decisions, action items |
| `vault.ingest` | `00-Inbox/{slug}.md` | content, source URL, type, preamble |
Every note gets `ai-first: true` in frontmatter and a two-sentence preamble so a future Claude can decide relevance in seconds without reading the full note.
`vault.init` (v2.5.0) scaffolds a methodology layout — `generic`, `para`, `lyt`, or `zettelkasten` — into an empty or existing vault, safe by default (`dryRun: true`). All write operations are now covered by per-file advisory locking with a 60s TTL, so multiple agents can write to the same vault concurrently without clobbering each other. Inspired by [claude-obsidian](https://github.com/AgriciDaniel/claude-obsidian).
---
## Thinking and research commands (v2.4.0)
Thirteen slash commands in `commands/` for use in any Claude Code, Codex CLI, Gemini CLI, or OpenCode session. They run reasoning over the vault using the MCP tools above — no LLM logic lives in the server.
| Command | What it does |
|---|---|
| `/vault-synthesize` | Scan recent notes for unnamed cross-source patterns; write synthesis notes |
| `/vault-reconcile` | Find semantic contradictions across vault notes; auto-resolve or flag ambiguous ones |
| `/vault-emerge` | Identify topics gaining momentum in the last 14 days |
| `/vault-research` | Web research dossier (Wikipedia, HN, arXiv, etc.) saved to `Research/` |
| `/vault-challenge` | Devil's advocate: surface weak claims and counter-evidence in a note |
| `/vault-connect` | Map unexpected connections between concepts, people, and projects |
| `/vault-panel` | Multi-perspective take: generate 3–5 stakeholder views with tensions |
| `/vault-recap` | Period review (week/month/quarter) from vault activity |
| `/vault-graduate` | Graduation decision on an idea: ship / invest more / archive |
| `/vault-learn` | Extract transferable principles from an experience and save to `Knowledge/` |
| `/vault-autoresearch` | Three-round autonomous research loop: question, investigate, refine, write up |
| `/vault-think` | Apply a 10-principle thinking framework to a topic or note |
| `/vault-expand` | Expand a single source into 8–15 interlinked wiki pages |
Inspired by [obsidian-second-brain](https://github.com/eugeniughelbur/obsidian-second-brain) and [claude-obsidian](https://github.com/AgriciDaniel/claude-obsidian). LLM Wiki provides the infrastructure; these commands provide the workflow patterns that sit on top.
---
## How it works (30-second tour)
Your markdown files -- with wikilinks `[[like this]]`, aliases, frontmatter tags, and mtime -- are the source of truth. The compiler turns raw topic folders into a concept graph (nodes = notes, edges = links and semantic relationships), summaries, and concept pages. The MCP server exposes this graph as tools: `vault.search`, `vault.backlinks`, `vault.graph`, and 40+ more.
When Claude Code (or any MCP-compatible agent) runs `/vault-librarian`, it calls `vault.search` and `vault.read` directly. The agent gets citations -- not guesses.
- No embeddings required at small scale. Optional pgvector-backed semantic search via the `memU` adapter.
- No database. Filesystem-only by default; a compiled graph is cached as plain JSON alongside the vault.
- No Obsidian required at runtime. The `filesystem` adapter is always available. Obsidian is an optional adapter if you want live plugin-API features via a WebSocket bridge.
- No code intelligence required at small scale. Optional project-wide knowledge graph (code + docs + PDFs + images) via the `graphify` adapter (`uv tool install graphifyy`).
---
## Deep dives
The wiki has the long-form answers. Read them in any order.
| Page | Answers |
|---|---|
| [**Rationale**](https://github.com/2233admin/obsidian-llm-wiki/wiki/Rationale) | Why this exists. Why not just grep, not just an Obsidian plugin, not just a vector DB, not just a long-context LLM. Covers the product drift. |
| [**Architecture**](https://github.com/2233admin/obsidian-llm-wiki/wiki/Architecture) | Four-layer system diagram. Request lifecycle (8 steps, `/vault-librarian` to cited answer). Extension points. |
| [**Adapter-Spec**](https://github.com/2233admin/obsidian-llm-wiki/wiki/Adapter-Spec) | Adapter contract, capability matrix, fan-out and ranking, failure modes, recipe for a fifth adapter. |
| [**Compile-Pipeline**](https://github.com/2233admin/obsidian-llm-wiki/wiki/Compile-Pipeline) | What each stage produces, where the graph lives on disk, performance reference points. |
| [**Research Compiler Loop**](docs/RESEARCH_COMPILER_LOOP.md) | The product loop: raw materials, compiled wiki, cited Q&A, AI-Output filing, review, promotion. |
| [**Settings Platform**](docs/SETTINGS.md) | Shared scopes, Obsidian control plane, compiler discovery, Secret References, and Doctor. |
| [**Migrations**](docs/MIGRATIONS.md) | Reversible legacy plugin settings and Project layout migration procedures. |
| [**Capability Inventory**](docs/CAPABILITY_INVENTORY.md) | Domain ownership, single-device/multi-device behavior, and release evidence status. |
| [**Persona-Design**](https://github.com/2233admin/obsidian-llm-wiki/wiki/Persona-Design) | User-facing knowledge roles vs underlying skills. The design discipline that keeps them from collapsing into one generic agent. |
| [**Security-Model**](https://github.com/2233admin/obsidian-llm-wiki/wiki/Security-Model) | Dry-run default, protected paths, preflight gates, bearer-token transport, what this explicitly does not secure. |
| [**Recipes**](https://github.com/2233admin/obsidian-llm-wiki/wiki/Recipes) | Content collectors and local knowledge feeders (Feishu, Gmail, Linear, X, WeChat, Dreamtime, and more) that land external sources into the vault. |
| [**FAQ**](https://github.com/2233admin/obsidian-llm-wiki/wiki/FAQ) | Does it need Obsidian running? How big a vault? Why dry-run? First-draft answers, expands as questions come in. |
---
---
## License
GPL-3.0. See [LICENSE](LICENSE).