# Deep Research Web UI
[English | [中文](README_zh.md)]
Deep Research Web UI turns a research question into a cited report: it plans searches, browses the web, verifies findings against real source pages, and lets you inspect and follow up on every citation — all from your browser, or self-hosted with your own API keys.
Features:
- 🚀 **Safe & Secure**: In Client Mode, config and API requests stay in your browser locally
- 🕙 **Realtime feedback**: Stream AI responses and reflect on the UI in real-time
- 🌳 **Search visualization**: Shows the research process using a tree structure. Supports searching in different languages
- 📄 **Export as PDF**: Export the final research report as Markdown / PDF
- 🤖 **Supports more models**: Uses plain prompts instead of newer, less widely supported features like Structured Outputs. This ensures to work with more providers that haven't caught up with the latest OpenAI capabilities.
- 🐳 **Docker support**: Deploy in your environment in one-line command
- 🔧 **Server Mode**: Deploy with environment variables, no need for users to configure API keys
- 🔎 **Evidence and follow-ups**: Inspect source excerpts from report citations, then research a finding further and update related passages while keeping the original report in history
- 🎯 **Focused search**: Separate queries from time and source filters, check result relevance, and retry once with a revised query when evidence is insufficient
- 📖 **On-demand full-page reading**: Fetches full source pages to extract verbatim evidence when search snippets aren't enough, sharing a token/request budget across the whole research run
Currently available providers:
- AI: OpenAI compatible, [ApiSmart](https://www.apismart.ai), SiliconFlow, DeepSeek, OpenRouter, Requesty, Ollama, LiteLLM and more
- Web Search: Tavily (1000 free credits / month), [Firecrawl](https://firecrawl.dev) (cloud / self-hosted), fastCRW (cloud / self-hosted), Google PSE, You.com, [Serply](https://serply.io), Parallel (keyless, Server Mode only)
Please give a 🌟 Star if you like this project!
---
**Sponsors**
MangoProxy provides Residential, ISP, Mobile, and Datacenter proxies in 200+ locations for web scraping, automation, SEO, and multi-account management. Promo code: `GITHUBISP` - 8% off Static ISP proxies.
 ---
ApiSmart.ai provides unified access to leading AI models through a single API. Use one API key to connect with LLM, image, and video models through an OpenAI-compatible interface, without managing multiple providers separately. Switch models easily, simplify billing, and improve reliability with intelligent routing and automatic failover. Build and scale AI applications faster with one streamlined API platform.
 ---
Helodata provides global proxy infrastructure covering 195+ countries and regions, with 80M+ ethically sourced residential IPs. We offer Residential, ISP, Unlimited Residential, Mobile, and Datacenter proxies for reliable data access across AI, web scraping, and automation workflows. Sign up using the promo code **`DRWEB`** to enjoy an exclusive 10% discount!
 ---
## How to use
### Inspect evidence and follow up
1. After a research finishes, click a `[1]`-style citation in the report, or click **Inspect evidence and follow up**.
2. In the evidence panel, review each finding's source, retrieval time, and excerpt. A new excerpt is only saved once it's matched against retrieved content; search summaries and page text are labeled separately. A matched excerpt does not by itself prove the finding — read it in context.
3. Enter what you want to verify, e.g. "Find the latest official pricing and confirm the eligibility terms," then click **Follow up and update report**. A follow-up searches at most two directions in one round, and updates only the Markdown blocks that cite that finding; tables and lists are updated as whole blocks.
4. On success, the new evidence and updated report are saved as a separate history entry, leaving the original report unchanged. On failure, cancellation, or when no matching excerpt is found, the original report is preserved.
This works in both Client Mode and Server Mode. Older history entries still load; findings without a saved excerpt are labeled accordingly. History is stored in your browser — export research you want to keep.
Live demo: https://deep-research.ataw.top
### Deployment modes
- **Client Mode**: users enter their own API keys in the browser. This is the best fit for static deployments such as EdgeOne Pages or `pnpm generate`.
- **Server Mode**: API keys are configured as server-side environment variables, so users do not need to enter keys in the UI. This requires an SSR/Nitro runtime such as the Docker image; it is not available in purely static deployments.
### Self hosted
#### Server Mode (Recommended)
Deploy with environment variables - users don't need to configure API keys. Use this mode when you can run the Nuxt server:
**Using Docker with environment variables:**
```bash
docker run -p 3000:3000 \
-e NUXT_PUBLIC_SERVER_MODE=true \
-e NUXT_AI_API_KEY=your-ai-api-key \
-e NUXT_WEB_SEARCH_API_KEY=your-search-api-key \
-e NUXT_PUBLIC_AI_PROVIDER=openai-compatible \
-e NUXT_PUBLIC_AI_MODEL=gpt-4o-mini \
-e NUXT_PUBLIC_WEB_SEARCH_PROVIDER=tavily \
anotia/deep-research-web:latest
```
**Using Docker with .env file:**
```bash
# Copy .env.example and update it with your configuration
cp .env.example .env
docker run -p 3000:3000 --env-file .env anotia/deep-research-web:latest
```
#### Client Mode (Traditional)
Users configure their own API keys in the browser. Use this mode for static deployments:
One-click deploy with [EdgeOne Pages](https://edgeone.ai/products/pages):
[](https://edgeone.ai/pages/new?from=github&template=https://github.com/AnotiaWang/deep-research-web-ui&from=github)
Use pre-built Docker image:
```bash
docker run -p 3000:3000 --name deep-research-web -d anotia/deep-research-web:latest
```
Use self-built Docker image:
```
git clone https://github.com/AnotiaWang/deep-research-web-ui
cd deep-research-web-ui
docker build -t deep-research-web .
docker run -p 3000:3000 --name deep-research-web -d deep-research-web
```
### Environment Variables
#### Server Mode Configuration
| Variable | Description | Default |
|----------|-------------|---------|
| `NUXT_PUBLIC_SERVER_MODE` | Enable server mode | `false` |
| `NUXT_ACCESS_PASSWORD` | Optional password required to call the `/api` routes | - |
| `NUXT_AI_API_KEY` | AI provider API key | - |
| `NUXT_AI_API_BASE` | AI provider base URL | - |
| `NUXT_WEB_SEARCH_API_KEY` | Web search API key | - |
| `NUXT_WEB_SEARCH_API_BASE` | Web search base URL | - |
| `NUXT_PROXY_URL` | Outbound proxy URL (http/https/socks5/socks5h) | - |
| `NUXT_NO_PROXY` | Hosts bypassing the proxy | `localhost,127.0.0.1,::1` |
#### Public Configuration (Server Mode)
| Variable | Description | Default |
|----------|-------------|---------|
| `NUXT_PUBLIC_AI_PROVIDER` | AI provider type | `openai-compatible` |
| `NUXT_PUBLIC_AI_MODEL` | AI model name | `gpt-4o-mini` |
| `NUXT_PUBLIC_AI_CONTEXT_SIZE` | Context size | `256000` |
| `NUXT_PUBLIC_AI_MAX_OUTPUT_TOKENS` | Max output tokens per call, including reasoning. Unset lets the provider decide | - |
| `NUXT_PUBLIC_WEB_SEARCH_PROVIDER` | Search provider | `tavily` |
| `NUXT_PUBLIC_WEB_SEARCH_CONCURRENCY_LIMIT` | Max concurrency | `2` |
| `NUXT_PUBLIC_WEB_SEARCH_SEARCH_LANGUAGE` | Search language | `en` |
| `NUXT_PUBLIC_TAVILY_ADVANCED_SEARCH` | Use Tavily advanced search | `false` |
| `NUXT_PUBLIC_TAVILY_SEARCH_TOPIC` | Tavily search topic | `general` |
| `NUXT_PUBLIC_GOOGLE_PSE_ID` | Google PSE ID | - |
#### Provider values
| Type | Supported values |
|------|------------------|
| AI provider | `openai-compatible`, `siliconflow`, `302-ai`, `openrouter`, `requesty`, `deepseek`, `ollama`, `litellm` |
| Web search provider | `tavily`, `firecrawl`, `crw`, `google-pse`, `youcom`, `serply`, `parallel` (Server Mode only) |
Notes:
- The `/api` routes only answer when `NUXT_PUBLIC_SERVER_MODE=true`. With server mode off they return `401` even if `NUXT_AI_API_KEY` is set, so the server's keys are never reachable through the API.
- When `NUXT_ACCESS_PASSWORD` is set, visitors must enter it before running research. Strongly recommended for publicly reachable server-mode deployments, since the server's API keys are otherwise usable by anyone.
- Requests that a browser marks as cross-site (`Sec-Fetch-Site` or `Origin`) are refused even with a valid password, so another website cannot spend your keys through a visitor's browser. If you run behind a reverse proxy that rewrites `Host`, forward the original name as `X-Forwarded-Host`.
- Upstream error text is logged in full on the server but reduced to a status code before it reaches the browser, so a provider that echoes the rejected key cannot leak it to a client.
- `NUXT_WEB_SEARCH_API_KEY` supports comma-separated keys for Tavily, Google PSE and Serply, for example `key1,key2,key3`.
- Google PSE requires both `NUXT_WEB_SEARCH_API_KEY` and `NUXT_PUBLIC_GOOGLE_PSE_ID`.
- Firecrawl self-hosted deployments can set `NUXT_WEB_SEARCH_API_BASE`.
- fastCRW (`crw`) is a Firecrawl-compatible web scraper (single binary; self-host or cloud). It defaults to the cloud base `https://fastcrw.com/api` and reads the key from `NUXT_WEB_SEARCH_API_KEY` (document as `CRW_API_KEY`); self-hosted deployments can set `NUXT_WEB_SEARCH_API_BASE`.
- You.com (`youcom`) reads its key from `NUXT_WEB_SEARCH_API_KEY` (optional, comma-separated keys supported for rotation). Without a key it uses the keyless endpoint with a limited daily quota; get a key at https://you.com/platform/api-keys.
- Serply (`serply`) returns Google web and news results through the [Serply API](https://serply.io/docs) and reads its key from `NUXT_WEB_SEARCH_API_KEY` (comma-separated keys supported for rotation). Time range, news intent, language and domain filters are applied natively; explicit publication-date windows are not.
- Ollama uses `http://localhost:11434/v1` as the default API base. When running the app inside Docker, `localhost` refers to the container itself, so set `NUXT_AI_API_BASE` to a reachable host or Docker network address if Ollama runs outside the container.
- LiteLLM uses `http://localhost:4000/v1` as the default API base. Its API key is optional when the proxy does not require authentication; set `NUXT_AI_API_BASE` when the proxy is not reachable at the default local address.
- Requesty uses `https://router.requesty.ai/v1` as the default API base and expects model IDs in `provider/model` format, such as `openai/gpt-4o`.
#### Parallel Search MCP (Server Mode only)
Set these variables in your server deployment:
```bash
NUXT_PUBLIC_SERVER_MODE=true
NUXT_PUBLIC_WEB_SEARCH_PROVIDER=parallel
```
Keep your AI provider configured as usual. Parallel search needs no Parallel account or API key and does not use `NUXT_WEB_SEARCH_API_KEY` or `NUXT_WEB_SEARCH_API_BASE`. Tavily remains the default when no search provider is selected.
This provider uses the free, rate-limited [Parallel Search MCP](https://docs.parallel.ai/integrations/mcp/search-mcp) at `https://search.parallel.ai/mcp`. Searches send queries and objectives to Parallel; on-demand page reading sends source URLs. Related calls share a random research session ID. Requests include `deep-research-web-ui/` as their User-Agent so Parallel can measure aggregate project usage. See Parallel's [Customer Terms](https://parallel.ai/customer-terms) and [Privacy Policy](https://parallel.ai/privacy-policy).
Public Server Mode deployments share one outbound IP, so users share the anonymous free-tier rate limits. Reduce concurrency if requests are rate-limited.
Search excerpts retain their URLs, titles and publication dates. The app can also request full source pages when excerpts are insufficient. News, time, domain and language filters are unsupported and appear through the app's existing limitation notices. The result count is capped locally. Service errors are surfaced without switching providers.
Parallel is available only in Server Mode, including follow-ups. Static deployments and the Client Mode provider picker do not support it because browsers cannot reliably send the project User-Agent. Server requests honor the outbound proxy settings below.
#### Outbound proxy (Server Mode only)
Set `NUXT_PROXY_URL` to route server-side requests through a proxy:
```bash
NUXT_PROXY_URL=socks5h://user:pass@gate.example.com:7777
NUXT_NO_PROXY=localhost,127.0.0.1,::1
```
- Supported schemes: `http`, `https`, `socks5`, `socks5h`, `socks`.
- `http(s)` proxies cover everything: AI providers, Google PSE, you.com, Serply, Parallel, and the Tavily / Firecrawl / CRW SDKs.
- `socks*` proxies cover AI providers, Google PSE, you.com, Serply and Parallel; the Tavily / Firecrawl / CRW SDKs (axios-based) cannot speak SOCKS and will connect directly. Use the `http://` endpoint of the same proxy (same credentials on most providers) for full coverage.
- `NUXT_NO_PROXY` accepts `*`, exact hosts and parent domains (`example.com` also matches `api.example.com`). Local AI gateways (Ollama, LiteLLM) and self-hosted scrapers stay direct via the default list.
- Standard `HTTP_PROXY` / `HTTPS_PROXY` / `NO_PROXY` env vars are honored as fallback when `NUXT_PROXY_URL` is unset.
- Proxy credentials are redacted in logs.
- Client Mode (browser) cannot use this: browsers have no SOCKS API. Configure a system / browser proxy instead.
- URL-encode special characters in credentials (`%` as `%25`, `@` as `%40`, `:` as `%3A`).
- An invalid `NUXT_PROXY_URL` fails server startup (fail-fast) instead of silently going direct.
#### Using a proxy (e.g. Helodata) with self-hosted deployments
If your server needs geo-targeted or rotating egress IPs, run the deployment behind a standard HTTP/SOCKS5 proxy. Example with Helodata:
```bash
# Full coverage: AI + Google PSE + you.com + Tavily/Firecrawl SDKs
NUXT_PROXY_URL="http://YOUR_HELODATA_USERNAME:YOUR_HELODATA_PASSWORD@gate.helodata.io:7777"
# Or SOCKS5: AI + Google PSE + you.com
# (Tavily/Firecrawl SDKs can't speak SOCKS and will connect directly)
NUXT_PROXY_URL="socks5h://YOUR_HELODATA_USERNAME:YOUR_HELODATA_PASSWORD@gate.helodata.io:7777"
docker run -p 3000:3000 \
-e NUXT_PUBLIC_SERVER_MODE=true \
-e NUXT_AI_API_KEY=your-ai-api-key \
-e NUXT_WEB_SEARCH_API_KEY=your-search-api-key \
-e NUXT_PROXY_URL="$NUXT_PROXY_URL" \
anotia/deep-research-web:latest
```
Get credentials from your [Helodata](https://helodata.com?ref=deepresearchwebui2) dashboard. See [Helodata docs](https://docs.helodata.com/) for region / city / sticky-session username format. For proxy behavior details, see [Outbound proxy (Server Mode only)](#outbound-proxy-server-mode-only).
---
## Developing
### Setup
Make sure to install dependencies:
```bash
pnpm install
```
## Development Server
Start the development server on `http://localhost:3000`:
```bash
pnpm dev
```
## Production
Build the application for production:
If you want to deploy a SSR application:
```bash
pnpm build
```
If you want to deploy a static, SSG application:
```bash
pnpm generate
```
Locally preview production build:
```bash
pnpm preview
```
Check out the [deployment documentation](https://nuxt.com/docs/getting-started/deployment) for more information.
## License
MIT
## Star History
[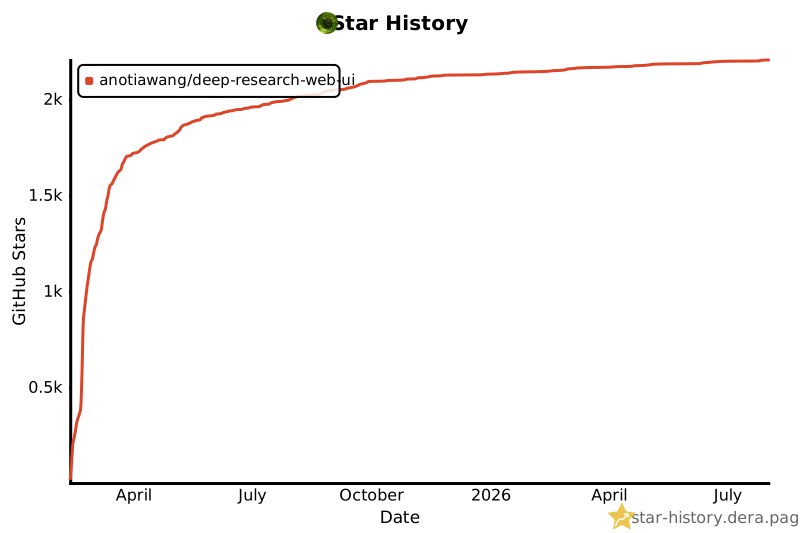](https://star-history.dera.page/#AnotiaWang/deep-research-web-ui&Date)
## Acknowledgements
The project is also hosted on [AtomGit](https://atomgit.com/AnotiaWang/deep-research-web-ui), which is more accessible from mainland China. Thanks to AtomGit for the hosting.