# RSCC
**RSCC: A Large-Scale Remote Sensing Change Caption Dataset for Disaster Events**
Zhenyuan Chen, Chenxi Wang, Ningyu Zhang, Feng Zhang
Zhejiang University
_Accepted by NeurIPS 2025 Datasets and Benchmarks Track_

 > [!IMPORTANT]
> We found a great number of people are encountering the issue of accessing to our RSCC subset (see Issue [#6](https://github.com/Bili-Sakura/RSCC/issues/6)). Therefore, we release this subset via GoogleDrive, you can download from this [link](https://drive.google.com/file/d/1ZZ6_pN2Z9V-pDKVFfMs5uL5Xef96Tmiv/view?usp=sharing).
> [!WARNING]
> The user should strictly obey the [xBD License](https://www.xview2.org/). Also, we (RSCC Team) highlight the distribution of this subset data is for research purpose only. We will take down it if any copyright issue concerned.
## Overview
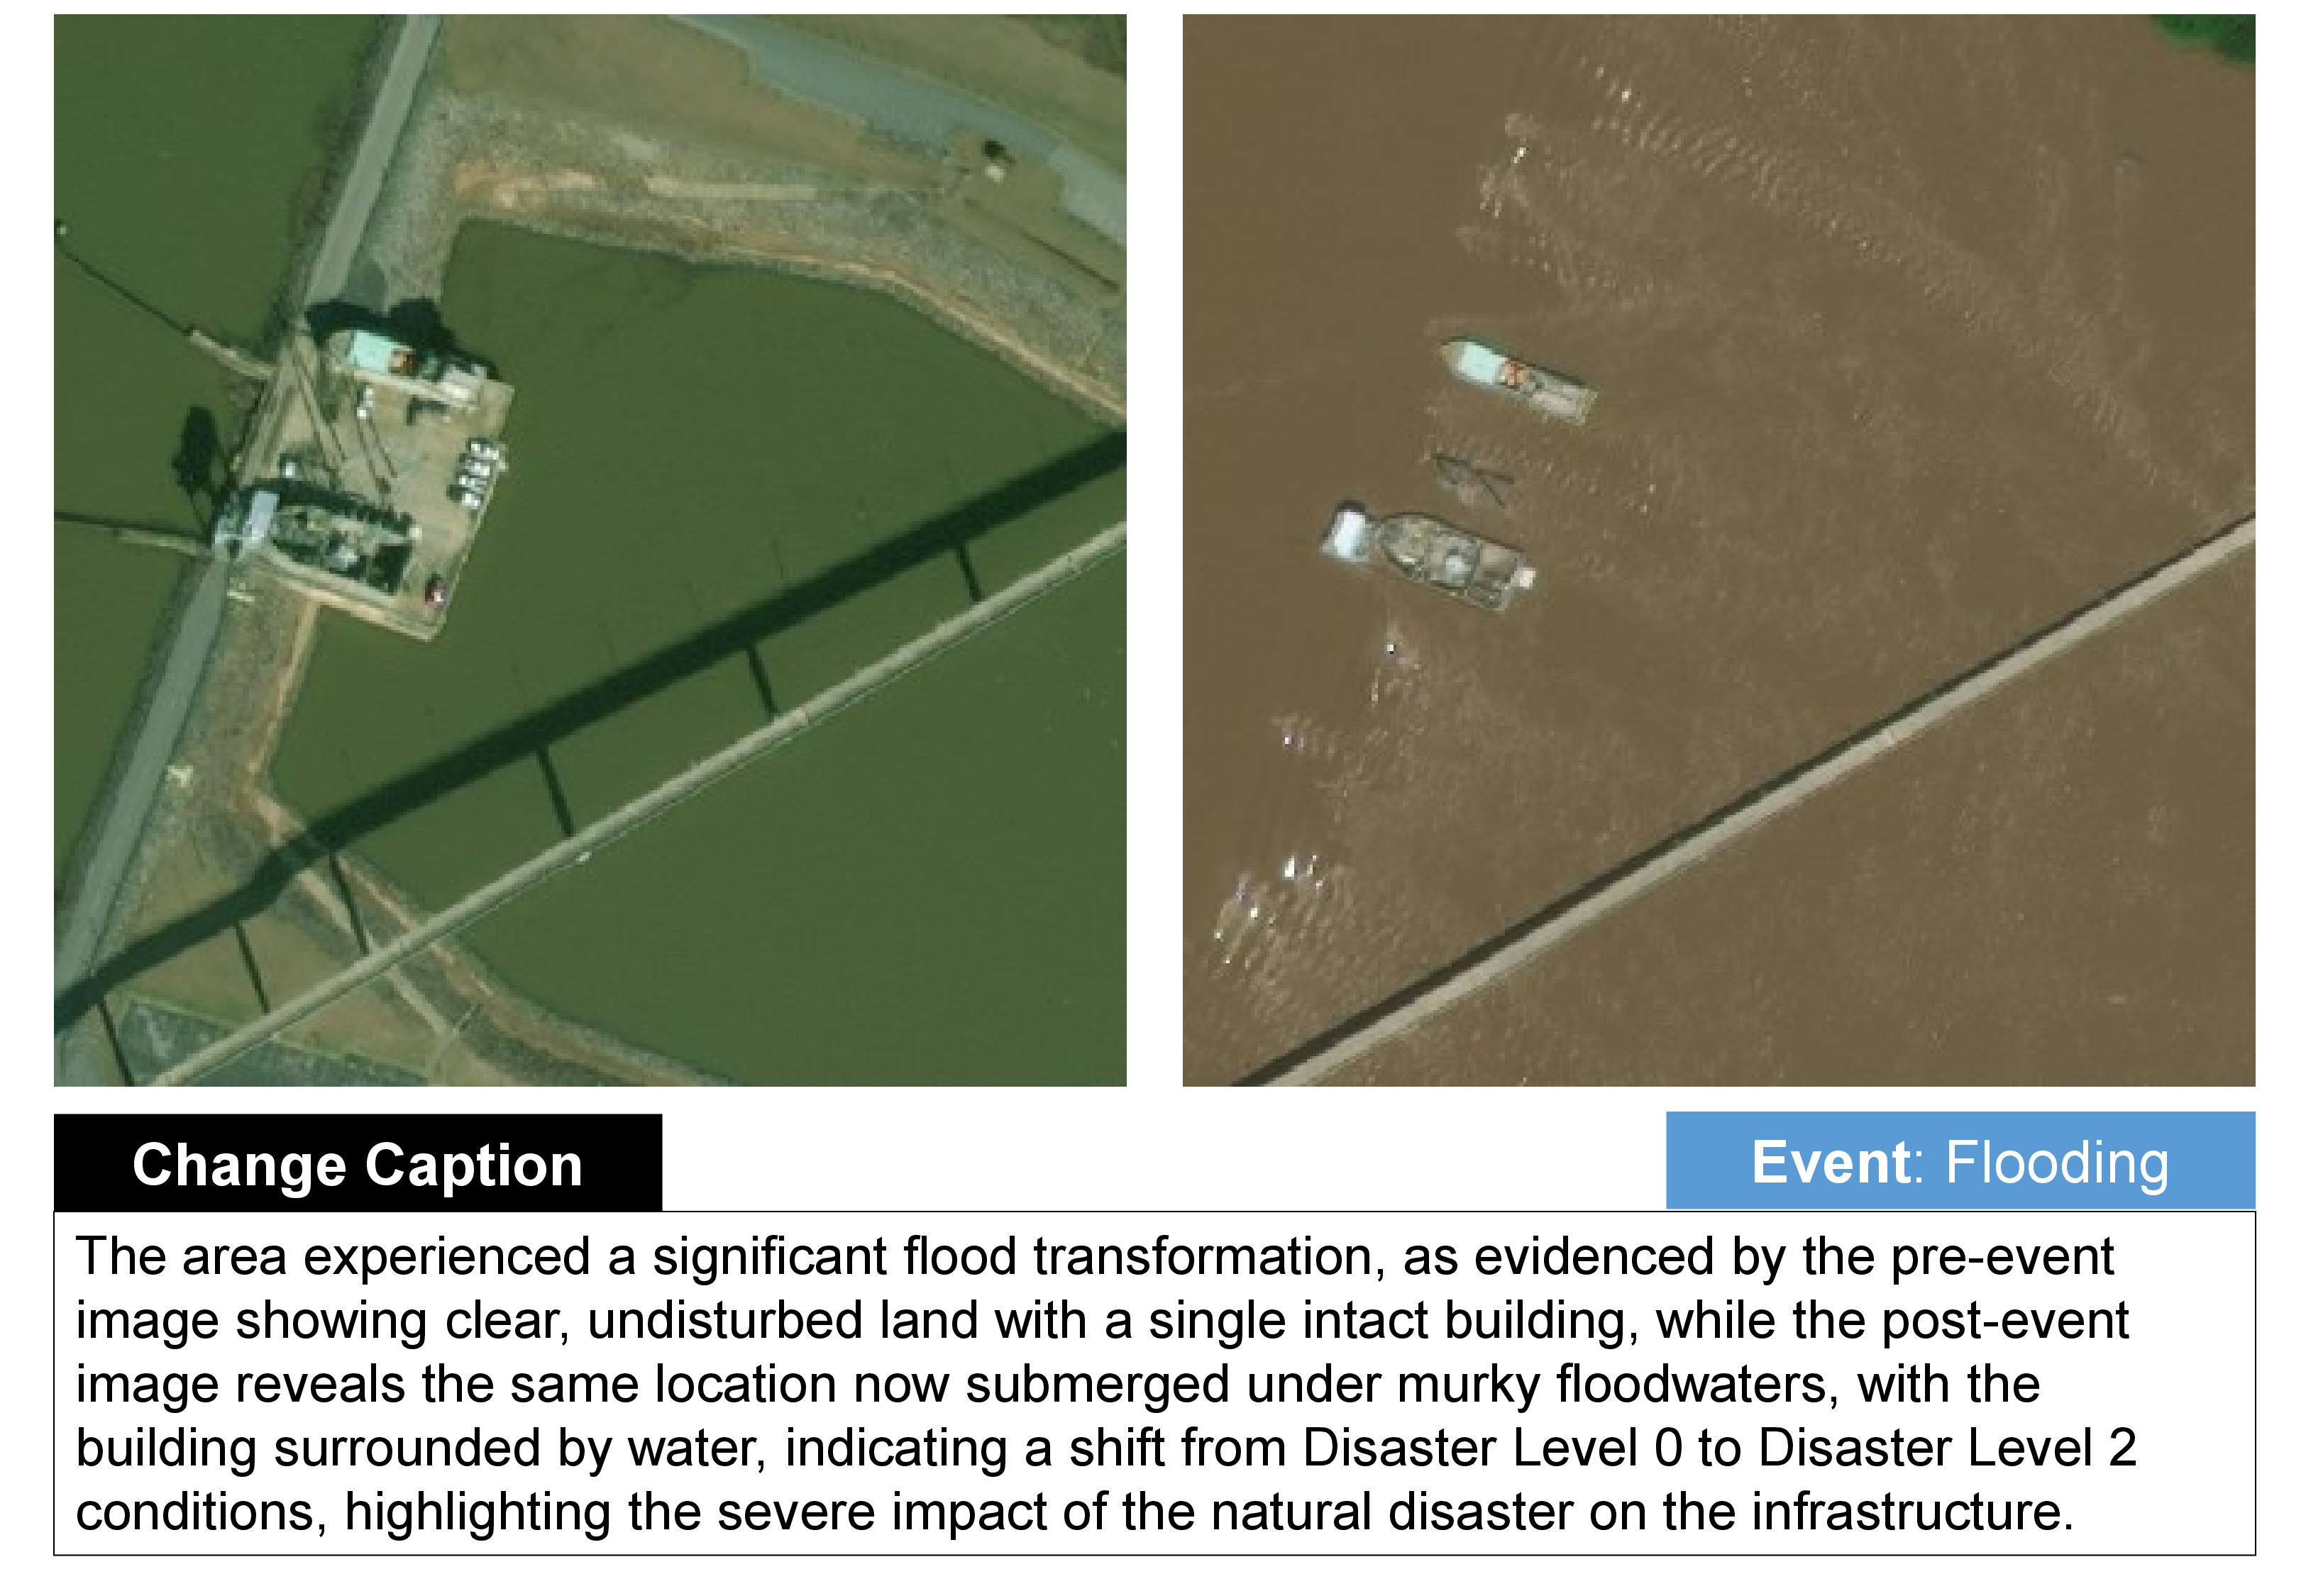
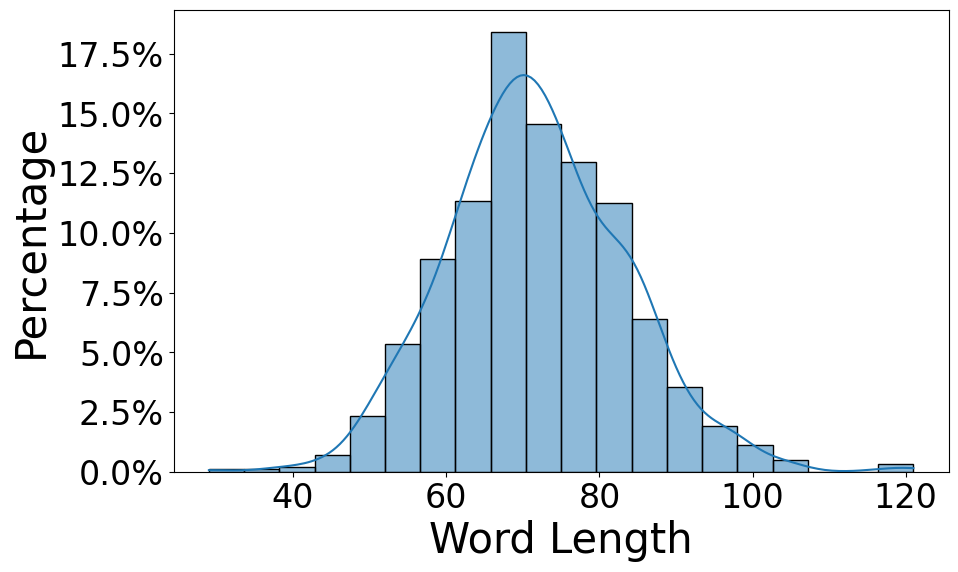
We introduce the Remote Sensing Change Caption (RSCC) dataset, a new benchmark designed to advance the development of large vision-language models for remote sensing. Existing image-text datasets typically rely on single-snapshot imagery and lack the temporal detail crucial for Earth observation tasks. By providing 62,351 pairs of pre-event and post-event images accompanied by detailed change captions, RSCC bridges this gap and enables robust disaster-awareness bi-temporal understanding. We demonstrate its utility through comprehensive experiments using interleaved multimodal large language models. Our results highlight RSCC’s ability to facilitate detailed disaster-related analysis, paving the way for more accurate, interpretable, and scalable vision-language applications in remote sensing.
## 📢News
**[NEWS]** We release RSCC subset on GoogleDrive for research purpose only.
**[NEWS]** 🎉 2025/09/19: Our paper "RSCC: A Large-Scale Remote Sensing Change Caption Dataset for Disaster Events" has been accepted by NeurIPS 2025 Datasets and Benchmarks Track!
**[COMPLETED]** Release RSCC dataset
- [x] 2025/05/01 All pre-event & post-event images of RSCC (total: 62,351 pairs) are released.
- [x] 2025/05/01 The change captions of RSCC-Subset (988 pairs) are released, including 10 baseline model results and QvQ-Max results (ground truth).
- [x] 2025/05/01 The change captions based on Qwen2.5-VL-72B-Instruct of RSCC (total: 62,351 pairs) are released.
- [x] 2025/09/09 Release RSCC change captions based on strong models (e.g., QvQ-Max, o3).
**[COMPLETED]** Release code for inference
- [x] 2025/05/01 Naive inference with baseline models.
- [x] 2025/05/15 Training-free method augmentation (e.g., VCD, DoLa, DeCo).
**[COMPLETED]** Release RSCCM training scripts
**[COMPLETED]** Release code for evaluation
- [x] 2025/05/01 Metrics for N-Gram (e.g. BLEU, METEOR, ROUGE).
- [x] 2025/05/01 Metrics for contextual similarity (e.g. Sentence-T5 Similarity, BERTScore).
- [x] 2025/05/01 Auto comparison of change captions using QvQ-Max (visual reasoning VLM) as a judge.
## Dataset
The dataset can be downloaded from [Huggingface](https://huggingface.co/datasets/BiliSakura/RSCC).
## Benchmark Results
| Model | N-Gram | N-Gram | Contextual Similarity | Contextual Similarity | Avg_L |
| --------------------------------------------------- | ---------------------------------------------------- | ----------------------------------------------------- | ---------------------------------------------------- | ---------------------------------------------------- | ------------------------------------- |
| (#Activate Params) | ROUGE(%)↑ | METEOR(%)↑ | BERT(%)↑ | ST5-SCS(%)↑ | (#Words) |
| BLIP-3 (3B) | 4.53 | 10.85 | 98.83 | 44.05 | \*456 |
| + Textual Prompt | 10.07 (+5.54↑) | 20.69 (+9.84↑) | 98.95 (+0.12↑) | 63.67 (+19.62↑) | \*302 |
| + Visual Prompt | 8.45 (-1.62↓) | 19.18 (-1.51↓) | 99.01 (+0.06↑) | 68.34 (+4.67↑) | \*354 |
| Kimi-VL (3B) | 12.47 | 16.95 | 98.83 | 51.35 | 87 |
| + Textual Prompt | 16.83 (+4.36↑) | 25.47 (+8.52↑) | 99.22 (+0.39↑) | 70.75 (+19.40↑) | 108 |
| + Visual Prompt | 16.83 (+0.00) | 25.39 (-0.08↓) | 99.30 (+0.08↑) | 69.97 (-0.78↓) | 109 |
| Phi-4-Multimodal (4B) | 4.09 | 1.45 | 98.60 | 34.55 | 7 |
| + Textual Prompt | 17.08 (+13.00↑) | 19.70 (+18.25↑) | 98.93 (+0.33↑) | 67.62 (+33.07↑) | 75 |
| + Visual Prompt | 17.05 (-0.03↓) | 19.09 (-0.61↓) | 98.90 (-0.03↓) | 66.69 (-0.93↓) | 70 |
| Qwen2-VL (7B) | 11.02 | 9.95 | 99.11 | 45.55 | 42 |
| + Textual Prompt | 19.04 (+8.02↑) | 25.20 (+15.25↑) | 99.01 (-0.10↓) | 72.65 (+27.10↑) | 84 |
| + Visual Prompt | 18.43 (-0.61↓) | 25.03 (-0.17↓) | 99.03 (+0.02↑) | 72.89 (+0.24↑) | 88 |
| LLaVA-NeXT-Interleave (8B) | 12.51 | 13.29 | 99.11 | 46.99 | 57 |
| + Textual Prompt | 16.09 (+3.58↑) | 20.73 (+7.44↑) | 99.22 (+0.11↑) | 62.60 (+15.61↑) | 75 |
| + Visual Prompt | 15.76 (-0.33↓) | 21.17 (+0.44↑) | 99.24 (+0.02↑) | 65.75 (+3.15↑) | 88 |
| LLaVA-OneVision (8B) | 8.40 | 10.97 | 98.64 | 46.15 | \*221 |
| + Textual Prompt | 11.15 (+2.75↑) | 19.09 (+8.12↑) | 98.85 (+0.21↑) | 70.08 (+23.93↑) | \*285 |
| + Visual Prompt | 10.68 (-0.47↓) | 18.27 (-0.82↓) | 98.79 (-0.06↓) | 69.34 (-0.74↓) | \*290 |
| InternVL 3 (8B) | 12.76 | 15.77 | 99.31 | 51.84 | 64 |
| + Textual Prompt | _19.81_ (+7.05↑) | _28.51_ (+12.74↑) | **99.55** (+0.24↑) | 78.57 (+26.73↑) | 81 |
| + Visual Prompt | 19.70 (-0.11↓) | 28.46 (-0.05↓) | 99.51 (-0.04↓) | **79.18** (+0.61↑) | 84 |
| Pixtral (12B) | 12.34 | 15.94 | 99.34 | 49.36 | 70 |
| + Textual Prompt | **19.87** (+7.53↑) | **29.01** (+13.07↑) | 99.51 (+0.17↑) | _79.07_ (+29.71↑) | 97 |
| + Visual Prompt | 19.03 (-0.84↓) | 28.44 (-0.57↓) | _99.52_ (+0.01↑) | 78.71 (-0.36↓) | 102 |
| CCExpert (7B) | 7.61 | 4.32 | 99.17 | 40.81 | 12 |
| + Textual Prompt | 8.71 (+1.10↑) | 5.35 (+1.03↑) | 99.23 (+0.06↑) | 47.13 (+6.32↑) | 14 |
| + Visual Prompt | 8.84 (+0.13↑) | 5.41 (+0.06↑) | 99.23 (+0.00) | 46.58 (-0.55↓) | 14 |
| TEOChat (7B) | 7.86 | 5.77 | 98.99 | 52.64 | 15 |
| + Textual Prompt | 11.81 (+3.95↑) | 10.24 (+4.47↑) | 99.12 (+0.13↑) | 61.73 (+9.09↑) | 22 |
| + Visual Prompt | 11.55 (-0.26↓) | 10.04 (-0.20↓) | 99.09 (-0.03↓) | 62.53 (+0.80↑) | 22 |
## Inference
### Environment Setup
```bash
cd RSCC # path of project root
conda env create -f environment.yaml # genai: env for most baseline models
conda env create -f environment_teochat.yaml # teohat: env for TEOChat
conda env create -f environment_ccexpert.yaml # CCExpert: env for CCExpert
```
### Prepare Pre-trainined Models and Dataset
> [!NOTE]
> As transformers.model_utils `from_pretrained` function would automatically download pre-trained models from huggingface.co, there is the case that you do not have internet connection and would like to use local pre-trained model folder.
We use the same style as [huggingface.co](https://huggingface.co) as `repo_id/model_id`. The model folder should be structured as below:
Show Structure
```text
/path/to/model/folder/
├── moonshotai/
│ └── Kimi-VL-A3B-Instruct/
├── Qwen/
│ └── Qwen2-VL-7B-Instruct/
├── Salesforce/
│ └── xgen-mm-phi3-mini-instruct-interleave-r-v1.5/
├── microsoft/
│ └── Phi-4-multimodal-instruct/
├── OpenGVLab/
│ └── InternVL3-8B/
├── llava-hf/
│ ├── llava-interleave-qwen-7b-hf/
│ └── llava-onevision-qwen2-7b-ov-hf/
├── mistralai/
│ └── Pixtral-12B-2409/
├── Meize0729/
│ └── CCExpert_7b/
└── jirvin16/
└── TEOChat/
```
> [!NOTE]
> When inferencing with BLIP-3 (xgen-mm-phi3-mini-instruct-interleave-r-v1.5) and CCExpert, you may need to pre-download `google/siglip-so400m-patch14-384` under the model folder.
>
> When inference with TEOChat, you may need to pre-download:
>
> - `LanguageBind/LanguageBind_Image`
> - (Optionally) `LanguageBind/LanguageBind_Video_merge`
>
> Then set in TEOChat's `configs.json`:
>
> ```json
> {
> "mm_image_tower": "/path/to/model/folder/LanguageBind/LanguageBind_Image",
> "mm_video_tower": "/path/to/model/folder/LanguageBind/LanguageBind_Video_merge"
> }
> ```
Download RSCC dataset and place them under your dataset folder:
```text
/path/to/dataset/folder
├── EBD/
│ └── {events}/
├── xbd/
│ └── images-w512-h512/
│ └── {events}/
└── xbdsubset/
└── {events}/
```
Set global variable for `PATH_TO_MODEL_FOLDER` and `PATH_TO_DATASET_FOLDER`.
```python
# `RSCC/utils/constants.py`
PATH_TO_MODEL_FOLDER = /path/to/model/folder/ # "/home/models"
PATH_TO_DATASET_FOLDER = /path/to/dataset/folder # "/home/datasets"
```
### Inference
0. Inference with QvQ-Max
- Set api configs under `RSCC/.env`.
```env
# API key for DashScope (keep this secret!)
DASHSCOPE_API_KEY="sk-xxxxxxxxxx"
# Model ID should match the official code
QVQ_MODEL_NAME="qvq-max-2025-03-25"
# API base URL
API_BASE_URL="https://dashscope.aliyuncs.com/compatible-mode/v1"
# Maximum concurrent workers
MAX_WORKERS=30
# Token threshold warning level
TOKEN_THRESHOLD=10000
```
- Run the script.
```python
conda activate genai
python ./inference/xbd_subset_qvq.py
```
1. Inference with baseline models
> [!WARNING]
> We support multi-GPUs inference while the Pixtral model and CCExpert model should only be runned on cuda:0.
```python
# inference/xbd_subset_baseline.py
...existing codes...
INFERENCE_MODEL_LIST = [
"moonshotai/Kimi-VL-A3B-Instruct",
"Qwen/Qwen2-VL-7B-Instruct",
"Salesforce/xgen-mm-phi3-mini-instruct-interleave-r-v1.5",
"microsoft/Phi-4-multimodal-instruct",
"OpenGVLab/InternVL3-8B",
"llava-hf/llava-interleave-qwen-7b-hf",
"llava-hf/llava-onevision-qwen2-7b-ov-hf",
"mistralai/Pixtral-12B-2409",
# "Meize0729/CCExpert_7b", # omit
# "jirvin16/TEOChat", # omit
]
```
```python
conda activate genai
python ./inference/xbd_subset_baseline.py
# or you can speficy the output file path, log file path and device
python ./inference/xbd_subset_baseline.py --output_file "./output/xbd_subset_baseline.jsonl" --log_file "./logs/xbd_subset_baseline.log" --device "cuda:0"
```
2. Inference with TEOChat
> [!NOTE]
> The baseline models and specialized model (i.e. TEOChat, CCExpert) use different env. You should use the correspond env along with model_list
```python
# inference/xbd_subset_baseline.py
...existing codes...
INFERENCE_MODEL_LIST = [ "jirvin16/TEOChat"]
```
```bash
conda activate teochat
python ./inference/xbd_subset_baseline.py
# or you can speficy the output file path, log file path and device
```
3. Inference with CCExpert
> [!NOTE]
> The baseline models and specialized model (i.e. TEOChat, CCExpert) use different env. You should use the correspond env along with model_list
```python
# inference/xbd_subset_baseline.py
...existing codes...
INFERENCE_MODEL_LIST = [ "Meize0729/CCExpert_7b"]
```
```bash
conda activate CCExpert
python ./inference/xbd_subset_baseline.py
```
### Inference with Correction Decoding
```bash
python ./inference_with_cd/inference_baseline_cd.py
```
## Evaluation
### Prepare Pre-trained Models
```text
/path/to/model/folder
├── sentence-transformers/ # used for STS-SCS metric
│ └── sentence-t5-xxl/ # or use `sentence-t5-base` for faster evaluation
└── FacebookAI/ # used for BERTSCORE metric
└── roberta-large/ # or use `roberta-base` for faster evaluation
```
### Run Metrics
We calcuate BLEU, ROUGE, METEOR, BERTSCORE and Sentence-T5 Embedding Similarity for change captions between ground truth and other generated by baseline models.
> [!NOTE]
> As we are using [huggingface/evaluate](https://github.com/huggingface/evaluate), you need have connection to [huggingface.co](https://huggingface.co) to get scripts and related source of metrics (e.g. BLEU, ROUGE and METEOR).
```bash
conda activate genai
python ./evaluation/metrics.py \
--ground_truth_file ./output/xbd_subset_qvq.jsonl \
--predictions_file ./output/xbd_subset_baseline.jsonl > ./logs/eval.log
```
### Fine-tuning RSCCM
```bash
cd RSCC
conda env create -f environment_qwenvl_ft.yaml
conda activate qwenvl_ft
bash train/qwen-vl-finetune/scripts/sft_for_rscc_model.sh
```
### Auto Comparison with MLLMs (e.g. Qwen QvQ-Max)
We provide scripts that employ the latest visual reasoning proprietary model (QvQ-Max) to choose the best change caption from a series of candidates.
Show Steps
1. Set api configs under `RSCC/.env`.
```env
# API key for DashScope (keep this secret!)
DASHSCOPE_API_KEY="sk-xxxxxxxxxx"
# Model ID should match the official code
QVQ_MODEL_NAME="qvq-max-2025-03-25"
# API base URL
API_BASE_URL="https://dashscope.aliyuncs.com/compatible-mode/v1"
# Maximum concurrent workers
MAX_WORKERS=30
# Token threshold warning level
TOKEN_THRESHOLD=10000
```
2. Run the script.
```bash
conda activate genai
python ./evaluation/autoeval.py
```
The token usage is auto logged and you can also check `RSCC/data/token_usage.json` to keep update with remaining token number.
## Licensing Information
The dataset is released under the [CC-BY-4.0](<[https://creativecommons.org/licenses/by-nc/4.0/deed.en](https://creativecommons.org/licenses/by/4.0/deed.en)>), which permits unrestricted use, distribution, and reproduction in any medium, provided the original work is properly cited.
## 🙏 Acknowledgement
Our RSCC dataset is built based on [xBD](https://www.xview2.org/) and [EBD](https://figshare.com/articles/figure/An_Extended_Building_Damage_EBD_dataset_constructed_from_disaster-related_bi-temporal_remote_sensing_images_/25285009) datasets.
We are thankful to [Kimi-VL](https://hf-mirror.com/moonshotai/Kimi-VL-A3B-Instruct), [BLIP-3](https://hf-mirror.com/Salesforce/xgen-mm-phi3-mini-instruct-interleave-r-v1.5), [Phi-4-Multimodal](https://hf-mirror.com/microsoft/Phi-4-multimodal-instruct), [Qwen2-VL](https://hf-mirror.com/Qwen/Qwen2-VL-7B-Instruct), [Qwen2.5-VL](https://hf-mirror.com/Qwen/Qwen2.5-VL-72B-Instruct), [LLaVA-NeXT-Interleave](https://hf-mirror.com/llava-hf/llava-interleave-qwen-7b-hf),[LLaVA-OneVision](https://hf-mirror.com/llava-hf/llava-onevision-qwen2-7b-ov-hf), [InternVL 3](https://hf-mirror.com/OpenGVLab/InternVL3-8B), [Pixtral](https://hf-mirror.com/mistralai/Pixtral-12B-2409), [TEOChat](https://github.com/ermongroup/TEOChat) and [CCExpert](https://github.com/Meize0729/CCExpert) for releasing their models and code as open-source contributions.
The metrics implements are derived from [huggingface/evaluate](https://github.com/huggingface/evaluate).
The training implements are derived from [QwenLM/Qwen2.5-VL](https://github.com/QwenLM/Qwen2.5-VL).
## 📜 Citation
```bibtex
@misc{chen2025rscclargescaleremotesensing,
title={RSCC: A Large-Scale Remote Sensing Change Caption Dataset for Disaster Events},
author={Zhenyuan Chen and Chenxi Wang and Ningyu Zhang and Feng Zhang},
year={2025},
eprint={2509.01907},
archivePrefix={arXiv},
primaryClass={cs.CV},
url={https://arxiv.org/abs/2509.01907},
}
```