## Updates & News
- [18/10/2024] We release the benchmark code.
- [16/06/2024] 📄 Paper on [arxiv](https://arxiv.org/abs/2406.10819) has released!
## Contents
- [Updates \& News](#updates--news)
- [Contents](#contents)
- [Dataset: GUI-World](#dataset-gui-world)
- [Overview](#overview)
- [How to use GUI-World](#how-to-use-gui-world)
- [Case Studies](#case-studies)
- [Evaluation](#evaluation)
- [GUI-Vid: A GUI-Oriented VideoLLM](#gui-vid-a-gui-oriented-videollm)
- [Contribution](#contribution)
- [Acknowledgments](#acknowledgments)
- [Citation](#citation)
## Dataset: GUI-World
### Overview
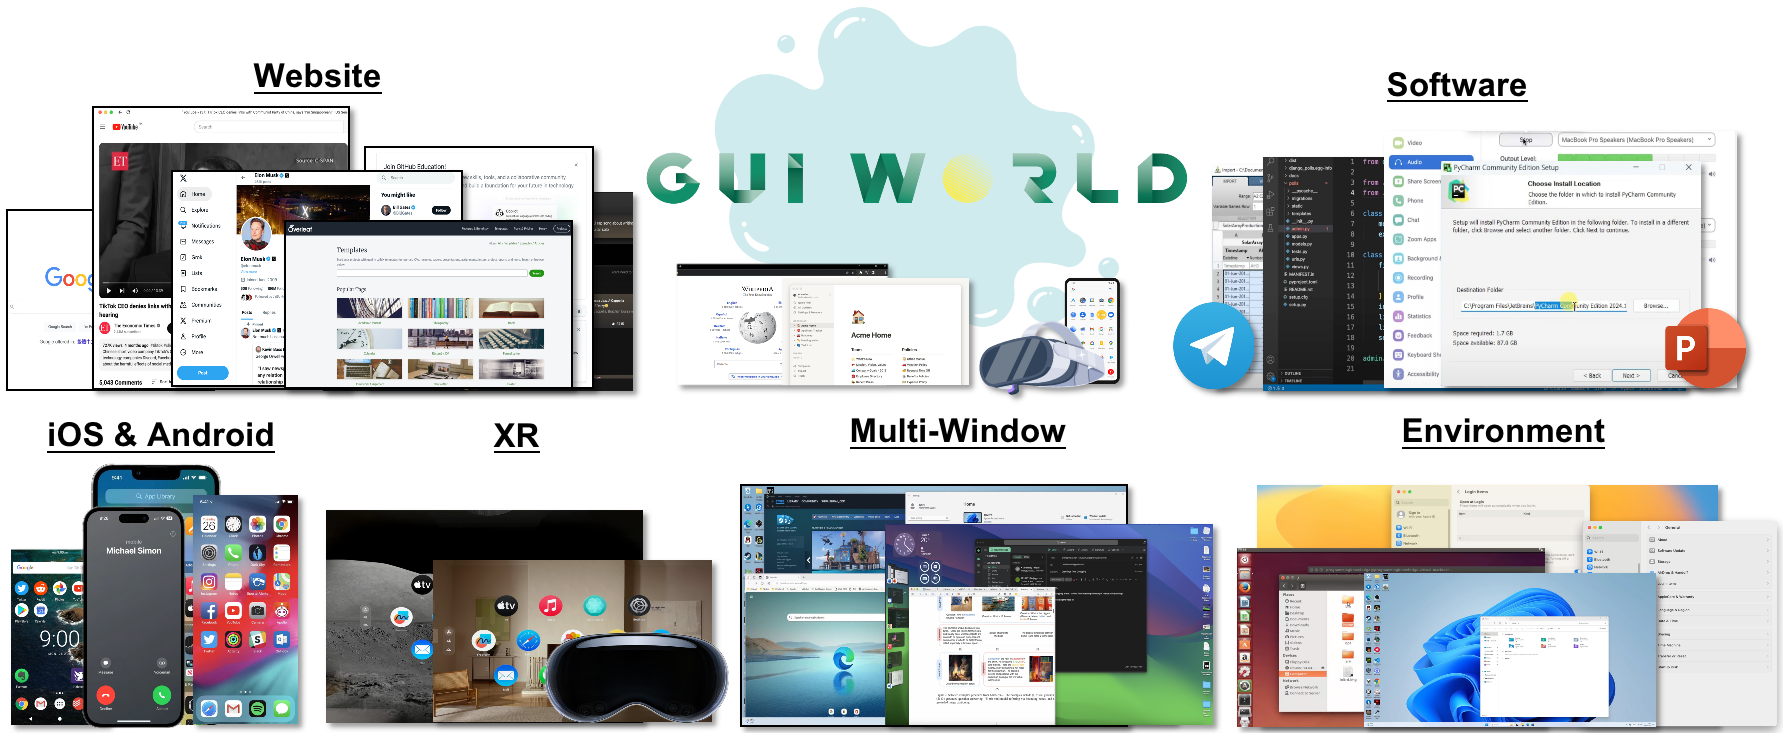
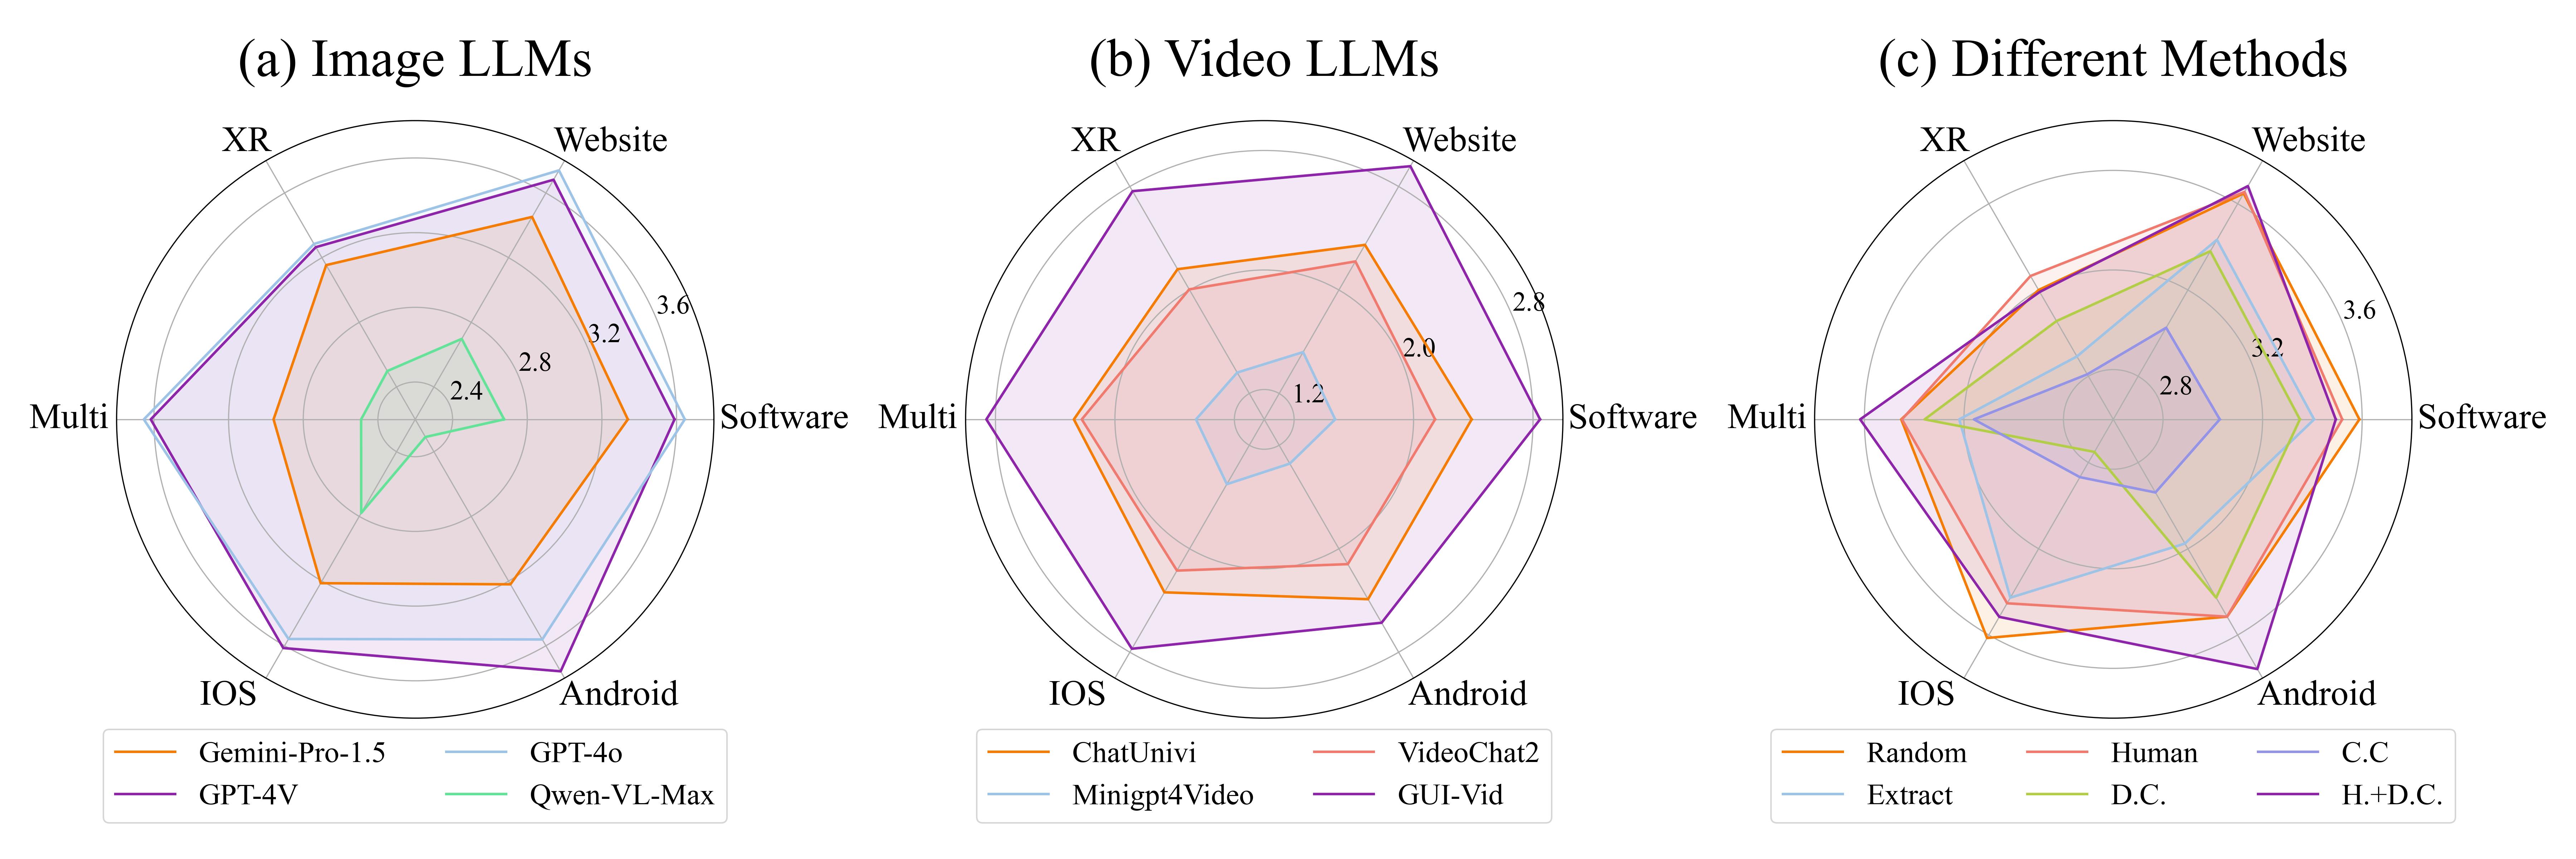
GUI-World introduces a comprehensive benchmark for evaluating MLLMs in dynamic and complex GUI environments. It features extensive annotations covering six GUI scenarios and eight types of GUI-oriented questions. The dataset assesses state-of-the-art ImageLLMs and VideoLLMs, highlighting their limitations in handling dynamic and multi-step tasks. It provides valuable insights and a foundation for future research in enhancing the understanding and interaction capabilities of MLLMs with dynamic GUI content. This dataset aims to advance the development of robust GUI agents capable of perceiving and interacting with both static and dynamic GUI elements.
### How to use GUI-World
GUI-World is split into train and test sets, available from the canonical
[ONE-Lab/GUI-World dataset](https://huggingface.co/datasets/ONE-Lab/GUI-World).
## Case Studies
Six complete examples are available in [`case_studies/`](case_studies/), with
normalized annotations, videos, and annotated frame images for Android, iOS,
multi-application, software, website, and XR scenarios.
## Evaluation
The maintained [evaluation guide](evaluation/README.md) covers dataset
download, supported providers, benchmark inference, LLM judging, resume
behavior, result schemas, and offline tests.
## GUI-Vid: A GUI-Oriented VideoLLM
GUI-Vid is a VideoLLM finetuned from [Videochat2](https://github.com/OpenGVLab/Ask-Anything). You can reproduce our experiment results following these instructions:
**Prepare the Environment**
```shell
git clone https://github.com/Dongping-Chen/GUI-World.git
cd GUI-World/GUI_Vid
conda create -n gui python=3.9
conda activate gui
pip install -r requirements.txt
```
**GUI-Oriented Finetuning**
- Download the [GUI-World dataset](https://huggingface.co/datasets/ONE-Lab/GUI-World) and modify the root path in `GUI_Vid/configs/instruction_data.py`, which is the root dir for your downloaded GUI-World data.
- Set `vit_blip_model_path`, `llama_model_path` and `videochat2_model_path` in `GUI_Vid/scripts/config_7b_stage3.py`, these checkpoints can be download from [GUI-Vid](https://huggingface.co/shuaishuaicdp/GUI-Vid).
```shell
# Vicuna
bash GUI_Vid/scripts/run_7b_stage3.sh
```
**Inference with GUI-Vid**
You can first download checkpoint from [Huggingface](https://huggingface.co/shuaishuaicdp/GUI-Vid). You also need to set the config according to the guidance in [Videochat2](https://github.com/OpenGVLab/Ask-Anything/tree/main/video_chat2).
Then, set the `model_path` in `scripts/demo_local.py`. Use the following script to inference a GUI video:
```shell
python demo_local.py \
--ckpt_path \
--keyframe 8 \
--video_path \
--qs
```
### How our video identifier works?
In our paper, we use five settings to extract keyframes in video. For `Human` and `Linspace` (we employed uniform sampling to select 10 frames from each video, maintaining equal intervals between frames. This is the previous `Random` setting and we now use `Linspace` replacing it to avoid confusion), you can refer to the original file of our annotation and perform it by `np.linspace`. For `Program`, we use [Katna](https://github.com/keplerlab/katna) to extract keyframes and our code is in `GUI_Vid/scripts/katna.py`. For [VIP](https://github.com/facebookresearch/vip) and [R3M](https://github.com/facebookresearch/r3m) based on [UVD](https://github.com/zcczhang/UVD), which are additional experiments in [NeurIPS Rebuttal](https://openreview.net/forum?id=h8LuywKj6N¬eId=IG1slwXfWC), we extract keyframes locally and you can download them from [this link](https://1drv.ms/u/c/32f66c0c65d8cc2b/EUkoaMigq6hAg3GQx54pEz8BG6FMgXohIfnJ1MB5H092Rw?e=p7exRF).
## Contribution
Contributions to this project are welcome. Please consider the following ways to contribute:
- Proposing new features or improvements
- Benchmark other mainstream MLLMs
## Acknowledgments
Many thanks to Yinuo Liu, Zhengyan Fu, Shilin Zhang, Yu, Tianhe Gu, Haokuan Yuan, and Junqi Wang for their invalueble effort in this project. This project is based on methodologies and code presented in [Videochat2](https://github.com/OpenGVLab/Ask-Anything).
## Citation
```
@article{chen2024gui,
title={GUI-WORLD: A Dataset for GUI-oriented Multimodal LLM-based Agents},
author={Chen, Dongping and Huang, Yue and Wu, Siyuan and Tang, Jingyu and Chen, Liuyi and Bai, Yilin and He, Zhigang and Wang, Chenlong and Zhou, Huichi and Li, Yiqiang and others},
journal={arXiv preprint arXiv:2406.10819},
year={2024}
}
```
 GUI-World: A Dataset for GUI-Orientated Multimodal Large Language Models
[](https://arxiv.org/abs/2406.10819) [](https://huggingface.co/datasets/ONE-Lab/GUI-World) [](https://gui-world.github.io/)