# 📘 Awesome AI Engineering
[](https://creativecommons.org/licenses/by/4.0/)
### The Full-Stack AI Engineering Playbook
A practical, systems-level guide to building production AI systems
and agentic applications — from core infrastructure to deployment,
security, and evaluation. For a deep dive into the research frontier,
explore the [📖 LLM Technology Landscape & Evolution](https://github.com/Eric-LLMs/LLMs-Lab/tree/main/Docs)
— a curated reading list covering the full LLM stack, from model architectures
and training, fine-tuning, inference optimization, reasoning, and agent systems.
## 🗺️ AI Engineering: End-to-End Architecture
A system-level view of AI engineering — from compute and data infrastructure, through model development, inference, tools, memory, and agent orchestration, to production applications, evaluation, security, and continuous improvement.
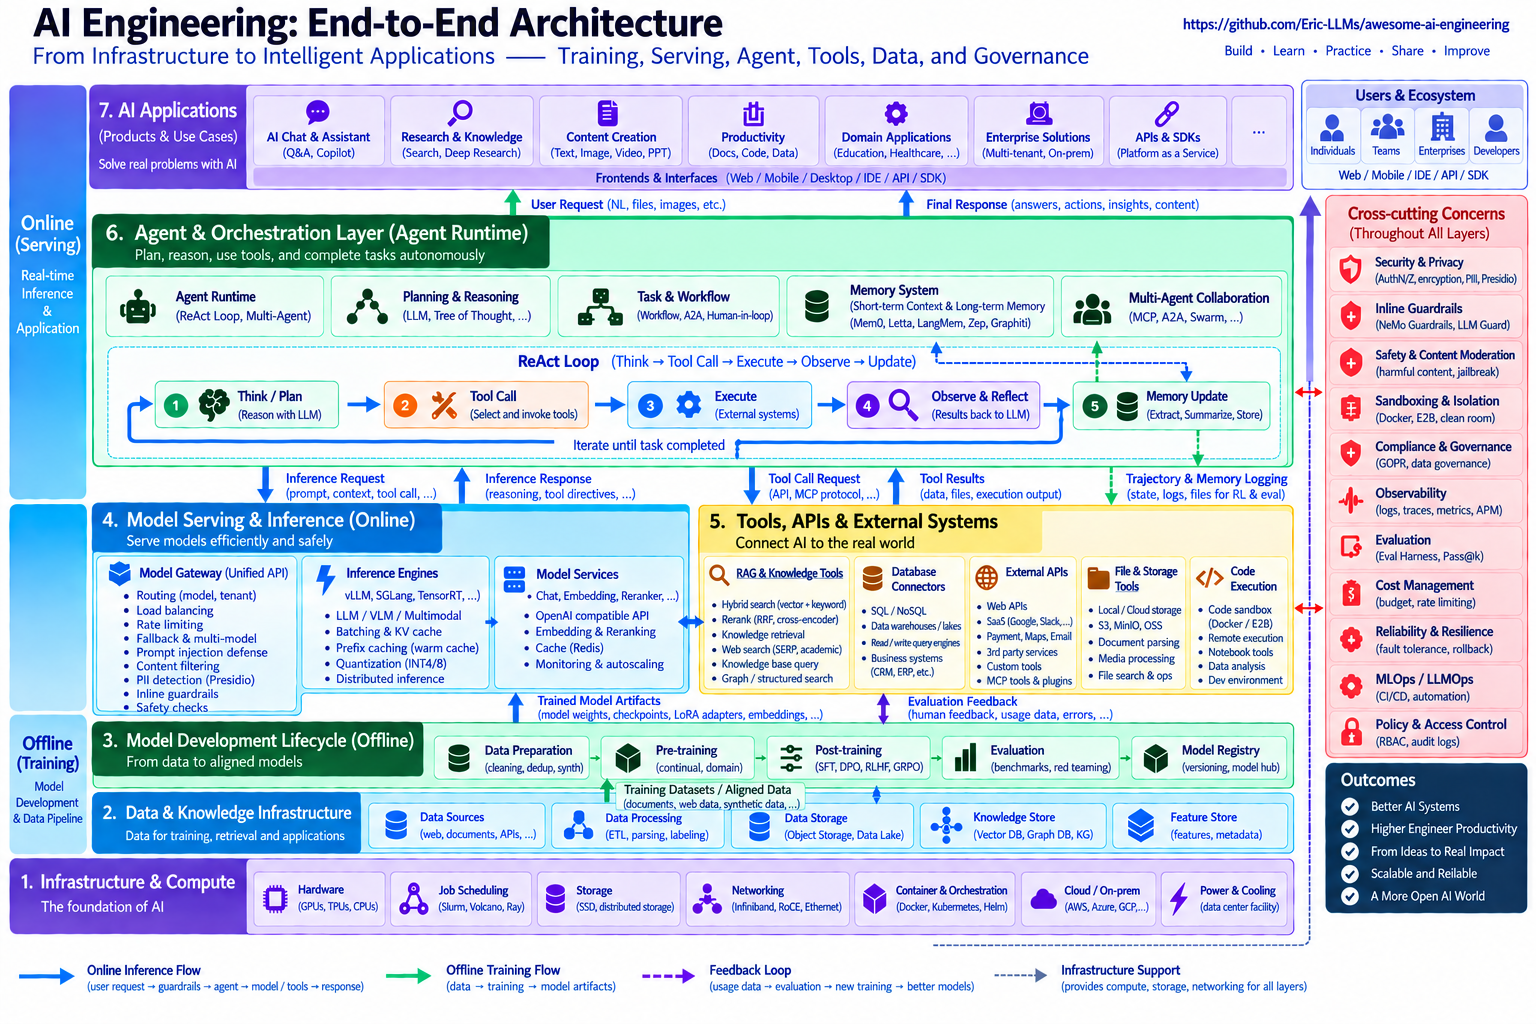
> This architecture is a conceptual map of the AI engineering stack, not a
> prescriptive runtime topology. It separates offline model development from
> online serving while showing the main interaction and feedback loops across
> the system.
## 📑 Table of Contents
| 📚 Content | 🔗 Quick Link |
|:----------------------------------------------------------------------|:--------------------------------------------------------------|
| Building LLMs for Production | [🔍 Explore](#building-llms-for-production) |
| Building High-Performance, Private AI Infrastructure for the Enterprise | [🔍 Explore](#high-performance-private-ai-infrastructure) |
| Building AI Agents | [🔍 Explore](#building-ai-agents) |
| Mastering the Model Context Protocol (MCP) | [🔍 Explore](#mastering-the-model-context-protocol) |
| Agent Memory Part I (A Survey of Memory) | [🔍 Explore](#agent-memory-part-i) |
| Agent Memory Part II (Building Memory Modules for Agentic AI Systems) | [🔍 Explore](#building-memory-modules-for-agentic-ai-Systems) |
| Agent Evaluation (Eval) Engineering | [🔍 Explore](#agent-eval) |
---
# 📚 Building LLMs for Production
This guide covers LLM production, from Transformer architectures to advanced techniques like RAG and Fine-Tuning. It explores frameworks like LangChain, methods to mitigate hallucinations, and optimization via quantization. Learn to build autonomous agents for real-world use.
### 🔑 Mind Map (Key Concepts)
[📥 **Download High-Resolution Mind Map** (.jpg)](https://raw.githubusercontent.com/Eric-LLMs/Awesome-AI-Engineering/main/summaries/building-llms-for-production/building-llms-for-production-mindmap.jpg)
🔍 Click here to unfold the full Mind Map (building-llms-for-production-mindmap.jpg)
(点击展开完整思维导图)
### 📑 Presentation Slides
> 💡 **Tip:** Press `Ctrl` + `Click` (or Command + Click) to open in a new tab.
[📥 View the "Building LLMs for Production" Slides (PDF)](./summaries/building-llms-for-production/building-llms-for-production-slides.pdf)
[📥 **Download PDF** (Direct Link)](https://raw.githubusercontent.com/Eric-LLMs/Awesome-AI-Engineering/main/summaries/building-llms-for-production/building-llms-for-production-slides.pdf)
### 🛠️ Hands-on Lab & Examples
* **[Delveta](https://github.com/Eric-LLMs/Delveta):** Production-grade AI system for personalized learning — agentic tutoring, dual-track memory, hybrid RAG, personal/team cloud storage, and self-hosted LLM infrastructure. Highlights:
- **Config-driven RAG pipeline**: plug-and-play retrieval nodes *(query rewrite → vector + keyword recall → RRF fusion → cross-encoder rerank → parent-expand → relevance check)* that you add / remove / reorder / toggle live from the admin console — no code, no restart; chunking preview, golden-set Eval (Recall@k / Precision@k / MRR), degrade-never-break retrieval, vision-LLM PDF table transcription, a Redis query cache (keyed on query + config + corpus version, auto-invalidated on re-index), and user feedback logged to an eval dataset.
- **Agent kernel**: ReactLoopAgent step loop with long-term dual-track memory (PG tsvector + pgvector via RRF, recency-decay weighted) plus hierarchical history compaction (bounded context, flat token window), a skill catalog, hot-reloadable, dependency-injected plugins, and a read-only sandbox gating every tool call (READ / WRITE / NETWORK).
- **Reliability & human-in-the-loop**: hard timeout + exponential-backoff retry for transient LLM errors, per-turn cost budget, human-approval gate (Redis pub/sub, deny on timeout), plan mode + bounded subagents, shadow-git checkpoints, and a Docker bash sandbox (network-disabled, resource-capped).
- **Layered, cache-friendly prompts & tools**: byte-stable head (identity + one-line tool catalog) + per-step dynamic tail (memory / skills / injected) — warm prefix cache (lower latency & token cost), cache identity measurable; deferred tools — a searchable one-line catalog, matched tools mount as stable stubs, full schemas via the search result.
- **Cloud drive**: private **My Drive** + shared **workspaces** with owner / admin / editor / viewer roles, member management, and an append-only activity log; per-user object store with SHA-256 content-addressing (identical files deduplicate to one ref-counted blob), 8 MB resumable chunked upload, multi-level folders, trash & 30-day retention, per-file ACLs and public links, and in-window previews for PDF / video / audio / Office documents.
- **Permissions & key management**: admin console for roles, users, LLM provider credentials + model catalog + routing weights, a per-user key-grant matrix (masked `sk-***`), SMTP, and stateless signed admin sessions.
- **Local-first & self-hosted**: Electron workbench works offline (file tree, multi-format viewer, video screenshots), big media is processed on the local client, and the whole stack (PostgreSQL/pgvector, Redis, TEI embedding, Kokoro TTS, LiteLLM gateway) runs via docker-compose — your data stays yours.
* **[LLMs-Lab](https://github.com/Eric-LLMs/LLMs-Lab):** Hands-on research and engineering modules covering **Fine-Tuning**, **RAG optimization**, **LangChain**, **Prompt Engineering**, **Function-Calling**, **Agents**, etc. — each explored as a standalone module with multiple project implementations.
[⬆️ Back to Top : Table of Contents](#top)
---
# 📚 Building High-Performance, Private AI Infrastructure for the Enterprise
Covers the full-stack AI infrastructure for the enterprise — AI chips, compute clusters, high-speed networking, distributed training, inference serving, cluster scheduling, and secure private deployment.
### 🛠️ Hands-on Projects & Tools
**I. AI Infrastructure**
* **[AIInfra — AI Infrastructure Reference](https://github.com/Infrasys-AI/AIInfra):** An open-source reference covering the full-stack AI infrastructure for LLMs — from AI chips, compute clusters, and high-speed networking, to distributed training, inference optimization, and deployment — a hands-on resource for building high-performance, private AI infrastructure for the enterprise.
**II. Cluster Scheduling & Orchestration**
* **[Volcano](https://github.com/volcano-sh/volcano):** A Kubernetes-native batch system with advanced GPU scheduling and job queueing — widely adopted for enterprise AI clusters.
* **[KubeRay](https://github.com/ray-project/kuberay):** A Kubernetes operator for running Ray clusters, bridging distributed compute with cloud-native orchestration.
**III. Training & Post-training**
#### Pre-training
* **[DeepSpeed](https://github.com/microsoft/DeepSpeed):** Microsoft's deep learning optimization library — ZeRO memory optimization, mixed precision, and system optimizations for training and fine-tuning models at massive scale.
* **[Megatron-LM](https://github.com/NVIDIA/Megatron-LM):** NVIDIA's large-scale language model training framework — tensor, pipeline, and sequence parallelism, often paired with DeepSpeed for pre-training.
#### Fine-tuning
* **[Unsloth](https://github.com/unslothai/unsloth):** A fast, memory-efficient fine-tuning library — up to 2x faster and 70% less memory for LoRA/QLoRA fine-tuning of LLMs.
* **[LLaMA-Factory](https://github.com/hiyouga/LLaMA-Factory):** A config-driven fine-tuning platform supporting LoRA, QLoRA, and full-parameter tuning across many open LLMs.
* **[HuggingFace PEFT](https://github.com/huggingface/peft):** The standard parameter-efficient fine-tuning library — LoRA, QLoRA, and more — widely used for enterprise model customization.
#### RL / Alignment
* **[veRL](https://github.com/verl-project/verl):** ByteDance Seed's production-grade RL post-training framework — supports PPO, GRPO, DAPO, PRIME, and multi-turn tool-calling agents, with vLLM/SGLang rollout and FSDP/Megatron-LM training backends.
* **[OpenRLHF](https://github.com/OpenRLHF/OpenRLHF):** A high-performance distributed RLHF framework built on Ray, vLLM, and DeepSpeed — supporting PPO, GRPO, REINFORCE++, and multi-turn agent training.
* **[TRL](https://github.com/huggingface/trl):** HuggingFace's official library for RLHF and post-training — the broadest algorithm coverage (SFT, DPO, GRPO, PPO, RLOO) with first-party OpenEnv integration.
* **[ART](https://github.com/OpenPipe/ART):** OpenPipe's Agent Reinforcement Trainer — a lightweight GRPO framework that adds RL training loops (inference → reward → LoRA) to any existing Python application.
**IV. Inference Serving & Deployment**
#### High-performance
* **[vLLM](https://github.com/vllm-project/vllm):** A high-throughput, memory-efficient LLM serving engine (PagedAttention, continuous batching, prefix caching) — the de facto standard for high-performance private inference.
* **[SGLang](https://github.com/sgl-project/sglang):** A fast, structured-generation runtime for LLM inference, complementing vLLM with radix attention and efficient prefix reuse.
#### Lightweight
* **[Ollama](https://github.com/ollama/ollama):** The simplest way to run LLMs locally — a lightweight, self-hosted private deployment option.
* **[LocalAI](https://github.com/mudler/LocalAI):** A local, OpenAI-compatible, self-hosted inference server for private model deployment.
**V. Distributed Computing**
* **[Ray](https://github.com/ray-project/ray):** A unified distributed framework for AI training, inference, and serving at scale.
**VI. Unified Gateway**
* **[Bifrost](https://github.com/maximhq/bifrost):** Open-source AI gateway with an OpenAI-compatible API, multi-provider routing, load balancing, virtual keys, and request logging.
* **[LiteLLM](https://github.com/BerriAI/litellm):** A unified LLM gateway with an OpenAI-compatible API — model routing, rate limits, budgets, and logging for enterprise private deployments.
**VII. Security & Guardrails**
* **[NeMo Guardrails](https://github.com/NVIDIA/NeMo-Guardrails):** NVIDIA's programmable guardrails framework for conversational AI — input, output, and retrieval rails.
* **[LLM Guard](https://github.com/protectai/llm-guard):** Protect AI's input/output security library for detecting prompt injection and sanitizing LLM traffic.
* **[PurpleLlama / Llama Guard](https://github.com/meta-llama/PurpleLlama):** Meta's Llama security toolkit — Llama Guard content-safety classifier and Prompt Guard injection detection.
* **[Garak](https://github.com/NVIDIA/garak):** NVIDIA's LLM vulnerability scanner for automated red-teaming.
* **[Microsoft Presidio](https://github.com/microsoft/presidio):** PII detection and data anonymization for compliance in enterprise AI deployments.
[⬆️ Back to Top : Table of Contents](#top)
---
# 📚 Building AI Agents
### 🔑 Mind Map (Key Concepts)
[📥 **Download High-Resolution Mind Map** (.jpg)](https://raw.githubusercontent.com/Eric-LLMs/Awesome-AI-Engineering/main/summaries/introduction-to-ai-agents/agents-architecture-operations-and-evolution-mindmap.jpg)
🔍 Click here to unfold the full Mind Map (agents-architecture-operations-and-evolution-mindmap.jpg)
(点击展开完整思维导图)
### 📑 Presentation Slides
> 💡 **Tip:** Press `Ctrl` + `Click` (or Command + Click) to open in a new tab.
[📥 View the "Building AI Agents" Slides (PDF)](./summaries/introduction-to-ai-agents/agents-architecture-operations-slides.pdf)
[📥 **Download PDF** (Direct Link)](https://raw.githubusercontent.com/Eric-LLMs/Awesome-AI-Engineering/main/summaries/introduction-to-ai-agents/agents-architecture-operations-slides.pdf)
### 🛠️ Hands-on: A Minimal ReAct Agent
👉 [**A Minimal ReAct Agent**](https://github.com/Eric-LLMs/LLMs-Lab/tree/main/Agent/Agent_Project) — a modular agent project in LLMs-Lab: ReAct reasoning loop with custom tools (Excel/Pandas data analysis, PDF QA, document generation, email).
### 🧰 Key Open-Source Projects & References
The following open-source projects represent prominent examples of agentic AI engineering:
| Project | Description | Key Strengths |
| :--- | :--- | :--- |
| **[Claude Code](https://github.com/anthropics/claude-code)** | Anthropic's official terminal-based agentic coding tool | Agentic coding, terminal-native, full codebase understanding, git workflows |
| **[claurst](https://github.com/Kuberwastaken/claurst)** | Community-maintained reference implementation of Claude Code | Internal architecture study, reverse-engineering insights, codebase structure reference |
| **[OpenAI Codex](https://github.com/openai/codex)** | OpenAI's open-source agentic coding CLI | Agentic coding, terminal-native, sandboxed execution, bash tool use |
| **[Hermes-Agent](https://github.com/NousResearch/hermes-agent)** | Self-improving AI agent with built-in learning loop | Skill creation from experience, cross-session memory, multi-channel (CLI/Telegram/Discord/Slack) |
| **[OpenClaw](https://github.com/openclaw/openclaw)** | Personal AI assistant, local-first, any OS/platform | Local-first Gateway, multi-channel messaging, voice support, session & tool management |
| **[Pi](https://github.com/earendil-works/pi)** | Open-source AI agent toolkit: unified multi-provider LLM API, agent runtime, and an interactive coding agent CLI | Self-extensible coding agent, multi-provider API, terminal UI library, npm supply-chain hardening |
| **[DeepSeek Harness](https://github.com/deepseek-ai/deepseek-harness)** | DeepSeek AI's open-source agent harness with a plugin-driven architecture ("everything is a plugin") | Plugin composability via Cordis, Web UI, monorepo, developer preview |
> These projects showcase diverse agent architectures — from developer-focused coding agents (Claude Code/OpenAI Codex/claurst) to general-purpose personal assistants (OpenClaw) and self-learning agents (Hermes-Agent). Studying their design decisions is valuable for building your own agent systems.
[⬆️ Back to Top : Table of Contents](#top)
---
# 📚 Mastering the Model Context Protocol (MCP)
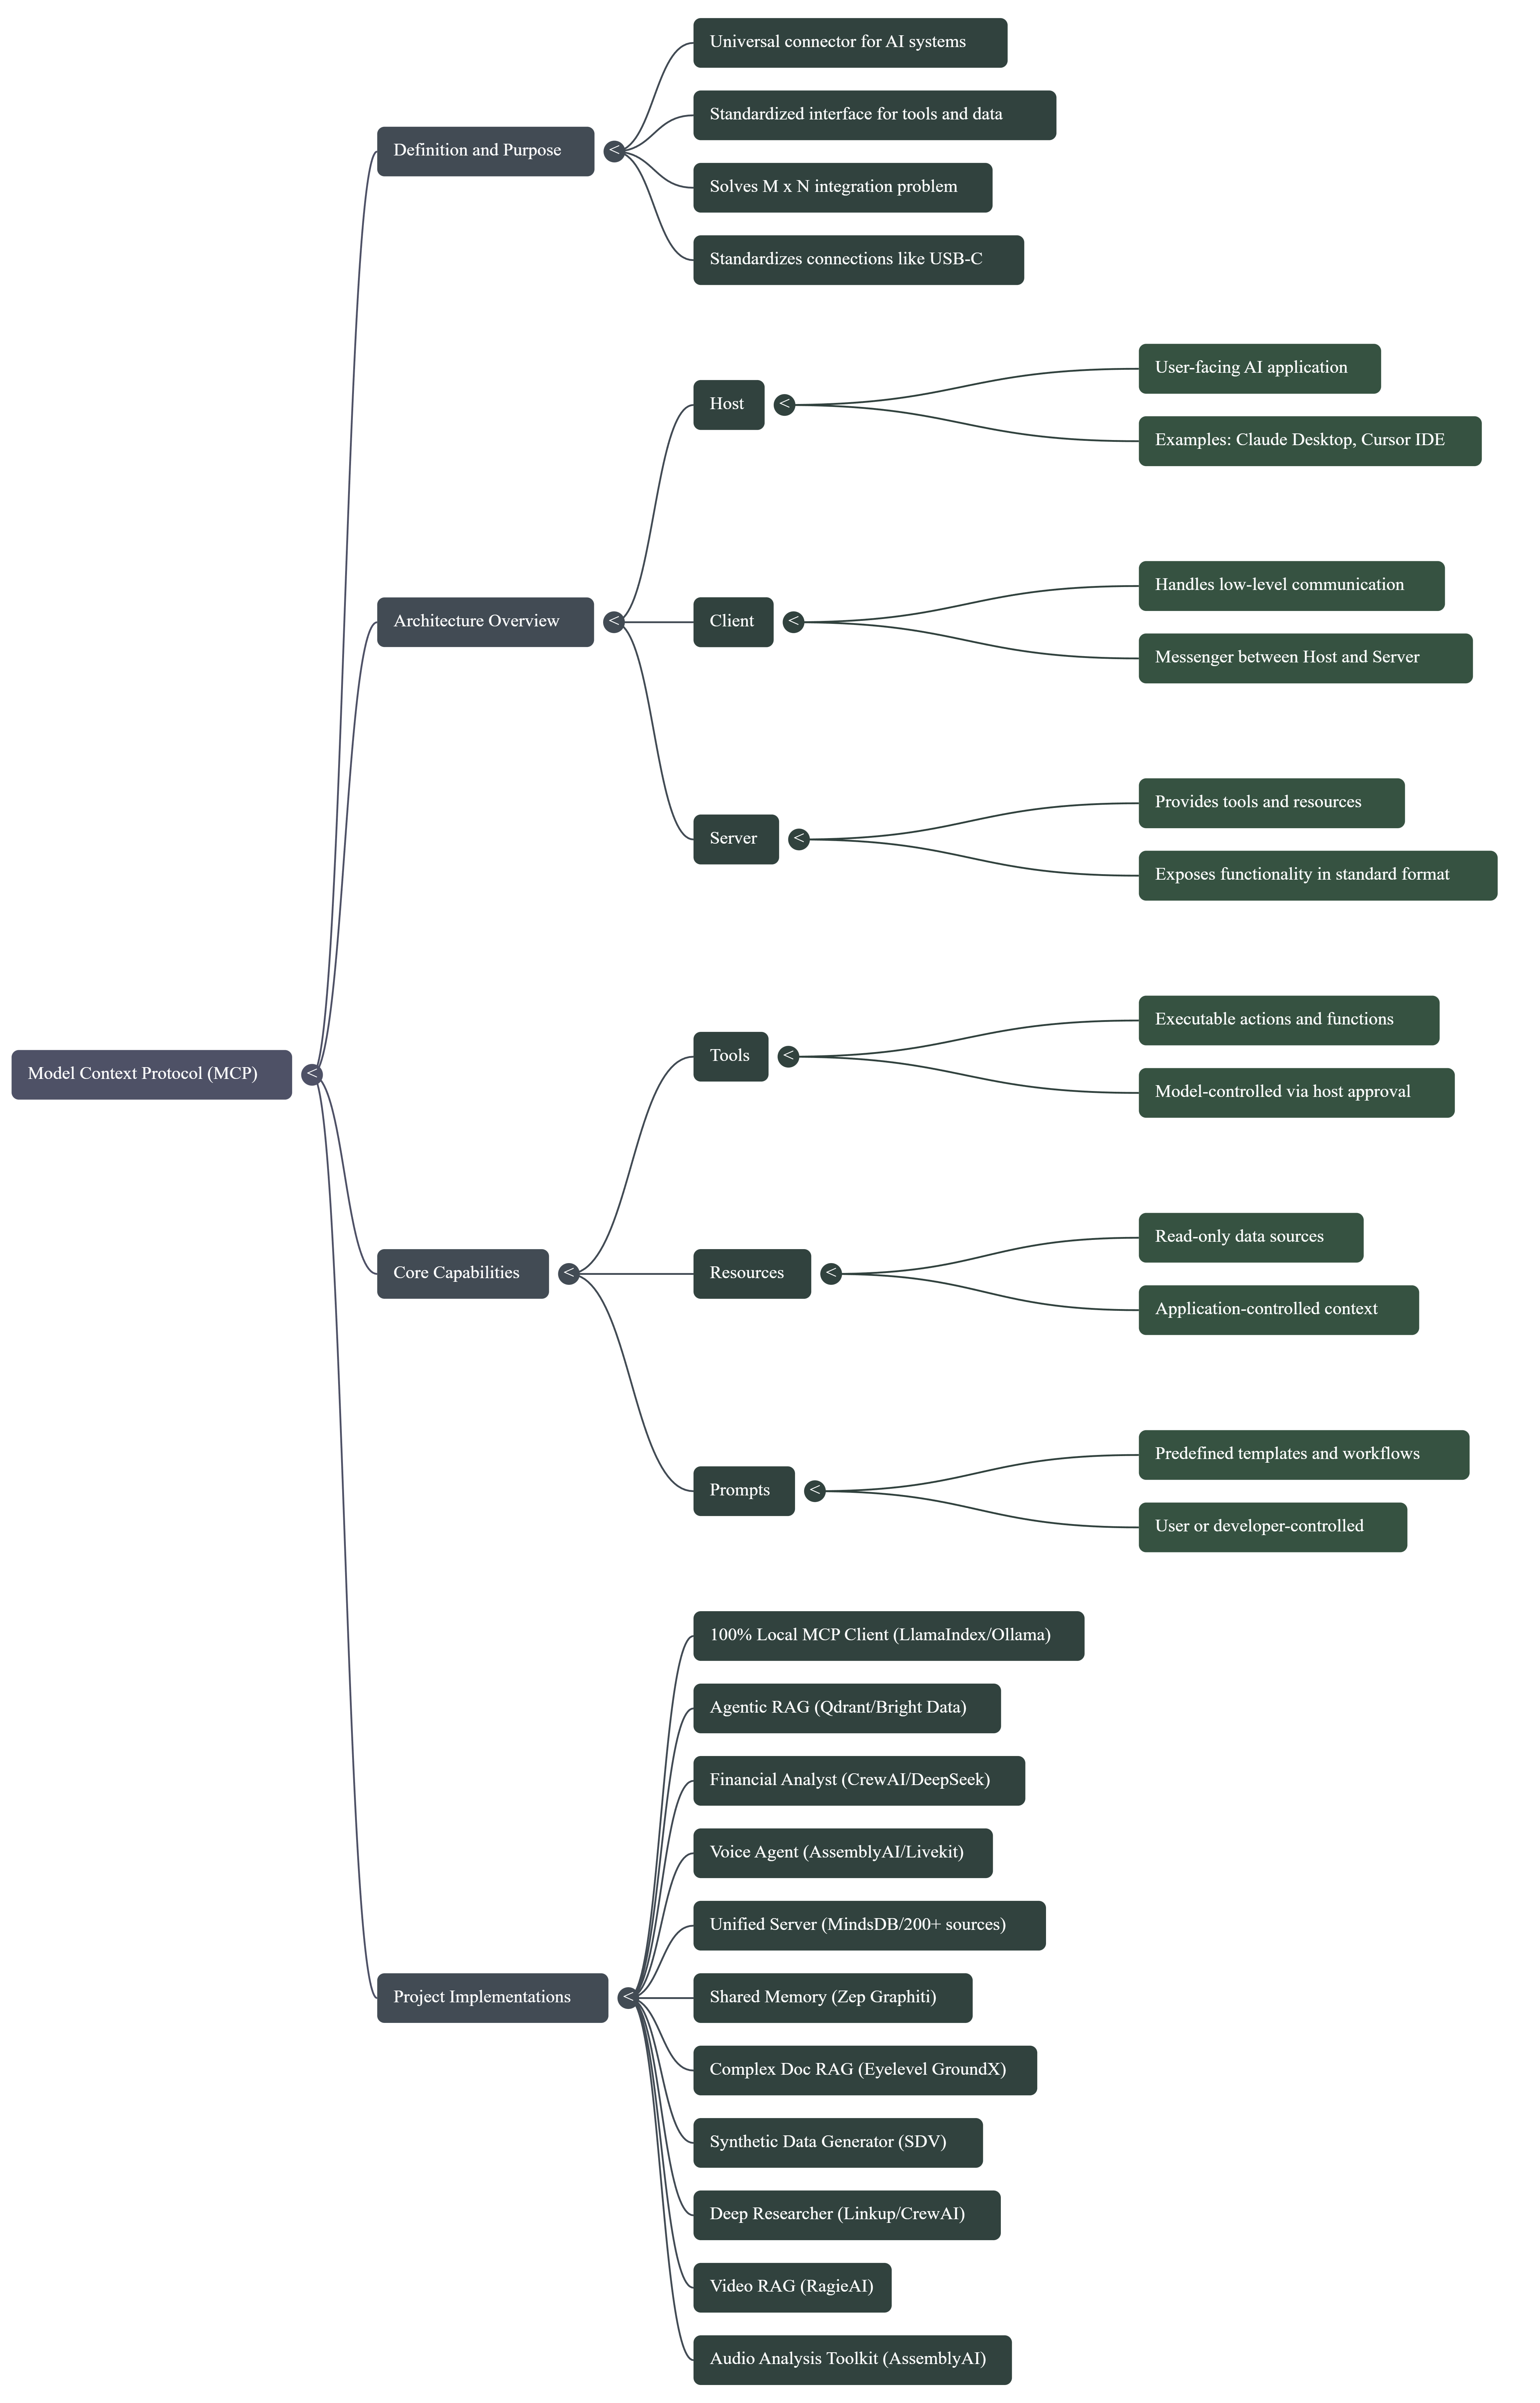
A deep dive into the Model Context Protocol (MCP) — the open standard that connects AI agents to tools and data sources. Covers the protocol architecture, official SDKs, and production server implementations.
### 🔑 Mind Map (Key Concepts)
[📥 **Download High-Resolution Mind Map** (.jpg)](https://raw.githubusercontent.com/Eric-LLMs/Awesome-AI-Engineering/main/summaries/mastering-the-model-context-protocol/mastering-the-model-context-protocol-mindmap.jpg)
🔍 Click here to unfold the full Mind Map (mastering-the-model-context-protocol-mindmap.jpg)
(点击展开完整思维导图)
### 📑 Presentation Slides
> 💡 **Tip:** Press `Ctrl` + `Click` (or Command + Click) to open in a new tab.
[📥 View the "Mastering the Model Context Protocol (MCP)" Slides (PDF)](./summaries/mastering-the-model-context-protocol/mastering-the-model-context-protocol-slides.pdf)
[📥 **Download PDF** (Direct Link)](https://raw.githubusercontent.com/Eric-LLMs/Awesome-AI-Engineering/main/summaries/mastering-the-model-context-protocol/mastering-the-model-context-protocol-slides.pdf)
### 🧰 Key Frameworks & Tools
The official Model Context Protocol SDKs and reference implementations for building and connecting MCP servers:
* **[specification](https://github.com/modelcontextprotocol/modelcontextprotocol)**: The official protocol specification and schema — core primitives (tools, resources, prompts) and transports.
* **[typescript-sdk](https://github.com/modelcontextprotocol/typescript-sdk)**: The official TypeScript SDK for building MCP servers and clients.
* **[python-sdk](https://github.com/modelcontextprotocol/python-sdk)**: The official Python SDK for building MCP servers and clients.
* **[servers — Official Reference Implementations](https://github.com/modelcontextprotocol/servers)**: The official collection of reference MCP servers, including filesystem, fetch, git, memory, and sequential thinking.
* **[registry](https://github.com/modelcontextprotocol/registry)**: The official, community-driven MCP server registry — an "app store" for discovering standardized MCP servers.
* **[FastMCP](https://github.com/jlowin/fastmcp)** *(community)*: The most popular high-level Python framework for building MCP servers — define tools and resources in a few lines of code.
### 🔗 Related Protocols
The Model Context Protocol connects agents to tools and data. For agent-to-agent collaboration and client interfaces, see:
* **[A2A (Agent2Agent Protocol)](https://github.com/a2aproject/A2A)**: The open standard for agent-to-agent communication — lets agents discover each other's capabilities and collaborate on tasks.
* **[ACP (Agent Client Protocol)](https://github.com/coder/agent-client-protocol)**: A protocol for connecting agents to editors and frontends.
### 🛠️ Hands-on Projects & Tools
👉 **[Explore Model Context Protocol (MCP) Projects on GitHub](https://github.com/Eric-LLMs/awesome-mcp-servers)** *A curated collection of industry-standard Model Context Protocol (MCP) server implementations.*
[⬆️ Back to Top : Table of Contents](#top)
---
# 📚 Agent Memory Part I
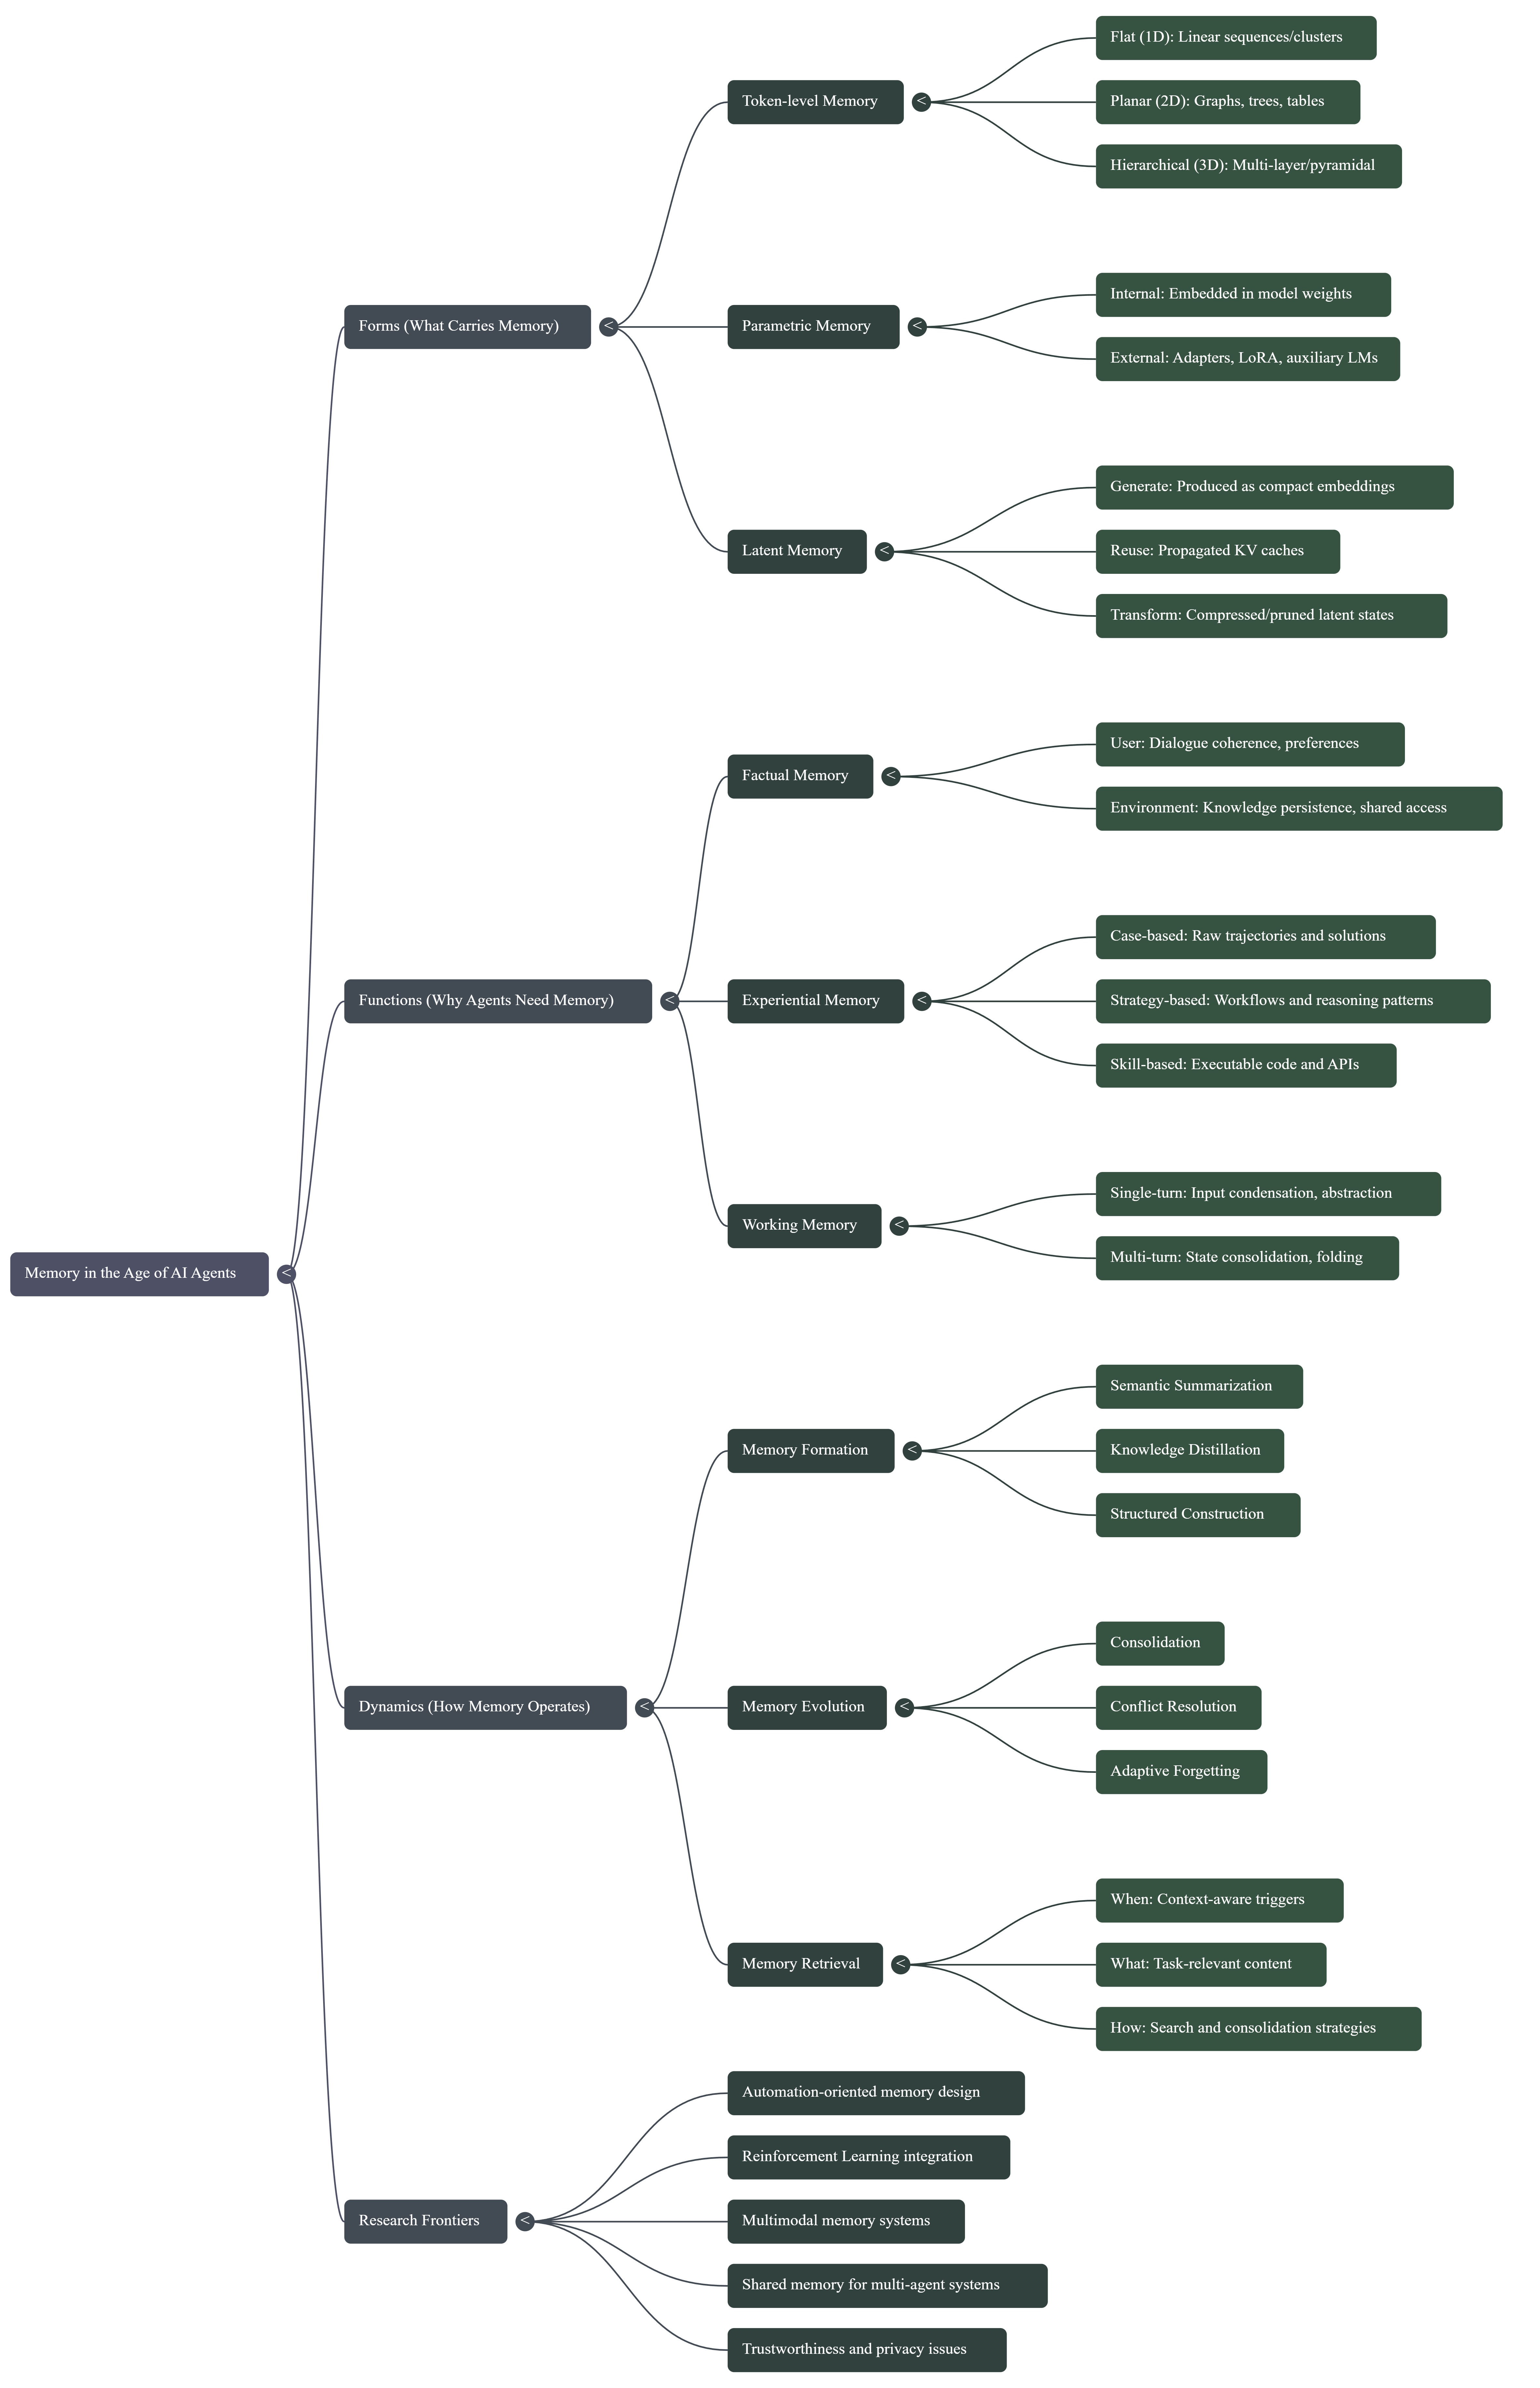
A survey of academic research on how agent memory is designed and categorized (forms, functions, dynamics).
### 🔑 Mind Map (Key Concepts)
[📥 **Download High-Resolution Mind Map** (.jpg)](https://raw.githubusercontent.com/Eric-LLMs/Awesome-AI-Engineering/main/summaries/memory-in-the-age-of-ai-agents-survey/unforgettable_agents_architecting_ai_memory-mindmap.jpg)
🔍 Click here to unfold the full Mind Map (unforgettable_agents_architecting_ai_memory-mindmap.jpg)
(点击展开完整思维导图)
### 📑 Presentation Slides
#### A Blueprint for Memory in Agentic Intelligence
> 💡 **Tip:** Press `Ctrl` + `Click` (or Command + Click) to open in a new tab.
[📥 View the "A Blueprint for Memory in Agentic Intelligence" Slides (PDF)](./summaries/memory-in-the-age-of-ai-agents-survey/a-blueprint-for-memory-in-agentic-intelligence.pdf)
[📥 **Download PDF** (Direct Link)](https://raw.githubusercontent.com/Eric-LLMs/Awesome-AI-Engineering/main/summaries/memory-in-the-age-of-ai-agents-survey/a-blueprint-for-memory-in-agentic-intelligence.pdf)
#### Unforgettable Agents Architecting AI Memory
> 💡 **Tip:** Press `Ctrl` + `Click` (or Command + Click) to open in a new tab.
[📥 View the "Unforgettable Agents Architecting AI Memory" Slides (PDF)](./summaries/memory-in-the-age-of-ai-agents-survey/unforgettable_agents_architecting_ai_memory.pdf)
[📥 **Download PDF** (Direct Link)](https://raw.githubusercontent.com/Eric-LLMs/Awesome-AI-Engineering/main/summaries/memory-in-the-age-of-ai-agents-survey/unforgettable_agents_architecting_ai_memory.pdf)
### 📑 Further Reading / Resources
For a comprehensive list of papers related to Agent Memory, we highly recommend checking out:
👉 [Agent-Memory-Paper-List](https://github.com/Shichun-Liu/Agent-Memory-Paper-List) by Shichun-Liu.
[⬆️ Back to Top : Table of Contents](#top)
---
# 📚 Building Memory Modules for Agentic AI Systems
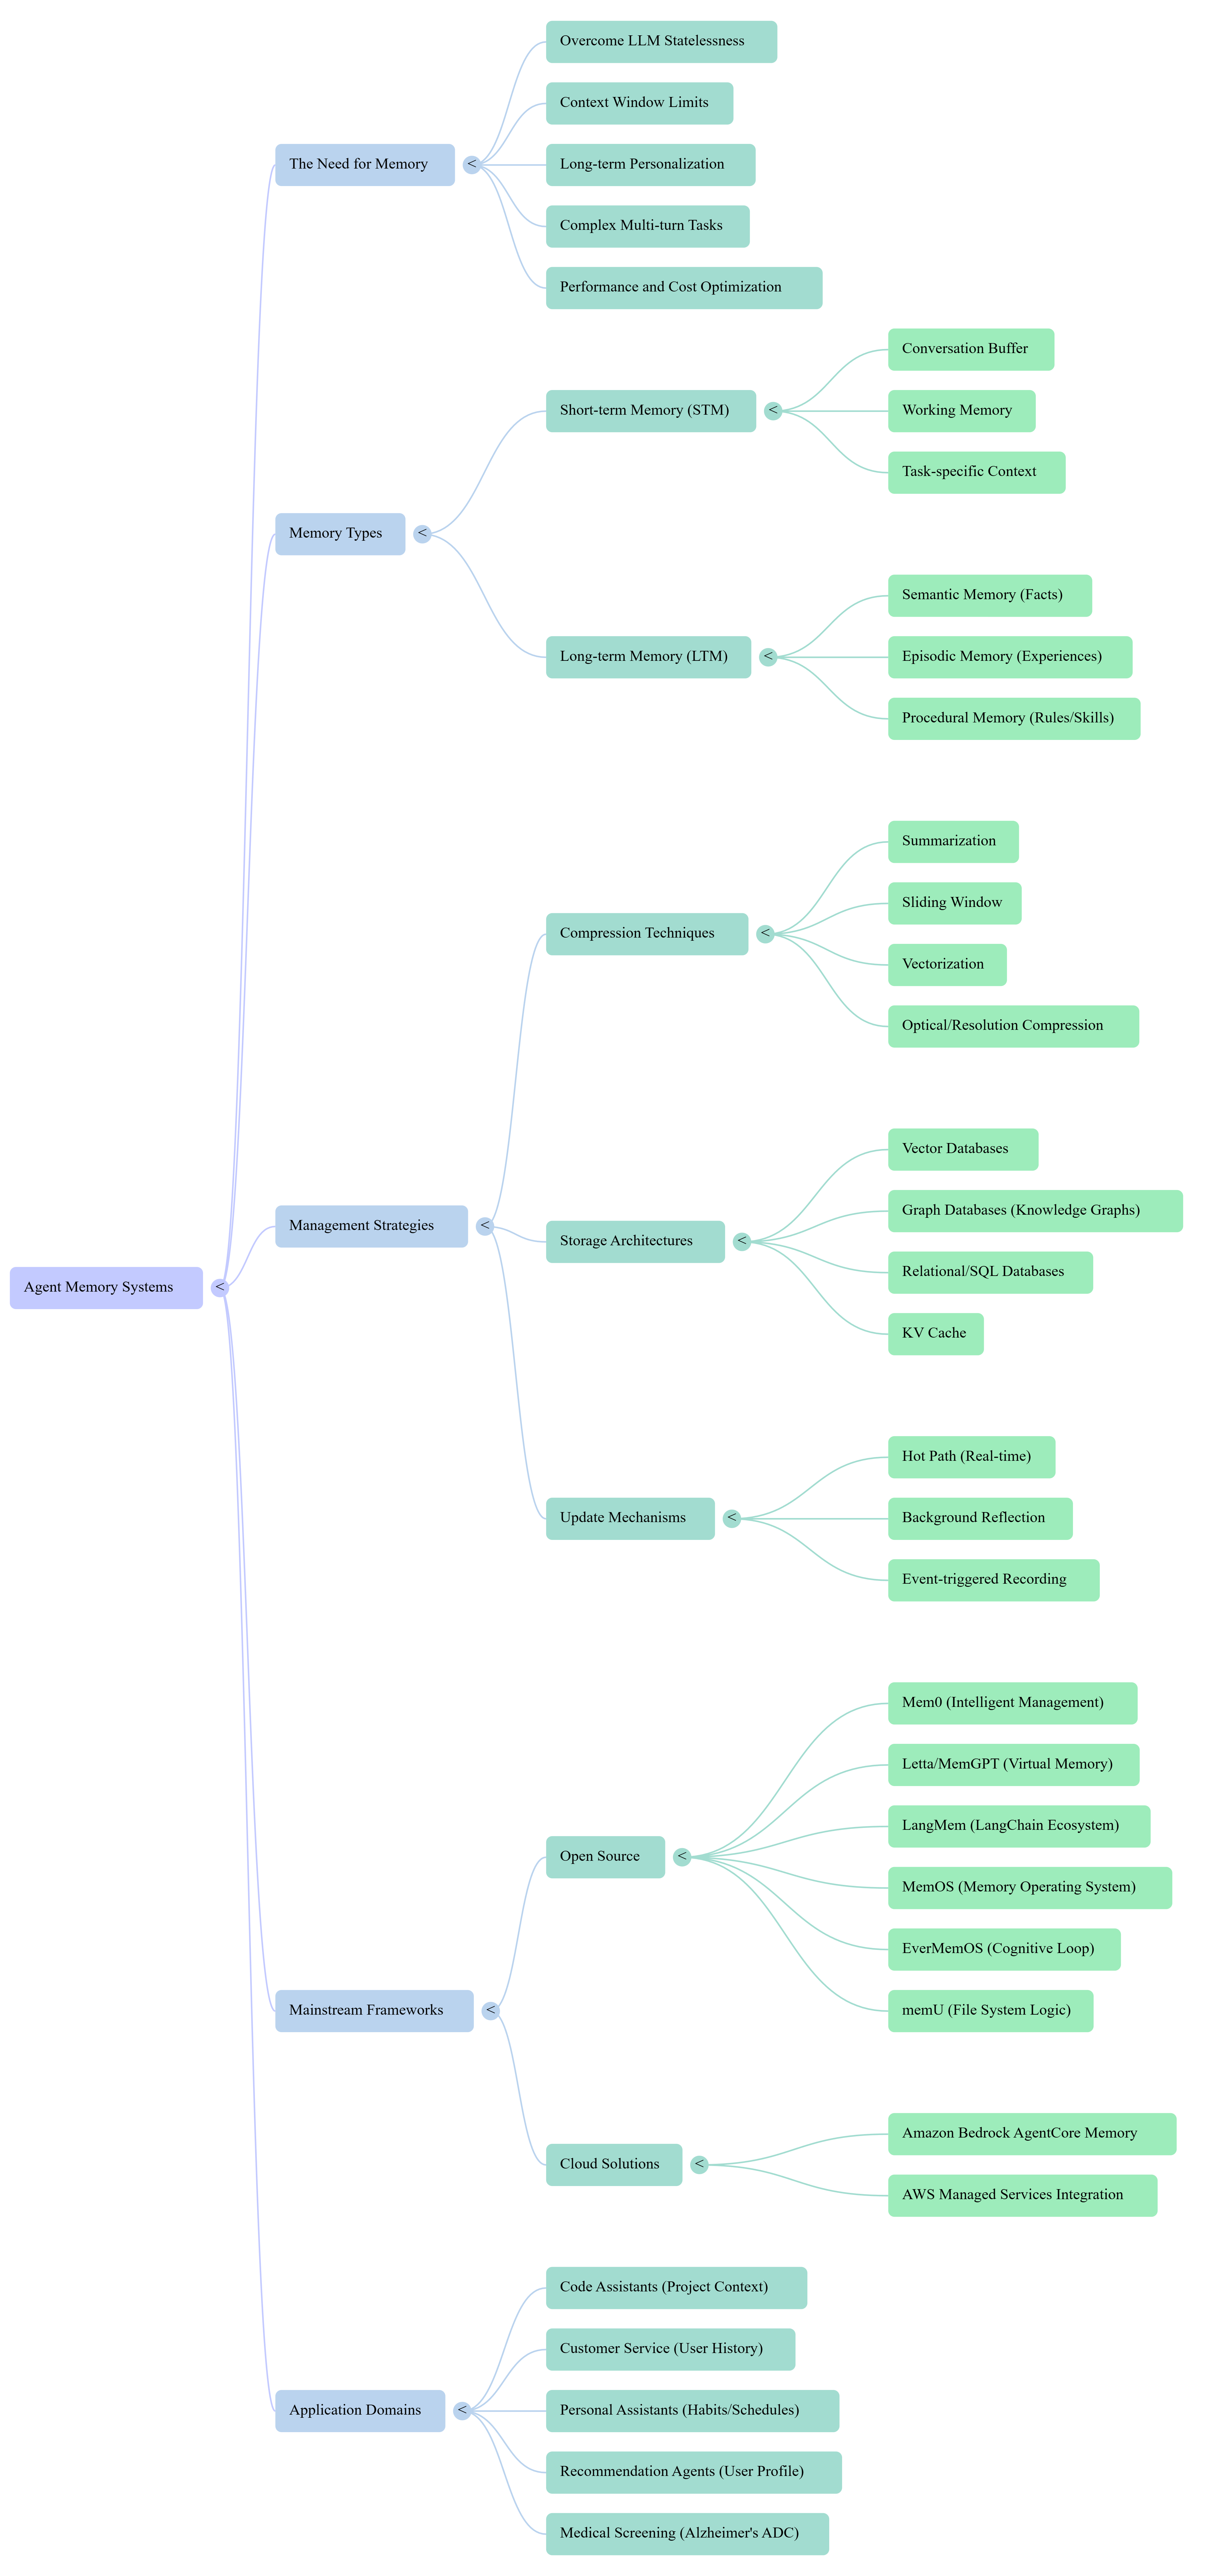
A comprehensive guide on designing memory systems for AI Agents. This document synthesizes academic surveys with practical implementation strategies — covering the taxonomy of agent memory (forms, functions, dynamics), deep dives into Mem0, Letta (MemGPT), and LangMem, and enterprise-grade solutions using Amazon Bedrock AgentCore.
### 🔑 Mind Map (Key Concepts)
[📥 **Download High-Resolution Mind Map** (mindmap.png)](https://raw.githubusercontent.com/Eric-LLMs/Awesome-AI-Engineering/main/summaries/building-memory-for-agentic-ai-theory-frameworks-and-practice/building-memory-for-agentic-ai-theory-frameworks-and-practice-mindmap.png)
🔍 Click here to unfold the full Mind Map
(点击展开完整思维导图)
### 📑 Presentation Slides
#### Building Memory for Agentic AI: Theory, Frameworks, and Practice
> 💡 **Tip:** Press `Ctrl` + `Click` (or Command + Click) to open in a new tab.
[📥 View Slides (PDF)](./summaries/building-memory-for-agentic-ai-theory-frameworks-and-practice/building-memory-for-agentic-ai-theory-frameworks-and-practice.pdf)
[📥 **Download PDF** (Direct Link)](https://raw.githubusercontent.com/Eric-LLMs/Awesome-AI-Engineering/main/summaries/building-memory-for-agentic-ai-theory-frameworks-and-practice/building-memory-for-agentic-ai-theory-frameworks-and-practice.pdf)
### 🧰 Key Frameworks & Code Samples
The following frameworks and repositories are discussed in this guide, representing the current state-of-the-art in Agentic Memory:
* **[Mem0](https://github.com/mem0ai/mem0)**: A dual-layer memory framework supporting working, factual, and semantic memory types for agent state persistence.
* **[Letta (MemGPT)](https://github.com/letta-ai/letta)**: Manages infinite context by treating agents like an OS with virtual memory and recursive summarization.
* **[LangMem](https://github.com/langchain-ai/langmem)**: A LangChain library that implements Semantic, Episodic, and Procedural memory integration for LangGraph agents.
* **[Zep / Graphiti](https://github.com/getzep/graphiti)**: Zep's temporal knowledge-graph framework — builds a dynamic, time-aware memory graph for agent state with causal event support.
* **[Amazon Bedrock Samples](https://github.com/aws-samples/amazon-bedrock-samples)**: A comprehensive collection of examples for using Amazon Bedrock, including various implementations of Agentic workflows and memory patterns.
[⬆️ Back to Top : Table of Contents](#top)
---
# 📚 Agent Evaluation (Eval) Engineering
Evaluating AI Agents requires a fundamental shift from simple output checks ("vibe checks") to analyzing multi-step trajectories, environment changes, and tool usage. This repository consolidates frameworks and engineering practices for moving from **intuition to instrumentation**.
---
### 🔑 Key Considerations
| Consideration | Description |
| :--- | :--- |
| The Intuition Trap | Why manual "vibe checks" fail as complexity scales. |
| The Harness | Building a standardized environment for agent execution composed of Inputs, Tasks, and Graders. |
| Trajectory vs. Outcome | Evaluating the *journey* (reasoning logs, tool calls) rather than just the *destination* (final answer). |
| Reliability Metrics — Pass@k | Can the agent succeed *at least once* in k tries? (Good for brainstorming). |
| Reliability Metrics — Pass^k | Can the agent succeed *every single time* in k tries? (Critical for autonomous agents). |
| Swiss Cheese Model | Layering defenses (Automated Evals → Human Review → Production Monitoring) to ensure reliability. |
| LLM-as-a-Judge | Using LLMs to grade outputs — with known biases (position bias, self-preference) that need calibration. |
| Task Benchmarks | Standardized suites (SWE-bench, GAIA, AgentBench, τ-bench, WebArena) for measuring real-world task success. |
| Tool-Call Correctness | Verifying the right tool, right arguments, and right timing — beyond just the final answer. |
| Process Supervision | Grading intermediate reasoning and tool-call steps, not only the outcome, to catch errors early. |
| Adversarial Robustness | Stress-testing against prompt injection and goal hijacking. |
| Agent Security | Testing permission boundaries, tool authorization, and data-handling safety — ensuring the agent cannot overstep access or leak sensitive data. |
| Cost & Latency | Token efficiency, wall-clock time, and per-task budget — decisive for production agents. |
| Long-Horizon Tasks | Sustained multi-step planning and memory over long-running tasks. |
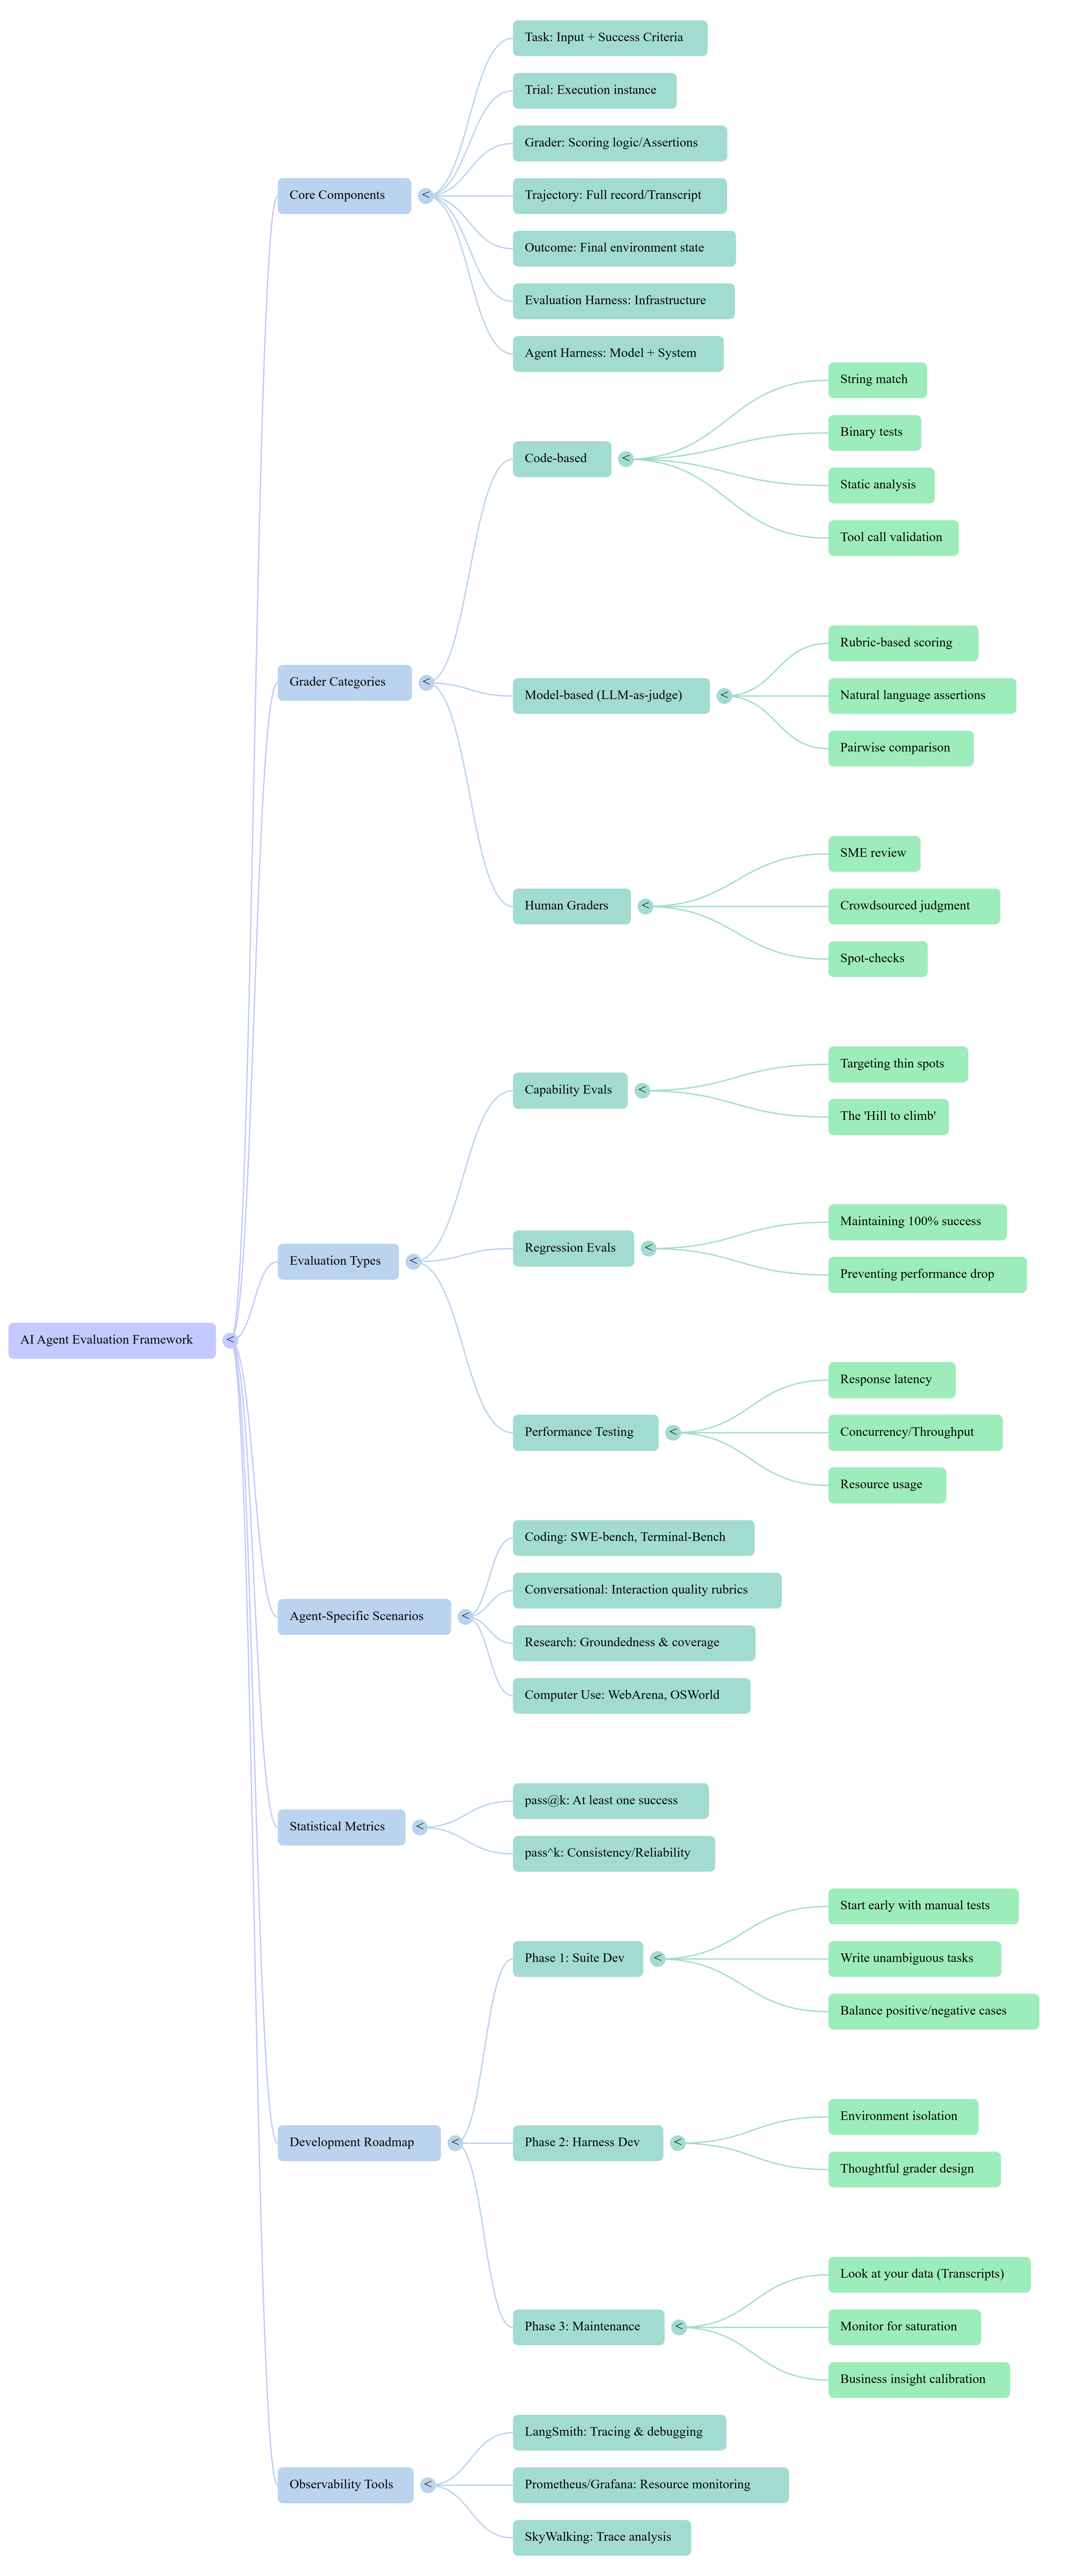
### 🔑 Mind Map (Framework Overview)
[📥 **Download High-Resolution Mind Map** (mindmap.png)](https://raw.githubusercontent.com/Eric-LLMs/Awesome-AI-Engineering/main/summaries/agent-evaluation/ai-agent-evaluation-framework.png)
🔍 Click here to unfold the full Mind Map
(点击展开完整思维导图)
---
### 📑 Presentation Slides
A comprehensive guide to evaluating AI agents, focusing on the engineering framework for testing — including the "Clean Room" methodology, reliability metrics (Pass@k), and the "Harness" architecture. It treats evaluation as a core development practice.
> 💡 **Tip:** Press `Ctrl` + `Click` (or Command + Click) to open in a new tab.
[📥 View Slides (PDF)](./summaries/agent-evaluation/agent-evaluation-engineering.pdf)
[📥 **Download PDF** (Direct Link)](https://raw.githubusercontent.com/Eric-LLMs/Awesome-AI-Engineering/main/summaries/agent-evaluation/agent-evaluation-engineering.pdf)
---
### 🧰 Key Tools, Frameworks & Strategies
#### 1. The Tooling Stack (Ecosystem)
Implementing a robust evaluation pipeline requires specific infrastructure. The following tools are referenced and utilized in this framework:
| Tool | Category | Key Features |
| :--- | :--- | :--- |
| **[LangSmith](https://smith.langchain.com/)** | Tracing & Debugging | Full trajectory tracing, `runnableConfig` tagging for A/B testing, and dataset management. |
| **[LangFuse](https://langfuse.com/)** | Observability | Open-source alternative for observability, prompt management, and lightweight evaluation. |
| **[Arize Phoenix](https://github.com/Arize-ai/phoenix)** | Observability & Eval | Open-source LLM tracing, embedding analysis, and RAG/agent evaluation. |
| **[W&B Weave](https://github.com/wandb/weave)** | Tracing & Eval | Lightweight LLM instrumentation, eval harnesses, and dataset versioning. |
| **[DeepEval](https://github.com/confident-ai/deepeval)** | Unit Testing | "Pytest for LLMs". Specific metrics for RAG (Hallucination, Answer Relevancy) and Agents. |
| **[OpenAI Evals](https://github.com/openai/evals)** | Evaluation Framework | OpenAI's open-source framework for model-graded evals — YAML/JSON config-driven, custom eval classes, and dataset registries. |
| **[OpenEvals](https://github.com/langchain-ai/openevals)** | Graders | A library of pre-built "LLM-as-a-judge" prompts (Conciseness, Correctness, Coherence) compatible with LangSmith. |
| **[AgentOps](https://github.com/AgentOps-AI/agentops)** | Agent DevOps & Monitoring | Session replays, agent benchmarking, and cost & reliability tracking for autonomous agents. |
| **[Promptfoo](https://github.com/promptfoo/promptfoo)** | Red Teaming & Regression | Declarative eval configs, LLM regression testing, and adversarial red-teaming. |
#### 2. Architecture: Hybrid Agent (Fast vs. Slow)
To balance cost and performance, we implement a **Hybrid Agent Architecture**:
* **Reactive Layer (System 1)**: Handles simple, direct queries (e.g., "What is the stock price?") with low latency.
* **Deliberative Layer (System 2)**: Activated for complex planning or multi-step reasoning tasks.
* **Coordination Layer**: A router that classifies intent and dispatches tasks.
Each layer is evaluated with different metrics:
* **Reactive Layer**: latency and single-step accuracy.
* **Deliberative Layer**: task completion rate, multi-step planning correctness, and trajectory quality.
* **Coordination Layer**: intent classification accuracy — misrouting is a common source of downstream failures.
#### 3. Evaluation Strategy: The "Clean Room"
To prevent "cheating" through shared state, every evaluation trial runs in a fresh container/sandbox.
* **Isolation**: Fresh container for every trial, plus state reset (environment, conversation history) and snapshot rollback to guarantee a clean slate.
* **Mocking & Replay**: Simulate external APIs — or record-and-replay real responses — to control latency and produce deterministic, reproducible outputs.
* **Determinism**: Fix seeds and use `temperature=0` so runs are repeatable and differences are attributable to code, not randomness.
* **Cleanup & Anti-Leakage**: Aggressive state teardown (no shared history) and guard against goal leakage that could let the agent take shortcuts via shared state.
[⬆️ Back to Top : Table of Contents](#top)