---
license: apache-2.0
tags:
- reinforcement-learning
- image-generation
- image-editing
- prompt-optimization
- flux
- qwen
models:
- wangfuyun/PrompRL
---
PromptRL

## Overview
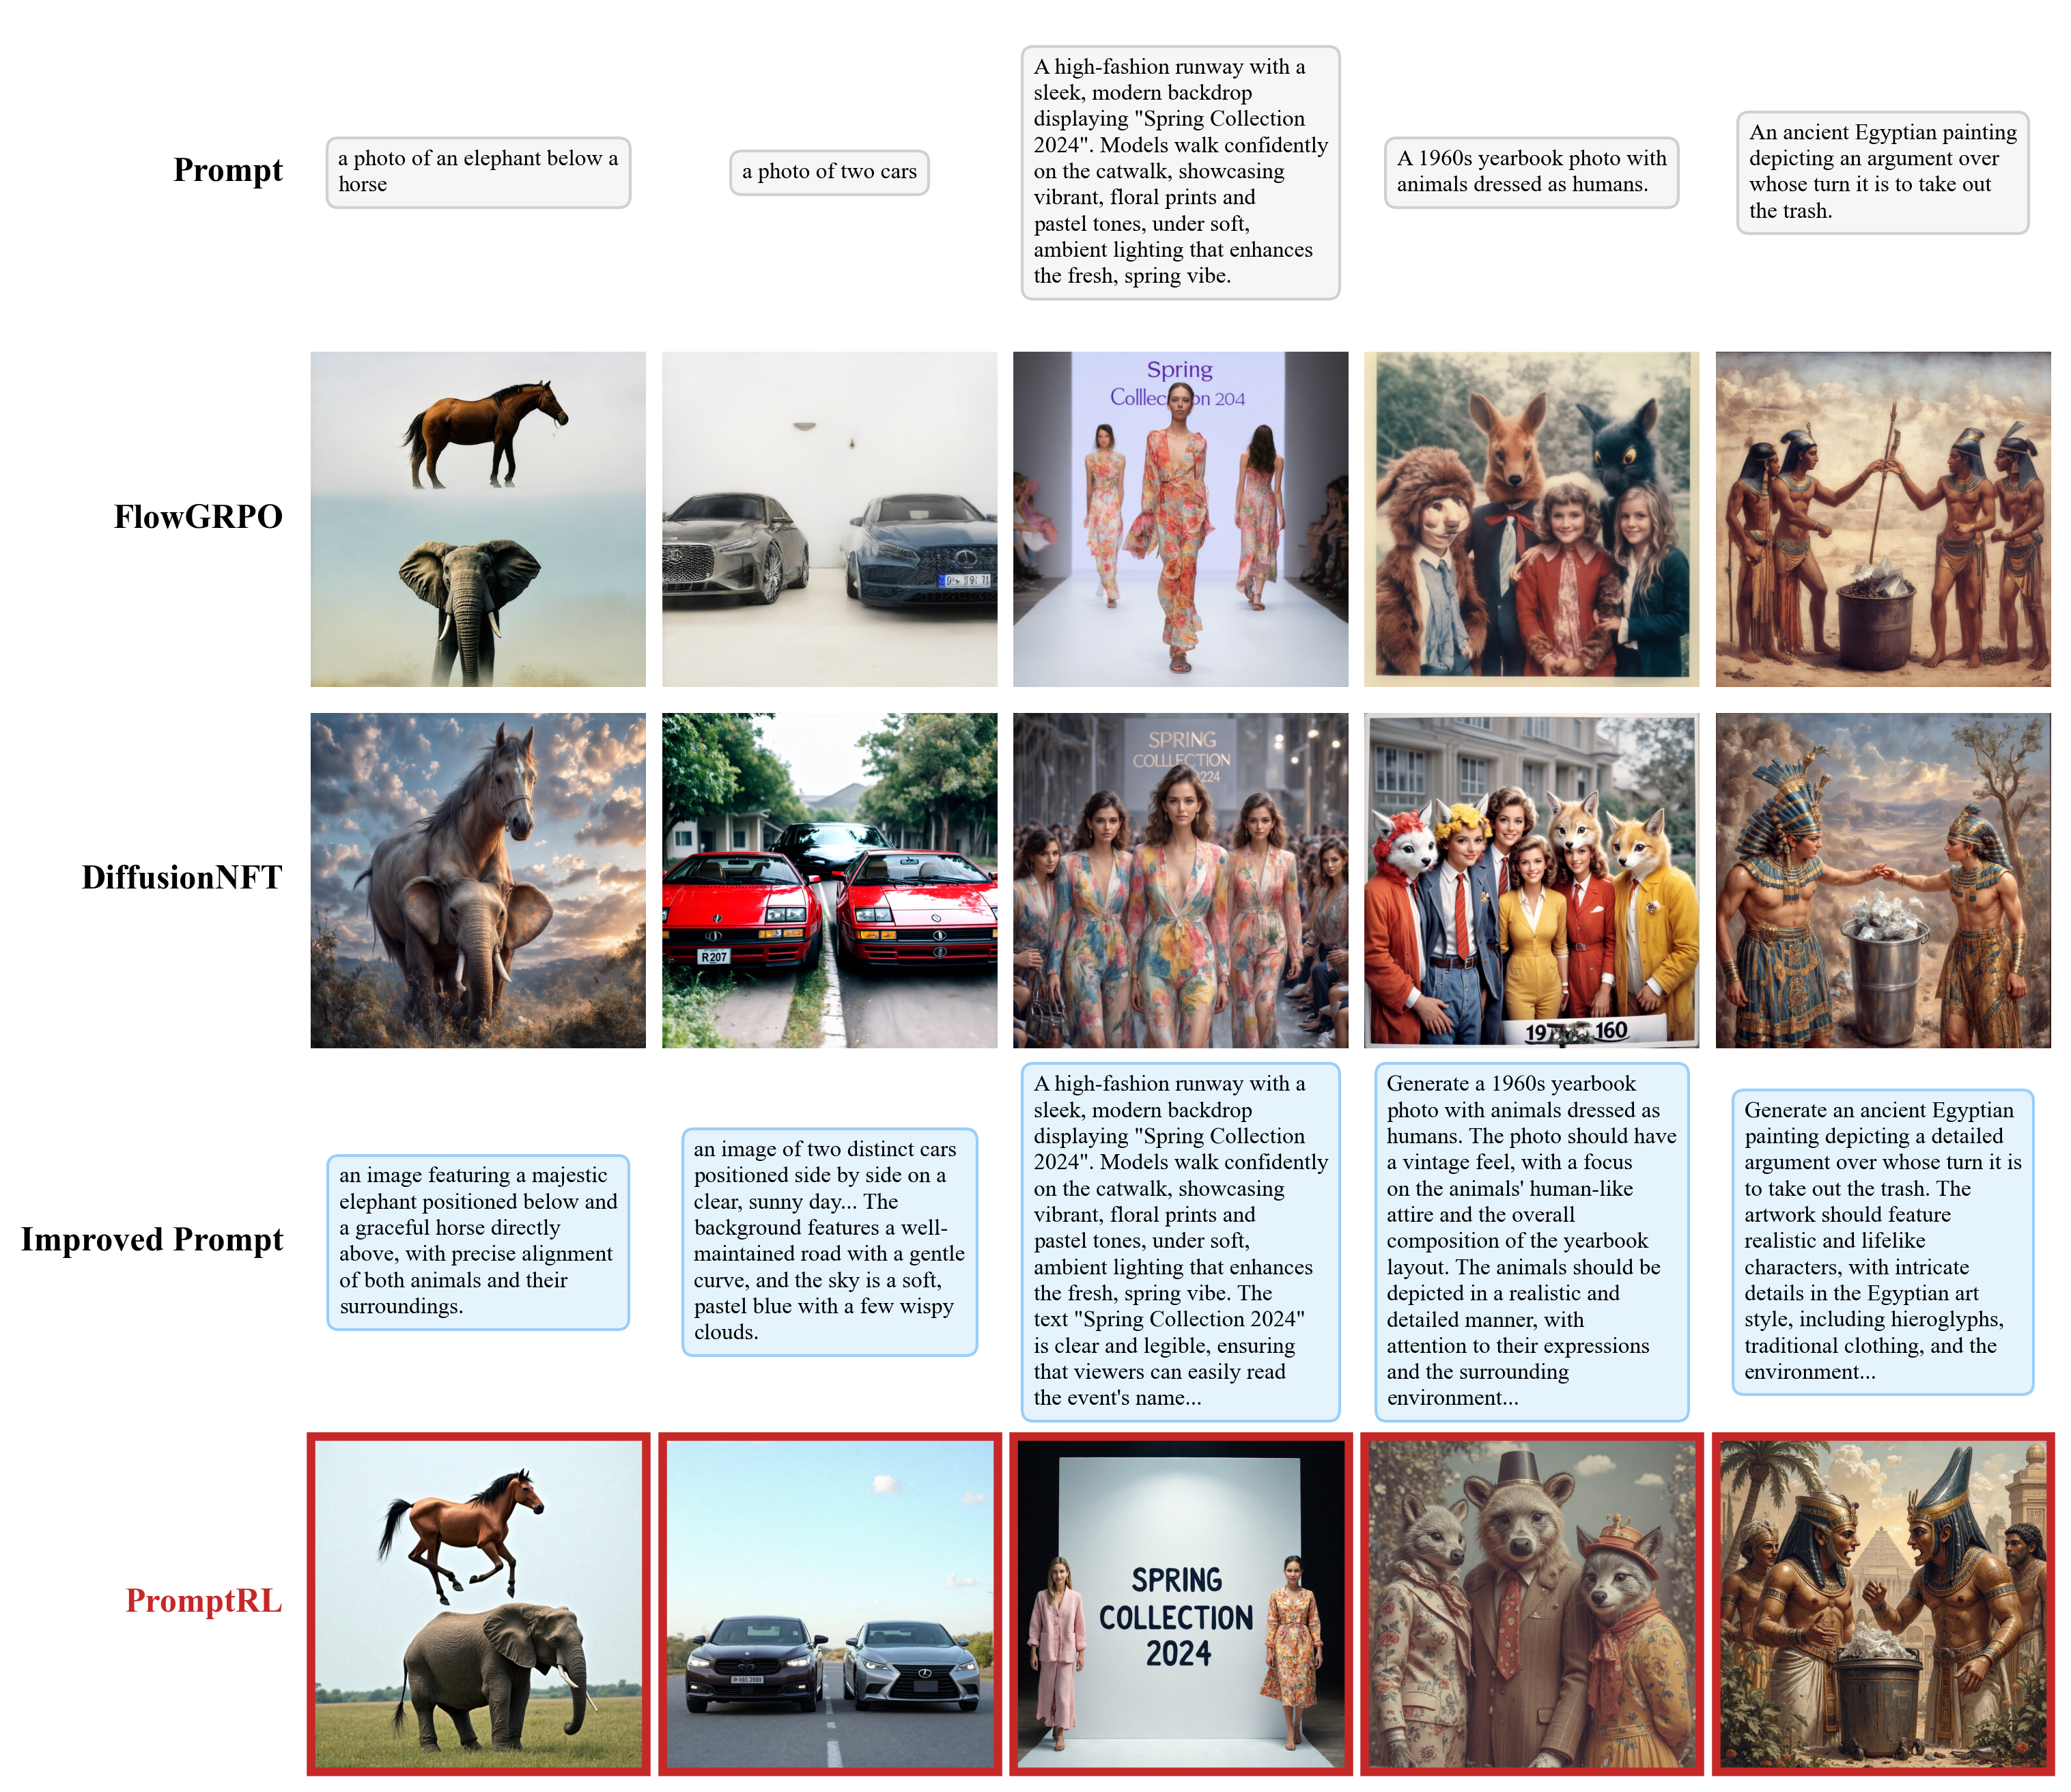
**PromptRL** is a framework that jointly trains language models (LMs) and flow-matching models (FMs) within a unified reinforcement learning loop for text-to-image generation. By incorporating LMs as adaptive prompt refiners, PromptRL addresses two critical limitations in current flow-based RL pipelines: *exploration collapse* due to insufficient generation diversity, and *prompt overfitting* where models memorize specific training formulations.
This release ships two RL paths: **image editing** with EditReward (FLUX.1-Kontext-dev or FLUX.2-klein-base-4B) and **text-to-image GenEval** (FLUX.1-dev or FLUX.2-klein-base-4B). Each path offers a prompt-only trainer (LLM updates, DiT frozen) and a joint LLM+DiT trainer.
## Installation
The training environment assumes Python 3.11, PyTorch 2.7 with CUDA 12.x, and a Linux box with NVIDIA GPUs (the default training + reward configuration uses **8× GPUs total** — see the edit-training section below).
```bash
conda env create -f environment.yml
conda activate unirl
pip install git+https://github.com/openai/CLIP.git
# diffusers >=0.38.0 is required for Flux2KleinPipeline (FLUX.2-klein-base). The
# 0.38 line also ships FLUX.1-Kontext, so a single pin covers both backbones.
pip install "diffusers>=0.38.0" huggingface-hub==0.36.2
MAX_JOBS=4 pip install flash-attn==2.7.4.post1 --no-build-isolation
```
FLUX.1-Kontext-dev, FLUX.2-klein-base-4B, and several reward checkpoints are gated on the Hub. Log in once before downloading them:
```bash
huggingface-cli login
```
To run the qualitative evaluation pipeline (text-to-image OCR / PickScore / GenEval / edit), use `bash gen.sh` — it downloads the eval split and runs four `unified_inference.py` jobs. It is *not* an installation smoke test.
Training The Edit Model And Running EditReward
**Scope**
This release keeps only the edit RL path. The trainer is `unirl/trainer/edit_grpo_trainer.py` (class `EditJointGRPOTrainer`), which jointly optimizes the Qwen-VL prompt refiner and a FLUX edit transformer. Two backbones are supported and auto-detected from the checkpoint path: **FLUX.1-Kontext-dev** (Qwen-Kontext) and **FLUX.2-klein-base-4B** (Qwen-Klein). The VAE, text encoders, and vision encoder stay frozen in both cases.
The partial-refinement setting is preserved: with the default `NUM_GENERATIONS=8` and `NUM_SKIP_REFINEMENT=2`, each source image produces six edits from Qwen-refined prompts and two edits from the original prompt.
Relevant files:
- `unirl/train_edit.py`: CLI entry point for joint edit GRPO (Kontext and Klein).
- `unirl/reward_evaluator/reward_evaluator.py`: EditReward HTTP client used by training.
- `rewards_services/api_services/editreward_scorer_service`: EditReward service wrapper.
- `scripts/train/edit_grpo.sh` / `scripts/train/edit_grpo_klein.sh`: per-backbone launch scripts (env-var configured).
**Dataset**
By default, `scripts/train/edit_grpo.sh` loads:
```text
https://huggingface.co/wangfuyun/PrompRL/resolve/main/data/omni_edit_train_50k.parquet
```
You can override it with `PROMPTS_FILE`. The loader also accepts the Hugging Face web URL form with `/blob/main/`; it is converted to the downloadable `/resolve/main/` URL automatically.
The dataset should be a `.parquet` or `.jsonl` file with:
| Column | Description |
| --- | --- |
| `image` | Source image before editing. For jsonl this can be an image path. |
| `prompt` | Edit instruction. |
Optional columns are `caption` and `target_caption`. For other column names, set `IMAGE_COLUMN` and `PROMPT_COLUMN`.
**1. Start EditReward**
The reward service runs in its own virtual env so its dependency pins (notably `transformers==4.56.1`) do not collide with the training env.
```bash
cd rewards_services/api_services/editreward_scorer_service
python -m venv .venv
source .venv/bin/activate
pip install --upgrade pip wheel setuptools # `wheel` is required by flash-attn's source build
# Pick the PyTorch wheel matching your driver. PyPI's default now ships cu130, which
# needs driver >=580 — if `nvidia-smi` reports CUDA 12.x, use the cu128 index instead.
# See https://pytorch.org/get-started/locally/ for other CUDA targets.
pip install --index-url https://download.pytorch.org/whl/cu128 torch torchvision torchaudio
pip install -r requirements.txt
pip install flash-attn --no-build-isolation
git clone https://github.com/TIGER-AI-Lab/EditReward.git
huggingface-cli download TIGER-Lab/EditReward-MiMo-VL-7B-SFT-2508 \
--local-dir EditReward/EditReward-MiMo-VL-7B-SFT-2508
export EDITREWARD_CUDA_DEVICES=0 # 1 worker is usually enough; bump to "0,1" + WORKERS=2 if reward is your bottleneck
export EDITREWARD_WORKERS=1
export EDITREWARD_PORT=18088
# export EDITREWARD_HOST=0.0.0.0 # only if the trainer runs on a different machine; defaults to 127.0.0.1
bash run.sh
```
If the EditReward repo or checkpoint is stored elsewhere:
```bash
export EDITREWARD_REPO_DIR=/path/to/EditReward
export EDITREWARD_CHECKPOINT_PATH=/path/to/EditReward-MiMo-VL-7B-SFT-2508
```
**2. Build the Qwen-Kontext (or Qwen-Klein) base checkpoint**
The trainer expects a *fused* checkpoint that wires `Qwen/Qwen2.5-VL-3B-Instruct` together with a FLUX diffusion expert. Two backbones are supported and auto-detected from the checkpoint path:
- **`QwenKontext`** — Qwen-VL + `black-forest-labs/FLUX.1-Kontext-dev` (12B, CLIP+T5 text encoders, 8-step distilled).
- **`QwenKlein`** — Qwen-VL + `black-forest-labs/FLUX.2-klein-base-4B` (4B, single Qwen3 text encoder, undistilled). Smaller, Apache 2.0.
Both base models are gated on the Hub — make sure `huggingface-cli login` has accepted their licenses, then build whichever checkpoint you want:
```bash
conda activate unirl
cd /path/to/PrompRL-opensource
python -m unimodel.qwenkontext.qwenkontext_inference
# produces outputs/pretrain/qwenkontext/ — use this as MODEL_NAME_OR_PATH below.
# Alternative: Qwen + FLUX.2-klein-base-4B
python -m unimodel.qwenklein.qwenklein_inference
# produces outputs/pretrain/qwenklein/ — point MODEL_NAME_OR_PATH at this and
# launch with scripts/train/edit_grpo_klein.sh instead of edit_grpo.sh.
```
Each `__main__` block downloads the Qwen-VL base and its FLUX diffusion expert, calls `initialize_diffusion_expert()` to attach the transformer / VAE / scheduler, runs a one-prompt sanity edit, and saves the combined weights.
**3. Launch Training**
Recommended layout on 8× 80 GB GPUs (H100/A100): **GPU 0 hosts a single EditReward worker; GPUs 1–7 run the trainer**. EditReward inference is small batches → one worker is rarely the bottleneck, so freeing the second GPU for the trainer is the better trade. If you have more GPUs to spare or want lower reward latency, bump `EDITREWARD_WORKERS` back up.
`NUM_GENERATIONS=8` is the launch default. If you OOM on 80 GB cards, drop it to `6` (4 refined + 2 original); Klein-base-4B fits more comfortably than Kontext at the same setting.
From the repository root (Kontext example):
```bash
export MODEL_NAME_OR_PATH=outputs/pretrain/qwenkontext # from step 2
# Optional. Defaults to the PromptRL OmniEdit 50k parquet on Hugging Face.
export PROMPTS_FILE=https://huggingface.co/wangfuyun/PrompRL/resolve/main/data/omni_edit_train_50k.parquet
export EDITREWARD_URL=http://127.0.0.1:18088/
export CUDA_VISIBLE_DEVICES=1,2,3,4,5,6,7
export NPROC_PER_NODE=7
export NUM_SDE=2
export RUN_NAME=qwenkontext-editreward
export NUM_GENERATIONS=8
export NUM_SKIP_REFINEMENT=2 # 6 refined + 2 original (partial-refinement preserved)
export PYTORCH_CUDA_ALLOC_CONF=expandable_segments:True
bash scripts/train/edit_grpo.sh
```
For Klein, swap the checkpoint and launch script (defaults that differ: `EDIT_GUIDANCE_SCALE=4.0`, output dir under `outputs/rl/klein/`):
```bash
export MODEL_NAME_OR_PATH=outputs/pretrain/qwenklein # from step 2
export RUN_NAME=qwenklein-editreward
export PROMPTRL_EDIT_NUM_INFERENCE_STEPS=6
export PROMPTRL_EDIT_GUIDANCE_SCALE=4
export PROMPTRL_DIFFUSION_LOSS_BATCH_SIZE=4
export PROMPTRL_EDIT_HEIGHT=512
export PROMPTRL_EDIT_WIDTH=512
export WANDB_PROJECT=PrompRL-klein
export REPORT_TO=wandb
bash scripts/train/edit_grpo_klein.sh
```
Common options:
```bash
export NUM_GENERATIONS=8
export NUM_SKIP_REFINEMENT=2
export NUM_INFERENCE_STEPS=8 # total FLUX denoising steps per edit (SDE prefix + ODE tail)
export NUM_SDE=2 # first N steps run SDE w/ logprob; remaining steps run pure ODE
export SDE_NOISE_SCALE=0.8 # multiplier on per-step SDE noise std (FlowGRPO default 0.8)
export PER_DEVICE_TRAIN_BATCH_SIZE=1
export DIT_LEARNING_RATE=2e-7
export LLM_LEARNING_RATE=3e-7
export DIT_BETA1=0.9 # joint RL: try 0.0 or 0.5 to react faster to LLM prompt shift
export DIT_BETA2=0.999
export LLM_BETA1=0.9
export LLM_BETA2=0.999
export BETA=1e-2
export IMAGE_COLUMN=image
export PROMPT_COLUMN=prompt
export REPORT_TO=wandb
```
Training logs sample source/edited images under:
```text
outputs/rl/kontext/$RUN_NAME/training_samples/ # Kontext launcher
outputs/rl/klein/$RUN_NAME/training_samples/ # Klein launcher
```
Training The T2I Model On GenEval (Prompt-Only And Joint)
**Scope**
GenEval RL is configured for object/attribute/composition rewards via the existing
GenEval scorer service. Two trainers live in `unirl/trainer/geneval_grpo_trainer.py`:
- `GenEvalPromptGRPOTrainer` — updates only the Qwen2.5-VL prompt refiner; the
FLUX transformer stays frozen. Cheaper and very stable.
- `GenEvalJointGRPOTrainer` — jointly updates LLM + DiT with SDE log-prob tracking,
same FlowGRPO-style PPO loss used by the edit trainer.
Both trainers are backbone-agnostic over two T2I backbones, auto-detected from the
checkpoint path substring:
- **`QwenFlux`** — Qwen-VL + `black-forest-labs/FLUX.1-dev` (12B, CLIP+T5, embedded
guidance). 20 inference steps / 10 SDE steps by default.
- **`QwenKlein`** — Qwen-VL + `black-forest-labs/FLUX.2-klein-base-4B` (4B, single
Qwen3 text encoder). 20 inference steps / 8 SDE steps by default.
Relevant files:
- `unirl/train_geneval.py` — CLI entrypoint (selects Prompt vs Joint via `--joint`).
- `unirl/reward_evaluator/reward_evaluator.py::RewardEvaluatorClient.evaluate_geneval` — HTTP client.
- `rewards_services/api_services/geneval_scorer_service/` — set up alongside the
EditReward scorer (see the GenEval scorer's own README for mmdetection installation).
- `scripts/train/geneval_grpo_flux.sh` / `scripts/train/geneval_grpo_klein.sh` — launch scripts.
**Dataset**
The launch scripts default to `assets/rl_datasets/train_metadata.jsonl` — a JSONL of
GenEval-style records, one per line:
```json
{"tag": "color_attr", "include": [{"class": "bus", "count": 1, "color": "yellow"}, {"class": "handbag", "count": 1, "color": "orange"}], "prompt": "a photo of a yellow bus and an orange handbag"}
```
Each line carries the original `prompt` plus the `tag` / `include` / `exclude` fields
consumed by the scorer. Override the file with `PROMPTS_FILE=...`.
**1. Start the GenEval scorer**
The GenEval service is the same shape as EditReward (pickled HTTP, port 18085 by
default) but uses mmdetection + Mask2Former to ground objects. It needs its own
conda env because mmcv/mmdet require legacy CUDA toolchain pins.
```bash
cd rewards_services/api_services/geneval_scorer_service
conda create -n geneval python=3.11 -y
conda activate geneval
# CUDA toolchain for mmcv/mmdet source builds
export CUDA_HOME=/usr/local/cuda
export PATH=$CUDA_HOME/bin:$PATH
export LD_LIBRARY_PATH=$CUDA_HOME/lib64:$LD_LIBRARY_PATH
# Mask2Former checkpoint used as the object detector
mkdir -p object_models
wget -O object_models/mask2former_swin-s-p4-w7-224_lsj_8x2_50e_coco.pth \
https://download.openmmlab.com/mmdetection/v2.0/mask2former/mask2former_swin-s-p4-w7-224_lsj_8x2_50e_coco/mask2former_swin-s-p4-w7-224_lsj_8x2_50e_coco_20220504_001756-743b7d99.pth
# Pinned deps from the GenEval reference setup
pip install torch==2.1.2 torchvision==0.16.2 torchaudio==2.1.2 --index-url https://download.pytorch.org/whl/cu121
pip install open-clip-torch==2.26.1 clip-benchmark einops lightning tomli platformdirs
pip install -U openmim
pip install "diffusers[torch]" transformers
pip install --upgrade setuptools==60.2.0
# mmcv / mmdetection from source (adjust -arch=sm_XX to your GPU)
git clone https://github.com/open-mmlab/mmcv.git
( cd mmcv && git checkout 1.x && MMCV_WITH_OPS=1 MMCV_CUDA_ARGS="-arch=sm_90" pip install -v -e . )
git clone https://github.com/open-mmlab/mmdetection.git
( cd mmdetection && git checkout 2.x && pip install -v -e . )
pip install gunicorn flask "numpy<2"
export GENEVAL_PORT=18085
# export GENEVAL_HOST=0.0.0.0 # only if the trainer runs on a different machine
bash run.sh
```
See `rewards_services/api_services/geneval_scorer_service/readme.txt` for the
canonical install commands.
**2. Build the QwenFlux (or QwenKlein) T2I base checkpoint**
```bash
conda activate unirl
cd /path/to/PrompRL-opensource
python -m unimodel.qwenflux.qwenflux_inference # outputs/pretrain/qwenflux/
# Or use the Klein checkpoint built earlier for the edit task; the path "qwenklein"
# is detected automatically.
```
**3. Launch training**
Prompt-only training (LLM updates, DiT frozen) on FLUX.1-dev:
```bash
export MODEL_NAME_OR_PATH=outputs/pretrain/qwenflux
export GENEVAL_URL=http://127.0.0.1:18085/
export RUN_NAME=qwenflux-geneval-prompt
bash scripts/train/geneval_grpo_flux.sh
```
Joint training on the same backbone — just flip `JOINT=true`:
```bash
export JOINT=true
export RUN_NAME=qwenflux-geneval-joint
bash scripts/train/geneval_grpo_flux.sh
```
Klein backbone:
```bash
export MODEL_NAME_OR_PATH=outputs/pretrain/qwenklein
export RUN_NAME=qwenklein-geneval-prompt # or qwenklein-geneval-joint with JOINT=true
bash scripts/train/geneval_grpo_klein.sh
```
Common overrides (defaults shown):
```bash
export NUM_GENERATIONS=8
export NUM_INFERENCE_STEPS=20 # total denoising steps
export NUM_SDE=10 # flux.dev: first 10 with SDE; klein default: 8
export GUIDANCE_SCALE=3.5 # klein: 4.0
export GENEVAL_ONLY_STRICT=False # set True for binary GenEval reward only
export LLM_LEARNING_RATE=1e-6 # prompt-only LR; joint mode also reads DIT_LEARNING_RATE
export DIT_LEARNING_RATE=2e-7
```
Training logs sample images and refined prompts under:
```text
outputs/rl/flux/$RUN_NAME/training_samples/ # FLUX.1-dev launcher
outputs/rl/klein/$RUN_NAME/training_samples/ # FLUX.2-klein launcher (T2I, prompt or joint)
```
## Qualitative Results
### Text-to-Image Generation
### Instructional Image Editing
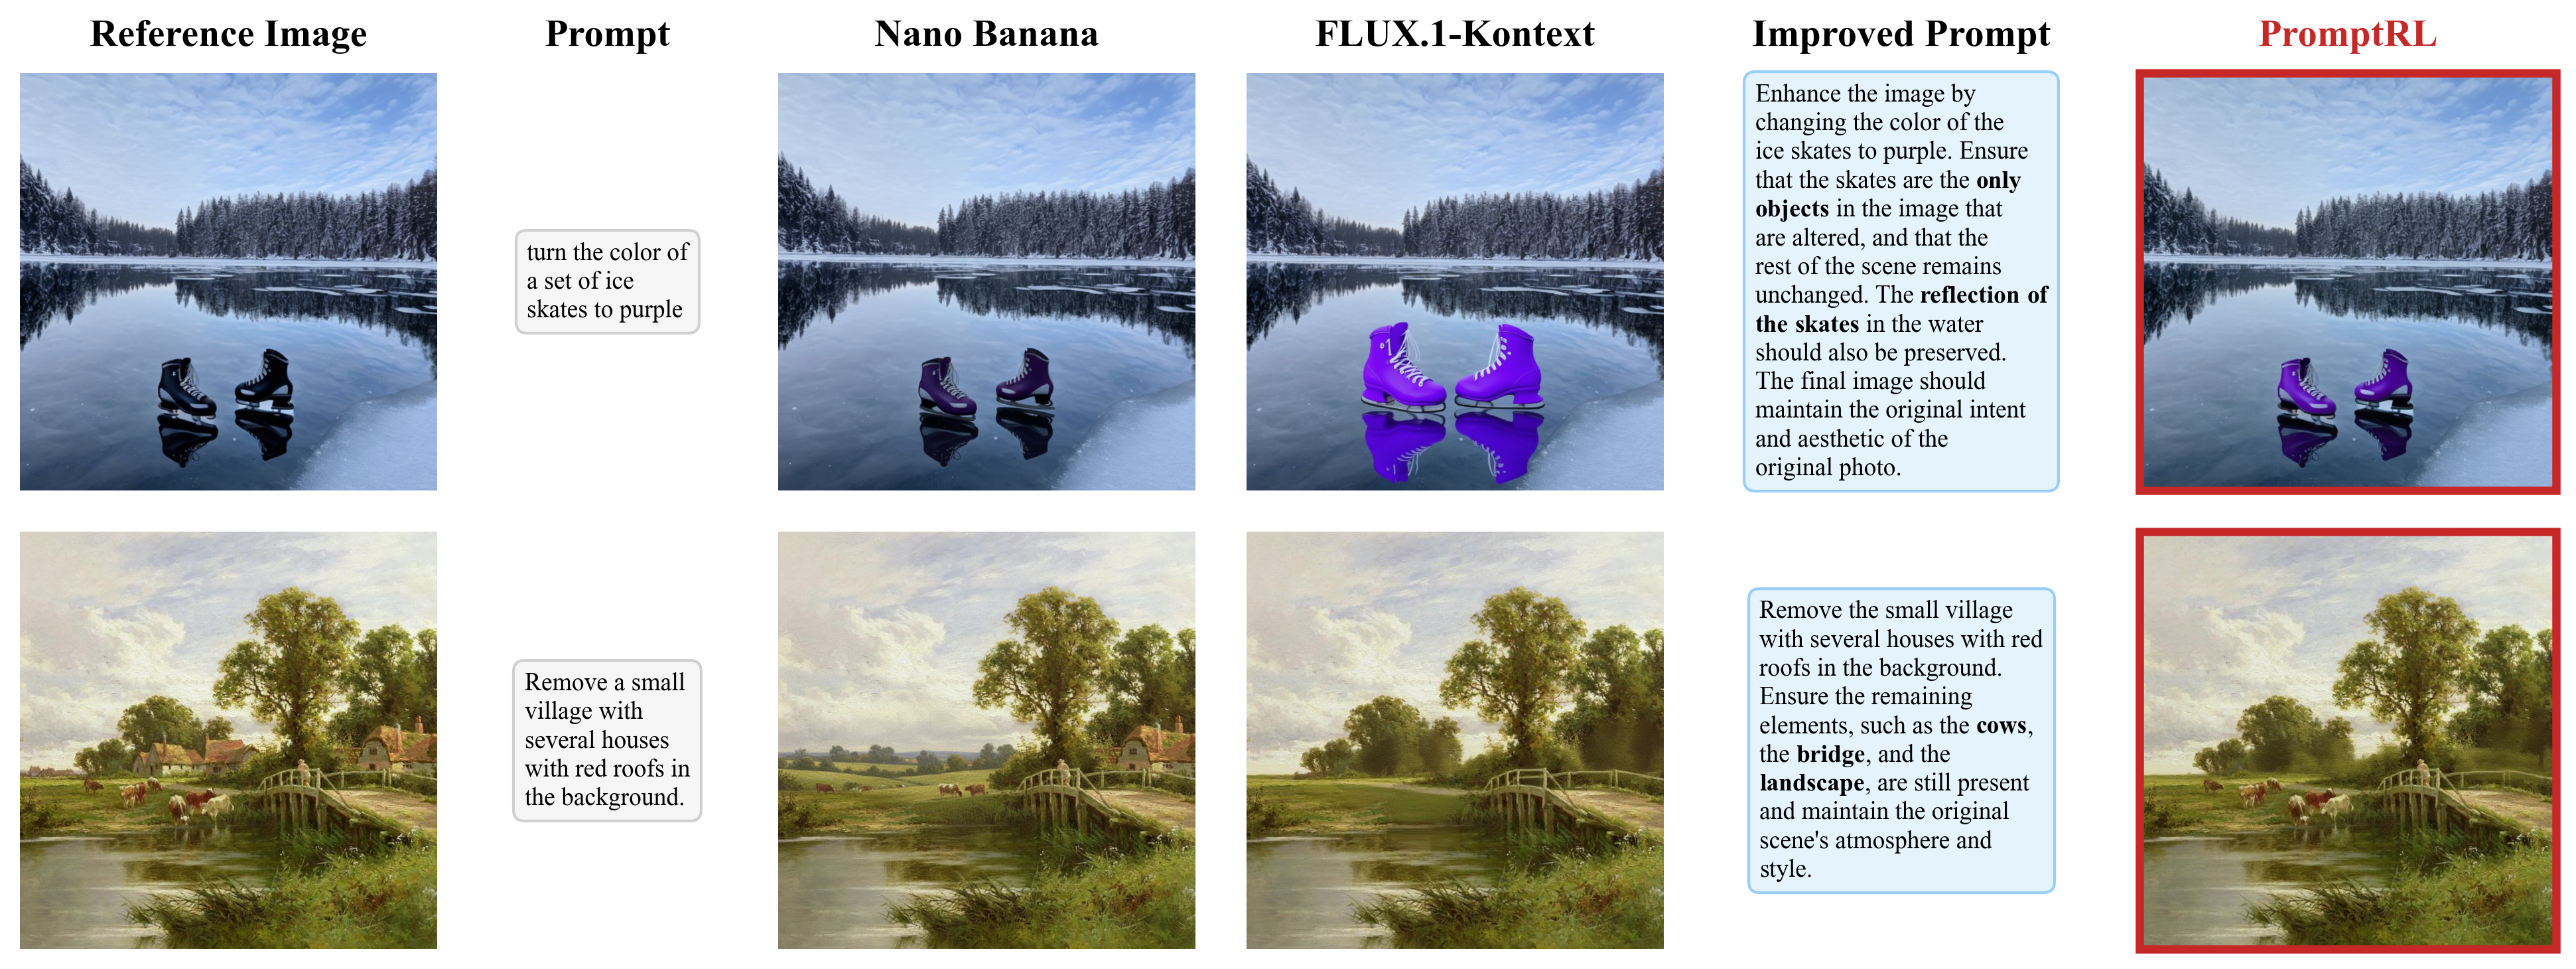
## Key Results
PromptRL improves sample efficiency over flow-only RL and trains an adaptive prompt-refinement agent that further boosts test-time performance.
### Summary
| Benchmark | Metric | PromptRL w/ PE | Best Baseline |
|:---|:---|:---:|:---:|
| GenEval | Avg. Score ↑ | **0.97** | 0.92 (FlowGRPO) |
| Aesthetic | PickScore ↑ | **24.05** | 23.63 (DiffusionNFT) |
| Aesthetic | HPS ↑ | **32.03** | 31.79 (DiffusionNFT) |
| OCR | OCR-1k ↑ | **0.98** | 0.89 (FlowGRPO) |
| Image Editing | EditReward Avg. ↑ | **1.43** | 1.44 (ReasonEdit-Think) |
---
📊 GenEval Benchmark (Full Results)
| Model | 1 Obj. | 2 Obj. | Cnt. | Clr. | Pos. | Attr. | Avg.↑ |
|:---|:---:|:---:|:---:|:---:|:---:|:---:|:---:|
| Show-o | 0.95 | 0.52 | 0.49 | 0.82 | 0.11 | 0.28 | 0.53 |
| Emu3-Gen | 0.98 | 0.71 | 0.34 | 0.81 | 0.17 | 0.21 | 0.54 |
| SD3 Medium | 0.98 | 0.74 | 0.63 | 0.67 | 0.34 | 0.36 | 0.62 |
| FLUX.1-dev | 0.98 | 0.81 | 0.74 | 0.79 | 0.22 | 0.45 | 0.66 |
| SD3.5 Large | 0.98 | 0.89 | 0.73 | 0.83 | 0.34 | 0.47 | 0.71 |
| JanusFlow | 0.97 | 0.59 | 0.45 | 0.83 | 0.53 | 0.42 | 0.63 |
| Janus-Pro-7B | 0.99 | 0.89 | 0.59 | 0.90 | 0.79 | 0.66 | 0.80 |
| HiDream | 1.00 | 0.98 | 0.79 | 0.91 | 0.60 | 0.72 | 0.83 |
| Seedream 3.0 | 0.99 | 0.96 | 0.91 | 0.93 | 0.47 | 0.80 | 0.84 |
| Qwen-Image | 0.99 | 0.92 | 0.89 | 0.88 | 0.76 | 0.77 | 0.87 |
| *RL-based* | | | | | | | |
| RePrompt | 0.98 | 0.87 | 0.77 | 0.85 | 0.62 | 0.49 | 0.76 |
| FlowGRPO | 1.00 | 0.99 | 0.91 | 0.89 | 0.95 | 0.80 | 0.92 |
| DiffusionNFT | 1.00 | 0.98 | 0.74 | 0.92 | 0.85 | 0.80 | 0.88 |
| PromptRL w/o PE | 1.00 | 0.96 | 0.95 | 0.95 | 0.93 | 0.85 | 0.94 |
| **PromptRL w/ PE** | **1.00** | **0.99** | **0.99** | **0.96** | **0.99** | **0.90** | **0.97** |
🎨 Aesthetic & OCR Metrics (Full Results)
| Model | P.S. | HPS | U.R. | OCR-1k | TMDB | OpenLib |
|:---|:---:|:---:|:---:|:---:|:---:|:---:|
| SD1.5 | 20.92 | 23.71 | 2.00 | 0.05 | 0.13 | 0.08 |
| SDXL | 22.14 | 26.67 | 2.78 | 0.13 | 0.20 | 0.09 |
| SD3 Medium | 22.38 | 28.56 | 3.09 | — | 0.44 | 0.33 |
| FLUX.1-schnell | 22.64 | 29.39 | 3.25 | 0.54 | 0.66 | 0.50 |
| FLUX.2-klein | 22.79 | 29.03 | 3.29 | 0.55 | 0.22 | 0.46 |
| Z-Image | 20.14 | 28.22 | 3.51 | 0.70 | 0.71 | 0.83 |
| Qwen-Image | 23.05 | 30.40 | 3.53 | 0.65 | 0.79 | 0.94 |
| Qwen-Image-2512 | 23.16 | 30.79 | 3.40 | 0.72 | 0.81 | 0.87 |
| *RL-based* | | | | | | |
| FlowGRPO | 23.33 | 29.80 | 3.33 | 0.89 | 0.83 | 0.73 |
| DiffusionNFT | 23.63 | 31.79 | 3.39 | 0.89 | 0.91 | 0.86 |
| PromptRL w/o PE | 24.01 | 31.79 | 3.38 | 0.97 | 0.92 | 0.95 |
| **PromptRL w/ PE** | **24.05** | **32.03** | **3.44** | **0.98** | **0.91** | **0.95** |
✏️ Image Editing - EditReward (Full Results)
| Model | Swap | Style | Add. | Attr. | Env. | Removal | Avg.↑ |
|:---|:---:|:---:|:---:|:---:|:---:|:---:|:---:|
| InstructPix2Pix | -0.24 | 0.91 | -0.45 | 0.45 | 0.48 | -0.80 | 0.02 |
| MagicBrush | -0.38 | 0.36 | -0.78 | -0.80 | 0.91 | -0.85 | -0.27 |
| LEDITS++ | -0.81 | -0.32 | -0.30 | -0.60 | -0.37 | -0.97 | -0.60 |
| Qwen-Image-Edit | 1.11 | 1.14 | 0.95 | 0.90 | 1.39 | 0.61 | 1.03 |
| FLUX.2-klein | 1.42 | 1.73 | 1.29 | 1.42 | 1.80 | 0.32 | 1.34 |
| Nano Banana | 1.58 | 1.20 | 1.28 | 1.18 | 1.61 | 1.13 | 1.37 |
| Step1X-Edit | 1.39 | 1.58 | 1.19 | 1.34 | 1.57 | 0.22 | 1.24 |
| ReasonEdit | 1.51 | 1.43 | 1.19 | 1.47 | 1.58 | 1.14 | 1.40 |
| ReasonEdit-Think | 1.52 | 1.47 | 1.19 | 1.44 | 1.69 | 1.27 | 1.44 |
| FLUX.1-Kontext | 1.35 | 1.36 | 1.16 | 1.15 | 1.44 | 0.55 | 1.19 |
| FLUX.1-Kontext w/ PE | 1.35 | 0.97 | 1.04 | 0.48 | 1.22 | 0.65 | 1.01 |
| PromptRL w/o PE | 1.45 | 1.46 | 1.28 | 1.35 | 1.56 | 0.98 | 1.36 |
| **PromptRL w/ PE** | **1.47** | **1.43** | **1.29** | **1.39** | **1.72** | **1.24** | **1.43** |
## Citation
```bibtext
@article{wang2025promptrl,
title={PromptRL: Prompt Matters in RL for Flow-Based Image Generation},
author={Wang, Fu-Yun and Zhang, Han and Gharbi, Michael and Li, Hongsheng and Park, Taesung},
journal={arXiv preprint arXiv:2602.01382},
year={2026}
}
```
```bibtext
@article{wang2025unirl,
title={UniRL-Zero: Reinforcement Learning on Unified Models with Joint Language Model and Diffusion Model Experts},
author={Wang, Fu-Yun and Zhang, Han and Gharbi, Michael and Li, Hongsheng and Park, Taesung},
journal={arXiv preprint arXiv:2510.17937},
year={2025}
}
```
## Acknowledgments
This codebase builds upon [UniRL-Zero](https://github.com/G-U-N/UniRL/tree/master).