# Agents-A1: Scaling the Horizon, Not the Parameters: Reaching Trillion-Parameter Performance with a 35B Agent
📰 Tech Report | 🏠 Home Page
---
## 🔥 News
- **2026.7.14**: 🔥🔥 The 4B model has been released.
- **2026.7.8**: 🔥🔥 By popular demand from the community, our 4B model is coming in the next few days — making it faster and easier to build your own local AI assistant.
- **2026.7.2**: 🔥🔥 Based on Agents-A1, we have released a series of quantized model variants. Please refer to the [Agents-A1 collection](https://huggingface.co/collections/InternScience/agents-a1). Besides, we’d like to thank the [mlx-community](https://huggingface.co/collections/mlx-community/agents-a1) for providing quantized versions at multiple scales. Try running Agents-A1 on your Mac!
- **2026.6.26**: 🔥🔥 We have open-sourced the Agents-A1 35B-A3B model, along with the evaluation code for selected domains and the technical report.
---
**Agents-A1** is a 35B Mixture-of-Experts Agentic Model that reaches trillion-parameter-level performance by scaling the agent horizon. We investigate agent-horizon scaling from two perspectives: scaling long-horizon trajectories and scaling heterogeneous agent abilities. To support this goal, we build a long-horizon knowledge-action infrastructure that connects external knowledge, actions, observations, and verifier outcomes, producing agentic trajectories with an average length of **45K tokens**. Based on this, we train Agents-A1 with a three-stage recipe. First, we perform full-domain supervised fine-tuning to align the base model with broad agentic behaviors. Second, we train domain-level teacher models to capture specialized expertise in each domain. Third, we propose a multi-teacher domain-routed on-policy distillation with salient vocabulary alignment to improve knowledge transfer efficiency across different domains, unifying **six heterogeneous domains** into one deployable student model.
## Highlights
- **Agentic Reasoning**: Agents-A1 excels at decomposing complex tasks into executable sub-steps, planning ahead, and adapting its strategy based on intermediate results.
- **Tool Use**: Natively supports function calling and tool integration, enabling seamless interaction with APIs, code interpreters, search engines, and other external tools.
- **Long-Context Understanding**: Handles extended conversations and documents with strong coherence and recall.
- **Instruction Following**: Precisely follows detailed, multi-constraint instructions across diverse domains.
We welcome developers and enterprises to integrate and try Agents-A1 and share their feedback.
## Performance
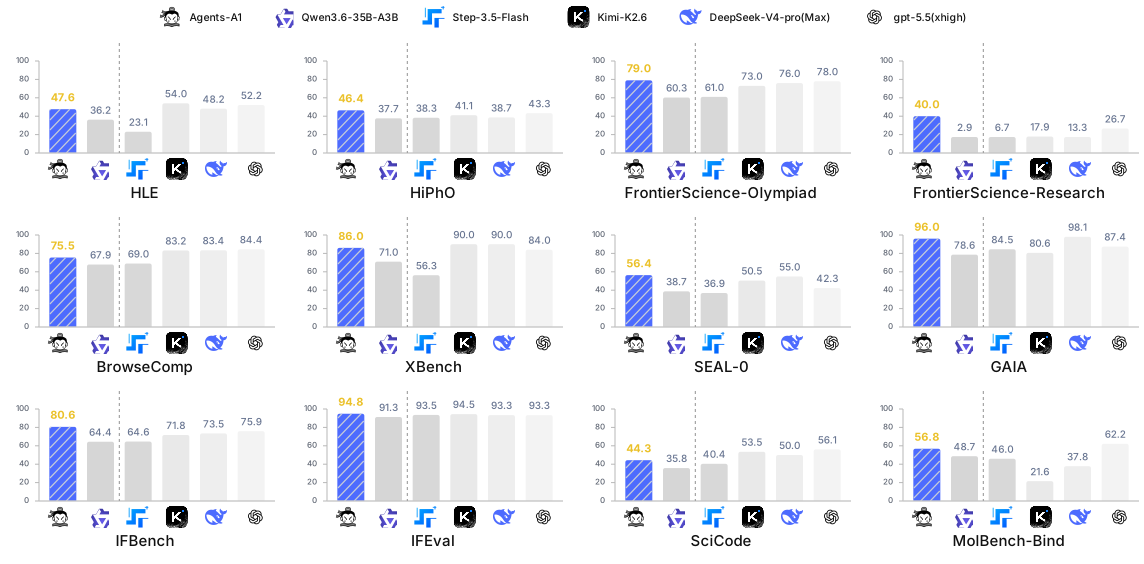
We evaluate Agents-A1 in real-world agentic and research-oriented workflows across six directions — long-horizon search, engineering tasks, scientific research, instruction following, general agentic tasks, and scientific agentic tasks. Despite operating in the ~35B model class, Agents-A1 delivers highly competitive performance against frontier-scale systems such as GPT-5.5, DeepSeek-V4-pro, and Kimi-K2.6. It achieves overall SOTA results on several challenging benchmarks, including Seal-0 (56.4), HiPhO (46.4), FrontierScience-Olympiad (79.0), FrontierScience-Research (40.00), IFBench (80.6), and IFEval (94.8), while also ranking as the best among comparable models on a broad range of tasks such as BrowseComp (75.5), XBench-DS-2510 (86.0), GAIA (96.0), SciCode (44.3), HLE with tools (47.6), and MolBench-bind (56.8). These results show that Agents-A1 combines strong long-horizon search ability, robust scientific reasoning, and reliable instruction following, establishing it as a highly capable and efficient agentic model that narrows the gap with much larger frontier models.
🥇 Overall SOTA
🟢 Best Among Comparable Models (~35B)
| Benchmark |
📏 Comparable Models (~35B)
|
🚀 Larger-scale Models
|
⭐ Ours
|
| Qwen3.5-35B-A3B |
Qwen3.6-35B-A3B |
Nex-N2-mini |
Step-3.5-Flash |
Kimi-K2.6 |
DeepSeek-V4-pro(Max) |
GPT-5.5(xhigh) |
Agents-A1 |
| 🔍 Long-horizon Search |
| BrowseComp |
61.0 |
67.93 |
74.1 |
69.0 |
83.2 |
83.4 |
🥇 84.4 |
🟢 75.51 |
| XBench-DS-2510 |
77.0 |
71.0 |
82.0 |
56.3 |
🥇 90.0 |
🥇 90.0 |
84.0 |
🟢 86.0 |
| Seal0 |
41.4 |
38.74 |
49.55 |
36.94 |
50.45 |
54.95 |
42.34 |
🥇 56.36 |
| GAIA |
59.8 |
78.64 |
82.52 |
84.5 |
80.58 |
🥇 98.06 |
87.38 |
🟢 96.04 |
| ⚙️ Engineering Tasks |
| SciCode |
37.7 |
35.8 |
29.9 |
40.4 |
53.5 |
50.0 |
🥇 56.1 |
🟢 44.33 |
| MLE-Lite |
24.24 |
34.85 |
34.85 |
54.55 |
62.12 |
63.64 |
🥇 72.73 |
🟢 43.94 |
| 🧪 Scientific Research |
| HLE w/ tools |
47.4 |
36.2 |
32.0 |
23.1 |
🥇 54.0 |
48.2 |
52.2 |
🟢 47.6 |
| HiPhO |
37.0 |
37.7 |
38.5 |
38.3 |
41.1 |
38.7 |
43.3 |
🥇 46.4 |
| FrontierScience-Olympiad |
64.5 |
60.3 |
52.0 |
61.0 |
73.0 |
76.0 |
78.0 |
🥇 79.0 |
| FrontierScience-Research |
2.5 |
2.9 |
5.0 |
6.7 |
17.9 |
13.3 |
26.7 |
🥇 40.0 |
| 📋 Instruction Following |
| IFBench |
70.2 |
64.4 |
54.08 |
64.6 |
71.77 |
73.47 |
75.9 |
🥇 80.61 |
| LongBench-v2 |
59.0 |
57.7 |
59.6 |
57.5 |
62.0 |
🥇 64.3 |
- |
🟢 60.2 |
| IFEval |
91.9 |
91.3 |
88.4 |
93.53 |
94.45 |
93.35 |
93.35 |
🥇 94.82 |
| 🤖 General Agentic Tasks |
| τ2-Bench |
🟢 81.2 |
79.0 |
74.53 |
75.77 |
81.93 |
🥇 82.2 |
81.63 |
79.81 |
| VitaBench |
31.9 |
35.6 |
23.0 |
30.0 |
35.63 |
🥇 49.04 |
45.0 |
🟢 38.75 |
| 🔬 Scientific Agentic Tasks |
| MatTools |
21.0 |
15.9 |
34.1 |
44.93 |
63.8 |
47.1 |
🥇 68.8 |
🟢 47.1 |
| MolBench-bind |
46.0 |
48.7 |
51.4 |
45.95 |
21.6 |
37.8 |
🥇 62.2 |
🟢 56.8 |
## Usage
### SGLang
[SGLang](https://github.com/sgl-project/sglang) is a fast serving framework for large language models and vision language models.
Install SGLang with uv:
```shell
uv venv --python 3.12 --seed --managed-python
source .venv/bin/activate
uv pip install sglang
```
See [its documentation](https://docs.sglang.ai/get_started/install.html) for more details.
The following commands create API endpoints at `http://localhost:8000/v1`:
- **Standard Version** (1 GPUs, 262K context):
```shell
python -m sglang.launch_server \
--model-path InternScience/Agents-A1 \
--port 8000 \
--tp-size 1 \
--mem-fraction-static 0.8 \
--context-length 262144 \
--reasoning-parser qwen3
```
- **Tool Use**:
```shell
python -m sglang.launch_server \
--model-path InternScience/Agents-A1 \
--port 8000 \
--tp-size 1 \
--mem-fraction-static 0.8 \
--context-length 262144 \
--reasoning-parser qwen3 \
--tool-call-parser qwen3_coder
```
### vLLM
[vLLM](https://github.com/vllm-project/vllm) is a high-throughput and memory-efficient inference and serving engine for LLMs.
Install vLLM from the main branch via uv:
```shell
uv venv --python 3.12 --seed --managed-python
source .venv/bin/activate
uv pip install vllm --torch-backend=auto
```
See [its documentation](https://docs.vllm.ai/en/stable/getting_started/installation/index.html) for more details.
The following commands create API endpoints at `http://localhost:8000/v1`:
- **Standard Version** (1 GPUs, 262K context):
```shell
vllm serve InternScience/Agents-A1 \
--port 8000 \
--tensor-parallel-size 1 \
--max-model-len 262144 \
--reasoning-parser qwen3
```
- **Tool Call**:
```shell
vllm serve InternScience/Agents-A1 \
--port 8000 \
--tensor-parallel-size 1 \
--max-model-len 262144 \
--reasoning-parser qwen3 \
--enable-auto-tool-choice \
--tool-call-parser qwen3_coder
```
- **Text-Only** (skips vision encoder to free KV cache memory):
```shell
vllm serve InternScience/Agents-A1 \
--port 8000 \
--tensor-parallel-size 1 \
--max-model-len 262144 \
--reasoning-parser qwen3 \
--language-model-only
```
> [!Note]
> For multi-GPU deployment, e.g., serving the model on 4 GPUs, please refer to the example launch script in the [`scripts/`](./scripts) directory.
### Recommended Sampling Parameters
For the best generation quality, we recommend the following sampling parameters:
- `temperature`: 0.85
- `top_p`: 0.95
- `top_k`: 20
- `min_p`: 0.0
- `presence_penalty`: 1.1
- `repetition_penalty`: 1.0
## Agent Capability Evaluation
To provide the community with a unified agent evaluation codebase for fair comparison, we have also open-sourced an evaluation framework for assessing agentic models across core capabilities, including tool use and multi-step reasoning. The evaluation code is included in the [`evaluation/`](./evaluation) of this repository.
We use this framework to evaluate the released model under a standardized and reproducible setting.
Specifically, the model is tested on a set of agent-oriented tasks that require it to understand user goals, decompose complex instructions, interact with tools or environments when necessary, and produce final results. The evaluation results reported in [Model Card](https://huggingface.co/InternScience/Agents-A1) are generated using the open-source framework above, so that users can reproduce the experiments, compare other models under the same protocol, and further extend the benchmark for new agent scenarios. (**Note that:** To ensure a fair comparison, we report the benchmark results from their original technical reports. If a model does not report the corresponding benchmark results, we evaluate it using the same evaluation protocol as our model.)
For detailed evaluation scripts, task definitions, metrics, and reproduction instructions, please refer to the evaluation codebase.
## Citation
If you find our work helpful, feel free to give us a cite.
```
@misc{bai2026scalinghorizonparametersreaching,
title={Scaling the Horizon, Not the Parameters: Reaching Trillion-Parameter Performance with a 35B Agent},
author={Lei Bai and Zongsheng Cao and Yang Chen and Zhiyao Cui and Shangheng Du and Yue Fan and Shiyang Feng and Zijie Guo and Haonan He and Liang He and Xiaohan He and Shuyue Hu and Yusong Hu and Songtao Huang and Yichen Jiang and Hao Li and Xin Li and Dahua Lin and Weihao Lin and Fenghua Ling and Dongrui Liu and Zhuo Liu and Runmin Ma and Chunjiang Mu and Haoyang Peng and Tianshuo Peng and Jinxin Shi and Luohe Shi and Boyuan Sun and Zelin Tan and Shengji Tang and Qianyi Wang and Yiming Wu and Yi Xie and Xiangchao Yan and Jingqi Ye and Peng Ye and Fangchen Yu and Jiakang Yuan and Bihao Zhan and Bo Zhang and Chen Zhang and Shufei Zhang and Shuaiyu Zhang and Wenlong Zhang and Yiqun Zhang and Junpeng Zhao and Zhijie Zhong and Bowen Zhou and Yuhao Zhou},
year={2026},
eprint={2606.30616},
archivePrefix={arXiv},
primaryClass={cs.CL},
url={https://arxiv.org/abs/2606.30616},
}
```