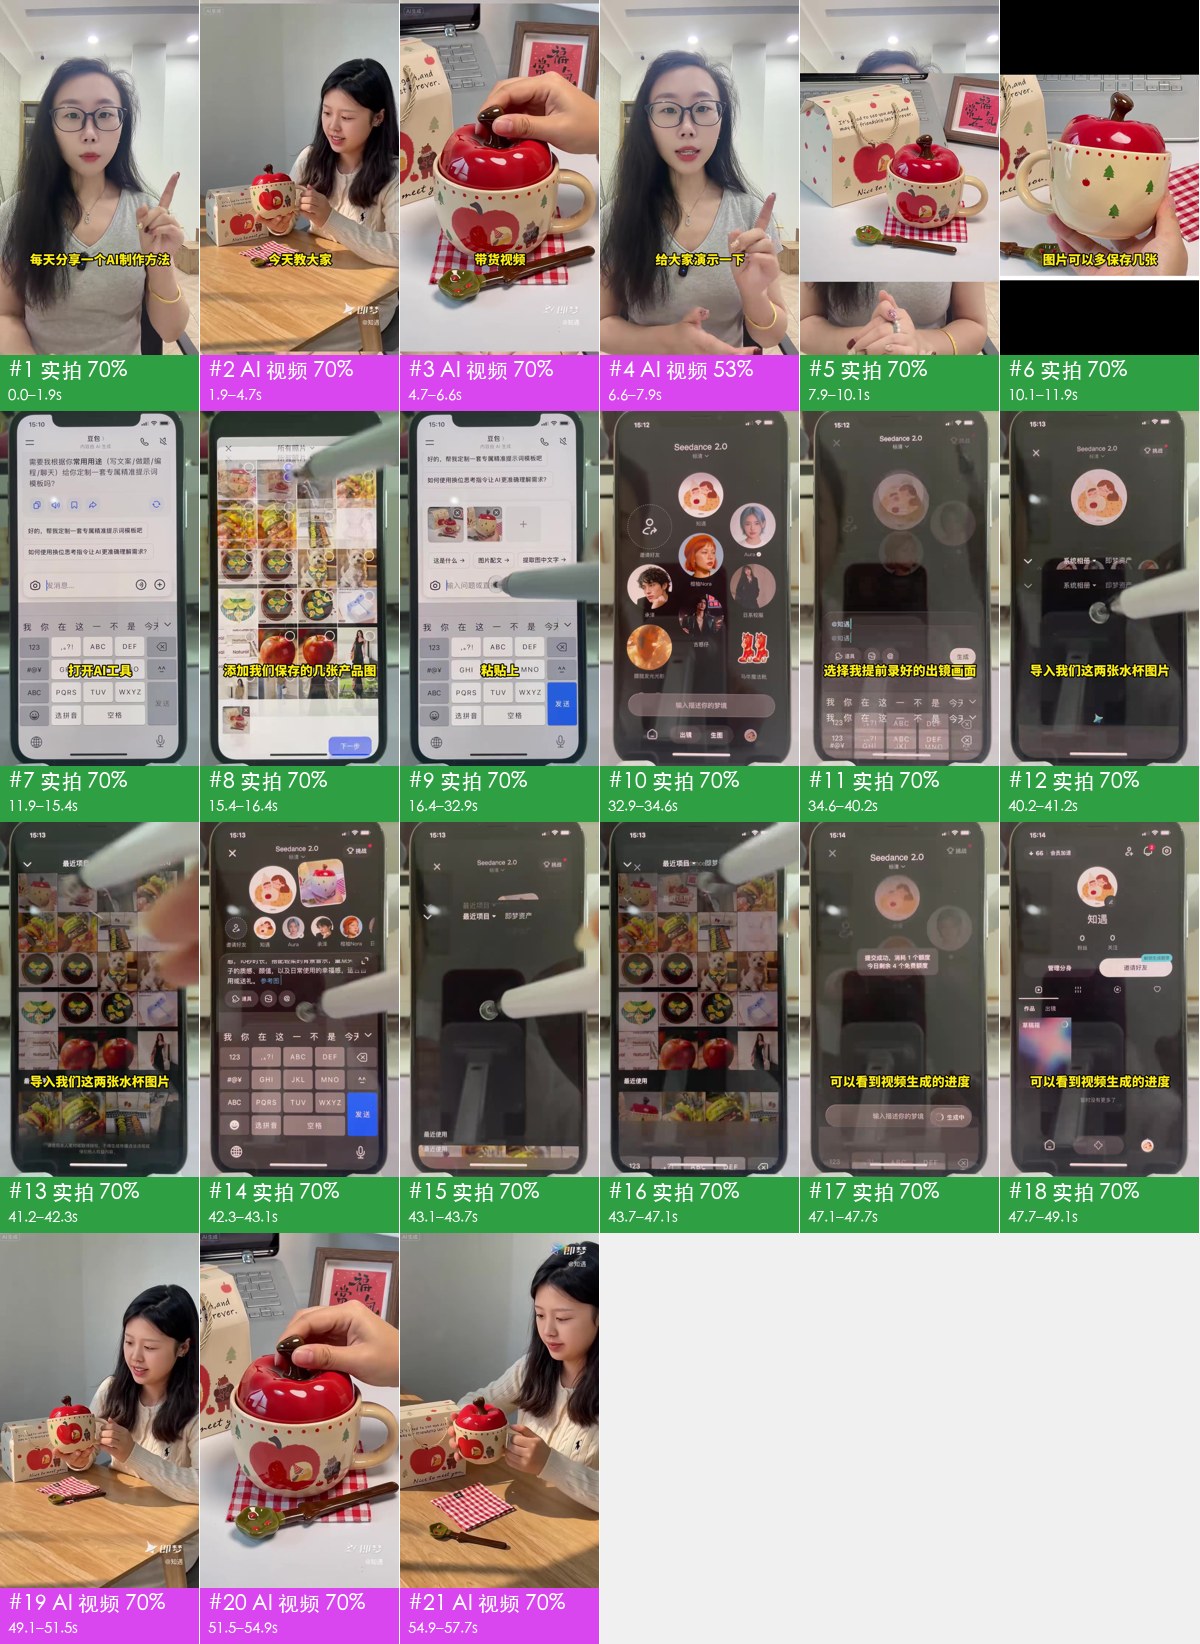
# Video breakdown report: chenxi_ai_daihuo.mp4 > English translation of [report.md](report.md), the Markdown report rea-video generated for this video. Section order and content follow the tool output. Text recognized on screen (the "text track" lines, text on objects in the frame and the packaging-table text) is kept in the original Chinese, since that is what appears in the frame. **Verdict**: mixed production: live footage 75% + AI-generated video 25% (for 100% of the duration the evidence for live vs. AI is insufficient, to be confirmed); overlays: styled text, text labels, graphic stickers, captions, title (composited in code / an editor); real material used: live video footage (43.1 s); references to prepare for a remake: product reference photos (4 shots); audio: voice + BGM at 114.8 BPM (library music) + 31 sound effects; editing and packaging: 300 captions, 4 styled-text items, 56 text labels, 29 sound effects timed to text / sticker entrances - Duration 57.667 s · 1080×1920 · 30.0 fps · 9:16 - 21 shots, 2.75 s average; transitions: cut×20, start×1 - Confidence (duration-weighted): 70%; method: deterministic forensics fused with a vision model (VLM) - VLM active (gemini-3.1-pro-preview, gemini-3.1-pro-preview-pc, gcp-gemini-3-pro-preview @ daydream88.fun); the agent (claude) visually reviewed 21 of 21 shots, merged into the verdict ![storyboard](storyboard.jpg) ## Production method share | Underlying picture | Duration | Share | |---|---|---| | Live footage | 43.13 s | 75% | | AI-generated video | 14.53 s | 25% | ## Remake plan **6 AI shots → 6 generation units, 6 Seedance 2.5 calls; 15 live-action shots → 2 scenes, 4 camera setups** - The default engine, Seedance 2.0 (including Mini / Fast), cannot produce several shots in one call; with it you would generate the 6 shots one by one. This plan assumes Seedance 2.5 (≤30 s per call, multi-shot in one call): 6 calls in total - Grouping rules: AI shots in the same set joined by hard cuts are merged into one generation (S01); ≤30 s per call; consecutive hard cuts inside a unit should stay ≤8 s, at most 10 s (S06); split at dissolves / fades and set changes (S03) - Audio: the model can generate action sound effects and ambience along with the picture; voice-over is better done as separate TTS and mixed in, so you can change the script and timing ### Generation units | Unit | Shots | Time | Duration | Method | Continuity | |---|---|---|---|---|---| | G1 | #2 | 1.9–4.7 s | 2.8 s | single shot | First frame: generate an image with the composition of the original shot 2 first frame (shots/shot_002_first.jpg) | | G2 | #3 | 4.7–6.6 s | 1.9 s | single shot | First frame: generate an image with the composition of the original shot 3 first frame (shots/shot_003_first.jpg) | | G3 | #4 | 6.6–7.9 s | 1.3 s | single shot | First frame: generate an image with the composition of the original shot 4 first frame (shots/shot_004_first.jpg) | | G4 | #19 | 49.1–51.5 s | 2.4 s | single shot | First frame: generate an image with the composition of the original shot 19 first frame (shots/shot_019_first.jpg) | | G5 | #20 | 51.5–54.9 s | 3.4 s | single shot | First frame: generate an image with the composition of the original shot 20 first frame (shots/shot_020_first.jpg) | | G6 | #21 | 54.9–57.7 s | 2.8 s | single shot | First frame: generate an image with the composition of the original shot 21 first frame (shots/shot_021_first.jpg) | **G1 · AI-generated video · shot #2 · 2.8 s** - Reference material: `@image1` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 1.9–4.7 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture) - First-frame image prompt: vertical 9:16, cozy tabletop scene: a long-haired young woman in a cream sweater sits at a natural-wood table holding a red apple-shaped ceramic mug with both hands (the lid is an apple, the beige body printed with small trees and apples), a beige gift box printed with apples behind her, a red-and-white gingham cloth and a wooden spoon on the table; soft natural light, light-colored wall softly blurred behind, photorealistic product-video style - Generate 4 s and trim to 2.8 s (very short shots are unstable when generated on their own) ```text Vertical 9:16; frontal soft light (flat), soft light (almost no shadow edge), warm (about 3000–4000K), background sharp. Character per @image1. Follow @video1 for motion, camera and cut rhythm. Smiling, the young woman picks up the apple-shaped ceramic mug from the table, holds it with both hands at chest height toward the camera and gently turns it so the apple print faces the lens; the camera pushes in slowly from a medium shot to a close-up of the mug, ending with the mug filling the center of the frame ```
English prompt (as generated by the tool) ```text A young woman in a cream sweater picks up an apple-shaped ceramic mug from a wooden table, holds it with both hands toward the camera and slowly turns it to show the apple print; the camera pushes in from a medium shot to a close-up of the mug, ending with the mug centered and filling the frame ```
**G2 · AI-generated video · shot #3 · 1.9 s** - Reference material: `@image1` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 4.7–6.6 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture) - First-frame image prompt: vertical 9:16, cozy tabletop scene: a long-haired young woman in a cream sweater sits at a natural-wood table holding a red apple-shaped ceramic mug with both hands (the lid is an apple, the beige body printed with small trees and apples), a beige gift box printed with apples behind her, a red-and-white gingham cloth and a wooden spoon on the table; soft natural light, light-colored wall softly blurred behind, photorealistic product-video style - Generate 4 s and trim to 1.9 s (very short shots are unstable when generated on their own) ```text Vertical 9:16; frontal soft light (flat), soft light (almost no shadow edge), warm (about 3000–4000K), background sharp. Character per @image1. Follow @video1 for motion, camera and cut rhythm. Smiling, the young woman picks up the apple-shaped ceramic mug from the table, holds it with both hands at chest height toward the camera and gently turns it so the apple print faces the lens; the camera pushes in slowly from a medium shot to a close-up of the mug, ending with the mug filling the center of the frame ```
English prompt (as generated by the tool) ```text A young woman in a cream sweater picks up an apple-shaped ceramic mug from a wooden table, holds it with both hands toward the camera and slowly turns it to show the apple print; the camera pushes in from a medium shot to a close-up of the mug, ending with the mug centered and filling the frame ```
**G3 · AI-generated video · shot #4 · 1.3 s** - Reference material: `@image1` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 6.6–7.9 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture) - First-frame image prompt: vertical, close-up, a young Asian woman with black-framed glasses, gray short-sleeved V-neck top, wearing a necklace, facing the camera, indoor background, white wall, downlights in the ceiling, bright frontal soft light, photorealistic photography style - Generate 4 s and trim to 1.3 s (very short shots are unstable when generated on their own) ```text Vertical 9:16; frontal soft light (flat), soft light (almost no shadow edge), warm (about 3000–4000K), background sharp. Character per @image1. Follow @video1 for motion, camera and cut rhythm. A young woman with black-framed glasses talks to the camera; she first raises her right index finger for emphasis, then naturally brings her hands together in front of her chest; smooth movements, fixed camera ```
English prompt (as generated by the tool) ```text A young woman wearing black-framed glasses is talking to the camera. She first raises her right index finger to emphasize a point, then naturally clasps her hands together in front of her chest. Smooth movements, fixed camera. ```
**G4 · AI-generated video · shot #19 · 2.4 s** - Reference material: `@image1` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 49.1–51.5 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture) - First-frame image prompt: vertical 9:16, cozy tabletop scene: a long-haired young woman in a cream sweater sits at a natural-wood table holding a red apple-shaped ceramic mug with both hands (the lid is an apple, the beige body printed with small trees and apples), a beige gift box printed with apples behind her, a red-and-white gingham cloth and a wooden spoon on the table; soft natural light, light-colored wall softly blurred behind, photorealistic product-video style - Generate 4 s and trim to 2.4 s (very short shots are unstable when generated on their own) ```text Vertical 9:16; frontal soft light (flat), soft light (almost no shadow edge), warm (about 3000–4000K), background sharp. Character per @image1. Follow @video1 for motion, camera and cut rhythm. Smiling, the young woman picks up the apple-shaped ceramic mug from the table, holds it with both hands at chest height toward the camera and gently turns it so the apple print faces the lens; the camera pushes in slowly from a medium shot to a close-up of the mug, ending with the mug filling the center of the frame ```
English prompt (as generated by the tool) ```text A young woman in a cream sweater picks up an apple-shaped ceramic mug from a wooden table, holds it with both hands toward the camera and slowly turns it to show the apple print; the camera pushes in from a medium shot to a close-up of the mug, ending with the mug centered and filling the frame ```
**G5 · AI-generated video · shot #20 · 3.4 s** - Reference material: `@image1` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 51.5–54.9 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture) - First-frame image prompt: vertical 9:16, cozy tabletop scene: a long-haired young woman in a cream sweater sits at a natural-wood table holding a red apple-shaped ceramic mug with both hands (the lid is an apple, the beige body printed with small trees and apples), a beige gift box printed with apples behind her, a red-and-white gingham cloth and a wooden spoon on the table; soft natural light, light-colored wall softly blurred behind, photorealistic product-video style - Generate 4 s and trim to 3.4 s (very short shots are unstable when generated on their own) ```text Vertical 9:16; frontal soft light (flat), soft light (almost no shadow edge), warm (about 3000–4000K), background sharp. Character per @image1. Follow @video1 for motion, camera and cut rhythm. Smiling, the young woman picks up the apple-shaped ceramic mug from the table, holds it with both hands at chest height toward the camera and gently turns it so the apple print faces the lens; the camera pushes in slowly from a medium shot to a close-up of the mug, ending with the mug filling the center of the frame ```
English prompt (as generated by the tool) ```text A young woman in a cream sweater picks up an apple-shaped ceramic mug from a wooden table, holds it with both hands toward the camera and slowly turns it to show the apple print; the camera pushes in from a medium shot to a close-up of the mug, ending with the mug centered and filling the frame ```
**G6 · AI-generated video · shot #21 · 2.8 s** - Reference material: `@image1` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 54.9–57.7 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture) - First-frame image prompt: vertical 9:16, cozy tabletop scene: a long-haired young woman in a cream sweater sits at a natural-wood table holding a red apple-shaped ceramic mug with both hands (the lid is an apple, the beige body printed with small trees and apples), a beige gift box printed with apples behind her, a red-and-white gingham cloth and a wooden spoon on the table; soft natural light, light-colored wall softly blurred behind, photorealistic product-video style - Generate 4 s and trim to 2.8 s (very short shots are unstable when generated on their own) ```text Vertical 9:16; frontal soft light (flat), soft light (almost no shadow edge), warm (about 3000–4000K), background sharp. Character per @image1. Follow @video1 for motion, camera and cut rhythm. Smiling, the young woman picks up the apple-shaped ceramic mug from the table, holds it with both hands at chest height toward the camera and gently turns it so the apple print faces the lens; the camera pushes in slowly from a medium shot to a close-up of the mug, ending with the mug filling the center of the frame ```
English prompt (as generated by the tool) ```text A young woman in a cream sweater picks up an apple-shaped ceramic mug from a wooden table, holds it with both hands toward the camera and slowly turns it to show the apple print; the camera pushes in from a medium shot to a close-up of the mug, ending with the mug centered and filling the frame ```
### Shooting sessions Shoot all the shots of one scene before moving to the next; within a scene shoot the wider sizes first, then the close-ups, so the lighting need not be reset. Leave about 1 s of handle at each end of every take. **S1**: shots #1, #5, #6, #7, #8, #9 (26.93 s in the cut); a woman with glasses delivers a voice-over explanation in a bright interior, raising one hand in an emphasis gesture, fixed close-up setup, even diffused light from above. - Lighting: backlit / background brighter than the subject, frontal (from the camera direction, both sides of the subject equally bright), about 1.1:1 (0.1 stops), neutral (about 5000K) - Setup close-up · moving (gimbal / handheld pan) · pan / track: shot #1, 1.93 s in the cut, suggested take 3.9 s - Setup close-up · fixed (tripod / stand / on a table) · static: shots #5, #6, #7, #8, #9, 25.0 s in the cut, suggested take 35.0 s **S2**: shots #10, #11, #12, #13, #14, #15, #16, #17, #18 (16.2 s in the cut); a close-up of a phone screen showing the Seedance 2.0 app; a hand holding a stylus taps an orange-haired girl avatar icon on the screen. - Lighting: frontal soft light (flat), frontal (from the camera direction, both sides of the subject equally bright), about 1.0:1 (0.1 stops), neutral (about 5000K) - Setup close-up · fixed (tripod / stand / on a table) · static: shots #10, #11, #12, #14, #16, #17, #18, 14.47 s in the cut, suggested take 28.5 s - Setup close-up · moving (gimbal / handheld pan) · static / pan / track: shots #13, #15, 1.73 s in the cut, suggested take 5.7 s ## Framing, lighting and editing - Framing: shot size close-up (phone screen) 86%, close-up (head and shoulders) 9%, close-up 4%; angle slightly high (phone standing / tilted on the desk, camera from front above); subject is the sharpest region of the frame (no face, shot size is an estimate) - Camera: fixed (tripod / stand / on a table) 92%, moving (gimbal / handheld pan) 8%; common move pan / track - Lighting: frontal soft light (flat). Key frontal (from the camera direction, both sides of the subject equally bright), level with the subject; contrast ratio about 1.1:1 (0.2 stops); soft light (wide shadow transition); neutral color temperature (about 5000K); background clearly blurred (shallow depth of field / portrait mode) - Grade: natural (close to source); normal saturation, normal contrast, normal blacks, neutral overall - Editing: 20.8 cuts per minute, 2.88 s average live-action shot; 5 setups / scenes; 0 jump cuts on the same setup, 4 punch-in cuts; inserts (screenshots / screen recordings / cards / stock) 25%; 31% of cuts land on speech pauses - Form: tabletop / product shooting (desk shot) (face as subject 4%, objects / hands as subject 96%, handheld 9%); visual judgment: voice-over tutorial + live phone-screen demo + AI-generated product-video segments (the creator's on-camera footage used as subject reference) **Live-action shooting plan** 1. Form: tabletop / product shooting 2. Framing: mainly close-up (phone screen), slightly high angle (phone standing / tilted on the desk, camera from front above) 3. Camera: fixed (tripod / stand / on a table) 92%, moving (gimbal / handheld pan) 8%; common move pan / track 4. Lighting: frontal soft light (flat): a large source from the camera direction, almost no shadows on the subject: face a window, use a ring light, or put a large softbox behind the camera 5. Editing: 20.8 cuts per minute, 2.88 s average live-action shot; 5 setups / scenes; 0 jump cuts on the same setup, 4 punch-in cuts; inserts (screenshots / screen recordings / cards / stock) 25%; 31% of cuts land on speech pauses Gear: - One large soft light directly above the desk / behind the camera (or two, symmetric at 45° left and right) - A white desktop or a white card bounce makes the shadows lighter - Note: background clearly blurred (shallow depth of field / portrait mode) | Dimension | Item | Conclusion | Source | |---|---|---|---| | Framing | Shot size | Close-up (phone screen) | Measured: close-up (phone screen); VLM: close-up; visual review: close-up (phone screen) | | Framing | Angle | Slightly high (phone standing / tilted on the desk, camera from front above) | VLM: eye level; visual review: slightly high (phone standing / tilted on the desk, camera from front above) | | Framing | Composition | Phone centered and filling the vertical frame, finger and stylus entering from the right | VLM: centered composition, the phone screen fills the vertical frame; visual review: phone centered and filling the vertical frame, finger and stylus entering from the right | | Camera | Support | Tripod / stand, fixed | Measured: fixed (tripod / stand / on a table); VLM: tripod / stand, fixed; visual review: tripod / stand, fixed | | Camera | Lens | Phone rear main camera | VLM: phone rear main camera; visual review: phone rear main camera | | Camera | Speed | Normal | VLM: normal; visual review: normal | | Camera | Setups / scene | Two live-action setups: (1) phone front-camera selfie voice-over (head-and-shoulders close-up, office corridor); (2) phone on a stand shot from above on the desk for the operation demo (37 s). The product video itself was generated by Jimeng Seedance 2.0 and does not need to be shot | VLM: setup 1: creator's frontal half-body selfie voice-over (phone front camera, vertical); setup 2: macro high-angle / close-up of the phone screen for hands-on operation (demonstrated with a capacitive stylus); setup 3: full-screen display of the AI-generated product video; visual review: two live-action setups: (1) phone front-camera selfie voice-over (head-and-shoulders close-up, office corridor); (2) phone on a stand shot from above on the desk for the operation demo (37 s). The product video itself was generated by Jimeng Seedance 2.0 and does not need to be shot | | Camera | Likely gear | One phone + a small stand; no lighting gear | VLM: smartphone front camera for the voice-over + rear camera for the close-up operation footage + capacitive stylus; visual review: one phone + a small stand; no lighting gear | | Lighting | Scene | Indoor, daytime, office desk | VLM: indoor, daytime; visual review: indoor, daytime, office desk | | Lighting | Key | Ceiling light from above, with a band of ceiling-light reflection on the screen | VLM: diffused natural light from above plus the phone screen's own glow; visual review: ceiling light from above, with a band of ceiling-light reflection on the screen | | Lighting | Softness | Soft (wide shadow transition) | Measured: soft (wide shadow transition); VLM: soft; visual review: soft | | Lighting | Fill | The phone screen itself is the main bright source | VLM: ambient diffuse fill; visual review: the phone screen itself is the main bright source | | Lighting | Rim | None | VLM: none; visual review: none | | Lighting | Catchlight | Ceiling-light reflection on the glasses, catchlight not obvious | VLM: point / ring catchlight; visual review: ceiling-light reflection on the glasses, catchlight not obvious | | Lighting | Visible sources | Phone screen, ceiling-light reflection on the screen | VLM: phone display; visual review: phone screen, ceiling-light reflection on the screen | | Lighting | Color temperature | Neutral (about 5000K) | Measured: neutral (about 5000K); VLM: neutral cool white; visual review: neutral | | Lighting | Setup | Overhead desk shot + ambient top light | VLM: indoor overhead flood plus the phone screen's own glow; visual review: overhead desk shot + ambient top light | | Lighting | Overall | Ambient indoor top light throughout, no dedicated lighting; in the voice-over segments the face is evenly lit and slightly dark, in the phone demo the screen is the main bright source | VLM: indoor fluorescent top lighting, the face evenly lit during the voice-over with a little indoor flood; visual review: ambient indoor top light throughout, no dedicated lighting; in the voice-over segments the face is evenly lit and slightly dark, in the phone demo the screen is the main bright source | | Grade | Style | Natural (close to source) | Measured: natural (close to source); VLM: natural documentary look, normal exposure and neutral color; visual review: natural | | Grade | Overall | Natural, straight out of the phone, slightly underexposed and desaturated | VLM: natural-color live footage, the phone screen bright and clear, the finished-video section in warm bright natural tones; visual review: natural, straight out of the phone, slightly underexposed and desaturated | | Editing | Technique | Tutorial structure: 3 s voice-over intro → 4.7 s AI-video preview → 1.3 s voice-over → 4 s product-photo picture-in-picture → 37 s phone operation demo (cut into 12 shots by step) → 8.5 s AI-video ending (the same clip as the opening). Yellow captions with black outline follow the voice-over line by line; key steps get an extra yellow-box tip | VLM: tight tutorial jump cuts, no filler between steps, hands-on phone operation intercut with the finished video; visual review: tutorial structure: 3 s voice-over intro → 4.7 s AI-video preview → 1.3 s voice-over → 4 s product-photo picture-in-picture → 37 s phone operation demo (cut into 12 shots by step) → 8.5 s AI-video ending (the same clip as the opening). Yellow captions with black outline follow the voice-over line by line; key steps get an extra yellow-box tip | | Form | Video form | Voice-over tutorial + live phone-screen demo + AI-generated product-video segments (the creator's on-camera footage used as subject reference) | Measured: tabletop / product shooting (desk shot); VLM: voice-over + overhead desk shot / unboxing / tutorial; visual review: voice-over tutorial + live phone-screen demo + AI-generated product-video segments (the creator's on-camera footage used as subject reference) | - Note: contrast ratio, softness, color temperature and shot size are measured on the subject's pixels (the face when there is one, otherwise the sharpest region, which is an estimate); platform transcoding crushes shadows, so softness and fill read conservative; angle, light source type, catchlight and rim come from visual review. Where measurement and visual review disagree, both are listed. ## Metadata clues - Encoder: `Lavf58.76.100` - platform: Douyin/TikTok ## Audio breakdown ![audio](audio.png) - Overall loudness −17.3 dBFS, peak −0.2 dBFS - **Voice**: present, 75% of duration, fundamental about 210.0 Hz (reads female) - **Background music**: 79% of duration (0.0–57.0 s), about 114.8 BPM (or 57.4 / 229.7), key F major (confidence 0.746), section changes at 41.0 s, 45.0 s - **Cuts vs beat**: 25% of cuts land on a beat (random baseline about 21%) **Audio source: AI-generated or existing material** - **Conclusion**: video type: live footage (sync sound + music added in post) → voice: human recording; music: library music; sound effects: live sync sound - **Separated stems**: `stems/original.wav` (original), `stems/vocals.wav` (dry voice; transient effects land here too), `stems/music.wav` (music + ambience) - Video form: explainer; AI picture 25%, live footage 75% - **Background music**: library music (existing_library 72%, popular_song 18%, ai_generated 10%) - The music is a bed under the picture: for an ordinary video the bed is most likely from a library (prior) - VLM listening judgment: library music - The music is cut off hard at the end (the video ends while it is still at full volume): typical of an excerpt from an existing track - How to confirm: on the Douyin / Xiaohongshu page check the music tag: a song title → existing track; "original sound by @author" → uploaded by the author (for music videos this is usually an AI song) - How to confirm: run Soda Music / QQ Music song recognition or ACRCloud: a hit means an existing song - How to confirm: listen: AI songs often have slurred diction, thin metallic highs and lyrics that track the picture closely; library beds are mostly instrumental, standard structure, cut off or faded at the end - **Voice**: human recording (human_recording 83%, tts 13%, ai_video_native 4%) - VLM judged it a human voice - 75% of the picture is live footage: the voice is most likely sync sound or a human voice-over - **Sound effects**: live sync sound (live_sync 65%, library_editor 24%, ai_native 12%) - The picture is mostly live footage: the ambience is most likely sync sound - Per-segment native-audio check: background change 6.8 dB at cuts, 8.5 dB within shots (ratio 0.79) → the sound runs continuously across cuts; it was laid over the whole cut in post **Sound effects** (31; source: vlm = heard by the model, deterministic = signal-detected candidate, low confidence) | Time | Type | Description | Matching picture | Source | |---|---|---|---|---| | 2.55 s | ding | text label 「nayaftrinnun」 appears | | deterministic_anchored | | 3.92 s | pop | text label 「odtssca」 appears | | deterministic_anchored | | 8.00 s | pop | styled text 「I+'s aod to see 」 appears | caption 「保存好要带货的水杯图片」 appears | deterministic_anchored | | 12.06 s | pop | text label 「三」 appears | caption 「豆包 内容由AI生成 需要我根据」 appears | deterministic_anchored | | 13.06 s | ding | text label 「帮我写」 appears | caption 「口」 appears | deterministic_anchored | | 14.81 s | whoosh | text label 「如」 appears | caption 「相册」 appears | deterministic_anchored | | 14.95 s | pop | text label 「量」 appears | caption 「相册」 appears | deterministic_anchored | | 15.44 s | ding | text label 「Natural」 appears | caption 「Natural」 appears | deterministic_anchored | | 25.46 s | ding | text label 「三」 appears | caption 「以生成带货视频的提示词,真人带货」 appears | deterministic_anchored | | 25.98 s | ding | text label 「7」 appears | caption 「内容由AI生成」 appears | deterministic_anchored | | 29.56 s | ding | text label 「这里给你3条适配10秒真人带货视」 appears | caption 「快时:」 appears | deterministic_anchored | | 30.09 s | ding | text label 「油色陶瓷杯,对着镜头开心展示。快」 appears | caption 「这里给你3条适配10秒真人带货视」 appears | deterministic_anchored | | 30.28 s | pop | text label 「子、红苹果杯盖,搭配轻快的背景音」 appears | caption 「《不」 appears | deterministic_anchored | | 30.92 s | pop | text label 「BGM)」 appears | caption 「喝水超有仪式感,适合送闺蜜的可爱」 appears | deterministic_anchored | | 31.77 s | pop | | caption 「真人出镜,元气 油色陶瓷杯,」 appears | deterministic | | 33.08 s | ding | | caption 「承泽」 appears | deterministic | | 33.54 s | pop | text label 「生成」 appears | caption 「道具 道具」 appears | deterministic_anchored | | 34.62 s | pop | text label 「@知遇 @知遇」 appears | caption 「123 123」 appears | deterministic_anchored | | 39.03 s | ding | text label 「恩,IU秒时长,拾配轻采的月京首」 appears | text label 「恩,IU秒时长,拾配轻采的月京首」 appears | deterministic_anchored | | 39.31 s | pop | text label 「子的质感、颜值,以及日常使用的幸」 appears | text label 「子的质感、颜值,以及日常使用的幸」 appears | deterministic_anchored | | 39.96 s | pop | text label 「系统相册」 appears | text label 「系统相册」 appears | deterministic_anchored | | 40.47 s | pop | text label 「ral」 appears | caption 「最近项目·即梦资产」 appears | deterministic_anchored | | 41.53 s | ding | text label 「思,U秒时长,抬配轻采的育」 appears | caption 「Seedance 2.0」 appears | deterministic_anchored | | 44.56 s | pop | | caption 「子的质感、颜值,以及日常使用的幸」 appears | deterministic | | 47.14 s | ding | text label 「提交成功,消耗1个额度」 appears | caption 「的梦境」 appears | deterministic_anchored | | 47.54 s | pop | text label 「知遇」 appears | caption 「66|会员加速」 appears | deterministic_anchored | | 50.41 s | pop | text label 「Aod tssca」 appears | text label 「Aod tssca」 appears | deterministic_anchored | | 51.41 s | ding | text label 「福」 appears | text label 「福」 appears | deterministic_anchored | | 53.52 s | ding | styled text 「gan,and」 appears | styled text 「gan,and」 appears | deterministic_anchored | | 54.40 s | pop | styled text 「礼」 appears | styled text 「礼」 appears | deterministic_anchored | | 55.09 s | pop | text label 「nayor」 appears | text label 「nayor」 appears | deterministic_anchored | **Audio remake plan** - voice (A01-narration): human voice-over / dialogue, young female, standard Mandarin, the warm, knowledgeable tone of a tutorial creator, medium-fast pace, crisp and clear, typical short-video teaching delivery → capsule-cinema DoubaoTTSTool / UniversalTTSTool (or a MiniMax cloned voice); use duration-controlled TTS (A02) when you must fit the original timing - music (A03-music): upbeat, lively tech-tutorial music, switching to a warm, relaxed lifestyle bed for the finished-video section in the second half; relaxed, everyday, soothing; 114.8 BPM; F major → the original leans library: search a library by BPM / mood / key, or generate a royalty-free track in a similar style with AI - sfx (A04-sfx): 3 effects → place them at the listed time points: capsule-cinema SoundEffectsTool / an effects library, or synthesize them procedurally like the plush recipe (pitch matched to the BGM key) - ambience (A04-sfx): quiet indoor ambience → ambience stock or a video-to-audio model - Mix: the voice-over sits clearly in front, BGM at a moderate level as a bed only, and in the finished-video section the background sound blends naturally into the product video's own voice ## Editing and packaging layer (captions / styled text / stickers / sound-effect sync) - 300 captions (middle / bottom / top, up to 5 lines): gray type, text height 2.3%; entrances: cut in ×191, zoom pop ×30, fade in ×7, slide in ×7, character by character ×5; color changes on keywords as they are spoken - 4 styled-text items (multicolor / gradient, pop-in entrance, tilted, orange type, large size, brown type): 「出镜」, 「rever.」, 「gan,and」, 「礼」 - 56 text labels (4 of them track a moving object): 「AA」, 「AA」, 「ABC ABC」, 「RXYZ」, 「Aura」, 「@知遇」 etc. - Sound-effect sync: 21 on caption entrances, 6 on text-label entrances, 2 on styled-text entrances - Export: `packaging/subtitles.srt`, `packaging/overlays.ass`, `packaging/timeline.json` (SRT is the caption timeline; ASS carries color, outline, position and entrance animation, the font must be swapped for the original's; timeline.json is the full timeline) | Time | Type | Text | Style | In / Out | SFX | |---|---|---|---|---|---| | 0.00–1.90 s | captions | 每天分享一个A制作方法 | yellow type, black outline, black box, text height 3.8% (about 74 px) | — | — | | 1.90–2.90 s | captions | 今天教大家 | yellow type, black outline, text height 4.1% (about 79 px) | cut in | — | | 1.90–5.60 s | captions | 即梦 | white type, orange keyword highlight, text height 3.0% (about 57 px) | cut in / cut out | — | | 1.90–5.10 s | captions | @知遇 | orange type, text height 2.5% (about 48 px) | cut in / shrink out | — | | 2.00–3.10 s | captions | Nicetomcet | brown type, brown outline, brown keyword highlight, text height 3.9% (about 75 px) | fade in / fade out | — | | 3.00–4.20 s | captions | 制作真人出镜的日用品 | yellow type, black outline, text height 3.8% (about 72 px) | fade in / cut out | — | | 3.20–4.20 s | captions · tracks object | Nicetomeet | black type, orange outline, text height 4.7% (about 90 px) | fade out | — | | 4.50–5.20 s | captions | 带货视频 | yellow type, black outline, text height 4.3% (about 83 px) | — | — | | 5.50–6.20 s | captions | 那我用这个水杯 | yellow type, black outline, text height 3.6% (about 69 px) | — | — | | 6.00–6.20 s | captions | s+ | orange type, text height 2.0% (about 39 px) | cut in / cut out | — | | 6.50–7.90 s | captions | 给大家演示一下 | yellow type, black outline, text height 4.1% (about 78 px) | cut out | — | | 7.90–10.10 s | captions | 福 ⏎ 氣 | brown type, text height 4.8% (about 92 px) | cut in / cut out | — | | 7.90–10.10 s | captions | Nice ta | gray type, text height 4.2% (about 81 px) | cut in / cut out | — | | 8.00–10.00 s | captions | 保存好要带货的水杯图片 | yellow type, black outline, text height 3.8% (about 72 px) | cut in | pop | | 10.00–11.90 s | captions | h,and | gray type, text height 4.5% (about 85 px) | pop in / cut out | — | | 10.00–11.90 s | captions | rever. | gray type, brown keyword highlight, text height 3.9% (about 75 px) | pop in / cut out | — | | 10.00–11.80 s | captions | 图片可以多保存几张 | yellow type, black outline, orange box, text height 3.6% (about 69 px) | cut out | — | | 11.90–15.10 s | captions | 模板吗? | gray type, gray keyword highlight, text height 2.6% (about 50 px) | cut in / shrink out (bounce / color change midway) | — | | 11.90–15.10 s | captions | 好的,帮我定制一套专属精准提示词模板吧 | gray type, gray keyword highlight, text height 2.2% (about 42 px) | cut in / slide out (bounce / color change midway) | — | | 11.90–13.00 s | captions | 我你在这一不是今天 | black type, text height 3.2% (about 62 px) | cut in / cut out | — | | 11.90–13.00 s | captions | ABC | white type, gray outline, text height 2.2% (about 42 px) | cut in / cut out | — | | 11.90–13.00 s | captions | DEF | white type, gray outline, bold, text height 2.1% (about 41 px) | cut in / cut out | — | | 11.90–13.00 s | captions | 123 | gray type, black keyword highlight, text height 2.3% (about 45 px) | cut in / cut out | — | | 11.90–13.30 s | captions | 打开AI工具 | yellow type, black outline, text height 4.1% (about 79 px) | cut in | — | | 11.90–13.30 s | captions | G | gray type, text height 1.5% (about 28 px) | cut in / cut out | — | | 11.90–13.00 s | captions | TUV | gray type, gray keyword highlight, text height 2.2% (about 42 px) | cut in / cut out | — | | 11.90–13.00 s | captions | PQRS | white type, gray outline, bold, text height 2.2% (about 43 px) | cut in / cut out | — | | 11.90–13.00 s | captions | WXYZ | gray type, gray keyword highlight, text height 2.1% (about 41 px) | cut in / cut out | — | | 11.90–13.00 s | captions | ABC | gray type, text height 2.3% (about 44 px) | cut in / cut out | — | | 11.90–13.00 s | captions | 发送 | gray type, gray outline, text height 2.5% (about 49 px) | cut in / cut out | — | | 11.90–13.00 s | captions | 选拼音 | gray type, gray outline, gray keyword highlight, text height 2.5% (about 49 px) | cut in / cut out | — | | 11.90–13.00 s | captions | 空格 | white type, gray outline, text height 2.6% (about 50 px) | cut in / cut out | — | | 11.90–15.10 s | captions | 豆包) ⏎ 内容由AI生成 | white type, gray outline, text height 2.4% (about 46 px) | cut in | — | | 12.00–12.10 s | captions | 豆包 ⏎ 内容由AI生成 ⏎ 需要我根据你常用用途(写文案 ⏎ 做题 ⏎ 编 ⏎ | gray type, gray keyword highlight, text height 2.5% (about 47 px) | cut in | pop | | 12.50–14.10 s | captions | 内容由AI生成 | gray type, text height 2.0% (about 39 px) | cut in | — | | 12.50–15.10 s | captions | 需要我根据你常用用途(写文案 ⏎ 做题 ⏎ 编 ⏎ 程 ⏎ 聊天)给你定制一套专 | gray type, gray keyword highlight, text height 2.6% (about 49 px) | slide out (bounce / color change midway) | — | | 13.00–14.40 s | captions | 拍题答疑 | white type, text height 2.3% (about 44 px) | cut in / cut out | — | | 13.00–14.40 s | captions | 文件 | white type, gray outline, text height 2.3% (about 45 px) | cut out | — | | 13.00–14.40 s | captions | 打电话 | white type, text height 2.1% (about 41 px) | cut out | — | | 13.00–14.40 s | captions | 相册 | white type, gray outline, text height 2.0% (about 39 px) | cut out | — | | 13.00–14.40 s | captions | 相机 | gray type, gray keyword highlight, text height 2.3% (about 44 px) | cut out | — | | 13.10–14.40 s | captions | 口 | gray type, bold, text height 2.7% (about 52 px) | cut in / cut out | ding | | 13.30–15.60 s | captions | 添加我们保存的几张产品图 | yellow type, black outline, text height 3.8% (about 72 px) | shrink out | — | | 13.50–15.50 s | captions | 么 | gray type, text height 2.0% (about 39 px) | cut out | — | | 14.50–14.60 s | captions | 豆包 ⏎ 内容由AI生成 ⏎ 需要我根据你常用用途(写文案 ⏎ 做题 ⏎ 编 | white type, gray outline, text height 2.4% (about 46 px) | cut in / cut out | — | | 14.50–15.40 s | captions | 照片动起来→ | gray type, gray keyword highlight, text height 2.5% (about 48 px) | slide in / cut out | — | | 14.50–15.40 s | captions | 这是什么→ | gray type, gray keyword highlight, text height 2.3% (about 44 px) | cut in / cut out | — | | 14.50–15.40 s | captions | 输入问题或直接发送.. | gray type, gray outline, text height 2.5% (about 49 px) | cut in / cut out | — | | 14.80–15.30 s | captions | 相册 | white type, text height 2.3% (about 44 px) | cut in / cut out | whoosh, pop | | 15.50–16.40 s | captions | Natural | gray type, text height 1.8% (about 34 px) | cut in / cut out | ding | | 15.50–16.40 s | captions | ral | white type, gray outline, gray keyword highlight, text height 1.5% (about 28 px) | cut in / cut out | — | | 15.50–16.40 s | captions | 下一步们 | blue type, blue box, blue keyword highlight, text height 2.9% (about 56 px) | cut in / cut out | — | | 15.80–16.40 s | captions | 所有照片 | white type, text height 2.4% (about 46 px) | cut in / cut out | — | | 16.00–16.40 s | captions | 粘贴上 | yellow type, black outline, black box, text height 4.4% (about 84 px) | cut in / cut out | — | | 16.50–32.60 s | captions | 豆包 ⏎ 内容由AI生成 | white type, gray outline, text height 2.2% (about 43 px) | character by character | — | | 16.50–18.00 s | captions | 内容由AI生成 ⏎ 好的,帮我定制一套专属精准提示词模板吧 | gray type, text height 2.2% (about 42 px) | cut in / fade out | — | | 16.50–18.10 s | captions | 如何使用换位思考指令让AI更准确理解需求? | gray type, text height 2.3% (about 45 px) | cut in / cut out | — | | 16.50–17.40 s | captions | 这是什么→ | gray type, gray keyword highlight, text height 2.4% (about 45 px) | cut in / cut out | — | | 16.50–28.20 s | captions | DEF | white type, gray outline, bold, text height 2.2% (about 42 px) | cut in / cut out | — | | 16.50–28.20 s | captions | ABC | white type, gray outline, text height 2.2% (about 42 px) | cut in / cut out | — | | 16.50–28.20 s | captions | 123 | gray type, black keyword highlight, text height 2.3% (about 44 px) | cut in / cut out | — | | 16.50–18.10 s | captions | 刚准备好的这个提示词 | yellow type, black outline, gray box, text height 4.0% (about 76 px) | cut in / slide out | — | | 16.50–28.20 s | captions | ABC | gray type, text height 2.3% (about 44 px) | cut in / cut out | — | | 16.50–27.60 s | captions | PQRS | white type, gray outline, bold, text height 2.1% (about 41 px) | cut in / cut out | — | | 16.50–27.60 s | captions | TUV | gray type, gray keyword highlight, text height 2.1% (about 41 px) | cut in | — | | 16.50–28.20 s | captions | WXYZ | gray type, gray keyword highlight, text height 2.1% (about 41 px) | cut in / cut out | — | | 16.50–27.60 s | captions | 发送 | blue type, blue outline, text height 2.6% (about 50 px) | cut in | — | | 16.50–28.20 s | captions | 空格 | white type, gray outline, text height 3.0% (about 59 px) | cut in / cut out | — | | 16.50–28.20 s | captions | 选拼音 | white type, gray keyword highlight, text height 2.7% (about 51 px) | cut in / cut out | — | | 17.10–18.10 s | captions | 这是什么→ | gray type, text height 2.0% (about 39 px) | slide in / cut out | — | | 18.00–19.10 s | captions | 内容由AI生成 | gray type, text height 2.0% (about 38 px) | pop in / cut out | — | | 18.00–18.10 s | captions | 提取图中文字→ | gray type, text height 2.2% (about 42 px) | cut in / cut out | — | | 18.00–28.20 s | captions | 约为打败不的是都利 | gray type, text height 3.0% (about 59 px) | cut out | — | | 18.00–25.00 s | captions | 这是一个陶瓷杯,给我生成 ⏎ 一段AI可以生成带货视频的 ⏎ 提示词,真人带货视 | black type, text height 3.3% (about 63 px) | cut in | — | | 18.50–25.10 s | captions | MNO | white type, gray outline, bold, text height 2.2% (about 42 px) | cut out | — | | 18.50–25.60 s | captions | AA | gray type, text height 1.5% (about 28 px) | pop in / cut out | — | | 18.50–22.10 s | captions | 么 | gray type, gray keyword highlight, text height 1.7% (about 33 px) | — | — | | 20.50–22.10 s | captions | 内容由AI生成 | gray type, text height 2.0% (about 39 px) | — | — | | 22.00–25.60 s | captions | 么 | gray type, gray keyword highlight, text height 1.7% (about 33 px) | — | — | | 25.00–28.20 s | captions | 提取图中文字→ | gray type, gray keyword highlight, text height 2.5% (about 48 px) | pop in / cut out | — | | 25.00–28.20 s | captions | 图片配文→ | gray type, gray keyword highlight, text height 2.3% (about 44 px) | cut out | — | | 25.00–28.20 s | captions | 这是什么→ | gray type, gray keyword highlight, text height 2.3% (about 44 px) | pop in / cut out | — | | 25.00–25.10 s | captions | 提示词呢 | yellow type, black outline, text height 4.2% (about 81 px) | cut in / cut out | — | | 25.50–27.10 s | captions | 以生成带货视频的提示词,真人带货 | white type, text height 2.6% (about 50 px) | — | ding | | 25.50–26.90 s | captions | 也可以按照自己的需求 | yellow type, black outline, gray box, text height 3.8% (about 72 px) | cut out | — | | 26.00–32.10 s | captions | 内容由AI生成 | gray type, text height 2.2% (about 42 px) | pop in / cut out | ding | | 26.90–27.50 s | captions | 来修改 | yellow type, black outline, text height 4.8% (about 93 px) | cut in | — | | 26.90–27.60 s | captions | GHI | white type, gray keyword highlight, text height 2.5% (about 49 px) | cut in / cut out | — | | 27.00–28.20 s | captions | 全用干什么、啥风格、多少宇、 | gray type, text height 2.8% (about 54 px) | cut out | — | | 27.00–28.20 s | captions | 说清给谁用、干什么、啥风格、多少字、 | gray type, gray keyword highlight, text height 2.6% (about 50 px) | cut out | — | | 27.00–28.20 s | captions | 不能写啥 | gray type, text height 2.1% (about 41 px) | cut out | — | | 27.00–28.20 s | captions | 我根据你常用用途(写文案/做题/编 | white type, text height 2.6% (about 50 px) | cut out | — | | 27.00–28.20 s | captions | 需要我根据你常用用途(写文家機题流编 ⏎ 程 ⏎ 聊天)给你定制一套专属精准提示 | gray type, text height 2.5% (about 49 px) | cut out | — | | 27.00–28.20 s | captions | 模板吗? | white type, text height 2.6% (about 50 px) | cut out | — | | 27.00–28.20 s | captions | 转人间意或直接发送, | gray type, text height 2.3% (about 44 px) | cut out | — | | 27.00–28.20 s | captions | 空格 | white type, text height 2.6% (about 50 px) | cut out | — | | 27.00–28.20 s | captions | 选拼音 | white type, gray outline, text height 2.4% (about 46 px) | cut out | — | | 27.50–28.10 s | captions | 点击发送 | yellow type, black outline, text height 4.4% (about 85 px) | shrink out | — | | 28.00–28.10 s | captions | MNO | white type, gray outline, bold, text height 2.1% (about 41 px) | cut in | — | | 28.00–28.10 s | captions | WXYZ | gray type, text height 2.1% (about 41 px) | — | — | | 28.00–29.60 s | captions · tracks object | 提示词接着就出来了 | yellow type, black outline, text height 3.6% (about 69 px) | cut out (bounce / color change midway) | — | | 28.40–32.90 s | captions | 帮我写 | gray type, text height 2.1% (about 41 px) | cut in / cut out | — | | 28.40–32.90 s | captions | 拍题答疑 | white type, gray outline, text height 2.0% (about 39 px) | cut in / cut out | — | | 28.40–32.90 s | captions | 快速 | white type, text height 2.3% (about 45 px) | cut in / cut out | — | | 28.40–32.90 s | captions | 发消息或按住说话.. | gray type, text height 2.3% (about 45 px) | cut in / cut out | — | | 28.50–28.80 s | captions | 3.办公类 | gray type, text height 2.6% (about 50 px) | cut in / shrink out | — | | 28.50–28.70 s | captions | 工作场景+文档类型+正式程度+必填 | gray type, gray keyword highlight, text height 2.7% (about 51 px) | cut in / fade out | — | | 28.50–28.60 s | captions | 内容 | white type, text height 2.6% (about 50 px) | cut in / cut out | — | | 28.50–29.00 s | captions | 六、一句话终极口诀 | gray type, bold, text height 2.7% (about 51 px) | cut in / cut out | — | | 28.50–28.60 s | captions | 说清给谁用、干什么、啥风格、多少字、 | white type, gray keyword highlight, text height 2.4% (about 46 px) | cut in / cut out | — | | 28.50–28.60 s | captions | 不能写啥 | gray type, text height 2.6% (about 50 px) | cut in / cut out | — | | 28.50–29.10 s | captions | 需要我根据你常用用途(写文案 ⏎ 做题 ⏎ 编 ⏎ 程 ⏎ 聊天)给你定制一套专 | gray type, text height 2.5% (about 49 px) | cut in / cut out | — | | 28.50–29.10 s | captions | 这是一个陶瓷杯,给我生成一段AI可 ⏎ 以生成带货视频的提示词,真人带货 | blue type, text height 2.4% (about 46 px) | cut in / cut out | — | | 28.50–28.60 s | captions | 视频,10秒的时长 | blue type, blue outline, text height 2.4% (about 46 px) | cut in / cut out | — | | 28.50–29.10 s | captions | 模? | gray type, text height 3.4% (about 65 px) | cut in / cut out | — | | 28.60–29.10 s | captions | 六、一包话终极口诀 | gray type, gray keyword highlight, text height 2.8% (about 54 px) | slide in / cut out | — | | 28.60–29.10 s | captions | 说清给谁用、手件么、风格、多少字、 | gray type, text height 3.1% (about 60 px) | cut in / cut out | — | | 28.60–29.10 s | captions | 不能写晗 | gray type, text height 3.0% (about 57 px) | cut in / cut out | — | | 28.60–29.10 s | captions | 需要我根据你用用(写文案/做 ⏎ 编 ⏎ 程/天)给你定制一套专属精淮提示词 | gray type, text height 2.9% (about 55 px) | cut in / cut out | — | | 28.60–29.10 s | captions | 视频;10秒的时长 | blue type, text height 2.7% (about 51 px) | cut in / cut out | — | **Text effects seen by the VLM** - 0.0 s styled text 「每天分享一个AI制作方法」 yellow type, black outline, no animation - 1.9 s styled text 「制作真人出镜的日用品带货视频」 yellow highlighted type, no animation - 12.0 s styled text 「打开AI工具」 white type with yellow keywords, no animation Remake: burn the captions and styled text in directly with `packaging/overlays.ass` (ffmpeg -vf ass=overlays.ass), or rebuild them from timeline.json in CapCut (JianYing) / Remotion; stickers and animated images need matching material (meme / GIF libraries); screenshots are under packaging/. ## Structure and copy (VLM) - Summary: a tutorial on using Doubao to refine prompts and Jimeng AI to generate a product video of everyday goods with a real-looking presenter on camera. - Form: explainer; hook: opens with the creator on camera saying "每天分享一个AI制作方法" ("one AI production method a day"), then cuts straight to an extremely realistic AI-generated ceramic-mug product video with a real-looking presenter, grabbing the attention of e-commerce creators. - Narration: human, young female, standard Mandarin, the warm knowledgeable tone of a tutorial creator; music: upbeat, lively tech-tutorial music, switching to a warm, relaxed lifestyle bed for the finished video in the second half; captions: bold sans-serif centered at the bottom, bright yellow combined with white, black outline - Overall judgment: live voice-over explanation combined with hands-on recording; the core showcase is the AI-generated product video; a typical low-cost, high-utility digital / AI short-video tutorial. - 0.0–1.93 s · intro and topic teaser · "One AI production method a day" - 1.93–6.63 s · quick preview of the finished result · "Today I'll show you how to make a product video of everyday goods with a real person on camera; let me demonstrate with this mug" - 6.63–11.93 s · preparation: product reference photos · "Save the photos of the mug you want to sell; save a few of them" - 11.93–32.93 s · step 1: generate shot-by-shot product-video prompts with Doubao · "Open the AI tool, add the product photos we saved, paste in the prompt we just prepared... tap send, and the prompts come right out; copy the one you like" - 32.93–48.0 s · step 2: generate the product video in Jimeng / Seedance · "Go to this screen, choose the on-camera footage I recorded in advance, paste the prompt we just copied, tap the image button below, import our two mug photos, then tap send; in Drafts you can see the generation progress" - 48.0–58.0 s · final result and wrap-up · "Let's look at the result: the scene is realistic, doesn't it draw you in? (line from the generated video: hot cocoa is so comforting, perfect whether for yourself or as a gift for a friend)" ## Real material in the frame 15 shots, 43.13 s (75%), contain real material (screen recordings, screenshots, photos, embedded video). A remake needs the original files; they cannot be replaced by generated output: - Shot #1 (00:00.000): live video footage, whole frame - Shot #5 (00:07.933): live video footage, whole frame - Shot #6 (00:10.067): live video footage, whole frame - Shot #7 (00:11.933): live video footage, whole frame - Shot #8 (00:15.400): live video footage, whole frame - Shot #9 (00:16.433): live video footage, whole frame - Shot #10 (00:32.933): live video footage, whole frame - Shot #11 (00:34.633): live video footage, whole frame - Shot #12 (00:40.167): live video footage, whole frame - Shot #13 (00:41.200): live video footage, whole frame - Shot #14 (00:42.267): live video footage, whole frame - Shot #15 (00:43.067): live video footage, whole frame - Shot #16 (00:43.733): live video footage, whole frame - Shot #17 (00:47.067): live video footage, whole frame - Shot #18 (00:47.733): live video footage, whole frame ## Reference material to prepare for the remake These shots were generated or shot; the items below appear in the frame and should be prepared as reference images / props for a remake (they are not embedded real pixels): - Shot #5 (00:07.933): product reference photo - Shot #6 (00:10.067): product reference photo, the hand-held beige ceramic mug with an apple lid - Shot #6 (00:10.067): product reference photo - Shot #8 (00:15.400): product reference photo, the assorted product images shown in the phone gallery (mug, burger, pet, apple, etc.) - Shot #9 (00:16.433): product reference photo, the photo of the red apple-shaped ceramic mug uploaded in the phone app ## Shot list | # | Time | Duration | Underlying picture | Confidence | Material | Overlays | Camera | Remake route | |---|---|---|---|---|---|---|---|---| | 1 | 00:00.000 | 1.93 s | Live footage | 70% | User's real material: live video footage | Captions, graphic stickers | Smooth move | R07-product-hero → capsule_cinema | | 2 | 00:01.933 | 2.77 s | AI-generated video | 70% | AI-generated | Captions, title | Smooth move | R07-product-hero → capsule_cinema | | 3 | 00:04.700 | 1.93 s | AI-generated video | 70% | AI-generated | Captions, title | Smooth move | R07-product-hero → capsule_cinema | | 4 | 00:06.633 | 1.30 s | AI-generated video | 53% | AI-generated | Text, graphic stickers | Smooth move | R07-product-hero → capsule_cinema | | 5 | 00:07.933 | 2.13 s | Live footage | 70% | User's real material: live video footage; remake reference: product reference photo | Text | Static | R07-product-hero → capsule_cinema | | 6 | 00:10.067 | 1.87 s | Live footage | 70% | User's real material: live video footage; remake reference: product reference photo | Text | Static | R07-product-hero → capsule_cinema | | 7 | 00:11.933 | 3.47 s | Live footage | 70% | User's real material: live video footage | Captions | Static | R07-product-hero → capsule_cinema | | 8 | 00:15.400 | 1.03 s | Live footage | 70% | User's real material: live video footage; remake reference: product reference photo | Captions | Static | R07-product-hero → capsule_cinema | | 9 | 00:16.433 | 16.50 s | Live footage | 70% | User's real material: live video footage; remake reference: product reference photo | Captions | Static | R07-product-hero → capsule_cinema | | 10 | 00:32.933 | 1.70 s | Live footage | 70% | User's real material: live video footage | Captions | Static | R07-product-hero → capsule_cinema | | 11 | 00:34.633 | 5.53 s | Live footage | 70% | User's real material: live video footage | Captions | Static | R07-product-hero → capsule_cinema | | 12 | 00:40.167 | 1.03 s | Live footage | 70% | User's real material: live video footage | Text | Static | R07-product-hero → capsule_cinema | | 13 | 00:41.200 | 1.07 s | Live footage | 70% | User's real material: live video footage | Captions | Smooth move | R07-product-hero → capsule_cinema | | 14 | 00:42.267 | 0.80 s | Live footage | 70% | User's real material: live video footage | — | Static | R07-product-hero → capsule_cinema | | 15 | 00:43.067 | 0.67 s | Live footage | 70% | User's real material: live video footage | — | Smooth move | R07-product-hero → capsule_cinema | | 16 | 00:43.733 | 3.33 s | Live footage | 70% | User's real material: live video footage | Captions | Static | R07-product-hero → capsule_cinema | | 17 | 00:47.067 | 0.67 s | Live footage | 70% | User's real material: live video footage | Text, captions, styled text | Static | R07-product-hero → capsule_cinema | | 18 | 00:47.733 | 1.40 s | Live footage | 70% | User's real material: live video footage | Captions, styled text | Static | R07-product-hero → capsule_cinema | | 19 | 00:49.133 | 2.37 s | AI-generated video | 70% | AI-generated | Captions, title | Smooth move | R07-product-hero → capsule_cinema | | 20 | 00:51.500 | 3.40 s | AI-generated video | 70% | AI-generated | Captions, title, styled text | Smooth move | R07-product-hero → capsule_cinema | | 21 | 00:54.900 | 2.77 s | AI-generated video | 70% | AI-generated | Title | Smooth move | R07-product-hero → capsule_cinema | ## Shot details ### #1 00:00.000–00:01.933 · Live footage + code / editor overlays (captions, graphic stickers); introduces real material (live video footage) ![shot_001](shots/shot_001.jpg) - Probabilities: live footage 82%, AI-generated video 7%, talking avatar 3% (fused) - ⚠️ To be confirmed: live footage or AI: the picture comes from 24 fps material and carries no AIGC label, which is not the signature of native 30 fps phone footage - Material: user's real material: live video footage - Photo / video texture: noise σ=0.31, 118 colors, flat blocks 10% - Re-encoded by the platform (Douyin/TikTok), sensor noise crushed: noise-based evidence is void; live vs. AI rests mainly on frame rate and picture content - [VLM] Real skin texture, hair detail and the lavalier microphone cable - [VLM] The finger gesture moves fluidly with correct structure and no warping - [VLM] Reflections on the glasses and the ceiling downlights follow real physics - [claude visual review] A real office corridor: wood-veneer wall, glass door, ceiling lights, with natural perspective and reflections - [claude visual review] Fingers, glasses and hair edges are sharp, the gesture has natural motion blur - [claude visual review] Phone front-camera selfie view, slight handheld shake - Picture: a woman with glasses delivers a voice-over explanation in a bright interior, raising one hand in an emphasis gesture, fixed close-up setup, even diffused light from above. - Framing / light: close-up; eye level; handheld selfie (front camera); backlit / background brighter than the subject; key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.1:1 (0.1 stops); soft light (almost no shadow edge) - Text track (captions / bottom): 每天分享一个AI制作方法 / 每天分享一个A制作方法 - Remake: the original is live footage: reshoot per the shooting plan (shot size / camera / lighting); only when shooting is not possible, approximate it with AI image-to-video (using the first frame as reference); the user must supply the real material: live video footage (whole frame) - First-frame image prompt: real vertical phone selfie, a young East Asian woman with black-framed glasses, long black hair, gray V-neck T-shirt, wearing a small lavalier microphone, white indoor wall and ceiling lights behind, bright even light, close-up half-body - Video prompt: a young woman with black-framed glasses talks naturally to the camera, raises her right index finger for emphasis and lowers it again, smiling, fixed indoor camera, natural fluid movement ### #2 00:01.933–00:04.700 · AI-generated video + code / editor overlays (captions, title) ![shot_002](shots/shot_002.jpg) - Probabilities: AI-generated video 81%, live footage 8%, 3D rendering 3% (fused) - ⚠️ To be confirmed: live footage / stop motion or AI: no AIGC label; 24 fps source traces occur in AI video, stop motion and cinema-camera footage alike - Text on objects in the frame (not post-production captions): Nice toneut geu, Nice tomectyu, Nicctomcee, Ir=utos, naydffimasng, Its - Material: AI-generated - Likely tool: Jimeng (ByteDance's AI video app) - Photo / video texture: noise σ=0.26, 217 colors, flat blocks 19% - Re-encoded by the platform (Douyin/TikTok), sensor noise crushed: noise-based evidence is void; live vs. AI rests mainly on frame rate and picture content - [VLM] A clear "AI生成" (AI-generated) watermark in the top-left corner - [VLM] A Jimeng AI-video-tool watermark in the bottom-right corner - [VLM] The English characters on the gift box in the background have the typical AI gibberish distortion - [VLM] As the camera pushes in, the mug print and finger edges show faint AI melting and warping - [claude visual review] A Jimeng watermark and the "@知遇" account name in the bottom-right corner: a clip exported from Jimeng - [claude visual review] The English print on the gift box is gibberish (OCR reads "I+'s aod to see you agay,and / may ou friendship las+frever."); real packaging would not look like this - Picture: a young woman sits at a wooden table showing a lidded ceramic mug printed with apples and a brown bear with both hands; the camera pushes in smoothly to a close-up of the mug's details. - Framing / light: medium close-up; eye level; gimbal; frontal soft light (flat); key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.2:1 (0.2 stops); soft light (almost no shadow edge) - Text track (captions / bottom): 今天教大家 / 制作真人出镜的日用品 - Text track (captions / bottom): 即梦 / @知遇 - Text track (captions / middle): Nice toneut geu / Nice tomectyu / Nicctomcee / Nicetamcet - Text track (captions / middle): Ir=utos / naydffimasng / Its / adtosca - Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first - First-frame image prompt: vertical 9:16, cozy tabletop scene: a long-haired young woman in a cream sweater sits at a natural-wood table holding a red apple-shaped ceramic mug with both hands (the lid is an apple, the beige body printed with small trees and apples), a beige gift box printed with apples behind her, a red-and-white gingham cloth and a wooden spoon on the table; soft natural light, light-colored wall softly blurred behind, photorealistic product-video style - Video prompt: smiling, the young woman picks up the apple-shaped ceramic mug from the table, holds it with both hands at chest height toward the camera and gently turns it so the apple print faces the lens; the camera pushes in slowly from a medium shot to a close-up of the mug, ending with the mug filling the center of the frame ### #3 00:04.700–00:06.633 · AI-generated video + code / editor overlays (captions, title) ![shot_003](shots/shot_003.jpg) - Probabilities: AI-generated video 83%, live footage 6%, 3D rendering 3% (fused) - ⚠️ To be confirmed: live footage / stop motion or AI: no AIGC label; 24 fps source traces occur in AI video, stop motion and cinema-camera footage alike - Text on objects in the frame (not post-production captions): st f'rever., st f rever., st frever., meet, mee - Material: AI-generated - Likely tool: Jimeng - Photo / video texture: noise σ=0.23, 252 colors, flat blocks 19% - Re-encoded by the platform (Douyin/TikTok), sensor noise crushed: noise-based evidence is void; live vs. AI rests mainly on frame rate and picture content - [VLM] A clear "AI生成" (AI-generated) watermark in the top-left corner - [VLM] A Jimeng logo in the bottom-right corner - [VLM] As the hand lifts the lid, the finger joints look slightly stiff and the lid's edge warps slightly while moving - [claude visual review] A Jimeng watermark and the "@知遇" account name in the bottom-right corner: a clip exported from Jimeng - [claude visual review] The English print on the gift box is gibberish (OCR reads "I+'s aod to see you agay,and / may ou friendship las+frever."); real packaging would not look like this - [claude visual review] The same clip is reused unchanged at 49.1 s (the opening and closing segments are identical frame by frame) - Picture: an indoor tabletop; a hand lifts the lid of an apple-shaped ceramic mug to reveal the drink inside, a matching spoon beside it, a gift box and a photo frame in the background. - Framing / light: medium close-up; slightly high angle; tripod / stand, fixed; backlit / background brighter than the subject; key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.3:1 (0.4 stops); hard light (clear shadow edge) - Text track (captions / bottom): 带货视频 / 那我用这个水杯 - Text track (captions / bottom): 7即梦 / @知遇 / 即梦 - Text track (captions / middle): st f'rever. / st f rever. / st frever. - Text track (captions / middle): meet / mee - Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first - First-frame image prompt: vertical 9:16, cozy tabletop scene: a long-haired young woman in a cream sweater sits at a natural-wood table holding a red apple-shaped ceramic mug with both hands (the lid is an apple, the beige body printed with small trees and apples), a beige gift box printed with apples behind her, a red-and-white gingham cloth and a wooden spoon on the table; soft natural light, light-colored wall softly blurred behind, photorealistic product-video style - Video prompt: smiling, the young woman picks up the apple-shaped ceramic mug from the table, holds it with both hands at chest height toward the camera and gently turns it so the apple print faces the lens; the camera pushes in slowly from a medium shot to a close-up of the mug, ending with the mug filling the center of the frame ### #4 00:06.633–00:07.933 · AI-generated video + code / editor overlays (text labels, graphic stickers) ![shot_004](shots/shot_004.jpg) - Probabilities: AI-generated video 51%, live footage 41%, talking avatar 2% (fused) - ⚠️ To be confirmed: live footage / stop motion or AI: no AIGC label; 24 fps source traces occur in AI video, stop motion and cinema-camera footage alike - Material: AI-generated - Likely tool: Kling/Hailuo - Photo / video texture: noise σ=0.31, 121 colors, flat blocks 10% - Re-encoded by the platform (Douyin/TikTok), sensor noise crushed: noise-based evidence is void; live vs. AI rests mainly on frame rate and picture content - [VLM] When the right hand is raised, the index finger's shape and nail edge look unnatural and warped - [VLM] When the hands come together, the structure where the fingers overlap is blurred and physically inconsistent - [VLM] Facial skin is too smooth, lacking real pores and texture detail - [claude visual review] A real office corridor: wood-veneer wall, glass door, ceiling lights, with natural perspective and reflections - [claude visual review] Fingers, glasses and hair edges are sharp, the gesture has natural motion blur - [claude visual review] Phone front-camera selfie view, slight handheld shake - Picture: a young woman with glasses talks to the camera indoors, first raising her right index finger, then bringing her hands together in front of her chest. - Framing / light: close-up; eye level; handheld selfie (front camera); backlit / background brighter than the subject; key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.1:1 (0.1 stops); soft light (almost no shadow edge) - Text track (text / bottom): 给大家演示一下 - Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first - First-frame image prompt: vertical, close-up, a young Asian woman with black-framed glasses, gray short-sleeved V-neck top, wearing a necklace, facing the camera, indoor background, white wall, downlights in the ceiling, bright frontal soft light, photorealistic photography style - Video prompt: a young woman with black-framed glasses talks to the camera; she first raises her right index finger for emphasis, then naturally brings her hands together in front of her chest; smooth movements, fixed camera ### #5 00:07.933–00:10.067 · Live footage + code / editor overlays (text labels); introduces real material (live video footage) ![shot_005](shots/shot_005.jpg) - Probabilities: live footage 83%, AI-generated video 4%, 3D rendering 3% (fused) - ⚠️ To be confirmed: live footage or AI: the picture comes from 24 fps material and carries no AIGC label, which is not the signature of native 30 fps phone footage - Text on objects in the frame (not post-production captions): 福, It's crod to see you agay,and, may oufriendship las+frever., Nice ta, Nice to - Material: user's real material: live video footage; remake reference: product reference photo - Photo / video texture: noise σ=0.27, 247 colors, flat blocks 14% - Re-encoded by the platform (Douyin/TikTok), sensor noise crushed: noise-based evidence is void; live vs. AI rests mainly on frame rate and picture content - [VLM] The ceramic mug's specular highlights and material look fully consistent with real physics - [VLM] The printed text "It's good to see you again" on the paper gift box is sharp, natural and in correct perspective - [VLM] The skin texture of the hands, the manicure and the jewelry are clear with no AI warping - [claude visual review] Three-band layout: the top and bottom bands are the live voice-over footage (the creator's head and hands are visible), the middle is a static product photo - [claude visual review] In the product photo the mug, gift box, cloth and wooden spoon are arranged on a white desk: a product photo the creator took themselves (the same two photos are uploaded in the demo later) - Picture: an indoor tabletop close-up with the presenter on camera. On the table are an apple-shaped lidded ceramic mug, its box, a matching small spoon and a 福 ("fortune") ornament; in front sits the presenter with hands folded, fixed camera. - Framing / light: close-up (head and shoulders); eye level; handheld selfie (front camera); frontal soft light (flat); key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.2:1 (0.3 stops); soft light (almost no shadow edge) - Text track (text / bottom): 保存好要带货的水杯图片 - Text track (captions / middle): 福 / It's crod to see you agay,and / may oufriendship las+frever. / It's crod to see you agay.and - Text track (captions / middle): Nice ta / Nice to - Remake: the original is live footage: reshoot per the shooting plan (shot size / camera / lighting); only when shooting is not possible, approximate it with AI image-to-video (using the first frame as reference); the user must supply the real material: live video footage (whole frame); reference for generation: product reference photo - First-frame image prompt: real photography, tabletop still-life close-up. On a beige desk sits a red apple-shaped lidded ceramic mug on a red-and-white gingham coaster, with a small apple-twig-shaped spoon beside it. Behind the mug is a pale-yellow gift bag box, a small red 福 ("fortune") photo frame leans at the right, a laptop in the background. A woman's folded hands appear at the bottom of the frame; soft indoor light, warm bright image, e-commerce display style, high detail. - Video prompt: fixed-camera live shot showing the apple ceramic mug and gift box on the desk, the presenter's hands at the bottom of the frame stay naturally folded, no camera shake, a static display. ### #6 00:10.067–00:11.933 · Live footage + code / editor overlays (text labels); introduces real material (live video footage) ![shot_006](shots/shot_006.jpg) - Probabilities: live footage 82%, AI-generated video 4%, 3D rendering 3% (fused) - ⚠️ To be confirmed: live footage or AI: the picture comes from 24 fps material and carries no AIGC label, which is not the signature of native 30 fps phone footage - ⚠️ Disagreement: the tool says AI-generated video, the VLM says live footage, and the verdict followed the VLM: check against the frame whether the VLM's evidence is actually visible - Text on objects in the frame (not post-production captions): an,and, Orever., hn,and - Material: user's real material: live video footage; remake reference: product reference photo - Photo / video texture: noise σ=0.27, 234 colors, flat blocks 12% - Re-encoded by the platform (Douyin/TikTok), sensor noise crushed: noise-based evidence is void; live vs. AI rests mainly on frame rate and picture content - [VLM] Finger skin texture, pores and knuckle reflections are extremely natural and real - [VLM] The glaze highlights on the ceramic mug and the ambient diffuse reflections follow real optics - [VLM] The laptop keyboard and gift box in the background are sharp with no warping - [claude visual review] The first frame is a full product photo letterboxed top and bottom (hand-held mug close-up), then it cuts back to the three-band layout - [claude visual review] In the photo the print on the mug and the glaze reflections are real - Picture: a tabletop product shot, a hand holding a beige ceramic mug with a Christmas-tree print and a red apple lid on top, a laptop and a gift box in the background. - Framing / light: close-up (head and shoulders); eye level; handheld selfie (front camera); front-side key + fill (standard setup); key front right; contrast about 1.4:1 (0.5 stops); cannot be determined - Text track (text / bottom): 图片可以多保存几张 - Text track (captions / middle): an,and / Orever. / hn,and / 入 - Remake: the original is live footage: reshoot per the shooting plan (shot size / camera / lighting); only when shooting is not possible, approximate it with AI image-to-video (using the first frame as reference); the user must supply the real material: live video footage (whole frame); reference for generation: product reference photo - First-frame image prompt: tabletop close-up, a hand holding a beige round-bellied ceramic mug printed with small Christmas trees and apples, the lid a plump glossy sculpted red apple with a brown stem, a light laptop keyboard and a gift box in the background, bright soft indoor light, real photography style. - Video prompt: fixed close-up, the hand steadily holds the beige ceramic mug with the red apple lid toward the camera, slightly adjusting the angle to show the print and the glaze's sheen, soft indoor light. ### #7 00:11.933–00:15.400 · Live footage + code / editor overlays (captions); introduces real material (live video footage) ![shot_007](shots/shot_007.jpg) - Probabilities: live footage 82%, 3D rendering 4%, AI-generated video 3% (fused) - ⚠️ To be confirmed: live footage or AI: the picture comes from 24 fps material and carries no AIGC label, which is not the signature of native 30 fps phone footage - Text on objects in the frame (not post-production captions): ABC, PQRS, TUV, 选拼音, 空格, 好的,帮我定制一套专属精准提示词模板吧 - Material: user's real material: live video footage - Re-encoded by the platform (Douyin/TikTok), sensor noise crushed: noise-based evidence is void; live vs. AI rests mainly on frame rate and picture content - [VLM] The phone's real physical bezel is visible - [VLM] A real stylus taps and swipes on the screen with real physical shadows - [VLM] Real ambient-light reflections on the screen surface - [claude visual review] The frame shows the phone's black bezel and rounded corners, a band of ceiling-light reflection on the screen, and a finger and stylus reaching in from the right: a camera filming a real phone, not a screen recording - [claude visual review] The screen shows real app UIs (Doubao / Jimeng Seedance 2.0) with status-bar times 15:10–15:14 - [claude visual review] Fixed camera; the phone and desk do not move - Picture: a close-up, fixed camera on a smartphone standing upright. A stylus operates an AI chat app on the phone, tapping the plus button to open the toolbar, choosing the gallery and ticking several product photos. - Framing / light: close-up (phone screen); slightly high angle (phone standing / tilted on the desk, camera from front above); tripod / stand, fixed; frontal soft light (flat); key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.0:1 (0.0 stops); soft light (wide shadow transition) - Text track (captions / bottom): 打开AI工具 / #@¥ / G / 添加我们保存的几张产品图 - Text track (captions / bottom): ABC / PQRS / TUV / WXYZ - Text track (captions / bottom): 选拼音 / 空格 - Text track (captions / middle): 好的,帮我定制一套专属精准提示词模板吧 / 如何使用换位思考指令让AI更准确理解需求? / 如 / 相机 - Remake: the original is live footage: reshoot per the shooting plan (shot size / camera / lighting); only when shooting is not possible, approximate it with AI image-to-video (using the first frame as reference); the user must supply the real material: live video footage (whole frame) - First-frame image prompt: close-up, a smartphone standing upright on a desk, its screen lit and showing a chat interface, a stylus tapping the screen, soft indoor light, photorealistic style - Video prompt: close-up, fixed camera. A smartphone shows an AI chat app interface. A stylus taps the plus button to the right of the input box and a menu pops up. The stylus taps the "gallery" icon and the screen switches to the phone's photo library. The stylus scrolls the library and ticks several product photos. ### #8 00:15.400–00:16.433 · Live footage + code / editor overlays (captions); introduces real material (live video footage) ![shot_008](shots/shot_008.jpg) - Probabilities: live footage 83%, 3D rendering 4%, AI-generated video 3% (fused) - ⚠️ To be confirmed: live footage or AI: the picture comes from 24 fps material and carries no AIGC label, which is not the signature of native 30 fps phone footage - Text on objects in the frame (not post-production captions): 下一步, 下一步(2), 下一步(2), Nacurat, ral, Naturo - Material: user's real material: live video footage; remake reference: product reference photo - Photo / video texture: noise σ=0.30, 398 colors, flat blocks 15% - Re-encoded by the platform (Douyin/TikTok), sensor noise crushed: noise-based evidence is void; live vs. AI rests mainly on frame rate and picture content - [VLM] The phone's real bezel and screen reflections are visible - [VLM] A real stylus taps the screen with natural movement - [VLM] The screen content gives real interaction feedback (selected state) as the stylus taps - [claude visual review] The frame shows the phone's black bezel and rounded corners, a band of ceiling-light reflection on the screen, and a finger and stylus reaching in from the right: a camera filming a real phone, not a screen recording - [claude visual review] The screen shows real app UIs (Doubao / Jimeng Seedance 2.0) with status-bar times 15:10–15:14 - [claude visual review] Fixed camera; the phone and desk do not move - Picture: a high-angle close-up of a phone screen; a stylus taps repeatedly in the gallery, selecting several product photos. - Framing / light: close-up (phone screen); slightly high angle (phone standing / tilted on the desk, camera from front above); tripod / stand, fixed; frontal soft light (flat); key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.0:1 (0.1 stops); soft light (almost no shadow edge) - Text track (captions / bottom): 添加我们保存的几张产品图 / 粘贴上 - Text track (captions / bottom): 下一步 / 下一步(2) / 下一步(2) - Text track (captions / middle): Nacurat / ral / Naturo / Natural - Text track (captions / middle): ral / Natural - Remake: the original is live footage: reshoot per the shooting plan (shot size / camera / lighting); only when shooting is not possible, approximate it with AI image-to-video (using the first frame as reference); the user must supply the real material: live video footage (whole frame); reference for generation: product reference photo - First-frame image prompt: close-up, high angle on a smartphone screen showing a gallery interface with product photos in a grid (mug, burger, apple, etc.), a white stylus tapping the screen, real light and shadow, photorealistic style. - Video prompt: close-up, fixed high-angle camera on a smartphone. The screen shows the gallery; a stylus taps repeatedly, selecting several product photos, and blue tick marks appear one by one in the top-right corner of each image; natural fluid movement. ### #9 00:16.433–00:32.933 · Live footage + code / editor overlays (captions); introduces real material (live video footage) ![shot_009](shots/shot_009.jpg) - Probabilities: live footage 76%, 3D rendering 5%, screen recording / screenshot 4% (fused) - ⚠️ To be confirmed: live footage or AI: the picture comes from 24 fps material and carries no AIGC label, which is not the signature of native 30 fps phone footage - Text on objects in the frame (not post-production captions): 选拼音, 空格, 发消息或按住说话.., 这是什么→, 图片配文→, 提取图中文字→ - Material: user's real material: live video footage; remake reference: product reference photo - In-shot motion beats: 17.17 s, 25.07 s, 27.63 s - Rendered texture: flat color blocks 29%, 95% of pixels use only 97 colors, horizontal / vertical straight edges 49% - Re-encoded by the platform (Douyin/TikTok), sensor noise crushed: noise-based evidence is void; live vs. AI rests mainly on frame rate and picture content - [VLM] Real phone body and reflections on the notched screen - [VLM] Real stylus taps on the screen with cast shadows - [VLM] Slight natural hand tremor and real handheld focus behavior - [claude visual review] The frame shows the phone's black bezel and rounded corners, a band of ceiling-light reflection on the screen, and a finger and stylus reaching in from the right: a camera filming a real phone, not a screen recording - [claude visual review] The screen shows real app UIs (Doubao / Jimeng Seedance 2.0) with status-bar times 15:10–15:14 - [claude visual review] Fixed camera; the phone and desk do not move - Picture: a close-up of a phone screen; the operator, holding a stylus, types a prompt into the Doubao app and taps send; the screen shows the ceramic-mug product copy being generated. - Framing / light: close-up (phone screen); slightly high angle (phone standing / tilted on the desk, camera from front above); tripod / stand, fixed; frontal soft light (flat); key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.1:1 (0.2 stops); soft light (almost no shadow edge) - Text track (captions / bottom): 粘贴上 / #@¥ / GHI / MNO - Text track (captions / bottom): ABC / PQRS / TUV / WXYZ - Text track (captions / bottom): 选拼音 / 空格 / 发消息或按住说话.. - Text track (captions / middle): 这是什么→ / 图片配文→ / 提取图中文字→ / 提示词,真人带货视频,10 - Remake: the original is live footage: reshoot per the shooting plan (shot size / camera / lighting); only when shooting is not possible, approximate it with AI image-to-video (using the first frame as reference); the user must supply the real material: live video footage (whole frame); reference for generation: product reference photo - First-frame image prompt: close-up of a white smartphone screen showing a Chinese AI chat app interface with a chat box and a stylus pointer, soft diffused indoor light, photorealistic digital style. - Video prompt: handheld close-up of a phone screen; a gray stylus taps the input box and then the blue send button, the screen then scrolls to show the AI-generated product-video script, with a slight natural handheld breathing motion. ### #10 00:32.933–00:34.633 · Live footage + code / editor overlays (captions); introduces real material (live video footage) ![shot_010](shots/shot_010.jpg) - Probabilities: live footage 81%, 3D rendering 4%, AI-generated video 3% (fused) - ⚠️ To be confirmed: live footage or AI: the picture comes from 24 fps material and carries no AIGC label, which is not the signature of native 30 fps phone footage - Text on objects in the frame (not post-production captions): 输入描述你的梦境, 邀请好友, Aura, √, 橙柚Nora, 承泽 - Material: user's real material: live video footage - Re-encoded by the platform (Douyin/TikTok), sensor noise crushed: noise-based evidence is void; live vs. AI rests mainly on frame rate and picture content - [VLM] Real physical phone screen reflections and bezel - [VLM] Natural movement, shadows and skin texture of the hand holding the stylus - [VLM] Real physical interaction and screen response as the stylus taps - [claude visual review] The frame shows the phone's black bezel and rounded corners, a band of ceiling-light reflection on the screen, and a finger and stylus reaching in from the right: a camera filming a real phone, not a screen recording - [claude visual review] The screen shows real app UIs (Doubao / Jimeng Seedance 2.0) with status-bar times 15:10–15:14 - [claude visual review] Fixed camera; the phone and desk do not move - Picture: a close-up of a phone screen showing the Seedance 2.0 app; a hand holding a stylus taps an orange-haired girl avatar icon on the screen. - Framing / light: close-up (phone screen); slightly high angle (phone standing / tilted on the desk, camera from front above); tripod / stand, fixed; frontal soft light (flat); key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.0:1 (0.1 stops); soft light (almost no shadow edge) - Text track (captions / bottom): 朦胧发光光影 / 马年魔法靴 / 我们来到这个界面 / 朦胧发 - Text track (text / bottom): 输入描述你的梦境 - Text track (captions / bottom): 出镜 / 生图 - Text track (text / middle): 知遇 - Remake: the original is live footage: reshoot per the shooting plan (shot size / camera / lighting); only when shooting is not possible, approximate it with AI image-to-video (using the first frame as reference); the user must supply the real material: live video footage (whole frame) - First-frame image prompt: close-up, a smartphone showing an app interface with several round avatars, a hand holding a stylus about to tap the screen, soft indoor light, real photography. - Video prompt: close-up, fixed camera. A smartphone shows an app interface with several round avatars. A hand holding a stylus taps the round avatar of an orange-haired girl slightly left of center. Natural fluid movement. ### #11 00:34.633–00:40.167 · Live footage + code / editor overlays (captions); introduces real material (live video footage) ![shot_011](shots/shot_011.jpg) - Probabilities: live footage 80%, 3D rendering 5%, AI-generated video 3% (fused) - ⚠️ To be confirmed: live footage or AI: the picture comes from 24 fps material and carries no AIGC label, which is not the signature of native 30 fps phone footage - Text on objects in the frame (not post-production captions): 我你在这一不是今天, 我23你在这ABC不D爆, 今天, 123, ABC, DEF - Material: user's real material: live video footage - Re-encoded by the platform (Douyin/TikTok), sensor noise crushed: noise-based evidence is void; live vs. AI rests mainly on frame rate and picture content - [VLM] The real phone bezel, hand and stylus are visible - [VLM] Hand movement and the on-screen UI feedback are perfectly in sync, consistent with real physical interaction - [VLM] Real reflections and shadows of the stylus on the screen - [claude visual review] The frame shows the phone's black bezel and rounded corners, a band of ceiling-light reflection on the screen, and a finger and stylus reaching in from the right: a camera filming a real phone, not a screen recording - [claude visual review] The screen shows real app UIs (Doubao / Jimeng Seedance 2.0) with status-bar times 15:10–15:14 - [claude visual review] Fixed camera; the phone and desk do not move - Picture: a close-up, fixed camera on a hand using a stylus in the Seedance 2.0 app on a phone screen, choosing an avatar, pasting text and tapping buttons in turn. - Framing / light: close-up (phone screen); slightly high angle (phone standing / tilted on the desk, camera from front above); tripod / stand, fixed; frontal soft light (flat); key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.1:1 (0.2 stops); soft light (almost no shadow edge) - Text track (captions / bottom): 选择我提前录好的出镜画面 / ABC / PQRS / TUV - Text track (captions / bottom): 我你在这一不是今天 / 我23你在这ABC不D爆 / 今天 / 发送 - Text track (captions / bottom): 123 / ABC / DEF / #@¥ - Text track (captions / middle): @知遇 / 我你在这一不是今天 / 我你在这一不是 - Remake: the original is live footage: reshoot per the shooting plan (shot size / camera / lighting); only when shooting is not possible, approximate it with AI image-to-video (using the first frame as reference); the user must supply the real material: live video footage (whole frame) - First-frame image prompt: close-up, slightly high angle, a hand holding a stylus operating a smartphone screen that shows an app interface with avatars and a text box, soft indoor light, real photography, high resolution. - Video prompt: close-up, fixed camera. A hand holding a stylus taps on a smartphone screen: first a round avatar at the top, then pastes a passage of text into the text box below, and finally taps the button at the bottom left. Natural movement, the screen UI sharp. ### #12 00:40.167–00:41.200 · Live footage + code / editor overlays (text labels); introduces real material (live video footage) ![shot_012](shots/shot_012.jpg) - Probabilities: live footage 84%, AI-generated video 3%, 3D rendering 3% (fused) - ⚠️ To be confirmed: live footage or AI: the picture comes from 24 fps material and carries no AIGC label, which is not the signature of native 30 fps phone footage - Text on objects in the frame (not post-production captions): 最近使用, 请使用本人素材或取得搜权,不得生成传播违法违规或, 请使用本人素材或取得授权,不得生成传播违法连规或, 便犯他人权益内容, 侵犯他人权益内容, 侵犯他人权益内容, - Material: user's real material: live video footage - Photo / video texture: noise σ=0.26, 409 colors, flat blocks 12% - Re-encoded by the platform (Douyin/TikTok), sensor noise crushed: noise-based evidence is void; live vs. AI rests mainly on frame rate and picture content - [VLM] Real finger and stylus materials - [VLM] Real physical reflections and fingerprint smudges on the phone screen - [VLM] Natural small hand movements and changing shadows - [VLM] Real app interaction feedback on the screen - [claude visual review] The frame shows the phone's black bezel and rounded corners, a band of ceiling-light reflection on the screen, and a finger and stylus reaching in from the right: a camera filming a real phone, not a screen recording - [claude visual review] The screen shows real app UIs (Doubao / Jimeng Seedance 2.0) with status-bar times 15:10–15:14 - Picture: a high-angle close-up of a phone on the desk; a hand with a stylus scrolls the gallery on the screen and ticks two images. - Framing / light: close-up (phone screen); slightly high angle (phone standing / tilted on the desk, camera from front above); tripod / stand, fixed; frontal soft light (flat); key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.1:1 (0.1 stops); soft light (almost no shadow edge) - Text track (text / bottom): 导入我们这两张水杯图片 - Text track (captions / bottom): 最近使用 / 请使用本人素材或取得搜权,不得生成传播违法违规或 / 请使用本人素材或取得授权,不得生成传播违法连规或 / 请使用本人素材或取得授权。不得生成传播违法连规或 - Text track (captions / bottom): 便犯他人权益内容 / 侵犯他人权益内容 / 侵犯他人权益内容, - Text track (captions / middle): 最近项目·即梦资产 / 无相册 - Remake: the original is live footage: reshoot per the shooting plan (shot size / camera / lighting); only when shooting is not possible, approximate it with AI image-to-video (using the first frame as reference); the user must supply the real material: live video footage (whole frame) - First-frame image prompt: close-up, high angle, a smartphone lying flat on a desk with its screen lit showing a photo-library interface, a hand holding a white stylus tapping an image on the screen, soft indoor light, photorealistic photography. - Video prompt: close-up, fixed high-angle camera on a phone on the desk. A hand holding a stylus scrolls the gallery on the phone screen and taps to select two images in succession. Natural fluid movement, real reflections on the screen. ### #13 00:41.200–00:42.267 · Live footage + code / editor overlays (captions); introduces real material (live video footage) ![shot_013](shots/shot_013.jpg) - Probabilities: live footage 81%, 3D rendering 5%, AI-generated video 3% (fused) - ⚠️ To be confirmed: live footage or AI: the picture comes from 24 fps material and carries no AIGC label, which is not the signature of native 30 fps phone footage - Text on objects in the frame (not post-production captions): 请使用本人素材或取得授权,不得生成传播违法连规或, 侵犯他人权益内容, 选拼音, ABC, PQRS, TUV - Material: user's real material: live video footage - Re-encoded by the platform (Douyin/TikTok), sensor noise crushed: noise-based evidence is void; live vs. AI rests mainly on frame rate and picture content - [VLM] Real finger skin texture and nail reflections - [VLM] Real physical interaction and shadows where the stylus touches the screen - [VLM] Real reflections and moiré on the phone screen - [VLM] Natural slight shake from handheld shooting - [claude visual review] The frame shows the phone's black bezel and rounded corners, a band of ceiling-light reflection on the screen, and a finger and stylus reaching in from the right: a camera filming a real phone, not a screen recording - [claude visual review] The screen shows real app UIs (Doubao / Jimeng Seedance 2.0) with status-bar times 15:10–15:14 - [claude visual review] Fixed camera; the phone and desk do not move - Picture: a close-up of a hand with a stylus operating a phone screen, selecting images in the Seedance 2.0 app and preparing to type text. - Framing / light: close-up (phone screen); slightly high angle (phone standing / tilted on the desk, camera from front above); tripod / stand, fixed; frontal soft light (flat); key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.1:1 (0.1 stops); soft light (almost no shadow edge) - Text track (captions / bottom): 导入我们这两张水杯图片 / ABC / PQRS / TUV - Text track (captions / bottom): 请使用本人素材或取得授权,不得生成传播违法连规或 / 侵犯他人权益内容 / 选拼音 / 空格 - Text track (captions / bottom): ABC / PQRS / TUV / WXYZ - Text track (captions / middle): ral / Natural / 我你在这一不是 / 123 - Remake: the original is live footage: reshoot per the shooting plan (shot size / camera / lighting); only when shooting is not possible, approximate it with AI image-to-video (using the first frame as reference); the user must supply the real material: live video footage (whole frame) - First-frame image prompt: close-up, high angle, a hand holding a white stylus operating a smartphone whose screen shows an image-selection interface and an input box, soft indoor light, photorealistic style. - Video prompt: close-up, high angle, a hand holding a white stylus taps on a smartphone screen, first scrolling the gallery to select images, then tapping the input box below so the keyboard pops up; slight handheld shake, real and natural. ### #14 00:42.267–00:43.067 · Live footage; introduces real material (live video footage) ![shot_014](shots/shot_014.jpg) - Probabilities: live footage 81%, 3D rendering 4%, AI-generated video 3% (fused) - ⚠️ To be confirmed: live footage or AI: the picture comes from 24 fps material and carries no AIGC label, which is not the signature of native 30 fps phone footage - Text on objects in the frame (not post-production captions): #@¥, GHI, JKL, ABC, PQRS, TUV - Material: user's real material: live video footage - Re-encoded by the platform (Douyin/TikTok), sensor noise crushed: noise-based evidence is void; live vs. AI rests mainly on frame rate and picture content - [VLM] Real hand skin texture and nail detail - [VLM] The stylus's physical shadow on the screen and the interaction feedback - [VLM] Real ambient reflections on the phone screen surface - [VLM] Natural slight handheld shake and optical background blur - [claude visual review] The frame shows the phone's black bezel and rounded corners, a band of ceiling-light reflection on the screen, and a finger and stylus reaching in from the right: a camera filming a real phone, not a screen recording - [claude visual review] The screen shows real app UIs (Doubao / Jimeng Seedance 2.0) with status-bar times 15:10–15:14 - [claude visual review] Fixed camera; the phone and desk do not move - Picture: a close-up of a hand with a white stylus operating a smartphone screen, tapping the "props" icon in the Seedance 2.0 app interface. - Framing / light: close-up (phone screen); slightly high angle (phone standing / tilted on the desk, camera from front above); tripod / stand, fixed; front-side key + fill (standard setup); key front right; contrast about 1.6:1 (0.7 stops); hard light (clear shadow edge) - Text track (captions / bottom): #@¥ / GHI / JKL / MNO - Text track (captions / bottom): ABC / PQRS / TUV / WXYZ - Text track (captions / bottom): 选拼音 / 空格 / #冒美 / POR'S - Text track (captions / bottom): 发送 / TUV / WXYZ / 空格 - Remake: the original is live footage: reshoot per the shooting plan (shot size / camera / lighting); only when shooting is not possible, approximate it with AI image-to-video (using the first frame as reference); the user must supply the real material: live video footage (whole frame) - First-frame image prompt: close-up, a hand holding a white stylus tapping a smartphone screen that shows an app interface with chat bubbles and tool icons, soft indoor light, photorealistic photography, shallow depth of field. - Video prompt: close-up, a hand holding a white stylus taps the "props" icon on a smartphone screen and the interface changes; natural fluid movement, a slight handheld-camera feel, real light and shadow. ### #15 00:43.067–00:43.733 · Live footage; introduces real material (live video footage) ![shot_015](shots/shot_015.jpg) - Probabilities: live footage 85%, AI-generated video 4%, 3D rendering 3% (fused) - ⚠️ To be confirmed: live footage or AI: the picture comes from 24 fps material and carries no AIGC label, which is not the signature of native 30 fps phone footage - Text on objects in the frame (not post-production captions): 最近使用, 最近使用, 请使用本人素材碳取得授权,不得生成传播违法违现或, 侵犯他人权益内容, 请使用本人素材或取得授权,不得生成传播建法违题显, ral - Material: user's real material: live video footage - Photo / video texture: noise σ=0.30, 398 colors, flat blocks 10% - Re-encoded by the platform (Douyin/TikTok), sensor noise crushed: noise-based evidence is void; live vs. AI rests mainly on frame rate and picture content - [VLM] Real hand skin texture and nail reflections - [VLM] The stylus's real physical shadow on the screen - [VLM] Real ambient reflections on the phone screen surface - [VLM] Natural optical blur in the background - [VLM] Natural tiny shake from handheld shooting - [claude visual review] The frame shows the phone's black bezel and rounded corners, a band of ceiling-light reflection on the screen, and a finger and stylus reaching in from the right: a camera filming a real phone, not a screen recording - Picture: a close-up of a hand with a white stylus scrolling a phone screen, browsing an image library labeled "Seedance 2.0". - Framing / light: close-up (phone screen); slightly high angle (phone standing / tilted on the desk, camera from front above); tripod / stand, fixed; frontal soft light (flat); key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.2:1 (0.3 stops); soft light (almost no shadow edge) - Text track (text / bottom): 最近使用 - Text track (text / bottom): 最近使用 - Text track (captions / bottom): 请使用本人素材碳取得授权,不得生成传播违法违现或 / 侵犯他人权益内容 / 请使用本人素材或取得授权,不得生成传播建法违题显 / 侵犯他人权益内容。 - Text track (captions / middle): ral / Natural - Remake: the original is live footage: reshoot per the shooting plan (shot size / camera / lighting); only when shooting is not possible, approximate it with AI image-to-video (using the first frame as reference); the user must supply the real material: live video footage (whole frame) - First-frame image prompt: close-up, slightly high angle, a hand holding a white stylus scrolling a smartphone screen that shows an image library with many pictures, a blurred interior in the background, natural light, photorealistic style. - Video prompt: close-up, a hand holding a white stylus scrolls up and down on a smartphone screen, browsing the image library as the content scrolls; handheld, slight shake. ### #16 00:43.733–00:47.067 · Live footage + code / editor overlays (captions); introduces real material (live video footage) ![shot_016](shots/shot_016.jpg) - Probabilities: live footage 77%, 3D rendering 7%, 2D animation 3% (fused) - ⚠️ To be confirmed: live footage or AI: the picture comes from 24 fps material and carries no AIGC label, which is not the signature of native 30 fps phone footage - Text on objects in the frame (not post-production captions): 123, 选拼音, 空格, Natura, ral, Natural - Material: user's real material: live video footage - Rendered texture: flat color blocks 26%, 95% of pixels use only 67 colors, horizontal / vertical straight edges 43% - Re-encoded by the platform (Douyin/TikTok), sensor noise crushed: noise-based evidence is void; live vs. AI rests mainly on frame rate and picture content - [VLM] Real phone bezel and screen reflections - [VLM] Real handheld stylus operation with natural continuous movement - [VLM] Slight moiré and perspective from a camera filming a screen - [claude visual review] The frame shows the phone's black bezel and rounded corners, a band of ceiling-light reflection on the screen, and a finger and stylus reaching in from the right: a camera filming a real phone, not a screen recording - [claude visual review] The screen shows real app UIs (Doubao / Jimeng Seedance 2.0) with status-bar times 15:10–15:14 - [claude visual review] Fixed camera; the phone and desk do not move - Picture: a close-up, the camera looking down at a phone screen. A hand holding a stylus operates the Jimeng app interface, entering a prompt and tapping send. - Framing / light: close-up (phone screen); slightly high angle (phone standing / tilted on the desk, camera from front above); tripod / stand, fixed; frontal soft light (flat); key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.0:1 (0.0 stops); soft light (almost no shadow edge) - Text track (captions / bottom): 最近使用 / #@¥ / 然后我们点击发送 / vv - Text track (text / bottom): 123 - Text track (captions / bottom): ABC / PQRS / TUV / WXYZ - Text track (captions / bottom): 选拼音 / 空格 - Remake: the original is live footage: reshoot per the shooting plan (shot size / camera / lighting); only when shooting is not possible, approximate it with AI image-to-video (using the first frame as reference); the user must supply the real material: live video footage (whole frame) - First-frame image prompt: close-up, high angle on a smartphone screen showing an AI video-generation app interface, a hand holding a stylus tapping the screen, real indoor light, photorealistic photography. - Video prompt: close-up, high angle on a smartphone screen showing an AI video-generation app. A hand holding a stylus scrolls the gallery on the screen, then taps the input box, and finally taps the blue send button. The frame stays fixed, with a real photographic look. ### #17 00:47.067–00:47.733 · Live footage + code / editor overlays (text labels, captions, styled text); introduces real material (live video footage) ![shot_017](shots/shot_017.jpg) - Probabilities: live footage 81%, 3D rendering 5%, AI-generated video 3% (fused) - ⚠️ To be confirmed: live footage or AI: the picture comes from 24 fps material and carries no AIGC label, which is not the signature of native 30 fps phone footage - Text on objects in the frame (not post-production captions): 出镜, 生图, 知道, 知遇, 提交成功,消耗1个额度, 邀请好友 - Material: user's real material: live video footage - Re-encoded by the platform (Douyin/TikTok), sensor noise crushed: noise-based evidence is void; live vs. AI rests mainly on frame rate and picture content - [VLM] Real ambient reflections on the phone screen surface - [VLM] Real physical interaction of a handheld stylus tapping the screen - [VLM] Real depth-of-field blur in the background - [VLM] A slight natural handheld breathing motion - [claude visual review] The frame shows the phone's black bezel and rounded corners, a band of ceiling-light reflection on the screen, and a finger and stylus reaching in from the right: a camera filming a real phone, not a screen recording - [claude visual review] The screen shows real app UIs (Doubao / Jimeng Seedance 2.0) with status-bar times 15:10–15:14 - [claude visual review] Fixed camera; the phone and desk do not move - Picture: a close-up of a phone screen showing the Seedance 2.0 app interface with several round avatars and a toast pop-up. A hand holding a white stylus taps the bottom-right corner of the screen. - Framing / light: close-up (phone screen); slightly high angle (phone standing / tilted on the desk, camera from front above); tripod / stand, fixed; frontal soft light (flat); key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.2:1 (0.3 stops); soft light (almost no shadow edge) - Text track (text / bottom): 可以看到视频生成的进度 - Text track (captions / bottom): 输入描述你的梦境 / 生成中 - Text track (captions / bottom): 出镜 / 生图 - Text track (captions / middle): 知道 / 知遇 - Remake: the original is live footage: reshoot per the shooting plan (shot size / camera / lighting); only when shooting is not possible, approximate it with AI image-to-video (using the first frame as reference); the user must supply the real material: live video footage (whole frame) - First-frame image prompt: close-up, a smartphone showing an app interface with several round avatars, real ambient reflections on the screen, a hand holding a white stylus about to tap the bottom-right corner of the screen, blurred background, natural indoor light, photorealistic photography. - Video prompt: close-up, handheld shot of a smartphone screen. The screen shows an app interface with several round character avatars and a semi-transparent toast pop-up. A hand holding a white stylus enters the frame and gently taps the button in the bottom-right corner. Slight handheld shake, real reflections on the screen surface, natural depth-of-field blur in the background. ### #18 00:47.733–00:49.133 · Live footage + code / editor overlays (captions, styled text); introduces real material (live video footage) ![shot_018](shots/shot_018.jpg) - Probabilities: live footage 76%, 3D rendering 6%, screen recording / screenshot 4% (fused) - ⚠️ To be confirmed: live footage or AI: the picture comes from 24 fps material and carries no AIGC label, which is not the signature of native 30 fps phone footage - Text on objects in the frame (not post-production captions): 知遇, 粉丝, 关注, 解锁生成额度, 作品, 出镜 - Material: user's real material: live video footage - Rendered texture: flat color blocks 30%, 95% of pixels use only 92 colors, horizontal / vertical straight edges 47% - Re-encoded by the platform (Douyin/TikTok), sensor noise crushed: noise-based evidence is void; live vs. AI rests mainly on frame rate and picture content - [VLM] The physical phone screen carries reflections of a real interior - [VLM] The real phone bezel, the earpiece slit and edge reflections are visible - [VLM] The draft thumbnail in the UI has an animated loading-ring progress indicator in its top-right corner - [claude visual review] The frame shows the phone's black bezel and rounded corners, a band of ceiling-light reflection on the screen, and a finger and stylus reaching in from the right: a camera filming a real phone, not a screen recording - [claude visual review] The screen shows real app UIs (Doubao / Jimeng Seedance 2.0) with status-bar times 15:10–15:14 - [claude visual review] Fixed camera; the phone and desk do not move - Picture: a fixed close-up of a smartphone on a stand; the screen shows an app's profile page and the progress ring of a video being generated in Drafts. - Framing / light: close-up (phone screen); slightly high angle (phone standing / tilted on the desk, camera from front above); tripod / stand, fixed; front-side key + fill (standard setup); key front left; contrast about 1.5:1 (0.5 stops); soft light (wide shadow transition) - Text track (captions / bottom): 可以看到视频生成的进度 / 暂时没有更多了 - Text track (text / middle): 知遇 - Text track (captions / middle): 粉丝 / 关注 / 解锁生成额度 / 管理分身 - Text track (captions / middle): 作品 / 出镜 / 草稿箱 - Remake: the original is live footage: reshoot per the shooting plan (shot size / camera / lighting); only when shooting is not possible, approximate it with AI image-to-video (using the first frame as reference); the user must supply the real material: live video footage (whole frame) - First-frame image prompt: close-up, straight on at eye level, a black smartphone standing upright with its screen lit, showing a clean modern app profile page; the Drafts entry has a colorful gradient cover and a round loading icon; a faint interior reflection on the screen, soft indoor light. - Video prompt: fixed close-up of a smartphone on a desk, the screen lit showing the app's profile page; in the bottom-left Drafts thumbnail the round progress ring in the top-right corner fills clockwise; the frame stays steady and sharp with no shake. ### #19 00:49.133–00:51.500 · AI-generated video + code / editor overlays (captions, title) ![shot_019](shots/shot_019.jpg) - Probabilities: AI-generated video 82%, live footage 6%, 3D rendering 3% (fused) - ⚠️ To be confirmed: live footage / stop motion or AI: no AIGC label; 24 fps source traces occur in AI video, stop motion and cinema-camera footage alike - Text on objects in the frame (not post-production captions): Niee tonekt gor, Nice tomectyou, Nicctomeety, mayaffimsNg, Nadtscay, Its - Material: AI-generated - Likely tool: Jimeng - Photo / video texture: noise σ=0.25, 210 colors, flat blocks 21% - Re-encoded by the platform (Douyin/TikTok), sensor noise crushed: noise-based evidence is void; live vs. AI rests mainly on frame rate and picture content - [VLM] Gibberish English letters on the gift box at the left (such as "And ts sca... friendeli") - [VLM] Slight blending and warping where the fingers meet the mug - [VLM] Details of the mug's print (the little bear, the dots) flicker and change slightly during motion - [VLM] A Jimeng watermark in the bottom-right corner and an "AI生成" (AI-generated) label in the top-left - [claude visual review] A Jimeng watermark and the "@知遇" account name in the bottom-right corner: a clip exported from Jimeng - [claude visual review] The English print on the gift box is gibberish (OCR reads "I+'s aod to see you agay,and / may ou friendship las+frever."); real packaging would not look like this - Picture: a young woman sits at a wooden table holding an apple-shaped lidded ceramic mug with both hands, showing it to the camera and speaking. The matching gift box and a gingham cloth are on the table. Sunlight comes from the right. The camera pushes in slowly. - Framing / light: medium close-up; eye level; cannot be determined (simulated tripod lock-off); frontal soft light (flat); key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.2:1 (0.3 stops); soft light (almost no shadow edge) - Text track (captions / bottom): 即梦 / @知遇 - Text track (text / bottom): Nicetomcety - Text track (captions / middle): Niee tonekt gor / Nice tomectyou / Nicctomeety - Text track (captions / middle): mayaffimsNg / Nadtscay / Its / frlololsn - Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first - First-frame image prompt: vertical 9:16, cozy tabletop scene: a long-haired young woman in a cream sweater sits at a natural-wood table holding a red apple-shaped ceramic mug with both hands (the lid is an apple, the beige body printed with small trees and apples), a beige gift box printed with apples behind her, a red-and-white gingham cloth and a wooden spoon on the table; soft natural light, light-colored wall softly blurred behind, photorealistic product-video style - Video prompt: smiling, the young woman picks up the apple-shaped ceramic mug from the table, holds it with both hands at chest height toward the camera and gently turns it so the apple print faces the lens; the camera pushes in slowly from a medium shot to a close-up of the mug, ending with the mug filling the center of the frame ### #20 00:51.500–00:54.900 · AI-generated video + code / editor overlays (captions, title, styled text) ![shot_020](shots/shot_020.jpg) - Probabilities: AI-generated video 79%, live footage 10%, 3D rendering 3% (fused) - ⚠️ To be confirmed: live footage / stop motion or AI: no AIGC label; 24 fps source traces occur in AI video, stop motion and cinema-camera footage alike - Text on objects in the frame (not post-production captions): reet, meer, meet - Material: AI-generated - Likely tool: Jimeng AI - Photo / video texture: noise σ=0.23, 232 colors, flat blocks 22% - Re-encoded by the platform (Douyin/TikTok), sensor noise crushed: noise-based evidence is void; live vs. AI rests mainly on frame rate and picture content - [VLM] A clear "AI生成" (AI-generated) watermark in the top-left corner - [VLM] A Jimeng AI platform watermark and creator handle in the bottom-right corner - [VLM] Slight warping and smooth melting at the contact surfaces as the fingers handle the lid and spoon - [VLM] The liquid's ripple and the spoon entering the drink show the typical physics of text / image-to-video generation - [claude visual review] A Jimeng watermark and the "@知遇" account name in the bottom-right corner: a clip exported from Jimeng - [claude visual review] The English print on the gift box is gibberish (OCR reads "I+'s aod to see you agay,and / may ou friendship las+frever."); real packaging would not look like this - Picture: a high-angle tabletop close-up; a hand lifts the red apple-shaped lid off the mug and sets it aside, then picks up the twig-shaped spoon and puts it into the cute cartoon mug full of milk tea. - Framing / light: close-up; slightly high angle; overhead desk stand; backlit / background brighter than the subject; key front right; contrast about 1.4:1 (0.4 stops); cannot be determined - Text track (captions / bottom): 即梦 / @知遇 - Text track (text / middle): rever. - Text track (captions / middle): reet / meer / meet - Text track (title / top): AI生成 / 即梦 - Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first - First-frame image prompt: vertical 9:16, cozy tabletop scene: a long-haired young woman in a cream sweater sits at a natural-wood table holding a red apple-shaped ceramic mug with both hands (the lid is an apple, the beige body printed with small trees and apples), a beige gift box printed with apples behind her, a red-and-white gingham cloth and a wooden spoon on the table; soft natural light, light-colored wall softly blurred behind, photorealistic product-video style - Video prompt: smiling, the young woman picks up the apple-shaped ceramic mug from the table, holds it with both hands at chest height toward the camera and gently turns it so the apple print faces the lens; the camera pushes in slowly from a medium shot to a close-up of the mug, ending with the mug filling the center of the frame ### #21 00:54.900–00:57.667 · AI-generated video + code / editor overlays (title) ![shot_021](shots/shot_021.jpg) - Probabilities: AI-generated video 82%, live footage 6%, 3D rendering 3% (fused) - ⚠️ To be confirmed: live footage / stop motion or AI: no AIGC label; 24 fps source traces occur in AI video, stop motion and cinema-camera footage alike - Text on objects in the frame (not post-production captions): Niet to mut you, Niek to mect yeu., Nicc to eet you, Niek to muat yeu. - Material: AI-generated - Likely tool: Jimeng - Photo / video texture: noise σ=0.27, 161 colors, flat blocks 21% - Re-encoded by the platform (Douyin/TikTok), sensor noise crushed: noise-based evidence is void; live vs. AI rests mainly on frame rate and picture content - [VLM] An "AI生成" (AI-generated) watermark in the top-left corner and a Jimeng logo in the top-right - [VLM] The English letters on the gift box are meaningless gibberish - [VLM] The fingers of the left hand warp and blend unnaturally while gripping the mug - [VLM] The spoon on the table is irregular in shape and warps slightly during motion - [claude visual review] A Jimeng watermark and the "@知遇" account name in the bottom-right corner: a clip exported from Jimeng - [claude visual review] The English print on the gift box is gibberish (OCR reads "I+'s aod to see you agay,and / may ou friendship las+frever."); real packaging would not look like this - Picture: a young woman sits at a wooden table cupping a red apple-shaped mug with both hands, bringing it up and pressing it to her cheek. The matching gift box, a gingham napkin and a small spoon are on the table. The camera pushes in slowly. - Framing / light: medium close-up; slightly high angle; tripod / stand, fixed; frontal soft light (flat); key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.2:1 (0.3 stops); soft light (almost no shadow edge) - Text track (captions / bottom): Niet to mut you / Niek to mect yeu. - Text track (text / middle): moAlDUa - Text track (captions / middle): Nicc to eet you / Niek to muat yeu. - Text track (title / top): AI生成 / 即梦 / 梦 - Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first - First-frame image prompt: vertical 9:16, cozy tabletop scene: a long-haired young woman in a cream sweater sits at a natural-wood table holding a red apple-shaped ceramic mug with both hands (the lid is an apple, the beige body printed with small trees and apples), a beige gift box printed with apples behind her, a red-and-white gingham cloth and a wooden spoon on the table; soft natural light, light-colored wall softly blurred behind, photorealistic product-video style - Video prompt: smiling, the young woman picks up the apple-shaped ceramic mug from the table, holds it with both hands at chest height toward the camera and gently turns it so the apple print faces the lens; the camera pushes in slowly from a medium shot to a close-up of the mug, ending with the mug filling the center of the frame ## Notes - Deterministic forensics are reliable for "is it moving, is it a whole-image push, is the texture rendered, was there a 24→30 frame-rate conversion"; telling live footage, AI and 3D apart relies on the VLM and human review. - Platform transcoding usually strips metadata; missing metadata does not mean there was none.