# Video breakdown report: qing_hiphop_full.mp4
> English translation of [report.md](report.md), the Markdown report rea-video generated for this video. Section order and content follow the tool output. Text recognized on screen (the "text track" lines) is kept in the original Chinese, since that is what appears in the frame; song lyrics quoted from the audio also stay in Chinese, with a short gloss where it helps.
**Verdict**: mixed production: AI-generated video 52% + still-image push / pan (Ken Burns) 17% + talking avatar 17% + 3D rendering 15%; overlays: text labels, graphic stickers, captions (composited in code / an editor); real material used: real photos (3.0 s), product photos (0.7 s); reference material to prepare for the remake: character / scene reference image (1 shot), product reference image (1 shot); audio: voice + BGM at 178.2 BPM (AI-generated music) + 56 sound effects
- Duration 164.958 s · 1080×1920 · 24.0 fps · 9:16
- 86 shots, 1.92 s average; transitions: cut×85, start×1
- Confidence (duration-weighted): 71%; method: deterministic forensics fused with a vision model (VLM)
- VLM partly active (gemini-3.1-pro-preview, gemini-3.1-pro-preview-pc, gcp-gemini-3-pro-preview: results for 60/60 shots, whole-video analysis failed); the agent (claude) visually reviewed 9 of 86 shots, merged into the verdict
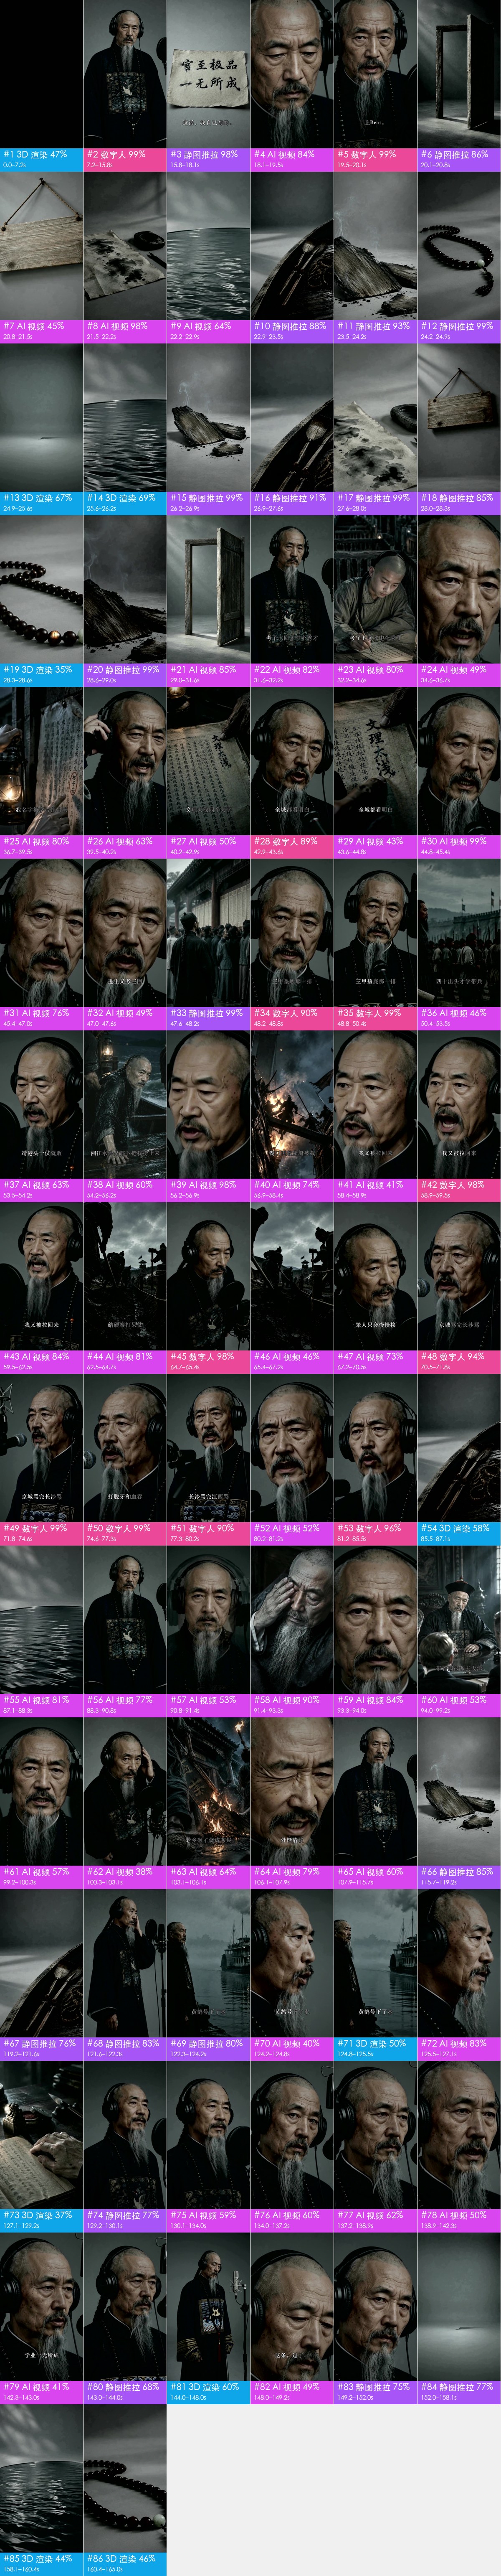
## Production method share
| Underlying picture | Duration | Share |
|---|---|---|
| AI-generated video | 86.04 s | 52% |
| Still-image push / pan (Ken Burns) | 27.46 s | 17% |
| Talking avatar | 27.25 s | 16% |
| 3D rendering | 24.21 s | 15% |
## Remake plan
**10 3D-rendered shots + 45 AI video shots → 34 generation units, 34 Seedance 2.5 calls; 19 still-image push / pan / still-frame shots → rebuilt locally; 12 talking-avatar shots → TTS + avatar driving**
- The default engine, Seedance 2.0 (including Mini / Fast), cannot produce several shots in one call; with it you would generate the 55 shots one by one. This plan assumes Seedance 2.5 (≤30 s per call, multi-shot in one call): 34 calls in total
- Grouping rules: AI shots in the same set joined by hard cuts are merged into one generation (S01); ≤30 s per call; consecutive hard cuts inside a unit should stay ≤8 s, at most 10 s (S06); split at dissolves / fades and set changes (S03)
- Audio: the model can generate action sound effects and ambience along with the picture; voice-over is better done as separate TTS and mixed in, so you can change the script and timing
### Generation units
| Unit | Shots | Time | Duration | Method | Continuity |
|---|---|---|---|---|---|
| G1 | #1 | 0.0–7.2 s | 7.2 s | single shot | First frame: generate an image with the composition of the original shot 1 first frame (shots/shot_001_first.jpg), swapping the product for @image1 |
| G2 | #4 | 18.1–19.5 s | 1.4 s | single shot | First frame: generate an image with the composition of the original shot 4 first frame (shots/shot_004_first.jpg), swapping the product for @image1 |
| G3 | #7 | 20.8–21.5 s | 0.7 s | single shot | First frame: generate an image with the composition of the original shot 7 first frame (shots/shot_007_first.jpg), swapping the product for @image1 |
| G4 | #8 | 21.5–22.2 s | 0.7 s | single shot | First frame: generate an image with the composition of the original shot 8 first frame (shots/shot_008_first.jpg), swapping the product for @image1 |
| G5 | #9, #13, #14 | 22.2–22.9 s, 24.9–26.2 s | 2.0 s | multi-shot in one call | First frame: generate an image with the composition of the original shot 9 first frame (shots/shot_009_first.jpg), swapping the product for @image1 |
| G6 | #19, #21 | 28.3–28.6 s, 29.0–31.6 s | 3.0 s | multi-shot in one call | First frame: generate an image with the composition of the original shot 19 first frame (shots/shot_019_first.jpg), swapping the product for @image1 |
| G7 | #22–#23 | 31.6–34.6 s | 3.0 s | multi-shot in one call | First frame: generate an image with the composition of the original shot 22 first frame (shots/shot_022_first.jpg), swapping the product for @image1 |
| G8 | #24–#27 | 34.6–42.9 s | 8.2 s | multi-shot in one call | First frame: generate an image with the composition of the original shot 24 first frame (shots/shot_024_first.jpg), swapping the product for @image1 |
| G9 | #29 | 43.6–44.8 s | 1.2 s | single shot | First frame: generate an image with the composition of the original shot 29 first frame (shots/shot_029_first.jpg), swapping the product for @image1 |
| G10 | #30–#32 | 44.8–47.6 s | 2.8 s | multi-shot in one call | First frame: generate an image with the composition of the original shot 30 first frame (shots/shot_030_first.jpg), swapping the product for @image1 |
| G11 | #36–#37 | 50.4–54.2 s | 3.8 s | multi-shot in one call | First frame: generate an image with the composition of the original shot 36 first frame (shots/shot_036_first.jpg), swapping the product for @image1 |
| G12 | #38 | 54.2–56.2 s | 2.0 s | single shot | First frame: generate an image with the composition of the original shot 38 first frame (shots/shot_038_first.jpg), swapping the product for @image1 |
| G13 | #39 | 56.2–56.9 s | 0.7 s | single shot | First frame: generate an image with the composition of the original shot 39 first frame (shots/shot_039_first.jpg), swapping the product for @image1 |
| G14 | #40 | 56.9–58.4 s | 1.5 s | single shot | First frame: generate an image with the composition of the original shot 40 first frame (shots/shot_040_first.jpg), swapping the product for @image1 |
| G15 | #41 | 58.4–58.9 s | 0.5 s | single shot | First frame: generate an image with the composition of the original shot 41 first frame (shots/shot_041_first.jpg), swapping the product for @image1 |
| G16 | #43 | 59.5–62.5 s | 3.0 s | single shot | First frame: generate an image with the composition of the original shot 43 first frame (shots/shot_043_first.jpg), swapping the product for @image1 |
| G17 | #44 | 62.5–64.7 s | 2.1 s | single shot | First frame: generate an image with the composition of the original shot 44 first frame (shots/shot_044_first.jpg), swapping the product for @image1 |
| G18 | #46 | 65.4–67.2 s | 1.8 s | single shot | First frame: generate an image with the composition of the original shot 46 first frame (shots/shot_046_first.jpg), swapping the product for @image1 |
| G19 | #47 | 67.2–70.5 s | 3.4 s | single shot | First frame: generate an image with the composition of the original shot 47 first frame (shots/shot_047_first.jpg), swapping the product for @image1 |
| G20 | #52 | 80.2–81.2 s | 1.0 s | single shot | First frame: generate an image with the composition of the original shot 52 first frame (shots/shot_052_first.jpg), swapping the product for @image1 |
| G21 | #54 | 85.5–87.1 s | 1.7 s | single shot | First frame: generate an image with the composition of the original shot 54 first frame (shots/shot_054_first.jpg), swapping the product for @image1 |
| G22 | #55 | 87.1–88.3 s | 1.2 s | single shot | First frame: generate an image with the composition of the original shot 55 first frame (shots/shot_055_first.jpg), swapping the product for @image1 |
| G23 | #56–#58 | 88.3–93.3 s | 5.0 s | multi-shot in one call | First frame: generate an image with the composition of the original shot 56 first frame (shots/shot_056_first.jpg), swapping the product for @image1 |
| G24 | #59 | 93.3–94.0 s | 0.7 s | single shot | First frame: generate an image with the composition of the original shot 59 first frame (shots/shot_059_first.jpg), swapping the product for @image1 |
| G25 | #60 | 94.0–99.2 s | 5.2 s | single shot | First frame: generate an image with the composition of the original shot 60 first frame (shots/shot_060_first.jpg), swapping the product for @image1 |
| G26 | #61–#64 | 99.2–107.9 s | 8.7 s | multi-shot in one call | First frame: generate an image with the composition of the original shot 61 first frame (shots/shot_061_first.jpg), swapping the product for @image1 |
| G27 | #65, #70 | 107.9–115.7 s, 124.2–124.8 s | 8.4 s | multi-shot in one call | First frame: generate an image with the composition of the original shot 65 first frame (shots/shot_065_first.jpg), swapping the product for @image1 |
| G28 | #71 | 124.8–125.5 s | 0.6 s | single shot | First frame: generate an image with the composition of the original shot 71 first frame (shots/shot_071_first.jpg), swapping the product for @image1 |
| G29 | #72 | 125.5–127.1 s | 1.6 s | single shot | First frame: generate an image with the composition of the original shot 72 first frame (shots/shot_072_first.jpg), swapping the product for @image1 |
| G30 | #73 | 127.1–129.2 s | 2.1 s | single shot | First frame: generate an image with the composition of the original shot 73 first frame (shots/shot_073_first.jpg), swapping the product for @image1 |
| G31 | #75–#77 | 130.1–138.9 s | 8.8 s | multi-shot in one call | First frame: generate an image with the composition of the original shot 75 first frame (shots/shot_075_first.jpg), swapping the product for @image1 |
| G32 | #78, #79, #81, #82 | 138.9–143.0 s, 144.0–149.2 s | 9.3 s | multi-shot in one call | First frame: use G31's last frame and continue the action (S05) |
| G33 | #85 | 158.1–160.4 s | 2.2 s | single shot | First frame: generate an image with the composition of the original shot 85 first frame (shots/shot_085_first.jpg), swapping the product for @image1 |
| G34 | #86 | 160.4–165.0 s | 4.6 s | single shot | First frame: generate an image with the composition of the original shot 86 first frame (shots/shot_086_first.jpg), swapping the product for @image1 |
**G1 · 3D rendering · shot #1 · 7.2 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 0.0–7.2 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- First-frame image prompt: profile close-up of an elderly Qing-dynasty official with a long white beard, wearing black modern over-ear headphones, pure black background, very strong single-side rim light, cinematic texture, 8k photoreal detail
- Alternative route: a 3D project. Have an LLM write a Blender script or a Three.js scene; model the characters / props once, set a camera per shot and render. Best for multiple angles and character consistency, and changing copy or shots is just changing code (R08)
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm.
Under side light on a black background, a long-bearded Qing-dynasty elder wearing modern over-ear headphones moves his face slightly, lips parting a little as he murmurs; the camera pushes forward extremely slowly to a facial close-up, keeping the high-contrast silhouette lighting unchanged
```
English prompt (as generated by the tool)
```text
Close-up of an elderly Qing Dynasty official with a long white beard wearing modern over-ear headphones, dramatic side rim lighting against a pure black background, subtle head movement and slight lip movements, slow smooth camera push-in.
```
**G2 · AI-generated video · shot #4 · 1.4 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 18.1–19.5 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- First-frame image prompt: close-up portrait of a very old Asian man, weathered face, deep wrinkles and age spots, thick moustache and long grey-white goatee, wearing black monitor headphones, deep black background, dramatic cinematic side light, ultra-fine skin texture, vertical composition.
- Generate 4 s and trim to 1.4 s (very short shots are unstable when generated on their own)
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm.
A very old long-bearded Asian man, head bowed and still, wearing black headphones, then slowly lifts his eyelids and stares into the camera, eyes deep and cold, face kept solemn, extremely faint breathing and tiny head movement, fixed shot.
```
English prompt (as generated by the tool)
```text
Close-up of an elderly Asian man with long grey beard and studio headphones, initially looking down, slowly raising his eyes to stare into the camera with an intense, solemn expression, minimal movement, locked-off shot.
```
**G3 · AI-generated video · shot #7 · 0.7 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 20.8–21.5 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- First-frame image prompt: minimalist still life, grey micro-cement wall, a single old iron nail with a thick hemp rope hanging a weathered, distressed strip of raw wood as a plaque, blank with no lettering, soft diffused light from upper side, fine wood-grain texture, vertical composition.
- Generate 4 s and trim to 0.7 s (very short shots are unstable when generated on their own)
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm.
The camera is on a vintage blank wooden plaque hanging on a grey wall, slightly low angle, pushing in toward the plaque steadily and extremely slowly.
```
English prompt (as generated by the tool)
```text
Camera slowly and smoothly pushing in on a rustic blank wooden hanging sign on a grey textured wall, subtle low angle, clean still-motion.
```
**G4 · AI-generated video · shot #8 · 0.7 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 21.5–22.2 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- First-frame image prompt: close-up, a wrinkled sheet of xuan paper with black ink-wash bleed marks spread on a dark-grey desk, a black inkstone and a brush on the right. Dark tones, minimalist, Eastern aesthetic. Sharp shadow of a window frame in the upper right, cinematic light and shadow, high contrast, 8k resolution, photoreal texture.
- Generate 4 s and trim to 0.7 s (very short shots are unstable when generated on their own)
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm.
The camera pans slowly to the right, showing the ink-wash paper, inkstone and brush on the desk; the light stays steady, the frame is quiet.
```
English prompt (as generated by the tool)
```text
The camera slowly pans to the right, revealing the ink-stained paper, inkstone, and brush on the desk. The lighting remains stable, creating a tranquil atmosphere.
```
**G5 · 3D rendering · shots #9, #13, #14 · 2.0 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 22.2–22.9 s, 24.9–26.2 s segments (cut out the inserted shots and join into one clip) as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- First-frame image prompt: black-and-white photography, close-up of ripples on a water surface, slightly curved horizon, overcast sky, minimalist, high contrast.
- These shots are separated by inserts in the final cut: generate them as one continuous clip, then put the inserts back in the edit
- Alternative route: a 3D project. Have an LLM write a Blender script or a Three.js scene; model the characters / props once, set a camera per shot and render. Best for multiple angles and character consistency, and changing copy or shots is just changing code (R08)
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm. Hard cuts between shots.
Shot 1 (0.0–0.7 s): black-and-white, ripples spread on the water surface and roll slowly forward, sky still, fixed camera.
Shot 2 (0.7–1.4 s): fixed long shot, an empty, dim studio of cold grey mist, a tiny human figure crawls along the floor extremely slowly, a single light source throws a very long shadow, the frame feels frozen and still
Shot 3 (1.4–2.0 s): fixed close-up, waves on a surface of black viscous liquid keep flowing and heaving, reflecting a faint silver-grey sheen, the arc at the top stays steady, no people, mysterious and calm mood
```
English prompt (as generated by the tool)
```text
Shot 1 (0.0-0.7s): Black and white, water ripples slowly moving forward, static sky, fixed camera.
Shot 2 (0.7-1.4s): Locked-off wide shot, minimalist misty dark grey studio, a tiny human figure slowly crawls on the floor, single hard spotlight casting an elongated sharp shadow.
Shot 3 (1.4-2.0s): Static close-up shot of dark liquid water ripples flowing continuously, reflecting subtle silvery light, smooth curved rim at the top, minimalist black and white 3D render.
```
**G6 · AI-generated video · shots #19, #21 · 3.0 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 28.3–28.6 s, 29.0–31.6 s segments (cut out the inserted shots and join into one clip) as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- First-frame image prompt: minimalist product photography, close-up. A string of rounded dark-brown wooden prayer beads laid in an S-curve on a smooth light-grey background. In the foreground focus, one bead with shiny golden cracks and one pale-green jade bead. Shallow depth of field, blurred background. Soft top light from the left, a zen, tranquil mood, high quality, photoreal style.
- These shots are separated by inserts in the final cut: generate them as one continuous clip, then put the inserts back in the edit
- Alternative route: a 3D project. Have an LLM write a Blender script or a Three.js scene; model the characters / props once, set a camera per shot and render. Best for multiple angles and character consistency, and changing copy or shots is just changing code (R08)
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm. Hard cuts between shots.
Shot 1 (0.0–0.3 s): the camera pushes forward slowly, a close-up of a string of dark wooden prayer beads on a smooth grey background, a bead with golden cracks and a pale-green bead in the foreground, the scene stays still, only the smooth camera push.
Shot 2 (0.3–3.0 s): fixed or slowly pushing camera, an ancient scholar with his back to the camera walks slowly forward through a gate, the wooden doors on both sides fixed, lantern light in the distant street flickering faintly, reflections on the water, the whole movement calm and slow
```
English prompt (as generated by the tool)
```text
Shot 1 (0.0-0.3s): Slow push-in shot on a string of dark wooden prayer beads resting on a smooth grey surface in an S-shape. In the foreground, there is a bead with a golden crack and a pale green bead in focus. The scene itself is completely static, with only the camera moving slowly forward.
Shot 2 (0.3-3.0s): Cinematic slow push-in shot, back view of an ancient Chinese scholar in robes slowly walking forward through an open wooden gate into a wet stone alley lined with glowing lanterns at night, subtle motion, moody atmosphere.
```
**G7 · AI-generated video · shots #22, #23 · 3.0 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 31.6–34.6 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- First-frame image prompt: photoreal, an aged Qing-dynasty official in a black embroidered crane rank badge robe with a court necklace, long white goatee, wearing professional black over-ear monitor headphones, a pop filter and microphone in front of him, dark-grey minimalist studio background, cinematic cool-toned side light, high-contrast dramatic light and shadow, vertical composition.
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm. Hard cuts between shots.
Shot 1 (0.0–0.5 s): the camera pushes steadily and quickly from a medium close-up into a facial close-up of the elder; he wears large headphones, eyes firm and serious, opens his mouth and raps hard into the microphone, beard moving naturally, expression stern.
Shot 2 (0.5–3.0 s): the camera pushes forward slowly, the scholar looks down writing intently, slight brush movements of the hand, small head movements.
```
English prompt (as generated by the tool)
```text
Shot 1 (0.0-0.5s): Smooth cinematic fast push-in to a tight close-up of an elderly Qing dynasty official wearing studio headphones, rapping into a podcast microphone with intense expressions, beard moving subtly, cold cinematic studio lighting.
Shot 2 (0.5-3.0s): Camera slowly pushes in. The young scholar looks down, focused on writing, with slight brush movements and subtle head motion.
```
**G8 · AI-generated video · shots #24, #25, #26, #27 · 8.2 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 34.6–42.9 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- First-frame image prompt: facial close-up of an ancient Chinese elder, grey-white beard, deep wrinkles and age spots across the face, wearing black modern over-ear headphones, low-key hard light, cinematic texture, ultra-realistic detail, 8k resolution
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm. Hard cuts between shots.
Shot 1 (0.0–2.0 s): fixed facial close-up of the elder, speaking to the camera sternly and coldly, lips opening and closing in sync, slight facial movement, firm gaze, camera stays still
Shot 2 (2.0–4.9 s): fixed close-up. In the night a kerosene lamp flame flickers faintly, dim yellow light on a results list. A finger points steadily at the three characters '林子安' inside a red circle, the paper of the list trembling very slightly in a breeze, keeping a dark, oppressive, suspenseful mood overall.
Shot 3 (4.9–5.6 s): fixed camera, a long-bearded Asian elder in black headphones holds one earcup, mouth open, singing / chanting with absorption, facial muscles and beard swaying slightly and naturally with the song, dark studio side light.
Shot 4 (5.6–8.2 s): a gaunt finger slowly traces the large characters on a memorial, the other hand enters from below and presses the paper, the camera pushes in slowly
```
English prompt (as generated by the tool)
```text
Shot 1 (0.0-2.0s): Extreme close-up of an elderly Asian man speaking seriously, lips synced to audio, intense gaze, highly detailed weathered skin, static shot.
Shot 2 (2.0-4.9s): Close-up static shot. In the dark night, the flame of a kerosene lantern flickers softly, casting warm light on an old paper roster on a wooden wall. A hand with prominent veins points its index finger steadily at the Chinese name '林子安' circled in red ink. Cinematic, low-key lighting, suspenseful atmosphere.
Shot 3 (4.9-5.6s): Fixed close-up shot, an elderly Asian man with long gray beard wearing studio headphones, holding the earcup with his hand, singing with deep emotion, subtle facial muscle and beard movement, low-key dramatic studio lighting.
Shot 4 (5.6-8.2s): Close-up of an old frail finger tracing large ink characters on a yellowed memorial scroll, another hand enters from below, slow push-in, dark cinematic tone
```
**G9 · AI-generated video · shot #29 · 1.2 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 43.6–44.8 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- First-frame image prompt: close shot of a yellowed memorial, the large characters 「文理太浅」 ("the writing is too shallow") centered, a finger pressing the paper's edge from above, dark tones
- Generate 4 s and trim to 1.2 s (very short shots are unstable when generated on their own)
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm.
A finger presses the memorial, the camera pushes in slightly on the large characters 「文理太浅」
```
English prompt (as generated by the tool)
```text
Close shot of the scroll with the large characters, a finger pressing the edge, gentle push-in
```
**G10 · AI-generated video · shots #30, #31, #32 · 2.8 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 44.8–47.6 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- First-frame image prompt: close-up, an elderly Asian man, long white beard, deeply wrinkled face, fine skin texture. Wearing black modern over-ear headphones and black Chinese-style clothing. Plain grey background. Cinematic light, soft side light, ultra-realistic, portrait photography.
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm. Hard cuts between shots.
Shot 1 (0.0–0.6 s): close-up, a long-bearded elder in headphones speaks into the microphone, natural mouth movement, slight head sway. Fixed camera.
Shot 2 (0.6–2.2 s): the camera pushes forward extremely slowly, the protagonist stands still with his back to us looking up at the results wall, the backs of the examinees around him sway with a faint breathing motion, the cold, solemn mood held to the end of the shot.
Shot 3 (2.2–2.8 s): the elder speaks straight into the camera, mouth opening and closing naturally, slight facial expression, head and body still, close-up, fixed camera
```
English prompt (as generated by the tool)
```text
Shot 1 (0.0-0.6s): Close-up, elderly Asian man with long beard wearing headphones speaks into microphone, natural mouth movements, slight head sway. Fixed camera.
Shot 2 (0.6-2.2s): Camera slowly dollies in from behind a Qing dynasty scholar with a braided queue looking up at the imperial examination results board, surrounded by crowds of examinees, somber cold cinematic lighting, subtle atmospheric breathing motion.
Shot 3 (2.2-2.8s): Close-up shot of an elderly Chinese man with a long white beard and deep wrinkles, wearing black over-ear headphones, speaking directly to the camera. Natural lip sync, slight facial expressions, head and body remain still. Solid gray background, side lighting, cinematic texture, fixed camera.
```
**G11 · AI-generated video · shots #36, #37 · 3.8 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 50.4–54.2 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- First-frame image prompt: beneath an ancient city wall under heavy clouds, Qing soldiers in ranks holding spears, a bushy-bearded general in profile in the left foreground, cold grey cinematic grade
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm. Hard cuts between shots.
Shot 1 (0.0–3.1 s): the ranks of soldiers move slowly, dust rises, the general in profile stands still, the camera tracks slowly sideways
Shot 2 (3.1–3.8 s): fixed close-up, a long-bearded Chinese elder in over-ear headphones starts to sing mournfully into the microphone, mouth opening and closing as he sings, facial muscles and beard trembling slightly and naturally, eyes slightly lowered and grave, light and shadow steady.
```
English prompt (as generated by the tool)
```text
Shot 1 (0.0-3.1s): Ancient army ranks beneath a city wall under heavy clouds, a bearded general in profile in the foreground, dust rising, slow lateral move
Shot 2 (3.1-3.8s): Close-up static shot of an elderly East Asian man with a long grey beard wearing over-ear studio headphones, singing with a sorrowful expression into a microphone, natural facial muscle and beard movements, studio low-key moody lighting.
```
**G12 · AI-generated video · shot #38 · 2.0 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 54.2–56.2 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- First-frame image prompt: on a small boat on a river at night, a drenched white-bearded Qing elder braces both hands on the deck boards, a kerosene lamp hanging behind him, cold blue tones
- Generate 4 s and trim to 2.0 s (very short shots are unstable when generated on their own)
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm.
The elder, panting, braces on the deck and lifts his head; the person behind him reaches out to pull him up; river waves churn
```
English prompt (as generated by the tool)
```text
At night on a small boat, a drenched old man with a white beard braces on the deck and looks up, someone behind reaches to pull him, waves churning
```
**G13 · AI-generated video · shot #39 · 0.7 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 56.2–56.9 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- First-frame image prompt: close-up, an Asian old man with a white beard, wearing black over-ear headphones, deeply wrinkled face, agitated expression with his mouth open, plain grey background, soft light from the left, high-contrast photoreal portrait.
- Generate 4 s and trim to 0.7 s (very short shots are unstable when generated on their own)
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm.
The old man speaks or sings with an agitated expression, mouth opening and closing naturally, slight head shake, light and shadow kept steady.
```
English prompt (as generated by the tool)
```text
Old man speaking or singing excitedly, natural mouth movement, slight head shake, stable lighting.
```
**G14 · AI-generated video · shot #40 · 1.5 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 56.9–58.4 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- First-frame image prompt: vertical, epic ancient naval battle, night, warships on fire, thick billowing smoke. In the center a wooden bridge links two ships; silhouettes of several ancient soldiers fight fiercely on it with spears and swords. Blazing fire and fluttering war banners behind. Strong backlight, high contrast, cinematic texture, dark style.
- Generate 4 s and trim to 1.5 s (very short shots are unstable when generated on their own)
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm.
The camera pushes forward slowly with a slight low angle. Soldiers fight on the burning wooden bridge swinging spears and swords, movements fierce. Flames blaze in the background, thick smoke drifts in the wind, sparks fly. The overall mood is tense and chaotic.
```
English prompt (as generated by the tool)
```text
Slow push-in and slight low-angle shot. Soldiers fight fiercely with spears and swords on a burning wooden bridge. Flames burn intensely in the background, thick smoke billows in the wind, and sparks fly. The overall atmosphere is tense and chaotic.
```
**G15 · AI-generated video · shot #41 · 0.5 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 58.4–58.9 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- First-frame image prompt: close-up, an elderly Asian man with a grey-white goatee, a face full of weathered wrinkles, serious expression, wearing black monitor headphones, speaking into a microphone in front of a dark-grey background. Eye level, single-side hard light bringing out the facial texture, cool tones, ultra-sharp photoreal photography, cinematic texture, vertical.
- Generate 4 s and trim to 0.5 s (very short shots are unstable when generated on their own)
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm.
Not applicable, this is an audio-driven avatar
```
English prompt (as generated by the tool)
```text
Not applicable, this is an audio-driven avatar
```
**G16 · AI-generated video · shot #43 · 3.0 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 59.5–62.5 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- First-frame image prompt: close-up, a weather-beaten ancient Chinese elder, long white beard, dark period clothing. Grave expression, head bowed, writing with a brush. Dim military tent in the background with faint firelight. Cinematic light, soft key from the left.
- Generate 4 s and trim to 3.0 s (very short shots are unstable when generated on their own)
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm.
The camera pushes in slowly, the elder's expression grave, writing slowly with the brush in hand, beard swaying slightly, firelight flickering in the background.
```
English prompt (as generated by the tool)
```text
Slow push-in shot. An ancient Chinese elder with a long white beard, wearing dark traditional clothes, is writing with a brush with a solemn expression. His beard sways slightly. Dim military tent background with flickering firelight.
```
**G17 · AI-generated video · shot #44 · 2.1 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 62.5–64.7 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- First-frame image prompt: vertical, full shot, slight low angle. An ancient battlefield camp under a gloomy, oppressive sky of dark clouds. In the foreground the black silhouettes of a group of ancient soldiers digging trenches with shovels and driving stakes with sledgehammers. A wooden watchtower faintly visible behind. Strong backlit silhouette effect, high contrast, dark epic style.
- Generate 4 s and trim to 2.1 s (very short shots are unstable when generated on their own)
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm.
Fixed camera. The silhouetted ancient soldiers begin to move: the soldier on the left swings a shovel to dig, the soldier on the right swings a sledgehammer onto a wooden stake, movements heavy. The dark clouds in the background sky drift slowly. Keep the strong backlit silhouette and the dark, oppressive mood.
```
English prompt (as generated by the tool)
```text
Fixed camera. The silhouettes of ancient soldiers begin to move. The soldier on the left swings a shovel to dig dirt, and the soldier on the right swings a sledgehammer to hit a wooden stake, with heavy movements. The dark clouds in the background sky flow slowly. Maintain a strong backlight silhouette and a dark, oppressive atmosphere.
```
**G18 · AI-generated video · shot #46 · 1.8 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 65.4–67.2 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- First-frame image prompt: an overcast camp, a group of Qing soldiers in backlit silhouette swinging hammers onto wooden stakes, a watchtower and banners in the distance
- Generate 4 s and trim to 1.8 s (very short shots are unstable when generated on their own)
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm.
People bend and swing hammers, driving stakes again and again, mud splashing, fixed camera
```
English prompt (as generated by the tool)
```text
Silhouetted soldiers hammering wooden stakes in a muddy camp under overcast sky, mud splashing, static camera
```
**G19 · AI-generated video · shot #47 · 3.4 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 67.2–70.5 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- First-frame image prompt: close-up portrait, vertical. A deeply wrinkled elderly Qing-dynasty official with a long grey-white goatee, wearing modern black over-ear monitor headphones and a black embroidered Qing official robe, plain grey studio background, soft top light, cinematic texture, cool low-saturation tones.
- Generate 4 s and trim to 3.4 s (very short shots are unstable when generated on their own)
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm.
Fixed close-up. An elderly man with a long grey-white beard, in a Qing official robe and modern headphones, speaks and raps passionately at the camera, head nodding slightly with the cadence, firm gaze, natural lifelike mouth movement, grey minimalist studio background.
```
English prompt (as generated by the tool)
```text
Fixed close-up shot. An elderly Chinese man with a grey goatee wearing Qing dynasty attire and modern over-ear headphones passionately rapping to the camera, head nodding subtly with speech rhythm, dark moody studio lighting.
```
**G20 · AI-generated video · shot #52 · 1.0 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 80.2–81.2 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- First-frame image prompt: close-up of a white-haired Asian elder with a long white beard, wearing black over-ear headphones, a black microphone in front of him. Plain dark-grey background. Ultra-realistic, cinematic light, high contrast, rich detail in facial wrinkles and pores, key light from the left.
- Generate 4 s and trim to 1.0 s (very short shots are unstable when generated on their own)
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm.
The elder speaks into the microphone, natural mouth shapes, slight natural head sway, focused gaze, facial features kept stable.
```
English prompt (as generated by the tool)
```text
Close-up of an elderly Asian man with a long white beard, wearing black headphones, speaking into a black microphone. Natural lip sync, slight head movements, focused expression. Dark grey background, cinematic lighting, highly detailed.
```
**G21 · 3D rendering · shot #54 · 1.7 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 85.5–87.1 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- First-frame image prompt: close-up, a dilapidated wooden boat moored on dark, fog-covered water, two wooden oars and a coil of rough rope inside. Minimalist, dark mood, cinematic light, cool tones, 8k resolution.
- Generate 4 s and trim to 1.7 s (very short shots are unstable when generated on their own)
- Alternative route: a 3D project. Have an LLM write a Blender script or a Three.js scene; model the characters / props once, set a camera per shot and render. Best for multiple angles and character consistency, and changing copy or shots is just changing code (R08)
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm.
The camera pushes forward slowly, the scene stays still, showing the details of the dilapidated wooden boat, oars and rope, with dark fog-covered water behind; the mood is gloomy and quiet.
```
English prompt (as generated by the tool)
```text
The camera slowly pushes forward, the scene remains static, showing the details of a dilapidated wooden boat, wooden oars, and ropes. The background is a dark water surface covered in thick fog, with a gloomy and quiet atmosphere.
```
**G22 · AI-generated video · shot #55 · 1.2 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 87.1–88.3 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- First-frame image prompt: black-and-white dark style, rippled water surface, gloomy sky, faint light through the clouds, curved horizon, minimalist cinematic feel.
- Generate 4 s and trim to 1.2 s (very short shots are unstable when generated on their own)
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm.
Black-and-white dark water, ripples rocking slowly, gloomy sky, light and shadow flowing with the waves, slow camera push.
```
English prompt (as generated by the tool)
```text
B&W dark water, slow ripples, gloomy sky, flowing light, slow push in.
```
**G23 · AI-generated video · shots #56, #57, #58 · 5.0 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 88.3–93.3 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- First-frame image prompt: a late-Qing elder, wrinkled face, pale long beard, wearing a black Qing official robe with a subtle pattern, a gaunt aged right hand covering his right eye, expression pained and weary, faint side light, cinematic texture, ultra-realistic detail, cool tones, vertical
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm. Hard cuts between shots.
Shot 1 (0.0–2.4 s): the elder keeps his right hand over his right eye, fingers trembling slightly, chest rising and falling faintly as he breathes, the camera pushes in slowly to a close-up of his face, the whole setting dim and oppressive.
Shot 2 (2.4–3.1 s): frontal close-up, the old man in headphones speaks seriously to the camera, lips opening and closing with the speech, micro-expressions shifting, slight natural head movement, body and background still, the camera pushes in slowly.
Shot 3 (3.1–5.0 s): the camera pushes in slowly on the elder's face; he keeps his hand pressed to his forehead, brow slightly furrowed, faint breathing, the whole body still with only tiny movement, dark cinematic mood.
```
English prompt (as generated by the tool)
```text
Shot 1 (0.0-2.4s): Close-up of an elderly Qing dynasty man covering his right eye with his wrinkled hand, subtle breathing motion and slight finger twitch, slow camera push-in towards the tired face, cinematic low-key lighting.
Shot 2 (2.4-3.1s): Close-up of an elderly Asian man with a long grey beard wearing modern studio headphones, speaking seriously to camera, lip-sync talking motion, subtle head movement, camera slowly zooming in, cinematic muted lighting.
Shot 3 (3.1-5.0s): Slow push-in shot onto the face of an elderly Chinese man with long white beard holding his forehead in dizziness, subtle breathing, dark cinematic lighting.
```
**G24 · AI-generated video · shot #59 · 0.7 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 93.3–94.0 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- First-frame image prompt: frontal close-up of a weather-beaten elderly East Asian man, deep wrinkles across the face, grey-white moustache and goatee, stern cold gaze, wearing a black headband / headphones, plain dark-grey background, high-contrast cinematic studio portrait lighting, extremely high detail.
- Generate 4 s and trim to 0.7 s (very short shots are unstable when generated on their own)
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm.
The frame pushes forward slowly and steadily by a small amount; the elder holds a stern, cold stare, his face drifting with extremely faint breathing, eyes firm and unmoving.
```
English prompt (as generated by the tool)
```text
Slow smooth push-in shot on the elderly Asian man, stoic and intense gaze fixed on the camera, extremely subtle breathing micro-movements, cinematic dramatic portrait lighting.
```
**G25 · AI-generated video · shot #60 · 5.2 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 94.0–99.2 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- First-frame image prompt: film still, a white-haired, white-bearded elderly Qing official seated upright at a dark negotiation table, in an official hat and crane rank badge robe, weathered face and grave expression, the out-of-focus backs of Westerners in the foreground, cool side backlight, dark teal-grey tones, high-contrast cinematic texture.
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm.
The elderly Qing official sits at the negotiation table staring heavily, both hands resting lightly on the table, a Westerner in the foreground holding a folded document, the camera pushes in slowly, the cold, solemn mood of a historical drama.
```
English prompt (as generated by the tool)
```text
Cinematic shot of an elderly Qing dynasty Chinese official in official robe sitting somberly at a negotiation table, Western diplomats blurred in the foreground, slow subtle push-in, dark cold moody lighting.
```
**G26 · AI-generated video · shots #61, #62, #63, #64 · 8.7 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 99.2–107.9 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- Shots #61, #62, #63, #64 have no prompt
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm. Hard cuts between shots.
Shot 1 (0.0–1.1 s): (no prompt: enable --vlm or have the agent write one from the frames)
Shot 2 (1.1–3.9 s): (no prompt: enable --vlm or have the agent write one from the frames)
Shot 3 (3.9–6.9 s): (no prompt: enable --vlm or have the agent write one from the frames)
Shot 4 (6.9–8.7 s): (no prompt: enable --vlm or have the agent write one from the frames)
```
**G27 · AI-generated video · shots #65, #70 · 8.4 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 107.9–115.7 s, 124.2–124.8 s segments (cut out the inserted shots and join into one clip) as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- These shots are separated by inserts in the final cut: generate them as one continuous clip, then put the inserts back in the edit
- Shots #65, #70 have no prompt
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm. Hard cuts between shots.
Shot 1 (0.0–7.8 s): (no prompt: enable --vlm or have the agent write one from the frames)
Shot 2 (7.8–8.4 s): (no prompt: enable --vlm or have the agent write one from the frames)
```
**G28 · 3D rendering · shot #71 · 0.6 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 124.8–125.5 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- Generate 4 s and trim to 0.6 s (very short shots are unstable when generated on their own)
- Alternative route: a 3D project. Have an LLM write a Blender script or a Three.js scene; model the characters / props once, set a camera per shot and render. Best for multiple angles and character consistency, and changing copy or shots is just changing code (R08)
- Shot #71 has no prompt
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm.
(no prompt: enable --vlm or have the agent write one from the frames)
```
**G29 · AI-generated video · shot #72 · 1.6 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 125.5–127.1 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- Generate 4 s and trim to 1.6 s (very short shots are unstable when generated on their own)
- Shot #72 has no prompt
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm.
(no prompt: enable --vlm or have the agent write one from the frames)
```
**G30 · 3D rendering · shot #73 · 2.1 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 127.1–129.2 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- Generate 4 s and trim to 2.1 s (very short shots are unstable when generated on their own)
- Alternative route: a 3D project. Have an LLM write a Blender script or a Three.js scene; model the characters / props once, set a camera per shot and render. Best for multiple angles and character consistency, and changing copy or shots is just changing code (R08)
- Shot #73 has no prompt
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm.
(no prompt: enable --vlm or have the agent write one from the frames)
```
**G31 · AI-generated video · shots #75, #76, #77 · 8.8 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 130.1–138.9 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- Shots #75, #76, #77 have no prompt
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm. Hard cuts between shots.
Shot 1 (0.0–3.9 s): (no prompt: enable --vlm or have the agent write one from the frames)
Shot 2 (3.9–7.1 s): (no prompt: enable --vlm or have the agent write one from the frames)
Shot 3 (7.1–8.8 s): (no prompt: enable --vlm or have the agent write one from the frames)
```
**G32 · AI-generated video · shots #78, #79, #81, #82 · 9.3 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 138.9–143.0 s, 144.0–149.2 s segments (cut out the inserted shots and join into one clip) as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- These shots are separated by inserts in the final cut: generate them as one continuous clip, then put the inserts back in the edit
- Alternative route: a 3D project. Have an LLM write a Blender script or a Three.js scene; model the characters / props once, set a camera per shot and render. Best for multiple angles and character consistency, and changing copy or shots is just changing code (R08)
- Shots #78, #79, #81, #82 have no prompt
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm. Hard cuts between shots.
Shot 1 (0.0–3.5 s): (no prompt: enable --vlm or have the agent write one from the frames)
Shot 2 (3.5–4.2 s): (no prompt: enable --vlm or have the agent write one from the frames)
Shot 3 (4.2–8.2 s): (no prompt: enable --vlm or have the agent write one from the frames)
Shot 4 (8.2–9.3 s): (no prompt: enable --vlm or have the agent write one from the frames)
```
**G33 · 3D rendering · shot #85 · 2.2 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 158.1–160.4 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- Generate 4 s and trim to 2.2 s (very short shots are unstable when generated on their own)
- Alternative route: a 3D project. Have an LLM write a Blender script or a Three.js scene; model the characters / props once, set a camera per shot and render. Best for multiple angles and character consistency, and changing copy or shots is just changing code (R08)
- Shot #85 has no prompt
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm.
(no prompt: enable --vlm or have the agent write one from the frames)
```
**G34 · 3D rendering · shot #86 · 4.6 s**
- Reference material: `@image1` product photos (front + logo side), supplied by the user; `@image2` character reference (one frontal + one half-body per character) to keep faces consistent across shots; `@video1` the original 160.4–165.0 s segment as a reference for motion, camera and cut rhythm (reference only, do not copy the picture)
- Alternative route: a 3D project. Have an LLM write a Blender script or a Three.js scene; model the characters / props once, set a camera per shot and render. Best for multiple angles and character consistency, and changing copy or shots is just changing code (R08)
- Shot #86 has no prompt
```text
Vertical 9:16; night / low-light ambient, no dedicated fill, soft light (wide shadow transition), neutral (about 5000K), background clearly blurred (shallow depth of field / portrait mode). Product look per @image1, keep the logo and details consistent. Character per @image2. Follow @video1 for motion, camera and cut rhythm.
(no prompt: enable --vlm or have the agent write one from the frames)
```
### Local rebuild
- #3 still-image push / pan 2.3 s; #6 still-image push / pan 0.7 s; #10 still-image push / pan 0.7 s; #11 still-image push / pan 0.7 s; #12 still-image push / pan 0.7 s; #15 still-image push / pan 0.7 s; #16 still-image push / pan 0.7 s; #17 still-image push / pan 0.3 s; #18 still-image push / pan 0.3 s; #20 still-image push / pan 0.4 s; #33 still-image push / pan 0.6 s; #66 still-image push / pan 3.5 s; #67 still-image push / pan 2.4 s; #68 still-image push / pan 0.7 s; #69 still-image push / pan 1.9 s; #74 still-image push / pan 0.9 s; #80 still-image push / pan 1.0 s; #83 still-image push / pan 2.8 s; #84 still-image push / pan 6.1 s: one image + the measured zoom / pan parameters, rendered directly with ffmpeg
## Framing, lighting and editing
- Framing: close-up 55%, extreme close-up 45%; eye-level angle; subject is a face (framing measured by face height)
- Camera: fixed (tripod / stand / on a table) 57%, moving (gimbal / handheld pan) 43%; common move: pull-out
- Lighting: night / low-light ambient, no dedicated fill. Key light from front right, from above (ceiling light / street light / high source); contrast ratio about 1.5:1 (0.6 stops); soft light (wide shadow transition); neutral color temperature (about 5000K); background clearly blurred (shallow depth of field / portrait mode)
- Grade: dark, low saturation (cinematic); low saturation, normal contrast, normal blacks, cool overall
- Editing: 30.9 cuts per minute, 2.27 s average live-action shot; 5 setups / scenes; 0 same-setup jump cuts, 0 punch-in cuts; inserts (screenshots / screen recordings / cards / stock) 84%; 50% of cuts land on speech pauses
**Remake shooting plan**
1. Framing: mostly close-ups, eye level
2. Camera: fixed (tripod / stand / on a table) 57%, moving (gimbal / handheld pan) 43%; common move: pull-out
3. Lighting: night / low-light ambient, no dedicated fill: the key comes from the environment (street lights, signs, indoor ceiling lights, screens); the subject reads dark and the contrast is set by the environment
4. Editing: 30.9 cuts per minute, 2.27 s average live-action shot; 5 setups / scenes; 0 same-setup jump cuts, 0 punch-in cuts; inserts (screenshots / screen recordings / cards / stock) 84%; 50% of cuts land on speech pauses
Gear:
- Phone night / portrait mode; use a street light or a sign as the key, with the subject standing diagonally below it
- For a cleaner look: add a small low-output warm LED (3200K) next to the lens
- Note: background clearly blurred (shallow depth of field / portrait mode)
| Dimension | Item | Conclusion | Source |
|---|---|---|---|
| Framing | Shot size | Close-up | Measured: close-up; VLM: medium shot (half body) |
| Framing | Angle | Eye level | VLM: eye level |
| Framing | Composition | Subject centered, vertical | VLM: subject centered, vertical |
| Camera | Support | Tripod / stand, fixed | Measured: mixed, fixed (tripod / stand / on a table) 57% / moving (gimbal / handheld pan) 43%; VLM: tripod / stand, fixed |
| Camera | Lens | Camera portrait / telephoto | VLM: camera portrait / telephoto |
| Lighting | Scene | Indoor; studio | VLM: indoor; studio |
| Lighting | Key | Upper left of frame, softbox | VLM: upper left of frame, softbox |
| Lighting | Softness | Soft light (wide shadow transition) | Measured: soft light (wide shadow transition); VLM: soft |
| Lighting | Fill | Shadow fill present, soft shadow transitions | VLM: shadow fill present, soft shadow transitions |
| Lighting | Rim | No obvious rim light | VLM: no obvious rim light |
| Lighting | Catchlight | Faint point | VLM: faint point |
| Lighting | Visible sources | None | VLM: none |
| Lighting | Color temperature | Neutral (about 5000K) | Measured: neutral (about 5000K); VLM: neutral, slightly cool |
| Lighting | Setup | Soft key from the left + faint rim from the right | VLM: soft key from the left + faint rim from the right |
| Grade | Style | Dark, low saturation (cinematic) | Measured: dark, low saturation (cinematic) |
- Note: contrast ratio, softness, color temperature and shot size are measured on the subject's pixels (the face when there is one, otherwise the sharpest region, which is an estimate); platform transcoding crushes shadows, so softness and fill read conservative; angle, light source type, catchlight and rim come from visual review. Where measurement and visual review disagree, both are listed.
## Metadata clues
- Encoder: `Lavf61.7.100`
## Audio breakdown

- Overall loudness −17.4 dBFS, peak −1.9 dBFS
- **Voice**: present, 26% of duration, fundamental about 142.8 Hz (reads male)
- **Background music**: 97% of duration (0.0–164.5 s), about 178.2 BPM (or 89.1 / 356.4), key A minor (confidence 0.658), section changes at 4.0 s, 19.0 s, 63.5 s, 68.0 s, 107.5 s, 111.5 s, 123.0 s, 133.5 s
- **Cuts vs beat**: 38% of cuts land on a beat (random baseline about 40%)
**Audio source: AI-generated or existing material**
- **Conclusion**: video type: music video / song (the whole piece is a sung song) → voice: TTS voice-over; music: AI-generated music (leaning, to be confirmed); sound effects: added in post from a library / editor (leaning, to be confirmed)
- **Separated stems**: `stems/original.wav` (original), `stems/vocals.wav` (dry voice; transient effects land here too), `stems/music.wav` (music + ambience)
- Video form: likely a sung song / music video; AI picture 69%, live footage 0%
- **Background music**: AI-generated music (ai_generated 52%, popular_song 26%, existing_library 22%)
- The music runs uninterrupted through the whole piece and the voice is sung (sustained-pitch ratio 0.24): looks like a song with vocals / a music video, high probability of an AI song (VLM not enabled; MV prior applied with reduced weight)
- Music and video end together: cut to length or custom-made (either source possible, weak evidence)
- How to confirm: on the Douyin / Xiaohongshu page check the music tag: a song title → existing track; "original sound by @author" → uploaded by the author (for music videos this is usually an AI song)
- How to confirm: run Soda Music / QQ Music song recognition or ACRCloud: a hit means an existing song
- How to confirm: listen: AI songs often have slurred diction, thin metallic highs and lyrics that track the picture closely; library beds are mostly instrumental, standard structure, cut off or faded at the end
- **Voice**: TTS voice-over (tts 64%, human_recording 27%, ai_video_native 9%)
- Voice and background sound are continuous across cuts: the whole narration was dubbed on separately in post (TTS or a human voice-over)
- **Sound effects**: added in post from a library / editor (library_editor 57%, ai_native 29%, live_sync 14%)
- Cartoon effects in 3D / animated videos are also often synthesized procedurally or added from a library (e.g. the capsule-cinema plush recipe synthesizes them procedurally)
- Per-segment native-audio check: background change 6.4 dB at cuts, 6.1 dB within shots (ratio 1.05) → sound is continuous across cuts, laid as one bed in post
**Sound effects** (56; source: vlm = heard by the model, deterministic = signal-detected candidate, low confidence)
| Time | Type | Description | Matching picture | Source |
|---|---|---|---|---|
| 10.29 s | ding | | | deterministic |
| 20.79 s | ding | | cut | deterministic |
| 31.67 s | ding | | cut | deterministic |
| 32.00 s | ding | | | deterministic |
| 50.71 s | ding | | | deterministic |
| 51.37 s | whoosh | | | deterministic |
| 51.57 s | whoosh | | | deterministic |
| 52.07 s | whoosh | | | deterministic |
| 59.72 s | whoosh | | | deterministic |
| 59.90 s | whoosh | | | deterministic |
| 60.07 s | ding | | | deterministic |
| 60.23 s | whoosh | | | deterministic |
| 63.63 s | hit | | | deterministic |
| 67.70 s | pop | | | deterministic |
| 84.71 s | whoosh | | | deterministic |
| 86.09 s | whoosh | | | deterministic |
| 86.42 s | whoosh | | | deterministic |
| 86.77 s | whoosh | | | deterministic |
| 88.13 s | pop | | | deterministic |
| 97.65 s | whoosh | | | deterministic |
| 100.02 s | ding | | | deterministic |
| 100.37 s | whoosh | | cut | deterministic |
| 102.72 s | whoosh | | | deterministic |
| 119.41 s | whoosh | | | deterministic |
| 122.12 s | whoosh | | | deterministic |
| 123.50 s | ding | | | deterministic |
| 123.83 s | ding | | | deterministic |
| 125.88 s | ding | | | deterministic |
| 132.68 s | whoosh | | | deterministic |
| 133.02 s | ding | | | deterministic |
| 135.05 s | ding | | | deterministic |
| 135.64 s | pop | | | deterministic |
| 136.41 s | ding | | | deterministic |
| 136.92 s | ding | | | deterministic |
| 137.09 s | ding | | | deterministic |
| 137.43 s | ding | | | deterministic |
| 137.76 s | ding | | | deterministic |
| 142.48 s | whoosh | | | deterministic |
| 151.37 s | whoosh | | | deterministic |
| 152.06 s | pop | | cut | deterministic |
**Audio remake plan**
- voice (A01-narration): voice, male → capsule-cinema DoubaoTTSTool / UniversalTTSTool (or a MiniMax cloned voice); use duration-controlled TTS (A02) when you must fit the original timing
- music (A03-music): 178.2 BPM; A minor → the original leans AI-generated: regenerate with Suno or similar (capsule-cinema UniversalMusicGenerationTool) by style / BPM / key; for a music video, write new lyrics for the new content as well
- sfx (A04-sfx): 56 effects → place by timestamp: capsule-cinema SoundEffectsTool / a sound library, or synthesize procedurally like the plush recipe (pitch aligned to the BGM key)
## Real material in the frame
2 shots, 3.04 s (2%), contain real material (screen recordings, screenshots, photos, embedded video). A remake needs the original files; they cannot be replaced by generated output:
- Shot #3 (00:15.750): real photo, whole frame
- Shot #3 (00:15.750): real photo, partial frame, a still photograph of rough xuan paper with handwritten brush calligraphy on a dark-grey surface
- Shot #12 (00:24.208): real photo, whole frame
- Shot #12 (00:24.208): product photo, partial frame, the whole frame is a product photograph of a prayer-bead bracelet
## Reference material to prepare for the remake
These shots were generated or filmed; the items below appear in the frame and should be prepared as reference images / props for the remake (they are not embedded real pixels):
- Shot #7 (00:20.833): character / scene reference image, a high-resolution still-life photo of a single hanging wooden plaque
- Shot #19 (00:28.292): product reference image, a still-life photo of dark wooden prayer beads
## Shot list
| # | Time | Duration | Underlying picture | Confidence | Material | Overlays | Camera | Remake route |
|---|---|---|---|---|---|---|---|---|
| 1 | 00:00.000 | 7.25 s | 3D rendering | 47% | Rendered by the producer | Text | Smooth move | R08-product-multiview → capsule_cinema |
| 2 | 00:07.250 | 8.50 s | Talking avatar | 99% | AI-generated | Captions | Static | R03-talking-head → capsule_cinema |
| 3 | 00:15.750 | 2.33 s | Still-image push / pan (Ken Burns) | 98% | User's real material: real photo | Captions, text | Whole-image push / pan | R17-still-motion → local_ffmpeg |
| 4 | 00:18.083 | 1.38 s | AI-generated video | 84% | AI-generated | Text | Smooth move | R07-product-hero → capsule_cinema |
| 5 | 00:19.458 | 0.67 s | Talking avatar | 99% | AI-generated | Captions, graphic sticker | Smooth move | R03-talking-head → capsule_cinema |
| 6 | 00:20.125 | 0.71 s | Still-image push / pan (Ken Burns) | 86% | AI-generated | — | Whole-image push / pan | R17-still-motion → local_ffmpeg |
| 7 | 00:20.833 | 0.67 s | AI-generated video | 45% | AI-generated; remake reference: character / scene reference image | — | Smooth move | R07-product-hero → capsule_cinema |
| 8 | 00:21.500 | 0.67 s | AI-generated video | 98% | AI-generated | — | Smooth move | R07-product-hero → capsule_cinema |
| 9 | 00:22.167 | 0.71 s | AI-generated video | 64% | AI-generated | Graphic sticker | Smooth move | R07-product-hero → capsule_cinema |
| 10 | 00:22.875 | 0.67 s | Still-image push / pan (Ken Burns) | 88% | Rendered by the producer | Graphic sticker | Whole-image push / pan | R17-still-motion → local_ffmpeg |
| 11 | 00:23.542 | 0.67 s | Still-image push / pan (Ken Burns) | 93% | AI-generated | — | Whole-image push / pan | R17-still-motion → local_ffmpeg |
| 12 | 00:24.208 | 0.71 s | Still-image push / pan (Ken Burns) | 99% | User's real material: real photo, product photo | — | Whole-image push / pan | R17-still-motion → local_ffmpeg |
| 13 | 00:24.917 | 0.67 s | 3D rendering | 67% | Rendered by the producer | — | Smooth move | R08-product-multiview → capsule_cinema |
| 14 | 00:25.583 | 0.67 s | 3D rendering | 69% | Rendered by the producer | Graphic sticker | Smooth move | R08-product-multiview → capsule_cinema |
| 15 | 00:26.250 | 0.67 s | Still-image push / pan (Ken Burns) | 99% | AI-generated | — | Whole-image push / pan | R17-still-motion → local_ffmpeg |
| 16 | 00:26.917 | 0.71 s | Still-image push / pan (Ken Burns) | 91% | AI-generated | — | Whole-image push / pan | R17-still-motion → local_ffmpeg |
| 17 | 00:27.625 | 0.33 s | Still-image push / pan (Ken Burns) | 99% | AI-generated | — | Whole-image push / pan | R17-still-motion → local_ffmpeg |
| 18 | 00:27.958 | 0.33 s | Still-image push / pan (Ken Burns) | 85% | AI-generated | — | Whole-image push / pan | R17-still-motion → local_ffmpeg |
| 19 | 00:28.292 | 0.33 s | 3D rendering | 35% | Rendered by the producer; remake reference: product reference image | — | Smooth move | R08-product-multiview → capsule_cinema |
| 20 | 00:28.625 | 0.38 s | Still-image push / pan (Ken Burns) | 99% | AI-generated | — | Whole-image push / pan | R17-still-motion → local_ffmpeg |
| 21 | 00:29.000 | 2.62 s | AI-generated video | 85% | AI-generated | Captions | Smooth move | R07-product-hero → capsule_cinema |
| 22 | 00:31.625 | 0.54 s | AI-generated video | 82% | AI-generated | Text | Smooth move | R07-product-hero → capsule_cinema |
| 23 | 00:32.167 | 2.46 s | AI-generated video | 80% | AI-generated | Text | Smooth move | R07-product-hero → capsule_cinema |
| 24 | 00:34.625 | 2.04 s | AI-generated video | 49% | AI-generated | Text | Smooth move | R07-product-hero → capsule_cinema |
| 25 | 00:36.667 | 2.88 s | AI-generated video | 80% | AI-generated | Text | Smooth move | R07-product-hero → capsule_cinema |
| 26 | 00:39.542 | 0.71 s | AI-generated video | 63% | AI-generated | — | Smooth move | R07-product-hero → capsule_cinema |
| 27 | 00:40.250 | 2.62 s | AI-generated video | 50% | AI-generated | Captions | Smooth move | R07-product-hero → capsule_cinema |
| 28 | 00:42.875 | 0.71 s | Talking avatar | 89% | AI-generated | Text | Smooth move | R03-talking-head → capsule_cinema |
| 29 | 00:43.583 | 1.21 s | AI-generated video | 43% | AI-generated | Text | Smooth move | R07-product-hero → capsule_cinema |
| 30 | 00:44.792 | 0.62 s | AI-generated video | 99% | AI-generated | — | Smooth move | R07-product-hero → capsule_cinema |
| 31 | 00:45.417 | 1.54 s | AI-generated video | 76% | AI-generated | Text | Smooth move | R07-product-hero → capsule_cinema |
| 32 | 00:46.958 | 0.62 s | AI-generated video | 49% | AI-generated | Text | Smooth move | R07-product-hero → capsule_cinema |
| 33 | 00:47.583 | 0.62 s | Still-image push / pan (Ken Burns) | 99% | AI-generated | Text | Smooth move | R17-still-motion → local_ffmpeg |
| 34 | 00:48.208 | 0.58 s | Talking avatar | 90% | AI-generated | Text | Smooth move | R03-talking-head → capsule_cinema |
| 35 | 00:48.792 | 1.58 s | Talking avatar | 99% | AI-generated | Text | Static (subject moving) | R03-talking-head → capsule_cinema |
| 36 | 00:50.375 | 3.08 s | AI-generated video | 46% | AI-generated | Captions | Smooth move | R07-product-hero → capsule_cinema |
| 37 | 00:53.458 | 0.75 s | AI-generated video | 63% | AI-generated | Text, graphic sticker | Smooth move | R07-product-hero → capsule_cinema |
| 38 | 00:54.208 | 2.00 s | AI-generated video | 60% | AI-generated | Captions | Smooth move | R07-product-hero → capsule_cinema |
| 39 | 00:56.208 | 0.71 s | AI-generated video | 98% | AI-generated | — | Smooth move | R07-product-hero → capsule_cinema |
| 40 | 00:56.917 | 1.50 s | AI-generated video | 74% | AI-generated | Captions | Smooth move | R07-product-hero → capsule_cinema |
| 41 | 00:58.417 | 0.50 s | AI-generated video | 41% | AI-generated | Text | Smooth move | R07-product-hero → capsule_cinema |
| 42 | 00:58.917 | 0.58 s | Talking avatar | 98% | AI-generated | Text, graphic sticker | Smooth move | R03-talking-head → capsule_cinema |
| 43 | 00:59.500 | 3.04 s | AI-generated video | 84% | AI-generated | Captions | Smooth move | R07-product-hero → capsule_cinema |
| 44 | 01:02.542 | 2.12 s | AI-generated video | 81% | AI-generated | Captions | Smooth move | R07-product-hero → capsule_cinema |
| 45 | 01:04.667 | 0.71 s | Talking avatar | 98% | AI-generated | Graphic sticker | Smooth move | R03-talking-head → capsule_cinema |
| 46 | 01:05.375 | 1.79 s | AI-generated video | 46% | AI-generated | Text | Smooth move | R07-product-hero → capsule_cinema |
| 47 | 01:07.167 | 3.38 s | AI-generated video | 73% | AI-generated | Captions | Smooth move | R07-product-hero → capsule_cinema |
| 48 | 01:10.542 | 1.25 s | Talking avatar | 94% | AI-generated | Text, graphic sticker | Smooth move | R03-talking-head → capsule_cinema |
| 49 | 01:11.792 | 2.79 s | Talking avatar | 99% | AI-generated | Captions, graphic sticker | Static (subject moving) | R03-talking-head → capsule_cinema |
| 50 | 01:14.583 | 2.71 s | Talking avatar | 99% | AI-generated | Captions | Static (subject moving) | R03-talking-head → capsule_cinema |
| 51 | 01:17.292 | 2.92 s | Talking avatar | 90% | AI-generated | Captions, graphic sticker | Smooth move | R03-talking-head → capsule_cinema |
| 52 | 01:20.208 | 1.00 s | AI-generated video | 52% | AI-generated | — | Smooth move | R07-product-hero → capsule_cinema |
| 53 | 01:21.208 | 4.25 s | Talking avatar | 96% | AI-generated | Captions | Smooth move | R03-talking-head → capsule_cinema |
| 54 | 01:25.458 | 1.67 s | 3D rendering | 58% | Rendered by the producer | — | Smooth move | R08-product-multiview → capsule_cinema |
| 55 | 01:27.125 | 1.21 s | AI-generated video | 81% | AI-generated | Graphic sticker | Smooth move | R07-product-hero → capsule_cinema |
| 56 | 01:28.333 | 2.42 s | AI-generated video | 77% | AI-generated | Text | Smooth move | R07-product-hero → capsule_cinema |
| 57 | 01:30.750 | 0.67 s | AI-generated video | 53% | AI-generated | — | Smooth move | R07-product-hero → capsule_cinema |
| 58 | 01:31.417 | 1.92 s | AI-generated video | 90% | AI-generated | Text | Smooth move | R07-product-hero → capsule_cinema |
| 59 | 01:33.333 | 0.67 s | AI-generated video | 84% | AI-generated | — | Smooth move | R07-product-hero → capsule_cinema |
| 60 | 01:34.000 | 5.21 s | AI-generated video | 53% | AI-generated | Captions | Smooth move | R07-product-hero → capsule_cinema |
| 61 | 01:39.208 | 1.12 s | AI-generated video | 57% | AI-generated | Text | Smooth move | R07-product-hero → capsule_cinema |
| 62 | 01:40.333 | 2.79 s | AI-generated video | 38% | AI-generated | Text, graphic sticker | Handheld shake | R07-product-hero → capsule_cinema |
| 63 | 01:43.125 | 3.00 s | AI-generated video | 64% | AI-generated | Captions | Smooth move | R07-product-hero → capsule_cinema |
| 64 | 01:46.125 | 1.79 s | AI-generated video | 79% | AI-generated | Text | Smooth move | R07-product-hero → capsule_cinema |
| 65 | 01:47.917 | 7.79 s | AI-generated video | 60% | AI-generated | Text | Smooth move | R07-product-hero → capsule_cinema |
| 66 | 01:55.708 | 3.50 s | Still-image push / pan (Ken Burns) | 85% | To be confirmed; verify whether real: photo / image material | — | Whole-image push / pan | R17-still-motion → local_ffmpeg |
| 67 | 01:59.208 | 2.38 s | Still-image push / pan (Ken Burns) | 76% | Rendered by the producer | — | Whole-image push / pan | R17-still-motion → local_ffmpeg |
| 68 | 02:01.583 | 0.71 s | Still-image push / pan (Ken Burns) | 83% | Rendered by the producer | — | Whole-image push / pan | R17-still-motion → local_ffmpeg |
| 69 | 02:02.292 | 1.92 s | Still-image push / pan (Ken Burns) | 80% | To be confirmed; verify whether real: photo / image material | Text | Whole-image push / pan | R17-still-motion → local_ffmpeg |
| 70 | 02:04.208 | 0.62 s | AI-generated video | 40% | AI-generated | Text | Smooth move | R07-product-hero → capsule_cinema |
| 71 | 02:04.833 | 0.62 s | 3D rendering | 50% | Rendered by the producer | Text | Smooth move | R08-product-multiview → capsule_cinema |
| 72 | 02:05.458 | 1.62 s | AI-generated video | 83% | AI-generated | — | Smooth move | R07-product-hero → capsule_cinema |
| 73 | 02:07.083 | 2.12 s | 3D rendering | 37% | Rendered by the producer | Text | Smooth move | R08-product-multiview → capsule_cinema |
| 74 | 02:09.208 | 0.92 s | Still-image push / pan (Ken Burns) | 77% | Rendered by the producer | Text, graphic sticker | Whole-image push / pan | R17-still-motion → local_ffmpeg |
| 75 | 02:10.125 | 3.88 s | AI-generated video | 59% | AI-generated | Text | Smooth move | R07-product-hero → capsule_cinema |
| 76 | 02:14.000 | 3.25 s | AI-generated video | 60% | AI-generated | Text | Smooth move | R07-product-hero → capsule_cinema |
| 77 | 02:17.250 | 1.62 s | AI-generated video | 62% | AI-generated | Graphic sticker | Smooth move | R07-product-hero → capsule_cinema |
| 78 | 02:18.875 | 3.46 s | AI-generated video | 50% | AI-generated | Text | Smooth move | R07-product-hero → capsule_cinema |
| 79 | 02:22.333 | 0.71 s | AI-generated video | 41% | AI-generated | Text, graphic sticker | Smooth move | R07-product-hero → capsule_cinema |
| 80 | 02:23.042 | 0.96 s | Still-image push / pan (Ken Burns) | 68% | Rendered by the producer | Graphic sticker | Whole-image push / pan | R17-still-motion → local_ffmpeg |
| 81 | 02:24.000 | 4.04 s | 3D rendering | 60% | Rendered by the producer | Captions | Smooth move | R08-product-multiview → capsule_cinema |
| 82 | 02:28.042 | 1.12 s | AI-generated video | 49% | AI-generated | Captions | Smooth move | R07-product-hero → capsule_cinema |
| 83 | 02:29.167 | 2.83 s | Still-image push / pan (Ken Burns) | 75% | To be confirmed; verify whether real: photo / image material | Text | Whole-image push / pan | R17-still-motion → local_ffmpeg |
| 84 | 02:32.000 | 6.12 s | Still-image push / pan (Ken Burns) | 77% | To be confirmed; verify whether real: photo / image material | — | Whole-image push / pan | R17-still-motion → local_ffmpeg |
| 85 | 02:38.125 | 2.25 s | 3D rendering | 44% | Rendered by the producer | Graphic sticker | Smooth move | R08-product-multiview → capsule_cinema |
| 86 | 02:40.375 | 4.58 s | 3D rendering | 46% | Rendered by the producer | — | Smooth move | R08-product-multiview → capsule_cinema |
## Shot details
### #1 00:00.000–00:07.250 · 3D rendering + code / editor overlays (text labels)

- Probabilities: 3D rendering 47%, code / template rendering 24%, AI-generated video 17% (fused)
- Material: rendered by the producer
- Likely tool: Midjourney + Kling / Hailuo
- Rendered texture: flat color blocks 66%, 95% of pixels use only 5 colors, horizontal / vertical straight edges 19%
- Per-frame sharpness oscillates periodically (period 2 frames, correlation 0.07): the picture went through frame interpolation / rate conversion; the original frame rate was lower
- Duplicate frames follow an interpolated pattern (22%, period 1): source was 24/25 fps then transcoded, typical of AI video, 3D / animation renders or film footage
- [VLM] A long-bearded Qing official wearing modern headphones is a typical AI creative concept
- [VLM] Motion is minimal, only a slight head turn and lips parting a little, consistent with image-to-video
- [VLM] High-contrast minimalist light on skin, beard and hair under side backlight; the background is pure black with no physical environment
- Picture: on a black background, the profile of an elder in a Qing official robe with a long white beard and large modern headphones moves slightly under side backlight and opens his mouth to speak; the camera pushes gently forward to a facial close-up.
- Framing / light: close-up; eye level; tripod / stand, fixed; night / low-light ambient, no dedicated fill; key front left; contrast about 1.4:1 (0.5 stops); soft light (wide shadow transition)
- Text track (text / middle): 大清有说唱
- Text track (text / middle): 和血吞
- Text track (text / middle): 作词Claude作曲Suno演唱曾国fan
- Remake: 3D rendering: first/last-frame AI generation gives an approximation; for precise multi-angle work go 3D modeling + Blender render
- First-frame image prompt: profile close-up of an elderly Qing-dynasty official with a long white beard, wearing black modern over-ear headphones, pure black background, very strong single-side rim light, cinematic texture, 8k photoreal detail
- Video prompt: under side light on a black background, a long-bearded Qing-dynasty elder wearing modern over-ear headphones moves his face slightly, lips parting a little as he murmurs; the camera pushes forward extremely slowly to a facial close-up, keeping the high-contrast silhouette lighting unchanged
### #2 00:07.250–00:15.750 · Talking avatar + code / editor overlays (captions)

- Probabilities: talking avatar 98%, AI-generated video 1%, 3D rendering 0% (fused)
- Material: AI-generated
- Likely tool: Midjourney + LivePortrait / Hedra
- Motion beats within the shot: 8.21 s, 9.96 s, 10.50 s, 14.71 s
- Face covers 9% of the frame and appears in 100% of sampled frames: a close shot of a person, flat blocks mostly from walls / clothing, rendering features down-weighted
- Photo / video texture: noise σ=0.14, 29 colors, flat blocks 36%
- Per-frame sharpness oscillates periodically (period None frames, correlation 0.00): the picture went through frame interpolation / rate conversion; the original frame rate was lower
- Duplicate frames follow an interpolated pattern (0%, period None): source was 24/25 fps then transcoded, typical of AI video, 3D / animation renders or film footage
- 100% of sampled frames have a frontal face with a fixed camera, and the audio track has voice
- [VLM] The body, clothing, headphones and microphone stay completely still and undeformed through the whole clip
- [VLM] Only the mouth opens and closes and the head sways slightly, consistent with a single image driven by audio
- [VLM] At 00:04–00:08, while the mouth moves, the long beard at the chin warps and pulls unnaturally
- Picture: an elder in a Chinese robe embroidered with cranes and a long white beard, wearing modern over-ear headphones, speaks in front of a microphone. Plain grey background, half-body medium close-up, fixed camera, soft studio light.
- Framing / light: close-up; eye level; tripod / stand, fixed; night / low-light ambient, no dedicated fill; key front right; contrast about 2.1:1 (1.0 stop); soft light (wide shadow transition)
- Text track (captions / bottom): 官至极品,一无所成。 / 这话,我自己写的。
- Remake: talking avatar: clone / synthesize the voice-over first, then drive an avatar model from the portrait + audio
- First-frame image prompt: vertical, half-body medium close-up, an ancient Chinese elder with a long white beard, wearing a black Chinese robe with fine crane embroidery on the chest, modern black over-ear headphones on his head, a microphone in front of him. Plain grey background, soft studio light, key from the left, rim from the right, cinematic texture, ultra-high detail, photoreal style.
- Video prompt: keep the frame still, the character's mouth speaks in sync with the audio, slight natural head sway, beard swaying slightly with it.
### #3 00:15.750–00:18.083 · Still-image push / pan (Ken Burns) (real photo) + code / editor overlays (captions, text labels); introduces real material (real photo)

- Probabilities: still-image push / pan 98%, live footage 1%, stop motion 0% (fused)
- Still source: photo
- Material: user's real material: real photo
- Likely tool: CapCut (JianYing)
- The whole frame moves as a single rigid transform (inliers 99%, residual 0.07 px, no local motion) → still-image push / pan: zoom +10.9%/s, pan 55 px/s
- Photo / video texture: noise σ=0.57, 25 colors, flat blocks 1%
- [VLM] No independent object motion or perspective change inside the frame
- [VLM] Only a flat, linear, slow push (Ken Burns zoom)
- [VLM] Paper fiber edges and brush-calligraphy ink are sharp and natural: a still-life photograph of a real object
- Picture: close-up, a sheet of handmade deckle-edged xuan paper lies flat on a dark-grey desk with the brush characters '官至极品 一无所成' ("rose to the highest rank, achieved nothing"); the camera pushes gently forward, enlarging it.
- Text track (captions / bottom): 这话,我自己写的 / 这话,我自己写的。
- Text track (text / middle): 官至极品
- Text track (text / middle): 一无所成
- Remake: still-image push / pan: reproduce exactly with one image + the measured zoom / pan parameters in local ffmpeg; the user must supply the real material: real photo (whole frame), real photo (partial frame)
### #4 00:18.083–00:19.458 · AI-generated video + code / editor overlays (text labels)

- Probabilities: AI-generated video 84%, talking avatar 8%, 3D rendering 2% (fused)
- Material: AI-generated
- Likely tool: Midjourney + Kling / Hailuo
- Low-light frame: 39% of the area is near-black but grainy (not a solid fill), flat blocks in the highlights only 1%, and there is a face: the flat blocks / few colors come from crushed shadows, so they are not counted as rendering features
- Photo / video texture: noise σ=0.45, 42 colors, flat blocks 19%
- Per-frame sharpness oscillates periodically (period None frames, correlation 0.00): the picture went through frame interpolation / rate conversion; the original frame rate was lower
- Duplicate frames follow an interpolated pattern (4%, period None): source was 24/25 fps then transcoded, typical of AI video, 3D / animation renders or film footage
- [VLM] Facial detail is extremely rich and lifelike, but motion is very slow, and the beard and jaw show the subtle warping and slight sticking typical of AI video as they move
- [VLM] Breathing and small head movements lack real muscle elasticity and physiological micro-tremor; the classic image-to-video "slowly raise the head to look at the camera" pattern
- Picture: an elderly Asian man with over-ear headphones and a long white beard lowers his eyes, then slowly raises his head to stare into the camera, expression deep and solemn, against a dim plain studio background.
- Framing / light: extreme close-up; eye level; tripod / stand, fixed; night / low-light ambient, no dedicated fill; key front right; contrast about 1.6:1 (0.7 stops); soft light (wide shadow transition)
- Text track (text / bottom): 上Beat。
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: close-up portrait of a very old Asian man, weathered face, deep wrinkles and age spots, thick moustache and long grey-white goatee, wearing black monitor headphones, deep black background, dramatic cinematic side light, ultra-fine skin texture, vertical composition.
- Video prompt: a very old long-bearded Asian man, head bowed and still, wearing black headphones, then slowly lifts his eyelids and stares into the camera, eyes deep and cold, face kept solemn, extremely faint breathing and tiny head movement, fixed shot.
### #5 00:19.458–00:20.125 · Talking avatar + code / editor overlays (captions, graphic sticker)

- Probabilities: talking avatar 64%, AI-generated video 35%, 3D rendering 0% (fused)
- Material: AI-generated
- Likely tool: Midjourney + HeyGen / SadTalker / CapCut avatar
- Face covers 30% of the frame and appears in 100% of sampled frames: a close shot of a person, flat blocks mostly from walls / clothing, rendering features down-weighted
- Photo / video texture: noise σ=0.19, 35 colors, flat blocks 37%
- [VLM] Skin texture and lighting are too perfect, with the typical Midjourney look
- [VLM] Frame comparison shows the body and background completely still with only the head and mouth moving, consistent with an audio-driven avatar
- Picture: close-up, a white-bearded elder in headphones speaks, plain background, fixed camera, side backlight.
- Framing / light: extreme close-up; eye level; tripod, fixed; night / low-light ambient, no dedicated fill; key front right; contrast about 2.0:1 (1.0 stop); soft light (wide shadow transition)
- Text track (captions / bottom): 上Beat. / LBeat.
- Remake: talking avatar: clone / synthesize the voice-over first, then drive an avatar model from the portrait + audio
- First-frame image prompt: close-up, an Asian white-bearded elder, black over-ear headphones, black Chinese-style clothing. Dark-grey background. Cinematic light, key from the left, cool rim from the right, extremely photoreal.
- Video prompt: the elder speaks facing the camera, natural mouth shapes, slight head movement, body still.
### #6 00:20.125–00:20.833 · Still-image push / pan (Ken Burns) (AI-generated image)

- Probabilities: still-image push / pan 86%, 3D rendering 6%, AI-generated video 6% (fused)
- Still source: ai_image
- Material: AI-generated
- Likely tool: Midjourney + CapCut (JianYing)
- The whole frame moves as a single rigid transform (inliers 100%, residual 0.03 px, no local motion) → still-image push / pan: zoom +2.3%/s, pan 11 px/s
- Rendered texture: flat color blocks 27%, 95% of pixels use only 27 colors, horizontal / vertical straight edges 26%
- [VLM] A single still image with a slow push and slight pan (Ken Burns effect)
- [VLM] Wood grain and shadows inside the frame are completely static, no internal physical motion
- [VLM] A surreal isolated wooden door in a dark void: strong AI concept-art traits
- Picture: a rough old wooden door stands half open in a dark void, a shaft of cool light pouring down from the upper left; the camera pushes forward very slowly.
- Remake: still-image push / pan: reproduce exactly with one image + the measured zoom / pan parameters in local ffmpeg
### #7 00:20.833–00:21.500 · AI-generated video

- Probabilities: AI-generated video 45%, 3D rendering 32%, live footage 8% (fused)
- Material: AI-generated; remake reference: character / scene reference image
- Likely tool: CapCut (JianYing) / Premiere keyframe pan motion
- [VLM] Plank grain, knots, hemp-rope fibers and the rusty iron nail are highly realistic in detail
- [VLM] No independent 3D perspective change between the plaque and its shadow on the wall; the camera motion is a pure 2D pan / push
- Picture: a vintage blank rectangular wooden plaque hangs on a grey wall from hemp rope and an iron nail; the camera pushes in slowly at a slight upward tilt.
- Framing / light: medium close-up; slight low angle; moving camera (gimbal / handheld pan); key from front side + fill (standard setup); key front left; contrast about 1.7:1 (0.8 stops); soft light (wide shadow transition)
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first; use as reference when generating: character / scene reference image
- First-frame image prompt: minimalist still life, grey micro-cement wall, a single old iron nail with a thick hemp rope hanging a weathered, distressed strip of raw wood as a plaque, blank with no lettering, soft diffused light from upper side, fine wood-grain texture, vertical composition.
- Video prompt: the camera is on a vintage blank wooden plaque hanging on a grey wall, slightly low angle, pushing in toward the plaque steadily and extremely slowly.
### #8 00:21.500–00:22.167 · AI-generated video

- Probabilities: AI-generated video 97%, still-image push / pan 1%, 3D rendering 0% (fused)
- Material: AI-generated
- Likely tool: Midjourney (base image) + Kling / Runway Gen-2
- [VLM] A highly stylized still-life photography look, perfect light but lacking real physical detail (e.g. the thickness of the paper's edge)
- [VLM] The move is a smooth pan to the right with tiny perspective change, consistent with the 3D camera moves of AI image-to-video
- Picture: close-up, a dark-grey desk with a wrinkled ink-stained sheet of paper, an inkstone and brush beside it. A window-frame shadow in the background. The camera pans slowly right.
- Framing / light: close-up; slight high angle; moving camera (gimbal / handheld pan); frontal soft light (flat); key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.0:1 (0.1 stops); soft light (almost no shadow edge)
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: close-up, a wrinkled sheet of xuan paper with black ink-wash bleed marks spread on a dark-grey desk, a black inkstone and a brush on the right. Dark tones, minimalist, Eastern aesthetic. Sharp shadow of a window frame in the upper right, cinematic light and shadow, high contrast, 8k resolution, photoreal texture.
- Video prompt: the camera pans slowly to the right, showing the ink-wash paper, inkstone and brush on the desk; the light stays steady, the frame is quiet.
### #9 00:22.167–00:22.875 · AI-generated video + code / editor overlays (graphic sticker)

- Probabilities: AI-generated video 64%, 3D rendering 34%, 2D animation 0% (fused)
- Material: AI-generated
- Likely tool: Kling / Runway / Hailuo
- [VLM] The water motion looks slightly viscous and warped, lacking the complex high-frequency detail of real fluid dynamics
- [VLM] The sky and clouds are completely still, only part of the water surface moves, a common AI video trait
- Picture: black-and-white close-up of a water surface, ripples rocking, a curved horizon, overcast sky, fixed camera.
- Framing / light: close-up; eye level; tripod / stand, fixed; outdoor overcast / shade soft light; key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.2:1 (0.3 stops); soft light (almost no shadow edge)
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: black-and-white photography, close-up of ripples on a water surface, slightly curved horizon, overcast sky, minimalist, high contrast.
- Video prompt: black-and-white, ripples spread on the water surface and roll slowly forward, sky still, fixed camera.
### #10 00:22.875–00:23.542 · Still-image push / pan (Ken Burns) (cg_3d) + code / editor overlays (graphic sticker)

- Probabilities: still-image push / pan 88%, 3D rendering 10%, live footage 1% (fused)
- Still source: cg_3d
- Material: rendered by the producer
- Likely tool: CapCut (JianYing)
- The whole frame moves as a single rigid transform (inliers 100%, residual 0.10 px, no local motion) → still-image push / pan: zoom +5.7%/s, pan 28 px/s
- Rendered texture: flat color blocks 25%, 95% of pixels use only 29 colors, horizontal / vertical straight edges 9%
- [VLM] No physical displacement of the water, rope or boat inside the frame
- [VLM] The whole clip has only a slow constant-speed pan and slight zoom (Ken Burns effect)
- Picture: a minimalist dark scene looking down on an old black wooden boat with two oars and hemp rope inside, faint stripes of light and shadow falling from the left; the camera pushes and pans slowly.
- Remake: still-image push / pan: reproduce exactly with one image + the measured zoom / pan parameters in local ffmpeg
### #11 00:23.542–00:24.208 · Still-image push / pan (Ken Burns) (AI-generated image)

- Probabilities: still-image push / pan 93%, AI-generated video 6%, screen recording / screenshot 0% (fused)
- Still source: ai_image
- Material: AI-generated
- Likely tool: Midjourney + CapCut (JianYing)
- The whole frame moves as a single rigid transform (inliers 100%, residual 0.03 px, no local motion) → still-image push / pan: zoom +1.4%/s, pan 7 px/s
- Photo / video texture: noise σ=0.46, 30 colors, flat blocks 5%
- [VLM] The smoke keeps the same shape throughout with no flow; local motion rate is 0
- [VLM] Only a pure 2D slow push / zoom (Ken Burns motion)
- [VLM] The charcoal fragments and wood grain have typical AI image-render traits
- Picture: close-up of a charred, carbonized fragment of plank with wisps of white smoke frozen on its surface, on a grey minimalist surface; the camera pushes in very slowly.
- Remake: still-image push / pan: reproduce exactly with one image + the measured zoom / pan parameters in local ffmpeg
### #12 00:24.208–00:24.917 · Still-image push / pan (Ken Burns) (real photo); introduces real material (real photo, product photo)

- Probabilities: still-image push / pan 99%, still frame 0%, AI-generated video 0% (fused)
- Still source: photo
- Material: user's real material: real photo, product photo
- Likely tool: CapCut (JianYing) / Premiere
- The whole frame moves as a single rigid transform (inliers 100%, residual 0.12 px, no local motion) → still-image push / pan: zoom +13.9%/s, pan 59 px/s
- [VLM] No independent motion inside the frame; beads, tassel and lighting stay absolutely still
- [VLM] The bead reflections are realistic, consistent with studio product photography
- [VLM] The reference signal shows a high kenburns_score; there may be an extremely slow push, but the subject does not change
- Picture: a black prayer-bead bracelet with a white main bead and black tassel rests on a dark-grey background; the frame has an extremely slow push or is fully static, emphasizing the product's texture.
- Remake: still-image push / pan: reproduce exactly with one image + the measured zoom / pan parameters in local ffmpeg; the user must supply the real material: real photo (whole frame), product photo (partial frame)
### #13 00:24.917–00:25.583 · 3D rendering

- Probabilities: 3D rendering 66%, AI-generated video 18%, live footage 14% (fused)
- Material: rendered by the producer
- Likely tool: Blender
- [VLM] A minimalist 3D dark-grey space with a seamless flat gradient floor and fog
- [VLM] The tiny crawling figure casts a neat, straight, hard-edged long shadow
- [VLM] No dynamic noise or warping in the frame, consistent with the volumetric fog and spotlight of a 3D renderer (e.g. Blender / C4D)
- Picture: an extreme wide shot looking down on an empty, dim grey space; a faint figure lies prone and crawls at the center of the floor while a spotlight throws a long thin shadow; a lonely, cold mood.
- Framing / light: wide; slight high angle; tripod / stand, fixed; frontal soft light (flat); key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.1:1 (0.2 stops); soft light (almost no shadow edge)
- Remake: 3D rendering: first/last-frame AI generation gives an approximation; for precise multi-angle work go 3D modeling + Blender render
- First-frame image prompt: extreme wide shot, an empty, cold greyscale foggy space, a person lying prone and crawling on the floor, a single low-angle hard spotlight throwing a long thin hard shadow, minimalist dark concept art, vertical
- Video prompt: fixed long shot, an empty, dim studio of cold grey mist, a tiny human figure crawls along the floor extremely slowly, a single light source throws a very long shadow, the frame feels frozen and still
### #14 00:25.583–00:26.250 · 3D rendering + code / editor overlays (graphic sticker)

- Probabilities: 3D rendering 69%, AI-generated video 20%, live footage 10% (fused)
- Material: rendered by the producer
- Likely tool: Blender / C4D
- [VLM] The water ripples are highly regular and match a displacement-map animation
- [VLM] The curved edge at the top is geometrically perfect and smooth, with no live-action noise or lens distortion
- [VLM] Monochrome black-and-white tone and metallic water reflections, a typical 3D renderer material preset
- Picture: a black liquid surface in minimalist black and white, fine ripples constantly rocking, a smooth curved edge above against a hazy sky; the camera is fixed, looking up.
- Framing / light: close-up; eye level; tripod / stand, fixed; key from front side + fill (standard setup); key front left; contrast about 1.5:1 (0.6 stops); medium softness
- Remake: 3D rendering: first/last-frame AI generation gives an approximation; for precise multi-angle work go 3D modeling + Blender render
- First-frame image prompt: black-and-white close-up, a dark fluid surface with gentle ripples glinting with silver-grey metallic highlights, a smooth curved boundary and a dim sky above in the background, minimalist, 3D-render texture
- Video prompt: fixed close-up, waves on a surface of black viscous liquid keep flowing and heaving, reflecting a faint silver-grey sheen, the arc at the top stays steady, no people, mysterious and calm mood
### #15 00:26.250–00:26.917 · Still-image push / pan (Ken Burns) (AI-generated image)

- Probabilities: still-image push / pan 99%, AI-generated video 0%, screen recording / screenshot 0% (fused)
- Still source: ai_image
- Material: AI-generated
- Likely tool: Midjourney (image) + CapCut (JianYing) / Premiere (zoom motion)
- The whole frame moves as a single rigid transform (inliers 100%, residual 0.03 px, no local motion) → still-image push / pan: zoom +1.8%/s, pan 9 px/s
- Photo / video texture: noise σ=0.50, 30 colors, flat blocks 2%
- [VLM] The smoke in the frame is completely still, with no sign of drifting or dissipating
- [VLM] The whole frame only has a uniform enlargement (push), with no relative motion of any internal element
- Picture: a few pieces of charred wood sit in front of a grey background with frozen wisps of smoke rising from them; the frame pushes forward slowly.
- Remake: still-image push / pan: reproduce exactly with one image + the measured zoom / pan parameters in local ffmpeg
### #16 00:26.917–00:27.625 · Still-image push / pan (Ken Burns) (AI-generated image)

- Probabilities: still-image push / pan 91%, AI-generated video 8%, screen recording / screenshot 0% (fused)
- Still source: ai_image
- Material: AI-generated
- Likely tool: CapCut (JianYing)
- The whole frame moves as a single rigid transform (inliers 98%, residual 0.18 px, no local motion) → still-image push / pan: zoom +7.9%/s, pan 45 px/s
- Rendered texture: flat color blocks 28%, 95% of pixels use only 29 colors, horizontal / vertical straight edges 6%
- [VLM] Water, hull and oars inside the frame are completely still with no independent physical motion
- [VLM] The camera shows only a slight overall 2D push / pan displacement (Ken Burns effect)
- [VLM] The oar and hull-edge textures have the ultra-fine distressed look typical of AI painting
- Picture: a close-up corner of a dilapidated wooden boat, two worn old oars leaning inside the hull, a hazy dim foggy water surface behind; the camera pushes in very slightly.
- Remake: still-image push / pan: reproduce exactly with one image + the measured zoom / pan parameters in local ffmpeg
### #17 00:27.625–00:27.958 · Still-image push / pan (Ken Burns) (AI-generated image)

- Probabilities: still-image push / pan 99%, AI-generated video 0%, screen recording / screenshot 0% (fused)
- Still source: ai_image
- Material: AI-generated
- Likely tool: Midjourney + CapCut (JianYing) effects
- The whole frame moves as a single rigid transform (inliers 100%, residual 0.10 px, no local motion) → still-image push / pan: zoom +0.4%/s, pan 10 px/s
- [VLM] No internal motion at all
- [VLM] The frame sequence shows a pure 2D pan
- [VLM] The ink edges have AI-generation traits
- Picture: close-up of ink on xuan paper and an inkstone.
- Remake: still-image push / pan: reproduce exactly with one image + the measured zoom / pan parameters in local ffmpeg
### #18 00:27.958–00:28.292 · Still-image push / pan (Ken Burns) (AI-generated image)

- Probabilities: still-image push / pan 85%, AI-generated video 9%, screen recording / screenshot 2% (fused)
- Still source: ai_image
- Material: AI-generated
- Likely tool: Midjourney / Stable Diffusion
- The whole frame moves as a single rigid transform (inliers 100%, residual 0.05 px, no local motion) → still-image push / pan: zoom +3.3%/s, pan 17 px/s
- [VLM] The frame is completely still over the given time sequence, not the slightest motion or change
- [VLM] The deterministic analysis reports a fairly high temporal_noise, probably video-encoding noise, but there is no actual motion
- [VLM] The plaque's texture and lighting look like a photoreal AI-generated image
- Picture: a blank distressed wooden plaque hangs on a grey wall, with light falling diagonally from the upper left
- Remake: still-image push / pan: reproduce exactly with one image + the measured zoom / pan parameters in local ffmpeg
### #19 00:28.292–00:28.625 · 3D rendering

- Probabilities: 3D rendering 35%, AI-generated video 31%, live footage 18% (fused)
- Material: rendered by the producer; remake reference: product reference image
- [VLM] The content is a static image with no internal motion at all (no beads rolling, no lighting change), the typical trait of still_motion
- [VLM] The timeline slice image provided (file_2.jpg) shows the frame content is identical at different times, with motion created only by push / pan
- [VLM] dup_ratio=0 and kenburns_score=0.235 in the deterministic first pass support the judgment that this is a still image with Ken Burns push / pan
- Picture: the camera shows a string of dark wooden prayer beads laid on a flat grey background. The string winds in an S-curve; in the foreground one bead with golden cracks and one pale-green bead serve as accents. The whole frame has a calm, zen mood.
- Framing / light: close-up; slight high angle; tripod / stand, fixed; frontal soft light (flat); key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.3:1 (0.4 stops); soft light (almost no shadow edge)
- Remake: 3D rendering: first/last-frame AI generation gives an approximation; for precise multi-angle work go 3D modeling + Blender render; use as reference when generating: product reference image
- First-frame image prompt: minimalist product photography, close-up. A string of rounded dark-brown wooden prayer beads laid in an S-curve on a smooth light-grey background. In the foreground focus, one bead with shiny golden cracks and one pale-green jade bead. Shallow depth of field, blurred background. Soft top light from the left, a zen, tranquil mood, high quality, photoreal style.
- Video prompt: the camera pushes forward slowly, a close-up of a string of dark wooden prayer beads on a smooth grey background, a bead with golden cracks and a pale-green bead in the foreground, the scene stays still, only the smooth camera push.
### #20 00:28.625–00:29.000 · Still-image push / pan (Ken Burns) (AI-generated image)

- Probabilities: still-image push / pan 99%, AI-generated video 0%, screen recording / screenshot 0% (fused)
- Still source: ai_image
- Material: AI-generated
- The whole frame moves as a single rigid transform (inliers 100%, residual 0.05 px, no local motion) → still-image push / pan: zoom +1.6%/s, pan 8 px/s
- [VLM] The smoke and particles inside the frame show no dynamic change; frames compare identical.
- [VLM] The charcoal texture and the smoke shapes have the typical traits of AI-generated images, such as implausible detail and blurred edges.
- Picture: a few pieces of burnt charcoal on a dark background with a few wisps of white smoke above. The whole frame is dark-toned and motionless.
- Remake: still-image push / pan: reproduce exactly with one image + the measured zoom / pan parameters in local ffmpeg
### #21 00:29.000–00:31.625 · AI-generated video + code / editor overlays (captions)

- Probabilities: AI-generated video 85%, 3D rendering 10%, live footage 3% (fused)
- Material: AI-generated
- Likely tool: Midjourney + Kling / Runway
- Per-frame sharpness oscillates periodically (period 2 frames, correlation 0.36): the picture went through frame interpolation / rate conversion; the original frame rate was lower
- Duplicate frames follow an interpolated pattern (0%, period None): source was 24/25 fps then transcoded, typical of AI video, 3D / animation renders or film footage
- [VLM] The character's gait slides slightly; contact with the ground lacks real weight and friction
- [VLM] The geometric edges of the doors on both sides and the tiles and lanterns behind show slight AI temporal flow and flicker
- [VLM] Water reflections and rainy-night lighting have the typical dark photoreal look of Midjourney / Runway
- Picture: the back of an ancient scholar walking slowly through a wooden gate toward a long, narrow lantern-lit old street on a rainy night. Medium-wide shot, slow push forward, cool teal-grey tones against warm yellow lantern light.
- Framing / light: full; eye level; gimbal; night / low-light ambient, no dedicated fill; key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.2:1 (0.2 stops); hard light (clear shadow edge)
- Text track (captions / bottom): 十四岁进考棚 / 考了七回才中个秀才
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: cinematic, the back of an ancient Chinese scholar in a blue-grey gown standing before an open wooden gate, a narrow wet flagstone old street stretching ahead, faint warm-yellow lanterns hung along both sides, deep-blue cool rainy night, fine photoreal detail, strong depth, vertical composition
- Video prompt: fixed or slowly pushing camera, an ancient scholar with his back to the camera walks slowly forward through a gate, the wooden doors on both sides fixed, lantern light in the distant street flickering faintly, reflections on the water, the whole movement calm and slow
### #22 00:31.625–00:32.167 · AI-generated video + code / editor overlays (text labels)

- Probabilities: AI-generated video 67%, talking avatar 15%, 3D rendering 10% (fused)
- Material: AI-generated
- Likely tool: Midjourney + Kling
- Face covers 34% of the frame and appears in 100% of sampled frames: a close shot of a person, flat blocks mostly from walls / clothing, rendering features down-weighted
- Photo / video texture: noise σ=0.27, 36 colors, flat blocks 29%
- [VLM] Facial skin and hair texture have the typical hyper-real AI-generated look
- [VLM] As the camera pushes in, the beard and the area around the lips move with a slightly sticky, floating quality, consistent with AI video / digital driving
- [VLM] A Qing official robe with modern studio headphones and microphone: a concept composite scene
- Picture: an elder in a Qing first-rank crane badge robe and modern headphones raps into a recording microphone; the camera pushes smoothly and quickly to a facial close-up; the light is cold, dark and serious.
- Framing / light: extreme close-up; eye level; gimbal; night / low-light ambient, no dedicated fill; key front right; contrast about 1.8:1 (0.9 stops); soft light (wide shadow transition)
- Text track (text / bottom): 考了七回才中个秀才
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: photoreal, an aged Qing-dynasty official in a black embroidered crane rank badge robe with a court necklace, long white goatee, wearing professional black over-ear monitor headphones, a pop filter and microphone in front of him, dark-grey minimalist studio background, cinematic cool-toned side light, high-contrast dramatic light and shadow, vertical composition.
- Video prompt: the camera pushes steadily and quickly from a medium close-up into a facial close-up of the elder; he wears large headphones, eyes firm and serious, opens his mouth and raps hard into the microphone, beard moving naturally, expression stern.
### #23 00:32.167–00:34.625 · AI-generated video + code / editor overlays (text labels)

- Probabilities: AI-generated video 80%, talking avatar 8%, live footage 5% (fused)
- Material: AI-generated
- Likely tool: Kling / Runway / Luma
- Low-light frame: 43% of the area is near-black but grainy (not a solid fill), flat blocks in the highlights only 0%, and there is a face: the flat blocks / few colors come from crushed shadows, so they are not counted as rendering features
- Photo / video texture: noise σ=0.56, 32 colors, flat blocks 6%
- Per-frame sharpness oscillates periodically (period None frames, correlation 0.00): the picture went through frame interpolation / rate conversion; the original frame rate was lower
- Duplicate frames follow an interpolated pattern (0%, period None): source was 24/25 fps then transcoded, typical of AI video, 3D / animation renders or film footage
- [VLM] The writing on the paper is illegible pseudo-Chinese gibberish
- [VLM] The hand holding the brush looks slightly stiff, and the brush strokes do not actually interact with the paper
- [VLM] The whole frame has the smooth AI-generated look and a faint floating motion
- Picture: a young scholar in Qing dress bends over a desk writing in a dim setting; the camera pushes in slowly on the scene of hard study.
- Framing / light: medium close-up; slight high angle; moving camera (gimbal / handheld pan); night / low-light ambient, no dedicated fill; key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.3:1 (0.4 stops); soft light (almost no shadow edge)
- Text track (text / bottom): 考了七回才中个秀才
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: a young Qing-dynasty scholar with shaved forehead and queue, in a grey cloth gown, bent over a desk writing with a brush in a dim study. A scroll on the desk, blurred lanterns behind. Soft key from the left, cinematic texture, dark tones, vertical.
- Video prompt: the camera pushes forward slowly, the scholar looks down writing intently, slight brush movements of the hand, small head movements.
### #24 00:34.625–00:36.667 · AI-generated video + code / editor overlays (text labels)

- Probabilities: AI-generated video 49%, live footage 34%, talking avatar 7% (fused)
- Material: AI-generated
- Likely tool: LivePortrait / SadTalker / HeyGen
- Low-light frame: 28% of the area is near-black but grainy (not a solid fill), flat blocks in the highlights only 2%, and there is a face: the flat blocks / few colors come from crushed shadows, so they are not counted as rendering features
- Photo / video texture: noise σ=0.47, 41 colors, flat blocks 10%
- [VLM] Only the lips and jaw move with the audio; the eyes and forehead wrinkles show almost no naturally linked micro-expressions
- [VLM] Teeth and the inside of the mouth are smooth with slight warping, consistent with AI audio-driven lip sync (avatar)
- [VLM] Hair and beard edges smear slightly in places as they move
- Picture: extreme close-up of an ancient elder's face in modern over-ear headphones, the face full of weathered wrinkles and age spots, lip-syncing to the lines.
- Framing / light: extreme close-up; eye level; tripod / stand, fixed; night / low-light ambient, no dedicated fill; key front right; contrast about 1.6:1 (0.7 stops); soft light (wide shadow transition)
- Text track (text / bottom): 同一场我爹上了榜
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: facial close-up of an ancient Chinese elder, grey-white beard, deep wrinkles and age spots across the face, wearing black modern over-ear headphones, low-key hard light, cinematic texture, ultra-realistic detail, 8k resolution
- Video prompt: fixed facial close-up of the elder, speaking to the camera sternly and coldly, lips opening and closing in sync, slight facial movement, firm gaze, camera stays still
### #25 00:36.667–00:39.542 · AI-generated video + code / editor overlays (text labels)

- Probabilities: AI-generated video 80%, 3D rendering 9%, live footage 9% (fused)
- Text on objects in the frame (not post captions): 光港流、光港海、光张、乖来染流库烧林子安、聚流摩烧林子安、项洗
- Material: AI-generated
- Likely tool: Kling
- Photo / video texture: noise σ=0.48, 70 colors, flat blocks 9%
- [VLM] Most of the brush writing on the list is meaningless fake / warped pseudo-Chinese; only '林子安' inside the red circle is legible
- [VLM] The hand holding the lamp and the hand pointing at the list are nearly still; veins and skin have an AI look and lack real micro-motion and muscle deformation
- [VLM] The lamp flame barely moves; the background and the paper texture show the typical slight temporal warping of AI video
- Picture: in the dim night, one hand holds a kerosene lamp while a finger of the other hand points at a yellow list posted on a wooden wall, the name '林子安' circled in red; steady close shot, faint warm-yellow lamplight lighting part of the frame.
- Framing / light: close-up; eye level; tripod / stand, fixed; night / low-light ambient, no dedicated fill; key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.2:1 (0.3 stops); hard light (clear shadow edge)
- Text track (text / bottom): 我名字被学台挂出来
- Text track (captions / middle): 光港流 / 光港海 / 光张 / 紫汽林子安
- Text track (captions / middle): 乖来染流库烧林子安 / 聚流摩烧林子安 / 项洗 / X
- Text track (text / middle): 茂
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: close-up, night, an ancient-style suspense mood. The left hand holds a lit vintage hurricane lamp, a warm yellow flame glowing through the glass. On the wooden wall to the right a yellowed brush-written list is posted; a finger of the right hand, veins standing out, points at the characters '林子安' circled in red on the list. Cinematic texture, faint dark surroundings against local warm light, lifelike detail.
- Video prompt: fixed close-up. In the night a kerosene lamp flame flickers faintly, dim yellow light on a results list. A finger points steadily at the three characters '林子安' inside a red circle, the paper of the list trembling very slightly in a breeze, keeping a dark, oppressive, suspenseful mood overall.
### #26 00:39.542–00:40.250 · AI-generated video

- Probabilities: AI-generated video 36%, live footage 29%, talking avatar 26% (fused)
- Material: AI-generated
- Face covers 25% of the frame and appears in 100% of sampled frames: a close shot of a person, flat blocks mostly from walls / clothing, rendering features down-weighted
- Photo / video texture: noise σ=0.15, 35 colors, flat blocks 37%
- [VLM] Skin pores, fine age spots and beard hairs are extremely fine and natural, no flicker or warping
- [VLM] The knuckles and bone structure of the hand on the headphones and its motion are physically entirely real
- [VLM] Teeth, tongue and muscle linkage inside the mouth while speaking follow real physics entirely
- [claude visual review] Same AI character (white-bearded elder, same headphones and prayer beads) and same studio background as the neighboring lip-sync shots
- [claude visual review] Mouth shapes follow the rap lyrics; there is no live-action scene anywhere in the piece
- [claude visual review] Characters and wardrobe are fully consistent between the AI shots and these shots across the whole music video
- Picture: close-up, an elderly Asian man with a long beard wears over-ear monitor headphones, one hand on the earcup, singing or speaking with feeling; plain dark-grey studio background, dark side-lit portrait look.
- Framing / light: extreme close-up; eye level; tripod / stand, fixed; night / low-light ambient, no dedicated fill; key front right; contrast about 1.8:1 (0.9 stops); hard light (clear shadow edge)
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: close-up, an Asian elder with a grey-white goatee, black monitor headphones, one hand on the edge of the headphones, a dark Chinese-style buttoned jacket, dark-grey minimalist background, single hard side light, sharp skin texture, film-grain cinematic look, vertical
- Video prompt: fixed camera, a long-bearded Asian elder in black headphones holds one earcup, mouth open, singing / chanting with absorption, facial muscles and beard swaying slightly and naturally with the song, dark studio side light.
### #27 00:40.250–00:42.875 · AI-generated video + code / editor overlays (captions)

- Probabilities: AI-generated video 48%, 3D rendering 24%, live footage 21% (fused)
- Text on objects in the frame (not post captions): 道枝憶花、杨况機光心、植税流横清热境福土文
- Material: AI-generated
- Rendered texture: flat color blocks 34%, 95% of pixels use only 25 colors, horizontal / vertical straight edges 12%
- Per-frame sharpness oscillates periodically (period None frames, correlation 0.00): the picture went through frame interpolation / rate conversion; the original frame rate was lower
- Duplicate frames follow an interpolated pattern (0%, period None): source was 24/25 fps then transcoded, typical of AI video, 3D / animation renders or film footage
- [VLM] Finger skin texture, nail beds and age spots are extremely real and natural, no AI warping
- [VLM] Paper fibers, ink bleed and creases behave physically exactly like live footage
- [VLM] The natural dark side backlight from the faint oil lamp in the upper left matches the hand's shadow
- [VLM] The strokes of the text on the scroll are neat and stable, without the melting and flicker common in AI-generated text
- [claude visual review] Apart from the four large characters 「文理太浅」, the small vertical text on the memorial is pseudo-Chinese that does not form real characters (臣謹枝槎、趙洼), a typical tell of generated imagery
- Picture: a dark, period-style close-up; a gaunt, withered finger presses on an old xuan-paper document bearing "文理太浅"; the camera drifts slowly, oil-lamp side light picking out part of the frame.
- Framing / light: close-up; high angle; gimbal; night / low-light ambient, no dedicated fill; key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.2:1 (0.2 stops); medium softness
- Text track (captions / bottom): 理太浅四个 / 文理太浅四个大字 / 全城都看明白
- Text track (captions / middle): 文理太浅 / 治国之道道楼 / 治国之道道洼 / 治国之道趙挂播
- Text track (captions / middle): 道枝憶花 / 杨况機光心 / 植税流横清热境福土文
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: dark close-up, a yellowed old memorial with the large ink characters 「文理太浅」, an aged, gaunt finger pressing on the paper, cinematic low saturation
- Video prompt: a gaunt finger slowly traces the large characters on a memorial, the other hand enters from below and presses the paper, the camera pushes in slowly
### #28 00:42.875–00:43.583 · Talking avatar + code / editor overlays (text labels)

- Probabilities: talking avatar 67%, AI-generated video 22%, code / template rendering 8% (fused)
- Material: AI-generated
- Likely tool: LivePortrait / SadTalker / Midjourney
- Face covers 25% of the frame and appears in 100% of sampled frames: a close shot of a person, flat blocks mostly from walls / clothing, rendering features down-weighted
- Photo / video texture: noise σ=0.22, 31 colors, flat blocks 30%
- [VLM] Body and background completely still, no physical micro-tremor
- [VLM] Only the mouth deforms to lip-sync with the audio, with slightly smeared edges
- [VLM] The surreal AI-image look of a period long-bearded elder wearing modern over-ear headphones
- Picture: close-up, a white-bearded period elder in headphones speaks into the microphone, lips syncing to the audio, fixed camera.
- Framing / light: extreme close-up; eye level; tripod / stand, fixed; night / low-light ambient, no dedicated fill; key front right; contrast about 1.6:1 (0.7 stops); hard light (clear shadow edge)
- Text track (text / bottom): 全城都看明白
- Remake: talking avatar: clone / synthesize the voice-over first, then drive an avatar model from the portrait + audio
- First-frame image prompt: close-up portrait, a weather-beaten old ancient Chinese Taoist, long white beard, professional black over-ear monitor headphones, a black microphone in front, plain dark-grey background, cinematic side light, ultra-realistic detail, low-saturation cool tones.
- Video prompt: static shot, the old man's mouth opens and closes in lip sync, slight eye movement, body and head kept steady, expression serious and composed.
### #29 00:43.583–00:44.792 · AI-generated video + code / editor overlays (text labels)

- Probabilities: AI-generated video 41%, live footage 32%, 3D rendering 21% (fused)
- Text on objects in the frame (not post captions): 文理太浅、臣遒枝槎协、臣枝槎说、治国之道趙挞挂播、治国之道趙洼、治国之道挞洼
- Material: AI-generated
- [VLM] Finger skin texture, nails and creases are extremely lifelike and natural
- [VLM] Xuan-paper fibers, ink bleed and the light on the paper's relief are physically real
- [VLM] No AI warping or flicker, consistent with a macro live-action prop shot in a drama
- [claude visual review] The same memorial; the small text is still pseudo-Chinese (挞洼、趙挞), and the glyphs change slightly frame to frame
- [claude visual review] Finger and paper textures are photoreal, stylistically continuous with #27: the same generation
- Picture: a cinematic close-up; a rough, aged finger presses on xuan paper bearing an inked document with the large characters "文理太浅"; the camera pushes in slowly by a small amount.
- Framing / light: close-up; high angle; gimbal; night / low-light ambient, no dedicated fill; key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.2:1 (0.2 stops); soft light (wide shadow transition)
- Text track (text / bottom): 全城都看明白
- Text track (captions / middle): 文理太浅 / 臣遒枝槎协 / 臣枝槎说 / 臣道枝槎倾协
- Text track (captions / middle): 治国之道趙挞挂播 / 治国之道趙洼 / 治国之道挞洼 / 台国之道随姑洼
- Text track (text / middle): 号
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: close shot of a yellowed memorial, the large characters 「文理太浅」 centered, a finger pressing the paper's edge from above, dark tones
- Video prompt: a finger presses the memorial, the camera pushes in slightly on the large characters 「文理太浅」
### #30 00:44.792–00:45.417 · AI-generated video

- Probabilities: AI-generated video 86%, talking avatar 12%, live footage 0% (fused)
- Text on objects in the frame (not post captions): 福
- Material: AI-generated
- Likely tool: Midjourney + Kling / Hailuo / Hedra
- Low-light frame: 42% of the area is near-black but grainy (not a solid fill), flat blocks in the highlights only 6%, and there is a face: the flat blocks / few colors come from crushed shadows, so they are not counted as rendering features
- Photo / video texture: noise σ=0.36, 34 colors, flat blocks 24%
- [VLM] Extremely high-precision skin texture and hair detail with the typical hyper-real AI look
- [VLM] A period elder combined with modern headphones and a microphone is a common AI creative concept
- [VLM] Clean background and perfect lighting, consistent with high-quality image-to-video
- Picture: close-up, a long white-bearded Asian elder in headphones speaks into the microphone, plain grey background, sculpted light, extremely photoreal.
- Framing / light: extreme close-up; eye level; tripod, fixed; night / low-light ambient, no dedicated fill; key front right; contrast about 1.6:1 (0.6 stops); soft light (wide shadow transition)
- Text track (text / middle): 福
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: close-up, an elderly Asian man, long white beard, deeply wrinkled face, fine skin texture. Wearing black modern over-ear headphones and black Chinese-style clothing. Plain grey background. Cinematic light, soft side light, ultra-realistic, portrait photography.
- Video prompt: close-up, a long-bearded elder in headphones speaks into the microphone, natural mouth movement, slight head sway. Fixed camera.
### #31 00:45.417–00:46.958 · AI-generated video + code / editor overlays (text labels)

- Probabilities: AI-generated video 76%, 3D rendering 14%, live footage 8% (fused)
- Material: AI-generated
- Likely tool: Midjourney + Kling / Runway
- Motion beats within the shot: 46.25 s
- [VLM] The backs of the Qing examinees and the crowd at the list have the realistic but smooth, oily look typical of Midjourney
- [VLM] The characters on the list have blurred, irregular strokes: AI-generated pseudo-text gibberish
- [VLM] The motion is an extremely faint slow push with slight local movement, lacking real physical interaction and crowd momentum
- Picture: a Qing imperial-exam results scene; a scholar in a skullcap with a long queue, back to the camera, looks up at the list, surrounded by a crowd also reading it; the camera pushes in very slowly.
- Framing / light: medium (back view, half body to the waist); slight low angle; gimbal; night / low-light ambient, no dedicated fill; key front left; contrast about 2.0:1 (1.0 stop); soft light (wide shadow transition)
- Text track (text / bottom): 进士又考三回
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: a Qing-dynasty imperial-exam results posting; medium shot from behind, a scholar with a Qing queue, skullcap and dark long gown looks up at the yellow golden list under a wooden gallery, the backs of examinees crowding around him, a Chinese traditional gallery, overcast cool tones, cinematic light, ultra-realistic detail.
- Video prompt: the camera pushes forward extremely slowly, the protagonist stands still with his back to us looking up at the results wall, the backs of the examinees around him sway with a faint breathing motion, the cold, solemn mood held to the end of the shot.
### #32 00:46.958–00:47.583 · AI-generated video + code / editor overlays (text labels)

- Probabilities: AI-generated video 49%, live footage 34%, talking avatar 7% (fused)
- Material: AI-generated
- Likely tool: HeyGen / D-ID / SadTalker
- Low-light frame: 33% of the area is near-black but grainy (not a solid fill), flat blocks in the highlights only 3%, and there is a face: the flat blocks / few colors come from crushed shadows, so they are not counted as rendering features
- Photo / video texture: noise σ=0.47, 36 colors, flat blocks 14%
- [VLM] Facial details (wrinkles, hair) stay absolutely still across frames; only the mouth region opens and closes, the typical trait of a single-image audio-driven avatar
- Picture: facial close-up of a white-bearded elder in headphones, speaking straight to the camera, plain grey background
- Framing / light: extreme close-up; eye level; tripod / stand, fixed; night / low-light ambient, no dedicated fill; key front right; contrast about 1.5:1 (0.6 stops); hard light (clear shadow edge)
- Text track (text / bottom): 进士又考三回
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: close-up, a Chinese elder with a long white beard and a face full of deep wrinkles, wearing black over-ear headphones, plain grey background, side lighting, cinematic texture, 8k high detail
- Video prompt: the elder speaks straight into the camera, mouth opening and closing naturally, slight facial expression, head and body still, close-up, fixed camera
### #33 00:47.583–00:48.208 · Still-image push / pan (Ken Burns) (AI-generated image) + code / editor overlays (text labels)

- Probabilities: still-image push / pan 99%, AI-generated video 0%, screen recording / screenshot 0% (fused)
- Still source: ai_image
- Material: AI-generated
- Likely tool: Midjourney (generated image) + an editor (push)
- The whole frame moves as a single rigid transform (inliers 92%, residual 0.19 px, no local motion) → still-image push / pan: zoom +7.8%/s, pan 23 px/s
- [VLM] The figures inside the frame are completely still, no small motion at all (breathing, clothing moving)
- [VLM] The only motion is a slow constant-speed push (zoom) of the whole frame
- [VLM] Edges and details of the crowd in the background have typical AI image-blending traits
- Picture: a group of Qing men with their backs to the camera look up at a list on a wall; medium shot, slow push, overcast cool tones.
- Text track (text / bottom): 三甲垫底那一排
- Remake: still-image push / pan: reproduce exactly with one image + the measured zoom / pan parameters in local ffmpeg
### #34 00:48.208–00:48.792 · Talking avatar + code / editor overlays (text labels)

- Probabilities: talking avatar 68%, AI-generated video 22%, live footage 8% (fused)
- Material: AI-generated
- Likely tool: LivePortrait / Hedra / CapCut avatar
- Face covers 38% of the frame and appears in 100% of sampled frames: a close shot of a person, flat blocks mostly from walls / clothing, rendering features down-weighted
- Photo / video texture: noise σ=0.29, 35 colors, flat blocks 25%
- [VLM] The base is a typical AI-generated photoreal portrait of a Chinese-style elder in modern monitor headphones
- [VLM] Body and headphone cable are completely still; only lips, chin and beard deform slightly, driven by the audio
- [VLM] Teeth and mouth edges show the local interpolation blur common in audio-driven portraits
- Picture: a white-bearded Taoist / elder in black monitor headphones speaks into a microphone in a dark studio, lips moving slightly in sync; close-up, fixed camera.
- Framing / light: extreme close-up; eye level; moving camera (gimbal / handheld pan); night / low-light ambient, no dedicated fill; key front right; contrast about 1.6:1 (0.6 stops); soft light (wide shadow transition)
- Text track (text / bottom): 三甲垫底那一排
- Remake: talking avatar: clone / synthesize the voice-over first, then drive an avatar model from the portrait + audio
- First-frame image prompt: close-up, a lean, spirited ancient Chinese elder with a wrinkled face and white beard, wearing professional black over-ear monitor headphones, a podcast microphone in front of him, dark-grey background, studio side light, film-grain texture, ultra-realistic detail
- Video prompt: slight head movement, lips opening and closing naturally with the speech audio, the beard on the chin swaying slightly, body and headphones steady, camera fixed
### #35 00:48.792–00:50.375 · Talking avatar + code / editor overlays (text labels)

- Probabilities: talking avatar 80%, AI-generated video 19%, 3D rendering 0% (fused)
- Material: AI-generated
- Likely tool: HeyGen / D-ID / CapCut avatar (base image probably from Midjourney)
- Face covers 21% of the frame and appears in 100% of sampled frames: a close shot of a person, flat blocks mostly from walls / clothing, rendering features down-weighted
- Photo / video texture: noise σ=0.12, 30 colors, flat blocks 39%
- 100% of sampled frames have a frontal face with a fixed camera, and the audio track has voice
- [VLM] The head sways slightly and the mouth forms speech, but body, headphones, microphone and background are completely still
- [VLM] The beard shows slight image warping and pulling as the chin moves, consistent with a single-image-driven avatar
- [VLM] Facial texture and lighting are too perfect, with typical AI-image traits
- Picture: close-up, an elderly man in over-ear headphones with a long white beard speaks into a microphone against a plain dark background.
- Framing / light: extreme close-up; eye level; tripod / stand, fixed; night / low-light ambient, no dedicated fill; key front right; contrast about 1.5:1 (0.6 stops); soft light (wide shadow transition)
- Text track (text / bottom): 三甲垫底那一排
- Remake: talking avatar: clone / synthesize the voice-over first, then drive an avatar model from the portrait + audio
- First-frame image prompt: close-up, an elderly Chinese man with a long white beard, wearing a black Chinese-style stand-collar garment and black over-ear monitor headphones, a black microphone in front of him. Dark-grey background, soft key from the left, cinematic, high detail, photoreal style, 8k resolution.
- Video prompt: slight natural head sway, mouth forming speech, tiny shifts in the eyes, body, headphones and microphone absolutely still.
### #36 00:50.375–00:53.458 · AI-generated video + code / editor overlays (captions)

- Probabilities: AI-generated video 44%, live footage 35%, 3D rendering 16% (fused)
- Material: AI-generated
- Rendered texture: flat color blocks 23%, 95% of pixels use only 25 colors, horizontal / vertical straight edges 21%
- [VLM] The photographic look of a live-action drama; extras, costumes and props are detailed and move naturally
- [VLM] The micro-expressions and skin texture of the general on the left are natural, no AI warping or flicker
- [VLM] The camera has a slow push and airborne dust in the environment; physical interaction is real
- [claude visual review] A realistic ancient army formation, but crowd and banner detail drift slightly between frames and the distant soldiers' bodies blur and merge
- [claude visual review] The same cold grey cinematic grade as the whole piece, without the noise and depth-of-field changes of a live set
- Picture: beneath a city wall under heavy clouds, a bearded middle-aged general holding a scroll stands solemnly in profile in the left foreground while ranks of Qing soldiers with spears march in the background. The camera pushes forward slowly; low saturation, an oppressive, grave period war-epic mood overall.
- Framing / light: medium (foreground figure, half-body profile); eye level; gimbal; night / low-light ambient, no dedicated fill; key front left; contrast about 1.8:1 (0.9 stops); soft light (wide shadow transition)
- Text track (captions / bottom): 四十出头才学带兵 / 靖港头一仗就败
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: beneath an ancient city wall under heavy clouds, Qing soldiers in ranks holding spears, a bushy-bearded general in profile in the left foreground, cold grey cinematic grade
- Video prompt: the ranks of soldiers move slowly, dust rises, the general in profile stands still, the camera tracks slowly sideways
### #37 00:53.458–00:54.208 · AI-generated video + code / editor overlays (text labels, graphic sticker)

- Probabilities: AI-generated video 36%, live footage 29%, talking avatar 26% (fused)
- Material: AI-generated
- Face covers 24% of the frame and appears in 100% of sampled frames: a close shot of a person, flat blocks mostly from walls / clothing, rendering features down-weighted
- Photo / video texture: noise σ=0.16, 37 colors, flat blocks 36%
- [VLM] Real skin folds, age spots and capillary detail look natural
- [VLM] Beard and hair edges are sharp and stable, no AI melting or flicker artifacts
- [VLM] Mouth muscles and the opening of the teeth move in a physiologically real way
- [claude visual review] Same AI character (white-bearded elder, same headphones and prayer beads) and same studio background as the neighboring lip-sync shots
- [claude visual review] Mouth shapes follow the rap lyrics; there is no live-action scene anywhere in the piece
- [claude visual review] Characters and wardrobe are fully consistent between the AI shots and these shots across the whole music video
- Picture: a recording-studio close-up; a white-haired elder with a long beard in over-ear headphones starts singing mournfully in front of the microphone; fixed eye-level camera, low-key dark lighting.
- Framing / light: extreme close-up; eye level; tripod / stand, fixed; night / low-light ambient, no dedicated fill; key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.1:1 (0.2 stops); soft light (almost no shadow edge)
- Text track (text / bottom): 靖港头一仗就败
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: close-up, an East Asian elder with a long grey goatee, wearing black over-ear headphones in front of a studio microphone, dark Chinese-style clothing, plain dark-grey background, professional cinematic low-key soft side light, extremely high facial wrinkle detail, lifelike photographic texture.
- Video prompt: fixed close-up, a long-bearded Chinese elder in over-ear headphones starts to sing mournfully into the microphone, mouth opening and closing as he sings, facial muscles and beard trembling slightly and naturally, eyes slightly lowered and grave, light and shadow steady.
### #38 00:54.208–00:56.208 · AI-generated video + code / editor overlays (captions)

- Probabilities: AI-generated video 58%, live footage 32%, 3D rendering 6% (fused)
- Material: AI-generated
- Low-light frame: 50% of the area is near-black but grainy (not a solid fill), flat blocks in the highlights only 1%, and there is a face: the flat blocks / few colors come from crushed shadows, so they are not counted as rendering features
- Photo / video texture: noise σ=0.58, 41 colors, flat blocks 2%
- Per-frame sharpness oscillates periodically (period None frames, correlation 0.00): the picture went through frame interpolation / rate conversion; the original frame rate was lower
- Duplicate frames follow an interpolated pattern (0%, period None): source was 24/25 fps then transcoded, typical of AI video, 3D / animation renders or film footage
- [VLM] Real actor skin detail, muscle lines and wet sheen
- [VLM] Fluid physics of water dripping naturally from the beard and the soaked gown
- [VLM] Drama-grade professional night lighting and color grading
- [claude visual review] The soaked elder lies on the boat's edge; the soldier's arm and the lamp edge in the background warp between frames
- Picture: on a wooden boat on the river at night, a soaked, white-bearded Qing elder is pulled from the cold river onto the deck by his men, hands braced on the boards, expression complex and grave.
- Framing / light: medium close-up; slight high angle; tripod / stand, fixed; night / low-light ambient, no dedicated fill; key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.2:1 (0.3 stops); hard light (clear shadow edge)
- Text track (captions / bottom): 湘江水冷是部下把我捞上来 / 湘江水冷是部下把我捞上菜
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: on a small boat on a river at night, a drenched white-bearded Qing elder braces both hands on the deck boards, a kerosene lamp hanging behind him, cold blue tones
- Video prompt: the elder, panting, braces on the deck and lifts his head; the person behind him reaches out to pull him up; river waves churn
### #39 00:56.208–00:56.917 · AI-generated video

- Probabilities: AI-generated video 78%, talking avatar 21%, live footage 0% (fused)
- Text on objects in the frame (not post captions): 一、一
- Material: AI-generated
- Likely tool: Kling / Hailuo / Hedra (image-to-video or audio-driven)
- Face covers 46% of the frame and appears in 100% of sampled frames: a close shot of a person, flat blocks mostly from walls / clothing, rendering features down-weighted
- Photo / video texture: noise σ=0.28, 43 colors, flat blocks 20%
- [VLM] Skin texture and hair have the typical high-quality AI-generated look
- [VLM] Motion is highly concentrated in the mouth opening and closing and slight head sway, consistent with image-driven video or an avatar
- [VLM] Plain background and extremely shallow depth of field, the standard AI portrait-generation style
- Picture: close-up: an Asian old man with a white beard wears headphones and speaks or sings with an agitated expression, plain grey background.
- Framing / light: extreme close-up; eye level; tripod / stand, fixed; night / low-light ambient, no dedicated fill; key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.3:1 (0.4 stops); soft light (almost no shadow edge)
- Text track (text / middle): 一
- Text track (text / middle): D
- Text track (text / middle): 一
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: close-up, an Asian old man with a white beard, wearing black over-ear headphones, deeply wrinkled face, agitated expression with his mouth open, plain grey background, soft light from the left, high-contrast photoreal portrait.
- Video prompt: the old man speaks or sings with an agitated expression, mouth opening and closing naturally, slight head shake, light and shadow kept steady.
### #40 00:56.917–00:58.417 · AI-generated video + code / editor overlays (captions)

- Probabilities: AI-generated video 73%, 3D rendering 13%, live footage 4% (fused)
- Material: AI-generated
- Likely tool: Kling / Runway / Hailuo
- Photo / video texture: noise σ=0.46, 80 colors, flat blocks 6%
- Per-frame sharpness oscillates periodically (period None frames, correlation 0.00): the picture went through frame interpolation / rate conversion; the original frame rate was lower
- Duplicate frames follow an interpolated pattern (0%, period None): source was 24/25 fps then transcoded, typical of AI video, 3D / animation renders or film footage
- [VLM] The weapons the soldiers swing (spears, swords) bend and deform unnaturally while moving
- [VLM] The edges of the flames and smoke in the background have the "boiling" and flicker common in AI generation
- [VLM] The figures' movements look slightly floaty, lacking real weight and force feedback
- Picture: an ancient naval battle at night; soldiers fight fiercely on the wooden bridge of a burning warship, blazing fire and billowing smoke behind, the figures in silhouette; the camera pushes in slowly.
- Framing / light: full; low angle; moving camera (gimbal / handheld pan); night / low-light ambient, no dedicated fill; key front left; contrast about 1.8:1 (0.9 stops); medium softness
- Text track (captions / bottom): 湖口再败座船被截 / 我又被拉回来
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: vertical, epic ancient naval battle, night, warships on fire, thick billowing smoke. In the center a wooden bridge links two ships; silhouettes of several ancient soldiers fight fiercely on it with spears and swords. Blazing fire and fluttering war banners behind. Strong backlight, high contrast, cinematic texture, dark style.
- Video prompt: the camera pushes forward slowly with a slight low angle. Soldiers fight on the burning wooden bridge swinging spears and swords, movements fierce. Flames blaze in the background, thick smoke drifts in the wind, sparks fly. The overall mood is tense and chaotic.
### #41 00:58.417–00:58.917 · AI-generated video + code / editor overlays (text labels)

- Probabilities: AI-generated video 41%, live footage 27%, 3D rendering 16% (fused)
- Material: AI-generated
- Likely tool: HeyGen / D-ID
- Face covers 45% of the frame and appears in 100% of sampled frames: a close shot of a person, flat blocks mostly from walls / clothing, rendering features down-weighted
- Photo / video texture: noise σ=0.36, 46 colors, flat blocks 16%
- [VLM] Facial muscle motion (especially mouth shapes and eyes) looks stiff, lacking the natural muscle linkage of a real person speaking, closer to an audio-driven avatar
- [VLM] The skin texture is lifelike, but there is almost no natural change in lighting while speaking, more like a single still image with local facial warping
- [VLM] The head-sway path is rather mechanical, without the natural shift of weight of real speech
- [VLM] Teeth and the inside of the mouth render unnaturally while speaking, with a pasted-on look
- Picture: a deeply wrinkled elderly Asian man with a grey-white beard, wearing black over-ear headphones, speaks into a microphone
- Framing / light: extreme close-up; eye level; tripod, fixed; night / low-light ambient, no dedicated fill; key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.2:1 (0.3 stops); soft light (almost no shadow edge)
- Text track (text / bottom): 我又被拉回来
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: close-up, an elderly Asian man with a grey-white goatee, a face full of weathered wrinkles, serious expression, wearing black monitor headphones, speaking into a microphone in front of a dark-grey background. Eye level, single-side hard light bringing out the facial texture, cool tones, ultra-sharp photoreal photography, cinematic texture, vertical.
- Video prompt: not applicable, this is an audio-driven avatar
### #42 00:58.917–00:59.500 · Talking avatar + code / editor overlays (text labels, graphic sticker)

- Probabilities: talking avatar 97%, AI-generated video 1%, 3D rendering 0% (fused)
- Material: AI-generated
- Likely tool: Hedra / D-ID
- Face covers 32% of the frame and appears in 100% of sampled frames: a close shot of a person, flat blocks mostly from walls / clothing, rendering features down-weighted
- Photo / video texture: noise σ=0.29, 44 colors, flat blocks 24%
- [VLM] Body and background completely still; only the head and mouth move
- [VLM] The beard moves as one piece with the chin, no independent hair motion
- [VLM] Consistent with the typical traits of a single-image audio-driven avatar
- Picture: close-up, a white-bearded elder in headphones sings passionately with an exaggerated expression in front of a dark background.
- Framing / light: extreme close-up; eye level; tripod / stand, fixed; night / low-light ambient, no dedicated fill; key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.1:1 (0.1 stops); soft light (almost no shadow edge)
- Text track (text / bottom): 我又被拉回来
- Remake: talking avatar: clone / synthesize the voice-over first, then drive an avatar model from the portrait + audio
- First-frame image prompt: close-up portrait, an Asian elder, long white beard, black over-ear headphones, black studded clothing. Dark-grey background. Cinematic light, key from the left, high contrast bringing out facial texture, ultra-realistic.
- Video prompt: using the image as the base, feed in impassioned audio to drive the character singing with his mouth wide open, slight head sway.
### #43 00:59.500–01:02.542 · AI-generated video + code / editor overlays (captions)

- Probabilities: AI-generated video 84%, talking avatar 8%, 3D rendering 2% (fused)
- Material: AI-generated
- Likely tool: Kling / Hailuo
- Low-light frame: 45% of the area is near-black but grainy (not a solid fill), flat blocks in the highlights only 0%, and there is a face: the flat blocks / few colors come from crushed shadows, so they are not counted as rendering features
- Photo / video texture: noise σ=0.54, 38 colors, flat blocks 4%
- Per-frame sharpness oscillates periodically (period None frames, correlation 0.00): the picture went through frame interpolation / rate conversion; the original frame rate was lower
- Duplicate frames follow an interpolated pattern (0%, period None): source was 24/25 fps then transcoded, typical of AI video, 3D / animation renders or film footage
- [VLM] The fingers holding the brush look slightly stiff; the brush tip's contact with the paper lacks real physical feedback
- [VLM] The beard edges flicker slightly and drift unnaturally
- Picture: close-up, a white-bearded elder in period dress writes with a brush against a dim camp-tent background; the camera pushes in slightly.
- Framing / light: close-up; eye level, slightly high; moving camera (gimbal / handheld pan); night / low-light ambient, no dedicated fill; key front right; contrast about 1.7:1 (0.8 stops); soft light (wide shadow transition)
- Text track (captions / bottom): 我又被拉回来 / 祁门被围遗嘱写好 / 不肯退营等最坏
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: close-up, a weather-beaten ancient Chinese elder, long white beard, dark period clothing. Grave expression, head bowed, writing with a brush. Dim military tent in the background with faint firelight. Cinematic light, soft key from the left.
- Video prompt: the camera pushes in slowly, the elder's expression grave, writing slowly with the brush in hand, beard swaying slightly, firelight flickering in the background.
### #44 01:02.542–01:04.667 · AI-generated video + code / editor overlays (captions)

- Probabilities: AI-generated video 81%, 3D rendering 17%, 2D animation 1% (fused)
- Material: AI-generated
- Likely tool: Kling / Hailuo / Runway
- Rendered texture: flat color blocks 34%, 95% of pixels use only 27 colors, horizontal / vertical straight edges 13%
- [VLM] The digging and hammer-swinging motions break physics, floaty with slight warping
- [VLM] When the figure on the left swings the shovel, the join between handle and arm blurs and becomes structurally unstable
- Picture: silhouettes of ancient soldiers digging a trench under a gloomy sky, figures swinging shovels and hammers, a watchtower in the background; high-contrast dark style overall.
- Framing / light: full; slight low angle; tripod / stand, fixed; night / low-light ambient, no dedicated fill; key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.2:1 (0.2 stops); soft light (wide shadow transition)
- Text track (captions / bottom): 结硬寨打呆仗 / 结硬寨打枭仗
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: vertical, full shot, slight low angle. An ancient battlefield camp under a gloomy, oppressive sky of dark clouds. In the foreground the black silhouettes of a group of ancient soldiers digging trenches with shovels and driving stakes with sledgehammers. A wooden watchtower faintly visible behind. Strong backlit silhouette effect, high contrast, dark epic style.
- Video prompt: fixed camera. The silhouetted ancient soldiers begin to move: the soldier on the left swings a shovel to dig, the soldier on the right swings a sledgehammer onto a wooden stake, movements heavy. The dark clouds in the background sky drift slowly. Keep the strong backlit silhouette and the dark, oppressive mood.
### #45 01:04.667–01:05.375 · Talking avatar + code / editor overlays (graphic sticker)

- Probabilities: talking avatar 97%, AI-generated video 1%, 3D rendering 0% (fused)
- Material: AI-generated
- Likely tool: HeyGen / D-ID / SadTalker / CapCut avatar
- Face covers 12% of the frame and appears in 100% of sampled frames: a close shot of a person, flat blocks mostly from walls / clothing, rendering features down-weighted
- Photo / video texture: noise σ=0.09, 26 colors, flat blocks 40%
- [VLM] Body, headphones and microphone completely still; only the head and mouth have slight driven motion
- [VLM] Where the beard meets the clothing there is slight 2D image pulling as the head moves
- [VLM] Typical traits of a single-image audio-driven avatar
- Picture: medium close-up, an elder in headphones with a long white beard in front of a microphone, head moving slightly, lips parted, grey background.
- Framing / light: close-up; eye level; tripod, fixed; night / low-light ambient, no dedicated fill; key front right; contrast about 1.5:1 (0.6 stops); medium softness
- Text track (text / bottom): 汉盛
- Remake: talking avatar: clone / synthesize the voice-over first, then drive an avatar model from the portrait + audio
- First-frame image prompt: ultra-realistic portrait photography, an elderly Asian man, long white beard, deeply wrinkled face, black over-ear monitor headphones, black Chinese-style clothing with crane embroidery on the chest, a black condenser microphone in front of him, plain grey background, soft side lighting, cinematic texture, 8k.
- Video prompt: using the base image, feed in audio to drive the character's mouth to speak, head swaying slightly and naturally with the speech, body, headphones, microphone and background kept still.
### #46 01:05.375–01:07.167 · AI-generated video + code / editor overlays (text labels)

- Probabilities: AI-generated video 43%, live footage 31%, 3D rendering 18% (fused)
- Material: AI-generated
- Rendered texture: flat color blocks 35%, 95% of pixels use only 27 colors, horizontal / vertical straight edges 13%
- [VLM] The physics of splashing mud and hammer-swinging labor is extremely real with no warping
- [VLM] The backlit silhouette outlines and the diffuse natural light of a rainy day have clear tonal layers
- [VLM] The typical on-set live-action look of a theatrical historical / war film
- [claude visual review] A backlit silhouetted crowd at work; the figures' actions repeat, and the hammers and stakes deform slightly between frames
- [claude visual review] Composition and grade are consistent with the whole piece: the same batch of AI shots
- Picture: on a muddy ancient worksite on a rainy, overcast day, several laborers swing shovels to dig and sledgehammers to drive stakes, with a wooden watchtower and distant hills behind; low-angle pan.
- Framing / light: medium; slight low angle; gimbal; night / low-light ambient, no dedicated fill; key front left; contrast about 1.9:1 (0.9 stops); soft light (wide shadow transition)
- Text track (text / bottom): 笨人只会慢慢挨
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: an overcast camp, a group of Qing soldiers in backlit silhouette swinging hammers onto wooden stakes, a watchtower and banners in the distance
- Video prompt: people bend and swing hammers, driving stakes again and again, mud splashing, fixed camera
### #47 01:07.167–01:10.542 · AI-generated video + code / editor overlays (captions)

- Probabilities: AI-generated video 44%, talking avatar 28%, live footage 19% (fused)
- Material: AI-generated
- Face covers 24% of the frame and appears in 100% of sampled frames: a close shot of a person, flat blocks mostly from walls / clothing, rendering features down-weighted
- Photo / video texture: noise σ=0.12, 32 colors, flat blocks 40%
- Per-frame sharpness oscillates periodically (period 6 frames, correlation 0.03): the picture went through frame interpolation / rate conversion; the original frame rate was lower
- Duplicate frames follow an interpolated pattern (0%, period None): source was 24/25 fps then transcoded, typical of AI video, 3D / animation renders or film footage
- [VLM] Pores, wrinkles and age spots on the face are extremely fine and natural, no AI warping or smearing
- [VLM] Beard and hair strands swing and occlude physically as the head moves
- [VLM] Lip muscles, the perspective of the teeth and tongue motion coordinate naturally while vocalizing
- [VLM] The leather and metal reflections of the headphones match real physical optics
- Picture: a white-bearded elderly man dressed as a Qing official wears monitor headphones and raps into a microphone with full emotion; plain grey background, fixed close-up.
- Framing / light: extreme close-up; eye level; tripod / stand, fixed; night / low-light ambient, no dedicated fill; key from the right of frame (side light); contrast about 2.5:1 (1.3 stops); soft light (wide shadow transition)
- Text track (captions / bottom): 笨人只会慢慢挨 / 打脱牙和血吞 / 京城骂完长沙骂
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: close-up portrait, vertical. A deeply wrinkled elderly Qing-dynasty official with a long grey-white goatee, wearing modern black over-ear monitor headphones and a black embroidered Qing official robe, plain grey studio background, soft top light, cinematic texture, cool low-saturation tones.
- Video prompt: fixed close-up. An elderly man with a long grey-white beard, in a Qing official robe and modern headphones, speaks and raps passionately at the camera, head nodding slightly with the cadence, firm gaze, natural lifelike mouth movement, grey minimalist studio background.
### #48 01:10.542–01:11.792 · Talking avatar + code / editor overlays (text labels, graphic sticker)

- Probabilities: talking avatar 63%, AI-generated video 31%, live footage 5% (fused)
- Material: AI-generated
- Likely tool: LivePortrait
- Face covers 24% of the frame and appears in 100% of sampled frames: a close shot of a person, flat blocks mostly from walls / clothing, rendering features down-weighted
- Photo / video texture: noise σ=0.22, 35 colors, flat blocks 29%
- [VLM] Body and background completely still; only lips and jaw deform, driven by the audio
- [VLM] The elder's face, white beard and headphones have the typical Midjourney hyper-real generated traits
- [VLM] No physical occlusion interaction or natural shadow change where the microphone edge meets the beard
- Picture: a long-bearded Taoist in black with monitor headphones recites into a microphone; facial close-up, eye-level fixed camera, dark studio light.
- Framing / light: extreme close-up; eye level; tripod / stand, fixed; night / low-light ambient, no dedicated fill; key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.1:1 (0.2 stops); soft light (almost no shadow edge)
- Text track (text / bottom): 京城骂完长沙骂
- Remake: talking avatar: clone / synthesize the voice-over first, then drive an avatar model from the portrait + audio
- First-frame image prompt: photoreal photography, close-up of a Chinese elder with a long white beard, professional black headphones, facing a microphone to the side, dark Taoist robe, dark studio background, Rembrandt light.
- Video prompt: the elder keeps facing the microphone, mouth opening to recite with the rap audio, slight head sway, serious expression, fixed camera.
### #49 01:11.792–01:14.583 · Talking avatar + code / editor overlays (captions, graphic sticker)

- Probabilities: talking avatar 74%, AI-generated video 25%, 3D rendering 0% (fused)
- Text on objects in the frame (not post captions): 2
- Material: AI-generated
- Likely tool: LivePortrait / SadTalker / Hedra
- Face covers 14% of the frame and appears in 100% of sampled frames: a close shot of a person, flat blocks mostly from walls / clothing, rendering features down-weighted
- Photo / video texture: noise σ=0.15, 34 colors, flat blocks 35%
- 100% of sampled frames have a frontal face with a fixed camera, and the audio track has voice
- [VLM] Body, clothing and the surrounding microphone and pop filter are completely still with no physical micro-motion
- [VLM] Only the mouth and jaw stretch and deform to lip-sync with the audio; the roots of the beard pull algorithmically with the lips
- [VLM] The head has only faint algorithmic displacement and tilt, eye motion is stiff: a typical still-image-driven talking head
- Picture: a long-bearded elder dressed as a Qing official wears professional monitor headphones and lip-syncs rap in front of a condenser microphone; fixed medium close-up, dark-grey studio background.
- Framing / light: close-up; eye level; tripod / stand, fixed; night / low-light ambient, no dedicated fill; key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.2:1 (0.3 stops); soft light (almost no shadow edge)
- Text track (captions / bottom): 京城骂完长沙骂 / 打脱牙和血吞
- Text track (text / bottom): 2
- Remake: talking avatar: clone / synthesize the voice-over first, then drive an avatar model from the portrait + audio
- First-frame image prompt: photoreal portrait, a white-haired, long-bearded late-Qing official in a dark rank badge robe with a court necklace, wearing modern professional black monitor headphones, a recording condenser microphone standing in front of him, plain dark-grey recording-studio background, high-contrast side light, sharply defined facial wrinkles, 8k detail
- Video prompt: the character's mouth opens and closes naturally lip-syncing the rap, beard swaying slightly as the jaw opens and closes, focused gaze, body and background fixed
### #50 01:14.583–01:17.292 · Talking avatar + code / editor overlays (captions)

- Probabilities: talking avatar 80%, AI-generated video 19%, 3D rendering 0% (fused)
- Material: AI-generated
- Likely tool: Midjourney (base image) + D-ID / HeyGen / SadTalker (audio-driven)
- Face covers 23% of the frame and appears in 100% of sampled frames: a close shot of a person, flat blocks mostly from walls / clothing, rendering features down-weighted
- Photo / video texture: noise σ=0.22, 36 colors, flat blocks 29%
- 100% of sampled frames have a frontal face with a fixed camera, and the audio track has voice
- [VLM] The head sways slightly and the mouth opens and closes in speech, but shoulders, clothing, the headphones and the microphone on the left stay completely still through the whole video, the typical trait of a single image driven by audio (avatar).
- [VLM] Skin texture is too sharp and perfect, with the typical AI-generated image look.
- Picture: close-up, an elder with a long white beard in modern over-ear headphones speaks into a microphone. Dark-grey background, strong light-and-shadow contrast.
- Framing / light: extreme close-up; eye level; tripod / stand, fixed; night / low-light ambient, no dedicated fill; key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.3:1 (0.4 stops); hard light (clear shadow edge)
- Text track (captions / bottom): 打脱牙和血吞 / 长沙骂完江西骂
- Remake: talking avatar: clone / synthesize the voice-over first, then drive an avatar model from the portrait + audio
- First-frame image prompt: close-up, an ancient-Chinese-style white-bearded elder, face covered in wrinkles, deep gaze, modern black over-ear monitor headphones on his head, a professional microphone in front of him. Plain dark-grey background, single hard light from the left, high contrast, cinematic texture, 8k resolution, extremely lifelike skin texture.
- Video prompt: the elder speaks into the microphone, mouth opening and closing naturally, slight natural head sway, body, headphones and microphone completely still.
### #51 01:17.292–01:20.208 · Talking avatar + code / editor overlays (captions, graphic sticker)

- Probabilities: talking avatar 55%, AI-generated video 36%, 3D rendering 9% (fused)
- Text on objects in the frame (not post captions): C
- Material: AI-generated
- Likely tool: LivePortrait / Hedra (base image generated with Midjourney)
- Face covers 15% of the frame and appears in 100% of sampled frames: a close shot of a person, flat blocks mostly from walls / clothing, rendering features down-weighted
- Photo / video texture: noise σ=0.16, 35 colors, flat blocks 33%
- Per-frame sharpness oscillates periodically (period None frames, correlation 0.00): the picture went through frame interpolation / rate conversion; the original frame rate was lower
- Duplicate frames follow an interpolated pattern (0%, period None): source was 24/25 fps then transcoded, typical of AI video, 3D / animation renders or film footage
- [VLM] Torso and background completely still; only the lip shapes and the head sway slightly with the audio
- [VLM] An AI composite composition: Qing official robe with modern studio headphones and a condenser mic
- [VLM] Slight driven stretching marks at the edges of the mouth and where it meets the beard
- Picture: an elder in a Qing official robe and monitor headphones raps into a microphone, head swaying slightly with the rhythm; dark studio medium close-up.
- Framing / light: close-up; eye level; tripod / stand, fixed; night / low-light ambient, no dedicated fill; key front left; contrast about 1.5:1 (0.6 stops); hard light (clear shadow edge)
- Text track (captions / bottom): 长沙骂完江西骂 / 岳州败靖港败湖口败
- Text track (text / bottom): C
- Remake: talking avatar: clone / synthesize the voice-over first, then drive an avatar model from the portrait + audio
- First-frame image prompt: photoreal portrait photography, a Qing-dynasty elder resembling Zeng Guofan, grey-white moustache and long goatee, in Qing court dress with prayer beads, wearing professional black monitor headphones, a podcast microphone set up in front of him, plain dark-grey background, high-contrast cinematic studio top light, vertical medium close-up.
- Video prompt: the elder faces the microphone lip-syncing the rap, head swaying slightly with the pace, serious expression, body and shoulders still, fixed camera, photoreal dark tones.
### #52 01:20.208–01:21.208 · AI-generated video

- Probabilities: AI-generated video 52%, live footage 28%, talking avatar 7% (fused)
- Material: AI-generated
- Likely tool: Midjourney (base image) + Hedra / HeyGen / CapCut avatar
- Low-light frame: 37% of the area is near-black but grainy (not a solid fill), flat blocks in the highlights only 6%, and there is a face: the flat blocks / few colors come from crushed shadows, so they are not counted as rendering features
- Photo / video texture: noise σ=0.30, 38 colors, flat blocks 21%
- [VLM] Extremely sharp skin texture (pores, wrinkles) with the typical Midjourney V6 hyper-real style
- [VLM] Motion is limited to the mouth opening and closing and slight head sway; body and background are completely still, consistent with a single-image audio-driven avatar
- [VLM] The beard may show slight non-physical deformation as the mouth moves
- Picture: close-up of a white-haired, long-bearded elder in over-ear headphones speaking into a microphone. Plain dark-grey background, high-contrast light bringing out the weathered face.
- Framing / light: extreme close-up; eye level; tripod / stand, fixed; night / low-light ambient, no dedicated fill; key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.3:1 (0.4 stops); soft light (almost no shadow edge)
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: close-up of a white-haired Asian elder with a long white beard, wearing black over-ear headphones, a black microphone in front of him. Plain dark-grey background. Ultra-realistic, cinematic light, high contrast, rich detail in facial wrinkles and pores, key light from the left.
- Video prompt: the elder speaks into the microphone, natural mouth shapes, slight natural head sway, focused gaze, facial features kept stable.
### #53 01:21.208–01:25.458 · Talking avatar + code / editor overlays (captions)

- Probabilities: talking avatar 58%, AI-generated video 38%, live footage 3% (fused)
- Material: AI-generated
- Likely tool: LivePortrait / SadTalker / Hedra
- Face covers 25% of the frame and appears in 100% of sampled frames: a close shot of a person, flat blocks mostly from walls / clothing, rendering features down-weighted
- Photo / video texture: noise σ=0.23, 35 colors, flat blocks 28%
- Per-frame sharpness oscillates periodically (period None frames, correlation 0.00): the picture went through frame interpolation / rate conversion; the original frame rate was lower
- Duplicate frames follow an interpolated pattern (0%, period None): source was 24/25 fps then transcoded, typical of AI video, 3D / animation renders or film footage
- [VLM] Body and clothing completely still; only lips and head show small driven deformation
- [VLM] The beard and the area around the lips have the typical blended edges of audio-driven avatar lip-sync
- [VLM] The base image has a strong AI-portrait look; pores and deep wrinkles read hyper-real
- Picture: a white-haired, long-bearded elder in headphones recites facing the microphone; fixed camera, dark studio side light.
- Framing / light: extreme close-up; eye level; tripod / stand, fixed; night / low-light ambient, no dedicated fill; key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.1:1 (0.2 stops); hard light (clear shadow edge)
- Text track (captions / bottom): 口一口和血吞 / 一口一口和血吞
- Remake: talking avatar: clone / synthesize the voice-over first, then drive an avatar model from the portrait + audio
- First-frame image prompt: close-up portrait, a weather-beaten elderly East Asian Taoist, bald, grey moustache and a very long white goatee, professional black monitor headphones, a black Chinese robe with knotted buttons, cool side light, face carved with deep wrinkles, plain dark-grey background, cinematic texture, ultra-realistic detail.
- Video prompt: the elderly man in headphones recites the lines seriously into the microphone, lips opening and closing on the lyrics, only the faintest nod and turn of the head, firm deep gaze, fixed close-up.
### #54 01:25.458–01:27.125 · 3D rendering

- Probabilities: 3D rendering 58%, AI-generated video 24%, code / template rendering 12% (fused)
- Material: rendered by the producer
- Likely tool: Midjourney + CapCut (JianYing)
- Rendered texture: flat color blocks 30%, 95% of pixels use only 27 colors, horizontal / vertical straight edges 8%
- Per-frame sharpness oscillates periodically (period 4 frames, correlation 0.50): the picture went through frame interpolation / rate conversion; the original frame rate was lower
- Duplicate frames follow an interpolated pattern (0%, period None): source was 24/25 fps then transcoded, typical of AI video, 3D / animation renders or film footage
- [VLM] No independent motion inside the frame (no water ripples, no rope swaying), only an extremely slow push / pan of the whole frame (Ken Burns effect), consistent with still-image processing.
- Picture: close-up, a dilapidated wooden boat moored on dark, fog-covered water, two oars and a coil of rope inside; a gloomy, minimalist mood.
- Framing / light: close-up; high angle; moving camera (gimbal / handheld pan); night / low-light ambient, no dedicated fill; key from the left of frame (side light); contrast about 5.4:1 (2.4 stops); soft light (wide shadow transition)
- Remake: 3D rendering: first/last-frame AI generation gives an approximation; for precise multi-angle work go 3D modeling + Blender render
- First-frame image prompt: close-up, a dilapidated wooden boat moored on dark, fog-covered water, two wooden oars and a coil of rough rope inside. Minimalist, dark mood, cinematic light, cool tones, 8k resolution.
- Video prompt: the camera pushes forward slowly, the scene stays still, showing the details of the dilapidated wooden boat, oars and rope, with dark fog-covered water behind; the mood is gloomy and quiet.
### #55 01:27.125–01:28.333 · AI-generated video + code / editor overlays (graphic sticker)

- Probabilities: AI-generated video 80%, 3D rendering 18%, 2D animation 0% (fused)
- Material: AI-generated
- Likely tool: Kling / Runway
- Per-frame sharpness oscillates periodically (period 5 frames, correlation 0.56): the picture went through frame interpolation / rate conversion; the original frame rate was lower
- Duplicate frames follow an interpolated pattern (0%, period None): source was 24/25 fps then transcoded, typical of AI video, 3D / animation renders or film footage
- [VLM] The water moves in a regular, viscous way, lacking real chaos
- [VLM] Reflections are smooth and perfect, with an AI look
- [VLM] The curve of the horizon is unnatural
- Picture: close-up of dark water, ripples rocking, overcast sky, slow camera push.
- Framing / light: medium close-up; eye level, slightly high; gimbal (simulated); outdoor overcast / shade soft light; key front left; contrast about 1.6:1 (0.6 stops); soft light (wide shadow transition)
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: black-and-white dark style, rippled water surface, gloomy sky, faint light through the clouds, curved horizon, minimalist cinematic feel.
- Video prompt: black-and-white dark water, ripples rocking slowly, gloomy sky, light and shadow flowing with the waves, slow camera push.
### #56 01:28.333–01:30.750 · AI-generated video + code / editor overlays (text labels)

- Probabilities: AI-generated video 77%, live footage 8%, talking avatar 7% (fused)
- Material: AI-generated
- Likely tool: Kling
- Low-light frame: 62% of the area is near-black but grainy (not a solid fill), flat blocks in the highlights only 0%, and there is a face: the flat blocks / few colors come from crushed shadows, so they are not counted as rendering features
- Photo / video texture: noise σ=0.52, 36 colors, flat blocks 9%
- Per-frame sharpness oscillates periodically (period 4 frames, correlation 0.34): the picture went through frame interpolation / rate conversion; the original frame rate was lower
- Duplicate frames follow an interpolated pattern (0%, period None): source was 24/25 fps then transcoded, typical of AI video, 3D / animation renders or film footage
- [VLM] Finger joints, skin folds and the beard show slight AI smoothing, blending and drift
- [VLM] The hand covering the right eye barely moves; the motion is mainly a very gentle camera push and slight facial movement
- [VLM] A typical hyper-real cinematic frame generated from an AI image (image-to-video)
- Picture: a white-bearded elder in a Qing official robe covers his right eye with his right hand, looking old and weary; the camera pushes in slowly; the setting is dim and heavy.
- Framing / light: close-up; eye level; tripod / stand, fixed; night / low-light ambient, no dedicated fill; key front left; contrast about 1.9:1 (0.9 stops); hard light (clear shadow edge)
- Text track (text / bottom): 同治九年右眼失明
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: a late-Qing elder, wrinkled face, pale long beard, wearing a black Qing official robe with a subtle pattern, a gaunt aged right hand covering his right eye, expression pained and weary, faint side light, cinematic texture, ultra-realistic detail, cool tones, vertical
- Video prompt: the elder keeps his right hand over his right eye, fingers trembling slightly, chest rising and falling faintly as he breathes, the camera pushes in slowly to a close-up of his face, the whole setting dim and oppressive.
### #57 01:30.750–01:31.417 · AI-generated video

- Probabilities: AI-generated video 53%, live footage 27%, talking avatar 7% (fused)
- Material: AI-generated
- Likely tool: LivePortrait / SadTalker / HeyGen
- Low-light frame: 44% of the area is near-black but grainy (not a solid fill), flat blocks in the highlights only 6%, and there is a face: the flat blocks / few colors come from crushed shadows, so they are not counted as rendering features
- Photo / video texture: noise σ=0.29, 36 colors, flat blocks 25%
- [VLM] A static AI portrait with lip-sync driving; body and headphones completely still
- [VLM] Slight stretching artifacts in the beard as the mouth opens and closes
- [VLM] Faint head displacement; the motion is mostly confined to the mouth region
- Picture: facial close-up of a white-bearded elder in headphones speaking to the camera, plain cool-toned studio background, the camera pushing in very slightly.
- Framing / light: extreme close-up; eye level; tripod / stand, fixed; night / low-light ambient, no dedicated fill; key front right; contrast about 2.0:1 (1.0 stop); soft light (wide shadow transition)
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: close-up, a weather-beaten old Chinese Taoist wearing modern over-ear headphones, long white beard, deep serious gaze, looking straight into the camera, dark Taoist robe, plain dark-grey studio background, cinematic photoreal, low saturation, cool soft light.
- Video prompt: frontal close-up, the old man in headphones speaks seriously to the camera, lips opening and closing with the speech, micro-expressions shifting, slight natural head movement, body and background still, the camera pushes in slowly.
### #58 01:31.417–01:33.333 · AI-generated video + code / editor overlays (text labels)

- Probabilities: AI-generated video 90%, live footage 8%, stop motion 0% (fused)
- Material: AI-generated
- Likely tool: Midjourney + Kling
- Per-frame sharpness oscillates periodically (period 6 frames, correlation 0.10): the picture went through frame interpolation / rate conversion; the original frame rate was lower
- Duplicate frames follow an interpolated pattern (0%, period None): source was 24/25 fps then transcoded, typical of AI video, 3D / animation renders or film footage
- [VLM] Where the elder's hand meets the eye socket there is the AI-specific blending and slight warping
- [VLM] Beard and skin texture show a faint AI flowing / boiling during the slow push
- [VLM] Extremely sculpted high-contrast cinematic wrinkle texture, typical Midjourney style
- Picture: a white-haired, long-bearded elder closes his eyes and rubs his temple, looking dizzy and pained; the camera pushes in slowly.
- Framing / light: close-up; eye level; moving camera (gimbal / handheld pan); night / low-light ambient, no dedicated fill; key front left; contrast about 2.0:1 (1.0 stop); medium softness
- Text track (text / bottom): 床在转头晕个不停
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: close-up, an ancient Chinese elder with white hair and a pale long beard, deeply wrinkled, one hand with prominent veins covering his right eye and forehead, looking pained and dizzy, dark long robe, low-saturation dark tones, side light sculpting the facial texture, cinematic, high-detail real texture.
- Video prompt: the camera pushes in slowly on the elder's face; he keeps his hand pressed to his forehead, brow slightly furrowed, faint breathing, the whole body still with only tiny movement, dark cinematic mood.
### #59 01:33.333–01:34.000 · AI-generated video

- Probabilities: AI-generated video 76%, live footage 15%, talking avatar 7% (fused)
- Material: AI-generated
- Likely tool: Midjourney + Kling
- Low-light frame: 21% of the area is near-black but grainy (not a solid fill), flat blocks in the highlights only 1%, and there is a face: the flat blocks / few colors come from crushed shadows, so they are not counted as rendering features
- Photo / video texture: noise σ=0.50, 43 colors, flat blocks 6%
- [VLM] Pores and deep wrinkles have the high-density synthetic look typical of Midjourney
- [VLM] The frame has only very slight drift and local micro-motion, lacking natural breathing and blinking
- [VLM] The boundary between beard and hairline looks slightly over-sculpted with slight edge blending
- Picture: extreme close-up of an elderly Asian man's face, gaze resolute and deep; the camera pushes forward slowly; high-contrast studio lighting.
- Framing / light: extreme close-up; eye level; tripod / stand, fixed; key from front side + fill (standard setup); key front right; contrast about 1.8:1 (0.8 stops); soft light (wide shadow transition)
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: frontal close-up of a weather-beaten elderly East Asian man, deep wrinkles across the face, grey-white moustache and goatee, stern cold gaze, wearing a black headband / headphones, plain dark-grey background, high-contrast cinematic studio portrait lighting, extremely high detail.
- Video prompt: the frame pushes forward slowly and steadily by a small amount; the elder holds a stern, cold stare, his face drifting with extremely faint breathing, eyes firm and unmoving.
### #60 01:34.000–01:39.208 · AI-generated video + code / editor overlays (captions)

- Probabilities: AI-generated video 46%, live footage 42%, talking avatar 7% (fused)
- Material: AI-generated
- Low-light frame: 34% of the area is near-black but grainy (not a solid fill), flat blocks in the highlights only 0%, and there is a face: the flat blocks / few colors come from crushed shadows, so they are not counted as rendering features
- Photo / video texture: noise σ=0.56, 56 colors, flat blocks 1%
- [VLM] The embroidery of the Qing first-rank crane badge is fine and accurate; the court necklace and official hat look real
- [VLM] The elder's hand skin, age spots and joint anatomy are natural; the table reflection follows physical optics
- [VLM] The foreground figure picks up and puts down the document fluidly; physical interaction is real
- [VLM] None of the texture boiling, finger deformation or flicker common in AI video
- [claude visual review] The same AI character now in a Qing official robe, in a Qing negotiation-table set: a dramatized AI-generated scene
- [claude visual review] Light, grain and the character match the AI shots before and after
- Picture: at a long Qing negotiation table, a white-bearded old official in a first-rank robe stares heavily; the backs of Westerners and document handling in the foreground; cool side light, slight push.
- Framing / light: medium close-up; eye level; gimbal; key from front side + fill (standard setup); key front right; contrast about 1.6:1 (0.7 stops); soft light (wide shadow transition)
- Text track (captions / bottom): 带着病被派去天津 / 案子一结卖国贼成了我的名
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
- First-frame image prompt: film still, a white-haired, white-bearded elderly Qing official seated upright at a dark negotiation table, in an official hat and crane rank badge robe, weathered face and grave expression, the out-of-focus backs of Westerners in the foreground, cool side backlight, dark teal-grey tones, high-contrast cinematic texture.
- Video prompt: the elderly Qing official sits at the negotiation table staring heavily, both hands resting lightly on the table, a Westerner in the foreground holding a folded document, the camera pushes in slowly, the cold, solemn mood of a historical drama.
### #61 01:39.208–01:40.333 · AI-generated video + code / editor overlays (text labels)

- Probabilities: AI-generated video 57%, live footage 25%, talking avatar 8% (deterministic)
- Material: AI-generated
- Low-light frame: 53% of the area is near-black but grainy (not a solid fill), flat blocks in the highlights only 3%, and there is a face: the flat blocks / few colors come from crushed shadows, so they are not counted as rendering features
- Photo / video texture: noise σ=0.27, 36 colors, flat blocks 28%
- Framing / light: extreme close-up; moving camera (gimbal / handheld pan); night / low-light ambient, no dedicated fill; key front right; contrast about 1.6:1 (0.7 stops); soft light (wide shadow transition)
- Text track (text / middle): 10777
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
### #62 01:40.333–01:43.125 · AI-generated video + code / editor overlays (text labels, graphic sticker)

- Probabilities: AI-generated video 38%, 3D rendering 27%, live footage 18% (deterministic)
- Material: AI-generated
- Face covers 10% of the frame and appears in 100% of sampled frames: a close shot of a person, flat blocks mostly from walls / clothing, rendering features down-weighted
- Photo / video texture: noise σ=0.11, 30 colors, flat blocks 39%
- Framing / light: close-up; handheld; night / low-light ambient, no dedicated fill; key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.3:1 (0.4 stops); soft light (wide shadow transition)
- Text track (text / bottom): 湖广会馆挂我的匾
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
### #63 01:43.125–01:46.125 · AI-generated video + code / editor overlays (captions)

- Probabilities: AI-generated video 65%, 3D rendering 19%, live footage 6% (deterministic)
- Material: AI-generated
- Photo / video texture: noise σ=0.54, 69 colors, flat blocks 7%
- Per-frame sharpness oscillates periodically (period None frames, correlation 0.00): the picture went through frame interpolation / rate conversion; the original frame rate was lower
- Duplicate frames follow an interpolated pattern (0%, period None): source was 24/25 fps then transcoded, typical of AI video, 3D / animation renders or film footage
- Framing / light: medium close-up; moving camera (gimbal / handheld pan); night / low-light ambient, no dedicated fill; key front right; contrast about 1.6:1 (0.7 stops); hard light (clear shadow edge)
- Text track (captions / bottom): 老乡砸了烧成灰烟 / 外惭清议
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
### #64 01:46.125–01:47.917 · AI-generated video + code / editor overlays (text labels)

- Probabilities: AI-generated video 79%, talking avatar 8%, live footage 7% (deterministic)
- Material: AI-generated
- Low-light frame: 31% of the area is near-black but grainy (not a solid fill), flat blocks in the highlights only 0%, and there is a face: the flat blocks / few colors come from crushed shadows, so they are not counted as rendering features
- Photo / video texture: noise σ=0.40, 42 colors, flat blocks 15%
- Per-frame sharpness oscillates periodically (period 2 frames, correlation 0.01): the picture went through frame interpolation / rate conversion; the original frame rate was lower
- Duplicate frames follow an interpolated pattern (0%, period None): source was 24/25 fps then transcoded, typical of AI video, 3D / animation renders or film footage
- Framing / light: extreme close-up; moving camera (gimbal / handheld pan); night / low-light ambient, no dedicated fill; key front right; contrast about 1.6:1 (0.7 stops); soft light (wide shadow transition)
- Text track (text / bottom): 外惭清议
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
### #65 01:47.917–01:55.708 · AI-generated video + code / editor overlays (text labels)

- Probabilities: AI-generated video 60%, 3D rendering 24%, talking avatar 6% (deterministic)
- Material: AI-generated
- Motion beats within the shot: 108.46 s, 111.12 s, 112.96 s
- Face covers 7% of the frame and appears in 100% of sampled frames: a close shot of a person, flat blocks mostly from walls / clothing, rendering features down-weighted
- Photo / video texture: noise σ=0.17, 30 colors, flat blocks 33%
- Per-frame sharpness oscillates periodically (period 6 frames, correlation 0.01): the picture went through frame interpolation / rate conversion; the original frame rate was lower
- Duplicate frames follow an interpolated pattern (0%, period None): source was 24/25 fps then transcoded, typical of AI video, 3D / animation renders or film footage
- Framing / light: medium close-up; moving camera (gimbal / handheld pan); night / low-light ambient, no dedicated fill; key front right; contrast about 2.4:1 (1.2 stops); soft light (wide shadow transition)
- Text track (text / bottom): 打脱牙和血吞
- Text track (text / bottom): GA
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
### #66 01:55.708–01:59.208 · Still-image push / pan (Ken Burns)

- Probabilities: still-image push / pan 85%, AI-generated video 9%, screen recording / screenshot 2% (deterministic)
- Still source: unknown
- Material: to be confirmed; verify whether real: photo / image material
- The whole frame moves as a single rigid transform (inliers 100%, residual 0.03 px, no local motion) → still-image push / pan: zoom +1.8%/s, pan 9 px/s
- Photo / video texture: noise σ=0.51, 29 colors, flat blocks 2%
- Remake: still-image push / pan: reproduce exactly with one image + the measured zoom / pan parameters in local ffmpeg
### #67 01:59.208–02:01.583 · Still-image push / pan (Ken Burns) (design / rendered graphic)

- Probabilities: still-image push / pan 76%, AI-generated video 14%, screen recording / screenshot 4% (deterministic)
- Still source: graphic
- Material: rendered by the producer
- The whole frame moves as a single rigid transform (inliers 99%, residual 0.15 px, no local motion) → still-image push / pan: zoom +6.9%/s, pan 39 px/s
- Rendered texture: flat color blocks 26%, 95% of pixels use only 29 colors, horizontal / vertical straight edges 7%
- Remake: still-image push / pan: reproduce exactly with one image + the measured zoom / pan parameters in local ffmpeg
### #68 02:01.583–02:02.292 · Still-image push / pan (Ken Burns) (design / rendered graphic)

- Probabilities: still-image push / pan 83%, AI-generated video 10%, screen recording / screenshot 3% (deterministic)
- Still source: graphic
- Material: rendered by the producer
- The whole frame moves as a single rigid transform (inliers 100%, residual 0.08 px, no local motion) → still-image push / pan: zoom -0.3%/s, pan 4 px/s
- Rendered texture: flat color blocks 42%, 95% of pixels use only 16 colors, horizontal / vertical straight edges 22%
- Remake: still-image push / pan: reproduce exactly with one image + the measured zoom / pan parameters in local ffmpeg
### #69 02:02.292–02:04.208 · Still-image push / pan (Ken Burns) + code / editor overlays (text labels)

- Probabilities: still-image push / pan 80%, AI-generated video 12%, screen recording / screenshot 3% (deterministic)
- Still source: unknown
- Material: to be confirmed; verify whether real: photo / image material
- The whole frame moves as a single rigid transform (inliers 98%, residual 0.16 px, no local motion) → still-image push / pan: zoom +2.9%/s, pan 14 px/s
- Text track (text / bottom): 黄号下了水
- Remake: still-image push / pan: reproduce exactly with one image + the measured zoom / pan parameters in local ffmpeg
### #70 02:04.208–02:04.833 · AI-generated video + code / editor overlays (text labels)

- Probabilities: AI-generated video 40%, 3D rendering 23%, live footage 20% (deterministic)
- Material: AI-generated
- Face covers 21% of the frame and appears in 100% of sampled frames: a close shot of a person, flat blocks mostly from walls / clothing, rendering features down-weighted
- Photo / video texture: noise σ=0.30, 40 colors, flat blocks 25%
- Framing / light: extreme close-up; moving camera (gimbal / handheld pan)
- Text track (text / bottom): 黄号下了水
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
### #71 02:04.833–02:05.458 · 3D rendering + code / editor overlays (text labels)

- Probabilities: 3D rendering 50%, AI-generated video 24%, code / template rendering 12% (deterministic)
- Material: rendered by the producer
- Rendered texture: flat color blocks 22%, 95% of pixels use only 22 colors, horizontal / vertical straight edges 24%
- Framing / light: medium; moving camera (gimbal / handheld pan); night / low-light ambient, no dedicated fill; key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.3:1 (0.4 stops); soft light (almost no shadow edge)
- Text track (text / bottom): 黄号下了水
- Remake: 3D rendering: first/last-frame AI generation gives an approximation; for precise multi-angle work go 3D modeling + Blender render
### #72 02:05.458–02:07.083 · AI-generated video

- Probabilities: AI-generated video 83%, 3D rendering 5%, live footage 4% (deterministic)
- Material: AI-generated
- Low-light frame: 38% of the area is near-black but grainy (not a solid fill), flat blocks in the highlights only 6%, and there is a face: the flat blocks / few colors come from crushed shadows, so they are not counted as rendering features
- Photo / video texture: noise σ=0.32, 39 colors, flat blocks 21%
- Per-frame sharpness oscillates periodically (period None frames, correlation 0.00): the picture went through frame interpolation / rate conversion; the original frame rate was lower
- Duplicate frames follow an interpolated pattern (0%, period None): source was 24/25 fps then transcoded, typical of AI video, 3D / animation renders or film footage
- Framing / light: extreme close-up; moving camera (gimbal / handheld pan); night / low-light ambient, no dedicated fill; key front right; contrast about 1.5:1 (0.6 stops); medium softness
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
### #73 02:07.083–02:09.208 · 3D rendering + code / editor overlays (text labels)

- Probabilities: 3D rendering 37%, AI-generated video 29%, live footage 18% (deterministic)
- Material: rendered by the producer
- Framing / light: medium; moving camera (gimbal / handheld pan); night / low-light ambient, no dedicated fill; key from the left of frame (side light); contrast about 3.9:1 (2.0 stops); soft light (wide shadow transition)
- Text track (text / bottom): 幼童出洋的折子我签了
- Remake: 3D rendering: first/last-frame AI generation gives an approximation; for precise multi-angle work go 3D modeling + Blender render
### #74 02:09.208–02:10.125 · Still-image push / pan (Ken Burns) (design / rendered graphic) + code / editor overlays (text labels, graphic sticker)

- Probabilities: still-image push / pan 77%, AI-generated video 13%, screen recording / screenshot 4% (deterministic)
- Still source: graphic
- Material: rendered by the producer
- The whole frame moves as a single rigid transform (inliers 97%, residual 0.19 px, no local motion) → still-image push / pan: zoom -3.5%/s, pan 37 px/s
- Rendered texture: flat color blocks 39%, 95% of pixels use only 24 colors, horizontal / vertical straight edges 13%
- Text track (text / bottom): ?
- Remake: still-image push / pan: reproduce exactly with one image + the measured zoom / pan parameters in local ffmpeg
### #75 02:10.125–02:14.000 · AI-generated video + code / editor overlays (text labels)

- Probabilities: AI-generated video 59%, 3D rendering 25%, talking avatar 6% (deterministic)
- Material: AI-generated
- Face covers 12% of the frame and appears in 100% of sampled frames: a close shot of a person, flat blocks mostly from walls / clothing, rendering features down-weighted
- Photo / video texture: noise σ=0.10, 27 colors, flat blocks 40%
- Per-frame sharpness oscillates periodically (period None frames, correlation 0.00): the picture went through frame interpolation / rate conversion; the original frame rate was lower
- Duplicate frames follow an interpolated pattern (0%, period None): source was 24/25 fps then transcoded, typical of AI video, 3D / animation renders or film footage
- Framing / light: close-up; moving camera (gimbal / handheld pan); night / low-light ambient, no dedicated fill; key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.1:1 (0.1 stops); hard light (clear shadow edge)
- Text track (text / bottom): 船开那天我没等到
- Text track (text / middle): C
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
### #76 02:14.000–02:17.250 · AI-generated video + code / editor overlays (text labels)

- Probabilities: AI-generated video 60%, 3D rendering 24%, talking avatar 6% (deterministic)
- Material: AI-generated
- Face covers 23% of the frame and appears in 100% of sampled frames: a close shot of a person, flat blocks mostly from walls / clothing, rendering features down-weighted
- Photo / video texture: noise σ=0.22, 33 colors, flat blocks 30%
- Per-frame sharpness oscillates periodically (period 2 frames, correlation 0.01): the picture went through frame interpolation / rate conversion; the original frame rate was lower
- Duplicate frames follow an interpolated pattern (0%, period None): source was 24/25 fps then transcoded, typical of AI video, 3D / animation renders or film footage
- Framing / light: extreme close-up; moving camera (gimbal / handheld pan); night / low-light ambient, no dedicated fill; key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.1:1 (0.1 stops); soft light (almost no shadow edge)
- Text track (text / bottom): 通籍三十年官至极品
- Text track (text / middle): 大
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
### #77 02:17.250–02:18.875 · AI-generated video + code / editor overlays (graphic sticker)

- Probabilities: AI-generated video 62%, 3D rendering 22%, talking avatar 6% (deterministic)
- Material: AI-generated
- Face covers 28% of the frame and appears in 100% of sampled frames: a close shot of a person, flat blocks mostly from walls / clothing, rendering features down-weighted
- Photo / video texture: noise σ=0.30, 34 colors, flat blocks 27%
- Per-frame sharpness oscillates periodically (period 2 frames, correlation 0.21): the picture went through frame interpolation / rate conversion; the original frame rate was lower
- Duplicate frames follow an interpolated pattern (0%, period None): source was 24/25 fps then transcoded, typical of AI video, 3D / animation renders or film footage
- Framing / light: extreme close-up; moving camera (gimbal / handheld pan); night / low-light ambient, no dedicated fill; key front right; contrast about 1.5:1 (0.6 stops); medium softness
- Text track (text / middle): 大
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
### #78 02:18.875–02:22.333 · AI-generated video + code / editor overlays (text labels)

- Probabilities: AI-generated video 50%, live footage 32%, talking avatar 7% (deterministic)
- Material: AI-generated
- Low-light frame: 38% of the area is near-black but grainy (not a solid fill), flat blocks in the highlights only 3%, and there is a face: the flat blocks / few colors come from crushed shadows, so they are not counted as rendering features
- Photo / video texture: noise σ=0.40, 34 colors, flat blocks 18%
- Framing / light: extreme close-up; moving camera (gimbal / handheld pan); night / low-light ambient, no dedicated fill; key front right; contrast about 1.4:1 (0.5 stops); medium softness
- Text track (text / bottom): 学业一无所成
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
### #79 02:22.333–02:23.042 · AI-generated video + code / editor overlays (text labels, graphic sticker)

- Probabilities: AI-generated video 41%, 3D rendering 24%, live footage 18% (deterministic)
- Material: AI-generated
- Face covers 27% of the frame and appears in 100% of sampled frames: a close shot of a person, flat blocks mostly from walls / clothing, rendering features down-weighted
- Photo / video texture: noise σ=0.27, 34 colors, flat blocks 28%
- Framing / light: extreme close-up; moving camera (gimbal / handheld pan); night / low-light ambient, no dedicated fill; key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.3:1 (0.4 stops); soft light (almost no shadow edge)
- Text track (text / bottom): 学业一无所成
- Text track (text / middle): 大
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
### #80 02:23.042–02:24.000 · Still-image push / pan (Ken Burns) (design / rendered graphic) + code / editor overlays (graphic sticker)

- Probabilities: still-image push / pan 68%, screen recording / screenshot 15%, AI-generated video 12% (deterministic)
- Still source: graphic
- Material: rendered by the producer
- The whole frame moves as a single rigid transform (inliers 96%, residual 0.18 px, no local motion) → still-image push / pan: zoom +0.1%/s, pan 15 px/s
- Rendered texture: flat color blocks 38%, 95% of pixels use only 30 colors, horizontal / vertical straight edges 15%
- Remake: still-image push / pan: reproduce exactly with one image + the measured zoom / pan parameters in local ffmpeg
### #81 02:24.000–02:28.042 · 3D rendering + code / editor overlays (captions)

- Probabilities: 3D rendering 60%, AI-generated video 20%, code / template rendering 12% (deterministic)
- Material: rendered by the producer
- Rendered texture: flat color blocks 37%, 95% of pixels use only 29 colors, horizontal / vertical straight edges 16%
- Per-frame sharpness oscillates periodically (period 2 frames, correlation 0.02): the picture went through frame interpolation / rate conversion; the original frame rate was lower
- Duplicate frames follow an interpolated pattern (0%, period None): source was 24/25 fps then transcoded, typical of AI video, 3D / animation renders or film footage
- Framing / light: medium close-up; moving camera (gimbal / handheld pan); night / low-light ambient, no dedicated fill; key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.2:1 (0.3 stops); hard light (clear shadow edge)
- Text track (captions / bottom): 德行一无可许 / 这条,过了
- Text track (text / middle): 同茶
- Remake: 3D rendering: first/last-frame AI generation gives an approximation; for precise multi-angle work go 3D modeling + Blender render
### #82 02:28.042–02:29.167 · AI-generated video + code / editor overlays (captions)

- Probabilities: AI-generated video 49%, live footage 32%, talking avatar 7% (deterministic)
- Material: AI-generated
- Low-light frame: 27% of the area is near-black but grainy (not a solid fill), flat blocks in the highlights only 6%, and there is a face: the flat blocks / few colors come from crushed shadows, so they are not counted as rendering features
- Photo / video texture: noise σ=0.49, 33 colors, flat blocks 13%
- Framing / light: extreme close-up; moving camera (gimbal / handheld pan); night / low-light ambient, no dedicated fill; key frontal (from the camera direction, both sides of the subject equally bright); contrast about 1.0:1 (0.0 stops); soft light (almost no shadow edge)
- Text track (captions / bottom): 这条,过了。 / 这条,过了
- Remake: the original is AI-generated: take the original shot's first and last frames for first/last-frame generation, which reproduces composition and motion closely; to swap the subject, edit the first frame with an image model first
### #83 02:29.167–02:32.000 · Still-image push / pan (Ken Burns) + code / editor overlays (text labels)

- Probabilities: still-image push / pan 75%, AI-generated video 15%, screen recording / screenshot 3% (deterministic)
- Still source: unknown
- Material: to be confirmed; verify whether real: photo / image material
- The whole frame moves as a single rigid transform (inliers 100%, residual 0.14 px, no local motion) → still-image push / pan: zoom +0.1%/s, pan 2 px/s
- Low-light frame: 34% of the area is near-black but grainy (not a solid fill), flat blocks in the highlights only 8%, and there is a face: the flat blocks / few colors come from crushed shadows, so they are not counted as rendering features
- Photo / video texture: noise σ=0.47, 35 colors, flat blocks 20%
- Text track (text / middle): m
- Remake: still-image push / pan: reproduce exactly with one image + the measured zoom / pan parameters in local ffmpeg
### #84 02:32.000–02:38.125 · Still-image push / pan (Ken Burns)

- Probabilities: still-image push / pan 77%, AI-generated video 14%, screen recording / screenshot 3% (deterministic)
- Still source: unknown
- Material: to be confirmed; verify whether real: photo / image material
- Motion beats within the shot: 155.00 s
- The whole frame moves as a single rigid transform (inliers 94%, residual 0.15 px, no local motion) → still-image push / pan: zoom +5.3%/s, pan 25 px/s
- Remake: still-image push / pan: reproduce exactly with one image + the measured zoom / pan parameters in local ffmpeg
### #85 02:38.125–02:40.375 · 3D rendering + code / editor overlays (graphic sticker)

- Probabilities: 3D rendering 44%, AI-generated video 41%, code / template rendering 9% (deterministic)
- Material: rendered by the producer
- Per-frame sharpness oscillates periodically (period 4 frames, correlation 0.39): the picture went through frame interpolation / rate conversion; the original frame rate was lower
- Duplicate frames follow an interpolated pattern (0%, period None): source was 24/25 fps then transcoded, typical of AI video, 3D / animation renders or film footage
- Framing / light: medium close-up; moving camera (gimbal / handheld pan); night / low-light ambient, no dedicated fill; key front left; contrast about 1.6:1 (0.7 stops); soft light (wide shadow transition)
- Remake: 3D rendering: first/last-frame AI generation gives an approximation; for precise multi-angle work go 3D modeling + Blender render
### #86 02:40.375–02:44.958 · 3D rendering

- Probabilities: 3D rendering 46%, AI-generated video 37%, code / template rendering 11% (deterministic)
- Material: rendered by the producer
- Per-frame sharpness oscillates periodically (period 4 frames, correlation 0.64): the picture went through frame interpolation / rate conversion; the original frame rate was lower
- Duplicate frames follow an interpolated pattern (0%, period None): source was 24/25 fps then transcoded, typical of AI video, 3D / animation renders or film footage
- Framing / light: medium close-up; moving camera (gimbal / handheld pan); key from front side + fill (standard setup); key front right; contrast about 1.6:1 (0.6 stops); medium softness
- Remake: 3D rendering: first/last-frame AI generation gives an approximation; for precise multi-angle work go 3D modeling + Blender render
## Notes
- Deterministic forensics are reliable for "is it moving, is it a whole-image push, is the texture rendered, was there a 24→30 frame-rate conversion"; telling live footage, AI and 3D apart relies on the VLM and human review.
- Platform transcoding usually strips metadata; missing metadata does not mean there was none.