# Harvestr
> **One username in, every video they've ever posted, across 50+ sites out.**
Harvestr is a cross-platform video archival tool that probes dozens of video
hosting, cam-archive, and creator-economy sites for a single username, then
pulls down every video it finds — with a browser UI, an aggressive
downloader stack (aria2c + ffmpeg + curl fallback), content-based
deduplication, and an extensible custom-scraper framework for sites
`yt-dlp` doesn't cover.
## Screenshots
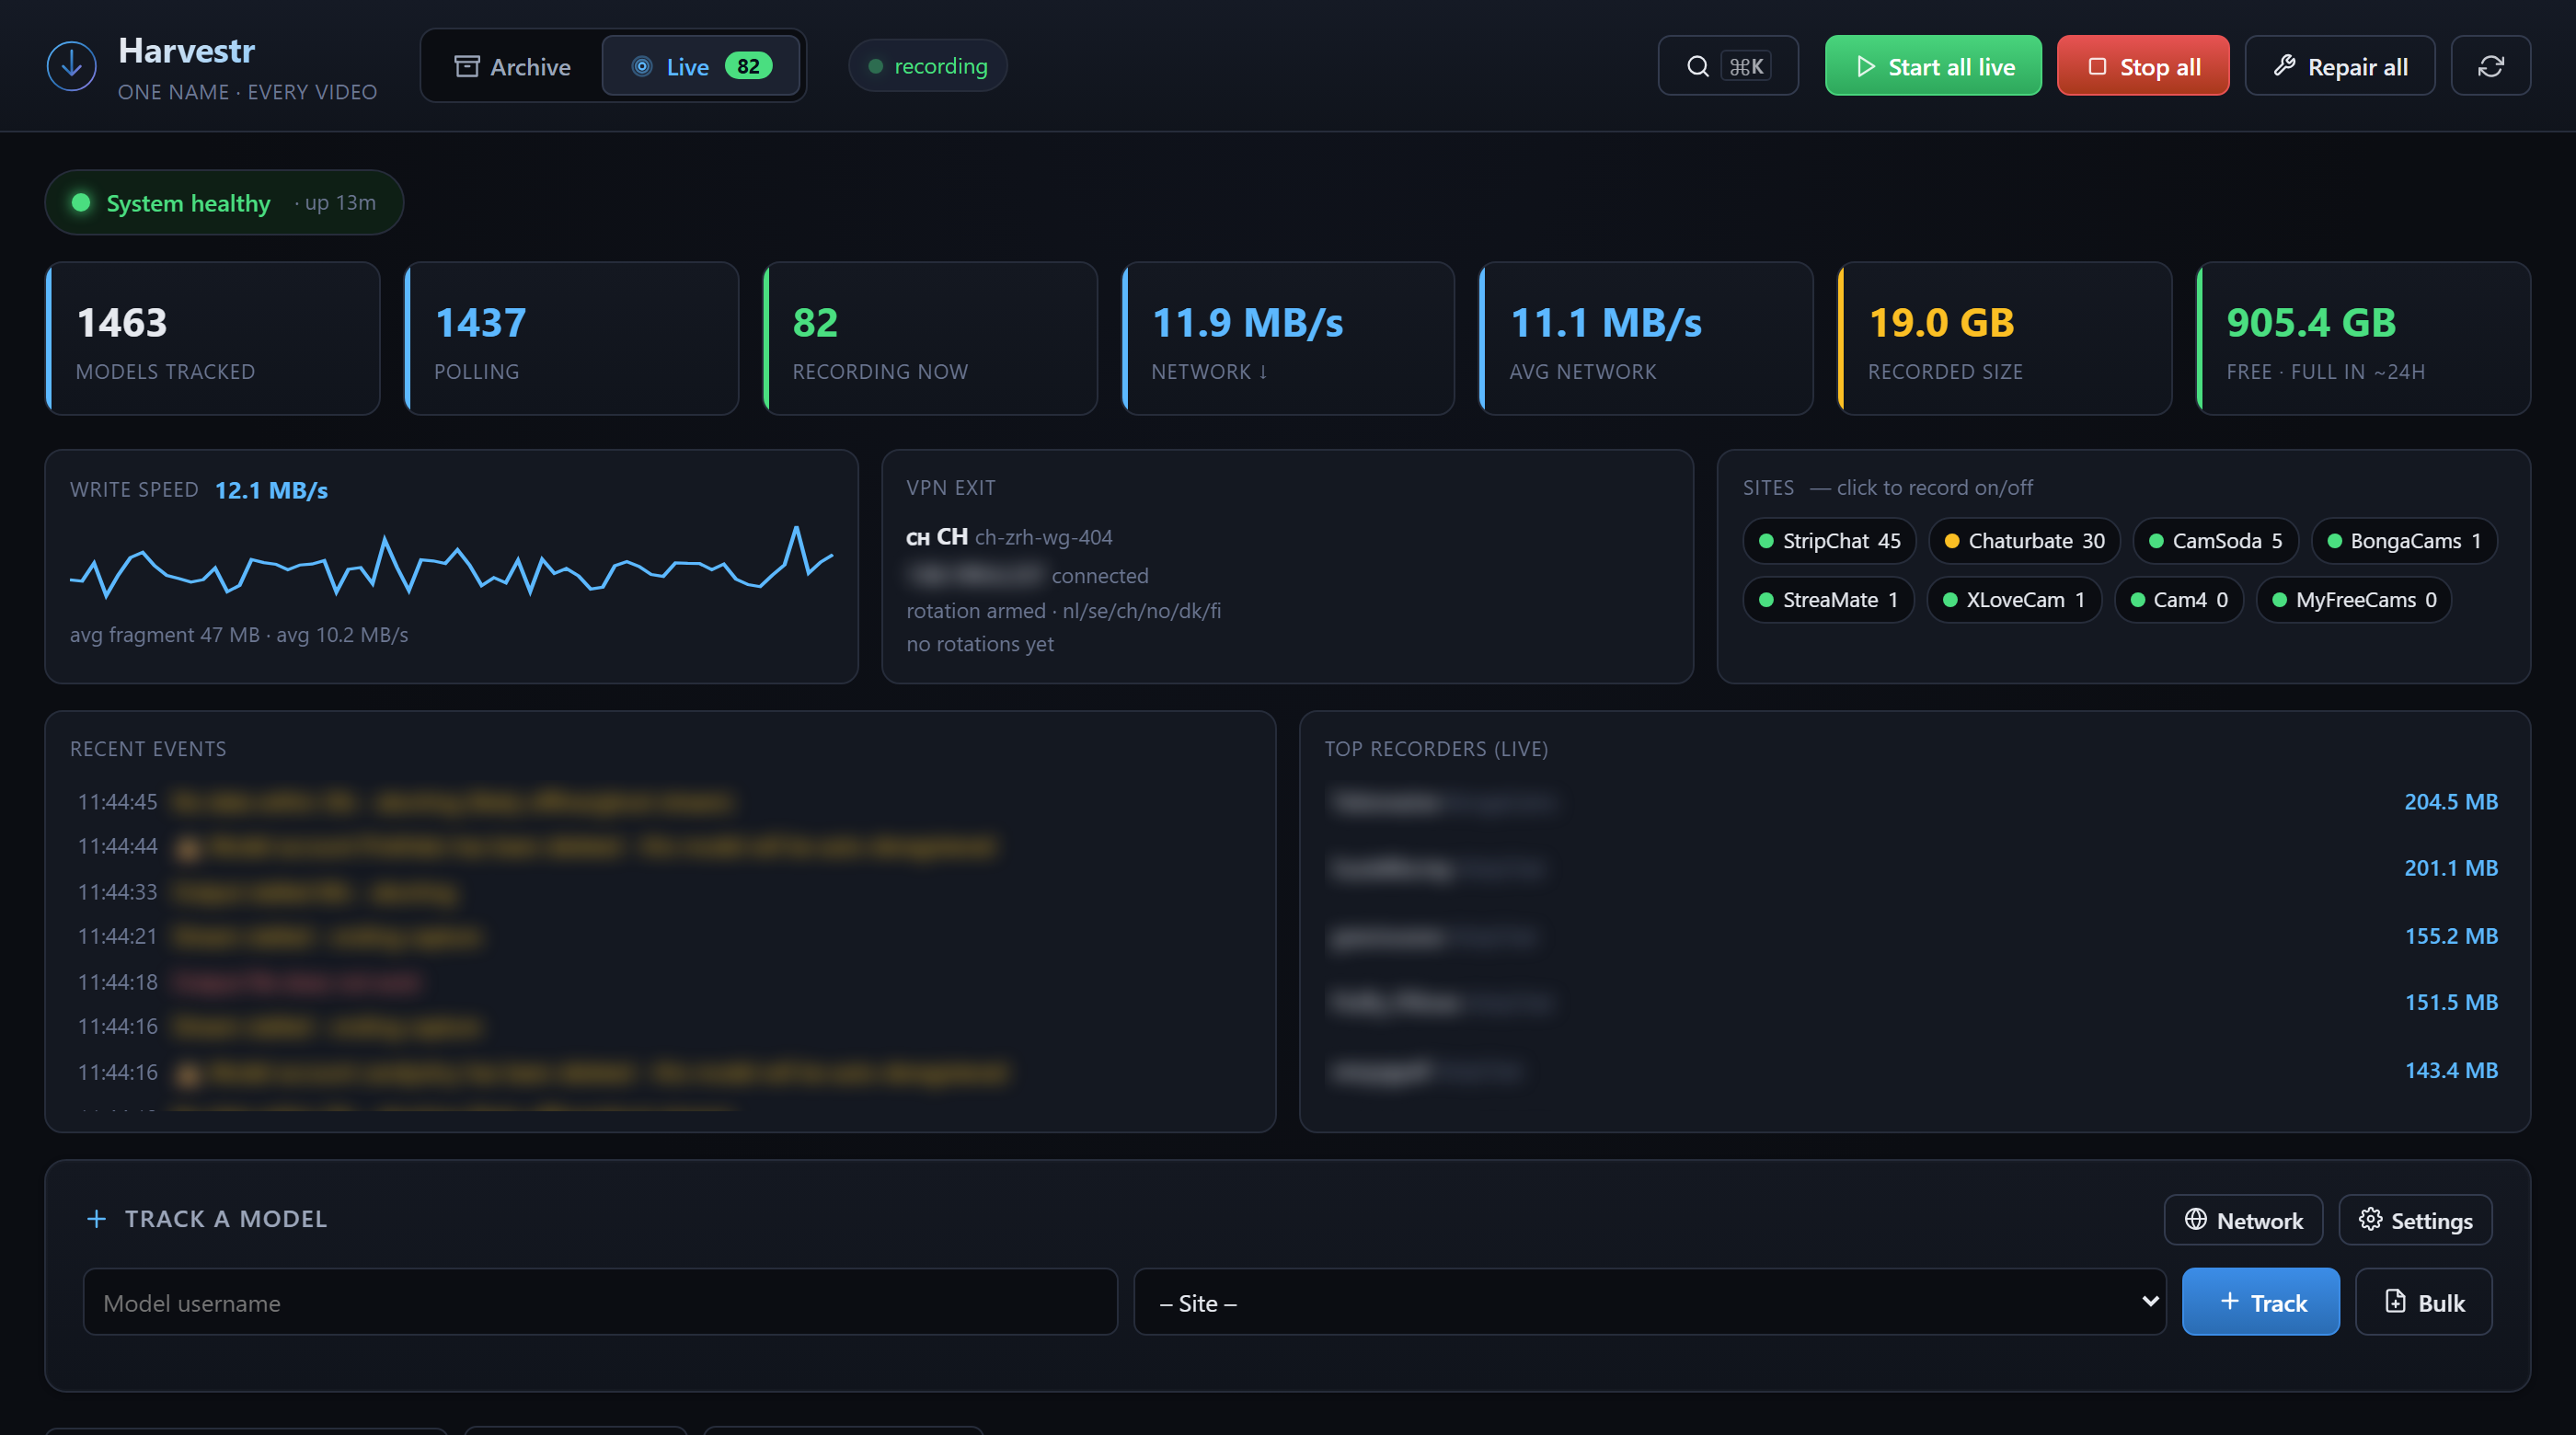
The Live dashboard, recording a real fleet — 1463 models tracked, 92 capturing
concurrently at 12 MB/s:
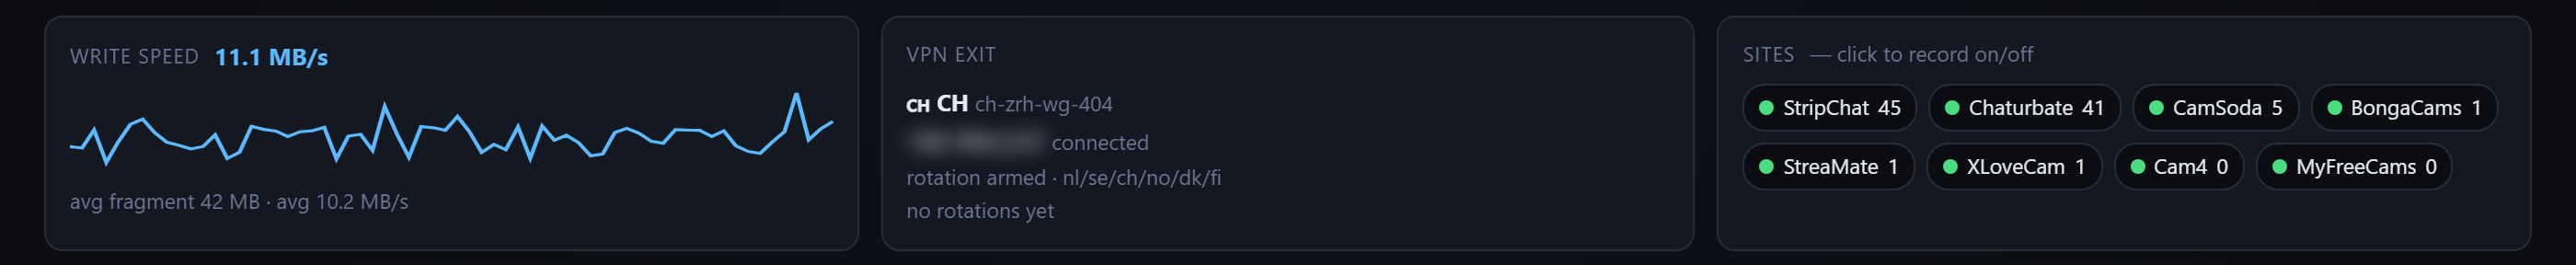
Monitoring row: write-speed sparkline, the current VPN exit (with auto-rotation
armed), and per-site switches. Clicking a site stops or resumes recording for
that whole site immediately — in-flight captures included, no restart:
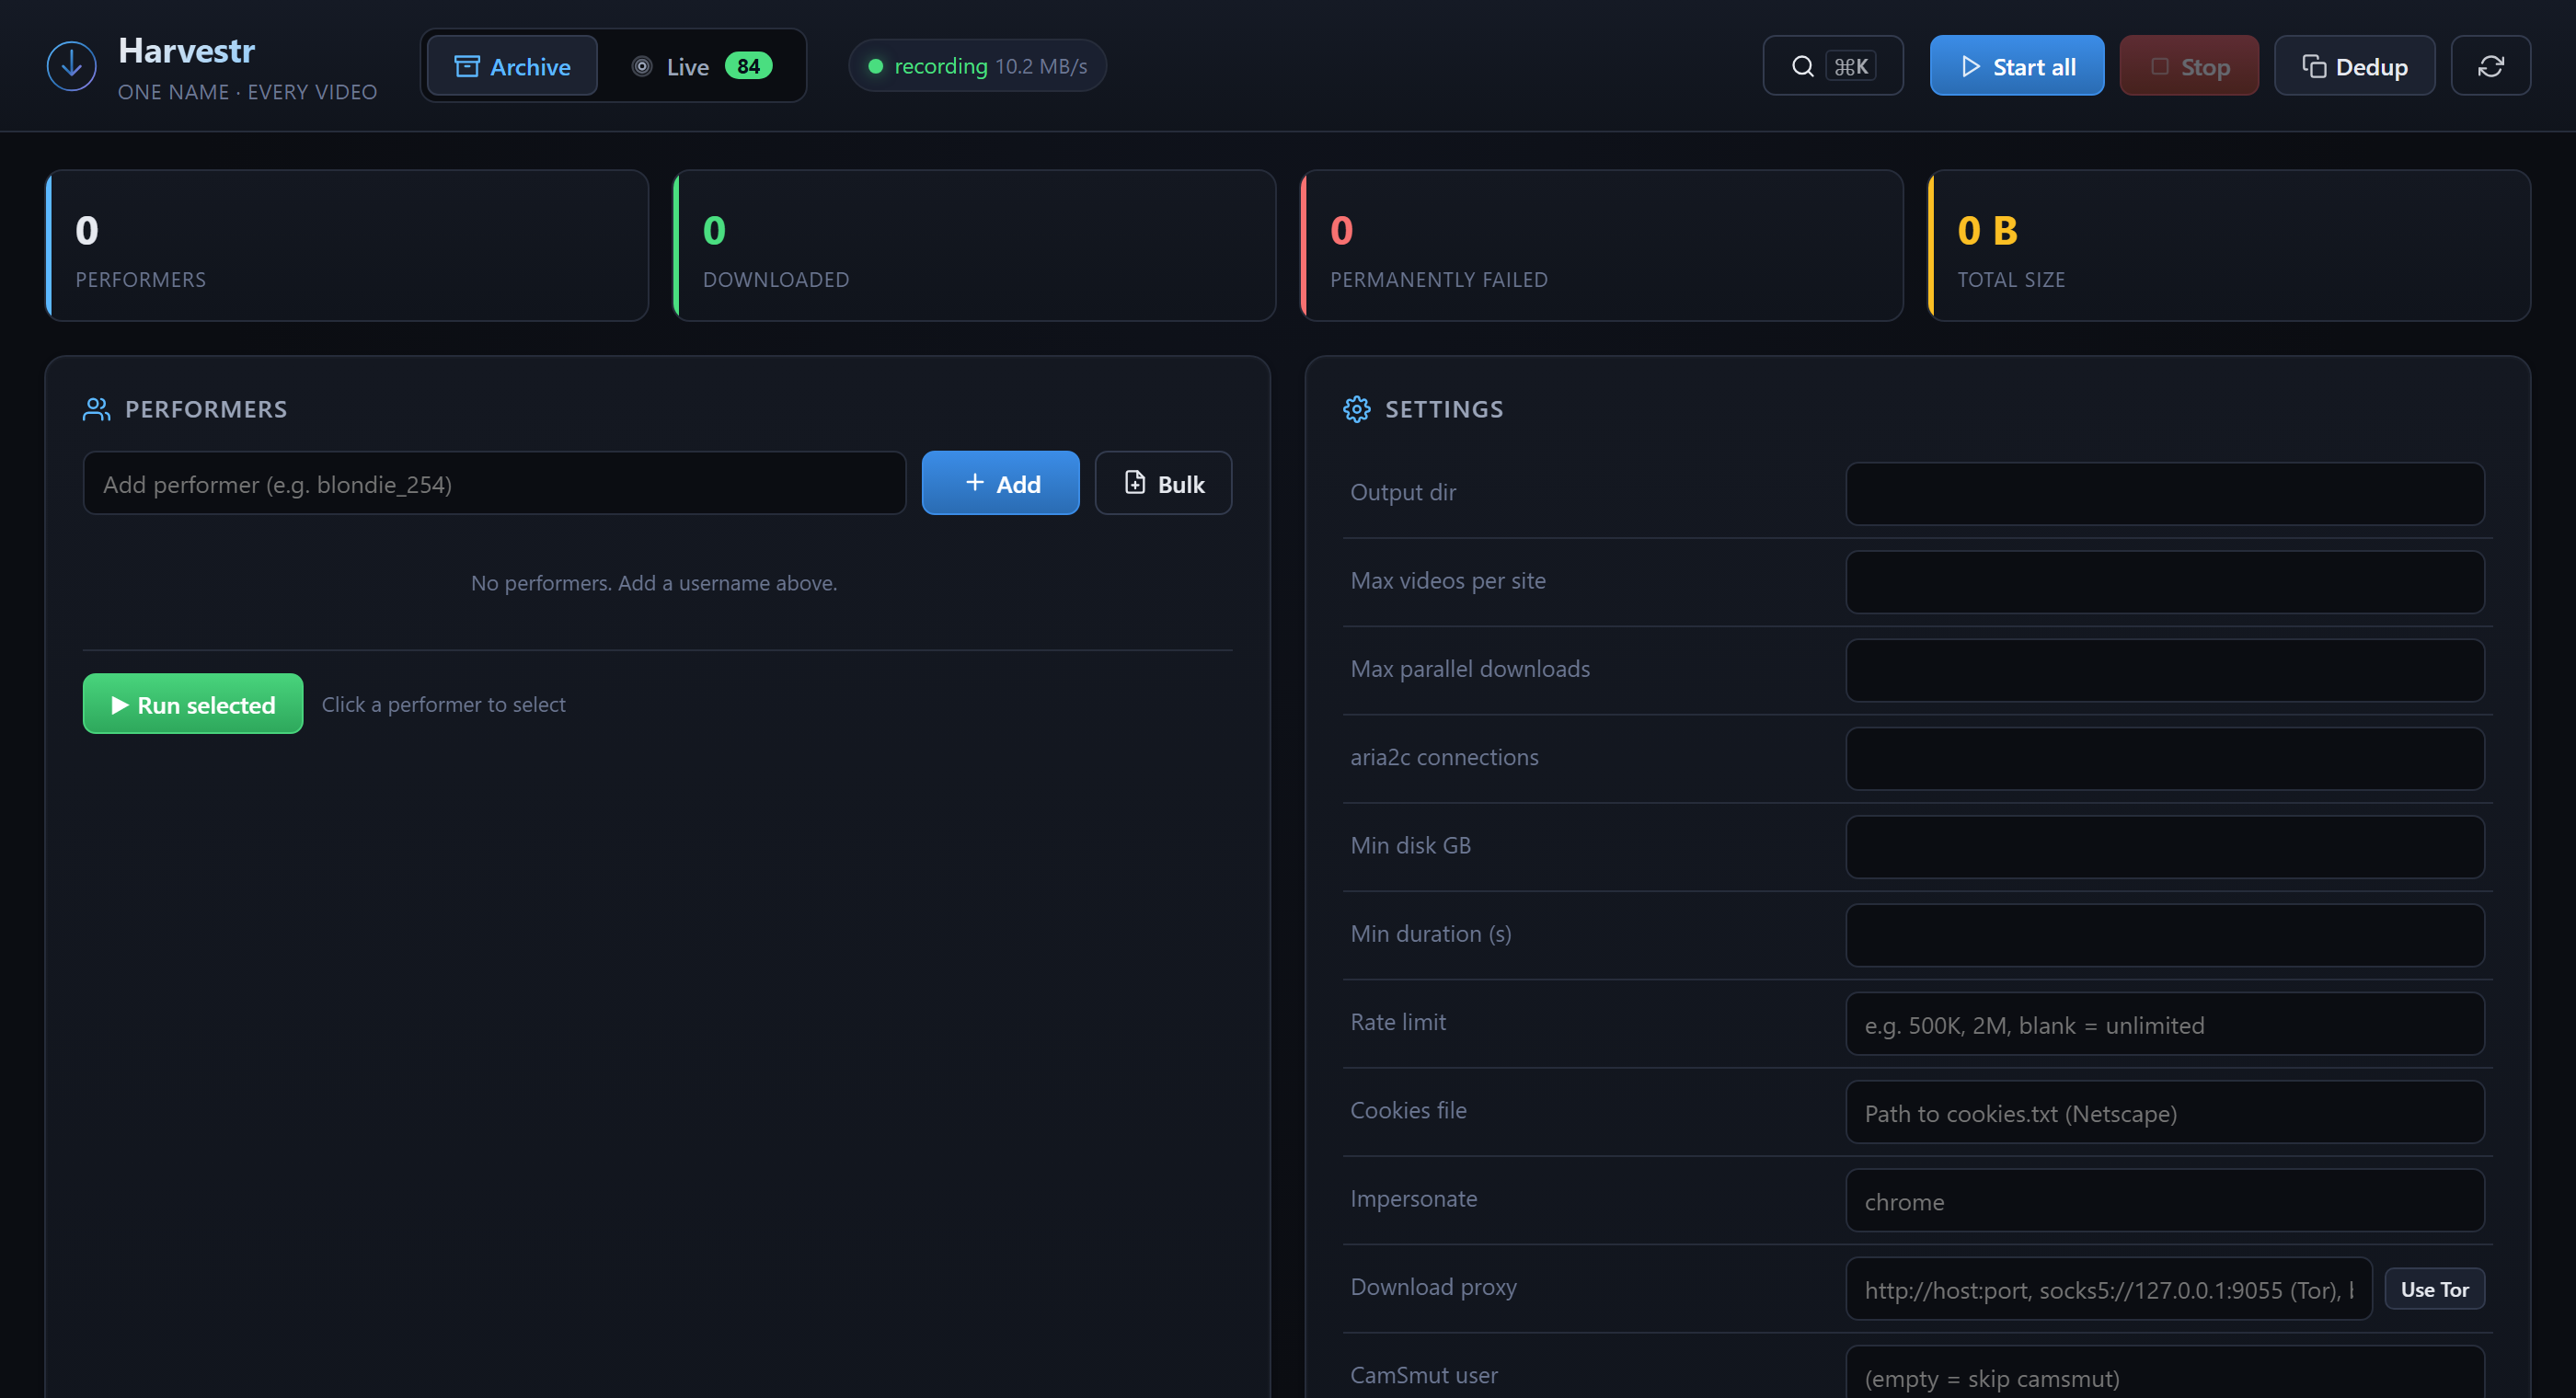
Archive mode — performers, per-run settings and the download controls:
Screenshots are from a live instance. Performer names, event text and the
VPN exit IP are blurred — the numbers and layout are otherwise untouched.
---
## Why
If you follow a creator and want a local archive of their work, their content
is usually scattered across 5-15 different sites: main platform,
cross-posted mirrors, archive sites, fan sites, leak sites, etc. Chasing
each site manually is tedious and you inevitably miss things, duplicate
downloads, or fall behind.
Harvestr solves this with one command:
```powershell
python universal_downloader.py alice_example
```
which fans out to 50+ sites in parallel, finds every profile/page for that
name, and downloads every video — skipping anything it already has.
## Features
| Capability | How |
|---|---|
| **1800+ sites via yt-dlp** | All mainstream + adult tube sites |
| **Custom scrapers for 25+ cam-archive + creator sites** | KVS mirror family, Coomer, Kemono, RedGifs, X.com, Reddit, Archivebate, Recordbate, Recu.me, CamCaps… |
| **Parallel probing** | 8-way concurrent site probing (~15 seconds for 50 sites) |
| **aria2c 16-connection downloads** | Multi-segment MP4 downloads at wire speed |
| **HLS / DASH / m3u8** | ffmpeg pipeline for fragmented streams |
| **Cloudflare bypass** | `curl_cffi` Chrome TLS fingerprint + `cloudscraper` fallback |
| **DDoS-Guard bypass** | `Accept: text/css` trick for Coomer / Kemono |
| **Cross-mirror dedup** | One video across 5 mirrors → downloaded once |
| **Content-based dedup** | Post-hoc sweep using size + head/tail SHA1 (99%+ accuracy, <50 ms per file) |
| **Cookie auth** | Netscape `cookies.txt` with per-site domain filtering |
| **Premium X.com (Twitter)** | GraphQL API with auth_token + ct0 cookies |
| **Web UI** | Flask dashboard with live log, start/stop, inline video preview |
| **Atomic state** | Thread-safe `history.json` / `failed.json`, Windows-safe |
| **Resumable** | Re-runs only download new videos; rolling window per site |
| **Dry-run mode** | See what would be downloaded without touching disk |
## Two modes: Archive & Live
Harvestr runs in **two complementary modes**, switchable with a single tab click
(or keyboard `2` / `1`) in the web UI:
### 📦 Archive mode (the default)
Given a username, fan out across 50+ sites to **find every video this person has
ever posted** and download the ones you don't already have. See the [Archive
section](#archive-mode) below.
### 🔴 Live mode (backed by vendored [StreaMonitor](https://github.com/lossless1/StreaMonitor))
Track cam models across **18 platforms** and auto-record the moment they go
live. Harvestr keeps a lightweight bot per model that polls the site every
5-30s; when status flips to `PUBLIC`, the HLS/RTMP stream is immediately
handed to ffmpeg and written to disk. Supported sites out-of-the-box:
| Site | Site | Site |
|---|---|---|
| Chaturbate | StripChat / StripChat VR | CamSoda |
| Cam4 | BongaCams | Flirt4Free |
| Cherry.tv | Streamate | MyFreeCams |
| ManyVids | FanslyLive | AmateurTV |
| CamsCom | DreamCam / DreamCam VR | SexChatHU |
| XLoveCam | | |
**Zero-setup** — StreaMonitor is vendored into `live_backend/streamonitor/`
and ships with Harvestr. Clone Harvestr, install `requirements.txt`, and the
Live tab lights up. No second repo to clone, no env var to set.
> GPL-3.0 notice: the vendored StreaMonitor code retains its original
> GPL-3.0 license (see `live_backend/LICENSE` and `live_backend/NOTICE.md`).
> Combined distributions of Harvestr + live_backend/ must comply with GPL-3.0.
> Harvestr's own code outside `live_backend/` remains MIT.
To point at a development checkout of StreaMonitor instead of the vendored
copy, set `HARVESTR_STREAMONITOR=` before launching `webui.py`.
**UI features:**
- Per-model cards with animated state dots (green pulse = recording, blue = connecting, purple = private, yellow = offline, red = problem)
- Filter by site, by status bucket, by username substring
- Sort by status / name / site / recorded size
- Live badge on the tab when any recording is active
- Bulk start/stop all
- Command palette (`Ctrl+K`) for quick actions across both tabs
**Scaling to 1000+ models — exit-IP rotation & proxy:**
At scale a single exit IP gets Cloudflare-flagged / rate-limited (Chaturbate is
the worst offender at 600+ models). Harvestr ships two complementary, **opt-in**
tools, configurable from a **Network** button in the Live tab (gear menu) or the
gitignored config files:
- **Mullvad VPN auto-rotation** — when a site rate-limits the current exit, a
*tiered* watchdog first **restarts** the affected bots on the same IP (most
limits are transient), and only **rotates** the Mullvad exit if it keeps
climbing. The Mullvad CLI is auto-detected; nothing is hard-coded to one
machine. There's a manual **Rotate exit now** button too.
- **Per-site residential proxy** — pin one site to a dedicated exit IP,
independent of the VPN, for a site that needs a clean residential IP. (Note:
the limit is *concurrent connections*, not bandwidth — a 100-thread proxy
can't feed Chaturbate's 600+ models, so CB stays on Mullvad.)
- **Rotation ride-through** — active recordings survive the rotation gap: sites
whose segments aren't IP-bound (Chaturbate) keep writing the **same file** on
the new IP; IP-bound sites (StripChat/doppiocdn) restart instantly for a fresh
token instead of stalling ~60 s.
Both config files (`vpn_config.json`, `site_proxies.json`) are **gitignored**, so
your credentials and working setup are never committed — the repo ships only
`*.example.json` templates. Full guide: **[VPN_SETUP.md](VPN_SETUP.md)**.
---
## Supported sites (partial list)
### Mainstream
YouTube · Dailymotion · Vimeo · Rumble · Twitch (VODs & clips) · Kick · Odysee ·
BitChute · Soundcloud · Reddit · **X.com / Twitter** (premium) · RedGifs
### Adult tubes (via yt-dlp)
PornHub · XVideos · xHamster · SpankBang · XNXX · YouPorn · Redtube ·
SpankWire · RedTube · 4Tube · TNA Flix · EPorner · Beeg · DrTuber · HotMovs ·
KeezMovies · ManyVids · Motherless · SxyPrn · Tube8
### Cam archive sites (custom scrapers)
camwhores.tv · camwhores.video · camwhores.co · camwhores.bz · camwhoresHD ·
camwhoresbay · camwhorescloud · camvideos.tv · camhub.cc · camwh.com · cambro.tv ·
camcaps.tv · camcaps.io · camstreams.tv · porntrex · camsrip · recordbate ·
archivebate · recu.me
### Creator / leak mirrors (no subscription needed)
- **Leakedzone.com** ✨ — OnlyFans / IG / Snap archive with HLS video streams
(served from the main domain — bypasses the Coomer CDN outage)
- **Fapello.com** ✨ — OnlyFans / IG / Snap archive with deterministic numbered posts
- **Coomer.st** — OnlyFans / Fansly / CandFans mirror (auto-recovers when their
CDN subnet comes back — see *Coomer outage* below)
- **Kemono.cr** — Patreon / Fanbox / Gumroad / SubscribeStar / Fantia / Boosty / Discord / DLSite mirror
- **RedGifs** — v2 API, auto-acquired temp token
> **⚠️ Coomer CDN outage (April 2026):** The `91.149.227.0/24` subnet that hosts
> Coomer's sharded video CDN (`n1-n4.coomer.st`) is globally null-routed. Metadata
> still works (profile pages, post counts, post titles) but video downloads time
> out. Harvestr has a **fast-fail pre-flight health check** that detects this
> and routes around Coomer for you — and the new **Leakedzone + Fapello**
> scrapers cover the same OnlyFans-archive content from unaffected infrastructure.
### Full list
```powershell
python universal_downloader.py --list-sites
```
---
## Install
### Dependencies
```powershell
# Required
pip install -U "yt-dlp[default,curl-cffi]" requests cloudscraper rich flask
# Recommended (16x faster downloads)
winget install aria2.aria2
# Required for HLS / m3u8 streams
# Download from https://www.gyan.dev/ffmpeg/builds/ and add to PATH
```
### Stealth browser tier (optional, auto-installed)
The browser-extraction code paths (`embed_extractors.py`,
`live_backend/streamonitor/utils/cf_broker.py`) prefer
[**patchright**](https://github.com/Kaliiiiiiiiii-Vinyzu/patchright) — a
Playwright fork with stealth patches that frequently lets invisible-managed
Cloudflare Turnstile auto-pass without a captcha service.
You don't need to install it manually. The first time the browser tier
runs and finds patchright missing, it will run **once** per machine:
```
pip install patchright
patchright install chromium # ~180 MB Chromium download
```
…then continue normally. The outcome is cached for the rest of the
process; subsequent calls hit the in-memory cache instantly. If the
install fails (offline, pip blocked, mirror down) the code falls back
to vanilla `playwright` silently — nothing breaks, you just lose the
stealth advantage on Cloudflare-protected hosts.
Forcing the install up-front is also fine:
```powershell
pip install patchright
patchright install chromium
```
Either way, the code auto-detects at import. On startup the log shows
which driver is in use (`Browser driver: patchright (stealth)` vs the
vanilla-playwright fallback).
### Clone
```powershell
git clone https://github.com/KevinStreetCoder/harvestr.git
cd harvestr
cp config.example.json config.json
```
---
## Quick start
### Web UI (recommended)
```powershell
python webui.py --port 7860
```
That ties the recorder to the terminal it was launched from — closing the
window stops it, mid-recording. For continuous recording use the launcher
instead, which starts it detached under `pythonw` (no console) so it survives
the terminal closing:
```powershell
.\start-harvestr.bat
.\stop-harvestr.bat
```
Both accept an optional port (`.\start-harvestr.bat 8080`). The launcher
refuses to start a second copy — two instances would restore the same tracked
fleet twice, write the same `live_models.json`, and record into the same
folders. Startup output goes to `logs\webui.out.log` / `logs\webui.err.log`,
since a detached process has no console to print a traceback to.
Open **http://127.0.0.1:7860** and you get:
- Performer management (add/remove by name)
- Per-site checkbox filter (or presets: **All** / **Custom only** / **yt-dlp only**)
- **Start** / **Stop** buttons with live log tail
- History table with inline video preview
- Failed / skipped table with reason codes
- One-click **Dedup** (content-based dupe scan)
- Auto-refresh every 2 seconds
### CLI
```powershell
# Download every video for one username across all sites
python universal_downloader.py alice_example
# Restrict to specific sites
python universal_downloader.py alice_example --sites coomer,kemono,xcom
# Dry-run (probe + enumerate, no downloads)
python universal_downloader.py alice_example --dry-run
# Run for every performer configured in config.json
python universal_downloader.py --all
# Show every supported site
python universal_downloader.py --list-sites
# Verbose / debug mode
python universal_downloader.py alice_example -v
```
### Storage management
The web UI's Archive tab now has a **Storage** card that shows:
- **Drive bar** — horizontal stacked chart of Harvestr archive / other files / free space
- **Free-space warning** — bar turns yellow under 10 GB free, red under 2 GB
- **Per-performer meter** — each performer is a row with a proportional fill bar, byte total, file count, and a ✕ button to wipe them
- **Cleanup tools**: "Prune older than…", "Free up space…" (prune oldest until N GB free), "Dedup"
All destructive ops are **2-step confirm** with dry-run preview:
```
Prune older than 90 days?
→ Found 23 files (would free 1.8 GB)
→ Delete them? [OK / Cancel]
```
### Programmatic API (also callable from the command palette, Ctrl+K)
| Endpoint | Method | Purpose |
|---|---|---|
| `/api/disk` | GET | Snapshot (cached 3 s) |
| `/api/disk/wipe` | POST | Remove every video for a performer (requires `confirm:true`) |
| `/api/disk/delete` | POST | Remove specific file paths |
| `/api/disk/prune_older` | POST | Remove files older than N days (dry-run by default; add `apply:true`) |
| `/api/disk/prune_to_free` | POST | Remove oldest until N GB free |
| `/api/disk/enforce_cap` | POST | Keep a performer's archive under N GB by deleting oldest |
History.json is kept in sync automatically — if you wipe a performer, their
entries disappear from history so they'll re-download cleanly on the next run.
## Content-based deduplication
```powershell
python dedupe.py # scan & report, no changes
python dedupe.py --apply # actually delete dupes
python dedupe.py --performer alice_example # limit to one
```
Dedup uses size + 64 KB head SHA1 + 64 KB tail SHA1, catching >99% of
real duplicates in <50 ms per file. Keeper chosen by longest filename
(most descriptive title), tiebreaker oldest mtime.
---
## Config
### `config.json`
```json
{
"output_dir": "C:\\...\\downloads",
"performers": ["alice_example", "bob_example"],
"enabled_sites": [],
"max_videos_per_site": 200,
"min_probe_entries": 1,
"max_parallel_probes": 8,
"max_parallel_downloads": 3,
"min_disk_gb": 5.0,
"use_aria2c": true,
"aria2c_connections": 16,
"rate_limit": "",
"cookies_from_browser": "",
"cookies_file": "",
"impersonate_target": "chrome",
"min_duration_seconds": 30.0,
"retries": 5,
"probe_timeout": 60,
"verbose": false
}
```
| Field | Purpose |
|---|---|
| `performers` | List used by `--all` and by the UI |
| `enabled_sites` | Empty = all sites. Otherwise a whitelist |
| `max_videos_per_site` | Rolling-window cap per performer per site per run |
| `max_parallel_probes` | How many site probes run concurrently |
| `max_parallel_downloads` | How many videos download concurrently |
| `min_disk_gb` | Pause if free space drops below this |
| `use_aria2c` | Toggle aria2c multi-segment downloader |
| `aria2c_connections` | Connections per file (16 = sweet spot) |
| `rate_limit` | Per-download cap, e.g. `"500K"` / `"2M"` |
| `cookies_from_browser` | `"chrome"` / `"firefox"` — picks up login cookies |
| `cookies_file` | Path to Netscape cookies.txt |
| `impersonate_target` | curl_cffi target, `"chrome"` is safe default |
| `min_duration_seconds` | Skip very short clips |
### Cookies
Some sites (recu.me, camwhores.tv private videos, camvault, X.com premium)
require login cookies. See **[COOKIES_SETUP.md](COOKIES_SETUP.md)** for the
full cookie-export walkthrough.
Sites that **do not** need auth:
Coomer, Kemono, RedGifs, Reddit (public), all KVS mirrors (tags/search pages).
Sites that benefit from auth:
X.com (premium = 10× daily quota), Recu.me (premium = unlimited plays).
Sites that absolutely need auth:
camwhores.tv "friend-locked" private videos, Recurbate premium downloads.
---
## Architecture
```
┌─────────┐ ┌──────────────────┐ ┌─────────────────────┐
│ CLI │ --> │ UniversalDown- │ --> │ probe_all_sites │
│ or │ │ loader │ │ (parallel fanout) │
│ UI │ │ (orchestrator) │ └─────┬───────────────┘
└─────────┘ └──────────────────┘ │
│
┌───────────────────────────────────────┴──────────┐
│ │
▼ ▼
┌────────────────┐ ┌─────────────────┐
│ yt-dlp flat │ │ custom scrapers │
│ extraction (29 │ │ (25+ classes) │
│ sites cfg'd) │ │ Coomer, Kemono, │
└───────┬────────┘ │ KVS family, ... │
│ └────────┬────────┘
└─────────────┬────────────────────────────────────┘
▼
┌────────────────┐
│ filter_new │ <-- cross-mirror dedup by video_id
│ (history + │ <-- URL / title filter (Macy Cartel etc.)
│ failed.json) │
└───────┬────────┘
▼
┌────────────────────────────┐
│ download_videos │
│ ┌──────────────────────┐ │
│ │ aria2c (MP4) │ │
│ │ ffmpeg (HLS/DASH) │ │
│ │ curl fallback │ │
│ └──────────────────────┘ │
└───────┬────────────────────┘
▼
┌────────────────┐
│ atomic history │
│ write + lock │
└────────────────┘
```
### Custom scraper contract
Every scraper in `custom_scrapers.py` implements four methods:
```python
class MyScraper(SiteScraper):
NAME = "mysite"
BASE_URL = "https://mysite.com"
CATEGORY = "adult" # or "mainstream", "archive"
COOKIE_DOMAIN = "mysite.com" # optional — filter cookies.txt per site
def probe(self, username) -> Optional[ProbeHit]:
"""Cheap test: does this user exist here? Return None or a hit."""
def enumerate(self, hit, username, limit) -> List[VideoRef]:
"""List all video refs (may or may not populate stream URL)."""
def extract_stream(self, ref) -> bool:
"""Resolve a ref's playable URL (m3u8 / direct mp4). Returns True on success."""
```
Register the class in `ALL_SCRAPER_CLASSES` at the bottom of
`custom_scrapers.py` and it's auto-picked-up by both CLI and UI.
### State files
Everything under `downloads/`:
- `history.json` — successful downloads, keyed by `{performer: {site|video_id: info}}`
- `failed.json` — failures, marked permanent after 3 attempts if dead / private
- `universal.log` — full debug log (also tailed live in the UI)
---
## Testing
Live end-to-end smoke test for the new scrapers (actually downloads one
small clip per working scraper):
```powershell
python tests/smoketest_new_scrapers.py
```
Expected output:
```
[PASS] Coomer (OnlyFans/Fansly mirror) PIPELINE OK (download skipped: CDN unreachable from this network)
[PASS] Kemono (Patreon/Fanbox mirror) PIPELINE OK (download skipped: CDN unreachable from this network)
[PASS] RedGifs OK user=toasted500 3.51 MB -> ...
[PASS] Reddit user OK user=GallowBoob 9.06 MB -> ...
[FAIL] X.com (needs auth cookies) (expected: no cookies.txt)
```
Coomer/Kemono produce valid URLs but their CDN shards (`n1-n4.coomer.st` /
equivalents) are blocked by some ISPs — use a VPN if the actual download step
times out.
---
## Bulk add / JSON import
Both the Archive and Live tabs have a **Bulk** button next to the `+ Add`
form. It opens a dialog with a textarea + JSON-upload button.
### Archive (performers)
Paste one username per line (or comma-separated). Lines starting with `#`
are treated as comments. Uploading a JSON file merges:
- `performers[]` (union, case-insensitive dedup)
- `enabled_sites[]`
- scalar settings like `max_videos_per_site`, `max_parallel_downloads`, etc.
Same schema as `config.example.json` — you can drop in another Harvestr
install's config.
### Live (cam models)
Paste one model per line. Format: `username Site [room_id]`.
```
alice_model Chaturbate
bob_model StripChat 987654 # with room id
charlie_m Cam4
```
Uploading a JSON file accepts the same schema as StreaMonitor's
`config.json`: an array of `{"username","site","room_id?"}` objects.
### Programmatic
- `POST /api/config/performer/bulk_add` — `{"text": "..."}` or `{"names": [...]}`
- `POST /api/config/import` — merge any config JSON
- `POST /api/live/bulk_add` — `{"text": "..."}` or `{"entries": [...]}`
## Troubleshooting
### "I'm only getting hits from Coomer, and they all fail"
This is the most common "nothing happens" scenario and it usually means
**two things combined**:
1. Your chosen performer has a narrow web footprint — Coomer is the
only place with their content. Not every archived creator exists on
every mirror. Harvestr logs `No hits for '' on: leakedzone,
fapello, kemono, …` at the end of the probe phase so you can see
exactly which scrapers reported zero content.
2. Your network can't reach Coomer's sharded CDN (`n1-n4.coomer.st`,
subnet `91.149.227.0/24`). We documented in April 2026 that this
subnet was null-routed globally for a stretch; even when it's back,
many ISPs IP-block the range regardless.
**Fix options (in order of least effort):**
- **Set a download proxy** in the UI's Settings card: `socks5://127.0.0.1:9055`
(built-in Tor — click "Use Tor" button, ~60s to bootstrap)
- **Connect a VPN** (Mullvad: Switzerland/Netherlands/Sweden exits work
best; US exits often apply SNI filtering that blocks Coomer entirely)
- **Try a different network** — mobile hotspot often routes differently
than a fixed-line ISP
The scraper is correct; only the route to the bytes is broken.
### "Progress tab shows nothing"
Make sure you haven't just completed a run — the progress card is only
shown while a session is active. If you're on the Archive tab and don't
see progress, check the Live tab badge (top-right of the nav) to see if
something's running over there.
### "CamSmut says NEEDS-BROWSER for every video"
CamSmut has two layers of anti-scraping:
1. **Hash obfuscation** in URLs — solved (we reverse the `pointerover`
JS transform automatically).
2. **Cloudflare + JS-rendered player** on the embed host (playmogo.com,
doodstream, etc.) — NOT solved with pure HTTP. The embed returns 403
Cloudflare challenge unless rendered in a real browser.
**Workaround:** use the standalone Playwright-based camsmut downloader at
`C:\Users\\Documents\Scripts\Downloaders\camsmut\camsmut_downloader.py`
for actual downloads. Harvestr's built-in CamSmut scraper correctly probes
and enumerates but marks individual videos `NEEDS-BROWSER` (skipped, not
failed) so they don't pollute `failed.json`.
### "The Live tab banner says 'Live recording failed to start'"
The vendored StreaMonitor under `live_backend/streamonitor/` failed to
import. Most likely causes:
- You deleted `live_backend/` (restore from git)
- You set `HARVESTR_STREAMONITOR` to an invalid path (unset it or point
at a real StreaMonitor checkout)
- A Python version mismatch (StreaMonitor targets 3.10+; upgrade if on 3.8-3.9)
## Coomer / Leakedzone / Fapello — which one runs first?
When you run Harvestr for an OnlyFans creator, all three scrapers probe in
parallel. Order of preference at download time:
1. **Leakedzone** — HLS streams over `leakedzone.com` main domain. Reachable
from networks where Coomer is blocked. Single-pass decoder pulls fresh
signed URLs → ffmpeg immediately (URLs expire in ~5 min).
2. **Fapello** — best for photo archives. Most creators on Fapello are
image-only (Harvestr skips images), so it's often 0 videos in practice.
3. **Coomer** — when its CDN is up, wins on coverage. CDN-health pre-check
short-circuits the 200+ video attempts when Coomer is down.
4. **Kemono** — Patreon/Fanbox content (different scope than the OF trio).
Cross-mirror dedup handles the common case of a single video appearing on
multiple sources — you'll only ever end up with one copy on disk.
---
## Legal & ethics
This tool is for **archiving content you have a right to access**:
creators you subscribe to, content in the public domain, content under
permissive licenses, backups of your own uploads, etc.
Don't use it to:
- Redistribute copyrighted content
- Bypass paywalls for content you don't have a legitimate license to
- Scrape at a rate that abuses or disrupts a host site
- Circumvent technological protection measures that violate your local
jurisdiction's anti-circumvention laws
You are responsible for complying with each site's Terms of Service and
your local law. The authors disclaim any liability for misuse.
---
## License
MIT — see [LICENSE](LICENSE).
## Credits
Stands on the shoulders of:
- [**yt-dlp**](https://github.com/yt-dlp/yt-dlp) — the universal extractor
- [**aria2**](https://aria2.github.io/) — multi-segment downloads
- [**ffmpeg**](https://ffmpeg.org/) — HLS / DASH demuxing
- [**curl_cffi**](https://github.com/lexiforest/curl_cffi) — Chrome TLS fingerprint
- [**cloudscraper**](https://github.com/VeNoMouS/cloudscraper) — Cloudflare IUAM bypass
- [**Flask**](https://flask.palletsprojects.com/) — web UI
- [**StreaMonitor**](https://github.com/lossless1/StreaMonitor) — the entire Live-mode
backend is StreaMonitor's 19-site `Bot` framework. We import it at runtime rather
than reimplementing the per-site reverse-engineering; they've earned those lines
of code the hard way
---
## Disclaimer
**Harvestr is a proof of concept.** It exists to demonstrate what a cross-site
username→video pipeline looks like in practice — probes, custom scrapers, embed
extractors, live recording, drift detection, UI, all glued together. It is **not**
a production-grade product: sites change layouts weekly, CDNs rotate, and any
one of the 50+ supported endpoints can go silently broken overnight. Treat every
download run as experimental, verify the output before trusting it, and expect
the occasional breakage that needs a quick scraper patch. PRs welcome — but
please understand this project prioritises "does it work today?" over long-term
maintenance commitments.