An Open Foundation Model and Benchmark to Accelerate Generative Recommendation
## 📖 Introduction
**OpenOneRec** is an open-source framework designed to bridge the gap between traditional recommendation systems and Large Language Models (LLMs). While Generative Recommendation has shown promise, existing models often struggle with isolated data silos and a lack of reasoning capabilities.
To address this, we introduce a unified framework that comprises:
* **RecIF-Bench**: The first holistic Recommendation Instruction-Following Benchmark, containing **100M interactions** from 200k users across heterogeneous domains (Short Video, Ads, Product).
* **OneRec-Foundation Models**: A family of models (1.7B & 8B) built on the Qwen3 backbone. The series includes **Standard** versions trained on our open-source dataset and **Pro** versions enhanced with a hundred-billion-token industrial corpus from Kuaishou.
* **Full-Stack Pipeline**: We open-source our comprehensive training pipeline, including data processing, co-pretraining, and post-training, to ensure full reproducibility and facilitate scaling law research in recommendation.
## 🔥 News
* **[2026.1.1]** 📑 **The technical report** has been released.
* **[2026.1.1]** 🎉 **OneRec-Foundation** models (1.7B, 8B) are now available on Hugging Face!
* **[2026.1.1]** 🚀 **RecIF-Bench** dataset and evaluation scripts are open-sourced.
## 📊 RecIF-Bench
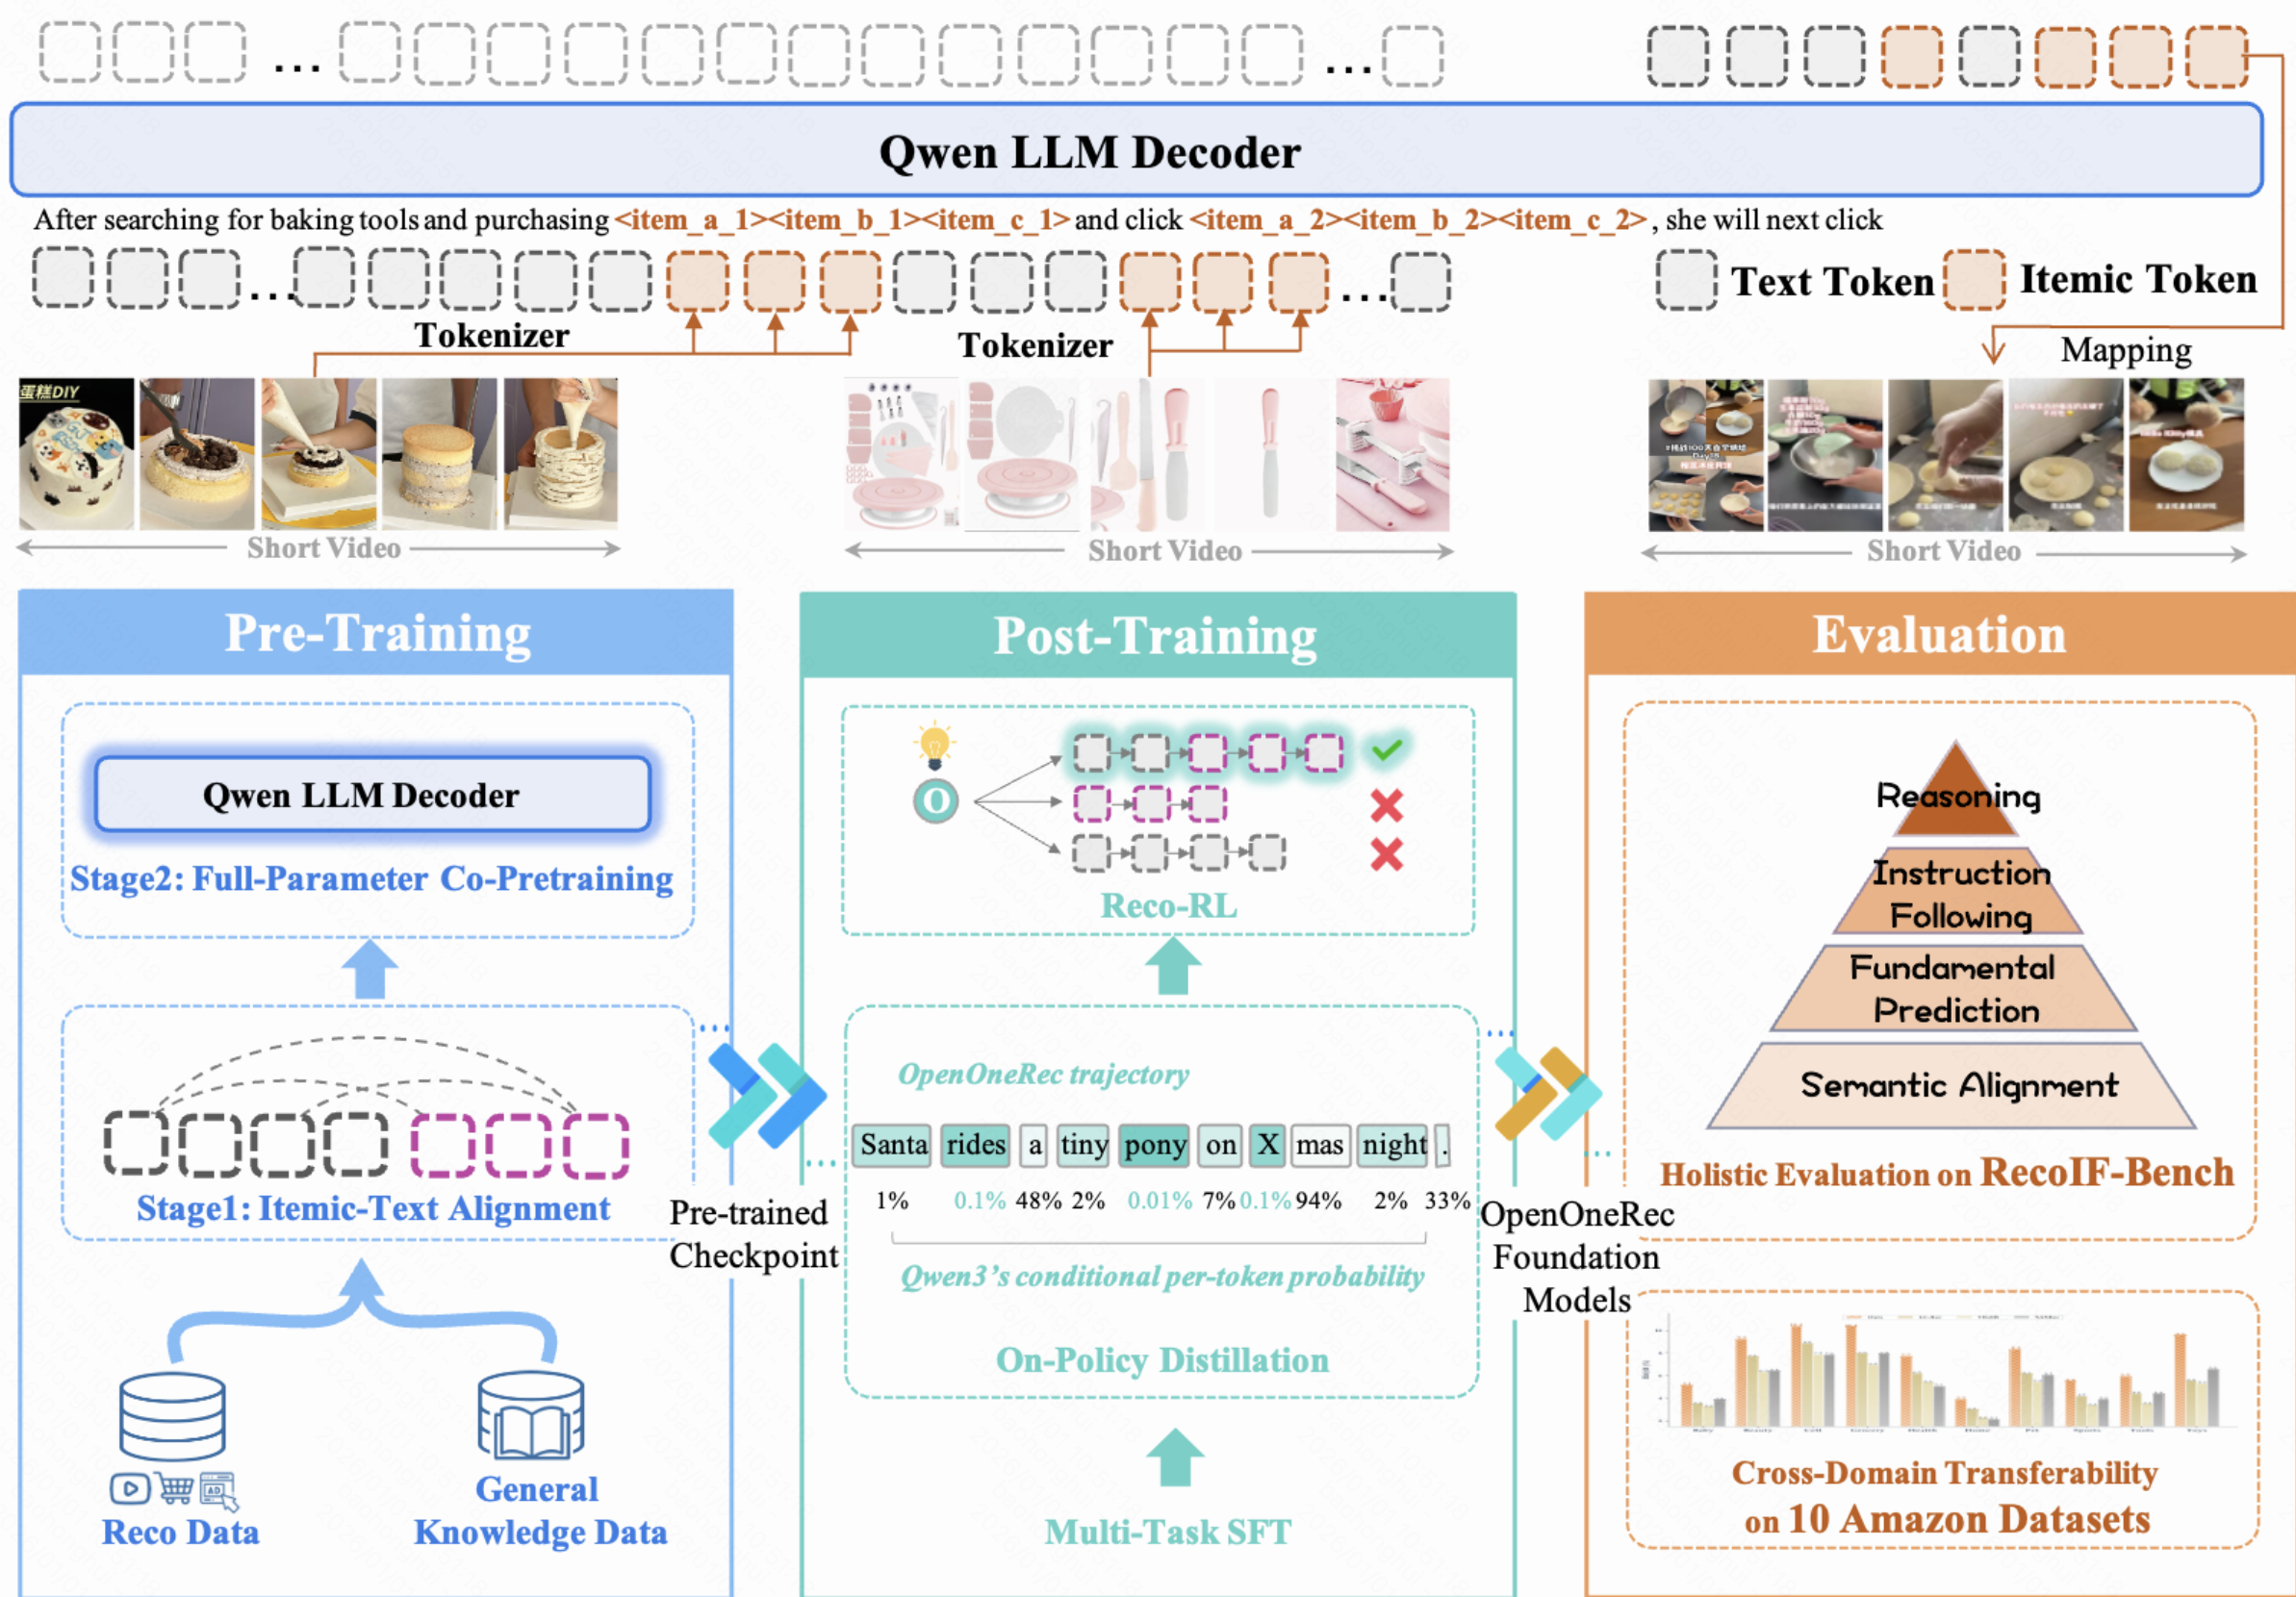
We propose **RecIF-Bench** to rigorously assess the synergy between instruction following and domain-specific recommendation. It organizes 8 distinct tasks into a four-layer capability hierarchy:
* **Layer 0: Semantic Alignment** (Item Understanding)
* **Layer 1: Fundamental Prediction** (Short Video Rec, Ad Rec, Product Rec, Label Prediction)
* **Layer 2: Instruction Following** (Interactive Rec, Label-Conditional Rec)
* **Layer 3: Reasoning** (Recommendation Explanation)
The benchmark aggregates data from three domains: **Short Video** (Content), **Ads** (Commercial), and **Product** (E-commerce).
## 🤖 Model Zoo
The OpenOneRec-Foundation series is built upon the Qwen architecture, enhanced with **Itemic Tokens** for modality alignment and trained via a multi-stage protocol.
| Model | Backbone | Parameters | Description | Link |
| :--- | :--- | :--- | :--- | :--- |
| **OneRec-1.7B** | Qwen3-1.7B | 1.7B | Standard version trained on open-source data (~33B tokens) | [HuggingFace](https://huggingface.co/OpenOneRec/OneRec-1.7B) |
| **OneRec-8B** | Qwen3-8B | 8B | Standard version trained on open-source data (~33B tokens) | [HuggingFace](https://huggingface.co/OpenOneRec/OneRec-8B) |
| **OneRec-1.7B-Pro** | Qwen3-1.7B | 1.7B | Scaled-up version with expanded datasets (~130B tokens) | [HuggingFace](https://huggingface.co/OpenOneRec/OneRec-1.7B-pro) |
| **OneRec-8B-Pro** | Qwen3-8B | 8B | Scaled-up version with expanded datasets (~130B tokens) | [HuggingFace](https://huggingface.co/OpenOneRec/OneRec-8B-pro) |
## 🏗️ Method & Architecture
OpenOneRec reframes recommendation as a general-purpose sequence modeling paradigm.
### 1. Items as Tokens
To bridge the modality gap, we treat items as a distinct modality using **Itemic Tokens** derived from hierarchical vector quantization. This allows the LLM to process interaction history as a cohesive context sequence.
### 2. Training Pipeline
Our framework utilizes the following recipe:
* **Pre-Training**: Integrates collaborative signals via Itemic-Text Alignment and Full-Parameter Co-Pretraining.
* **Post-Training**:
* *Stage 1*: Multi-task Supervised Fine-tuning for basic instruction following.
* *Stage 2*: On-policy Distillation to restore general reasoning performance.
* *Stage 3*: Reinforcement Learning to enhance recommendation capabilities.
### Cross-Domain Transferability
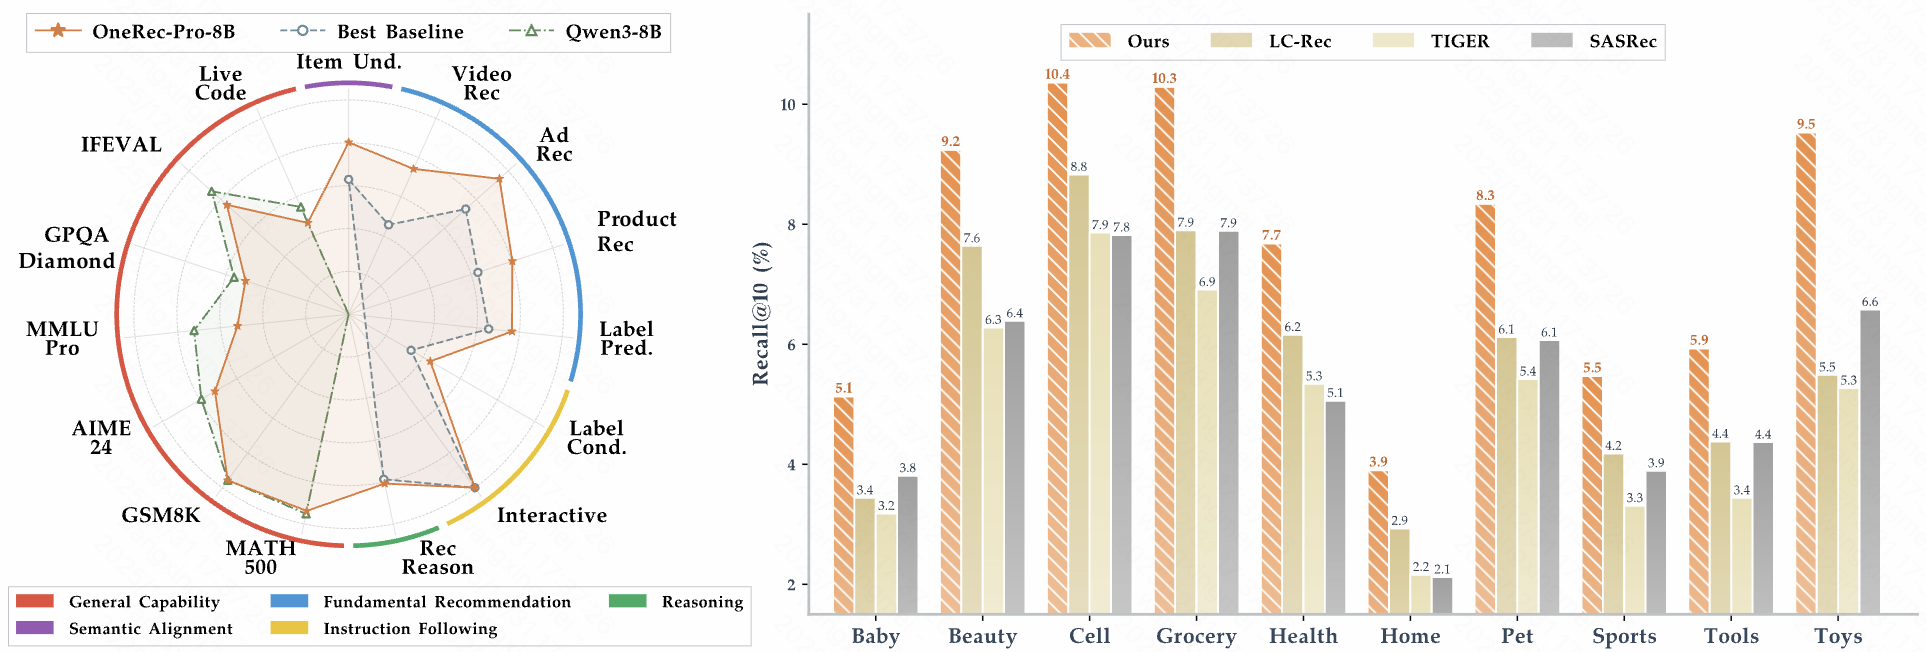
On the **Amazon Benchmark** (10 datasets), OpenOneRec demonstrates exceptional zero-shot/few-shot transfer capabilities, achieving an average **26.8% improvement** in Recall@10 over the second-best method.
| Domain | SASRec | TIGER | LC-Rec | **Ours** |
| :--- | :--- | :--- | :--- | :--- |
| Baby | 0.0381 | 0.0318 | 0.0344 | **0.0513** |
| Beauty | 0.0639 | 0.0628 | 0.0764 | **0.0924** |
| Cell Phones | 0.0782 | 0.0786 | 0.0883 | **0.1036** |
| Grocery | 0.0789 | 0.0691 | 0.0790 | **0.1029** |
| Health | 0.0506 | 0.0534 | 0.0616 | **0.0768** |
| Home | 0.0212 | 0.0216 | 0.0293 | **0.0390** |
| Pet Supplies | 0.0607 | 0.0542 | 0.0612 | **0.0834** |
| Sports | 0.0389 | 0.0331 | 0.0418 | **0.0547** |
| Tools | 0.0437 | 0.0344 | 0.0438 | **0.0593** |
| Toys | 0.0658 | 0.0527 | 0.0549 | **0.0953** |
*Metric: Recall@10. Ours refers to OneRec-Foundation with text-augmented itemic tokens strategy.*
## 🚀 Quick Start
*Code release and detailed usage instructions are coming soon.*
Currently, you can load our models using `transformers>=4.51.0`:
```python
from transformers import AutoModelForCausalLM, AutoTokenizer
model_name = "OpenOneRec/OneRec-8B"
# load the tokenizer and the model
tokenizer = AutoTokenizer.from_pretrained(model_name)
model = AutoModelForCausalLM.from_pretrained(
model_name,
torch_dtype="auto",
device_map="auto"
)
# prepare the model input
# case - prompt with itemic tokens
prompt = "这是一个视频:<|sid_begin|><|sid_end|>,帮我总结一下这个视频讲述了什么内容"
messages = [
{"role": "user", "content": prompt}
]
text = tokenizer.apply_chat_template(
messages,
tokenize=False,
add_generation_prompt=True,
enable_thinking=True # Switches between thinking and non-thinking modes. Default is True.
)
model_inputs = tokenizer([text], return_tensors="pt").to(model.device)
# conduct text completion
generated_ids = model.generate(
**model_inputs,
max_new_tokens=32768
)
output_ids = generated_ids[0][len(model_inputs.input_ids[0]):].tolist()
# parsing thinking content
try:
# rindex finding 151668 ()
index = len(output_ids) - output_ids[::-1].index(151668)
except ValueError:
index = 0
thinking_content = tokenizer.decode(output_ids[:index], skip_special_tokens=True).strip("\n")
content = tokenizer.decode(output_ids[index:], skip_special_tokens=True).strip("\n")
print("thinking content:", thinking_content)
print("content:", content)
```
## 🛣️ Roadmap / Under Development
We are actively working on the following features:
- [ ] **General-domain data**: scripts to fetch and preprocess public general-domain corpora used in `data/general_text`.
- [ ] **Reproducible environments**: training pipeline Docker/Apptainer images for easier end-to-end reproduction.
- [ ] **One-click reproduction**: further code cleanup and streamlined training recipes for an end-to-end “run from scratch” experience.
- [ ] **Docs & tutorials**: improved documentation, tutorials, and best-practice guides.
- [ ] **Unified VeRL integration**: consolidate RL and distillation codepaths into a single, consistent VeRL-based implementation.
- [ ] **More model sizes**: support additional pretraining scales and configurations beyond current checkpoints.
Contributions are welcome! Please refer to the detailed documentation in each module.
## 📜 Citation
If you find our work helpful, please cite our technical report:
```bibtex
@misc{OpenOneRec,
title={OpenOneRec Technical Report},
author={Guorui Zhou and Honghui Bao and Jiaming Huang and Jiaxin Deng and Jinghao Zhang and Junda She and Kuo Cai and Lejian Ren and Lu Ren and Qiang Luo and Qianqian Wang and Qigen Hu and Rongzhou Zhang and Ruiming Tang and Shiyao Wang and Wuchao Li and Xiangyu Wu and Xinchen Luo and Xingmei Wang and Yifei Hu and Yunfan Wu and Zhanyu Liu and Zhiyang Zhang and Zixing Zhang and Bo Chen and Bin Wen and Chaoyi Ma and Chengru Song and Chenglong Chu and Defu Lian and Fan Yang and Feng Jiang and Hongtao Cheng and Huanjie Wang and Kun Gai and Pengfei Zheng and Qiang Wang and Rui Huang and Siyang Mao and Tingting Gao and Wei Yuan and Yan Wang and Yang Zhou and Yi Su and Zexuan Cheng and Zhixin Ling and Ziming Li},
year={2025},
eprint={2512.24762},
archivePrefix={arXiv},
primaryClass={cs.IR}
}
```
## 🛡️ License
The code in this repository is licensed under the Apache 2.0 License. The model weights are subject to their specific license agreements.
## 🙏 Acknowledgements
OpenOneRec is built upon and inspired by the open-source ecosystem. We would like to thank:
- **Qwen3**: for providing the base architecture and model initialization that OpenOneRec builds upon.
- **General-domain data sources**: for the public corpora referenced in [`data/general_text`](https://github.com/Kuaishou-OneRec/OpenOneRec/tree/main/data/general_text) used for mixed-domain training.
- **VeRL & PyTorch distributed training**: for the training infrastructure and scalable primitives (e.g., **FSDP**) used in post-training and large-scale runs.
We sincerely thank these projects for their outstanding work.