# LynnReal-Hand
### Unlocking World Interaction with Hand Control
[English](README.md) · [简体中文](README_zh-CN.md)
[arXiv](https://arxiv.org/pdf/2611.21479) · [Hugging Face Paper](https://huggingface.co/papers/2611.21479) · [YouTube](https://youtu.be/OdywWF0srpU)
[Demo](#demo-gallery) · [Models](#models) · [Quick Start](#quick-start) · [Documentation](#documentation) · [License](LICENSE)
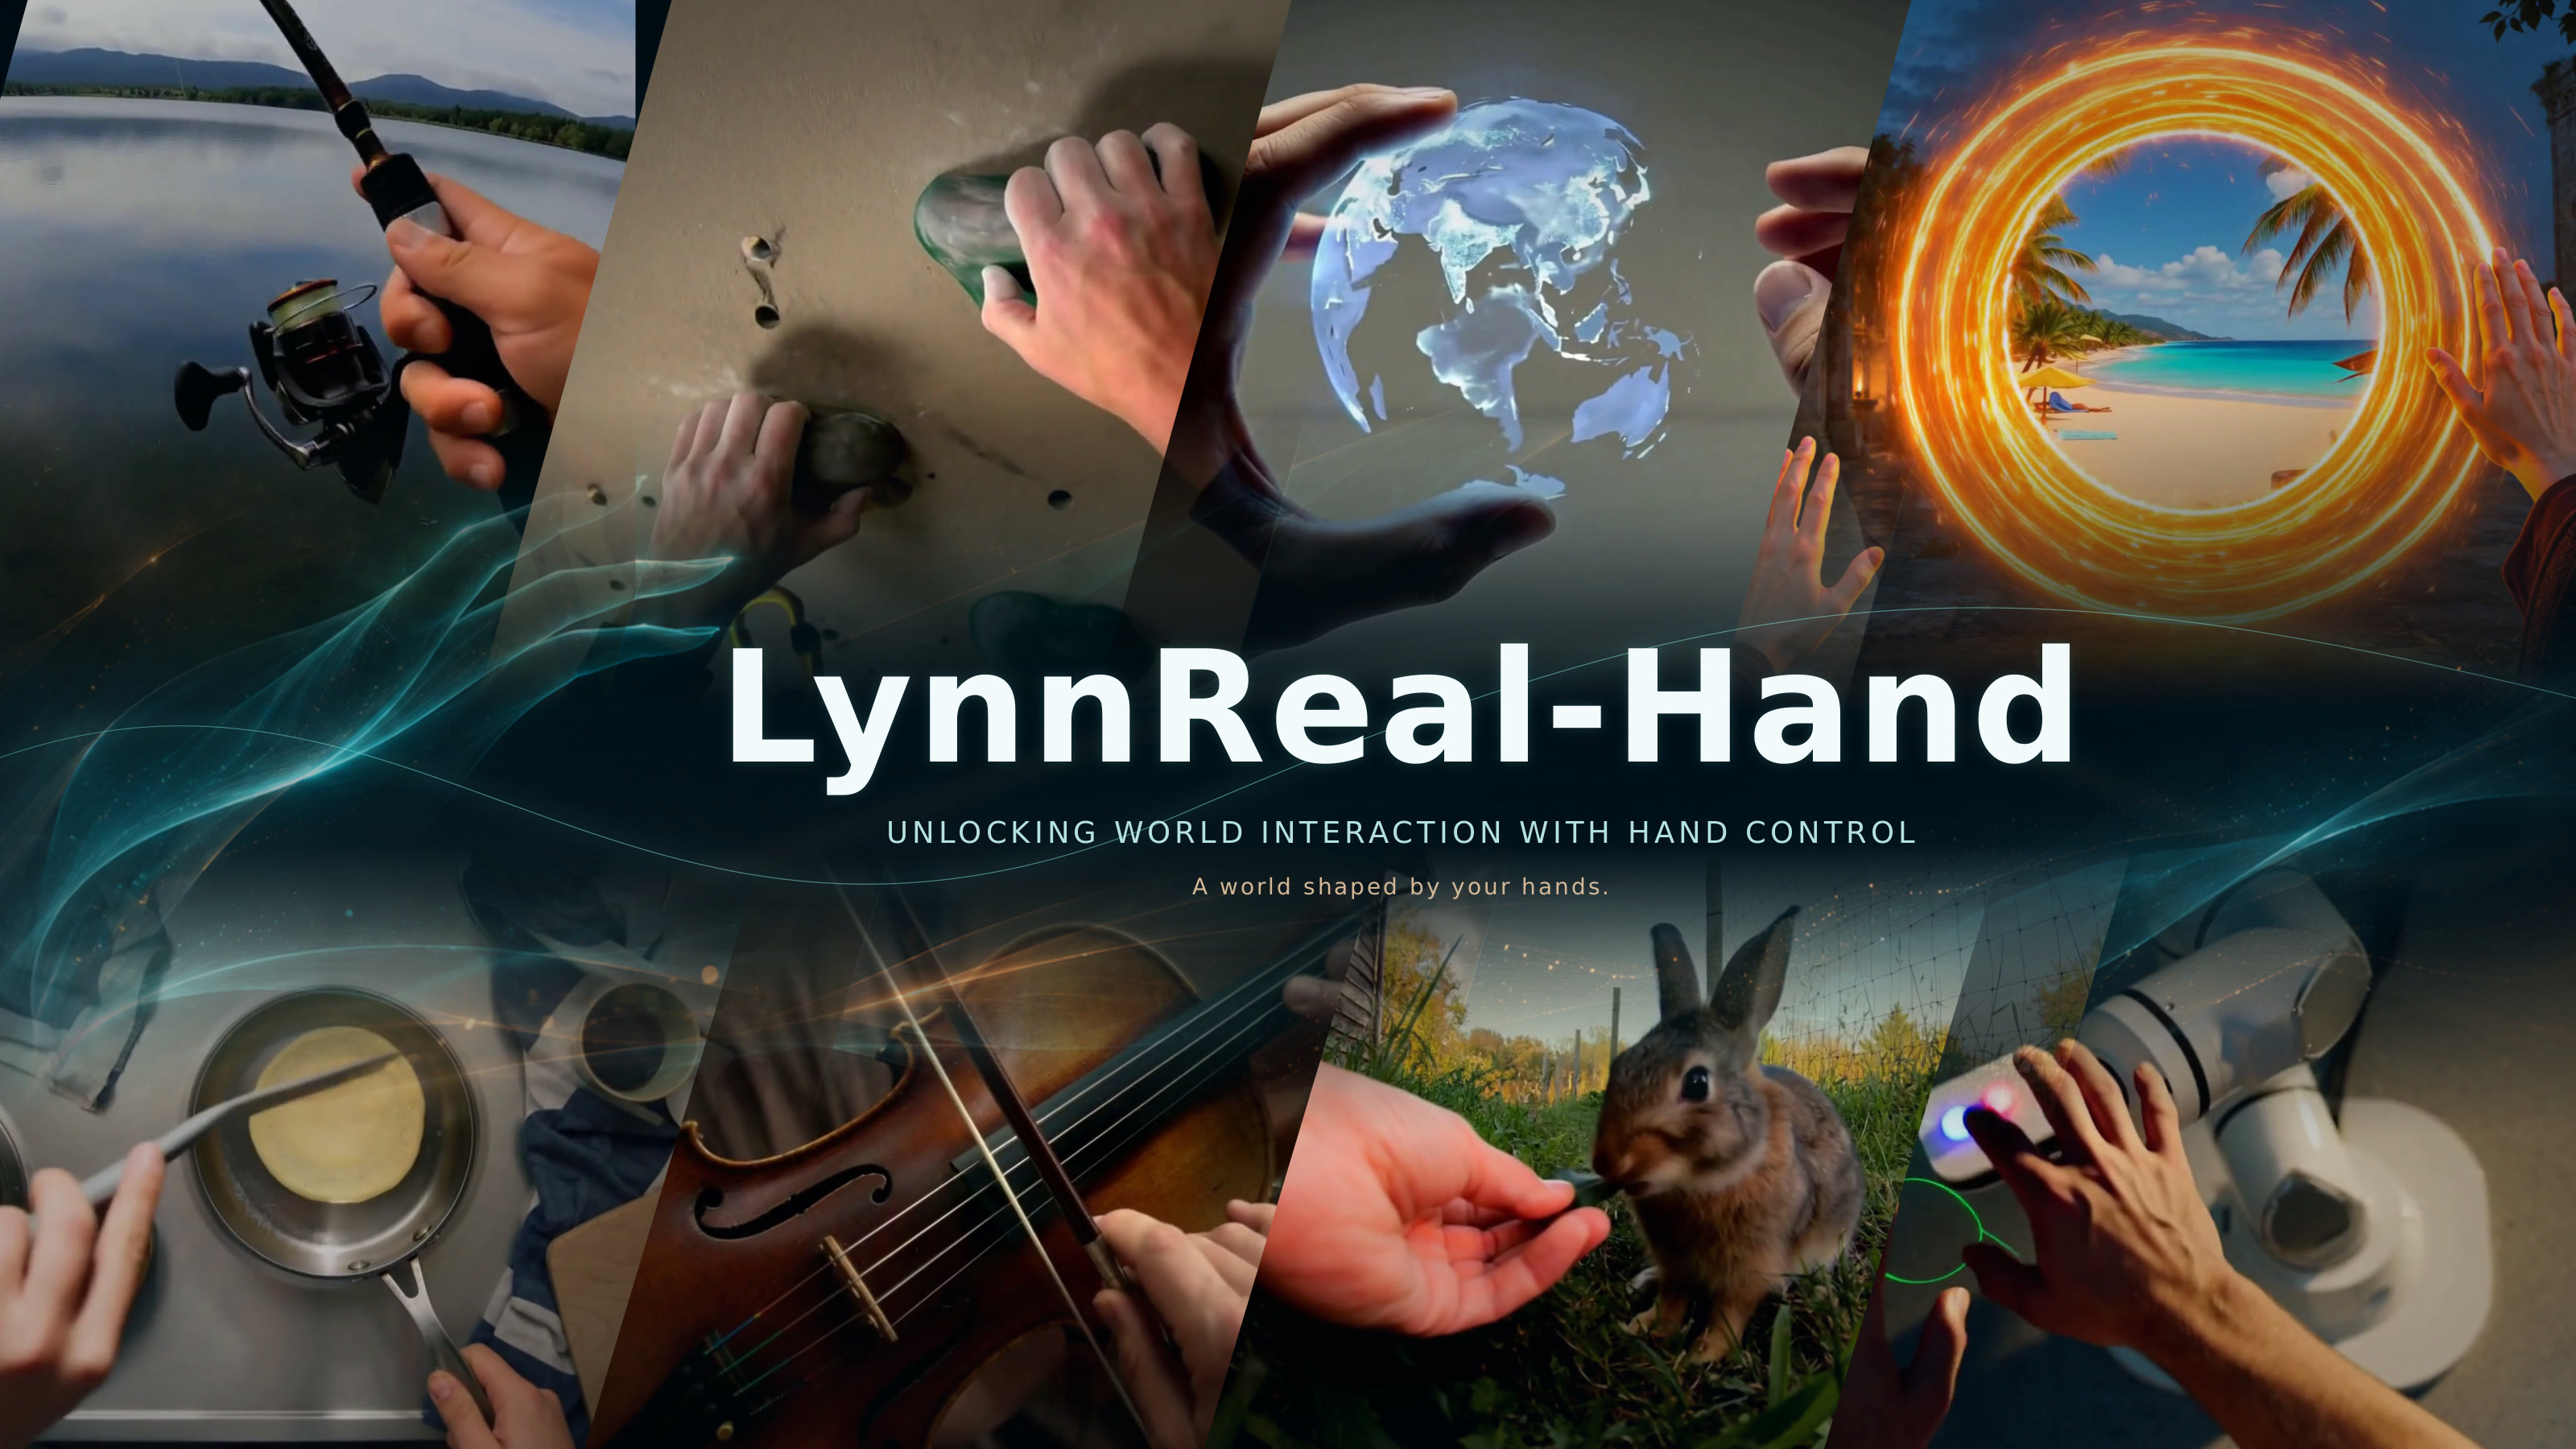
**LynnReal-Hand** is a hand-controlled video world model. Given an initial image, a text prompt, hand motion, and camera poses, it generates videos of interactions across everyday and imagined environments.
- **Fine-grained hand–object interaction.** Use articulated hand motion and camera trajectories to guide reaching, grasping, releasing, and coordinated bimanual interactions across diverse scenes.
- **Interaction-Preserving Training (IPT).** Trained on 100K interaction clips, LynnReal-Hand prioritizes small hand and contact regions through hand-aware multilevel supervision and preserves control fidelity during causal distillation.
- **Three-step causal generation.** LynnReal-Hand-Base generates full sequences; LynnReal-Hand-Fast learns a causal flow map and refines it on self-generated histories. A fixed first-frame anchor, bounded sliding context, and local temporal-position resets support streaming without an ever-growing attention cache.
- **Ultra-Fast-VAE for responsive streaming.** The compact decoder preserves the native H3 latent interface while recovering spatial and temporal reconstruction fidelity through distillation.
- **Low-latency streaming.** Optimized Fast reaches **18.03 FPS at 540p on one H200**, with **741 ms mean warmed response per chunk**. A separate warmed measurement records **34.89 GiB peak allocated GPU memory** with sampling-specific AdaLN tables and the native VAE/Qwen encoder offloaded; see [performance](#performance) for measurement scope.
This repository provides inference code, model downloads, and example inputs.
## Demo Gallery
https://github.com/user-attachments/assets/3df7244c-e001-490f-8743-9b556942767b
The demo presents hand-controlled interactions across natural, everyday, and imagined environments. [Watch on YouTube](https://youtu.be/OdywWF0srpU) · [Download the video](assets/demo.mp4).
## Models
| Model | Description | Default output | Download |
| --- | --- | --- | --- |
| **LynnReal-Hand-Base** | 33B backbone; bidirectional full-sequence generation | 1344 × 768 | [Hugging Face](https://huggingface.co/shaohao011/LynnReal-Hand-Base-1.0) |
| **LynnReal-Hand-Fast** | 33B causal backbone; three sampling steps, W2 context, first-frame anchor | 960 × 540 | [Hugging Face](https://huggingface.co/shaohao011/LynnReal-Hand-Fast-preview) |
| **Ultra-Fast-VAE** | Video decoder used by LynnReal-Hand-Fast | 960 × 540 in the Fast pipeline | [Hugging Face](https://huggingface.co/shaohao011/LynnReal-ultra-fast-vae-1.0) |
Both generation packages use sampling-specialized transformer exports. Fast also includes its matching hand encoder. Each generation package includes the official MiniMax H3 VAE, Qwen image/text encoder, tokenizer, and processor. Fast also includes Ultra-Fast-VAE. See [model weights](docs/weights.md) for component layouts.
## Quick Start
### Installation
The reference environment is **Linux, Python 3.10, PyTorch 2.9.1 / CUDA 12.8, and one NVIDIA H200**. Install FFmpeg and ffprobe with your system package manager. Building FlashAttention-3 requires a C++ compiler and a CUDA toolkit with `nvcc`.
```bash
git clone https://github.com/LynnReal-AI/LynnReal.git
cd LynnReal
python -m venv .venv
source .venv/bin/activate
pip install --upgrade pip
pip install torch==2.9.1 torchvision==0.24.1 --index-url https://download.pytorch.org/whl/cu128
pip install -e .
bash scripts/install_fa3.sh
lynnreal-hand doctor
export CUDA_VISIBLE_DEVICES=0
```
Run the following commands from the repository root. For dependency details and the required FlashAttention-3 build, see [installation](docs/installation.md).
### Model Download
Download the complete package for your chosen model:
```bash
# LynnReal-Hand-Base
python scripts/download_weights.py --component base
# LynnReal-Hand-Fast
python scripts/download_weights.py --component fast
```
Fast can be used independently of Base. To choose another download directory, add `--weights-root /path/to/checkpoints` and use the same path in subsequent preparation and inference commands. Add `--dry-run` to inspect a download plan.
### Example Inputs
Seven examples include aligned initial images, hand-motion videos, camera poses, captions, and Base/Fast reference results:
| Example | Scene | Inputs | Base | Fast |
| --- | --- | --- | --- | --- |
| 01 | Bottle handling | [Inputs](examples/01/example.json) | [Video](examples/01/base.mp4) | [Video](examples/01/fast.mp4) |
| 02 | Preparing corn | [Inputs](examples/02/example.json) | [Video](examples/02/base.mp4) | [Video](examples/02/fast.mp4) |
| 03 | Preparing ingredients | [Inputs](examples/03/example.json) | [Video](examples/03/base.mp4) | [Video](examples/03/fast.mp4) |
| 04 | Opening a carton | [Inputs](examples/04/example.json) | [Video](examples/04/base.mp4) | [Video](examples/04/fast.mp4) |
| 05 | Pet interaction | [Inputs](examples/05/example.json) | [Video](examples/05/base.mp4) | [Video](examples/05/fast.mp4) |
| 06 | Clay modeling | [Inputs](examples/06/example.json) | [Video](examples/06/base.mp4) | [Video](examples/06/fast.mp4) |
| 07 | Wooden puzzle | [Inputs](examples/07/example.json) | [Video](examples/07/base.mp4) | [Video](examples/07/fast.mp4) |
The reference results use 1344 × 768 output; the Fast quick start defaults to 960 × 540. See [example details](examples/README.md) for frame rates and file layouts. Validate the inputs before generation:
```bash
lynnreal-hand validate --config configs/base.json --example examples/05/example.json
lynnreal-hand validate --config configs/fast.json --example examples/05/example.json
```
Input validation runs without model weights or a GPU. After downloading weights, add `--weights-root checkpoints --check-weights` to check the model-package entry files.
### LynnReal-Hand-Base
Base uses full-sequence bidirectional sampling at **1344 × 768**, with 30 sampling schedule points and CFG 3. Prepare its conditions, then generate the video:
```bash
lynnreal-hand prepare \
--config configs/base.json --weights-root checkpoints \
--example examples/05/example.json \
--output outputs/cache/base/example_05
lynnreal-hand infer \
--config configs/base.json --weights-root checkpoints \
--cache outputs/cache/base/example_05 \
--output outputs/base/example_05.mp4 \
--seed 42
```
### LynnReal-Hand-Fast
Fast generates at **960 × 540**, with three flow-map transitions and W2 context: the current chunk and the preceding generated chunk, together with a fixed first-frame anchor. Each full chunk produces 17 RGB frames.
```bash
lynnreal-hand prepare \
--config configs/fast.json --weights-root checkpoints \
--example examples/05/example.json \
--output outputs/cache/fast/example_05
lynnreal-hand infer \
--config configs/fast.json --weights-root checkpoints \
--cache outputs/cache/fast/example_05 \
--output outputs/fast/example_05.mp4 \
--seed 42
```
Base and Fast require separate conditioning caches. Keep the original hand video accessible for online hand encoding in accelerated Fast.
For native **1344 × 768** Fast generation, use [`configs/fast_768.json`](configs/fast_768.json) for both preparation and inference. Each resolution requires its own conditioning cache; see the [768p benchmark commands](docs/benchmark.md#native-768p).
### Accelerated Fast
After preparing the Fast cache, enable the single-H200 accelerated path with `--accelerated`:
```bash
lynnreal-hand infer \
--config configs/fast.json --weights-root checkpoints \
--cache outputs/cache/fast/example_05 \
--output outputs/fast_accelerated/example_05.mp4 \
--seed 42 --accelerated
```
The first run includes compilation and CUDA graph capture. Later generation reuses the compiled shapes within the same process. For warmed throughput and latency measurements, use the [benchmark guide](docs/benchmark.md).
The CLI saves the generated MP4 and a JSON file containing the model, frame count, frame rate, seed, and example ID. Add `--save-latents` to retain generated latents. See [inference](docs/inference.md) for the streaming Python interface and output details.
**Featured example: Pet interaction**
[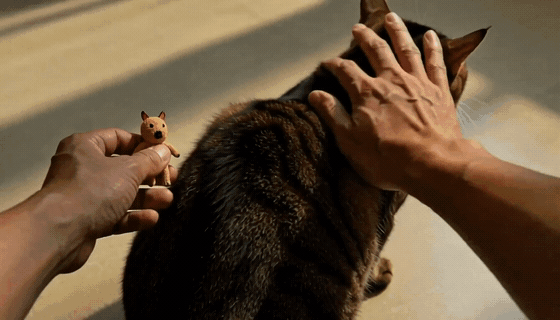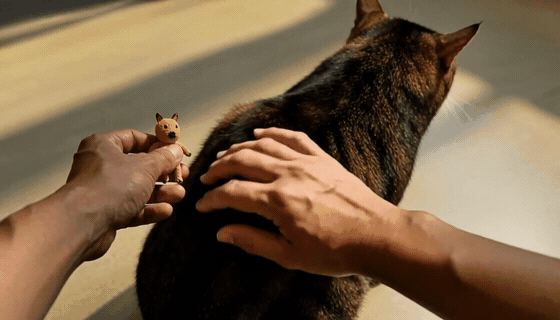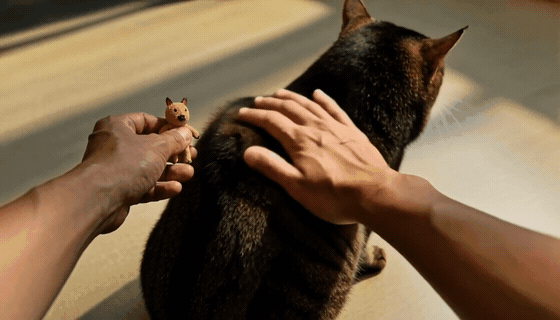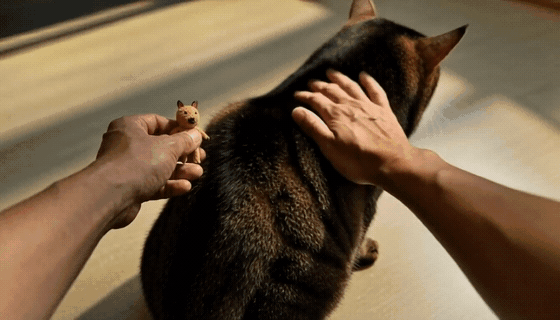](examples/05/fast.mp4)
[Fast video](examples/05/fast.mp4) · [Base video](examples/05/base.mp4) · [Example inputs](examples/05/example.json)
## Custom Inputs
Place your initial image, hand-motion video, and camera arrays beside an `example.json`:
```json
{
"id": "my_example",
"image": "image.png",
"hand_video": "hand.mp4",
"camera": "camera.npz",
"caption": "An egocentric view of a hand picking up a cup from a table.",
"frames": 124,
"fps": 30.0
}
```
Paths resolve relative to `example.json`. Match the caption, frame count, and frame rate to your inputs. The packaged input pipeline accepts **124, 158, 243, or 260 frames** and preserves the input frame rate.
Use your manifest path in the `validate` and `prepare` commands, then pass the resulting cache to `infer`. Image, hand motion, and camera poses must share the same field of view and frame order. See [example inputs](examples/README.md) and [data preparation](docs/data.md) for camera alignment and input requirements.
## Performance
### Video generation
Paper results on one H200. Fast reports mean warmed response at 540p; the other methods report median latency at 768p. Resolutions, clip lengths, and timed units vary across methods.
| Model | Backbone | Resolution | Timed unit | Latency (s) ↓ | FPS ↑ | Peak (GiB) |
| --- | ---: | ---: | ---: | ---: | ---: | ---: |
| JointControlVideo | 14B | 768p | Full seq. | 1320.324 | 0.053 | 59.50 |
| Generated Reality | 5B | 768p | Full seq. | 446.484 | 0.221 | 15.87 |
| Hand2World-Bi | 5B | 768p | Full seq. | 104.682 | 1.195 | 59.67 |
| Hand2World-AR | 5B | 768p | 4 frames | 0.437 | 8.646 | 33.44 |
| **LynnReal-Hand-Base** | 33B | 768p | Full seq. | 770.155 | 0.136 | 82.59 |
| **LynnReal-Hand-Fast** | 33B | 540p | 17 frames | 0.741 | 18.03 | 34.89 |
Fast response includes online hand encoding, generation, decoding, and delivery to CPU; sustained FPS also includes history-cache updates. Its memory entry is a separate warmed measurement with sampling-specific AdaLN tables and the native VAE/Qwen encoder off device. Conditioning preparation and cold startup are excluded. Base's memory entry uses the original full AdaLN projections. See [benchmark methodology](docs/benchmark.md).
### VAE decoding
Paper decoder results at **1344 × 768**, measured per **17 frames** on one H200. Latency and FPS measure decoding only. Temporal error is deltaMAE × 10³.
| Decoder | Params (M) ↓ | PSNR (dB) ↑ | LPIPS ↓ | Temporal error ↓ | Latency (ms) ↓ | FPS ↑ |
| --- | ---: | ---: | ---: | ---: | ---: | ---: |
| Native H3 | 2423.5 | 35.04 | 0.0434 | 9.05 | 831.30 | 20.44 |
| Tiny-H3 | 9.9 | 30.40 | 0.1040 | 13.78 | 10.90 | 1555.64 |
| StreamRender¹ | 1617.8 | 33.74 | 0.0533 | 10.09 | 143.31 | 118.63 |
| StreamRender² | 1617.8 | 33.95 | 0.0516 | 9.88 | 157.65 | 123.91 |
| SolarX V3 | 2423.5 | 34.09 | 0.0484 | 10.20 | 552.79 | 30.54 |
| LightVAE | 1752.1 | 35.13 | 0.0423 | 8.97 | 586.40 | 28.97 |
| **Ultra-Fast-VAE** | 361.2 | 34.43 | 0.0511 | 9.80 | 46.77 | 363.21 |
StreamRender¹/² uses one/two latents per call; LightVAE uses seven, including two future latents. Ultra-Fast-VAE uses W8A8. The generation pipeline includes additional work beyond decoding.
See [benchmark methodology](docs/benchmark.md) for packaged-runtime measurements and reproduction commands.
## AdaLN Memory Optimization
Base and Fast include only the AdaLN modulation tables required by their default sampling schedules. These compact tables load directly in place of the learned per-block projections, reducing download size and resident parameter memory. Fast uses three sampling steps. The native VAE and Qwen encoder are needed for conditioning preparation and can be offloaded before Fast generation. See [inference memory](docs/inference.md#adaln-memory) for schedule constraints and memory scope.
## Documentation
| Guide | Contents |
| --- | --- |
| [Installation](docs/installation.md) | Dependencies, FlashAttention-3, and environment setup |
| [Model weights](docs/weights.md) | Downloads and component layouts |
| [Inference](docs/inference.md) | Base, Fast, acceleration, and streaming |
| [Data preparation](docs/data.md) | Input format, camera alignment, and conditioning caches |
| [Benchmarks](docs/benchmark.md) | Performance measurements and timing definitions |
| [Output verification](docs/VALIDATION.md) | Input and generated-media checks |
## Related Projects
- [BiWM](https://github.com/LynnReal-AI/BiWM)
- [LynnReal-Omni](https://github.com/LynnReal-AI/LynnReal-Omni)
## License
This repository follows the [MiniMax H3 Community License Agreement](LICENSE). Third-party components retain their respective licenses and notices; see [NOTICE](NOTICE) and [acknowledgements](third_party/acknowledgements/README.md).
## Acknowledgements
We thank the SolarWM, H3, Qwen, Diffusers, PyTorch, TAEHV, and DuoMatching contributors for their open implementations. Component-specific attribution is provided in [third_party/README.md](third_party/README.md).
## Citation
If you use LynnReal-Hand or Ultra-Fast-VAE in your research, please cite our paper:
```bibtex
@misc{rui2026lynnrealhandunlockingworldinteraction,
title={LynnReal-Hand: Unlocking World Interaction with Hand Control},
author={Shaohao Rui and Chaoyang Zhang and Xiaofeng Mao and Weijie Ma},
year={2026},
eprint={2611.21479},
archivePrefix={arXiv},
primaryClass={cs.CV},
url={https://arxiv.org/abs/2611.21479}
}
```
## Related Publications
Related publications:
- **BiWM: Advancing Open-Source Interactive Video World Models with Bidirectional Autoregression** — [Paper](https://arxiv.org/abs/2606.10135) · [Code](https://github.com/LynnReal-AI/BiWM)
- **LynnReal-Omni: Native multi-modal Video Generation for Agentic Visual Workflows** — [Paper](https://arxiv.org/abs/2609.15863) · [Code](https://github.com/LynnReal-AI/LynnReal-Omni)
```bibtex
@article{rui2026biwm,
title={BiWM: Advancing Open-Source Interactive Video World Models with Bidirectional Autoregression},
author={Rui, Shaohao and Mao, Xiaofeng and Zhang, Zhanyu and Lin, Peijia and Zhu, Yansong and Zhang, Yibo and Wan, Haibin and Zhao, Zhangrui and Ma, Weijie},
journal={arXiv preprint arXiv:2606.10135},
year={2026},
url={https://arxiv.org/abs/2606.10135}
}
@misc{mao2026lynnrealomninativemultimodalvideo,
title={LynnReal-Omni: Native multi-modal Video Generation for Agentic Visual Workflows},
author={Xiaofeng Mao and Peijia Lin and Shaohao Rui and Yibo Zhang and Haibin Wan and Weijie Ma},
year={2026},
eprint={2609.15863},
archivePrefix={arXiv},
primaryClass={cs.CV},
url={https://arxiv.org/abs/2609.15863}
}
```