# Install Environment
Our code is based on the requirements of the official [CropMAE repository](https://github.com/alexandre-eymael/CropMAE).
In addition to those requirements, we include several additional dependencies, which can be found in `requirements.txt`.
To set up the environment, please run:
```
conda create -n preti python=3.11
conda activate preti
pip install -r requirements.txt
```
# Dataset Structure
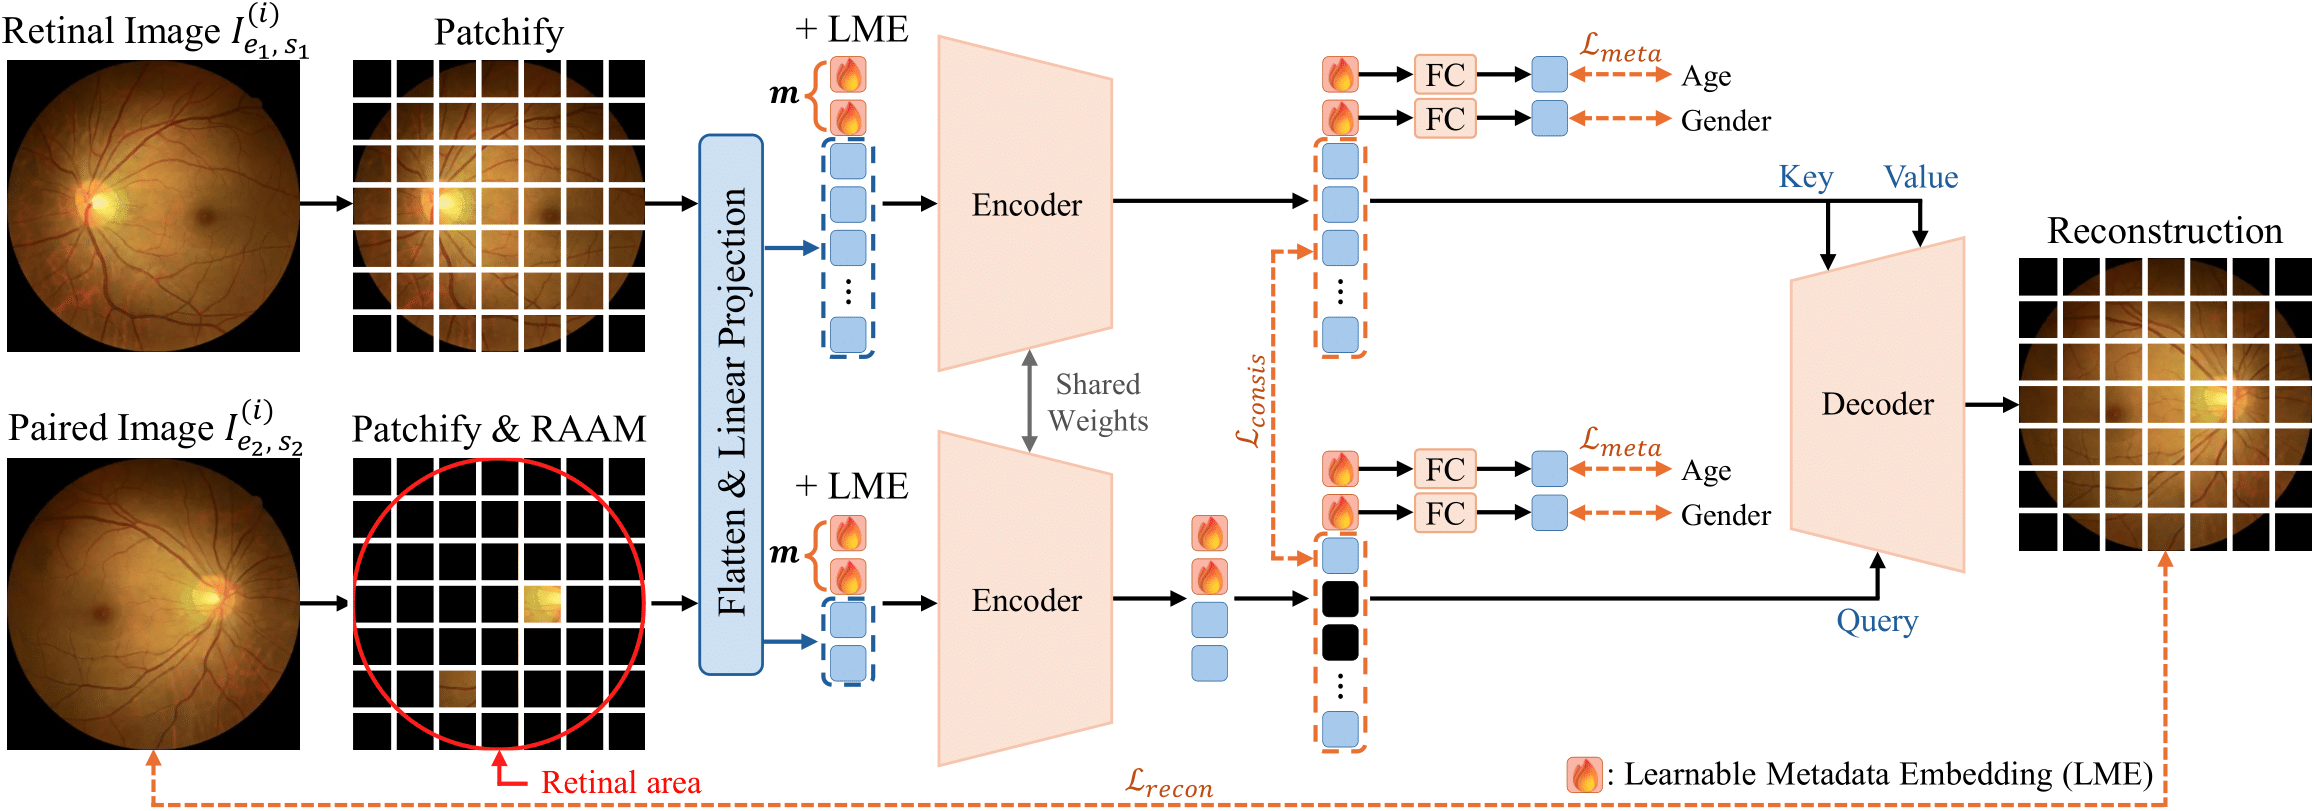
Our model uses a paired fundus image dataset with age, gender, and corresponding ROI masks. Each sample consists of a left-right eye pair (can include self-pairs) and their corresponding metadata.
### 🔧 Requirements
To build the dataset correctly, you need:
1. A CSV file with the following columns:
- `patient_id`: Unique ID per subject
- `exam_id`: Examination ID
- `jpg_h512_path_automorph`: Path to the fundus image (resolution 512x512 recommended)
- `mask_path`: Path to the binary mask image
- `age`: Age of the patient (float or int)
- `gender`: "Male" or "Female"
- `laterality`: Value indicating eye side (e.g., 0.0 = Left, 1.0 = Right)
2. Images & masks must be accessible via paths in the CSV.
# Model Variants
| Script Name | Description |
|------------------------------|-----------------------------------------------------------------------------|
| `run_train.py` | Full **PRETI** model with both **LME** (Learnable Metadata Embedding) and **RAAM** (Region-Aware Attention Masking). |
| `run_train_no_meta.py` | PRETI **without LME** – removes metadata embeddings for age and gender. |
| `run_train_no_ram.py` | PRETI **without RAAM** – disables region-aware masking, using random masking instead. |
| `run_train_no_meta_no_ram.py`| PRETI **without both LME and RAAM** – baseline model with no metadata or region-aware masking. |
# Pretrained Weights
We provide pretrained weights for the PRETI model trained on fundus image pairs.
| Model Variant | Description | Download Link |
|---------------|---------------------------|----------------|
| `preti-vitb` | ViT-Base backbone | [Download](https://drive.google.com/file/d/1mEFm3bxSPPOm4bLPC9Ey64oeq-6F0S0G/view?usp=drive_link) |
## Citation
If you found this code useful, please cite the following paper:
```
@InProceedings{2025preti,
author = {Lee, Yeonkyung and Han, Woojung and Jun, Youngjun and Kim, Hyeonmin and Cho, Jungkyung and Hwang, Seong Jae},
title = {PRETI: Patient-Aware Retinal Foundation Model via Metadata-Guided Representation Learning},
booktitle = {International Conference on Medical Image Computing and Computer-Assisted Intervention},
year = {2025},
organization={Springer}
}
```