# Benchmarks
Quality and speed benchmarks for `semble`.
- [Main results](#main-results)
- [Token efficiency](#token-efficiency)
- [By language](#by-language)
- [Ablations](#ablations)
- [Dataset](#dataset)
- [Methods](#methods)
- [Excluded methods](#excluded-methods)
- [Running the benchmarks](#running-the-benchmarks)
## Main results
Quality and speed across all methods.
| Method | NDCG@10 | Index | Query p50 |
| -------------------- | --------: | ---------: | ----------: |
| **semble** | **0.854** | **306 ms** | **0.91 ms** |
| CodeRankEmbed | 0.839 | 116 s | 16 ms |
| ColGREP | 0.693 | 5.4 s | 122 ms |
| BM25 | 0.673 | 47 ms | 0.17 ms |
| zvec-grep | 0.670 | 3.4 s | 391 ms |
| ck | 0.642 | 96 s | 187 ms |
| codebase-memory-mcp | 0.630 | 454 ms | 46 ms |
| grepai | 0.561 | 35 s | 48 ms |
| probe | 0.387 | — | 207 ms |
| cs | 0.200 | — | 22 ms |
| ripgrep | 0.126 | — | 14 ms |
|  |  |
| :-----------------------------------------------------------------: | :-----------------------------------------------------------------: |
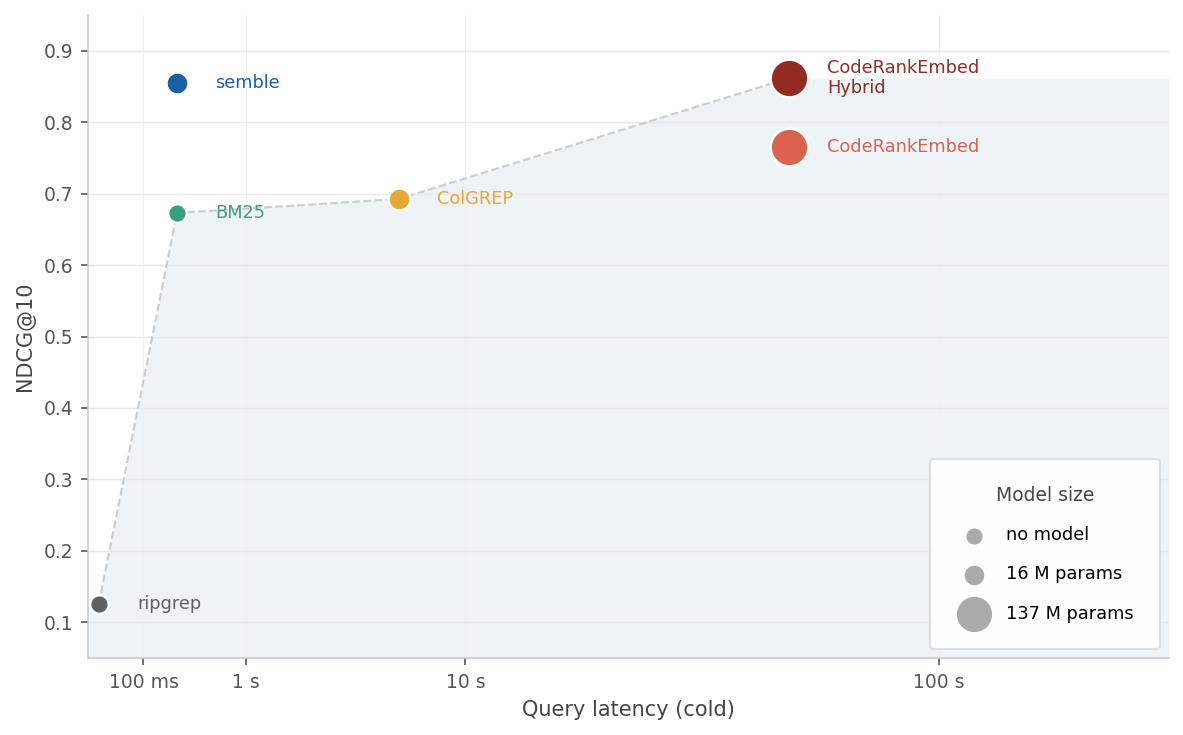
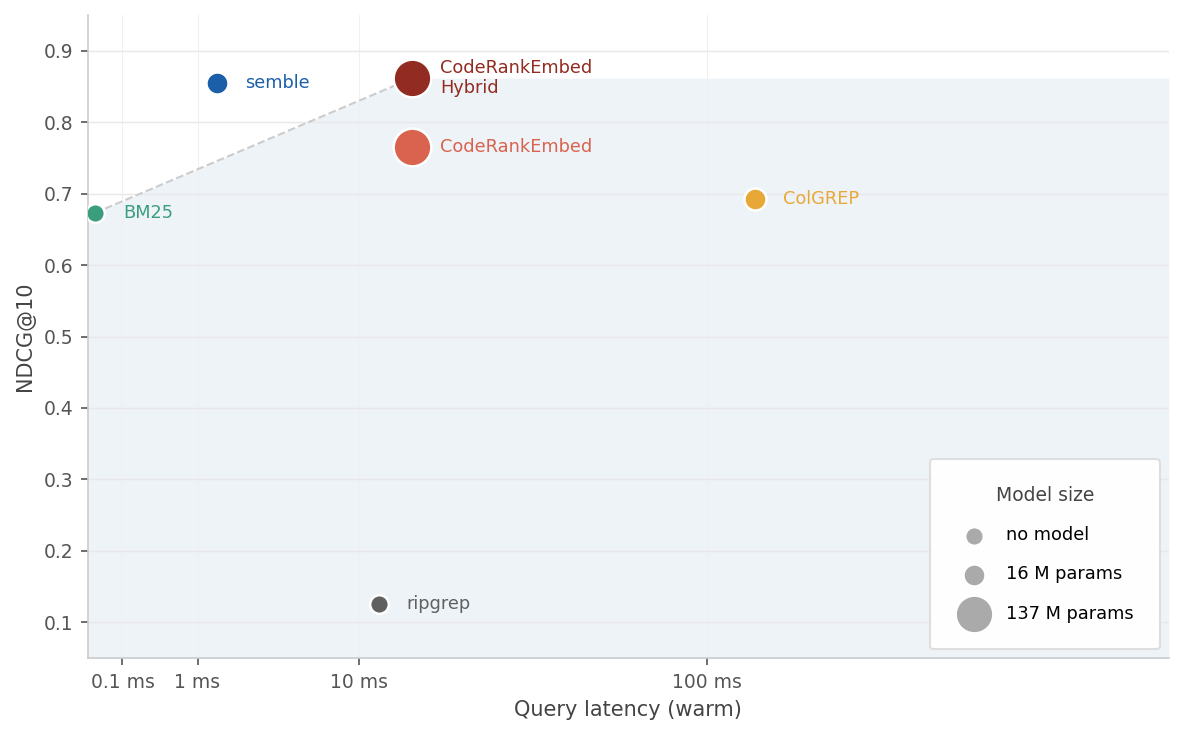
| _Time to first result (index + query) vs NDCG@10_ | _Query latency on a warm index vs NDCG@10_ |
semble matches the NDCG@10 of the 137M-param CodeRankEmbed while winning index time by ~380x and query latency by ~17x.
NDCG@10 is averaged across all queries. Speed numbers use one repo per language, CPU only: cold-start index time and warm query p50 (median across 5 consecutive runs).
## Token efficiency
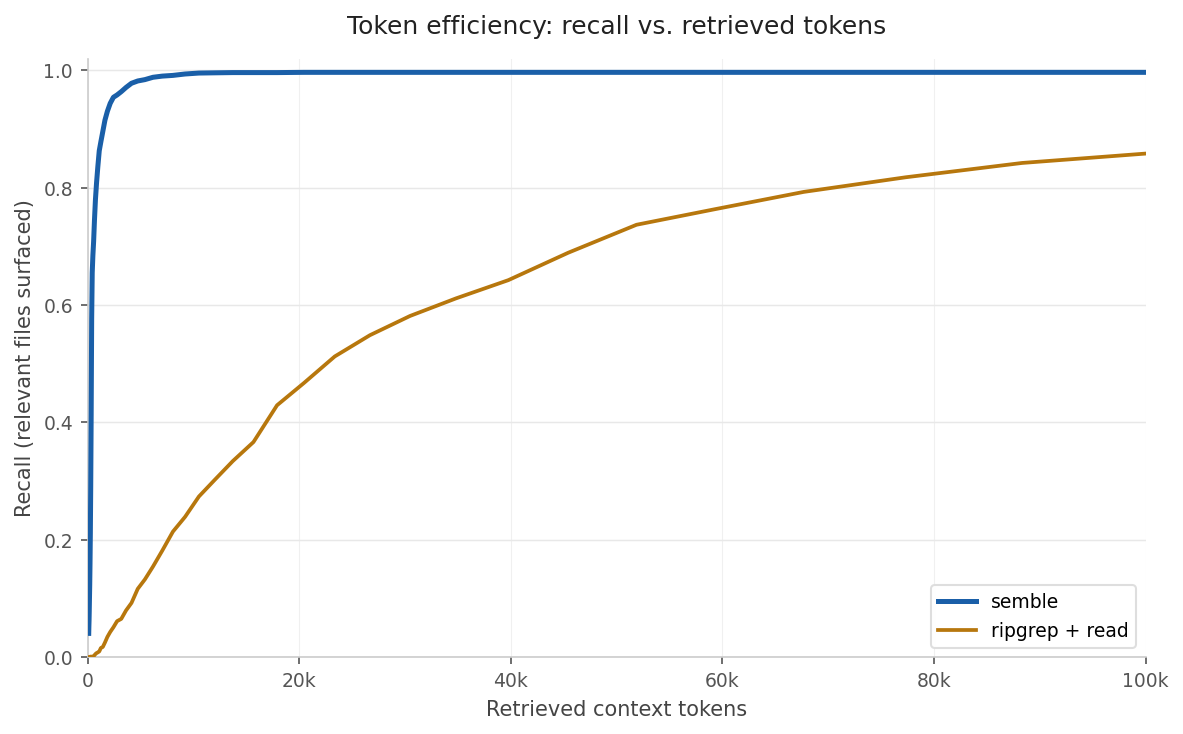
Coding agents (Claude Code, OpenCode, etc.) typically find code by running `grep` on keywords and reading the matched files. We model that workflow and compare it against semble's chunk retrieval across our full benchmark of 1251 queries.
### Expected tokens per query
For each query: tokens consumed at first relevant hit, or 32k if the method never finds anything. Averaged across all 1251 queries.
| Method | Expected tokens | Savings |
| ------------------- | --------------: | ------------: |
| ripgrep + read file | 45,587 | baseline |
| **semble** | **348** | **99% fewer** |
### Recall at fixed token budgets
A relevant file is "covered" once any retrieved unit comes from it.
| Method | 500 | 1k | 2k | 4k | 8k | 16k | 32k |
| ------------------- | --------: | --------: | --------: | --------: | --------: | --------: | --------: |
| **semble** | **0.842** | **0.923** | **0.967** | **0.988** | **0.995** | **0.995** | **0.995** |
| ripgrep + read file | 0.001 | 0.008 | 0.037 | 0.086 | 0.207 | 0.374 | 0.583 |
Methodology
semble returns the top-50 ranked chunks. `ripgrep+read` splits the query into keywords (dropping stopwords and short words), runs `rg --fixed-strings --ignore-case` for each keyword, then reads matched files in full ranked by how many distinct keywords they contain. Both methods search the same set of file types and ignored directories. Tokens are counted with `cl100k_base` via `tiktoken`. A relevant file is "covered" once any retrieved unit overlaps its annotated span.
## By language
NDCG@10 per language, sorted by semble. CRE = CodeRankEmbed, cbm = codebase-memory-mcp. Best score per row is bolded.
| Language | semble | CRE | ColGREP | zvec-grep | ck | cbm | grepai | probe | cs | ripgrep |
| ----------- | --------: | --------: | --------: | ---------: | --------: | --------: | --------: | --------: | --------: | --------: |
| javascript | 0.917 | **0.925** | 0.823 | 0.760 | 0.772 | 0.770 | 0.675 | 0.588 | 0.171 | 0.176 |
| cpp | **0.915** | 0.897 | 0.626 | 0.677 | 0.687 | 0.630 | 0.731 | 0.375 | 0.262 | 0.126 |
| zig | **0.913** | 0.911 | 0.474 | 0.664 | 0.511 | 0.766 | 0.755 | 0.369 | 0.121 | 0.000 |
| scala | 0.909 | **0.925** | 0.765 | 0.799 | 0.717 | 0.704 | 0.330 | 0.392 | 0.111 | 0.180 |
| ruby | **0.909** | 0.905 | 0.708 | 0.758 | 0.738 | 0.689 | 0.643 | 0.382 | 0.255 | 0.230 |
| go | **0.895** | 0.713 | 0.785 | 0.512 | 0.458 | 0.506 | 0.722 | 0.410 | 0.183 | 0.133 |
| elixir | **0.894** | 0.893 | 0.808 | 0.811 | 0.786 | 0.506 | 0.669 | 0.412 | 0.397 | 0.134 |
| csharp | **0.885** | 0.848 | 0.614 | 0.609 | 0.548 | 0.775 | 0.277 | 0.392 | 0.248 | 0.117 |
| python | 0.867 | **0.878** | 0.777 | 0.704 | 0.721 | 0.643 | 0.634 | 0.488 | 0.305 | 0.202 |
| swift | **0.860** | 0.845 | 0.710 | 0.709 | 0.672 | 0.630 | 0.429 | 0.280 | 0.151 | 0.160 |
| php | **0.858** | 0.847 | 0.663 | 0.583 | 0.615 | 0.608 | 0.402 | 0.340 | 0.180 | 0.123 |
| rust | **0.856** | 0.754 | 0.662 | 0.541 | 0.419 | 0.454 | 0.519 | 0.242 | 0.193 | 0.162 |
| java | **0.849** | 0.790 | 0.641 | 0.685 | 0.606 | 0.554 | 0.386 | 0.536 | 0.136 | 0.198 |
| bash | 0.825 | **0.834** | 0.706 | 0.725 | 0.677 | 0.768 | 0.723 | 0.226 | 0.170 | 0.000 |
| lua | 0.823 | **0.829** | 0.798 | 0.736 | 0.738 | 0.591 | 0.699 | 0.336 | 0.050 | 0.000 |
| kotlin | 0.821 | **0.823** | 0.637 | 0.628 | 0.587 | 0.611 | 0.478 | 0.335 | 0.170 | 0.166 |
| haskell | 0.765 | **0.811** | 0.683 | 0.689 | 0.733 | 0.624 | 0.483 | 0.313 | 0.160 | 0.000 |
| c | 0.741 | **0.771** | 0.676 | 0.598 | 0.606 | 0.655 | 0.555 | 0.384 | 0.175 | 0.000 |
| typescript | **0.706** | 0.671 | 0.430 | 0.476 | 0.456 | 0.455 | 0.394 | 0.354 | 0.145 | 0.128 |
| **overall** | **0.854** | 0.839 | 0.693 | 0.670 | 0.642 | 0.630 | 0.561 | 0.387 | 0.200 | 0.126 |
## Ablations
`raw` returns retrieval scores directly; `+ ranking` feeds them through semble's hybrid ranker.
| Retrieval | Raw | + ranking |
| ---------------------- | ----: | --------: |
| BM25 | 0.675 | 0.834 |
| potion-code-16M-v2 | 0.650 | 0.821 |
| BM25 + potion-code-16M-v2 | — | **0.854** |
By query category
| Mode | Architecture | Semantic | Symbol |
| ---------------------------------- | -----------: | --------: | --------: |
| BM25 raw | 0.628 | 0.676 | 0.719 |
| potion-code-16M raw | 0.626 | 0.666 | 0.629 |
| semble BM25 (+ ranking) | 0.770 | 0.819 | 0.957 |
| semble potion-code-16M (+ ranking) | 0.757 | 0.808 | 0.943 |
| **semble hybrid** | **0.802** | **0.846** | **0.958** |
## Dataset
~1,250 queries over 63 repositories in 19 languages, grouped into three categories:
| Category | Queries | What it tests |
| ------------ | ------: | -------------------------------------------------------- |
| semantic | 711 | Code that implements a specific behavior or concept |
| architecture | 343 | Design decisions, module boundaries, structural patterns |
| symbol | 204 | Named entity lookup (function, class, type, variable) |
Notes
**Languages**: three repos per language (nine for Python): bash, C, C++, C#, Elixir, Go, Haskell, Java, JavaScript, Kotlin, Lua, PHP, Python, Ruby, Rust, Scala, Swift, TypeScript, Zig. Repos are pinned by revision in `repos.json`.
**How the benchmark was built**: queries and ground-truth relevance labels are generated by Claude Sonnet 4.6. The same model is used as LLM-as-judge to verify label quality.
## Methods
- **[ripgrep](https://github.com/BurntSushi/ripgrep)**: fast regex search over files, included as a raw keyword-match baseline.
- **[probe](https://github.com/buger/probe)**: BM25 keyword ranking backed by tree-sitter parse trees. We use its free `probe search` mode; its `probe agent` mode (which does query rewriting) needs a paid LLM API key and isn't tested here.
- **[cs (Code Spelunker)](https://github.com/boyter/cs)**: structural BM25 ranker which ranks matches differently in code/comments/strings).
- **[ColGREP](https://github.com/lightonai/next-plaid/tree/main/colgrep)**: late-interaction code retrieval built on next-plaid with the [LateOn-Code-edge](https://huggingface.co/lightonai/LateOn-Code-edge) model.
- **[grepai](https://github.com/nicholasgasior/grepai)**: semantic search using [nomic-embed-text](https://huggingface.co/nomic-ai/nomic-embed-text-v1) (137M params) via a local Ollama daemon.
- **[codebase-memory-mcp](https://github.com/DeusData/codebase-memory-mcp)**: code intelligence engine that indexes a repo into a SQLite/graph store. We benchmark its `search_graph` tool in `fast` mode, which does BM25 full-text search with structural boosting.
- **[ck](https://github.com/BeaconBay/ck)**: hybrid regex + semantic search using [BAAI/bge-small-en-v1.5](https://huggingface.co/BAAI/bge-small-en-v1.5).
- **[zvec-grep](https://github.com/zvec-ai/zvec-grep)**: [potion-code-16M-v2](https://huggingface.co/minishlab/potion-code-16M-v2) static embeddings + BM25. Benchmarked in `direct` mode.
- **[CodeRankEmbed](https://huggingface.co/nomic-ai/CodeRankEmbed)**: 137M-param transformer embedding model for code retrieval, used for semantic-only dense search.
- **[semble](https://github.com/your-repo/semble)**: this library. [potion-code-16M-v2](https://huggingface.co/minishlab/potion-code-16M-v2) static embeddings + BM25 + the semble reranking stack.
## Excluded methods
The following tools were considered but not included in the main comparison:
- **[codanna](https://codanna.io)**: symbol-level semantic search with fastembed. Excluded because it does not support Haskell, Bash, Zig, Scala, Elixir, or Ruby (6 of the 19 benchmark languages).
- **[claude-context](https://github.com/zilliztech/claude-context)**: retrieval-augmented code search using OpenAI embeddings and a vector database. Excluded because it requires a paid OpenAI API key and a running vector-DB service.
- **[GitNexus](https://github.com/abhigyanpatwari/GitNexus)**: knowledge-graph code search (BM25 + local embeddings + RRF). Excluded because it does not support Bash, Elixir, Haskell, Lua, Scala, or Zig (6 of the 19 benchmark languages).
- **[codegraph](https://github.com/colbymchenry/codegraph)**: SQLite FTS5 symbol search + graph traversal. Excluded because it does not support Haskell, Bash, Elixir, or Zig (4 of the 19 benchmark languages).
- **[tgrep](https://github.com/microsoft/tgrep)**: indexed regex search. Excluded
because its results are nearly identical to ripgrep (0.1255 vs 0.1259 NDCG@10), and
ripgrep is already fast enough that indexing adds nothing in our benchmarks.
## Running the benchmarks
Repos are pinned in `repos.json` and cloned into `~/.cache/semble-bench`:
```bash
uv run python -m benchmarks.sync_repos # clone / update
uv run python -m benchmarks.sync_repos --check # verify only
```
All tools run CPU-only. semble uses `minishlab/potion-code-16M-v2`; CodeRankEmbed uses `nomic-ai/CodeRankEmbed` (137M params). The speed benchmark touches one repo per language with a cold-start index and 5 query runs per repo.
semble
```bash
uv run python -m benchmarks.run_benchmark
uv run python -m benchmarks.run_benchmark --repo fastapi --repo axios
uv run python -m benchmarks.run_benchmark --language python
```
Full runs write to `benchmarks/results/semble-hybrid-.json`.
Speed benchmark
```bash
uv run python -m benchmarks.speed_benchmark
uv run python -m benchmarks.speed_benchmark --tools semble zvec-grep # subset of tools
uv run python -m benchmarks.speed_benchmark --repo flask --repo axios # subset of repos
```
Writes to `benchmarks/results/speed-.json`.
Ablations
```bash
uv run python -m benchmarks.baselines.ablations
uv run python -m benchmarks.baselines.ablations --mode bm25
uv run python -m benchmarks.baselines.ablations --mode semble-semantic
```
probe
Needs `probe` on `$PATH` (`npm install -g @buger/probe`).
```bash
uv run python -m benchmarks.baselines.probe
uv run python -m benchmarks.baselines.probe --repo fastapi --repo axios
```
grepai
Needs `grepai` on `$PATH` and Ollama running with `nomic-embed-text` pulled:
```bash
ollama pull nomic-embed-text
```
```bash
uv run python -m benchmarks.baselines.grepai
uv run python -m benchmarks.baselines.grepai --repo fastapi --repo axios
```
Large repos take several minutes to index. Use `--timeout ` (default 120) for repos with many files:
```bash
uv run python -m benchmarks.baselines.grepai --timeout 1800 --output results.json
```
The `--output` flag enables resume mode: already-completed repos are skipped on restart.
cs (Code Spelunker)
Needs `cs` on `$PATH` (`go install github.com/boyter/cs/v3@latest`).
```bash
uv run python -m benchmarks.baselines.cs
uv run python -m benchmarks.baselines.cs --repo fastapi --repo axios
```
codebase-memory-mcp
Needs `codebase-memory-mcp` on `$PATH` (`uv tool install codebase-memory-mcp`, or `pip`/`npm`/`brew`). First run downloads a small platform binary.
```bash
uv run python -m benchmarks.baselines.codebase_memory
uv run python -m benchmarks.baselines.codebase_memory --repo fastapi --repo axios
```
Each repo is indexed under a `semble-bench-` project name and deleted again after evaluation, so it doesn't collide with any projects you have indexed for real use.
ck
Needs `ck` on `$PATH` (`cargo install ck-search` or `npm install -g @beaconbay/ck-search`). Requires outbound HTTPS to Hugging Face to download its `BAAI/bge-small-en-v1.5` embedding model on first run.
```bash
uv run python -m benchmarks.baselines.ck
uv run python -m benchmarks.baselines.ck --repo fastapi --repo axios
```
zvec-grep
Needs `zg` on `$PATH` (`npm install -g @zvec/zvec-grep@0.2.1`, requires Node.js 22+). Downloads the `potion-code-16m-v2` embedding model on first index. The published numbers were measured with 0.2.1; the runner records the installed version in its results file, and pinning matters because it parses `zg`'s human-readable output.
```bash
uv run python -m benchmarks.baselines.zvecgrep
uv run python -m benchmarks.baselines.zvecgrep --repo fastapi --repo axios
```
ripgrep
Needs `rg` on `$PATH` (`brew install ripgrep` / `apt install ripgrep`).
```bash
uv run python -m benchmarks.baselines.ripgrep
uv run python -m benchmarks.baselines.ripgrep --no-fixed-strings
```
ColGREP
Needs the `colgrep` binary on `$PATH`.
```bash
uv run python -m benchmarks.baselines.colgrep
uv run python -m benchmarks.baselines.colgrep --repo fastapi --repo axios
```
Runs with `--code-only` everywhere except bash repos (bash-it, bats-core, nvm), which use `--no-code-only` because ColGREP's code filter excludes `.sh`/`.bash` files.
CodeRankEmbed
Requires the `benchmark` extra (`uv sync --extra benchmark`).
```bash
uv run python -m benchmarks.baselines.coderankembed
uv run python -m benchmarks.baselines.coderankembed --repo fastapi --repo axios
```
Context-efficiency benchmark
Requires the `benchmark` extra (`uv sync --extra benchmark`) and `rg` on `$PATH`.
```bash
# Recall vs. token-budget across all queries; plots automatically.
uv run python -m benchmarks.token_efficiency recall
uv run python -m benchmarks.token_efficiency recall --repo fastapi
# Regenerate the plot from a saved recall payload.
uv run python -m benchmarks.token_efficiency plot
```
Writes `benchmarks/results/token-efficiency-.json` and `assets/images/token_efficiency.png`.
Plots
```bash
uv run python -m benchmarks.plot
```
Writes `speed_vs_ndcg_cold.png` and `speed_vs_ndcg_warm.png` to `assets/images/`.