## 📣 News and Discussions
- [10/16/2026][**Beam-1.0-501B-A23B**](https://huggingface.co/reflection/Beam-1.0-501B-A23B) We now support LoRA and full-parameter fine-tuning for Reflection AI's 501B-A23B sparse MoE with mixed sliding-window and full attention, using FSDP2, expert parallelism, and packed sequences. Check out the [Tulu3 LoRA EP8](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/beam/beam_1_0_501b_a23b_tulu3_lora_ep8.yaml) and [Tulu3 SFT EP64 8-node](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/beam/beam_1_0_501b_a23b_tulu3_ep64_8nodes.yaml) recipes and the [model coverage page](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/model-coverage/llm/reflection/beam-1-0-501b-a23b.mdx).
- [10/15/2026][**Muse Spark Open**](https://huggingface.co/meta-models/Muse-Spark-open-816B-A42B) Fine-tune Meta's MoE model with expert, pipeline, and context parallelism. See the [model card](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/model-coverage/vlm/muse/muse_spark_open.mdx). Explore the [image-text SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/9c9c4cfdb27461da359263bb342a086307ecaba7/examples/vlm_finetune/muse_spark/muse_spark_open_medpix_nonpacked4k_ep64_pp4_100steps.yaml), [LoRA](https://github.com/NVIDIA-NeMo/Automodel/blob/9c9c4cfdb27461da359263bb342a086307ecaba7/examples/vlm_finetune/muse_spark/muse_spark_open_medpix_nonpacked4k_lora_ep32.yaml), and [128K long-context packed SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/9c9c4cfdb27461da359263bb342a086307ecaba7/examples/llm_finetune/muse_spark/muse_spark_open_tulu3_packed128k_ep32_pp2_cp32_magi.yaml) recipes.
- [10/15/2026][**NVIDIA Nemotron 3.5 Super VL**](https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Super-VL-120B-A12B-BF16) Fine-tune the 120B-A12B vision-language model with [CORD-v2 SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/nemotron_3_5_super_vl/nemotron_3_5_super_vl_cord_v2.yaml), [CORD-v2 PEFT (LoRA)](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/nemotron_3_5_super_vl/nemotron_3_5_super_vl_cord_v2_peft.yaml), [256K packed SFT (GB200)](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/nemotron_3_5_super_vl/nemotron_3_5_super_vl_tulu3_packed_256k_cp8_ep16_gb200.yaml). See the [CORD-v2 tutorial](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/guides/vlm/nemotron-3-5-super-vl.mdx) for data preparation, training, and evaluation.
- [10/14/2026][**Step-5-Preview-BF16**](https://huggingface.co/stepfun-ai/Step-5-Preview-BF16) We now support StepFun's 600B-A27B sliding-window and sparse-attention MoE with FSDP2, expert, pipeline and context parallelism. Check out the [model coverage page](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/model-coverage/llm/stepfun-ai/step-5-preview-bf16.mdx) and the [Tulu3 SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/stepfun/step_5_preview_tulu3_sft.yaml), [LoRA](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/stepfun/step_5_preview_tulu3_lora.yaml), and [128K long-context CP32](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/stepfun/step_5_preview_tulu3_packed128k_cp32.yaml) recipes.
- [10/12/2026][**FLUX 3 Image Klein Base**](https://docs.nvidia.com/nemo/automodel/nightly/model-coverage/diffusion/black-forest-labs/flux-3-image-klein-base) We added text-to-image and image-editing LoRA fine-tuning for Black Forest Labs' base image model. See the [T2I LoRA recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/diffusion/finetune/flux3_t2i_flow_lora.yaml) and [model guide](https://docs.nvidia.com/nemo/automodel/nightly/model-coverage/diffusion/black-forest-labs/flux-3-image-klein-base) for checkpoint setup and the 100-step validation scope.
- [10/04/2026][**HunyuanImage-3.0**](https://huggingface.co/tencent/HunyuanImage-3.0) We now support text-to-image full fine-tuning and LoRA for Tencent's 80B-A13B MoE multimodal decoder with FSDP2 and expert parallelism, many thanks to [@Khazic](https://github.com/khazic). Check out the [full fine-tuning](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/diffusion/finetune/hunyuan_image3_t2i_flow.yaml) and [LoRA](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/diffusion/finetune/hunyuan_image3_t2i_flow_lora.yaml) recipes and the [model coverage page](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/model-coverage/diffusion/tencent/hunyuan-image-3.mdx).
- [09/28/2026][**Qwen-Image-2.1**](https://huggingface.co/Qwen/Qwen-Image-2.1) We now support text-to-image full fine-tuning and LoRA for Qwen's 7B single-stream DiT conditioned on Qwen3-VL. Check out the [full fine-tuning](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/diffusion/finetune/qwen_image_21_t2i_flow.yaml) and [LoRA](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/diffusion/finetune/qwen_image_21_t2i_flow_lora.yaml) recipes and the [model coverage page](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/model-coverage/diffusion/qwen/qwen-image-2-1.mdx).
- [09/26/2026][**MiMo-V2.5-Pro**](https://huggingface.co/XiaomiMiMo/MiMo-V2.5-Pro) We now support full-parameter fine-tuning for Xiaomi's hybrid full and sliding-window attention Mixture-of-Experts model from its FP8 checkpoint. Check out the [HellaSwag PP18/EP8 recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/mimo_v25/mimo_v25_pro_hellaswag.yaml) and [model coverage page](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/model-coverage/llm/xiaomimimo/mimo-v2-5-pro.mdx).
- [09/22/2026][**MiMo-V2.6-Flash-RL**](https://huggingface.co/XiaomiMiMo/MiMo-V2.6-Flash-RL) We now support full-parameter fine-tuning for Xiaomi's multimodal Mixture-of-Experts model with expert, pipeline, and context parallelism. Check out the [packed Tulu3 EP64/CP2 recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/mimo_v2_flash/mimo_v2_6_flash_rl_tulu3_packed4k_ep64_cp2_100steps.yaml), [non-packed MedPix EP64 recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/mimo_v2_flash/mimo_v2_6_flash_rl_medpix_nonpacked4k_ep64_100steps.yaml), and [model coverage page](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/model-coverage/llm/xiaomimimo/mimo-v2-flash.mdx).
- [09/11/2026][**DeepSeek-V4.1-Flash**](https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash) We now support SFT and LoRA for DeepSeek's causal encoder/decoder backbone with CSA2, single-pass mHC, and Engram, many thanks to [@Khazic](https://github.com/khazic). Check out the [HellaSwag EP64 16-node recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/deepseek_v41/deepseek_v41_flash_hellaswag_ep64_16nodes.yaml) and [model coverage page](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/model-coverage/llm/deepseek-ai/deepseek-v41-flash.mdx).
- [08/29/2026][**GLM-5.3**](https://huggingface.co/zai-org/GLM-5.3) We now support full-parameter fine-tuning of Z.ai's GLM-5.3 with cuDNN DSA and HybridEP. Check out the [EP64/PP4 recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/glm/glm_5.3_tulu3_4k_cudnn_100step.yaml) and [model coverage page](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/model-coverage/llm/thudm/glm5-moe-dsa.mdx).
- [08/28/2026][**Ox Alpha / GLM-5.3-Flash**](https://huggingface.co/zai-org/GLM-5.3-Flash) We now support fine-tuning Z.ai's 320B-A18B hybrid-attention MoE VLM with packed CP and EP. Check out the [MedPix EP72/CP2 recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/glm5_next/glm5_3_flash_medpix_packed2k_ep72_cp2_100steps.yaml) and [model coverage page](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/model-coverage/vlm/thudm/glm-5-3-flash.mdx).
- [08/26/2026][**Qwen3.8-Flash-Next**](https://huggingface.co/Qwen/Qwen3.8-Flash-Next) We now support full-parameter fine-tuning for the 180B hybrid-attention Engram MoE with FlexAttention sparse QSA, packed (THD) sequences, and model-owned context parallelism. Check out the [HellaSwag EP64 recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/qwen/qwen3_8_flash_next_180b_hellaswag_ep64.yaml) and [model coverage page](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/model-coverage/llm/qwen/qwen3-8-flash-next.mdx).
- [08/21/2026][**DFlash 2**](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/guides/speculative/dflash.mdx) We now support training DFlash 2 drafters: the DFlash block-diffusion backbone plus a two-tap dynamic convolution and a pairwise path selector for higher acceptance lengths. Check out the [Qwen3-8B recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/speculative/dflash/qwen3_dflash2.yaml) and the [speculative decoding overview](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/speculative/README.md).
- [08/14/2026][**Qwen3.8-27B**](https://huggingface.co/Qwen/Qwen3.8-27B) We now support full-parameter SFT and LoRA fine-tuning for Qwen's dense 27B vision-language model. Check out the [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/qwen3_8/qwen3_8_27b.yaml) and [LoRA](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/qwen3_8/qwen3_8_27b_lora.yaml) recipes, [fine-tuning guide](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/guides/vlm/qwen3-8.mdx), and [model coverage page](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/model-coverage/vlm/qwen/qwen3-8-vl.mdx).
- [08/12/2026][**Qwen3.8-2.4T-A95B**](https://huggingface.co/Qwen/Qwen3.8-2.4T-A95B) We now support full-parameter fine-tuning for `Qwen/Qwen3.8-2.4T-A95B` checkpoints. Check out the [HellaSwag EP32/PP8 recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/qwen/qwen3_8_2_4t_a95b_hellaswag_ep32_pp8.yaml) and [model coverage page](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/model-coverage/llm/qwen/qwen3-8-2-4t-a95b.mdx).
- [08/12/2026][**North Micro Vision**](https://huggingface.co/CohereLabs/North-Micro-Vision-Instruct) We now support LoRA fine-tuning for Cohere Labs' 2.4B-parameter native-resolution vision-language model. Check out the [RDR recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/cohere_micro_vision/north_micro_vision_rdr.yaml) and [model coverage page](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/model-coverage/vlm/coherelabs/north-micro-vision.mdx).
- [08/10/2026][**MuseGlimmer**](https://huggingface.co/meta-models/Muse-Glimmer-30B) We now support SFT/LoRA the dense 30B MuseGlimmer vision-language model, including TP/CP packed sequence recipes. Check out the [recipes](https://github.com/NVIDIA-NeMo/Automodel/tree/main/examples/vlm_finetune/muse_glimmer) and [model coverage page](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/model-coverage/vlm/muse/muse_glimmer.mdx).
- [08/08/2026][**Nemotron 3.5 Lightning**](https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-BF16) We now support LoRA fine-tuning for NVIDIA's 30B-A3B hybrid MoE model with multi-token prediction. Check out the [HellaSwag recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/nemotron/nemotron_nano_v3_5_lightning_hellaswag_peft.yaml) and [model coverage page](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/model-coverage/llm/nvidia/nemotron-h.mdx).
- [07/30/2026][**Inkling-Small**](https://huggingface.co/thinkingmachines/Inkling-Small) We now support full-parameter fine-tuning for the 276B-parameter, 12B-active Inkling-Small model on 64 H100 GPUs. Check out the [MedPix EP64 recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/inkling/Inkling_small_medpix_ep64.yaml) and [model coverage page](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/model-coverage/vlm/thinkingmachines/inkling.mdx).
- [07/29/2026][**Kimi K3**](https://huggingface.co/moonshotai/Kimi-K3) We now support full-parameter fine-tuning for Moonshot AI's 2.8T-parameter MoE model on NVIDIA GB200. Check out the [HellaSwag EP32/PP8 recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/kimi/k3_hellaswag.yaml) on 256 GB200.
- [07/21/2026][**Laguna S 2.1**](https://huggingface.co/poolside/Laguna-S-2.1) We now support finetuning Poolside's 118B-A8B Laguna S 2.1 MoE model. Check out our [HellaSwag EP16 recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/laguna/laguna_s_2p1_hellaswag_ep16.yaml).
- [07/18/2026][**Inkling VLM MoE**](https://huggingface.co/thinkingmachines/Inkling) We now support finetuning Inkling. Check out our [MedPix recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/inkling/inkling_medpix.yaml).
- [06/27/2026] [**Speculative decoding in NeMo AutoModel**](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/guides/speculative/eagle.mdx) Train target-aligned drafters end to end: EAGLE-1/2/3, P-EAGLE, DFlash, and DeepSeek's newly released [DSpark](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/speculative/dspark/qwen3_0.6b_dspark.yaml). Huge thanks to [@Khazic](https://github.com/khazic) for the speculative decoding stack and [@kashif](https://github.com/kashif) for DSpark support.
- [06/21/2026][**GLM-5.2**](https://huggingface.co/zai-org/GLM-5.2) We now support finetuning `zai-org/GLM-5.2` with IndexShare DSA, optional TileLang sparse kernels, and long-context CP recipes. Check out our [32K long-context recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/glm/glm_5.2_tulu3_32k_tilelang_cp8.yaml) and [model coverage page](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/model-coverage/llm/thudm/glm5-moe-dsa.mdx).
- [06/15/2026][**DiffusionGemma**](https://huggingface.co/google/diffusiongemma-26B-A4B-it). We now support fine-tuning the `google/diffusiongemma-26B-A4B-it` model. Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/dllm_sft/diffusion_gemma_sft.yaml) and [guide](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/guides/dllm/diffusiongemma.mdx).
- [06/12/2026][**MiniMax M3**](https://huggingface.co/MiniMaxAI/MiniMax-M3) We now support finetuning MiniMax's MiniMax-M3. Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/minimax_m3/minimax_m3_vl_sft_ep32pp4.yaml) and [guide](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/guides/vlm/minimax-m3.mdx).
- [06/04/2026][**Nemotron-3 Ultra**](https://huggingface.co/nvidia/NVIDIA-Nemotron-3-Ultra-550B-A55B-BF16) We now support finetuning NVIDIA's Nemotron 3 Ultra 550B A55B. Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/nemotron/nemotron_ultra_v3_hellaswag_peft.yaml) and [guide](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/guides/llm/nemotron-3-ultra.md).
- [06/03/2026][**Gemma 4 12B**](https://huggingface.co/google/gemma-4-12B) We now support finetuning the dense `google/gemma-4-12B` model. Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/gemma/gemma_4_12b_hellaswag.yaml).
- [05/27/2026][**Step-3.7-Flash**](https://huggingface.co/stepfun-ai/Step-3.7-Flash) We added model coverage for Stepfun AI's 198B-A13B MoE vision-language model, targeting image/video agentic developer workflows with a 256k context language backbone and 1.8B ViT vision tower. See the [model coverage page](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/model-coverage/vlm/stepfun-ai/step-3-7.md).
- [05/19/2026][**Ling 2.0**](https://huggingface.co/collections/inclusionAI/ling-20) We now support finetuning the inclusionAI Ling 2.0 MoE family (`inclusionAI/Ling-mini-2.0`, `inclusionAI/Ling-flash-2.0`, and `inclusionAI/Ling-1T`), thanks to [@Hayden727](https://github.com/Hayden727). Check out our [recipes](https://github.com/NVIDIA-NeMo/Automodel/tree/main/examples/llm_finetune/ling).
- [05/17/2026][**ERNIE 4.5**](https://huggingface.co/baidu) and [**MiMo-V2-Flash**](https://huggingface.co/XiaomiMiMo/MiMo-V2-Flash) We now support finetuning `baidu/ERNIE-4.5-0.3B-PT`, `baidu/ERNIE-4.5-21B-A3B-PT`, and `XiaomiMiMo/MiMo-V2-Flash`. Check out our ERNIE [dense recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/ernie4_5/ernie4_5_0p3b_hellaswag.yaml), ERNIE [MoE recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/ernie4_5/ernie4_5_21b_a3b_hellaswag.yaml), and MiMo [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/mimo_v2_flash/mimo_v2_flash_hellaswag.yaml).
- [04/29/2026][**Mistral Medium 3.5**](https://huggingface.co/mistralai/Mistral-Medium-3.5-128B) We now support finetuning Mistral AI's 128B FP8-native VLM Mistral Medium 3.5. Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/mistral3p5/mistral3p5_128b_medpix.yaml) and [guide](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/guides/vlm/mistral-medium-3-5.md).
- [04/28/2026][**Nemotron-3-Nano-Omni**](https://huggingface.co/nvidia/Nemotron-3-Nano-Omni-30B-A3B-Reasoning-BF16) We now support finetuning `nvidia/Nemotron-3-Nano-Omni-30B-A3B-Reasoning-BF16`, NVIDIA's 30B-A3B omnimodal MoE (text · image · audio) with NemotronH hybrid Mamba+Attention backbone. Check out our [SFT recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/nemotron_omni/nemotron_omni_cord_v2.yaml), [LoRA recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/nemotron_omni/nemotron_omni_cord_v2_peft.yaml), and [guide](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/guides/vlm/nemotron-omni.md).
- [04/28/2026][**Hy3-preview**](https://huggingface.co/tencent/Hy3-preview) We now support finetuning `tencent/Hy3-preview`, thanks to [@Khazic](https://github.com/khazic). Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/hy_v3/hy3_preview_deepep.yaml).
- [04/25/2026][**DeepSeek V4 Flash**](https://huggingface.co/deepseek-ai/DeepSeek-V4-Flash) We now support finetuning `deepseek-ai/DeepSeek-V4-Flash`, thanks to [@Khazic](https://github.com/khazic). Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/deepseek_v4/deepseek_v4_flash_hellaswag.yaml) and [guide](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/guides/llm/dsv4-flash.md).
- [04/22/2026][**Qwen3.6-27B**](https://huggingface.co/Qwen/Qwen3.6-27B) We now support finetuning `Qwen/Qwen3.6-27B`. Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/qwen3_5/qwen3_6_27b.yaml).
- [04/20/2026][**Qwen-Image**](https://huggingface.co/Qwen/Qwen-Image) We now support finetuning `Qwen/Qwen-Image`, thanks to [@harshareddy832](https://github.com/harshareddy832). Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/diffusion/finetune/qwen_image_t2i_flow.yaml).
- [04/16/2026][**Qwen3.6 MoE**](https://huggingface.co/Qwen/Qwen3.6-35B-A3B) We now support finetuning `Qwen/Qwen3.6-35B-A3B`. Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/qwen3_5_moe/qwen3_6_35b.yaml).
- [04/16/2026][**LLaVA-OneVision-1.5**](https://huggingface.co/lmms-lab/LLaVA-OneVision-1.5-4B-Instruct) We now support finetuning `lmms-lab/LLaVA-OneVision-1.5-4B-Instruct`, thanks to [@vgauraha62](https://github.com/vgauraha62). Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/llava_onevision/llava_ov_1_5_4b_finetune.yaml).
- [04/12/2026][**MiniMax-M2.7**](https://huggingface.co/MiniMaxAI/MiniMax-M2.7) We now support finetuning `MiniMaxAI/MiniMax-M2.7`. Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/minimax_m2/minimax_m2.7_hellaswag_pp.yaml).
- [04/07/2026][**GLM-5.1**](https://huggingface.co/zai-org/GLM-5.1) We now support finetuning `zai-org/GLM-5.1`. GLM-5.1 is Zhipu AI's latest open-source MoE model featuring MLA + DeepSeek Sparse Attention. Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/glm/glm_5.1_hellaswag_pp.yaml) and [discussion](https://github.com/NVIDIA-NeMo/Automodel/discussions/1719).
- [04/02/2026][**Gemma 4**](https://huggingface.co/collections/google/gemma-4) We support fine-tuning for Gemma4 (2B, 4B, 31B, 26BA4B)! Check out our [recipes](https://github.com/NVIDIA-NeMo/Automodel/tree/main/examples/vlm_finetune/gemma4).
- [03/30/2026]**NeMo AutoModel** ships with **agent-friendly skills** in [skills/](https://github.com/NVIDIA-NeMo/Automodel/tree/main/skills) to help you with common development tasks (e.g., running a recipe, model onboarding, development) across the repo. We welcome PRs that improve existing skills or add new ones.
- [03/16/2026][**Mistral Small 4**](https://huggingface.co/mistralai/Mistral-Small-4-119B-2603) We support fine-tuning for Mistral4 119B! Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/mistral4/mistral4_medpix.yaml).
- [03/11/2026][**Nemotron Super v3**](https://huggingface.co/nvidia/NVIDIA-Nemotron-3-Super-120B-A12B-BF16) We support fine-tuning for `nvidia/NVIDIA-Nemotron-3-Super-120B-A12B-BF16`. Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/nemotron/nemotron_super_v3_hellaswag.yaml).
- [03/11/2026][**GLM-5**](https://huggingface.co/zai-org/GLM-5) We now support finetuning `zai-org/GLM-5`. Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/glm/glm_5_hellaswag_pp.yaml).
- [03/02/2026][**Qwen3.5 small models**](https://huggingface.co/collections/Qwen/qwen35) We support finetuning for Qwen3.5 small models 0.8B, 2B, 4B ([recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/qwen3_5/qwen3_5_4b.yaml)) and 9B ([recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/qwen3_5/qwen3_5_9b.yaml))
- [02/16/2026][**Qwen3.5 MoE**](https://huggingface.co/collections/Qwen/qwen35) We support finetuning for `Qwen/Qwen3.5-397B-A17B` ([recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/qwen3_5_moe/qwen3_5_moe_medpix.yaml)) and `Qwen/Qwen3.5-35B-A3B` ([recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/qwen3_5_moe/qwen3_5_35b.yaml))
Previous News
- [02/13/2026] [**MiniMax-M2.5**](https://huggingface.co/MiniMaxAI/MiniMax-M2.5) We support finetuning for `MiniMaxAI/MiniMax-M2.5`. Checkout our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/minimax_m2/minimax_m2.5_hellaswag_pp.yaml)
- [02/11/2026] [**GLM-4.7-Flash**](https://huggingface.co/zai-org/GLM-4.7-Flash) We now support finetuning GLM-4.7-Flash. Checkout our [packed sequence recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/glm/glm_4.7_flash_te_packed_sequence.yaml)
- [02/09/2026] [**MiniMax-M2**](https://huggingface.co/MiniMaxAI/MiniMax-M2) We support finetuning for `MiniMaxAI/MiniMax-M2`. Checkout our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/5f63eb428bacf4146e9a5ae9949d58c5751df7b9/examples/llm_finetune/minimax_m2/minimax_m2.1_hellaswag_pp.yaml)
- [02/06/2026] [**Qwen3 VL 235B**](https://huggingface.co/Qwen/Qwen3-VL-235B-A22B-Instruct) We support finetuning for `Qwen/Qwen3-VL-235B-A22B-Instruct`. Checkout our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/qwen3/qwen3_vl_moe_235b.yaml)
- [02/06/2026] [**GLM4.7**](https://huggingface.co/zai-org/GLM-4.7) We now support finetuning GLM4.7. Checkout our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/glm/glm_4.7_te_deepep.yaml)
- [02/06/2026] [**Step3.5-flash**](https://huggingface.co/stepfun-ai/Step-3.5-Flash) is out! Finetune it with our [finetune recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/stepfun/step_3.5_flash_hellaswag_pp.yaml)
- [02/05/2026] [**DeepSeek-V3.2**](https://huggingface.co/deepseek-ai/DeepSeek-V3.2) is out! Checkout out [the finetune recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/deepseek_v32/deepseek_v32_hellaswag_pp.yaml)!
- [02/04/2026] [**Kimi K2.5 VL**](https://huggingface.co/moonshotai/Kimi-K2.5) is out! Finetune it with [NeMo AutoModel](https://github.com/NVIDIA-NeMo/Automodel/discussions/1161)
- [01/30/2026] [**Kimi VL**](https://huggingface.co/moonshotai/Kimi-VL-A3B-Instruct) We support fine-tuning for `moonshotai/Kimi-VL-A3B-Instruct`. Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/kimi/kimi2vl_cordv2.yaml).
- [01/12/2026] [**Nemotron Flash**](https://huggingface.co/nvidia/Nemotron-Flash-1B) We support fine-tuning for `nvidia/Nemotron-Flash-1B`. Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/nemotron_flash/nemotron_flash_1b_squad.yaml).
- [01/12/2026] [**Nemotron Parse**](https://huggingface.co/nvidia/NVIDIA-Nemotron-Parse-v1.1) We support fine-tuning `nvidia/NVIDIA-Nemotron-Parse-v1.1` ([recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/nemotron/nemotron_parse_v1_1.yaml), [tutorial](https://github.com/NVIDIA-NeMo/Automodel/blob/main/tutorials/nemotron-parse/finetune.ipynb) and [try on Brev](https://brev.nvidia.com/launchable/deploy/now?launchableID=env-3C6LDKU2DfOvpVTFhjw3YQ4djPM)).
- [01/07/2026] [**Devstral-Small**](https://huggingface.co/mistralai/Devstral-Small-2-24B-Instruct-2512) We support fine-tuning for `mistralai/Devstral-Small-2-24B-Instruct-2512`. Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/devstral/devstral2_small_2512_squad.yaml).
- [12/18/2025] [**FunctionGemma**](https://huggingface.co/google/functiongemma-270m-it) is out! Finetune it with [NeMo AutoModel](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/guides/llm/toolcalling.md)!
- [12/15/2025] [**NVIDIA-Nemotron-3-Nano-30B-A3B**](https://huggingface.co/nvidia/NVIDIA-Nemotron-3-Nano-30B-A3B-FP8) is out! Finetune it with [NeMo AutoModel](https://github.com/NVIDIA-NeMo/Automodel/discussions/976)!
- [11/6/2025] [Accelerating Large-Scale Mixture-of-Experts Training in PyTorch](https://developer.nvidia.com/blog/accelerating-large-scale-mixture-of-experts-training-in-pytorch/)
- [10/6/2025] [Enabling PyTorch Native Pipeline Parallelism for 🤗 Hugging Face Transformer Models](https://github.com/NVIDIA-NeMo/Automodel/discussions/589)
- [9/22/2025] [Fine-tune Hugging Face Models Instantly with Day-0 Support with NVIDIA NeMo AutoModel](https://github.com/NVIDIA-NeMo/Automodel/discussions/477)
- [9/18/2025] [🚀 NeMo Framework Now Supports Google Gemma 3n: Efficient Multimodal Fine-tuning Made Simple](https://github.com/NVIDIA-NeMo/Automodel/discussions/494)
## Overview
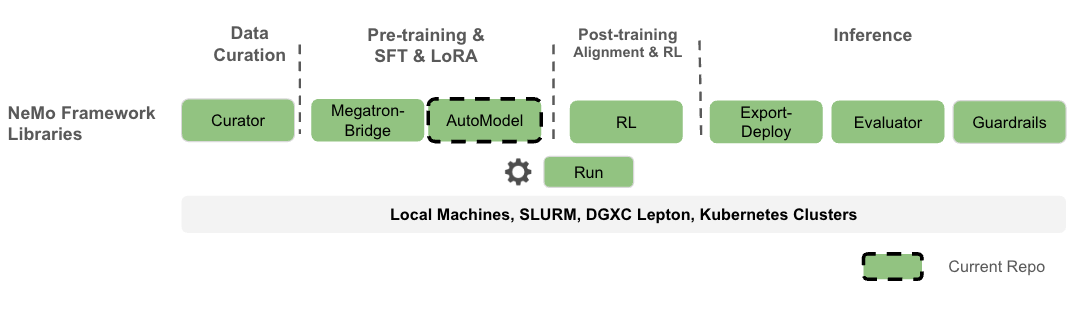
Nemo AutoModel is a Pytorch DTensor‑native SPMD open-source training library under [NVIDIA NeMo Framework](https://github.com/NVIDIA-NeMo), designed to streamline and scale training and finetuning for LLMs, VLMs, diffusion models, and retrieval models. Designed for flexibility, reproducibility, and scale, NeMo AutoModel enables both small-scale experiments and massive multi-GPU, multi-node deployments for fast experimentation in research and production environments.
What you can expect:
- **Hackable** with a modular design that allows easy integration, customization, and quick research prototypes.
- **Minimal ceremony**: YAML-driven recipes; override any field using CLI.
- **High performance and flexibility** with custom kernels and DTensor support.
- **Seamless integration** with Hugging Face for day-0 model support, ease of use, and wide range of supported models.
- **Efficient resource management** using Kubernetes and Slurm, enabling scalable and flexible deployment across configurations.
- **Documentation** with step-by-step guides and runnable examples.
### Why PyTorch Distributed and SPMD
- **One program, any scale**: The same training script runs on 1 GPU or 1000+ by changing the mesh.
- **PyTorch Distributed native**: Partition model/optimizer states with `DeviceMesh` + placements (`Shard`, `Replicate`).
- **SPMD first**: Parallelism is configuration. No model rewrites when scaling up or changing strategy.
- **Decoupled concerns**: Model code stays pure PyTorch; parallel strategy lives in config.
- **Composability**: Mix **tensor**, **sequence**, and **data** parallel by editing placements.
- **Portability**: Fewer bespoke abstractions; easier to reason about failure modes and restarts.
## Table of Contents
- [Feature Roadmap](#feature-roadmap)
- [Getting Started](#getting-started)
- [LLM](#llm-pre-training)
- [Pre-training](#llm-pre-training)
- [Supervised Fine-Tuning (SFT)](#llm-supervised-fine-tuning-sft)
- [Parameter-Efficient Fine-Tuning (PEFT)](#llm-parameter-efficient-fine-tuning-peft)
- [VLM](#vlm-supervised-fine-tuning-sft)
- [Supervised Fine-Tuning (SFT)](#vlm-supervised-fine-tuning-sft)
- [Parameter-Efficient Fine-Tuning (PEFT)](#vlm-parameter-efficient-fine-tuning-peft)
- [Supported Models](#supported-models)
- [Performance](#performance)
- [Interoperability](#-interoperability)
- [Contributing](#-contributing)
- [License](#-license)
> TL;DR: SPMD turns “how to parallelize” into a *runtime layout choice*, not a code fork.
## Feature Roadmap
✅ _Implemented on `main`_ | 🔜 _Planned_
For released features, see the [release notes](https://github.com/NVIDIA-NeMo/Automodel/releases). Docker examples target the [26.10 container](https://catalog.ngc.nvidia.com/orgs/nvidia/containers/nemo-automodel/tags?version=26.10.00).
High-throughput scalable training
- ✅ **PyTorch DTensor-native SPMD training** Same training script can scale from 1 GPU to large multi-node jobs by changing the device mesh/config.
- ✅ **Composable Parallelism** - PyTorch native FSDP2, HSDP, TP, CP, SP and PP for distributed training.
- ✅ **Optimized kernels** - Uses NVIDIA-oriented kernel paths such as Transformer Engine, DeepEP, FlexAttn, TorchSDPA, fused attention, rotary embeddings, Triton, and optional kernel patches.
- ✅ **MoE acceleration** - Includes MoE routing and DeepEP integration, plus expert-parallel configurations used in DeepSeek, Qwen MoE, GPT-OSS, and Nemotron MoE benchmarks.
- ✅ **FP8 and mixed precision** - FP8 support with torchao and Transformer Engine.
- ✅ **MXFP8 MoE training** - Transformer Engine and torchao MXFP8 grouped-expert training on GB200.
- ✅ **Activation checkpointing** - Trades recomputation for lower activation memory, especially useful with FSDP and memory-efficient losses.
- ✅ **Memory-efficient loss** - Linear-Cut / fused linear cross entropy avoids materializing full logits for the loss, reducing output-layer memory pressure.
- ✅ **Sequence packing** - Packs variable-length examples together to reduce padding compute and improve GPU utilization.
- ✅ **FlashAttention packed-sequence support** - Packed masks can feed variable-length FlashAttention paths using per-document cu_seqlens.
- ✅ **DCP** - Supports PyTorch DCP and SafeTensors, sharded and consolidated layouts, merge/reshard utilities, and Hugging Face-compatible outputs.
- ✅ **Async checkpointing** - Can write checkpoints in the background to reduce training stalls caused by I/O.
- ✅ **Dion and Muon optimizers** - Distributed optimizer integrations with typed recipe configuration.
- ✅ **Environment Support** - SLURM, interactive, SkyPilot, and Kubernetes (via SkyPilot) launchers.
SOTA algorithms
- ✅ **Pre-training** - Support for model pre-training, including DeepSeekV3.
- ✅ **Learning Algorithms** - SFT (Supervised Fine-Tuning), PEFT (LoRA, QLoRA), and QAT (Quantization-Aware Training).
- ✅ **Knowledge distillation** - Support for knowledge distillation with LLMs.
- ✅ **VLM knowledge distillation** - Chunked KD loss and a Qwen3.5-VL teacher-student recipe.
- ✅ **Speculative decoding training** - Train target-aligned EAGLE-1/2/3, P-EAGLE, DFlash, DFlash 2, and DSpark drafters for faster verified generation.
Model Coverage and 🤗 Ecosystem compatibility
- ✅ **Transformers v5 🤗** - Built on latest transformers with device-mesh driven parallelism.
- ✅ **🤗 HuggingFace Integration** - Works with dense models (e.g., Qwen, Llama3, etc) and large MoEs (e.g., DSv3, DSv4).
- ✅ **VLM** - Finetuning for VLMs (Qwen2.5/3/3.5/3.6 VL, Gemma-3/3n/4 VL, Mistral 3.5/4, LLaVA-OneVision-1.5, Kimi-VL, etc.).
- ✅ **Omnimodal** - Finetuning for omnimodal MoE models (Nemotron-3-Nano-Omni, Qwen3-Omni).
- ✅ **Diffusion** - Pretraining and LoRA finetuning for image/video diffusion models (Qwen-Image, Qwen-Image-2.1, FLUX, [FLUX 3 Image Klein Base](https://docs.nvidia.com/nemo/automodel/nightly/model-coverage/diffusion/black-forest-labs/flux-3-image-klein-base), Wan2.1, Wan2.2-T2V-A14B, Hunyuan).
- ✅ **dLLM** - Discrete diffusion LM finetuning (LLaDA, LLaDA2, Nemotron-Labs-Diffusion, DiffusionGemma).
- ✅ **Retrieval** - Bi-encoder and cross-encoder training with in-batch negative sampling.
- ✅ **Extended MoE support** - GPT-OSS, Kimi K3, Qwen3 / Qwen3.5 / Qwen3.6 MoE, Qwen-next, MiniMax-M2.x, GLM-4.7 / GLM-5 / GLM-5.1 / GLM-5.2 / GLM-5.3 / GLM-5.3-Flash, DeepSeek V3.2 / V4 / V4-Flash, ERNIE 4.5, MiMo-V2-Flash / MiMo-V2.5-Pro, Ling 2.0, Hy3-preview.
Agentic Development and UX
- ✅ **Agent-friendly skills** - Curated [`skills/`](https://github.com/NVIDIA-NeMo/Automodel/tree/main/skills) for common dev tasks (recipe runs, model onboarding, CI).
Planned
- 🔜 **Unified Engine API and recipes** - Introduce a common engine and consolidate the LLM and VLM recipe paths.
- 🔜 **Composable component configuration** - Complete the typed config and `.build()` refactor across data and remaining components.
- 🔜 **Packed long-context training with CP** - Combine THD sequence packing with context parallelism, including DeepSeek V4 coverage.
- 🔜 **Kernel and runtime upgrades** - Add partial CUDA graphs, evaluate FlashAttention 3/4, and upgrade to DeepEP v2.
- 🔜 **Multimodal retrieval** - Expand vision-language retrieval datasets and models and improve retriever performance.
- 🔜 **Convergence and regression testing** - Add automated loss, evaluation, and performance gates to NeMo CI.
- 🔜 **Transformers 5.12 alignment** - Upgrade the Transformers integration and restore affected model parity coverage.
- 🔜 **Recipe consistency** - Align diffusion recipes with the shared AutoModel recipe and configuration patterns.
## Getting Started
Run a 10-step Qwen3-0.6B fine-tuning example on two GPUs with the container:
```bash
mkdir -p checkpoints
docker run --gpus all -it --rm --shm-size=8g \
-v "$PWD/checkpoints:/opt/Automodel/checkpoints" \
nvcr.io/nvidia/nemo-automodel:26.10.00 \
automodel /opt/Automodel/examples/llm_finetune/qwen/qwen3_0p6b_hellaswag.yaml \
--nproc-per-node 2 \
--step_scheduler.max_steps 10
```
The model and HellaSwag dataset are public; no Hugging Face token is required. Checkpoints are saved to the mounted `checkpoints` directory.
For source installation, use **uv** for reproducible Python environments.
```bash
# Setup environment before running any recipes
uv venv
# Choose ONE:
uv sync --frozen # LLM recipes (default)
# uv sync --frozen --extra vlm --extra vlm-media # VLM recipes (Qwen/Mistral/Omni need vlm-media for video/vision; fixes: ImportError: qwen_vl_utils is not installed)
# uv sync --frozen --extra cuda # Optional CUDA deps (e.g., Transformer Engine, Mamba SSM)
# uv sync --frozen --extra cuda_source # Optional bitsandbytes dependency
# uv sync --frozen --extra all # Most optional deps (includes `vlm` and `cuda`; NOTE: excludes media — add --extra media for video/image decode)
# uv sync --frozen --all-extras # Everything (includes `fa`, `moe`, `media`, etc.)
# One-off runs (examples):
# uv run --extra vlm
# uv run --extra cuda
uv run python -c "import nemo_automodel; print('NeMo AutoModel ready')"
```
### Run a Recipe
All recipes are launched via the `automodel` CLI (or its short alias `am`). Each YAML config specifies the recipe class and all training parameters:
```bash
# LLM example: multi-GPU fine-tuning of Qwen3-0.6B with FSDP2 (no HF token required)
automodel examples/llm_finetune/qwen/qwen3_0p6b_hellaswag.yaml --nproc-per-node 8
# VLM example: single-GPU fine-tuning (Gemma-3-VL) with LoRA
automodel examples/vlm_finetune/gemma3/gemma3_vl_4b_cord_v2_peft.yaml
# Both commands also work with uv run:
uv run automodel examples/llm_finetune/qwen/qwen3_0p6b_hellaswag.yaml --nproc-per-node 8
```
> [!TIP]
> **NeMo-Run submission:** The `cli` extra adds NeMo Run to the base package: `uv pip install "nemo-automodel[cli]"`. It is additive; the base package still installs its core training dependencies, including PyTorch.
## LLM Pre-training
### LLM Pre-training Single Node
We provide an example SFT experiment using the [FineWeb dataset](https://arxiv.org/abs/2406.17557/) with a nano-GPT model, ideal for quick experimentation on a single node.
```sh
automodel examples/llm_pretrain/nanogpt_pretrain.yaml --nproc-per-node 8
```
## LLM Supervised Fine-Tuning (SFT)
We provide an example SFT experiment using the [HellaSwag dataset](https://rowanzellers.com/hellaswag/).
### LLM SFT Single Node
The default SFT configuration is set to run on a single GPU. To start the experiment:
```sh
automodel examples/llm_finetune/qwen/qwen3_0p6b_hellaswag.yaml
```
This fine-tunes [Qwen3-0.6B](https://huggingface.co/Qwen/Qwen3-0.6B) on HellaSwag using a single GPU. The model and dataset are public; no Hugging Face token is required.
To use multiple GPUs on a single node, add the `--nproc-per-node` argument:
```sh
automodel examples/llm_finetune/qwen/qwen3_0p6b_hellaswag.yaml --nproc-per-node 8
```
### LLM SFT Multi Node
To launch on a SLURM cluster, copy the reference sbatch script and adapt it to your cluster:
```sh
cp slurm.sub my_cluster.sub
# Edit my_cluster.sub — change CONFIG, #SBATCH directives, container, mounts, etc.
sbatch my_cluster.sub
```
All cluster-specific settings (nodes, GPUs, partition, container, mounts) live in your sbatch script.
NeMo-Run (`nemo_run:`) sections are also supported -- see our
[cluster guide](https://docs.nvidia.com/nemo/automodel/latest/launcher/cluster.html) for details.
## LLM Parameter-Efficient Fine-Tuning (PEFT)
We provide a PEFT example using the [HellaSwag dataset](https://rowanzellers.com/hellaswag/).
### LLM PEFT Single Node
```bash
# Memory-efficient SFT with LoRA
automodel examples/llm_finetune/qwen/qwen3_0p6b_hellaswag_peft.yaml
# Override any YAML parameter via the command line:
automodel examples/llm_finetune/qwen/qwen3_0p6b_hellaswag_peft.yaml \
--step_scheduler.local_batch_size 16
```
> [!NOTE]
> Launching a multi-node PEFT example uses the same `sbatch slurm.sub` workflow as the SFT case above.
## VLM Supervised Fine-Tuning (SFT)
We provide a VLM SFT example using Qwen2.5-VL for end-to-end fine-tuning on image-text data.
### VLM SFT Single Node
```bash
# Qwen2.5-VL on 8 GPUs
automodel examples/vlm_finetune/qwen2_5/qwen2_5_vl_3b_rdr.yaml --nproc-per-node 8
```
## VLM Parameter-Efficient Fine-Tuning (PEFT)
We provide a VLM PEFT (LoRA) example for memory-efficient adaptation with Gemma3 VLM.
### VLM PEFT Single Node
```bash
# Gemma-3-VL PEFT on 8 GPUs
automodel examples/vlm_finetune/gemma3/gemma3_vl_4b_medpix_peft.yaml --nproc-per-node 8
```
## Supported Models
NeMo AutoModel provides native support for a wide range of models available on the Hugging Face Hub, enabling efficient fine-tuning for various domains. Below is a small sample of ready-to-use families (train as-is or swap any compatible 🤗 causal LM), you can specify nearly any LLM/VLM model available on 🤗 hub:
| Domain | Model Family | Model ID | Recipes |
|--------|--------------|----------|---------|
| **LLM** | **GPT-OSS** | [`GPT-OSS-20B`](https://huggingface.co/openai/gpt-oss-20b) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/gpt_oss/gpt_oss_20b.yaml) |
| | | [`GPT-OSS-120B`](https://huggingface.co/openai/gpt-oss-120b) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/gpt_oss/gpt_oss_120b.yaml) |
| **LLM** | **DeepSeek** | [`DeepSeek-V3`](https://huggingface.co/deepseek-ai/DeepSeek-V3) | [Pretrain](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_pretrain/deepseekv3_pretrain.yaml) |
| **LLM** | **Kimi K3** | [`moonshotai/Kimi-K3`](https://huggingface.co/moonshotai/Kimi-K3) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/kimi/k3_hellaswag.yaml) |
| **LLM** | **GLM-5.3** | [`zai-org/GLM-5.3`](https://huggingface.co/zai-org/GLM-5.3) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/glm/glm_5.3_tulu3_4k_cudnn_100step.yaml) |
| **LLM** | **Moonlight** | [`Moonlight-16B-TE`](https://huggingface.co/moonshotai/Moonlight-16B-A3B) | [Pretrain](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_pretrain/megatron_pretrain_moonlight_16b_te_slurm.yaml), [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/moonlight/moonlight_16b_te.yaml) |
| **LLM** | **Nemotron-H** | [`nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-BF16`](https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Lightning-30B-A3B-BF16) | [LoRA](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/nemotron/nemotron_nano_v3_5_lightning_hellaswag_peft.yaml) |
| **LLM** | **Ling 2.0** | [`inclusionAI/Ling-mini-2.0`](https://huggingface.co/inclusionAI/Ling-mini-2.0) | [LoRA SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/ling/ling_mini_2_0_squad.yaml), [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/ling/ling_mini_2_0_sft.yaml) |
| | | [`inclusionAI/Ling-flash-2.0`](https://huggingface.co/inclusionAI/Ling-flash-2.0) | [LoRA SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/ling/ling_flash_2_0_lora.yaml), [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/ling/ling_flash_2_0_sft.yaml) |
| | | [`inclusionAI/Ling-1T`](https://huggingface.co/inclusionAI/Ling-1T) | [LoRA SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/ling/ling_1t_lora_pp.yaml), [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/ling/ling_1t_sft.yaml) |
| **LLM** | **ERNIE 4.5** | [`baidu/ERNIE-4.5-0.3B-PT`](https://huggingface.co/baidu/ERNIE-4.5-0.3B-PT) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/ernie4_5/ernie4_5_0p3b_hellaswag.yaml) |
| | | [`baidu/ERNIE-4.5-21B-A3B-PT`](https://huggingface.co/baidu/ERNIE-4.5-21B-A3B-PT) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/ernie4_5/ernie4_5_21b_a3b_hellaswag.yaml) |
| **LLM** | **MiMo V2 Flash** | [`XiaomiMiMo/MiMo-V2-Flash`](https://huggingface.co/XiaomiMiMo/MiMo-V2-Flash) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/mimo_v2_flash/mimo_v2_flash_hellaswag.yaml) |
| **LLM** | **MiMo-V2.5-Pro** | [`XiaomiMiMo/MiMo-V2.5-Pro`](https://huggingface.co/XiaomiMiMo/MiMo-V2.5-Pro) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/mimo_v25/mimo_v25_pro_hellaswag.yaml) |
| **LLM** | **LLaMA** | [`meta-llama/Llama-3.2-1B`](https://huggingface.co/meta-llama/Llama-3.2-1B) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/llama3_2/llama3_2_1b_squad.yaml), [PEFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/llama3_2/llama3_2_1b_hellaswag_peft.yaml) |
| | | [`meta-llama/Llama-3.2-3B-Instruct`](https://huggingface.co/meta-llama/Llama-3.2-3B-Instruct) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/llama3_2/llama_3_2_3b_instruct_squad.yaml), [PEFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/llama3_2/llama_3_2_3b_instruct_squad_peft.yaml) |
| | | [`meta-llama/Llama-3.1-8B`](https://huggingface.co/meta-llama/Llama-3.1-8B) | [FP8](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/llama3_1/llama3_1_8b_hellaswag_fp8.yaml) |
| | | [`meta-llama/Llama-3.3-70B-Instruct`](https://huggingface.co/meta-llama/Llama-3.3-70B-Instruct) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/llama3_3/llama_3_3_70b_instruct_squad.yaml), [PEFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/llama3_3/llama_3_3_70b_instruct_squad_peft.yaml) |
| **LLM** | **Mistral** | [`mistralai/Mistral-7B-v0.1`](https://huggingface.co/mistralai/Mistral-7B-v0.1) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/mistral/mistral_7b_squad.yaml), [PEFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/mistral/mistral_7b_squad_peft.yaml), [FP8](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/mistral/mistral_7b_hellaswag_fp8.yaml) |
| | | [`mistralai/Mistral-Nemo-Base-2407`](https://huggingface.co/mistralai/Mistral-Nemo-Base-2407) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/mistral/mistral_nemo_2407_squad.yaml), [PEFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/mistral/mistral_nemo_2407_squad_peft.yaml), [FP8](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/mistral/mistral_nemo_2407_hellaswag_fp8.yaml) |
| | | [`mistralai/Mixtral-8x7B-Instruct-v0.1`](https://huggingface.co/mistralai/Mixtral-8x7B-Instruct-v0.1) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/mistral/mixtral-8x7b-v0-1_squad.yaml), [PEFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/mistral/mixtral-8x7b-v0-1_squad_peft.yaml) |
| **LLM** | **Qwen** | [`Qwen/Qwen2.5-7B`](https://huggingface.co/Qwen/Qwen2.5-7B) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/qwen/qwen2_5_7b_squad.yaml), [PEFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/qwen/qwen2_5_7b_squad_peft.yaml), [FP8](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/qwen/qwen2_5_7b_hellaswag_fp8.yaml) |
| | | [`Qwen/Qwen3-0.6B`](https://huggingface.co/Qwen/Qwen3-0.6B) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/qwen/qwen3_0p6b_hellaswag.yaml), [PEFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/qwen/qwen3_0p6b_hellaswag_peft.yaml) |
| | | [`Qwen/Qwen3.8-2.4T-A95B`](https://huggingface.co/Qwen/Qwen3.8-2.4T-A95B) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/qwen/qwen3_8_2_4t_a95b_hellaswag_ep32_pp8.yaml) |
| | | [`Qwen/Qwen3.8-Flash-Next`](https://huggingface.co/Qwen/Qwen3.8-Flash-Next) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/qwen/qwen3_8_flash_next_180b_hellaswag_ep64.yaml) |
| | | [`Qwen/QwQ-32B`](https://huggingface.co/Qwen/QwQ-32B) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/qwen/qwq_32b_squad.yaml), [PEFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/qwen/qwq_32b_squad_peft.yaml) |
| **LLM** | **Gemma** | [`google/gemma-3-270m`](https://huggingface.co/google/gemma-3-270m) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/gemma/gemma_3_270m_squad.yaml), [PEFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/gemma/gemma_3_270m_squad_peft.yaml) |
| | | [`google/gemma-2-9b-it`](https://huggingface.co/google/gemma-2-9b-it) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/gemma/gemma_2_9b_it_squad.yaml), [PEFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/gemma/gemma_2_9b_it_squad_peft.yaml), [FP8](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/gemma/gemma_2_9b_it_hellaswag_fp8.yaml) |
| | | [`google/gemma-7b`](https://huggingface.co/google/gemma-7b) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/gemma/gemma_7b_squad.yaml), [PEFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/gemma/gemma_7b_squad_peft.yaml) |
| **LLM** | **Phi** | [`microsoft/phi-2`](https://huggingface.co/microsoft/phi-2) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/phi/phi_2_squad.yaml), [PEFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/phi/phi_2_squad_peft.yaml) |
| | | [`microsoft/Phi-3-mini-4k-instruct`](https://huggingface.co/microsoft/Phi-3-mini-4k-instruct) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/phi/phi_3_mini_it_squad.yaml), [PEFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/phi/phi_3_mini_it_squad_peft.yaml) |
| | | [`microsoft/phi-4`](https://huggingface.co/microsoft/phi-4) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/phi/phi_4_squad.yaml), [PEFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/phi/phi_4_squad_peft.yaml), [FP8](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/phi/phi_4_hellaswag_fp8.yaml) |
| **LLM** | **Seed** | [`ByteDance-Seed/Seed-Coder-8B-Instruct`](https://huggingface.co/ByteDance-Seed/Seed-Coder-8B-Instruct) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/seed/seed_coder_8b_instruct_squad.yaml), [PEFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/seed/seed_coder_8b_instruct_squad_peft.yaml), [FP8](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/seed/seed_coder_8b_instruct_hellaswag_fp8.yaml) |
| | | [`ByteDance-Seed/Seed-OSS-36B-Instruct`](https://huggingface.co/ByteDance-Seed/Seed-OSS-36B-Instruct) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/seed/seed_oss_36B_hellaswag.yaml), [PEFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/seed/seed_oss_36B_hellaswag_peft.yaml) |
| **LLM** | **Baichuan** | [`baichuan-inc/Baichuan2-7B-Chat`](https://huggingface.co/baichuan-inc/Baichuan2-7B-Chat) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/baichuan/baichuan_2_7b_squad.yaml), [PEFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/baichuan/baichuan_2_7b_squad_peft.yaml), [FP8](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/baichuan/baichuan_2_7b_mock_fp8.yaml) |
| **VLM** | **NVIDIA Nemotron 3.5 Super VL** | [`nvidia/NVIDIA-Nemotron-3.5-Super-VL-120B-A12B-BF16`](https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Super-VL-120B-A12B-BF16) | [CORD-v2 SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/nemotron_3_5_super_vl/nemotron_3_5_super_vl_cord_v2.yaml), [CORD-v2 PEFT (LoRA)](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/nemotron_3_5_super_vl/nemotron_3_5_super_vl_cord_v2_peft.yaml), [256K packed SFT (GB200)](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/nemotron_3_5_super_vl/nemotron_3_5_super_vl_tulu3_packed_256k_cp8_ep16_gb200.yaml) |
| **VLM** | **Gemma** | [`google/gemma-3-4b-it`](https://huggingface.co/google/gemma-3-4b-it) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/gemma3/gemma3_vl_4b_cord_v2.yaml), [PEFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/gemma3/gemma3_vl_4b_cord_v2_peft.yaml) |
| | | [`google/gemma-3n-e4b-it`](https://huggingface.co/google/gemma-3n-e4b-it) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/gemma3n/gemma3n_vl_4b_medpix.yaml), [PEFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/gemma3n/gemma3n_vl_4b_medpix_peft.yaml) |
| **VLM** | **Ox Alpha / GLM-5.3-Flash** | [`zai-org/GLM-5.3-Flash`](https://huggingface.co/zai-org/GLM-5.3-Flash) | [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/glm5_next/glm5_3_flash_medpix_packed2k_ep72_cp2_100steps.yaml) |
| **VLM** | **Muse Spark Open** | [`meta-models/Muse-Spark-open-816B-A42B`](https://huggingface.co/meta-models/Muse-Spark-open-816B-A42B) | [Model card](docs/model-coverage/vlm/muse/muse_spark_open.mdx), [SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/9c9c4cfdb27461da359263bb342a086307ecaba7/examples/vlm_finetune/muse_spark/muse_spark_open_medpix_nonpacked4k_ep64_pp4_100steps.yaml), [PEFT](https://github.com/NVIDIA-NeMo/Automodel/blob/9c9c4cfdb27461da359263bb342a086307ecaba7/examples/vlm_finetune/muse_spark/muse_spark_open_medpix_nonpacked4k_lora_ep32.yaml), [128K packed SFT](https://github.com/NVIDIA-NeMo/Automodel/blob/9c9c4cfdb27461da359263bb342a086307ecaba7/examples/llm_finetune/muse_spark/muse_spark_open_tulu3_packed128k_ep32_pp2_cp32_magi.yaml) |
| **VLM** | **North Micro Vision** | [`CohereLabs/North-Micro-Vision-Instruct`](https://huggingface.co/CohereLabs/North-Micro-Vision-Instruct) | [PEFT](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/cohere_micro_vision/north_micro_vision_rdr.yaml) |
| **Embedding** | **Nemotron 3 Embed** | [`nvidia/Nemotron-3-Embed-1B-BF16`](https://huggingface.co/nvidia/Nemotron-3-Embed-1B-BF16) | [End-to-end text bi-encoder recipe](https://github.com/NVIDIA-NeMo/Nemotron/tree/main/docs/nemotron/embed) |
> [!NOTE]
> Check out more [LLM](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune) and [VLM](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune) examples. Any causal LM on Hugging Face Hub can be used with the base recipe template, just overwrite `--model.pretrained_model_name_or_path ` in the CLI or in the YAML config.
## Performance
NeMo AutoModel achieves great training performance on NVIDIA GPUs. Below are highlights from our benchmark results:
| Model | #GPUs | Seq Length | Model TFLOPs/sec/GPU | Tokens/sec/GPU | Kernel Optimizations |
|-------|------:|-----------:|---------------------:|---------------:|----------------------|
| DeepSeek V3 671B | 256 | 4096 | 250 | 1,002 | TE + DeepEP |
| GPT-OSS 20B | 8 | 4096 | 279 | 13,058 | TE + DeepEP + FlexAttn |
| Qwen3 MoE 30B | 8 | 4096 | 212 | 11,842 | TE + DeepEP |
For complete benchmark results including configuration details, see the [Performance Summary](docs/performance-summary.mdx).
## 🔌 Interoperability
- **[NeMo RL](https://github.com/NVIDIA-NeMo/RL)**: Use AutoModel checkpoints directly as starting points for DPO/RM/GRPO pipelines.
- **[Hugging Face](https://github.com/huggingface/transformers)**: Train any LLM/VLM from 🤗 without format conversion.
- **[Megatron Bridge](https://github.com/NVIDIA-NeMo/Megatron-Bridge)**: Optional conversions to/from Megatron formats for specific workflows.
## 🗂️ Project Structure
```
NeMo-Automodel/
├── cli/ # `automodel` / `am` CLI entry-point
│ └── app.py
├── docker/ # Container build files
├── docs/ # Documentation and guides
├── examples/
│ ├── convergence/ # Convergence test configs
│ ├── diffusion/ # Diffusion pretrain/finetune configs
│ ├── dllm_sft/ # Discrete diffusion LM SFT configs
│ ├── dllm_generate/ # Discrete diffusion LM generation
│ ├── llm_benchmark/ # LLM benchmarking configs
│ ├── llm_finetune/ # LLM finetune YAML configs
│ ├── llm_kd/ # LLM knowledge-distillation configs
│ ├── llm_pretrain/ # LLM pretrain configs
│ ├── llm_seq_cls/ # LLM sequence classification configs
│ ├── retrieval/ # Bi-encoder / cross-encoder configs
│ ├── vlm_benchmark/ # VLM benchmarking configs
│ ├── vlm_finetune/ # VLM finetune configs
│ └── vlm_generate/ # VLM generation configs
├── nemo_automodel/
│ ├── _diffusers/ # HF Diffusers integration (NeMoAutoDiffusionPipeline)
│ ├── _transformers/ # HF Transformers integration
│ ├── components/ # Core library
│ │ ├── _peft/ # PEFT implementations (LoRA, QLoRA)
│ │ ├── attention/ # Attention implementations
│ │ ├── checkpoint/ # Distributed checkpointing
│ │ ├── config/
│ │ ├── datasets/ # LLM, VLM, diffusion, retrieval datasets
│ │ ├── distributed/ # FSDP2, Megatron FSDP, pipelining, CP, etc.
│ │ ├── launcher/ # Launcher backends (SLURM, NeMo-Run, SkyPilot)
│ │ ├── loggers/ # Loggers
│ │ ├── loss/ # Optimized loss functions
│ │ ├── models/ # User-defined model examples
│ │ ├── moe/ # Optimized kernels for MoE models
│ │ ├── optim/ # Optimizer/LR scheduler components (incl. Dion)
│ │ ├── quantization/ # FP8, QAT, QLoRA
│ │ ├── training/ # Train utils
│ │ └── utils/ # Misc utils
│ ├── recipes/
│ │ ├── llm/ # Main LLM train loop
│ │ ├── vlm/ # Main VLM train loop
│ │ ├── diffusion/ # Diffusion training loop
│ │ ├── dllm/ # Discrete diffusion LM training loop
│ │ └── retrieval/ # Retrieval / biencoder training loop
│ └── shared/
├── tools/ # Developer tooling
└── tests/ # Comprehensive test suite
```
## Citation
If you use NeMo AutoModel in your research, please cite it using the following BibTeX entry:
```
@misc{nemo-automodel,
title = {NeMo AutoModel: DTensor-native SPMD library for scalable and efficient training},
howpublished = {\url{https://github.com/NVIDIA-NeMo/Automodel}},
year = {2025--2026},
note = {GitHub repository},
}
```
## 🤝 Contributing
We welcome contributions! Please see our [Contributing Guide](https://github.com/NVIDIA-NeMo/Automodel/blob/main/CONTRIBUTING.md) for details.
## 📄 License
NVIDIA NeMo AutoModel is licensed under the [Apache License 2.0](https://github.com/NVIDIA-NeMo/Automodel/blob/main/LICENSE).
 [**Speculative decoding in NeMo AutoModel**](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/guides/speculative/eagle.mdx) Train target-aligned drafters end to end: EAGLE-1/2/3, P-EAGLE, DFlash, and DeepSeek's newly released [DSpark](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/speculative/dspark/qwen3_0.6b_dspark.yaml). Huge thanks to [@Khazic](https://github.com/khazic) for the speculative decoding stack and [@kashif](https://github.com/kashif) for DSpark support.
- [06/21/2026][**GLM-5.2**](https://huggingface.co/zai-org/GLM-5.2) We now support finetuning `zai-org/GLM-5.2` with IndexShare DSA, optional TileLang sparse kernels, and long-context CP recipes. Check out our [32K long-context recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/glm/glm_5.2_tulu3_32k_tilelang_cp8.yaml) and [model coverage page](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/model-coverage/llm/thudm/glm5-moe-dsa.mdx).
- [06/15/2026][**DiffusionGemma**](https://huggingface.co/google/diffusiongemma-26B-A4B-it). We now support fine-tuning the `google/diffusiongemma-26B-A4B-it` model. Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/dllm_sft/diffusion_gemma_sft.yaml) and [guide](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/guides/dllm/diffusiongemma.mdx).
- [06/12/2026][**MiniMax M3**](https://huggingface.co/MiniMaxAI/MiniMax-M3) We now support finetuning MiniMax's MiniMax-M3. Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/minimax_m3/minimax_m3_vl_sft_ep32pp4.yaml) and [guide](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/guides/vlm/minimax-m3.mdx).
- [06/04/2026][**Nemotron-3 Ultra**](https://huggingface.co/nvidia/NVIDIA-Nemotron-3-Ultra-550B-A55B-BF16) We now support finetuning NVIDIA's Nemotron 3 Ultra 550B A55B. Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/nemotron/nemotron_ultra_v3_hellaswag_peft.yaml) and [guide](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/guides/llm/nemotron-3-ultra.md).
- [06/03/2026][**Gemma 4 12B**](https://huggingface.co/google/gemma-4-12B) We now support finetuning the dense `google/gemma-4-12B` model. Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/gemma/gemma_4_12b_hellaswag.yaml).
- [05/27/2026][**Step-3.7-Flash**](https://huggingface.co/stepfun-ai/Step-3.7-Flash) We added model coverage for Stepfun AI's 198B-A13B MoE vision-language model, targeting image/video agentic developer workflows with a 256k context language backbone and 1.8B ViT vision tower. See the [model coverage page](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/model-coverage/vlm/stepfun-ai/step-3-7.md).
- [05/19/2026][**Ling 2.0**](https://huggingface.co/collections/inclusionAI/ling-20) We now support finetuning the inclusionAI Ling 2.0 MoE family (`inclusionAI/Ling-mini-2.0`, `inclusionAI/Ling-flash-2.0`, and `inclusionAI/Ling-1T`), thanks to [@Hayden727](https://github.com/Hayden727). Check out our [recipes](https://github.com/NVIDIA-NeMo/Automodel/tree/main/examples/llm_finetune/ling).
- [05/17/2026][**ERNIE 4.5**](https://huggingface.co/baidu) and [**MiMo-V2-Flash**](https://huggingface.co/XiaomiMiMo/MiMo-V2-Flash) We now support finetuning `baidu/ERNIE-4.5-0.3B-PT`, `baidu/ERNIE-4.5-21B-A3B-PT`, and `XiaomiMiMo/MiMo-V2-Flash`. Check out our ERNIE [dense recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/ernie4_5/ernie4_5_0p3b_hellaswag.yaml), ERNIE [MoE recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/ernie4_5/ernie4_5_21b_a3b_hellaswag.yaml), and MiMo [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/mimo_v2_flash/mimo_v2_flash_hellaswag.yaml).
- [04/29/2026][**Mistral Medium 3.5**](https://huggingface.co/mistralai/Mistral-Medium-3.5-128B) We now support finetuning Mistral AI's 128B FP8-native VLM Mistral Medium 3.5. Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/mistral3p5/mistral3p5_128b_medpix.yaml) and [guide](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/guides/vlm/mistral-medium-3-5.md).
- [04/28/2026][**Nemotron-3-Nano-Omni**](https://huggingface.co/nvidia/Nemotron-3-Nano-Omni-30B-A3B-Reasoning-BF16) We now support finetuning `nvidia/Nemotron-3-Nano-Omni-30B-A3B-Reasoning-BF16`, NVIDIA's 30B-A3B omnimodal MoE (text · image · audio) with NemotronH hybrid Mamba+Attention backbone. Check out our [SFT recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/nemotron_omni/nemotron_omni_cord_v2.yaml), [LoRA recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/nemotron_omni/nemotron_omni_cord_v2_peft.yaml), and [guide](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/guides/vlm/nemotron-omni.md).
- [04/28/2026][**Hy3-preview**](https://huggingface.co/tencent/Hy3-preview) We now support finetuning `tencent/Hy3-preview`, thanks to [@Khazic](https://github.com/khazic). Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/hy_v3/hy3_preview_deepep.yaml).
- [04/25/2026][**DeepSeek V4 Flash**](https://huggingface.co/deepseek-ai/DeepSeek-V4-Flash) We now support finetuning `deepseek-ai/DeepSeek-V4-Flash`, thanks to [@Khazic](https://github.com/khazic). Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/deepseek_v4/deepseek_v4_flash_hellaswag.yaml) and [guide](https://github.com/NVIDIA-NeMo/Automodel/blob/main/docs/guides/llm/dsv4-flash.md).
- [04/22/2026][**Qwen3.6-27B**](https://huggingface.co/Qwen/Qwen3.6-27B) We now support finetuning `Qwen/Qwen3.6-27B`. Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/qwen3_5/qwen3_6_27b.yaml).
- [04/20/2026][**Qwen-Image**](https://huggingface.co/Qwen/Qwen-Image) We now support finetuning `Qwen/Qwen-Image`, thanks to [@harshareddy832](https://github.com/harshareddy832). Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/diffusion/finetune/qwen_image_t2i_flow.yaml).
- [04/16/2026][**Qwen3.6 MoE**](https://huggingface.co/Qwen/Qwen3.6-35B-A3B) We now support finetuning `Qwen/Qwen3.6-35B-A3B`. Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/qwen3_5_moe/qwen3_6_35b.yaml).
- [04/16/2026][**LLaVA-OneVision-1.5**](https://huggingface.co/lmms-lab/LLaVA-OneVision-1.5-4B-Instruct) We now support finetuning `lmms-lab/LLaVA-OneVision-1.5-4B-Instruct`, thanks to [@vgauraha62](https://github.com/vgauraha62). Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/llava_onevision/llava_ov_1_5_4b_finetune.yaml).
- [04/12/2026][**MiniMax-M2.7**](https://huggingface.co/MiniMaxAI/MiniMax-M2.7) We now support finetuning `MiniMaxAI/MiniMax-M2.7`. Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/minimax_m2/minimax_m2.7_hellaswag_pp.yaml).
- [04/07/2026][**GLM-5.1**](https://huggingface.co/zai-org/GLM-5.1) We now support finetuning `zai-org/GLM-5.1`. GLM-5.1 is Zhipu AI's latest open-source MoE model featuring MLA + DeepSeek Sparse Attention. Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/glm/glm_5.1_hellaswag_pp.yaml) and [discussion](https://github.com/NVIDIA-NeMo/Automodel/discussions/1719).
- [04/02/2026][**Gemma 4**](https://huggingface.co/collections/google/gemma-4) We support fine-tuning for Gemma4 (2B, 4B, 31B, 26BA4B)! Check out our [recipes](https://github.com/NVIDIA-NeMo/Automodel/tree/main/examples/vlm_finetune/gemma4).
- [03/30/2026]**NeMo AutoModel** ships with **agent-friendly skills** in [skills/](https://github.com/NVIDIA-NeMo/Automodel/tree/main/skills) to help you with common development tasks (e.g., running a recipe, model onboarding, development) across the repo. We welcome PRs that improve existing skills or add new ones.
- [03/16/2026][**Mistral Small 4**](https://huggingface.co/mistralai/Mistral-Small-4-119B-2603) We support fine-tuning for Mistral4 119B! Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/mistral4/mistral4_medpix.yaml).
- [03/11/2026][**Nemotron Super v3**](https://huggingface.co/nvidia/NVIDIA-Nemotron-3-Super-120B-A12B-BF16) We support fine-tuning for `nvidia/NVIDIA-Nemotron-3-Super-120B-A12B-BF16`. Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/nemotron/nemotron_super_v3_hellaswag.yaml).
- [03/11/2026][**GLM-5**](https://huggingface.co/zai-org/GLM-5) We now support finetuning `zai-org/GLM-5`. Check out our [recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/llm_finetune/glm/glm_5_hellaswag_pp.yaml).
- [03/02/2026][**Qwen3.5 small models**](https://huggingface.co/collections/Qwen/qwen35) We support finetuning for Qwen3.5 small models 0.8B, 2B, 4B ([recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/qwen3_5/qwen3_5_4b.yaml)) and 9B ([recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/qwen3_5/qwen3_5_9b.yaml))
- [02/16/2026][**Qwen3.5 MoE**](https://huggingface.co/collections/Qwen/qwen35) We support finetuning for `Qwen/Qwen3.5-397B-A17B` ([recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/qwen3_5_moe/qwen3_5_moe_medpix.yaml)) and `Qwen/Qwen3.5-35B-A3B` ([recipe](https://github.com/NVIDIA-NeMo/Automodel/blob/main/examples/vlm_finetune/qwen3_5_moe/qwen3_5_35b.yaml))