# MiniCPM-OCR 1.0
[中文版](./minicpm_ocr_1dot0_zh.md)
[← Back to the homepage](../README.md) · [MiniCPM-OCR Jev](./minicpm_ocr_jev_en.md)
**MiniCPM-OCR 1.0** (1.3B) is the first OCR-specific model in the [MiniCPM-V/o](https://github.com/openbmb/MiniCPM-V) family. It focuses on text-centric document understanding, covering text, tables, formulas, charts, seals, and structured information extraction. This page covers its highlights, technical specifications, usage, model downloads, complete evaluation results, efficiency results, and examples.
## Model Highlights
- 🏆 **SOTA document parsing**: MiniCPM-OCR 1.0 achieves a **SOTA score of 93.68 on Real5-OmniDocBench**, a benchmark for real-world document parsing, and demonstrates leading parsing capabilities on OmniDocBench v1.6, Wild-OmniDocBench, and olmOCR-Bench. It supports Chinese and English documents and PDFs, handling both standard documents and challenging capture conditions, including scans, curved pages, photographs, skewed pages, and recaptured documents.
- ⚡ **Efficient inference.** With DSpark decoding acceleration ([**DSpark-BF16**](https://huggingface.co/openbmb/MiniCPM-OCR-1.0-DSpark), [**DSpark-GGUF**](https://huggingface.co/openbmb/MiniCPM-OCR-1.0-DSpark-gguf)), MiniCPM-OCR 1.0 improves **end-to-end processing efficiency by 55%**. Its throughput is approximately **1.49×** that of PaddleOCR-VL-1.6 and **3.62×** that of MinerU2.5 Pro, reducing the time needed for large-scale document parsing.
- 🔍 **General recognition and information extraction**: MiniCPM-OCR 1.0 achieves a **SOTA score of 54.7 on OCRBench v2**, demonstrating strong general OCR capabilities. It **also supports key information extraction (KIE)**, extracting relevant document content for downstream information management and automated processing.
- 🛠️ **Easy deployment and development**: MiniCPM-OCR 1.0 supports **vLLM, SGLang, llama.cpp, and Ollama from day one**, with multiple chip platforms and quantized versions available at release. It **supports further fine-tuning** and provides a **[pip SDK](https://pypi.org/project/minicpm-ocr/)** and a **[full-featured API](https://platform.modelbest.ai/console/docs/api/document-parse)** for application integration and customization. You can also **[get started quickly with SKILL.md](./SKILL_en.md)**. Try the online Demo ([CN](https://platform.modelbest.cn/console/playground/document-parse) / [Global](https://platform.modelbest.ai/console/playground/document-parse)) to explore parsing results.
## Usage
### Skill
Ask a coding agent to follow the [skill](./SKILL_en.md) to set up the environment, download models, and parse your first document. Send the following instruction to the agent:
```text
Read and execute https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/SKILL_en.md
```
If you have already cloned this repository, you can use `./docs/SKILL_en.md` directly.
### Free API
Use the Free API to access MiniCPM-OCR 1.0 recognition. See the [API docs](https://platform.modelbest.ai/console/docs/api/document-parse).
### Local Deployment
Run the model on your own hardware to parse PDFs and images into Markdown or JSON. See the [SDK and deployment tutorial](./minicpm_ocr_tutorial_en.md). The [Inference](#inference) section lists deployment guides for each backend.
## Model Base and Architecture
MiniCPM-OCR 1.0 is **specialized for OCR through training based on MiniCPM-V 4.6**. The standard model combines a **SigLIP vision encoder and a Qwen3.5 language model** and runs with the accompanying Transformers 5 model integration.
| Item | Description |
| :--- | :--- |
| Parameters | 1.3B |
| Primary languages | Chinese and English |
| Recognition tasks | Text, tables, formulas, charts, seals, and key information extraction |
| Document parsing components | MiniCPM-OCR 1.0 recognition model + PP-DocLayoutV3 layout model + `minicpmvocr` SDK |
## Document Parsing Workflow
The SDK parses complete documents, while the recognition model processes their image regions:
1. **Read the document**: The SDK accepts PDF, PNG, or JPG files and converts PDF pages to images.
2. **Analyze the layout**: PP-DocLayoutV3 detects document regions and analyzes reading order; the SDK crops the regions.
3. **Recognize the content**: The SDK sends document regions to the MiniCPM-OCR 1.0 inference service and recognizes them concurrently.
4. **Assemble the output**: The SDK combines results into Markdown in reading order, converts OTSL table representations to HTML, and preserves formulas as LaTeX.
The SDK and inference service use separate Python environments and may run on different machines. The SDK handles layout detection, cropping, and result assembly; the inference backend handles model recognition. See the [SDK tutorial](./minicpm_ocr_tutorial_en.md) for installation and configuration.
### Single-Region Recognition
If layout regions have already been extracted, call the recognition service directly. Use a cropped image and the prompt corresponding to its region type:
| Region | Prompt | Result handling |
| :--- | :--- | :--- |
| Text | `Text Recognition:` | Returns recognized text |
| Table | `Table Recognition:` | The raw format depends on the model version; the SDK can handle table postprocessing |
| Formula | `Formula Recognition:` | Check that the LaTeX content and structure are complete |
| Seal | `Seal Recognition:` | Returns the recognized seal text |
| Chart | `Chart to Table:` | Converts chart content into a table |
See the [API example](./vllm_deploy_en.md#22-image-recognition) for a complete request and response checks. If `finish_reason` is `length`, check for truncated output and adjust the output budget.
## Key Information Extraction (KIE)
MiniCPM-OCR 1.0 supports extracting specified fields from images, such as the store name and amount on a receipt. Send the image and a field extraction prompt directly to the recognition service, requesting a JSON object keyed by the field names. KIE can process the input image directly without generating full-document Markdown first.
Follow the [image recognition API example](./vllm_deploy_en.md#22-image-recognition) and replace `Text Recognition:` in the request with:
```text
Extract the "store_name", "amount". Format the output as a JSON object with keys: "store_name", "amount". If an item is not in the image, use "###".
```
Replace both field lists with the fields needed for your application, keeping their names consistent; field names can be in Chinese or English. The prompt requests `"###"` for fields absent from the image. The response is model-generated text; parse the JSON and check its fields and values before using it downstream.
## Model Weights
| Weights | Hugging Face | ModelScope |
| :--- | :--- | :--- |
| Main model BF16 | [Download](https://huggingface.co/openbmb/MiniCPM-OCR-1.0) | [Download](https://modelscope.cn/models/OpenBMB/MiniCPM-OCR-1.0) |
| Main model GGUF | [Download](https://huggingface.co/openbmb/MiniCPM-OCR-1.0-gguf) | [Download](https://modelscope.cn/models/OpenBMB/MiniCPM-OCR-1.0-gguf) |
| Main model AWQ | [Download](https://huggingface.co/openbmb/MiniCPM-OCR-1.0-AWQ) | [Download](https://modelscope.cn/models/OpenBMB/MiniCPM-OCR-1.0-AWQ) |
| Main model GPTQ | [Download](https://huggingface.co/openbmb/MiniCPM-OCR-1.0-GPTQ) | [Download](https://modelscope.cn/models/OpenBMB/MiniCPM-OCR-1.0-GPTQ) |
| DSpark sampling head BF16 | [Download](https://huggingface.co/openbmb/MiniCPM-OCR-1.0-DSpark) | [Download](https://modelscope.cn/models/OpenBMB/MiniCPM-OCR-1.0-DSpark) |
| DSpark sampling head GGUF | [Download](https://huggingface.co/openbmb/MiniCPM-OCR-1.0-DSpark-gguf) | [Download](https://modelscope.cn/models/OpenBMB/MiniCPM-OCR-1.0-DSpark-gguf) |
**DSpark runs the main model together with its matching draft model (sampling head)**. For example, BF16 deployment pairs `openbmb/MiniCPM-OCR-1.0` with `openbmb/MiniCPM-OCR-1.0-DSpark`; ordinary decoding does not require a draft model. See [DSpark acceleration](./minicpm_ocr_tutorial_en.md#3-start-the-service) for weight selection and startup arguments. FlagOS-adapted BF16 versions for multiple chips are listed in the [download table](./flagos_deploy_en.md#model-downloads).
## Inference
For your first PDF or image, start with the [SDK tutorial](./minicpm_ocr_tutorial_en.md). If a recognition service is already running, configure the SDK to connect to its address.
| Inference option | Guide |
| :--- | :--- |
| vLLM | [API service and single-region recognition](./vllm_deploy_en.md) |
| SGLang | [Deployment guide](./sglang_deploy.md) |
| llama.cpp | [GGUF deployment guide](./llamacpp_deploy.md) |
| Ollama | [Deployment guide](./ollama_deploy.md) |
| FlagOS | [Multi-chip deployment guide](./flagos_deploy_en.md) |
The SDK's `pipeline.max_workers` controls recognition-region requests, while `pipeline.page_workers` controls page concurrency. Configure both to match the backend's capacity: the current DSpark example uses `--max-num-seqs 32` as its per-instance concurrency limit. See the [SDK tutorial](./minicpm_ocr_tutorial_en.md#4-parse-documents) for multiple instances and concurrency configuration.
## Fine-Tuning
The [LLaMA-Factory](./llamafactory_minicpm_ocr_french_en.md) and [ms-swift](./swift_minicpm_ocr_french_en.md) tutorials cover data preparation, training, and evaluation using French handwritten text-line recognition. The example uses full-parameter SFT, trains the vision encoder and language model while freezing the multimodal projector, and applies 4× visual token compression. These settings apply to the fine-tuning experiment in those tutorials.
## Evaluation
### SOTA Performance, Higher Throughput
Among the open-source OCR models shown below, MiniCPM-OCR 1.0 achieves 1.2 pages/s and the highest overall performance on OmniDocBench v1.6, Real5-OmniDocBench, Wild-OmniDocBench, and olmOCR-Bench.
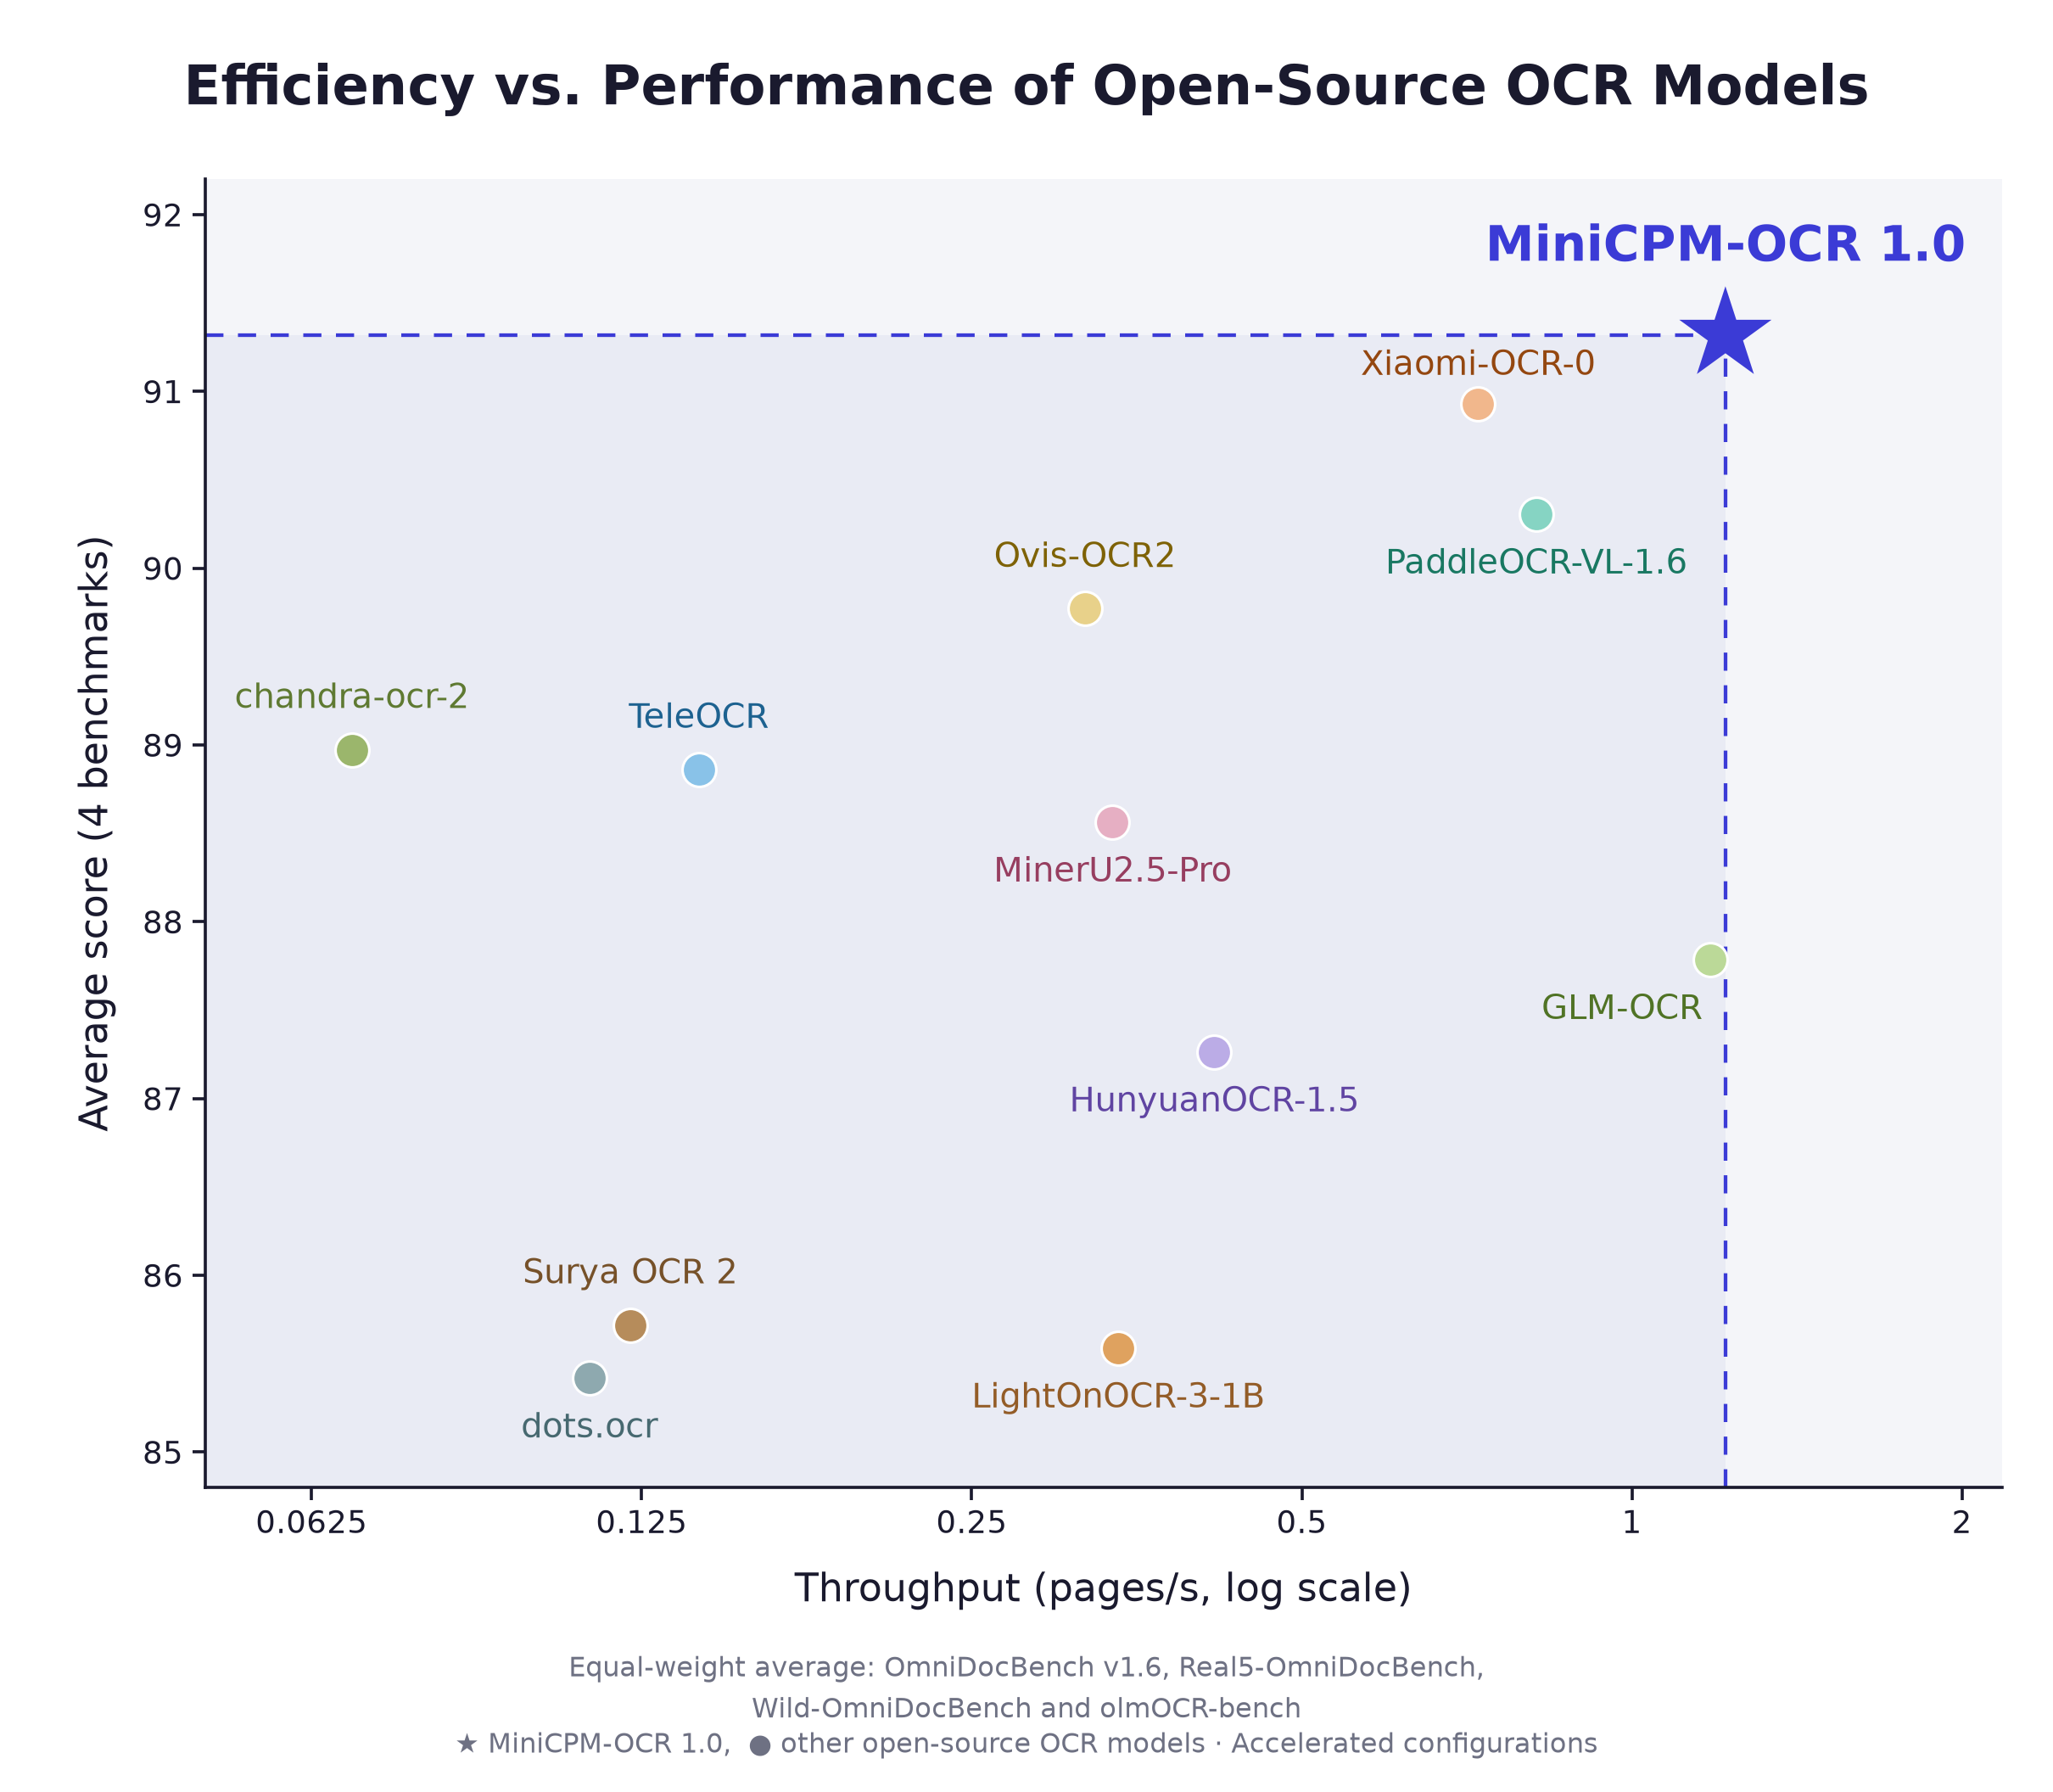
See the [reproduction guide](./benchmark_reproduction_en.md) for test settings and reproduction details, and [Throughput](#throughput) for each model's throughput values.
### Benchmark Comparisons
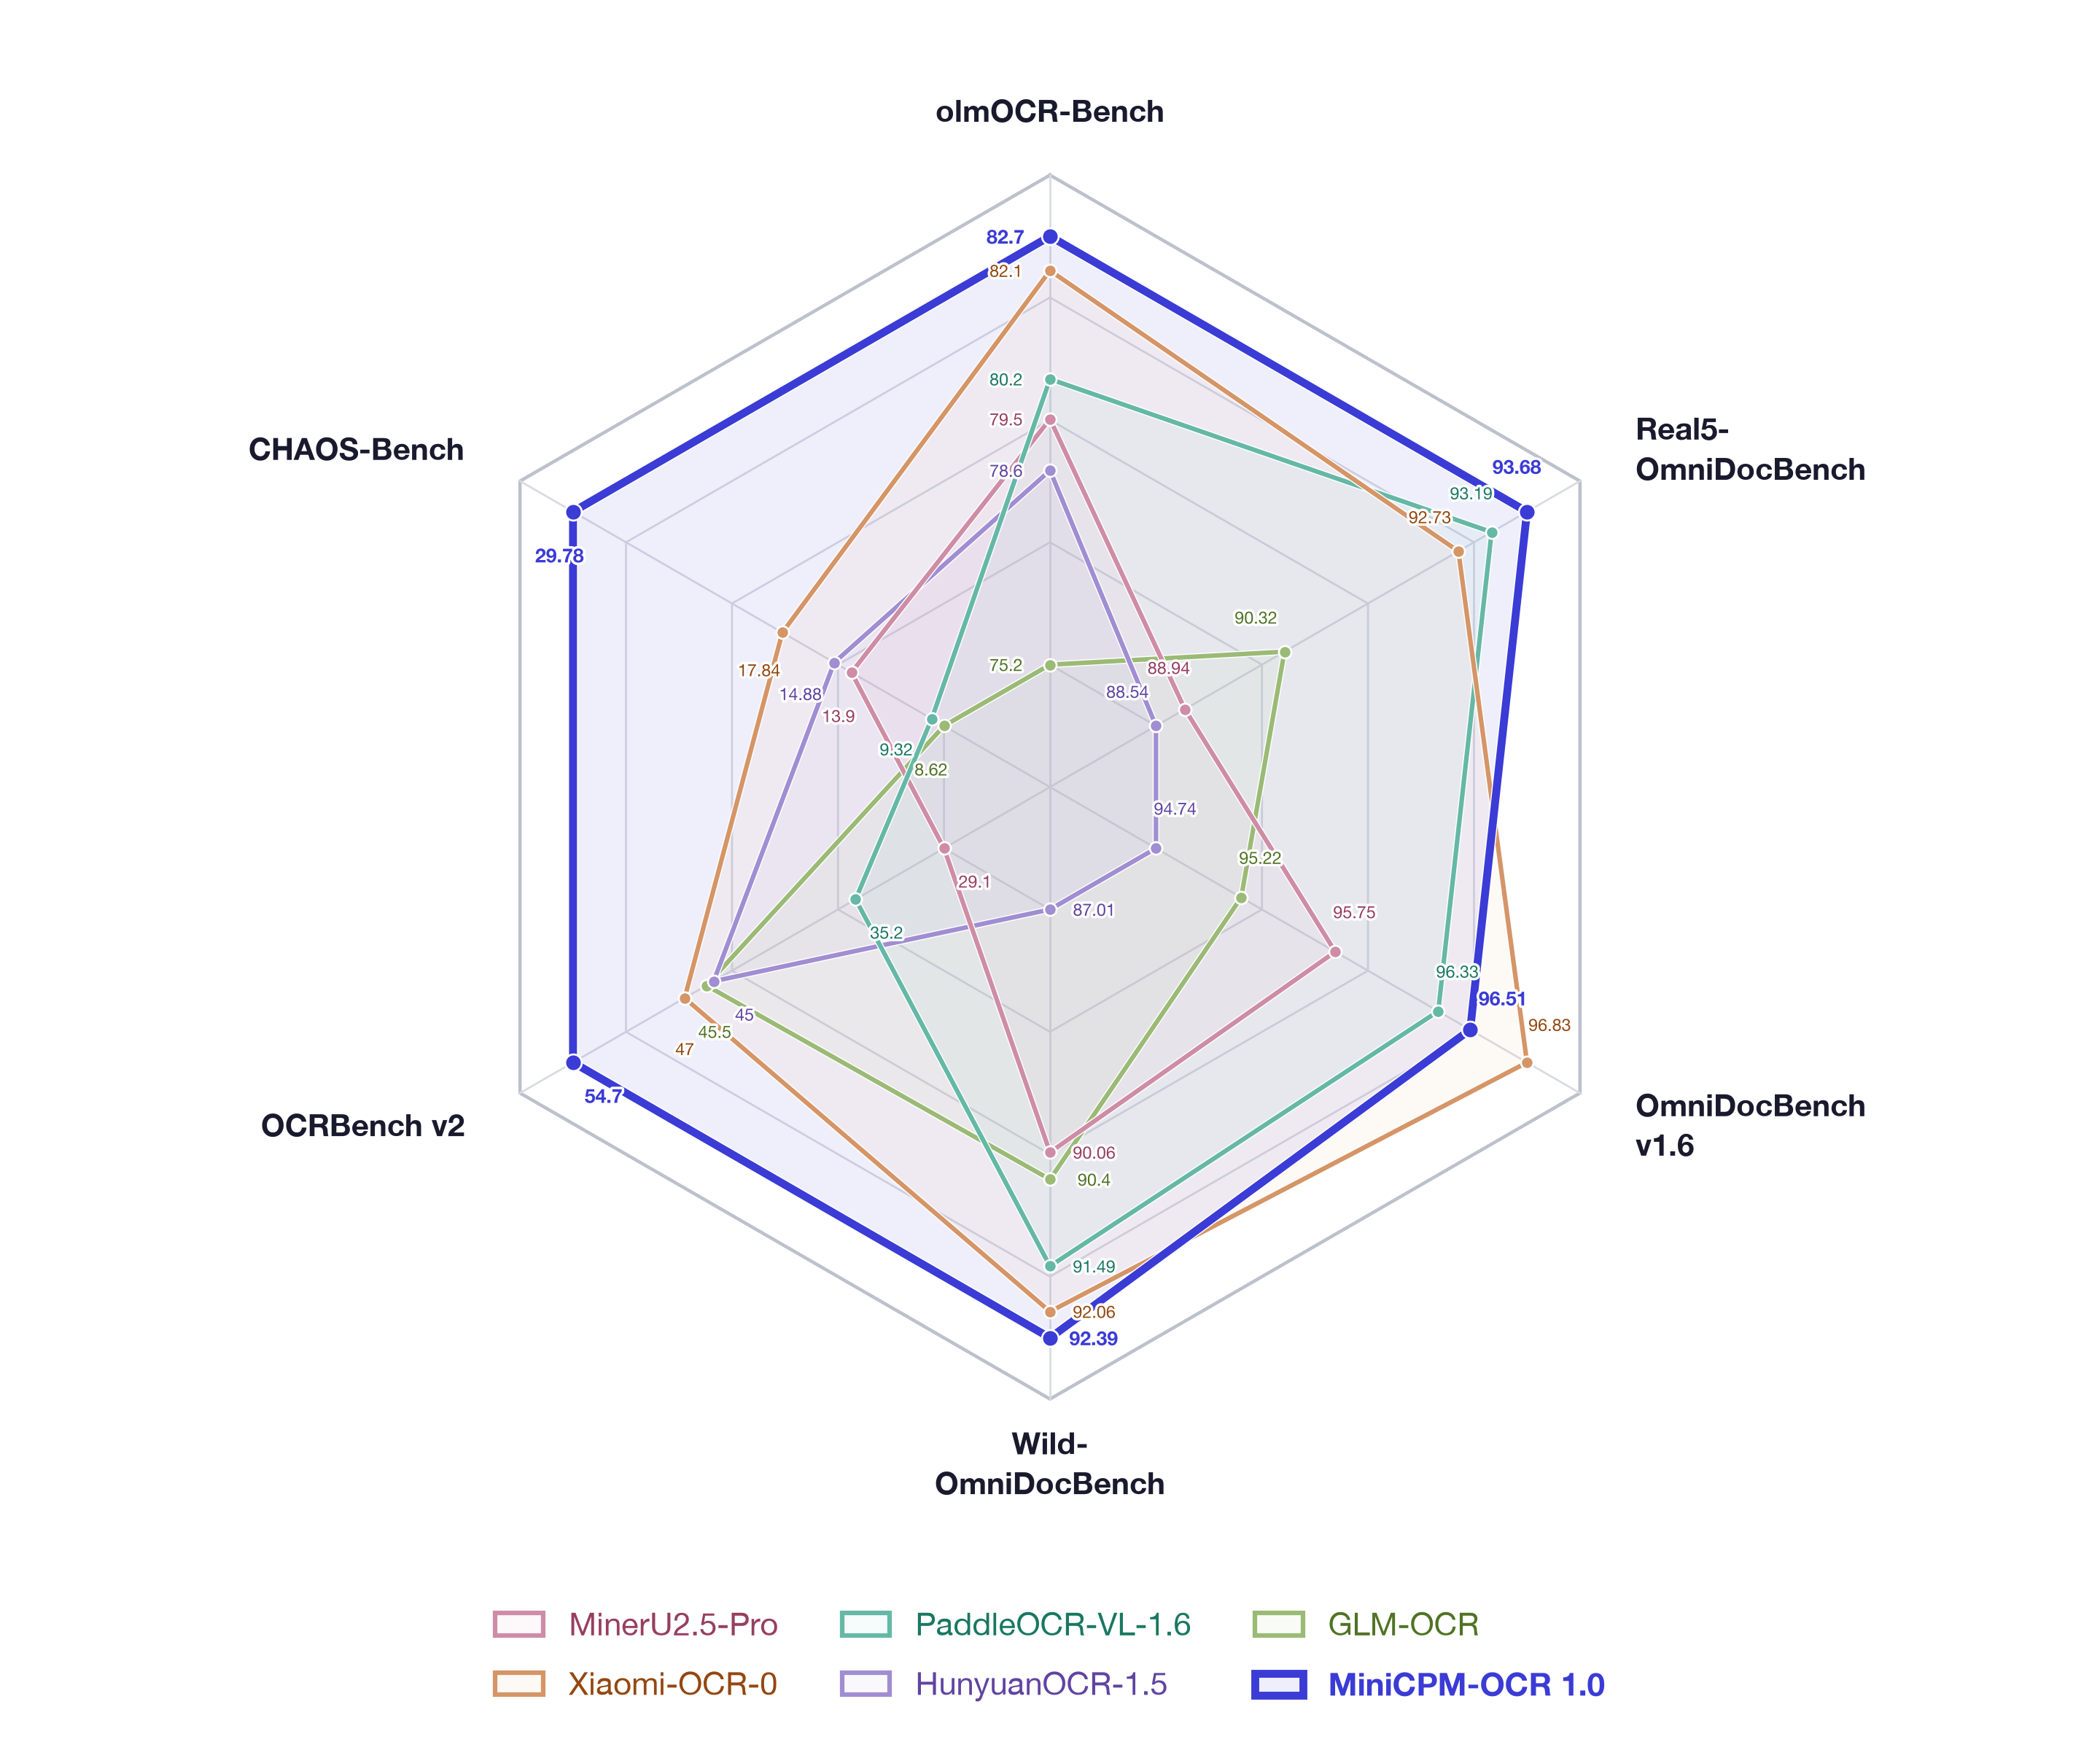
The figure below compares results on six benchmarks. Each panel retains its benchmark's original scores; higher is better. Scores from different benchmarks should not be compared directly.
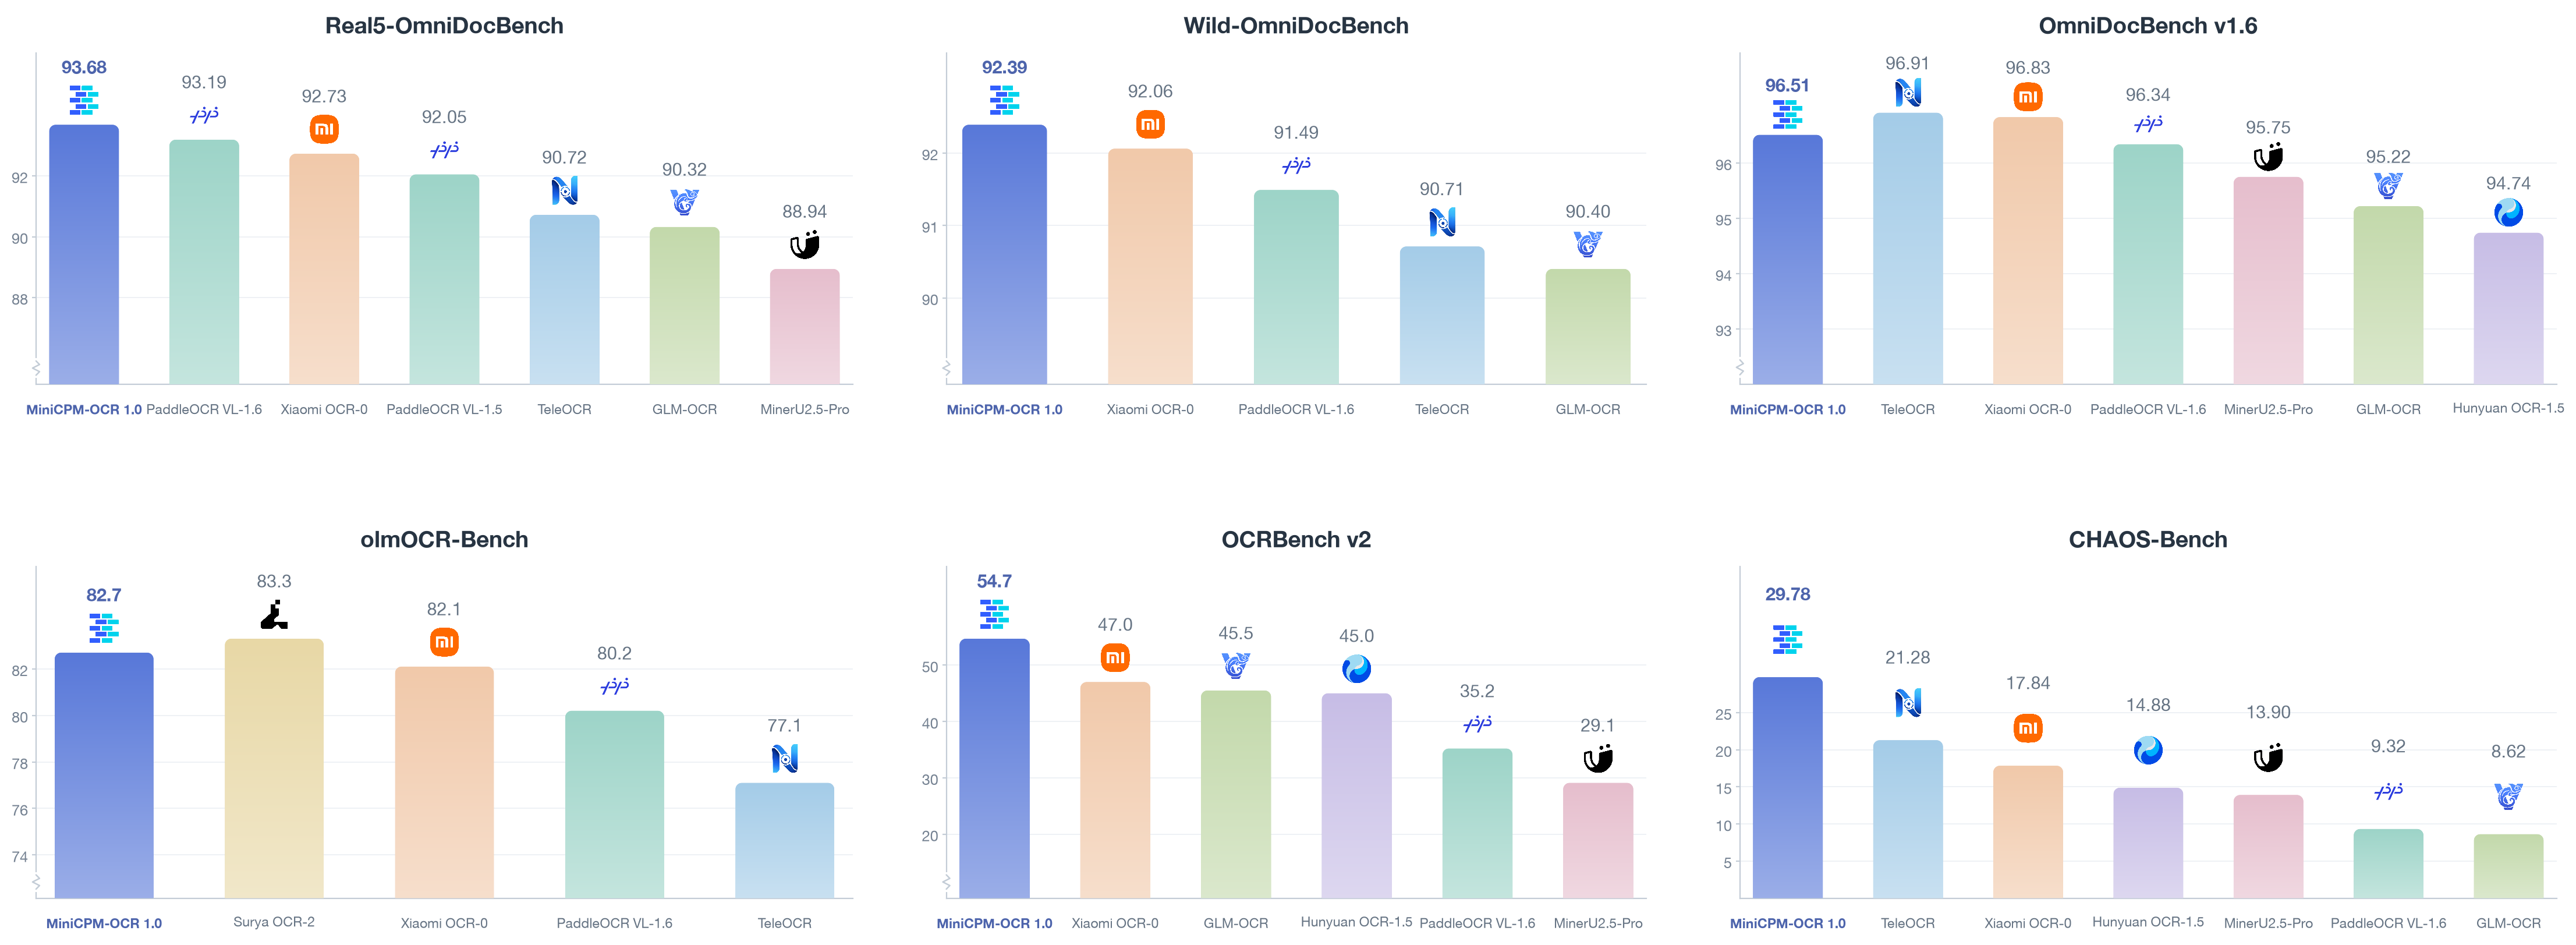
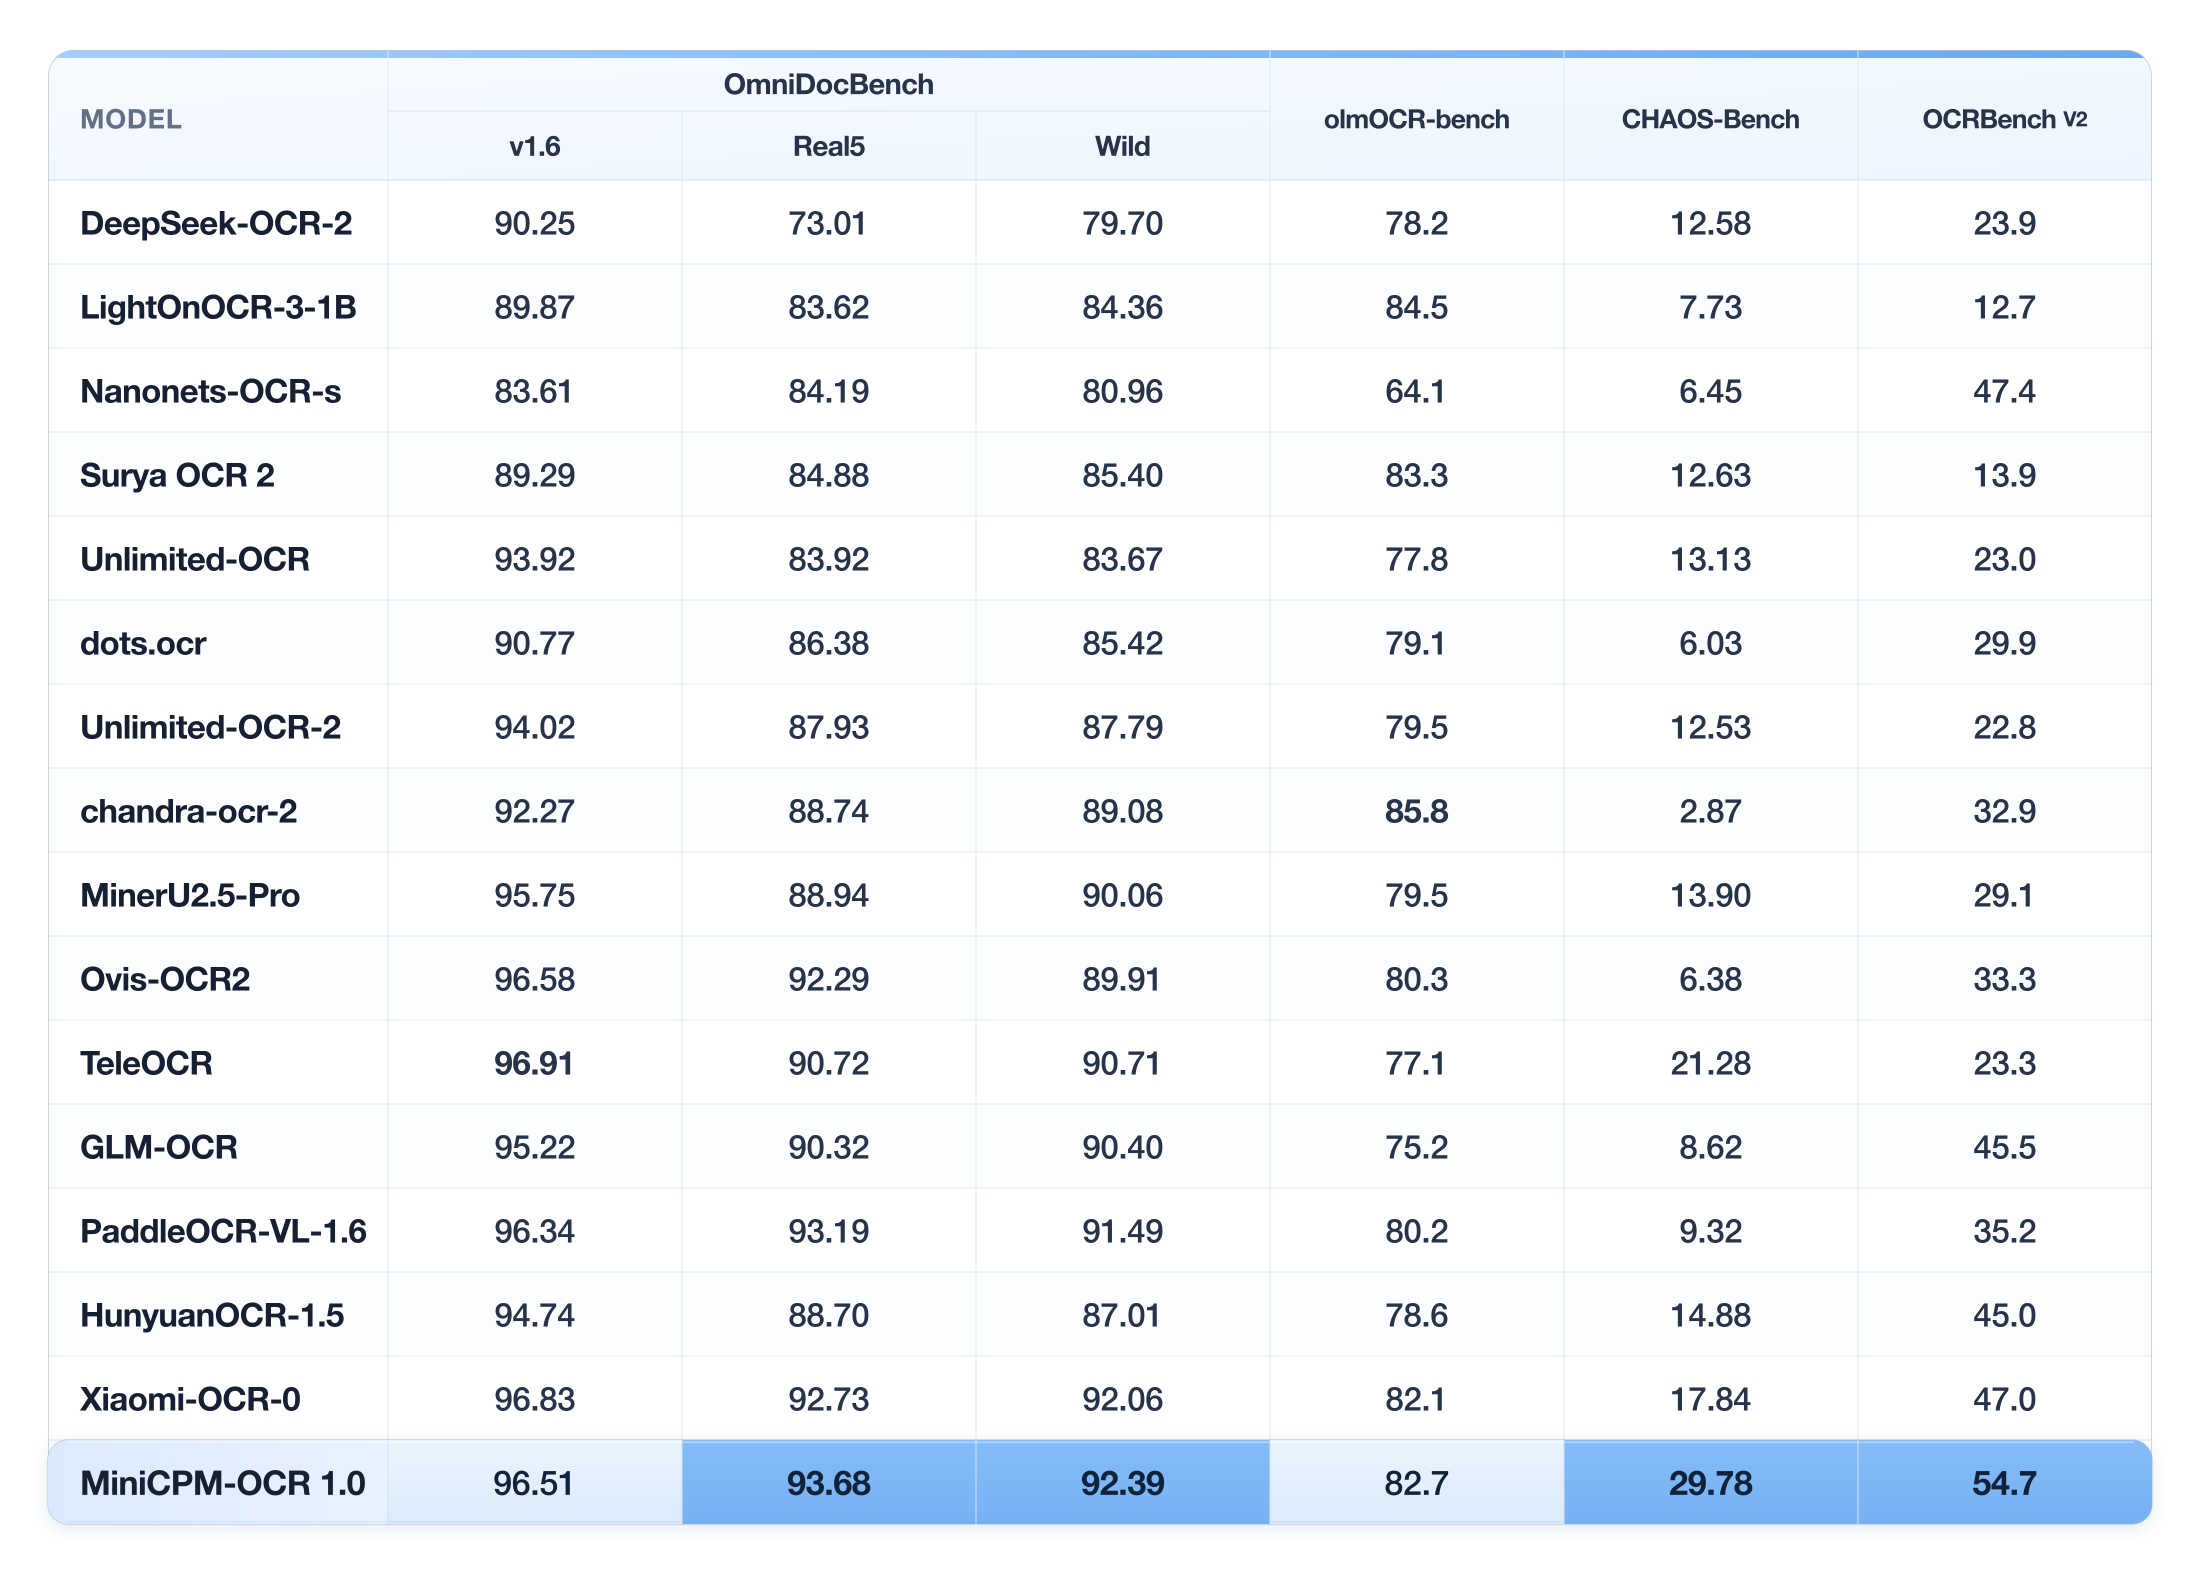
The figure includes selected models to show differences across benchmarks. Complete evaluation results are provided below.
View complete MiniCPM-OCR 1.0 evaluation results
## Throughput
### System Comparison at Concurrency 1
On an NVIDIA GeForce RTX 5090, using all 1,651 images in OmniDocBench v1.6, image-level concurrency of 1, and each system's accelerated configuration, MiniCPM-OCR 1.0 achieves **1.2 pages/s**. Relative throughput is normalized to MiniCPM-OCR 1.0 at **1.00×**; a higher value indicates faster processing.
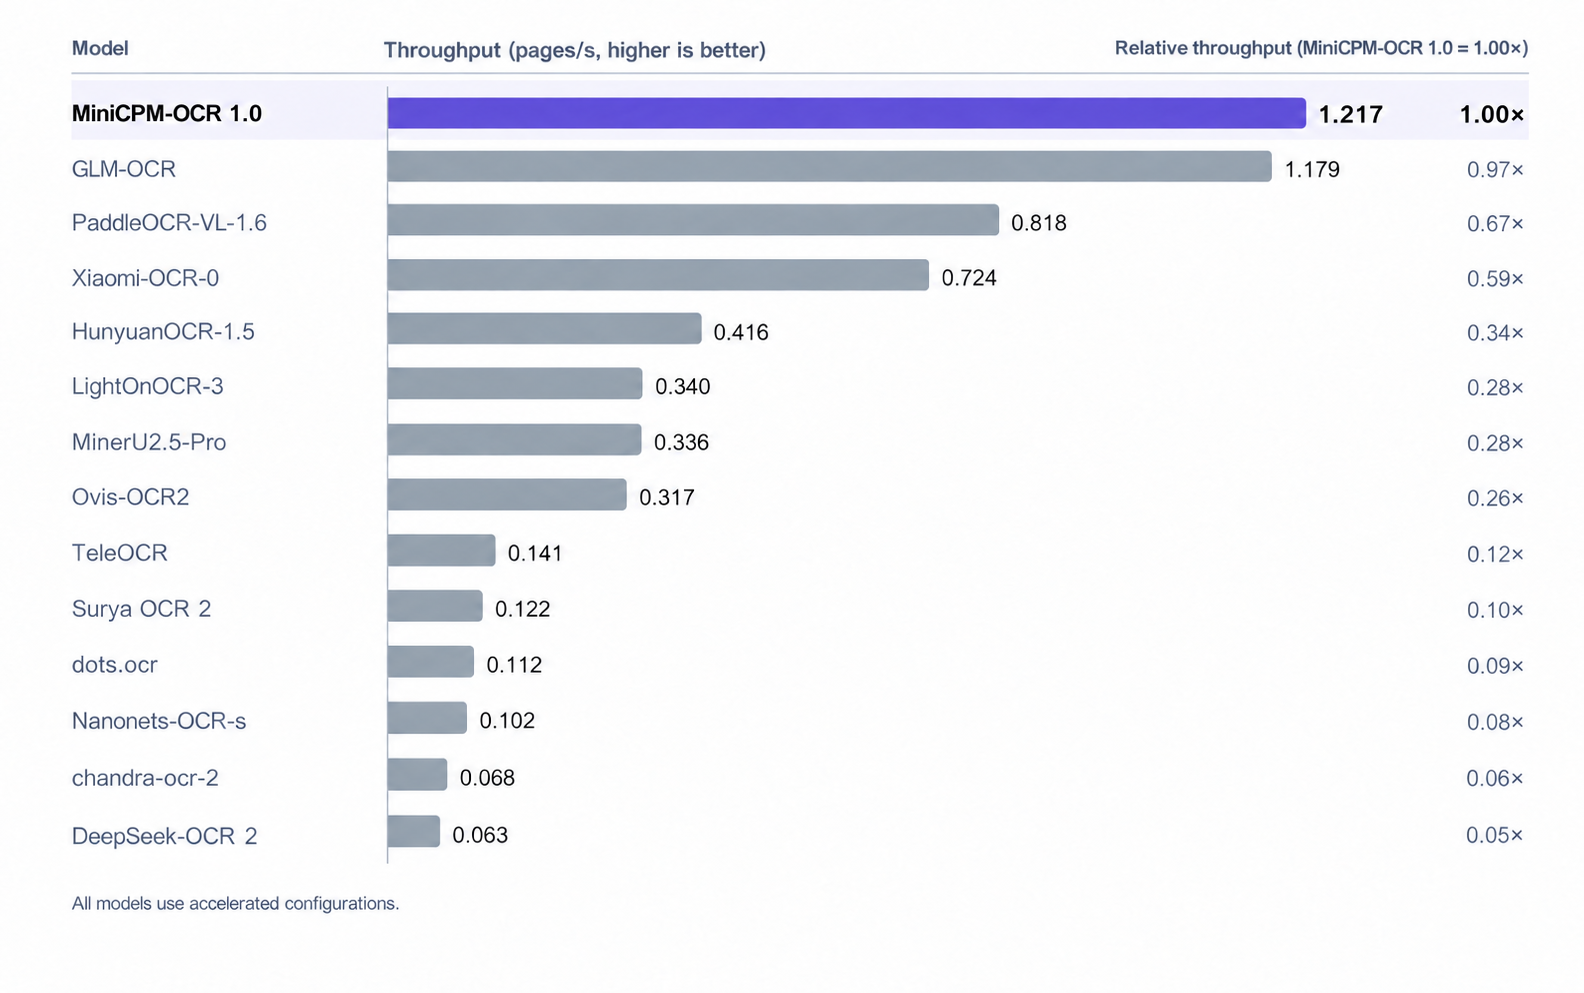
Detailed throughput and latency results are listed below. Higher Pages / s is better (↑); P95 and P99 are the 95th and 99th percentiles of processing time per sample, where lower values are better (↓).
| Model | Pages / s ↑ | P95 Time per Sample ↓ | P99 Time per Sample ↓ |
| --- | ---: | ---: | ---: |
| **MiniCPM-OCR 1.0** | **1.217** | **2.1** | **3.8** |
| GLM-OCR | 1.179 | 2.0 | 4.7 |
| PaddleOCR-VL-1.6 | 0.818 | 2.8 | 6.0 |
| Xiaomi-OCR-0 | 0.724 | 4.0 | 7.9 |
| HunyuanOCR-1.5 | 0.416 | 7.2 | 9.2 |
| LightOnOCR-3 | 0.340 | 9.1 | 9.4 |
| MinerU2.5-Pro | 0.336 | 10.0 | 15.4 |
| OvisOCR2 | 0.317 | 10.4 | 19.6 |
| Unlimited-OCR2 | 0.246 | 11.8 | 19.5 |
| TeleOCR | 0.141 | 13.2 | 18.6 |
| Surya OCR 2 | 0.122 | 39.6 | 51.1 |
| dots.ocr | 0.112 | 27.4 | 63.0 |
| Nanonets-OCR-s | 0.102 | 21.7 | 144.4 |
| chandra-ocr-2 | 0.068 | 38.4 | 161.0 |
| DeepSeek-OCR-2 | 0.063 | 22.5 | 66.7 |
During testing, one image is processed at a time, while multiple recognition regions within that image can be processed concurrently.
### Throughput at Different Concurrency Levels
The table below shows MiniCPM-OCR 1.0 throughput at different image-level concurrency settings on an NVIDIA GeForce RTX 5090, using all 1,651 images in OmniDocBench v1.6. Speedup is relative to the **1.217 pages/s** baseline at image-level concurrency 1 in this table. In this test, **image-level concurrency 8 achieves the highest throughput at 2.133 pages/s, a 1.75× speedup over concurrency 1**.
| Image-Level Concurrency | Throughput (pages/s) | Speedup |
| ---: | ---: | ---: |
| 1 | 1.217 | 1.00× |
| 2 | 1.613 | 1.33× |
| 4 | 1.888 | 1.55× |
| 6 | 2.031 | 1.67× |
| **8** | **2.133** | **1.75×** |
## Examples
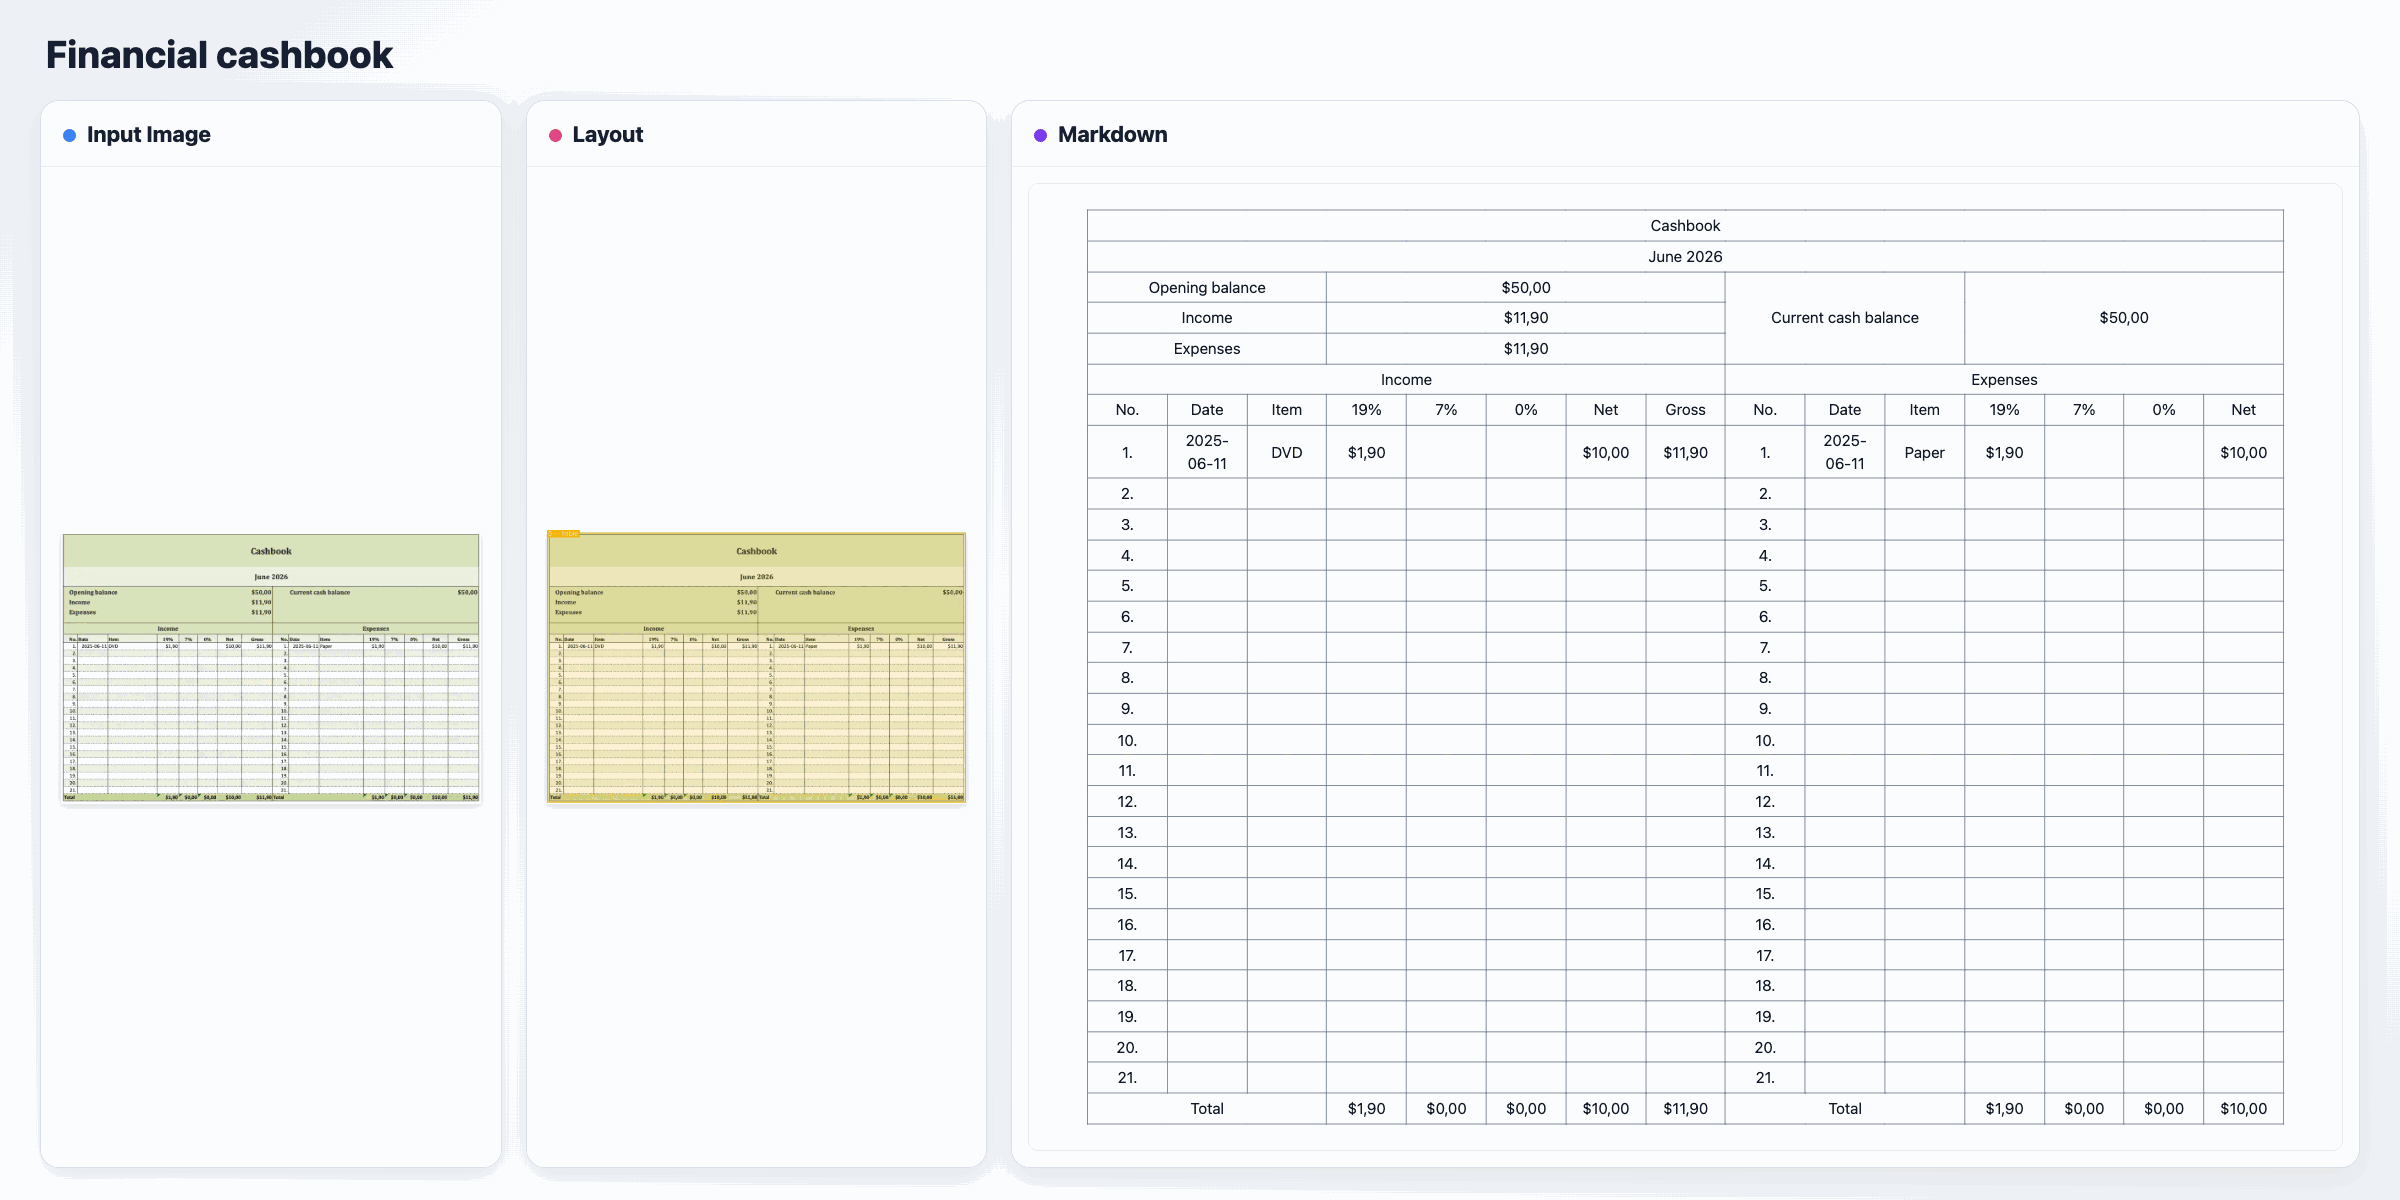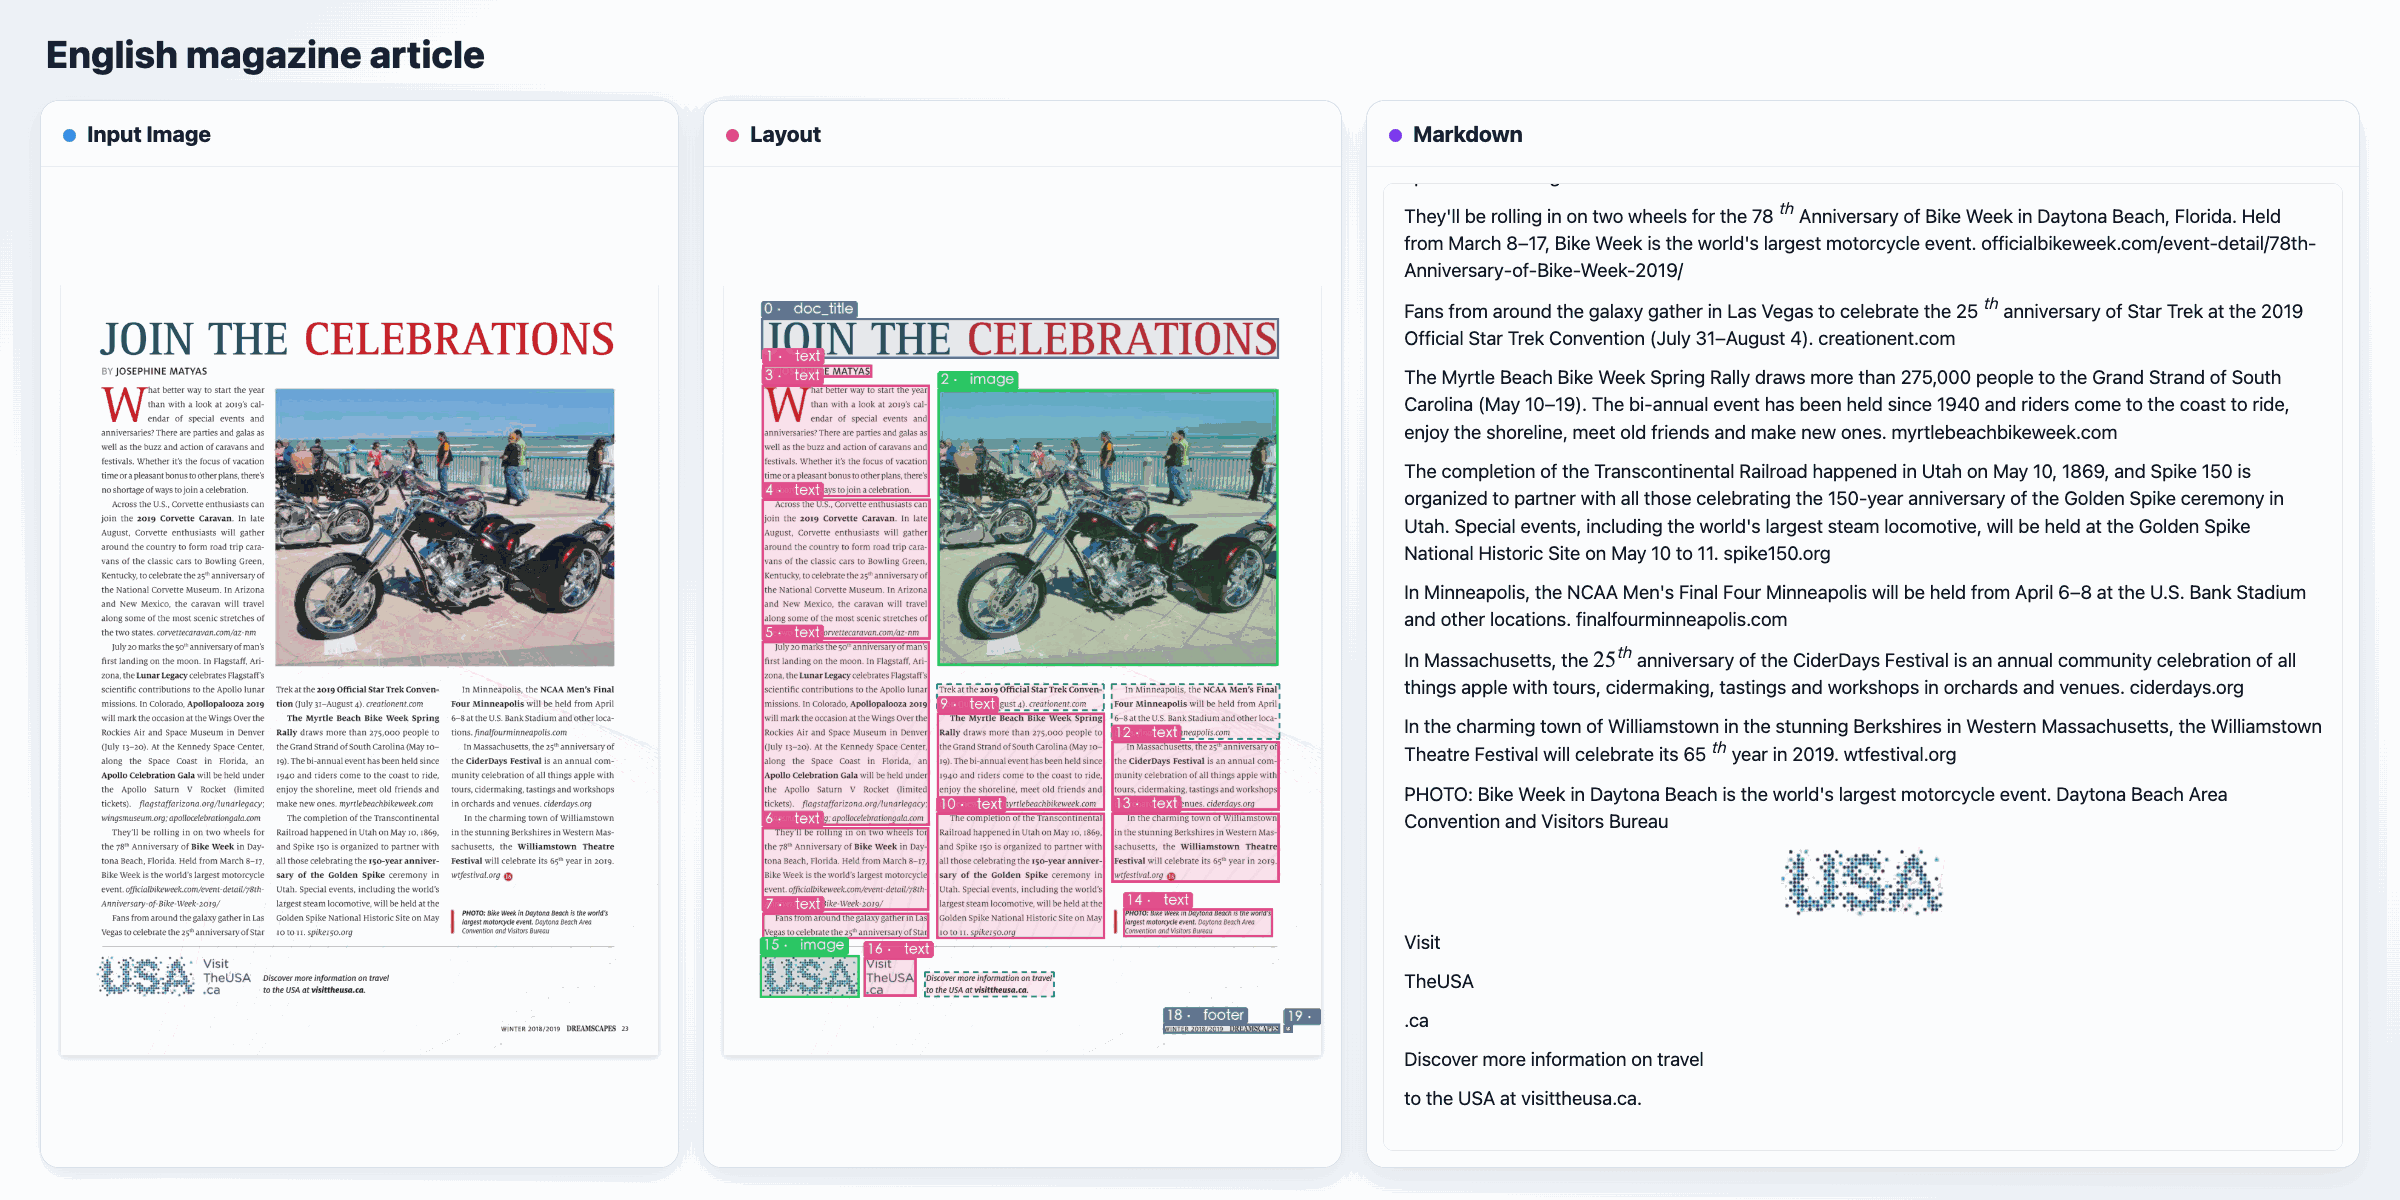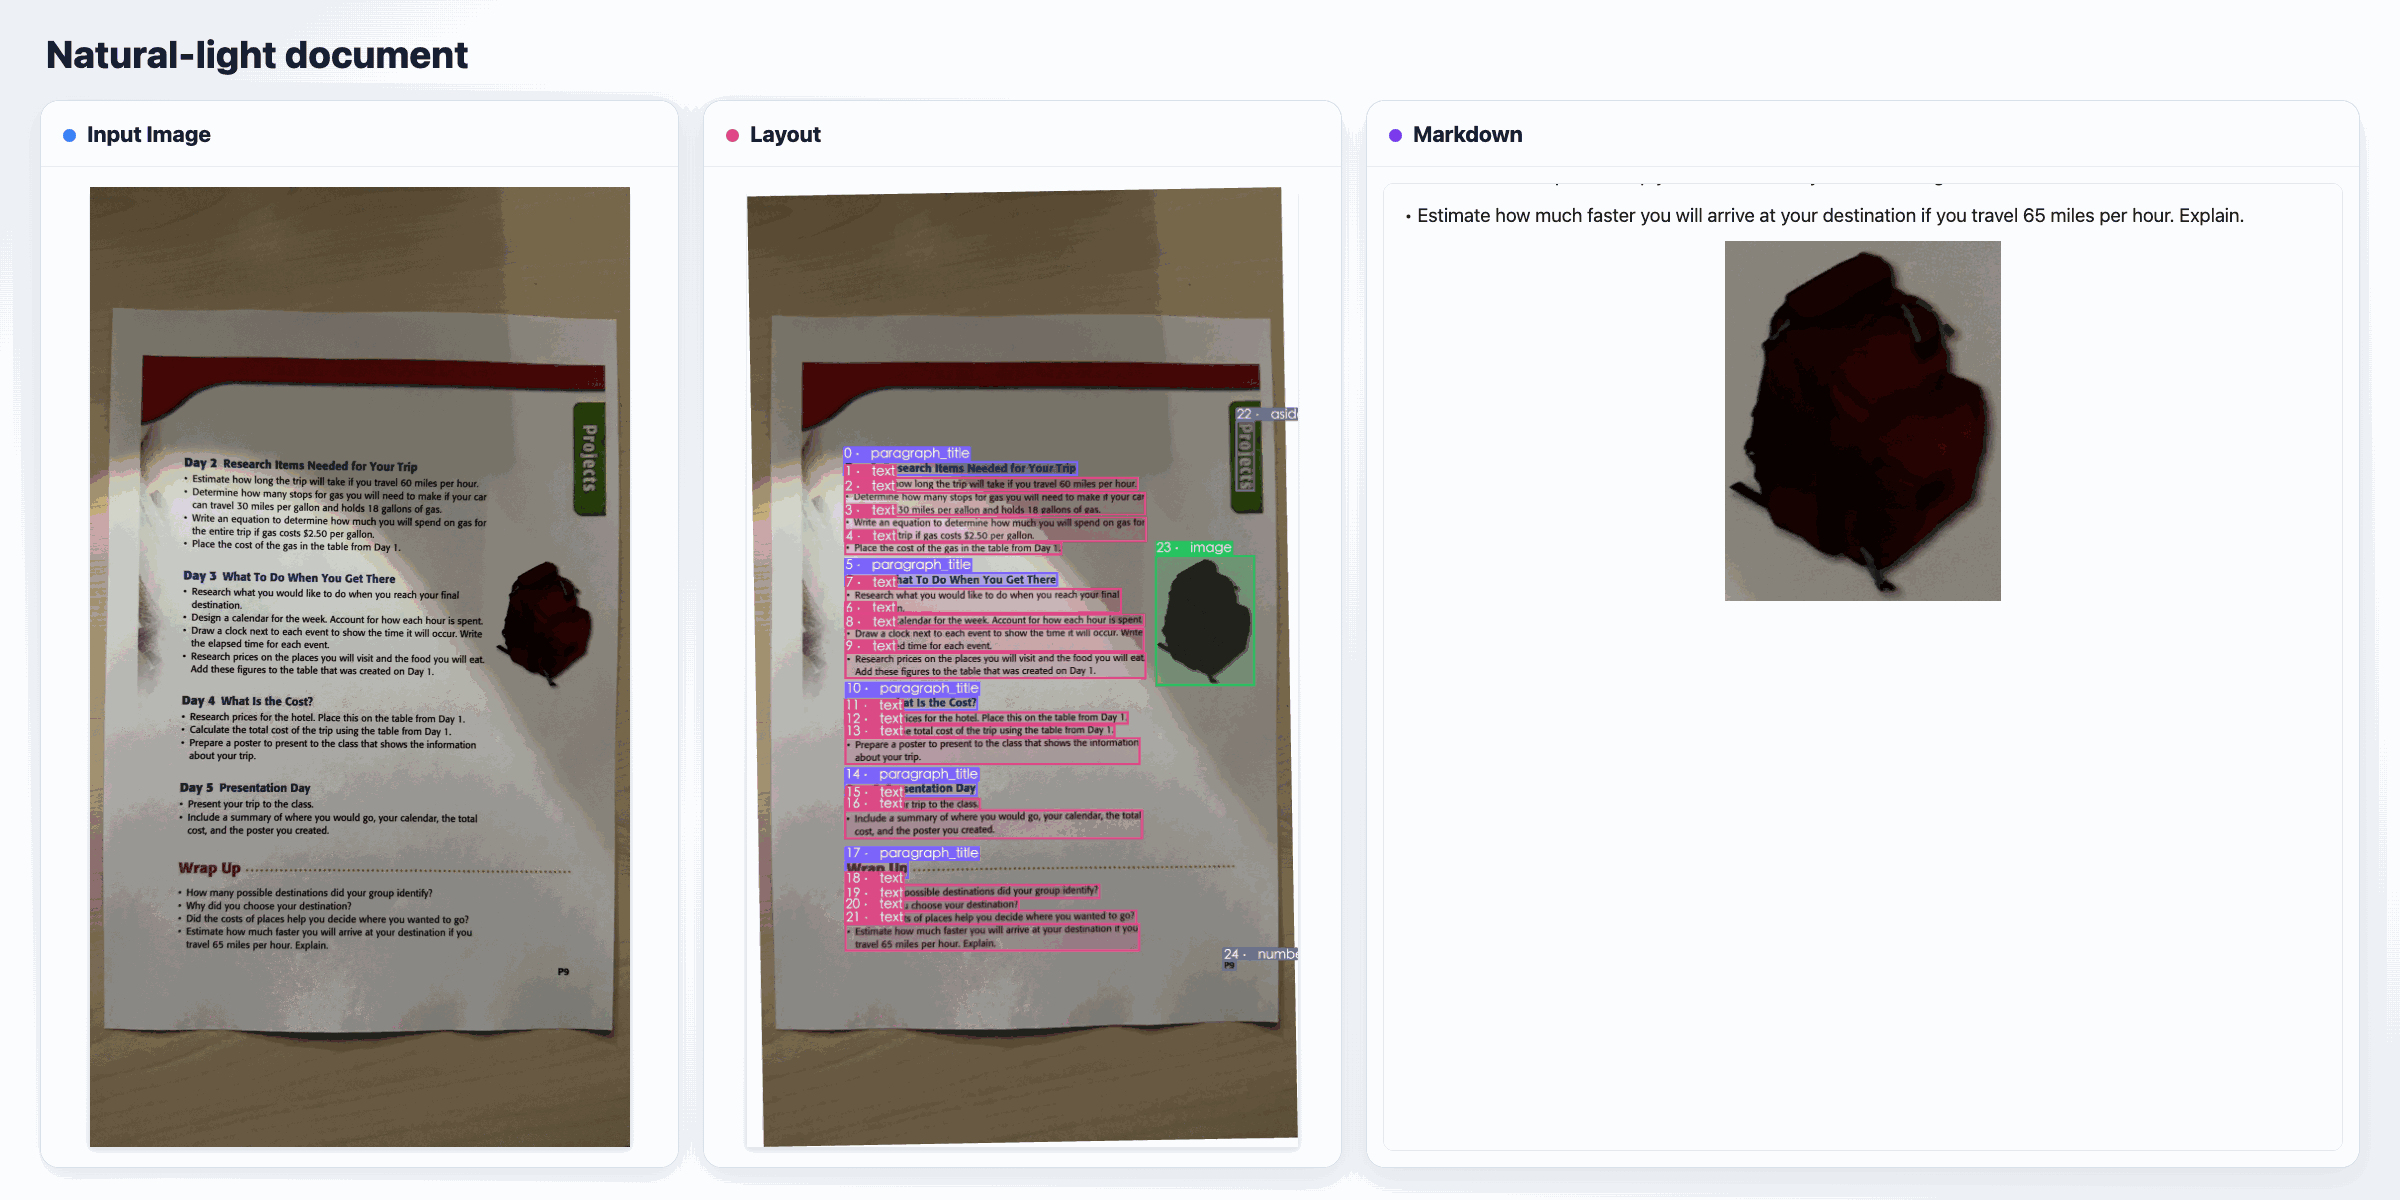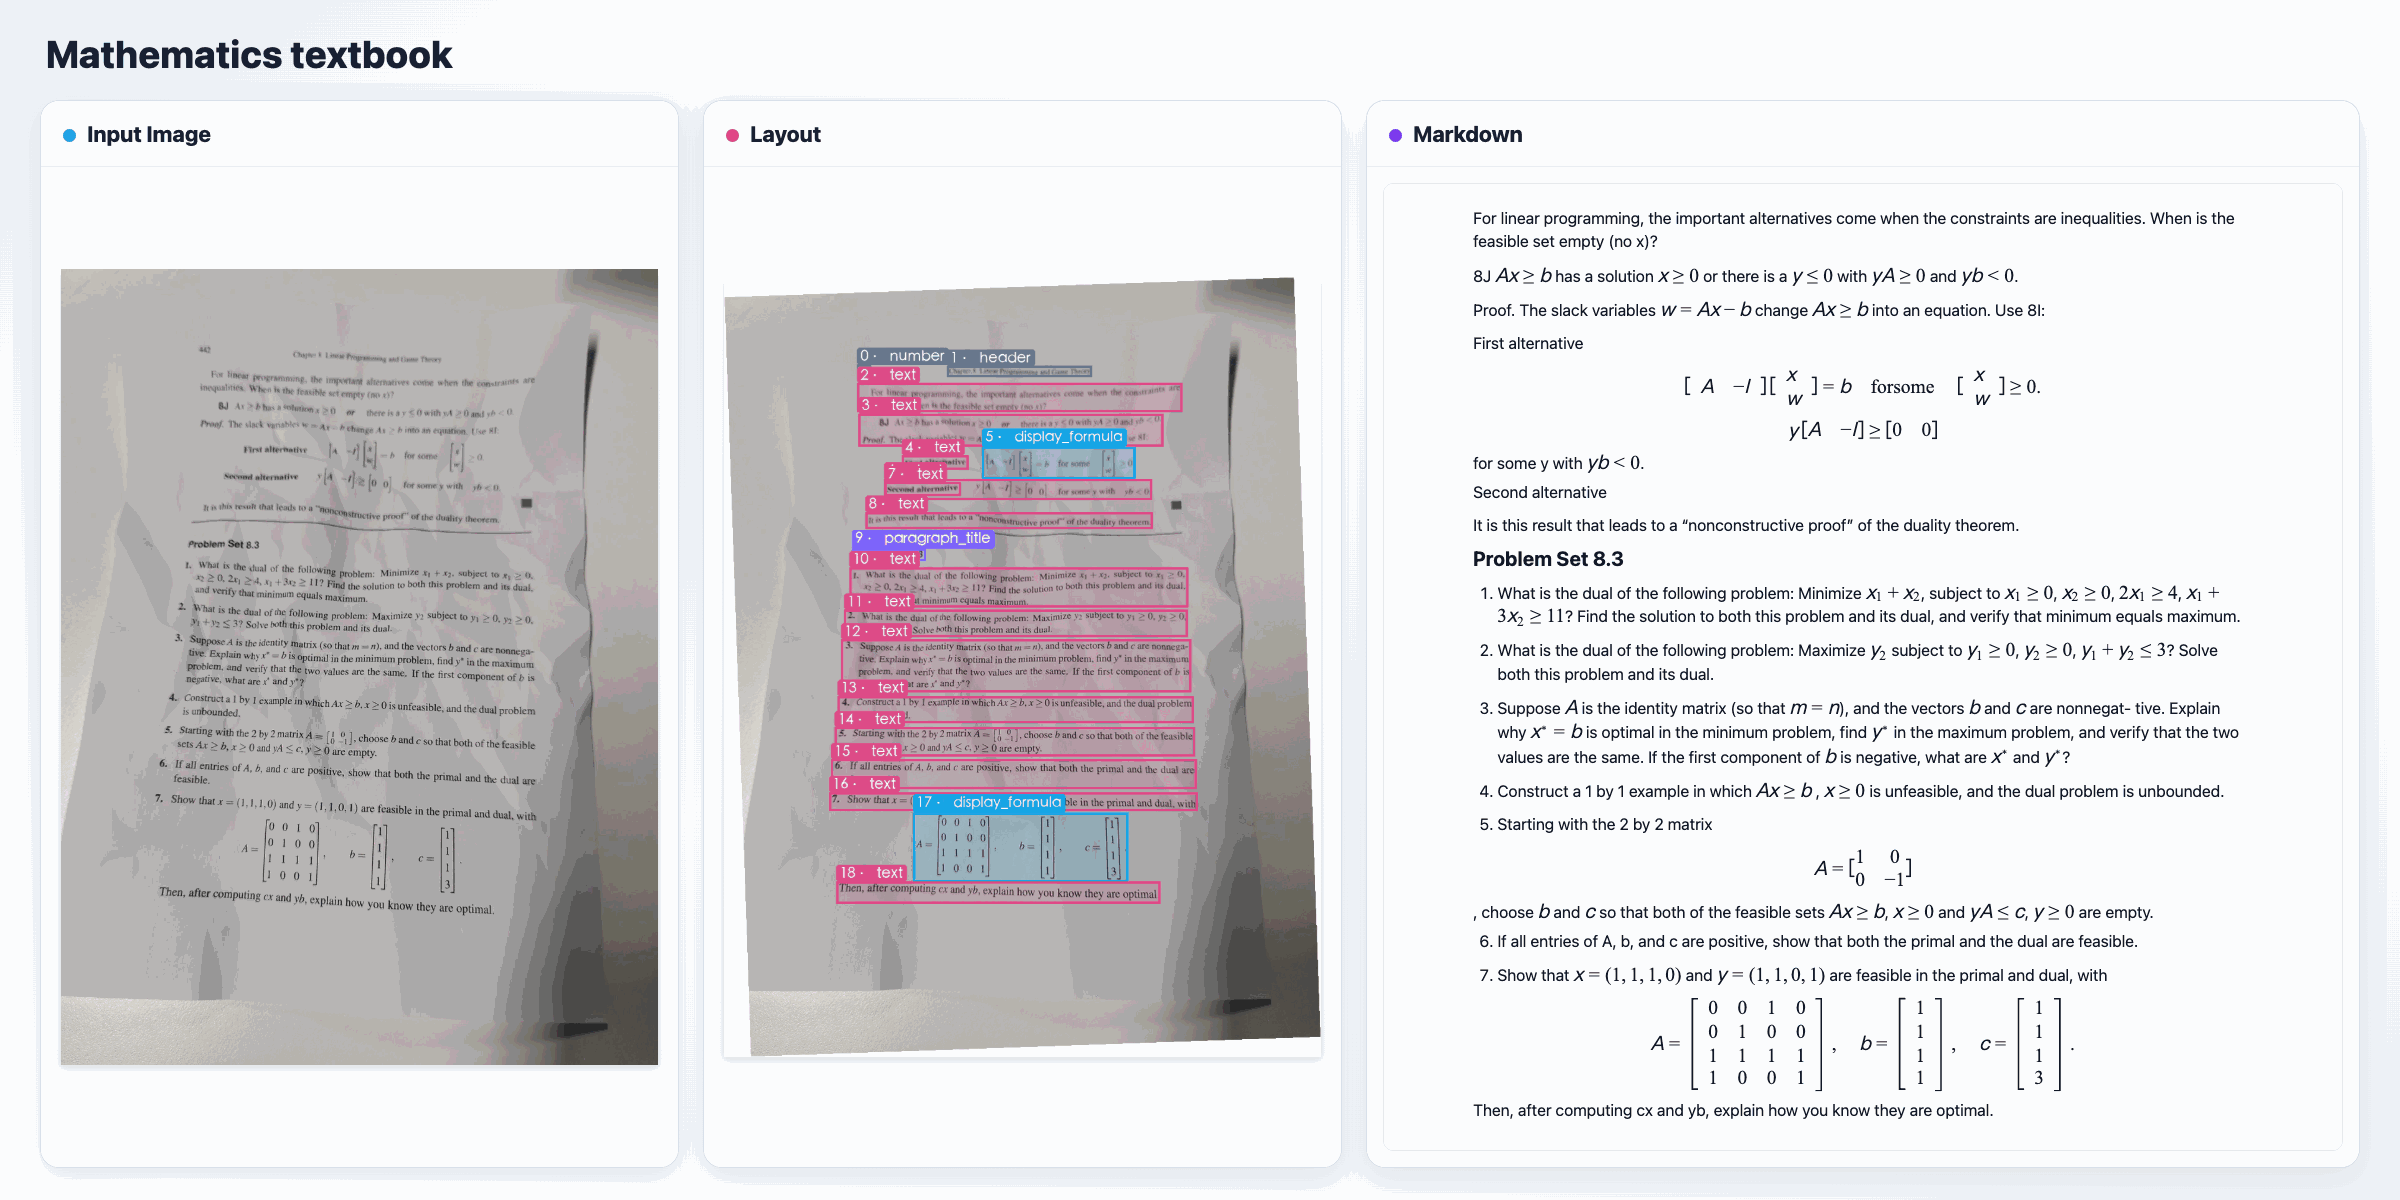
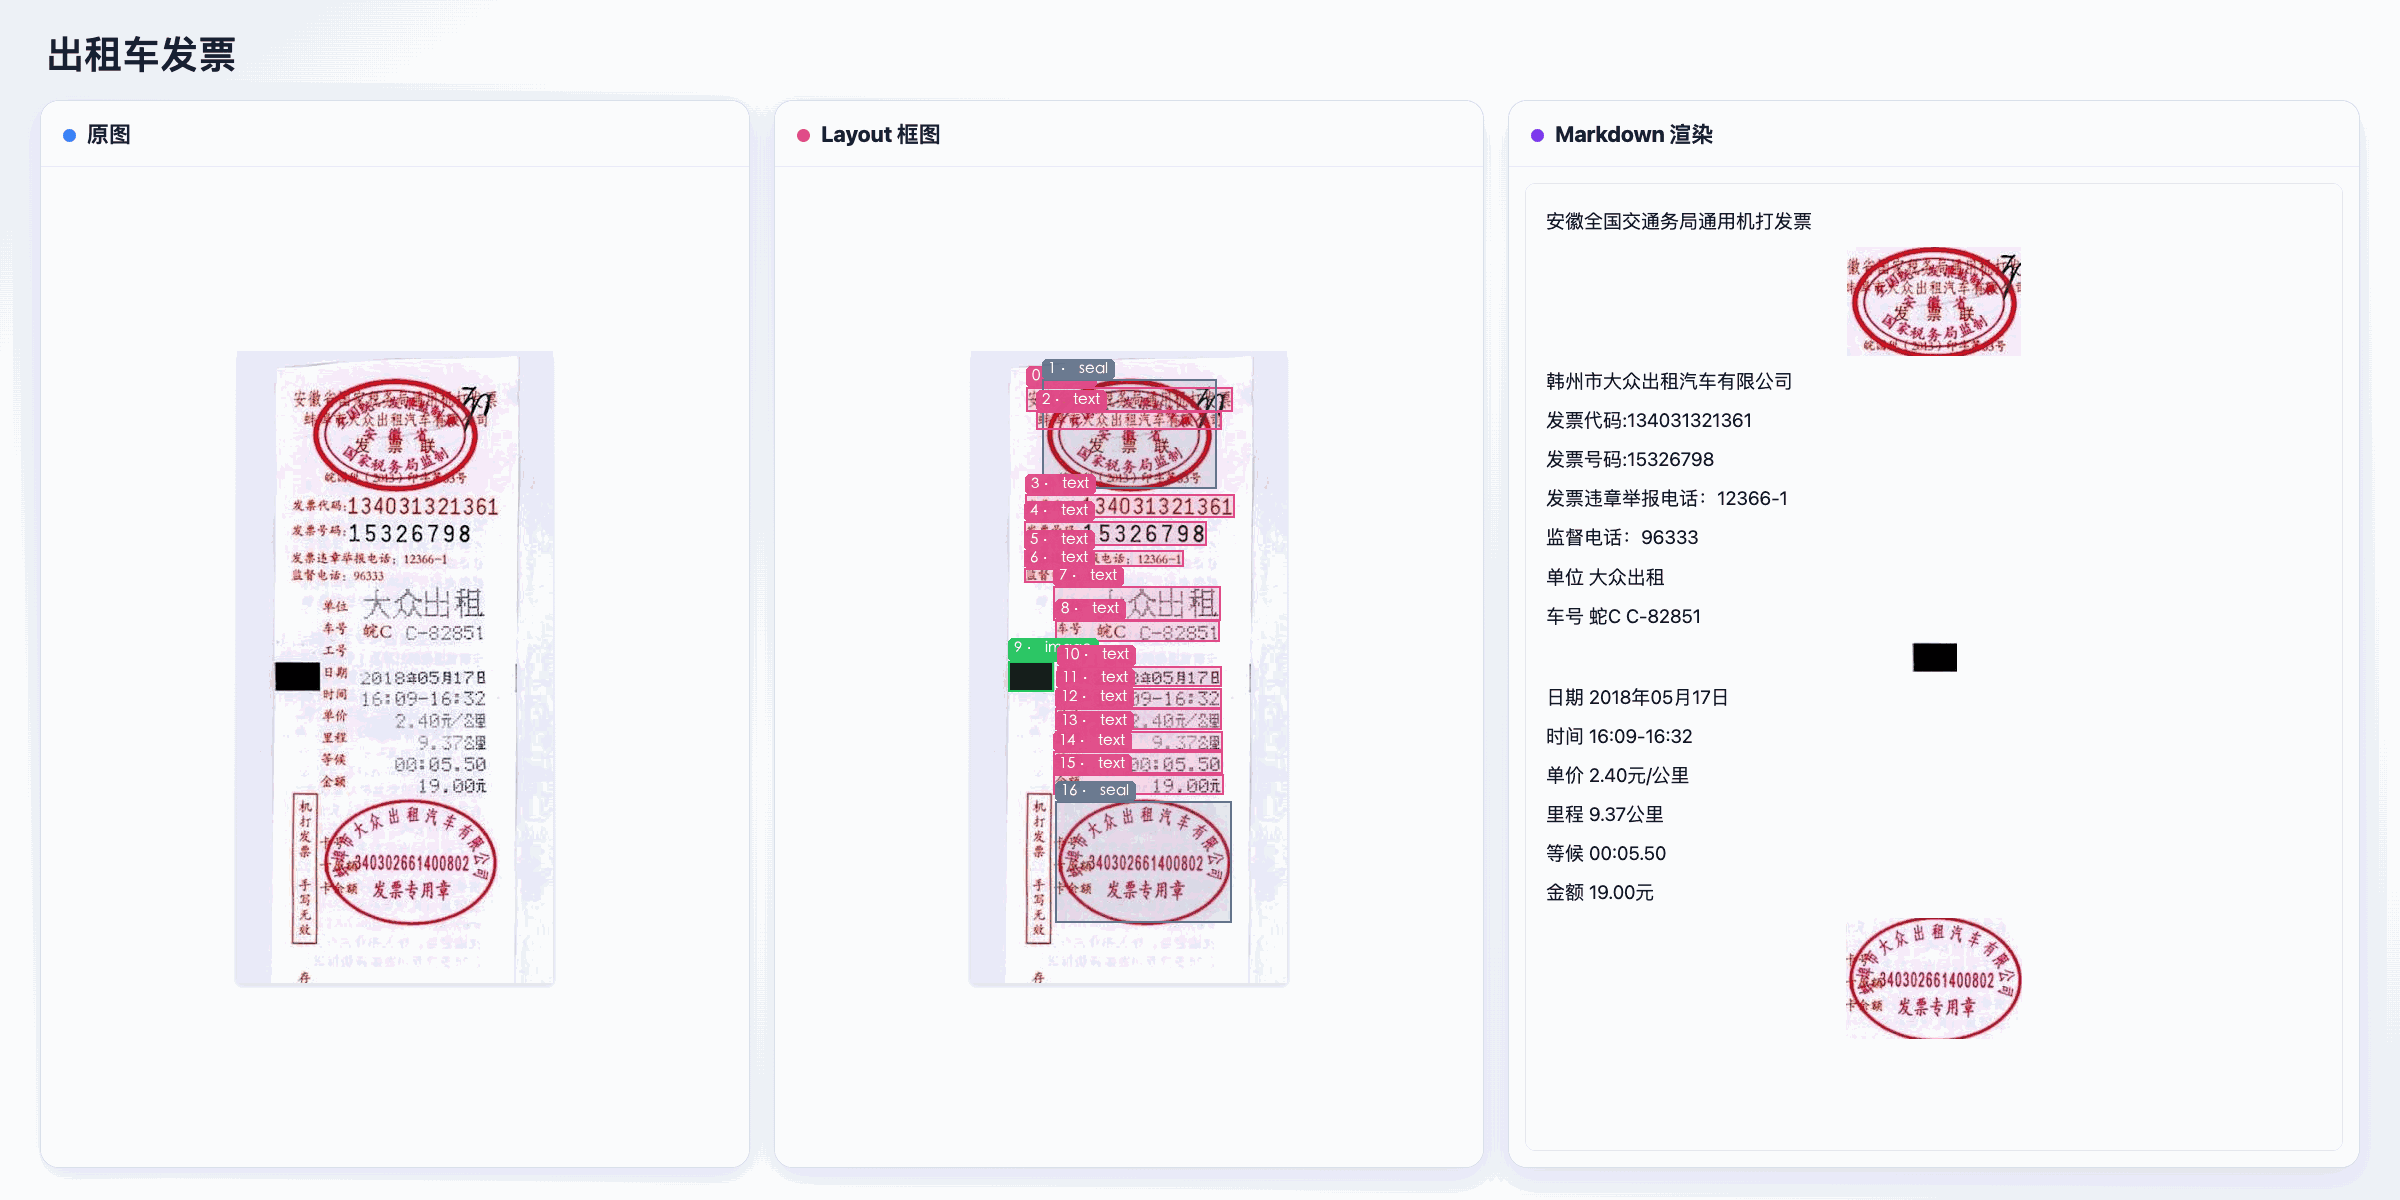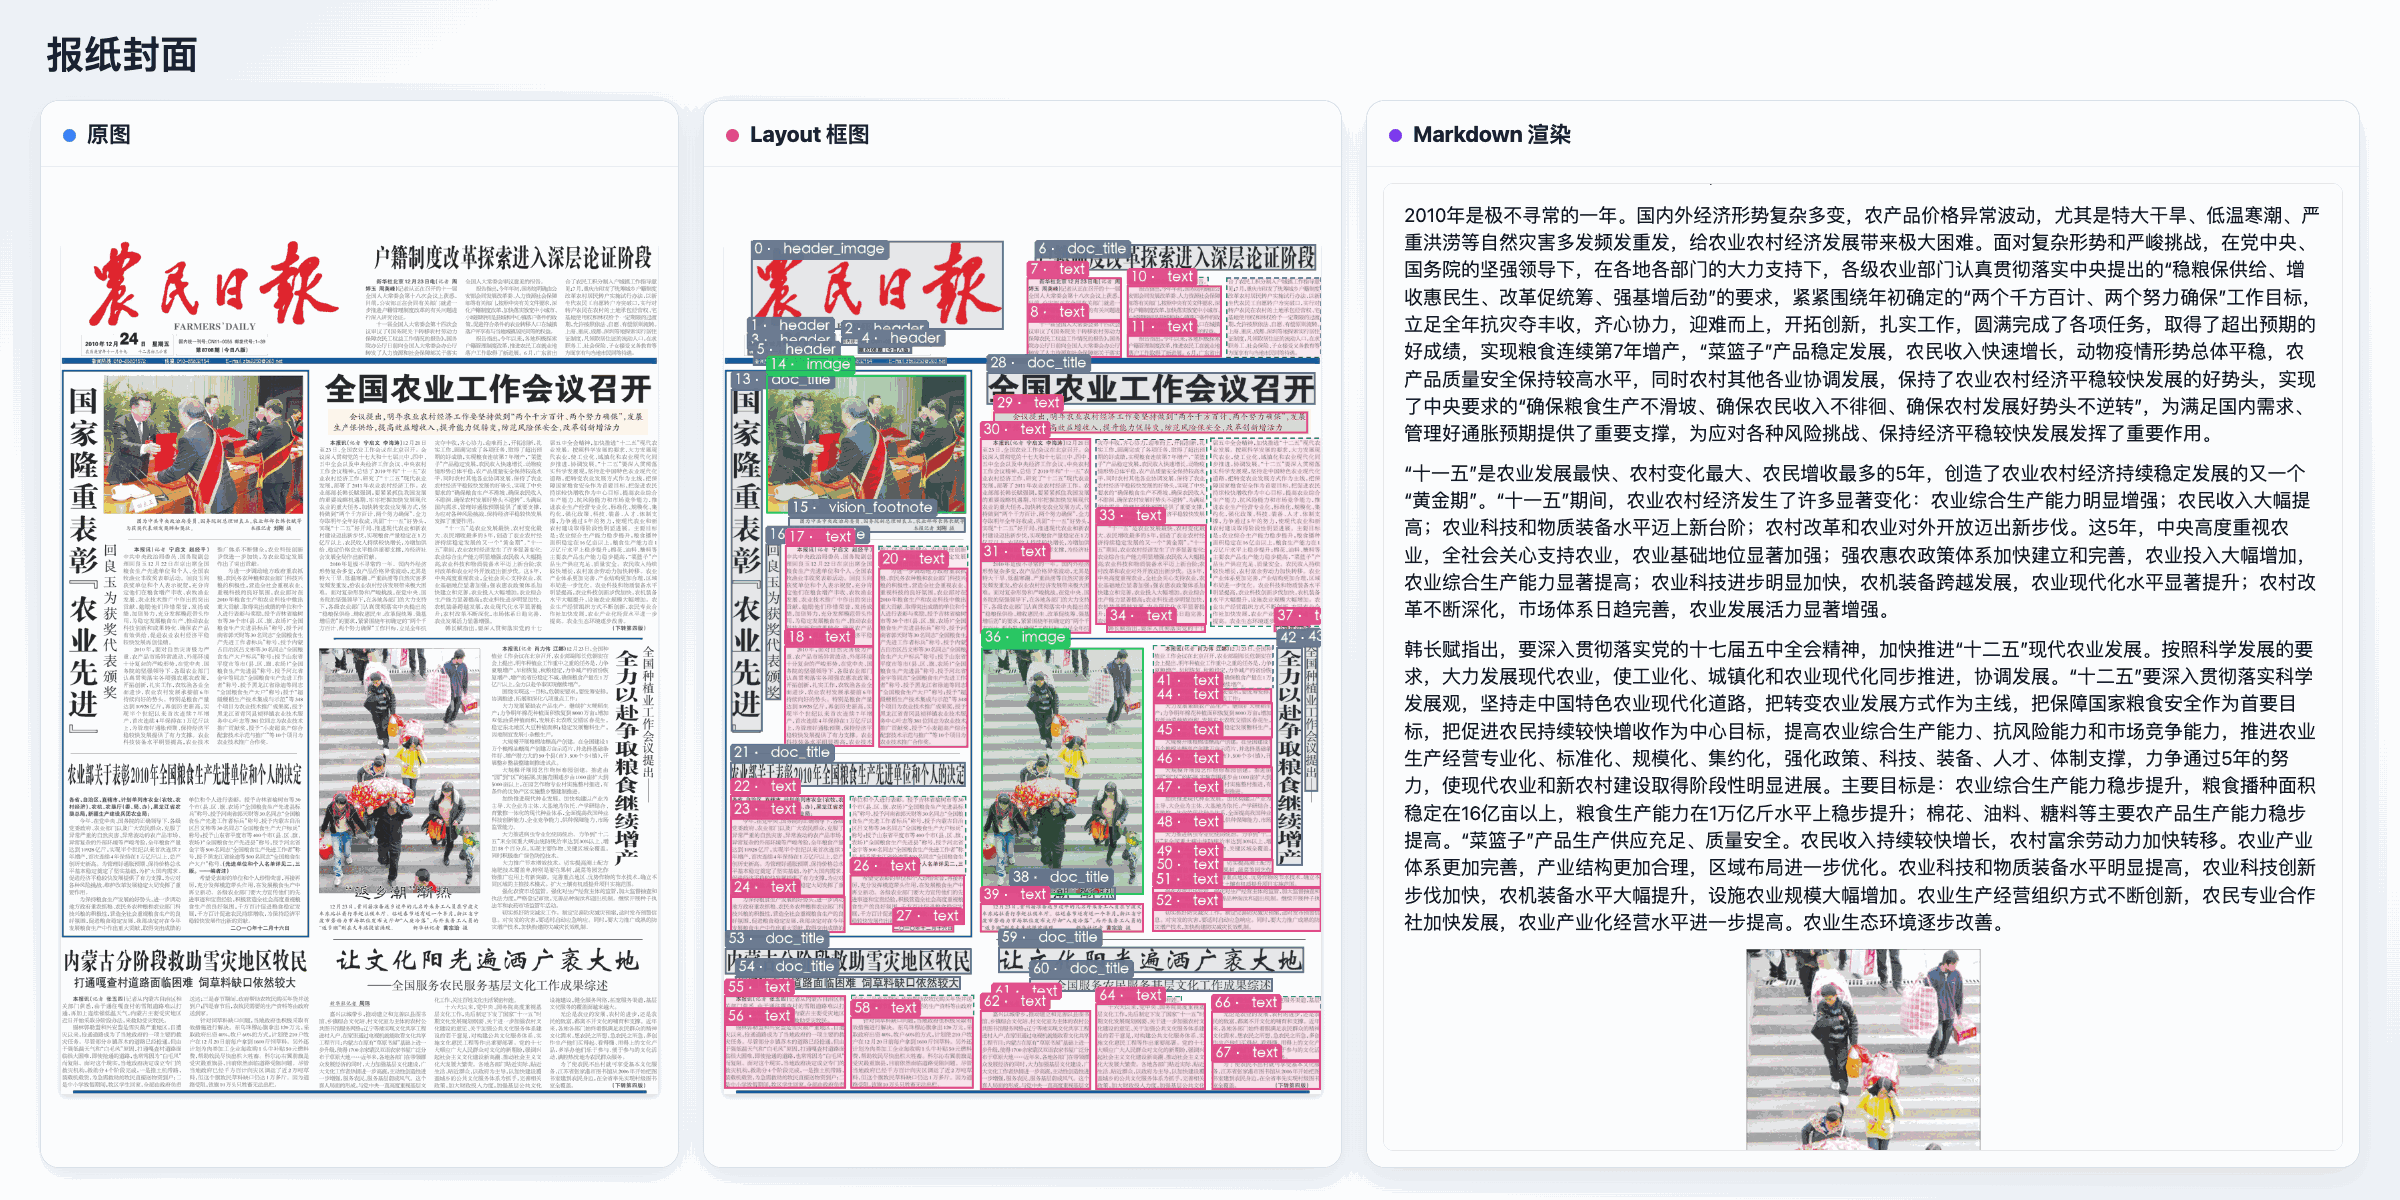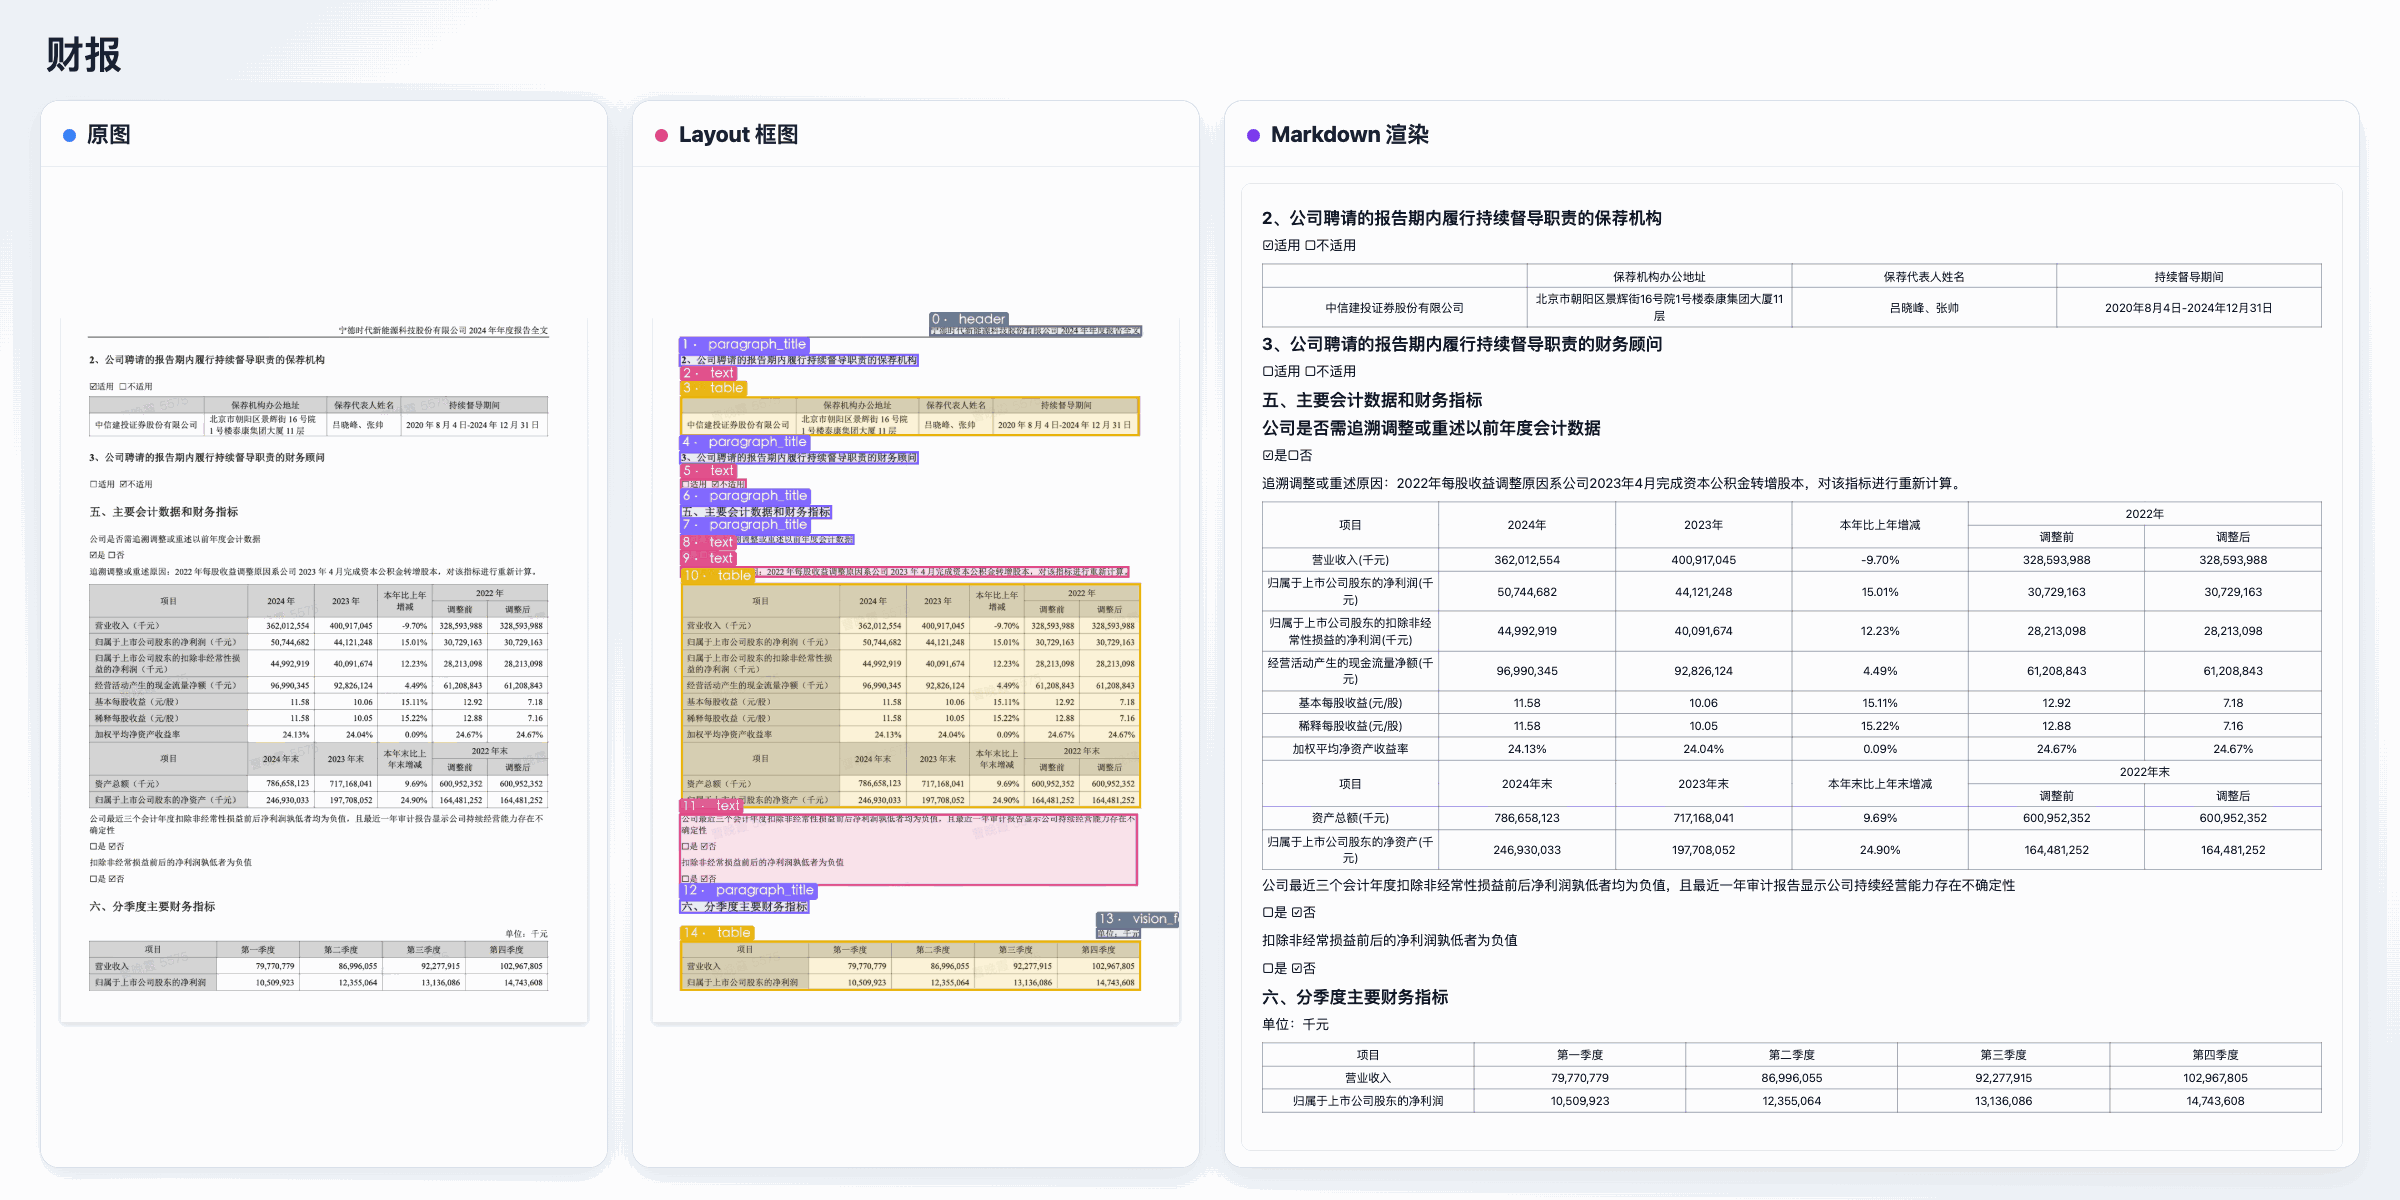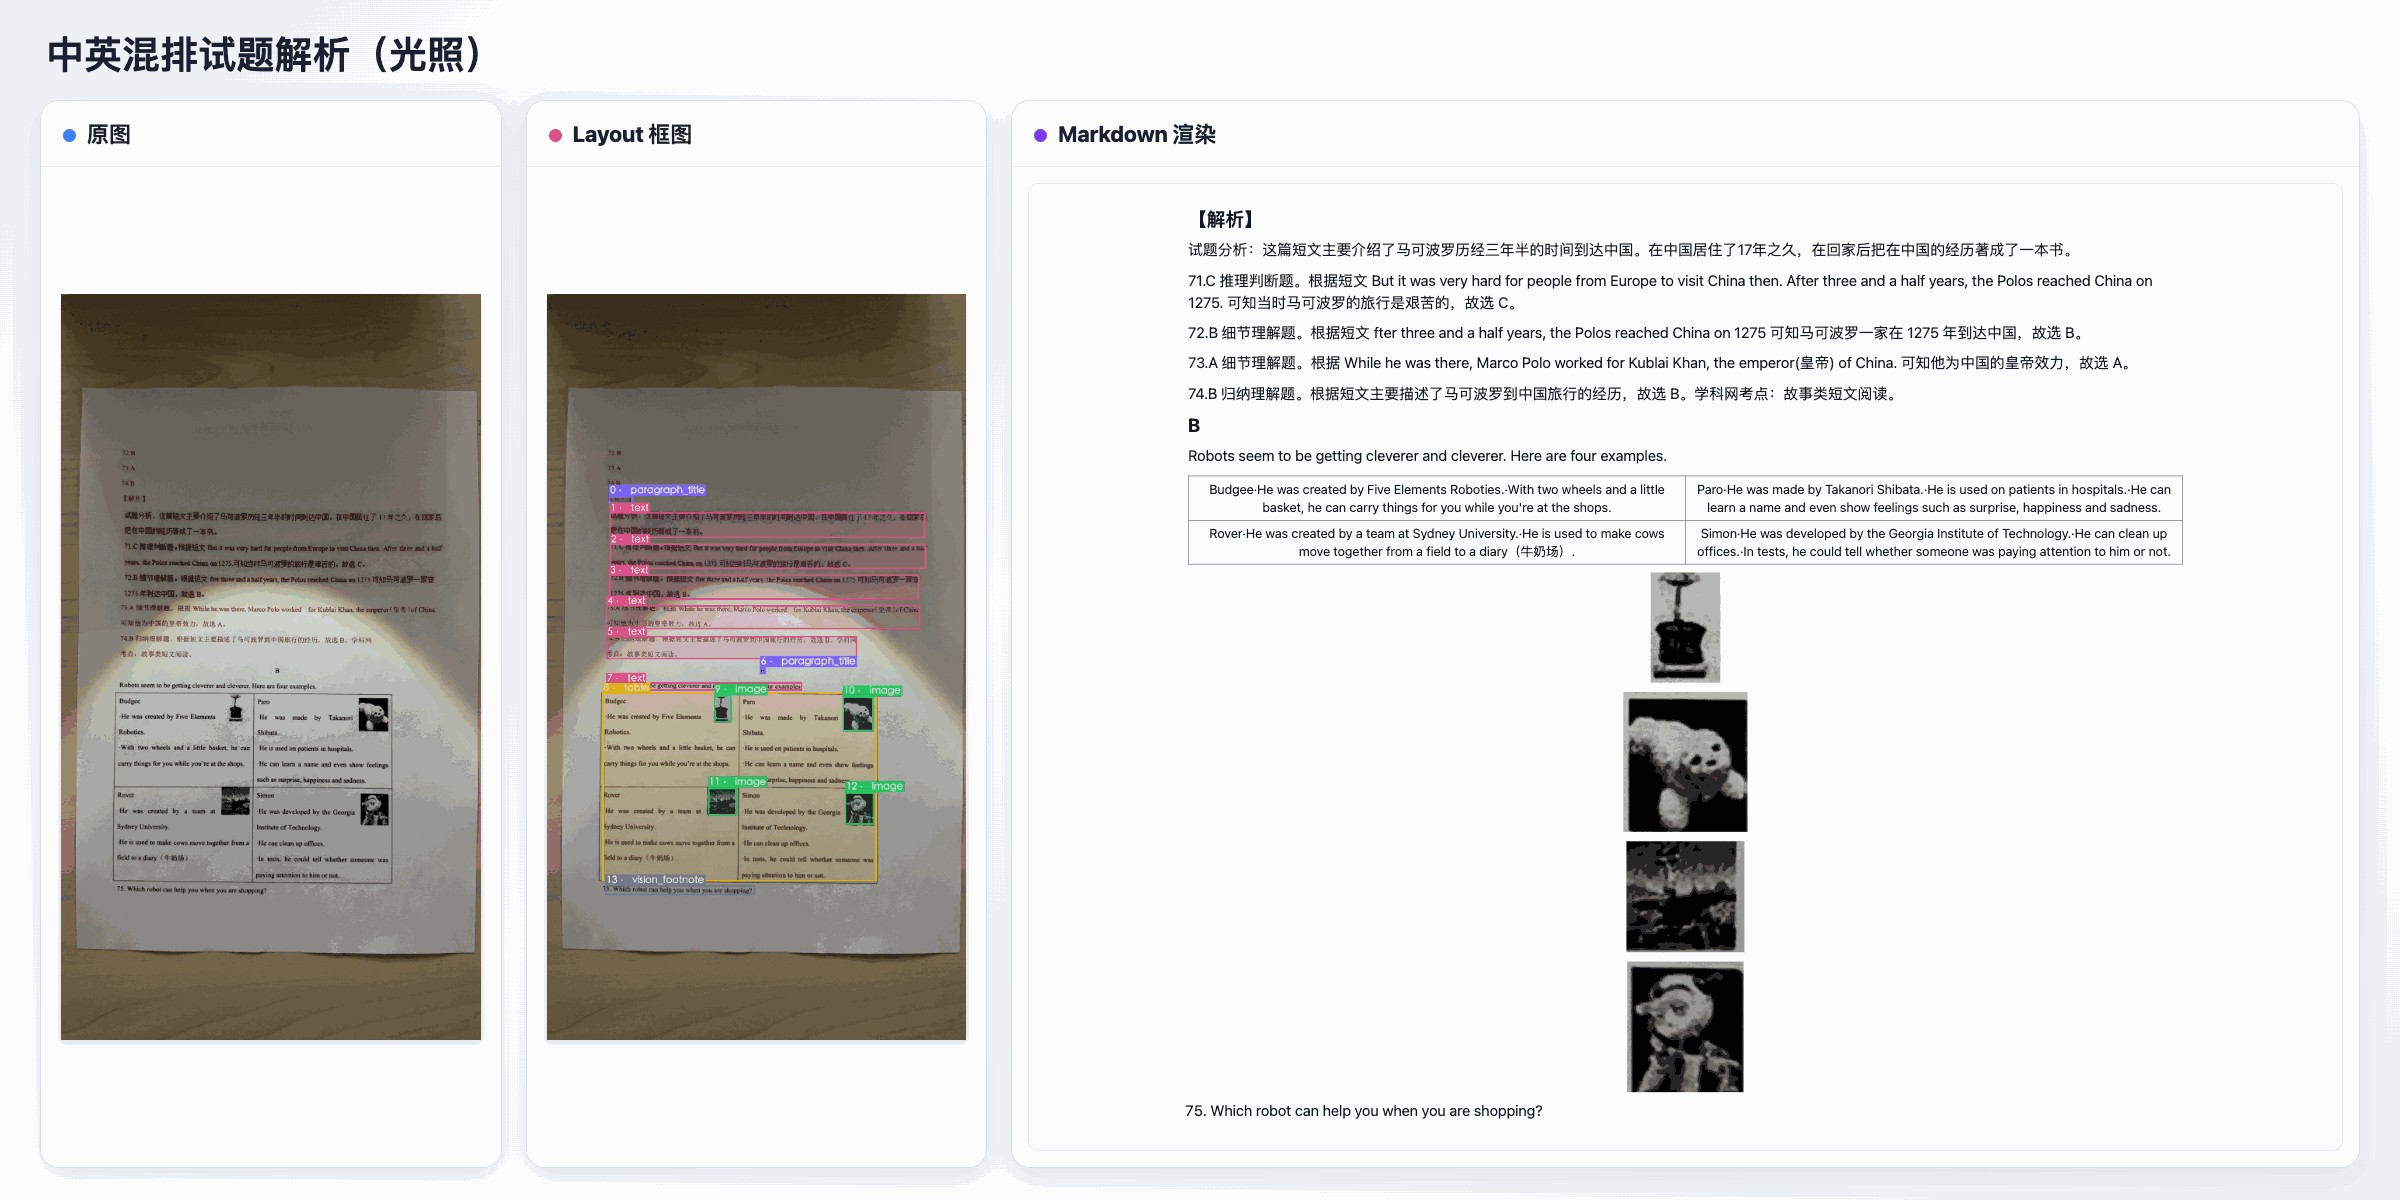
Left to right: original document, detected layout, and rendered Markdown.
### English Documents
### Chinese Documents
More Examples
Original documents and parsed results, side by side.
**Chinese Documents**
**English Documents**
## Reproduction
See the [reproduction guide](./benchmark_reproduction_en.md) for test settings, DSpark comparison requirements, and evaluation details still to be added. For current dependency versions and prerequisites, see [Version and environment checks](./SKILL_en.md#2-check-versions-and-prerequisites-against-the-checkout).
## Frequently Asked Questions
See the [FAQ](./faq_en.md) for installation, model downloads, GPU memory, input formats, and unexpected outputs.
## License
MiniCPM-OCR 1.0 model weights, code, and documentation are released under the [Apache License 2.0](../LICENSE).