# Video DeltaNet: Hybrid Attention to Speed Up Video Models with Near-Lossless Quality
[[`📄 Paper`](https://arxiv.org/abs/2609.20744)] [[`Blog`](https://openvdn.github.io/)] [[`Code`](https://github.com/OpenVDN/vdn-minimax-h3)] [[`🤗 Weights`](https://huggingface.co/OpenVDN/vdn-minimax-h3)] [[`ModelScope`](https://www.modelscope.ai/models/OpenVDN/vdn-minimax-h3)] [[`Local Inference`](https://github.com/FlashML-org/FreeVideo)] [[`License`](#license)]
We release **VDN-Minimax-H3** (**VDN-H3**), a hybrid-attention model that generates video faster than it plays, powered by [MiniMax H3](https://huggingface.co/MiniMaxAI/MiniMax-H3). It offers these key features:
- **Fast inference:** With SGLang Diffusion on 8×B200 GPUs, VDN-H3 generates a 14.4-second clip in about **9.0 seconds end-to-end**, including **6.9 seconds for denoising**, using 8 denoising steps.
- **Hybrid Architecture:** We propose a hybrid-attention architecture: one frame-wise linear attention branch that is highly efficient, and a softmax branch that maintains the backbone's visual quality and consistency.
- **Plug-and-Play:** The checkpoint adds a separate linear attention branch and two small LoRA adapters that can be merged into the backbone during inference without touching the backbone weights.
- **Fully open-source:** We don't just open-source the weights. The optimized inference stack and its corresponding training code are released together.
We present some samples of generated videos here:
## News
- **October 2, 2026:** [FreeVideo](https://github.com/FlashML-org/FreeVideo), built on VDN-H3, runs MiniMax H3 on consumer GPUs with as little as 8 GB of VRAM.
- **September 17, 2026:** The [Video DeltaNet paper](https://arxiv.org/abs/2609.20744) is available on arXiv.
- **September 17, 2026:** We support the [Ref2VA-like](#supporting-ref2va-like-task) task now with the same checkpoint: reference images through the FL2VA weights.
- **September 14, 2026:** [SGLang Diffusion](https://github.com/sgl-project/sglang) now supports VDN-H3, achieving its fastest reported performance: 6.9 seconds for denoising and about 9.0 seconds end-to-end for a 14.4-second video on 8×B200 GPUs. See the [MiniMax-H3 cookbook](https://github.com/sgl-project/sglang/blob/main/docs/cookbook/diffusion/MiniMax/MiniMax-H3.mdx#7-vdn-h3-hybrid-attention-8-step-distill) for more details.
- **September 8, 2026:** We support I2VA, FL2VA and L2VA now with the same checkpoint.
- **September 6, 2026:** We released the [VDN-H3 blog](https://openvdn.github.io/), [training and inference code](https://github.com/OpenVDN/vdn-minimax-h3), and [model weights](https://huggingface.co/OpenVDN/vdn-minimax-h3).
## Set up the environment
**Before you begin**, please read the [license](#license) before downloading or running VDN-H3.
1. Clone the VDN-H3 repository from GitHub.
```bash
git clone https://github.com/OpenVDN/vdn-minimax-h3.git
cd vdn-minimax-h3
```
2. Create the environment. We recommend PyTorch 2.13 (`torch.__version__` = `2.13.0+cu129`) and installing FlashAttention 4: on Hopper and data-center Blackwell the window softmax runs on its kernels, through [FlexAttention's Flash backend](https://pytorch.org/blog/flexattention-flashattention-4-fast-and-flexible/) or directly. On Ampere, Ada and consumer Blackwell (RTX 50 series), or without it, the window softmax runs on FlexAttention's Triton kernel and on PyTorch's own varlen attention.
```bash
conda create -n vdn python=3.12 -y
conda activate vdn
pip install uv
uv pip install torch==2.13.0 --index-url https://download.pytorch.org/whl/cu129
```
3. Install the other packages shown in `pyproject.toml`, `flash-attn-4` included (`--prerelease=allow` is needed for its pre-release `nvidia-cutlass-dsl` dependency); on Ampere, Ada and consumer Blackwell neither it nor the regular `flash-attn` is used, as attention there runs on PyTorch's own kernels.
```bash
uv pip install --prerelease=allow -e .
```
4. Install the patched Diffusers. The setup script handles everything:
```bash
bash scripts/setup_diffusers.sh
```
5. Read [H3-Context-IR](https://platform.minimax.io/docs/api-reference/video-generation-v2-h3-context-ir) and the official [prompt-writing skills](https://github.com/MiniMax-AI/MiniMax-H3/tree/main/skills). Rewriting your prompt with them before encoding it can greatly improve the generated video quality for VDN-H3 inference.
## Quick Start — Generate your own video
### Inference with Diffusers
The quickest way to a first render is using diffusers, as we already release the checkpoints as modular diffusers components:
```python
import torch
from accelerate import cpu_offload_with_hook
from diffusers import ModularPipeline
from diffusers.hooks import apply_group_offloading
pipe = ModularPipeline.from_pretrained("OpenVDN/vdn-minimax-h3", workflow="t2va")
pipe.load_components(trust_remote_code=True, torch_dtype=torch.bfloat16)
apply_group_offloading(pipe.text_encoder, onload_device="cuda", offload_type="leaf_level",
use_stream=True)
_, vae = cpu_offload_with_hook(pipe.vae, execution_device="cuda")
cpu_offload_with_hook(pipe.audio_vae, execution_device="cuda", prev_module_hook=vae)
pipe.transformer.to("cuda")
out = pipe(prompt="a prompt", num_frames=345, num_inference_steps=9,
output=["videos", "audio", "sampling_rate"])
```
`num_inference_steps` counts sigma grid points, so 9 of them is 8 model evaluations.
Or as a script, keyframes included:
```bash
python src/inference/infer_diffusers.py "a prompt" --out results/diffusers.mp4
python src/inference/infer_diffusers.py "a prompt" \
--first prompts/image/first.png --last prompts/image/last.png
```
On a 24 GB card, stream the transformer in one block at a time: swap `pipe.transformer.to("cuda")` for the line below, or add `--offload_dit` to the script. 345 frames then peak at 22 GB, 20 in fp8.
```python
apply_group_offloading(pipe.transformer, onload_device="cuda", offload_type="block_level",
num_blocks_per_group=1, use_stream=True)
```
Offloading granularity, the window-softmax backend, fp8 and your own quantization config are described in [docs/diffusers.md](docs/diffusers.md).
### Inference with SGLang
[SGLang Diffusion](https://github.com/sgl-project/sglang) provides native VDN-H3 serving for T2VA and FL2VA. Install SGLang and launch the 8×B200 configuration below. Set `--num-gpus` to 1, 2, or 4 for the corresponding smaller configuration:
```bash
uv pip install "sglang[diffusion]" --prerelease=allow
sglang serve \
--model-path OpenVDN/vdn-minimax-h3 \
--num-gpus 8 \
--quantization fp8 \
--attention-backend hybrid_window_attn_h3 \
--performance-mode speed \
--warmup-num-frames 345 \
--warmup-resolutions 1344x768 \
--port 30010
```
With MXFP8, denoising takes 47.6, 25.9, 13.1, and 6.9 seconds on 1, 2, 4, and 8 B200 GPUs, respectively. The 8-GPU configuration returns the finished 14.4-second video in about 9.0 seconds end-to-end after warm-up. See the [MiniMax-H3 cookbook](https://github.com/sgl-project/sglang/blob/main/docs/cookbook/diffusion/MiniMax/MiniMax-H3.mdx#7-vdn-h3-hybrid-attention-8-step-distill) for more details.
### Inference with our repository
The configs, kernels, fp8, the eight-GPU layout and the prompt caches are described in [docs/inference.md](docs/inference.md).
#### Download the weights
To render through this repository's own stack instead -- fp8, the tuned kernels, and Ulysses across eight GPUs, which is where the numbers in [Results](#results) come from -- download everything (about 82 GB) from [Hugging Face](https://huggingface.co/OpenVDN/vdn-minimax-h3) into `ckpts/` using
```bash
hf download OpenVDN/vdn-minimax-h3 --local-dir ckpts
```
or from [ModelScope](https://www.modelscope.ai/models/OpenVDN/vdn-minimax-h3) with
```bash
modelscope download --model OpenVDN/vdn-minimax-h3 --local_dir ckpts
```
The layout will look like
```text
ckpts/
h3-base/ the released MiniMax H3: transformer, video and audio VAEs, schedulers · 72 GB
stage-b-step-2000/ VDN-H3-50-step: linear_branch/ + adapters/default/ LoRA · 4.3 GB
stage-dmd-step-250/ VDN-H3-8-step: the above + adapters/turbo/ · 5.1 GB
```
#### Render a video
Then, run the following script:
```bash
bash scripts/inference/8nfe_tuned_fp8.sh
```
Note that the first run needs to compile all of the kernels, which might take several minutes. Later runs can reuse the cache.
#### Use your own prompt
We provide [three examples](prompts/README.md) and encode them using the Qwen3-VL-32B VLM. For your own prompt, you should first encode it using the VLM, then render it through the main diffusion model:
```bash
python src/inference/encode_prompt.py --prompt "..." --out prompts/mine.pt
python src/inference/infer.py \
--config configs/inference/8nfe_tuned_fp8.yaml \
checkpoint=ckpts/stage-dmd-step-250 \
render.prompt_file=prompts/mine.pt \
render.out=results/mine.mp4
```
#### Supporting FL2VA, I2VA, and L2VA
The same checkpoints also generate from keyframes. We provide an FL2VA example in [prompts/image/](prompts/image/):
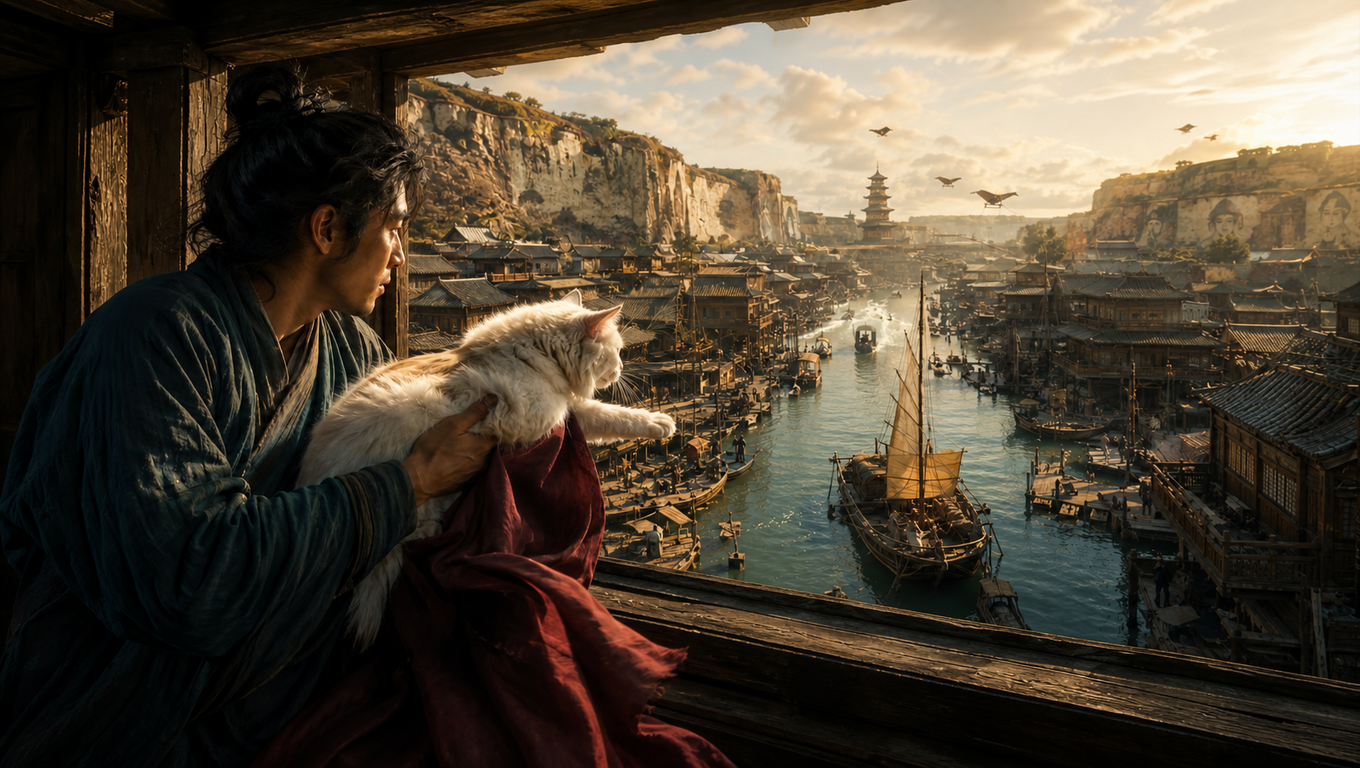 |
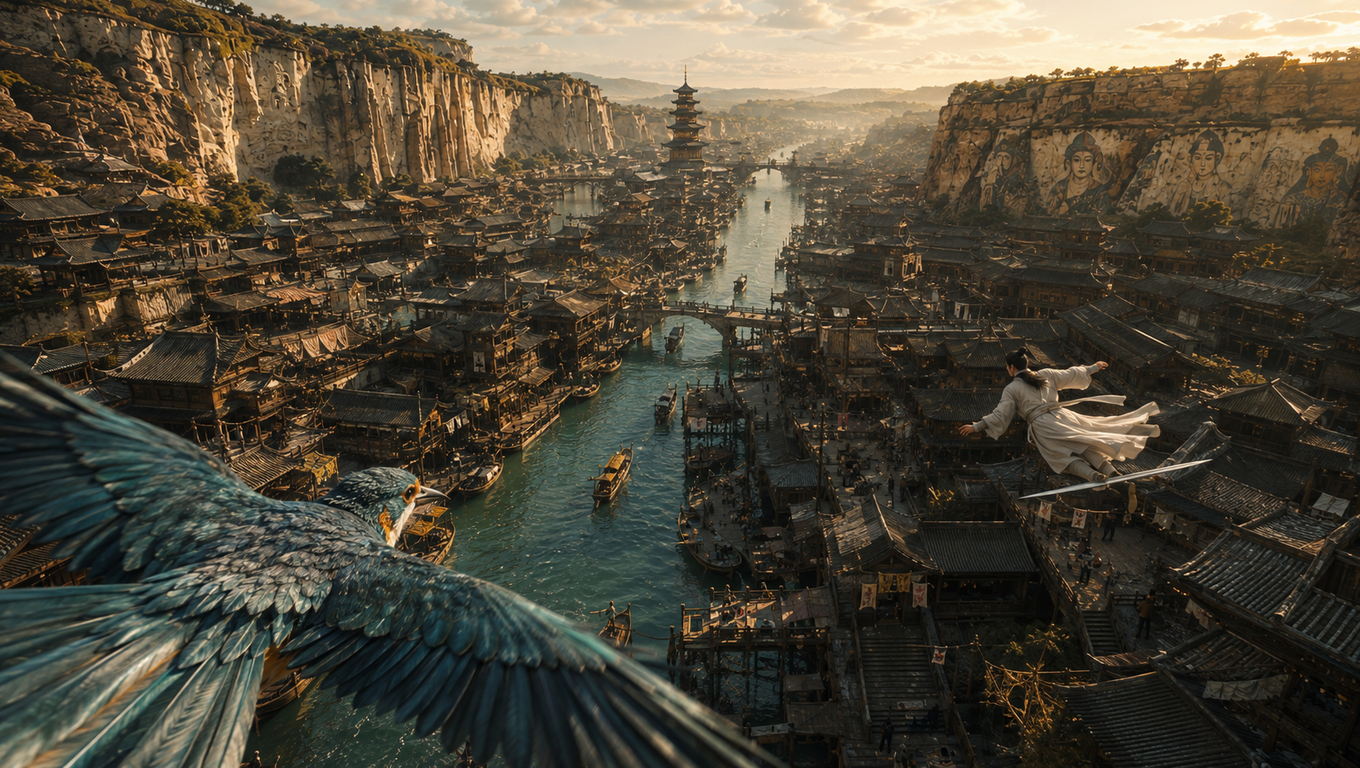 |
prompts/image/first.png |
prompts/image/last.png |
Render it with:
```bash
python src/inference/infer.py \
--config configs/inference/8nfe_tuned_fp8.yaml \
checkpoint=ckpts/stage-dmd-step-250 \
render.prompt_file=prompts/image/example_fl2va.pt \
render.out=results/example_fl2va.mp4
```
and you should get something like this:
For your own keyframes, encode the prompt together with the images first:
```bash
python src/inference/encode_keyframes.py --prompt "..." \
--first first.png --last last.png --out prompts/image/mine.pt
```
`--first` alone is I2VA, `--last` alone is L2VA, both is FL2VA. Each mode wants its own instruction as the prompt's first line, given by MiniMax-H3's [prompt writing guide](https://huggingface.co/MiniMaxAI/MiniMax-H3/blob/main/docs/VIDEO_PROMPT_WRITING_GUIDE_base_en.md).
The multi-GPU entrypoint takes the same prompt file:
```bash
torchrun --standalone --nproc_per_node=8 src/inference/infer_ulysses.py \
--config configs/inference/8nfe_tuned_fp8_ulysses_h200.yaml \
checkpoint=ckpts/stage-dmd-step-250 \
render.prompt_file=prompts/image/example_fl2va.pt \
render.out=results/example_fl2va.mp4
```
#### Supporting Ref2VA-Like Task
The MiniMax-H3 FL2VA checkpoints have zero-shot ability to take reference images and perform the way the MiniMax-H3 Ref2VA checkpoints generate videos. Each reference image appears in the prompt as a `` entry and is accompanied by its own block of conditioning rows placed before the video tokens.
Generation still uses the FL2VA weights rather than MiniMax-H3's separate Ref2VA transformer, which is why we describe this mode as Ref2VA-like rather than Ref2VA proper.
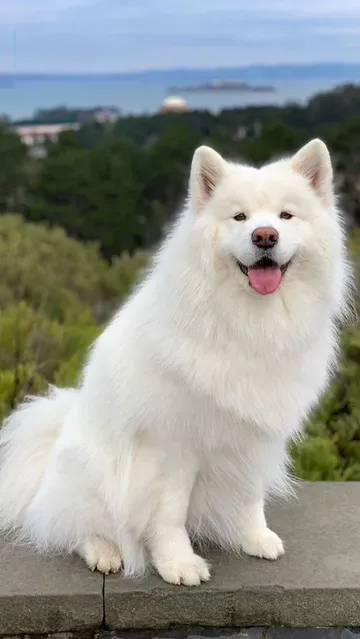
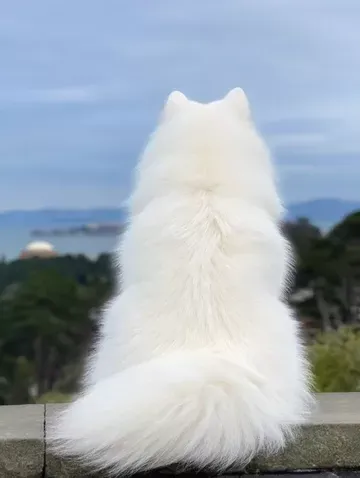
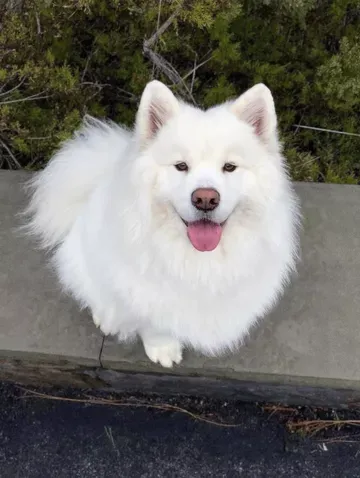
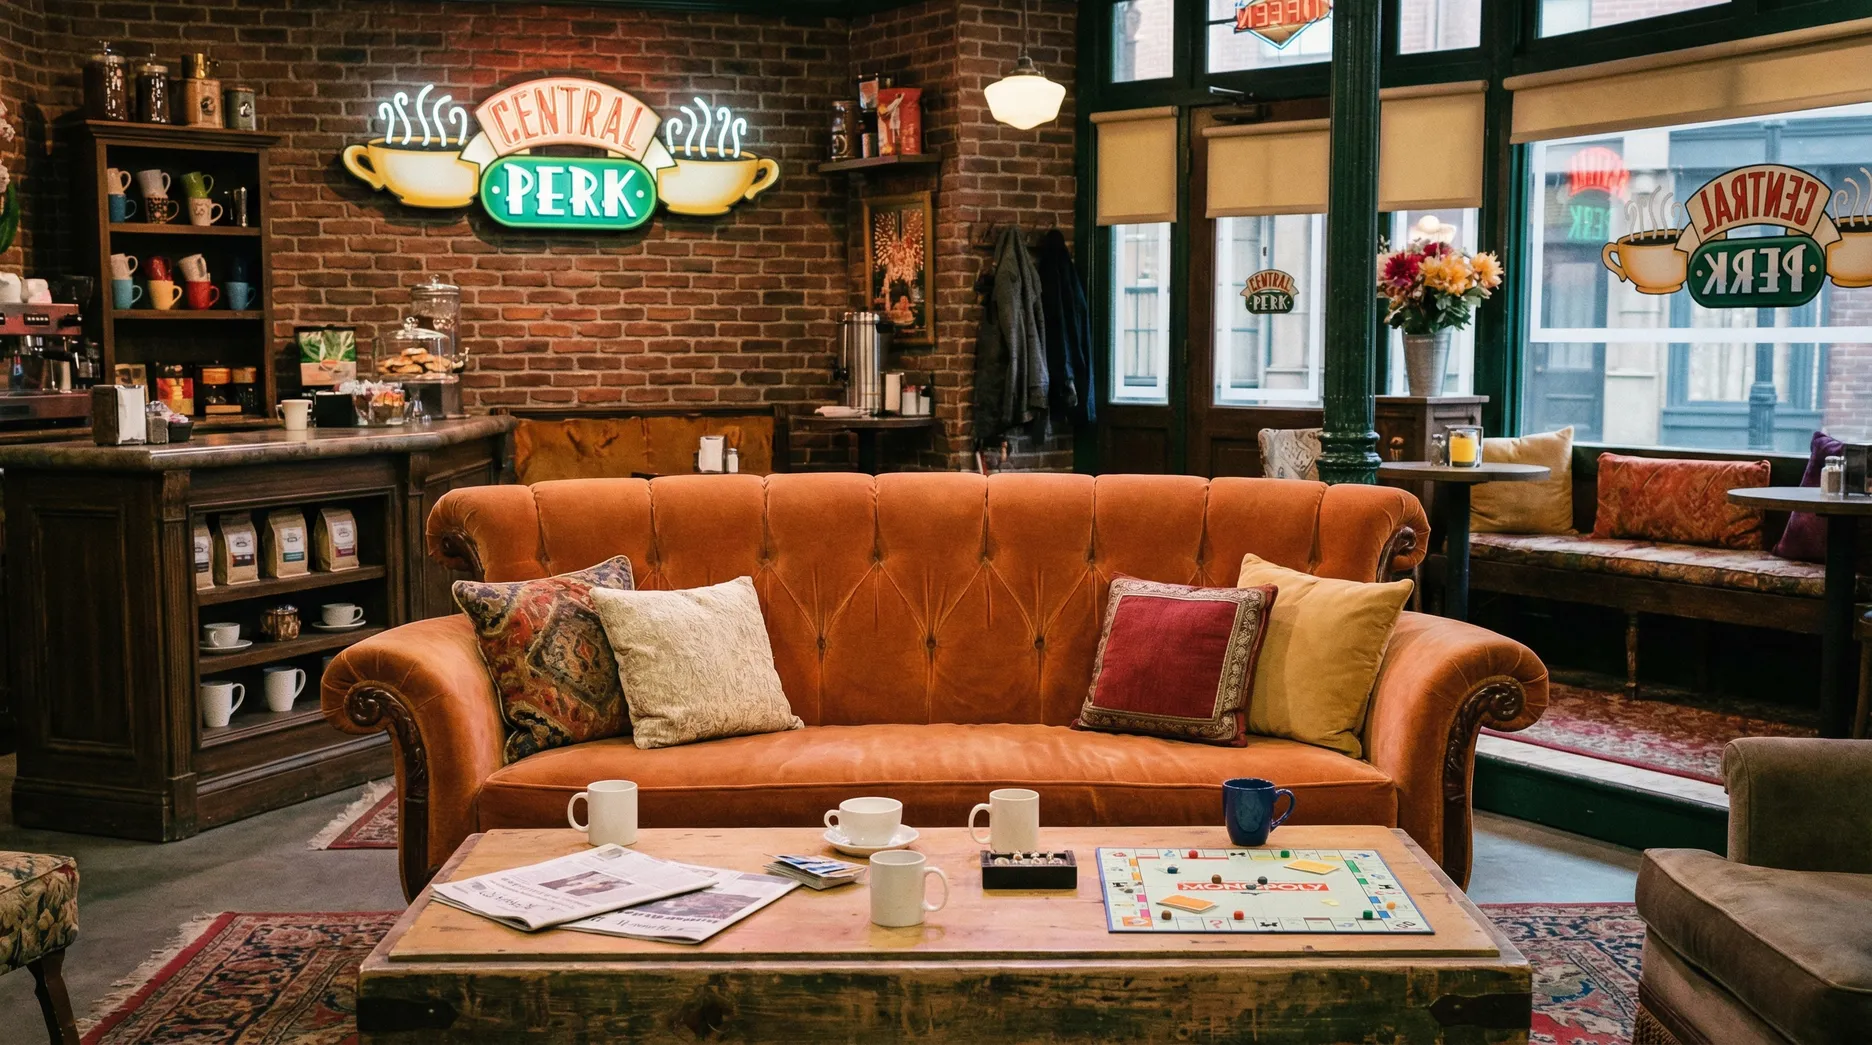
An example is provided in [prompts/reference/](prompts/reference/), using six reference images that cover two characters, a Samoyed, and a cafe:
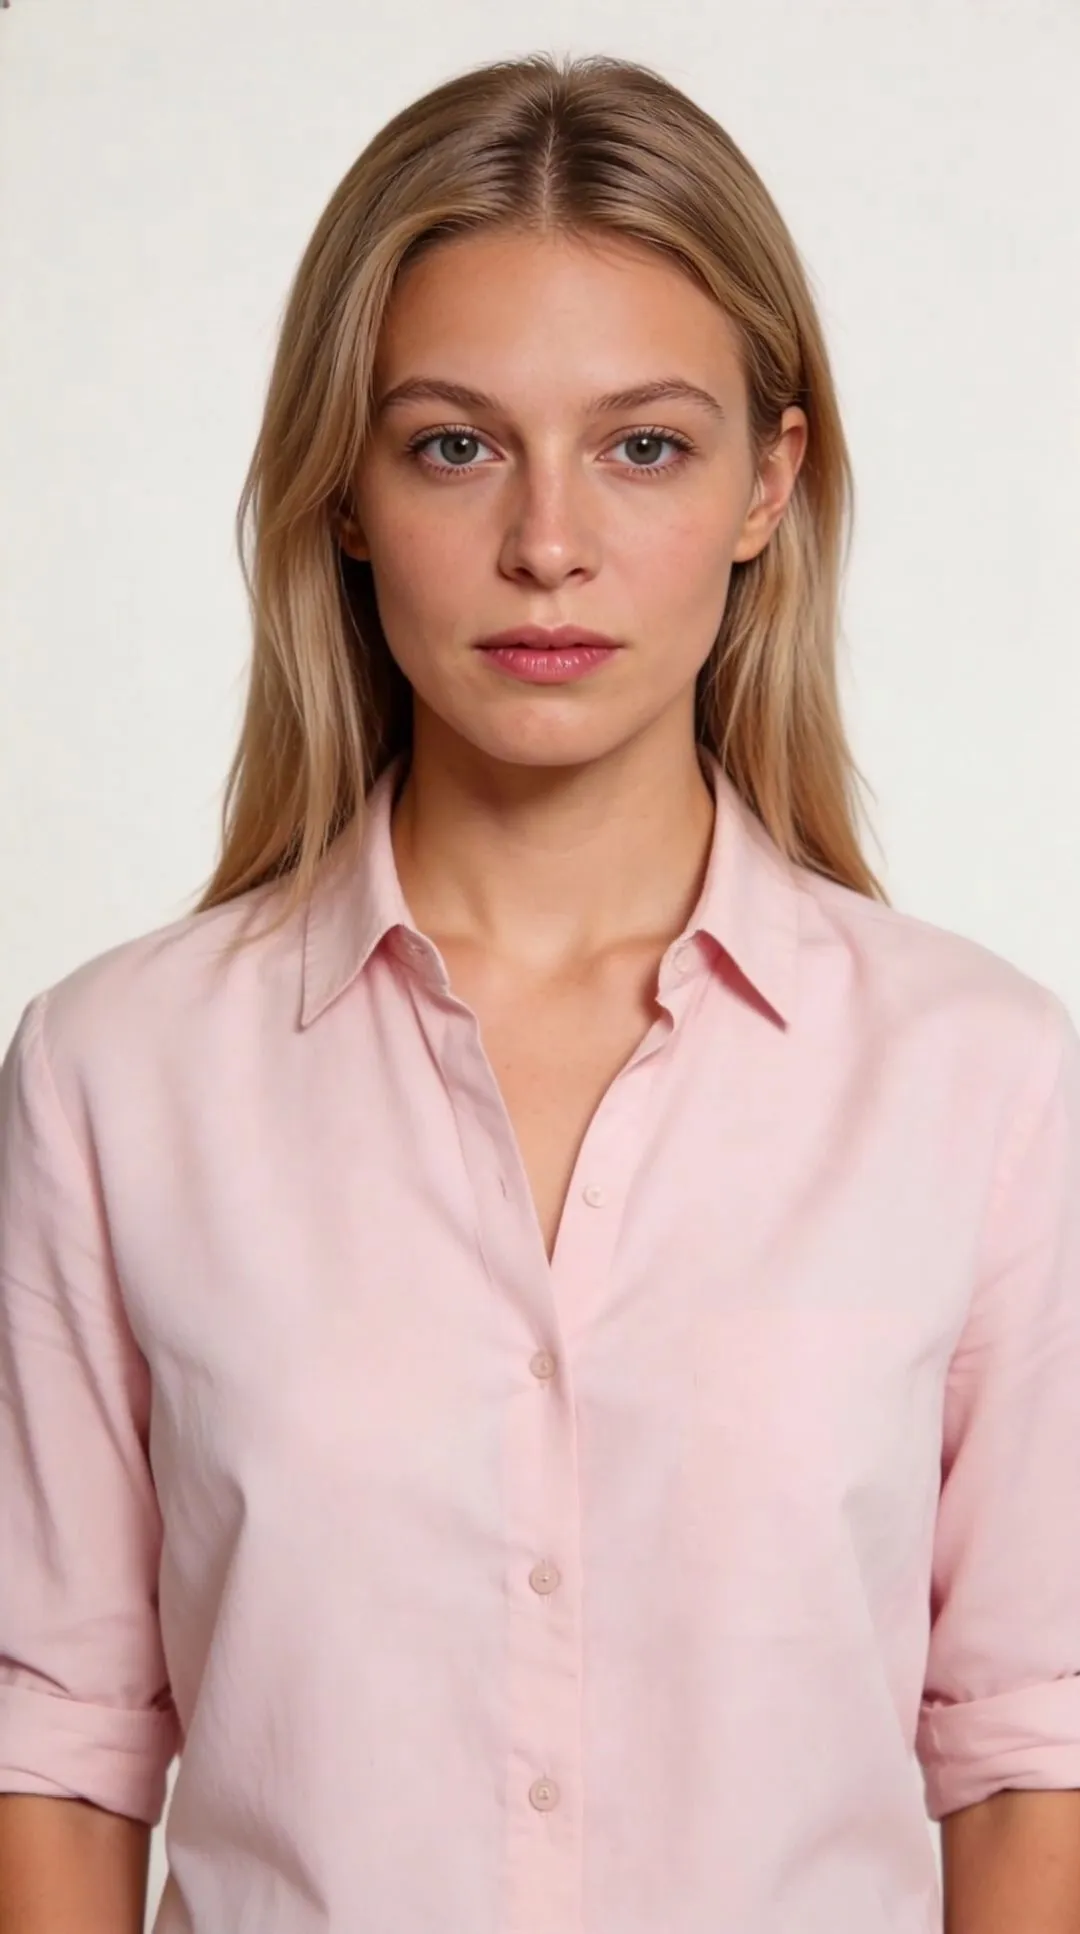 |
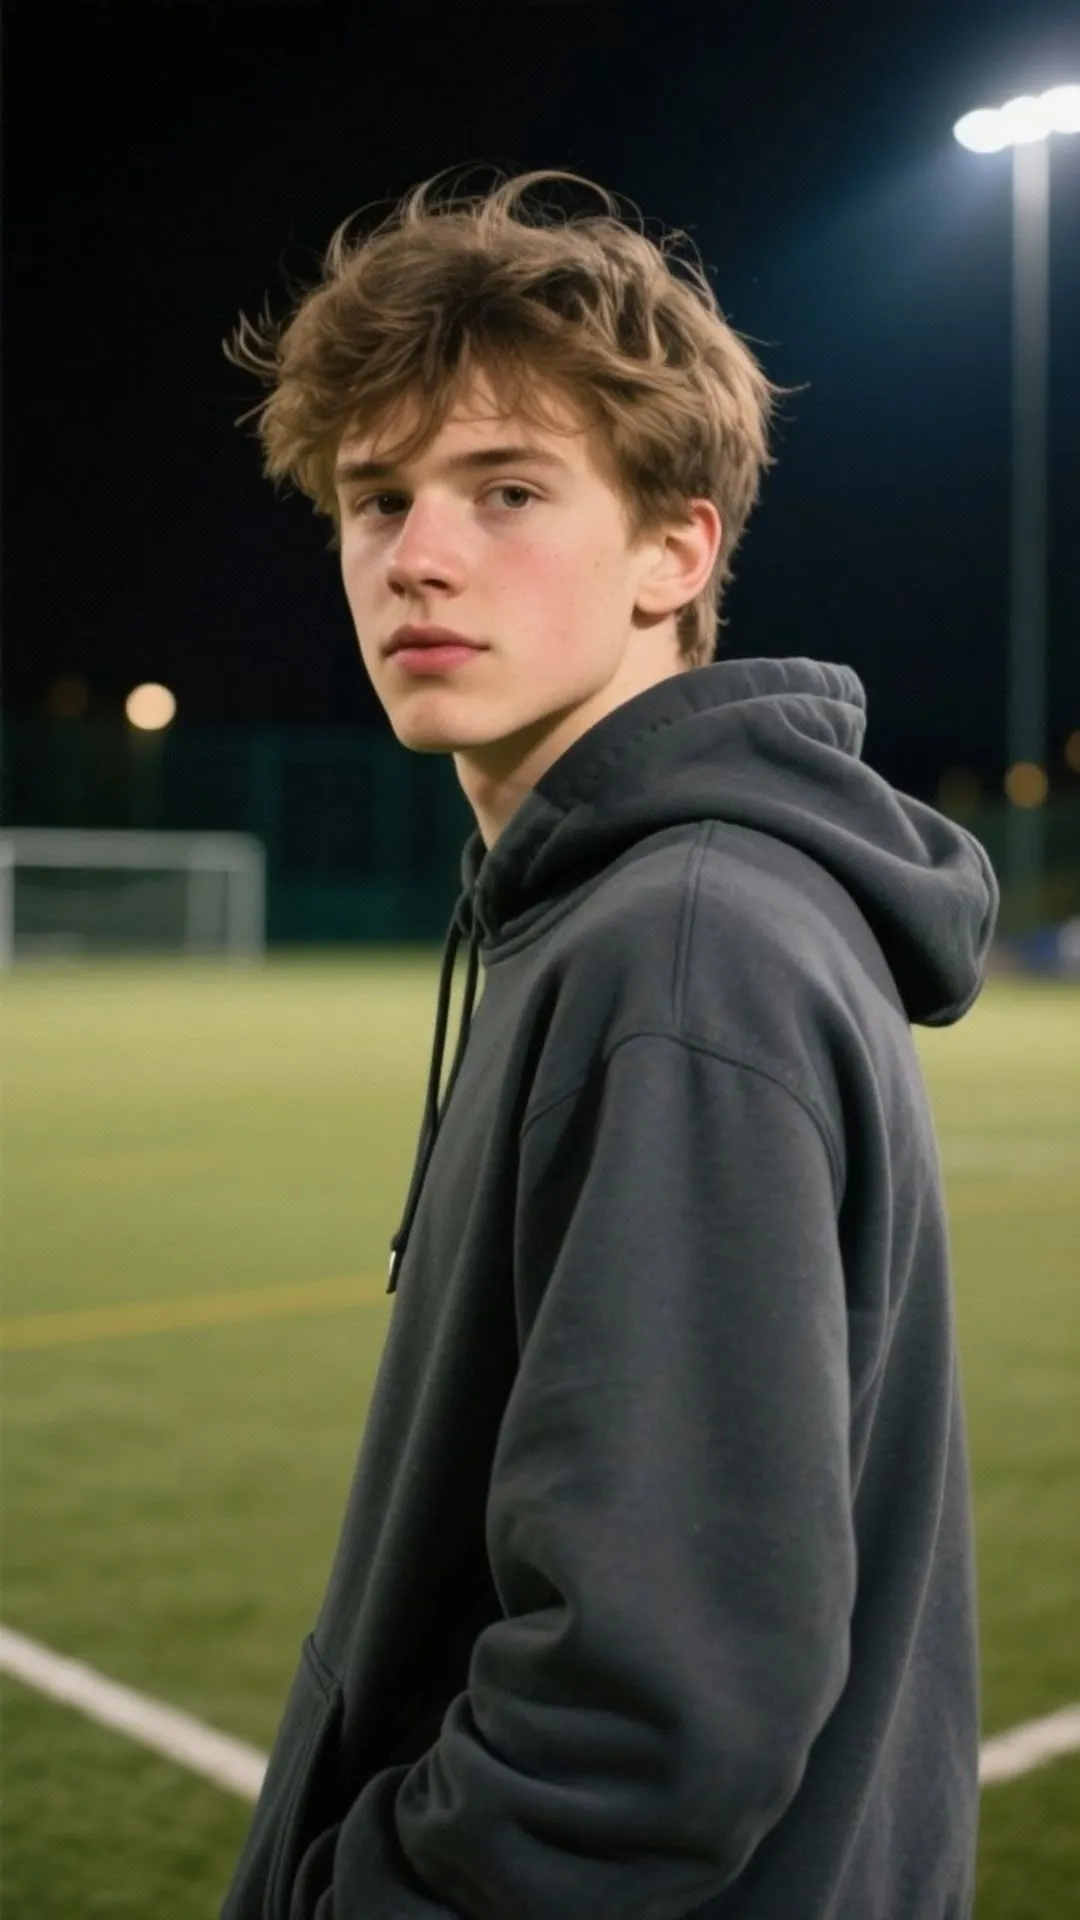 |
 |
 |
 |
 |
ref-1.png |
ref-2.png |
ref-3.png |
ref-4.png |
ref-5.png |
ref-6.png |
Render it with:
```bash
python src/inference/infer.py \
--config configs/inference/8nfe_tuned_fp8.yaml \
checkpoint=ckpts/stage-dmd-step-250 \
render.prompt_file=prompts/reference/example_ref2va.pt \
render.out=results/example_ref2va.mp4
```
and you should get something like this:
For your own references, encode the prompt together with the images, in the order the prompt numbers them:
```bash
python src/inference/encode_keyframes.py --prompt "..." \
--refs ref-1.png ref-2.png ref-3.png --out prompts/reference/mine.pt
```
Each reference is put on a 768-pixel short edge (`--ref_size`). The prompt defines its subjects by picture, in the format of MiniMax-H3's [reference prompt guide](https://huggingface.co/MiniMaxAI/MiniMax-H3/blob/main/docs/VIDEO_PROMPT_WRITING_GUIDE_ref_en.md).
#### Choosing an inference configuration
We support both single-GPU and multi-GPU inference for the released model. Single-GPU scripts auto-detect the best kernels for your GPU. Multi-GPU scripts vary for different hardware (H200, B200) to achieve the best performance.
```bash
bash scripts/inference/8nfe_tuned_fp8.sh # one GPU
bash scripts/inference/8nfe_tuned_fp8_ulysses_h200.sh # eight H200s, one node
bash scripts/inference/8nfe_tuned_fp8_ulysses_b200.sh # eight B200s, one node
```
## Results
Our fastest reported result uses SGLang Diffusion on 8×B200 GPUs: 6.9 seconds for denoising and about 9.0 seconds end-to-end for a 768p, 14.4-second video. The tables below compare its steady-state denoising speed with our reference inference pipeline on H200s and B200s:
**H200:**
| Configuration | GPUs | Seconds/NFE | 50 NFE (VDN-H3-50-step) | 8 NFE (VDN-H3-8-step) |
|---|---:|---:|---:|---:|
| dense MiniMax H3 | 1 | 32.7 | 27.3 min | 4.4 min |
| VDN-H3 FP8 | 1 | 11.2 | 9.4 min | 90.5 s |
| VDN-H3 FP8 Distributed | 8 | 2.29 | 1.9 min | 18.3 s |
**B200:**
| Configuration | GPUs | Seconds/NFE | 50 NFE (VDN-H3-50-step) | 8 NFE (VDN-H3-8-step) |
|---|---:|---:|---:|---:|
| dense MiniMax H3 (cuDNN) | 1 | 16.74 | 13.95 min | 2.23 min |
| VDN-H3 FP8 | 1 | 6.41 | 5.3 min | 51 s |
| VDN-H3 FP8 Distributed | 8 | 1.40 | 1.2 min | 11.23 s |
| SGLang Diffusion, VDN-H3 FP8 Distributed | 8 | **0.88** | **44.0 s** | **6.9 s** |
We exclude model loading, warm-up, VAE decoding, and MP4 encoding. For a live setup, we recommend running the text prompt rewriter, VAE decoding, and MP4 conversion on separate machines, so the eight GPUs only denoise.
## Training Recipe
VDN-H3 is trained in three stages based on the frozen dense model, each starting from the previous stage's final checkpoint. We additionally include a DMD training stage to align with the community [few-step distillation LoRA](https://huggingface.co/larryvrh/MiniMax-H3-Turbo-Lora). The training scripts are located in `src/training/` and `scripts/training/`, and all training configurations can be found under `configs/training/`.
| Stage | What it trains | Steps |
|---|---|---:|
| A1 | the new linear-attention branch, aligned per layer to the dense model | 200 |
| A2 | the same parameters, end-to-end | 500 |
| B | a LoRA on the QKV and O projections plus the linear branch | 2000 |
| DMD | the 8-step `turbo` LoRA, by DMD2 (no GAN) | 250 |
To reproduce the training process, run:
```bash
bash scripts/training/stage_a1.sh data.index_file=/path/to/video_index.jsonl
bash scripts/training/stage_a2.sh data.index_file=/path/to/video_index.jsonl
bash scripts/training/stage_b.sh data.index_file=/path/to/video_index.jsonl
bash scripts/training/stage_dmd_vdn.sh data.index_file=/path/to/video_index.jsonl
```
### Data Preprocess
The trainers read pre-encoded video latents, audio latents, and text latents, following the H3 standard pipeline. Captions should be written in the same format inference expects.
The preprocessed data should be placed as follows, with a `video_index.jsonl` carrying the metadata:
```
/
├── video_index.jsonl one JSON row per clip, carrying its "latent_path"
├── video/
│ ├── 00000.pt (24, 102, 48, 84) bf16 — video VAE, normalized space
│ └── ...
├── audio/
│ ├── 00000.pt (2, 32, 575) bf16 — audio VAE, stereo, 40 latents/s
│ └── ...
└── text/
├── 00000.pt {"prompt_embeds": (L, 5120) bf16,
│ "text_token_tags": (L,) int64}
└── ...
```
`data.index_file` names the jsonl. Only `latent_path` is read from a row; the audio and text sidecars are found by path arithmetic — same file name, sibling directory — so `latent_path` must end in `video/.pt`. The reader is `src/training/dataset_h3_latents.py`.
### Stage-DMD
Stage-DMD is data-free, only requiring the text rows. Its `turbo` LoRA adapter is initialized from [larryvrh/MiniMax-H3-Turbo-Lora](https://huggingface.co/larryvrh/MiniMax-H3-Turbo-Lora), which the config expects in `ckpts/external/`:
```bash
hf download larryvrh/MiniMax-H3-Turbo-Lora \
minimax_h3_turbo_v4_step600_ema.safetensors --local-dir ckpts/external
```
## Acknowledgement
VDN-H3 is built on [MiniMax H3](https://huggingface.co/MiniMaxAI/MiniMax-H3) and starts from its released transformer weights. We also thank [Diffusers](https://github.com/huggingface/diffusers), [FlashAttention](https://github.com/Dao-AILab/flash-attention), and [Triton](https://github.com/triton-lang/triton), on which the optimized inference path is built. We thank [Kernel Design Agents (KDA)](https://github.com/mit-han-lab/kernel-design-agents) for kernel design support. We also thank [Flash Linear Attention (FLA)](https://github.com/fla-org/flash-linear-attention) and [FlexAttention](https://pytorch.org/docs/stable/nn.attention.flex_attention.html) for their open-source attention implementations.
## BibTeX
```bibtex
@misc{xi2026videodeltanet,
title = {VideoDeltaNet on MiniMax H3},
author = {Haocheng Xi and Yiming Xie and Hexu Zhao and Yiwen Zhang and Michael Liu and Thomas Creavin and Kurt Keutzer and Xiuyu Li and Zhaoyang Lv and Chenfeng Xu and Haiwen Feng},
year = {2026},
url = {https://openvdn.github.io/}
}
```
---
*VDN-Minimax-H3 · Independent architecture study · 2026*
## License
This repository contains the VDN-H3 training and inference code, which is licensed under the [Apache License, Version 2.0](LICENSE). Copyright 2026 the VDN authors.
**The model weights are not in this repository and are not covered by that license.** VDN-H3 is a derivative of MiniMax H3, and its weights are distributed separately at [huggingface.co/OpenVDN/vdn-minimax-h3](https://huggingface.co/OpenVDN/vdn-minimax-h3) under the [MiniMax H3 Community License Agreement](licenses/MiniMax-H3-Community-License-Agreement.txt).