Hepato-LLaVA: An Expert MLLM with Sparse Topo-Pack Attention for Hepatocellular Pathology Analysis on Whole Slide Images

---
## 🔥 News
- [2026/07/01] The model checkpoints are publicly available! 🚀
- [2026/06/20] The code are publicly available! 🚀
- [2026/06/13] Hepto-LLaVA has been accepted at MICCAI 2026 as a poster! 🎉
- [2026/03/01] Hepto-LLaVA is now live on arXiv! 🔥
## 👀 Introduction
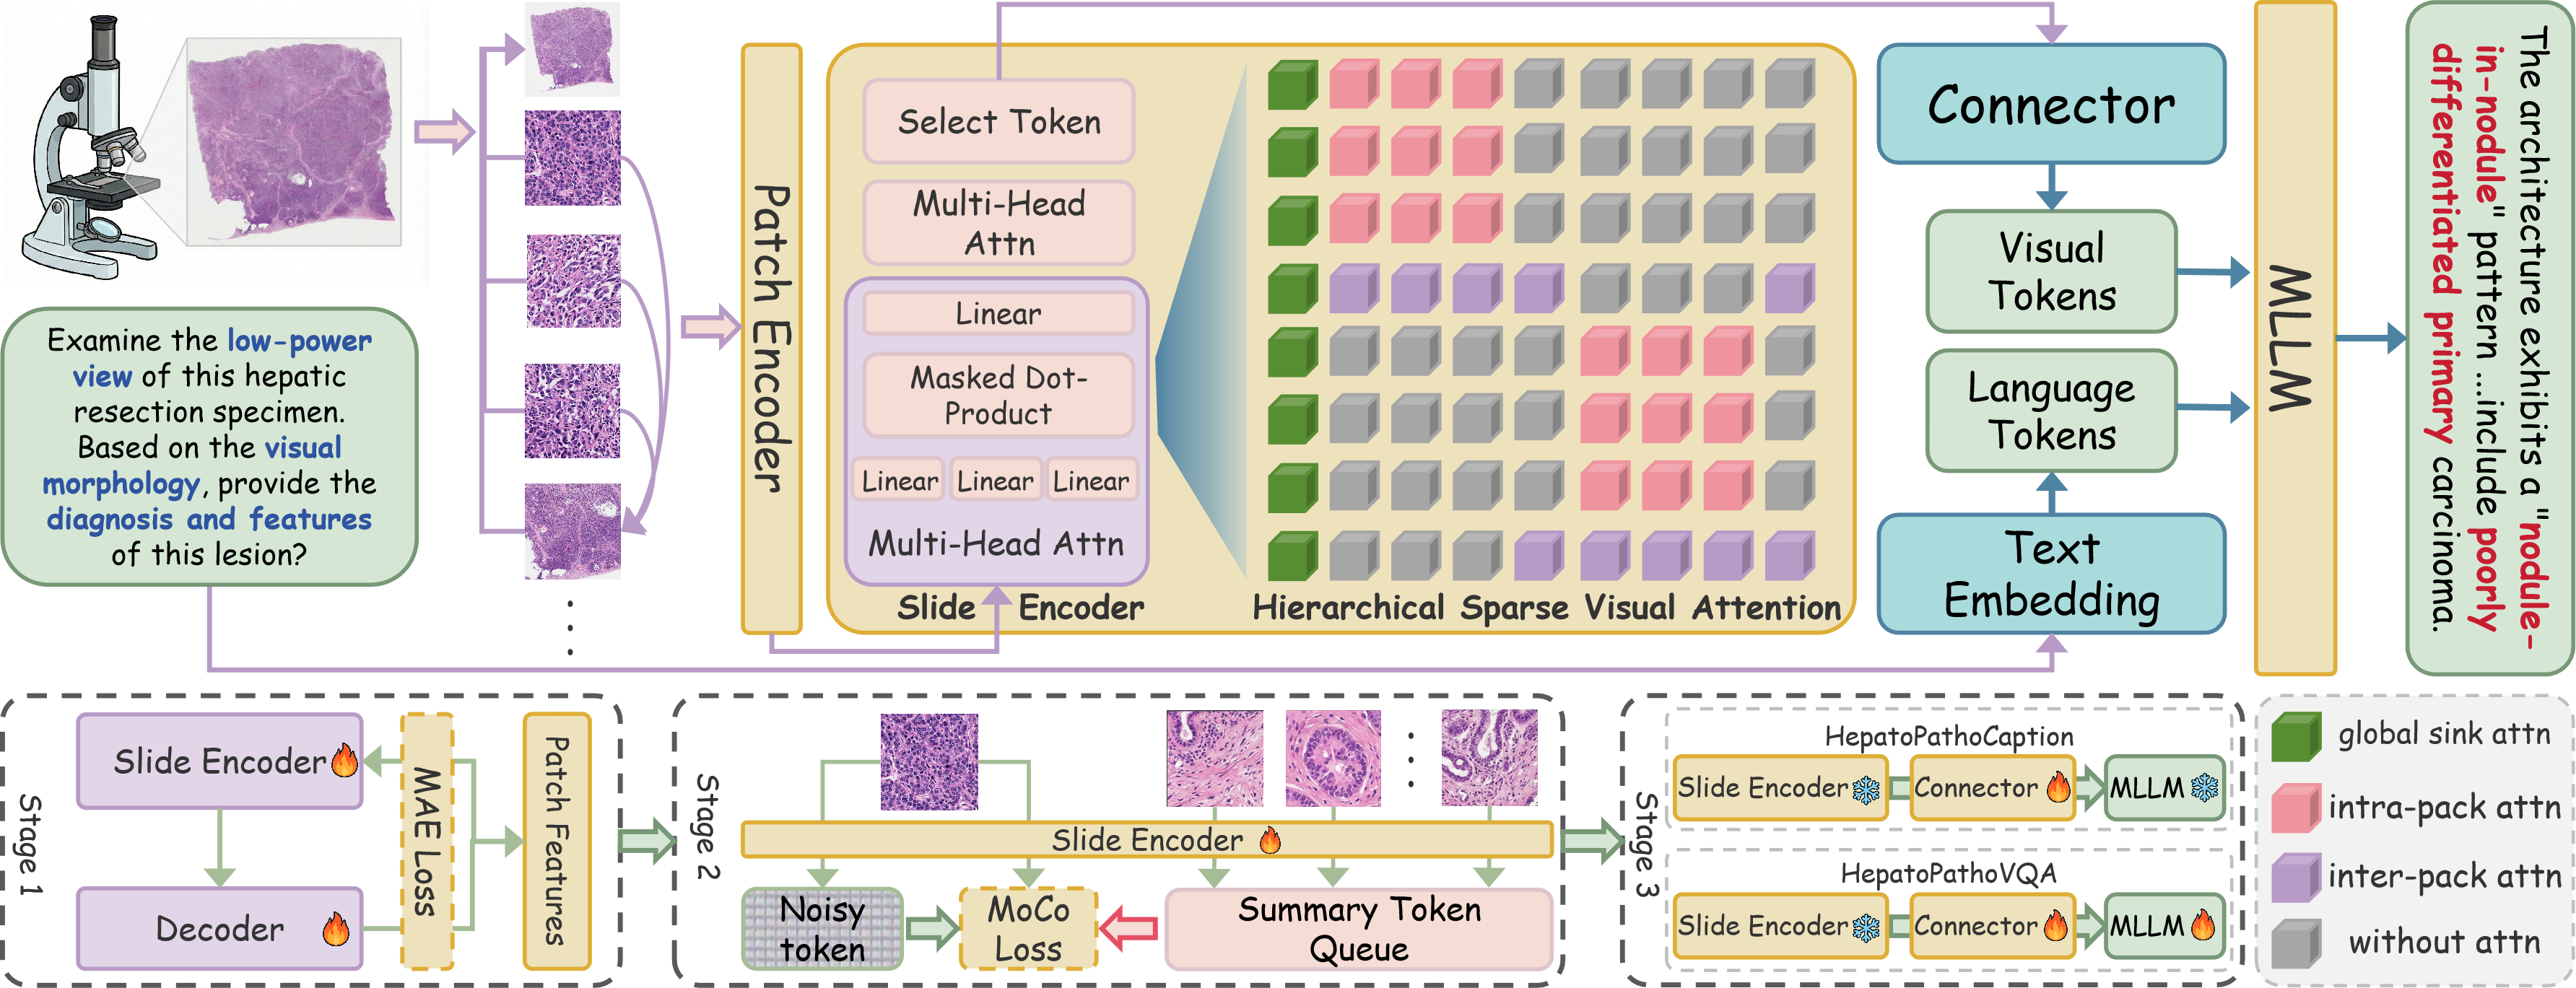
Hepatocellular Carcinoma (HCC) relies on histopathological **Whole Slide Images (WSIs)** examination as the gold standard. However, manual analysis of these gigapixel, highly heterogeneous WSIs is labor-intensive and prone to inter-observer variability. This has catalyzed WSI-based **Multi-modal Large Language Models (MLLMs)** to enable VQA.
A key challenge in pathology MLLMs is gigapixel WSI representation. Existing methods either use **thumbnail-based approaches** that lose critical high-resolution diagnostic details, or employ **slide-encoder approaches** that generate excessively redundant tokens.
We propose **Hepato-LLaVA**, a specialized MLLM for fine-grained hepatocellular pathology analysis. It features a novel **Hierarchical Sparse Visual Attention (HSVA)** mechanism that models 2D tissue topology to aggregate diagnostic evidence while preserving context. To address multiscale data scarcity, we also present **HepatoPathoVQA**, comprising **33K hierarchically structured QA pairs** validated by pathologists. **Hepato-LLaVA** achieves state-of-the-art diagnostic accuracy, outperforming existing pathology MLLMs by an absolute **20%**.
---
## 🛠️ Installation
```bash
git clone https://github.com/wssf3092/Hepato-LLaVA.git
cd Hepato-LLaVA
conda create -n hepato_llava python=3.10 -y
conda activate hepato_llava
pip install --upgrade pip
pip install -r requirements.txt
```
For the patch encoder, please follow the official installation instructions of [CONCH](https://github.com/mahmoodlab/CONCH) to set up the model and obtain the pretrained weights.
---
## 📦 Data Preparation
### Feature Extraction
Use the CONCH encoder to extract patch-level features from WSIs:
```bash
bash data/feature/1_run.sh
```
For data augmentation (generating 9 variants per WSI):
```bash
bash data/feature/1_run_augment.sh
```
### Data Format Conversion
Convert VQA data to LLaVA fine-tuning format:
- `data/conversation/qa.py` — convert QA JSONL to LLaVA fine-tuning format
- `data/conversation/caption.py` — convert captioning data to fine-tuning format
---
## 🚀 Training
Hepato-LLaVA follows a three-stage training pipeline:
**Stage 1: MAE Pre-training** — Self-supervised pre-training of the HSAN slide encoder with curriculum masking (patch-level → pack-level):
```bash
bash scripts/run_mae.sh
```
**Stage 2: MoCo Pre-training** — Contrastive learning for summary token representations:
```bash
bash scripts/run_moco_summary.sh
```
**Stage 3: LLaVA Fine-tuning** — End-to-end fine-tuning with DeepSpeed and LoRA:
```bash
bash scripts/run_llava_finetune.sh
```
---
## 🔍 Inference & Evaluation
Run VQA evaluation:
```bash
bash scripts/run_eval_vqa.sh
```
For GPT-4 based open-ended evaluation:
```bash
python scripts/eval_open.py
```
For choice question statistics:
```bash
python scripts/stat_choice.py
```
---
## ⚙️ Hyperparameter Settings
### LoRA
| Parameter | Value |
|-----------|-------|
| LORA_R | 128 |
| LORA_ALPHA | 256 |
### Training
| Parameter | Value |
|-----------|-------|
| NUM_EPOCHS | 3 |
| BATCH_SIZE | 8 |
| GRADIENT_ACCUMULATION | 4 |
| LEARNING_RATE | 2e-5 |
| MM_PROJECTOR_LR | 2e-5 |
| WARMUP_RATIO | 0.03 |
| MODEL_MAX_LENGTH | 8192 |
### Generation
| Parameter | Value |
|-----------|-------|
| TEMPERATURE | 0.0 |
| TOP_P | 0.9 |
| NUM_BEAMS | 1 |
| MAX_NEW_TOKENS | 2048 |
---
## 📚 Citation
```bibtex
@article{hepatollava2026,
title={Hepato-LLaVA: An Expert MLLM with Sparse Topo-Pack Attention for Hepatocellular Pathology Analysis on Whole Slide Images},
author={Yang, Yuxuan and Yan, Zhonghao and Zhang, Yi and Yun, Bo and Diao, Muxi and Zhao, Guowei and Liang, Kongming and Li, Wenbin and Ma, Zhanyu},
year={2026}
}
```
---
## 🙏 Acknowledgements
This code is built on [CONCH](https://github.com/mahmoodlab/CONCH) and [WSI-LLaVA](https://github.com/XinhengLyu/WSI-LLaVA). We thank the authors for sharing their codes.