Note: The following experimental results are all obtained from ___An Empirical Study of Instruction-tuning Large Language Models in Chinese___.
### 1. Benchmarks
This paper selects two evaluation benchmarks, Belle-eval and MMCU, to comprehensively evaluate LLM competencies in Chinese.
Belle-eval is constructed by self-instruct with ChatGPT, which has 1,000 diverse instructions that involve 10 categories covering common NLP tasks (e.g., QA) and challenging tasks (e.g., code and math). We use ChatGPT to rate the model responses based on the golden answers. This benchmark is considered to be as the assessment of AGI (instruction-following) capability.
MMCU is a collection of Chinese multiple choice questions in four professional disciplines of medicine, law, psychology and education (e.g., Gaokao examination). It allows LLMs to take exams in human society in a multiple-choice test manner, making it suitable for evaluating the breadth and depth of knowledge of LLMs across multiple disciplines.
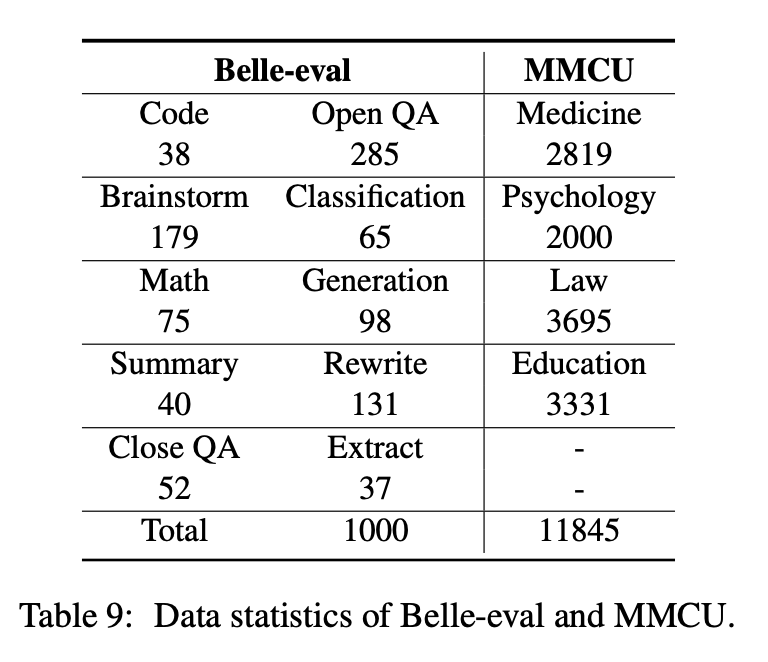
Data statistics of Belle-eval and MMCU are shown in the table above.
### 2. Main Factors
We conduct experiments to study the three main factors in instruction-tuning LLMs: LLM bases, Parameter-efficient Methods, Chinese Instruction Datasets.
#### 2.1 LLM Bases
For open LLMs, we test existing LLMs and LLMs fine-tuned with LoRA on Alpaca-GPT4 on Belle-eval and MMCU, respectively.
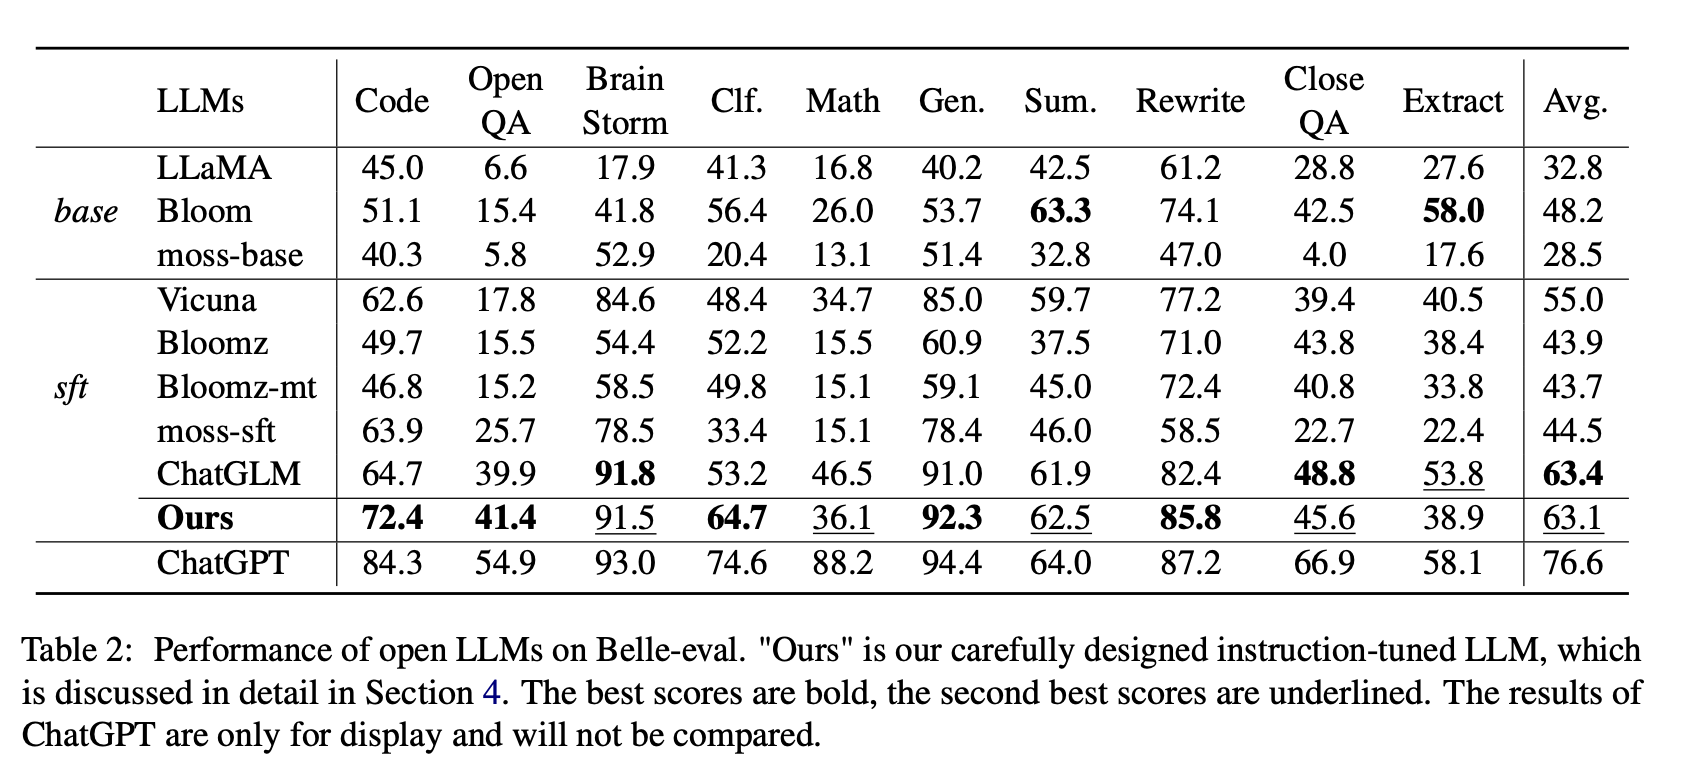
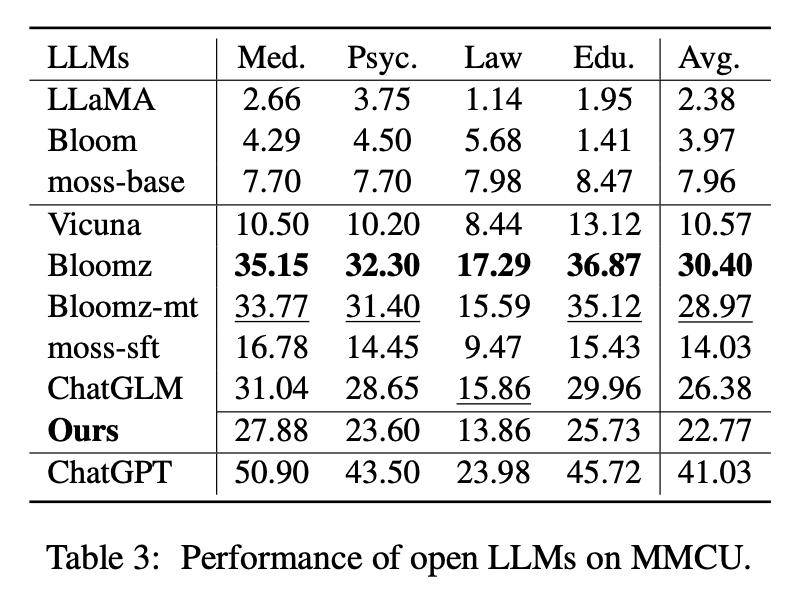
Table 2 shows the scores of open LLMs on Belle-eval. Table 3 shows the accuracy of LLMs on MMCU. They fine-tune all the open LLMs with the same parameter-efficient method LoRA and the same instruction dataset Alpaca-GPT4.
___Experimental Results:___
1. Evaluation of Existing LLMs
___Performance on Belle-eval___
(1) For base LLMs, Bloom performs the best.
(2) For sft LLMs, ChatGLM outperforms others by large margins, thanks to the fact that it is trained with the most Chinese tokens and HFRL.
(3) The Open QA, Math, CloseQA and Extract categories are still very challenging for existing open LLMs.
(4) Vicuna and moss-sft have clear improvements compared to their bases, LLaMA and moss-base, respectively.
(5) In contrast, the performance of sft models, Bloomz and Bloomz-mt, is reduced compared to the base model Bloom, because they tend to generate a shorter response.
___Performance on MMCU___
(1) All base LLMs perform poorly because it is almost difficult to generate content in the specified format before fine-tuning, e.g., outputting option numbers.
(2) All sft LLMs outperform their corresponding base LLMs, respectively. In particular, Bloomz performs the best (even beats ChatGLM) because it can generate option number directly as required without generating other irrelevant content, which is also due to the data characteristics of its supervised fine-tuning dataset xP3.
(3) Among the four disciplines, law is the most challenging for LLMs.
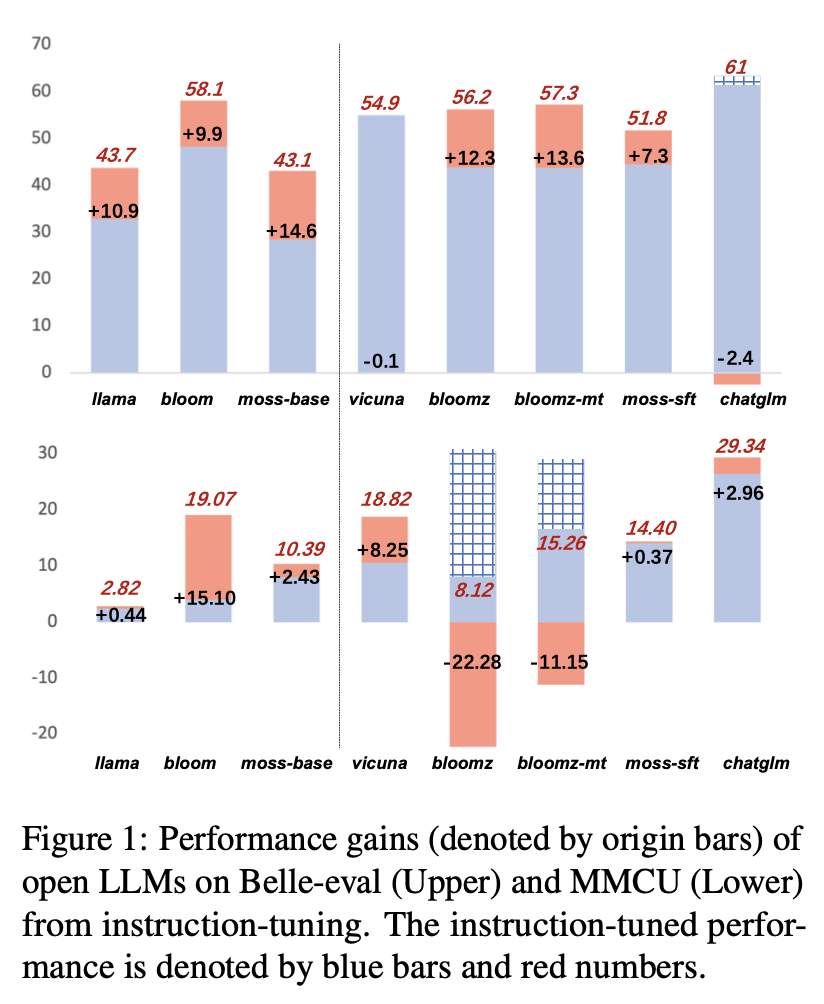
The performance results of LLMs after instruction-tuning on Alpaca-GPT4-zh are shown in Figure 1.
2. Instruction-tuning Different LLMs
(1) On Belle-eval, the performance improvement of sft LLMs brought by instruction-tuning is not as significant as that of base LLMs, except for sft Bloomz and Bloomz-mt.
(2) Vicuna and ChatGLM encounter performance drops after instruction-tuning, because Vicuna is trained from real human-ChatGPT conversations, with better quality than Alpaca-GPT4. ChatGLM adopts HFRL, which may be no longer suitable for further instruction-tuning.
(3) On MMCU, most LLMs achieve performance boosts after instruction-tuning, with the exception of Bloomz and Bloomz-mt, which have unexpectedly significantly decreased performance.
(4) After instruction-tuning, Bloom has significant improvements and performs well on both benchmarks. Although ChatGLM beats Bloom consistently, it suffers performance drop during instruction-tuning. Therefore, among all open LLMs, Bloom is most suitable as a foundation model in the subsequent experiments for Chinese instruction-tuning exploration.
#### 2.2 Parameter-efficient Methods
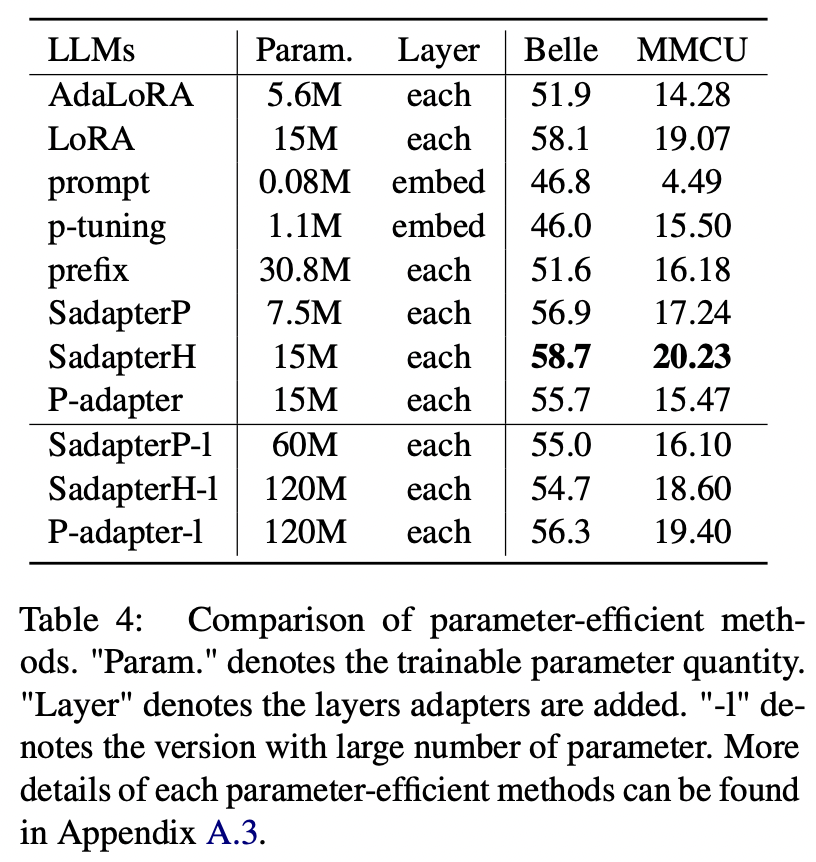
For parameter-efficient methods other than LoRA, the paper collects a range of parameter-efficient methods to instruction-tune Bloom on the Alpaca-GPT4 dataset.
___Experimental Results:___
1. Comparison of Parameter-efficient Methods
(1) SadapterH performs the best among all parameter-efficient methods, which can be used as an alternative to LoRA.
(2) P-tuning and prompt-tuning underperform others by large margins, indicating that only adding trainable layers in the embedding layer are not enough to support LLMs for generation tasks.
(3) Although AdaLoRA is an improvement of LoRA, its performance has a clear drop, possibly because the LoRA's trainable parameters for LLMs are not suitable for further reduction.
(4) Comparing the upper and lower parts, it can be seen that increasing the number of trainable parameters for sequential adapters (i.e., SadapterP and SadapterH) does not bring gain, while the opposite phenomenon is observed for parallel adapters(i.e., P-adapter)
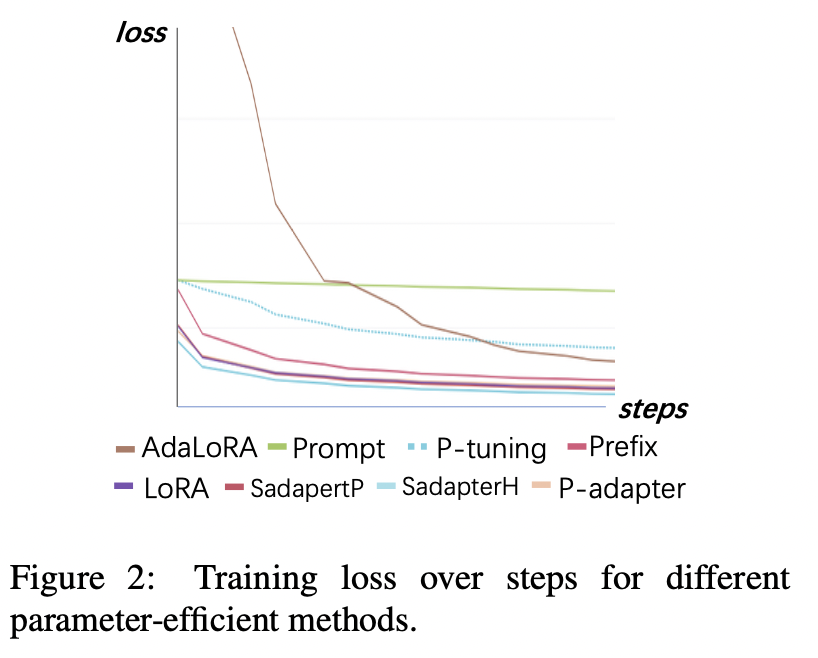
2. Training Loss
(1) Prompt-tuning and P-tuning converge the slowest and has the highest losses after convergence. This shows that embedding-only adapters are not suitable for instruction-tuning LLMs.
(2) The initial loss of AdaLoRA is very high because it requires simultaneous learning of parameter budget allocation, which makes the model unable to fit the training data well.
(3) The other methods can quickly converge on training data and fit it well.
#### 2.3 Chinese instruction Datasets
For the impact of various types of Chinese instruction datasets, authors gather popular open Chinese instructions (as shown in Table 5) to fine-tune Bloom with LoRA.
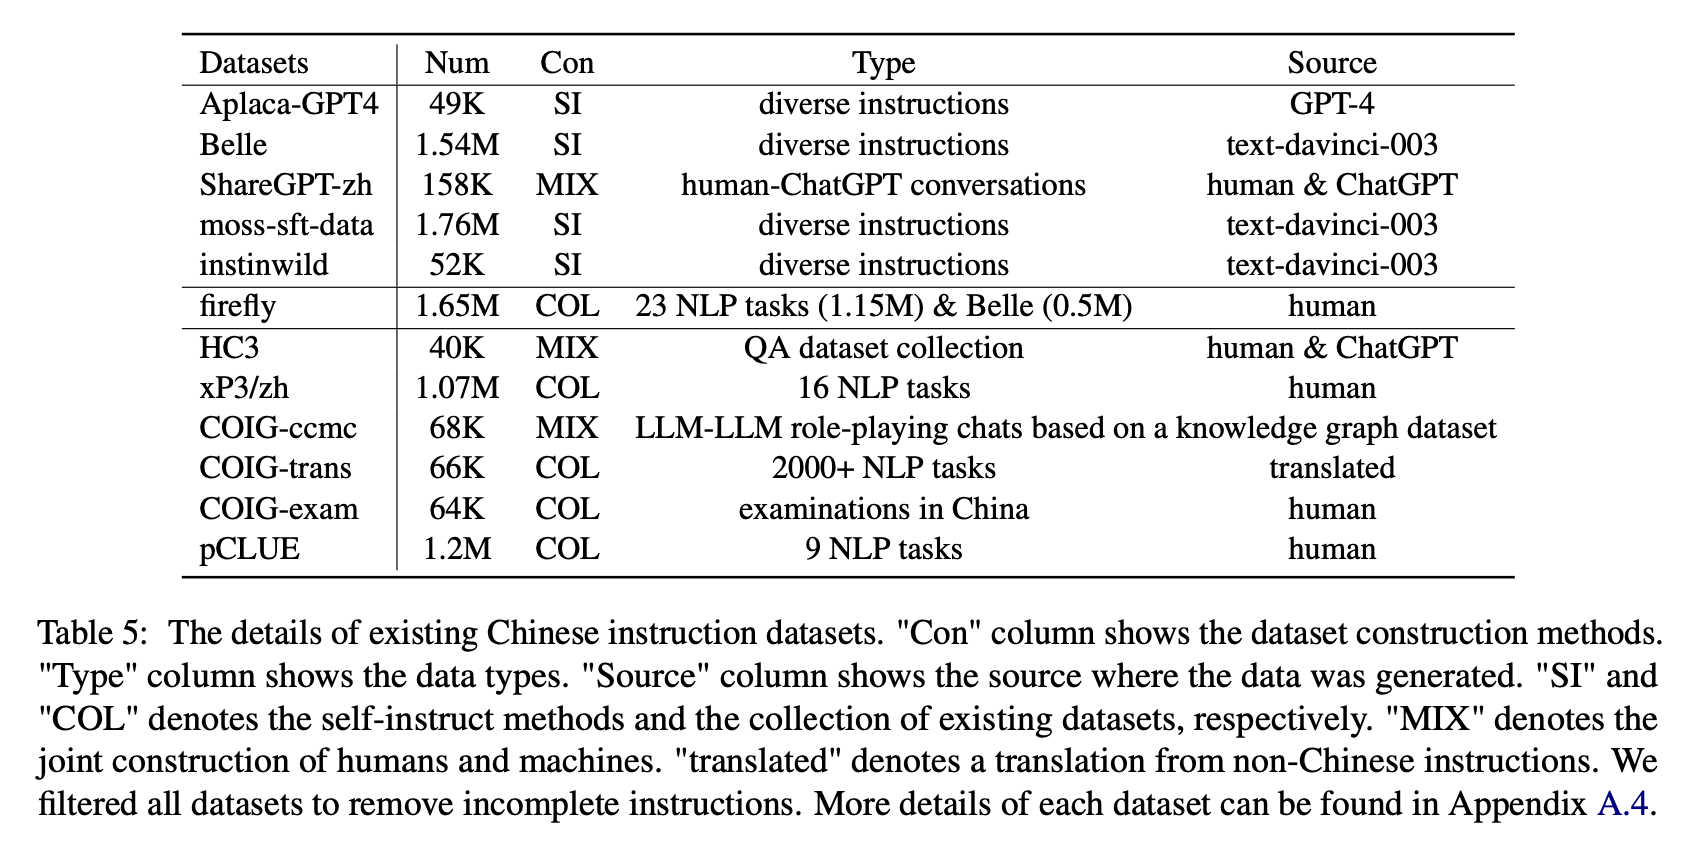
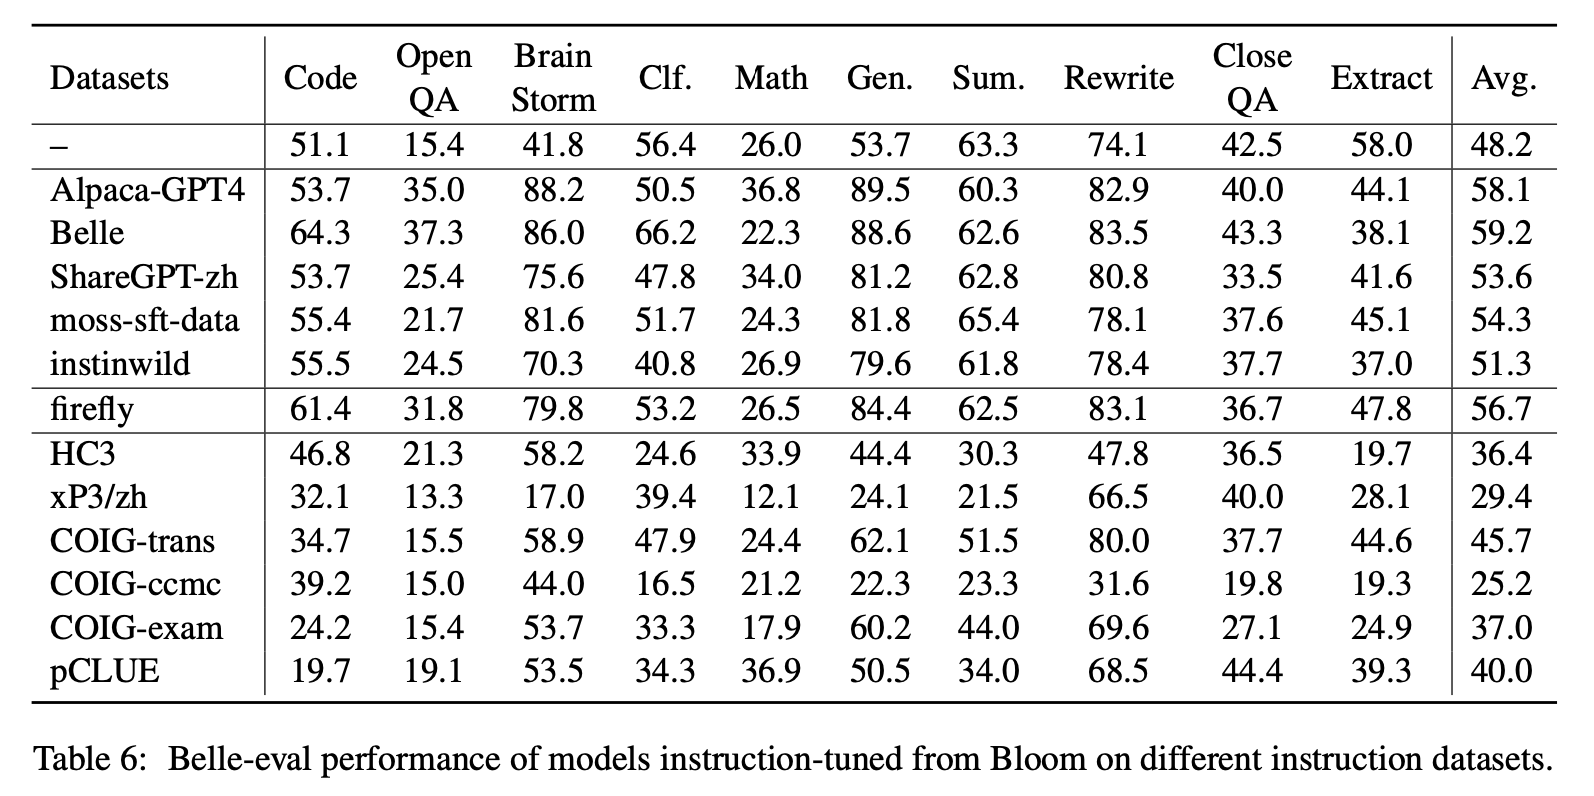
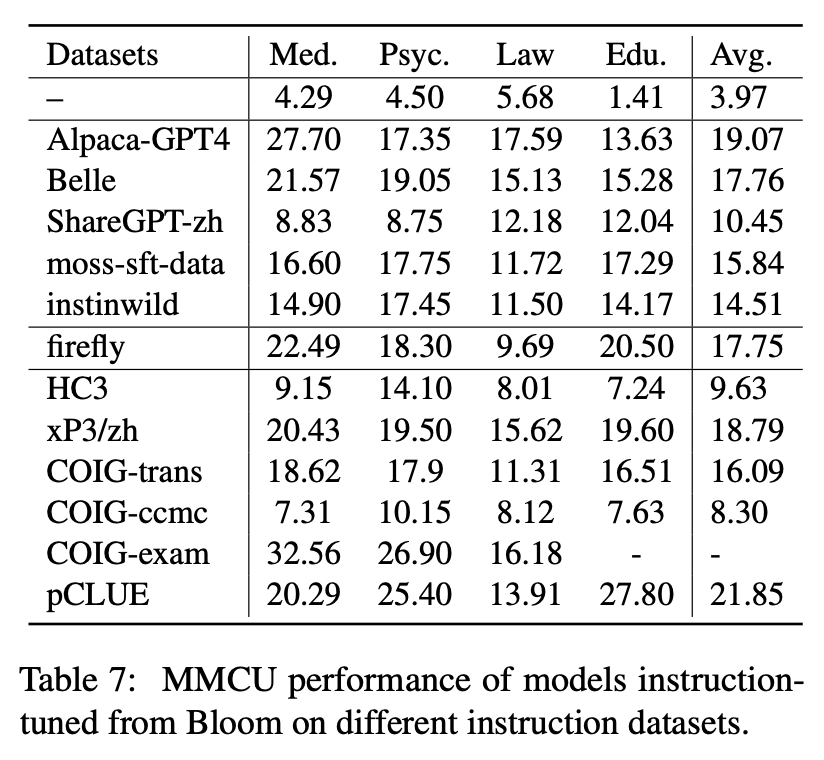
Table 6 and Table 7 show Bloom's fine-tuning on different instruction datasets.
___Experimental Results:___
1. Performance on Belle-eval
(1) the instruction data constructed by ChatGPT (e.g., using self-instruction methods or collecting real human-ChatGPT conversations) consistently enhances the instruction-following ability with 3.1 ∼ 11-point score increases.
(2) Among these datasets, Belle has the best performance due to the largest amount of instruction data. However, the performance of models trained on moss-sft-data, containing more data built in a similar way, is unsatisfactory.
(3) The performance brought by the Alpaca-GPT4 instructions is the second best, with only 49K being comparable to the 1.54M Belle.
(4) Instinwild brings the least performance gains among them because the seed instructions it crawls from Tweet ("in wild") are not as comprehensive as those (like Alpaca) carefully designed by humans.
(5) These ChatGPT-based data mainly have a significant improvement effect on open generation tasks such as Brain Storm and Generation, while there is a significant decrease in tasks that require high reading comprehension skills, such as Close QA and Extract.
(6) These instruction datasets cause damage to the model's instruction-following ability, because the form and intent of each NLP or examination dataset are unitary, which can easily be overfitted.
(7) Among them, COIG-trans performs the best because it involves over 2000 different tasks with a wide variety of task instructions. In contrast, xP3 and COIG-ccmc have the worst negative impact on model performance. Both of them only cover a few types of tasks (translation and QA for the former, counterfactual correction conversations for the latter), which hardly cover the popular instructions and tasks for humans.
2. Performance on MMCU
(1) Instruction-tuning on each dataset can always result in performance improvement.
(2) Among the ChatGPT-based data shown in the upper part, ShareGPT-zh underperforms others by large margins. This may be due to the fact that real users rarely ask multiple choice questions about academic topics.
(3) Among the dataset-collection data shown in the lower part, HC3 and COIG-ccmc results in the lowest accuracy because the unique questions of HC3 are only 13K, and the task format of COIG-ccmc is significantly different from MMCU.
(4) COIG-exam brings the greatest accuracy improvement, benefiting from the similar task format as MMCU.
### 3. Other Factors
Four Other Factors: CoT, Expansion of Chinese Vocabulary, Language of Prompts and Human-value Alignment
#### 3.1 CoT
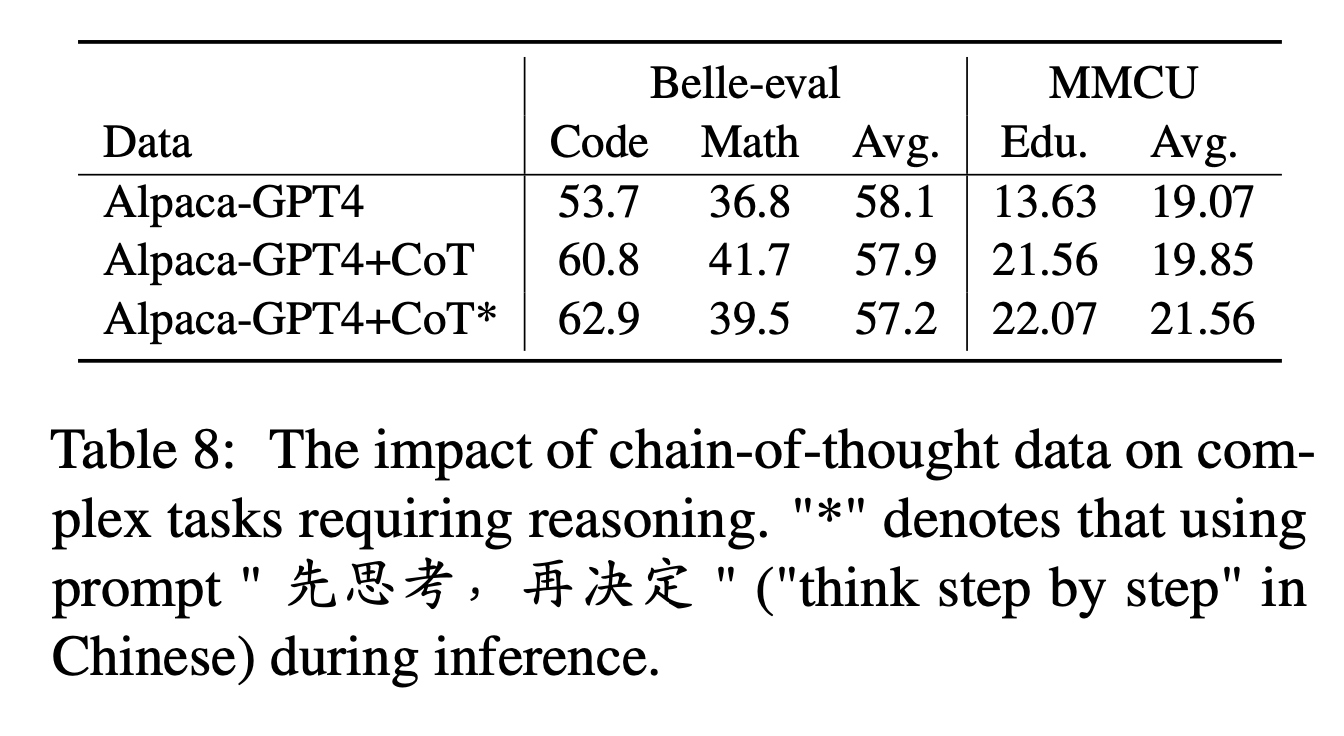
For CoT, authors compare the performance before and after adding CoT data during instruction-tuning.
___Experiment Settings:___
We collect 9 CoT datasets and their prompts from FLAN, and then translate them into Chinese using Google Translate. They compare the performance before and after adding CoT data during instruction-tuning.
First note the way to add CoT data as "Alpaca-GPT4+CoT". In addition, add a sentence "先思考,再决定" ("think step by step" in Chinese) at the end of each instruction, to induce the model to respond to instructions based on the CoT, and label this way as "Alpaca-GPT4+CoT*".
___Experimental Results:___
1. "Alpaca-GPT4+CoT" outperforms "Alpaca-GPT4" in Code and Math tasks that require strong reasoning ability. Besides, there is also a significant improvement in the MMCU Education task.
2. As shown in the line of "Alpaca-GPT4+CoT*", the simple sentence can further improve the performance of reasoning tasks Code and Education, while the Math performance is slightly inferior to "Alpaca-GPT4+CoT". This may require further exploring of more robust prompts.
#### 3.2 Expansion of Chinese Vocabulary
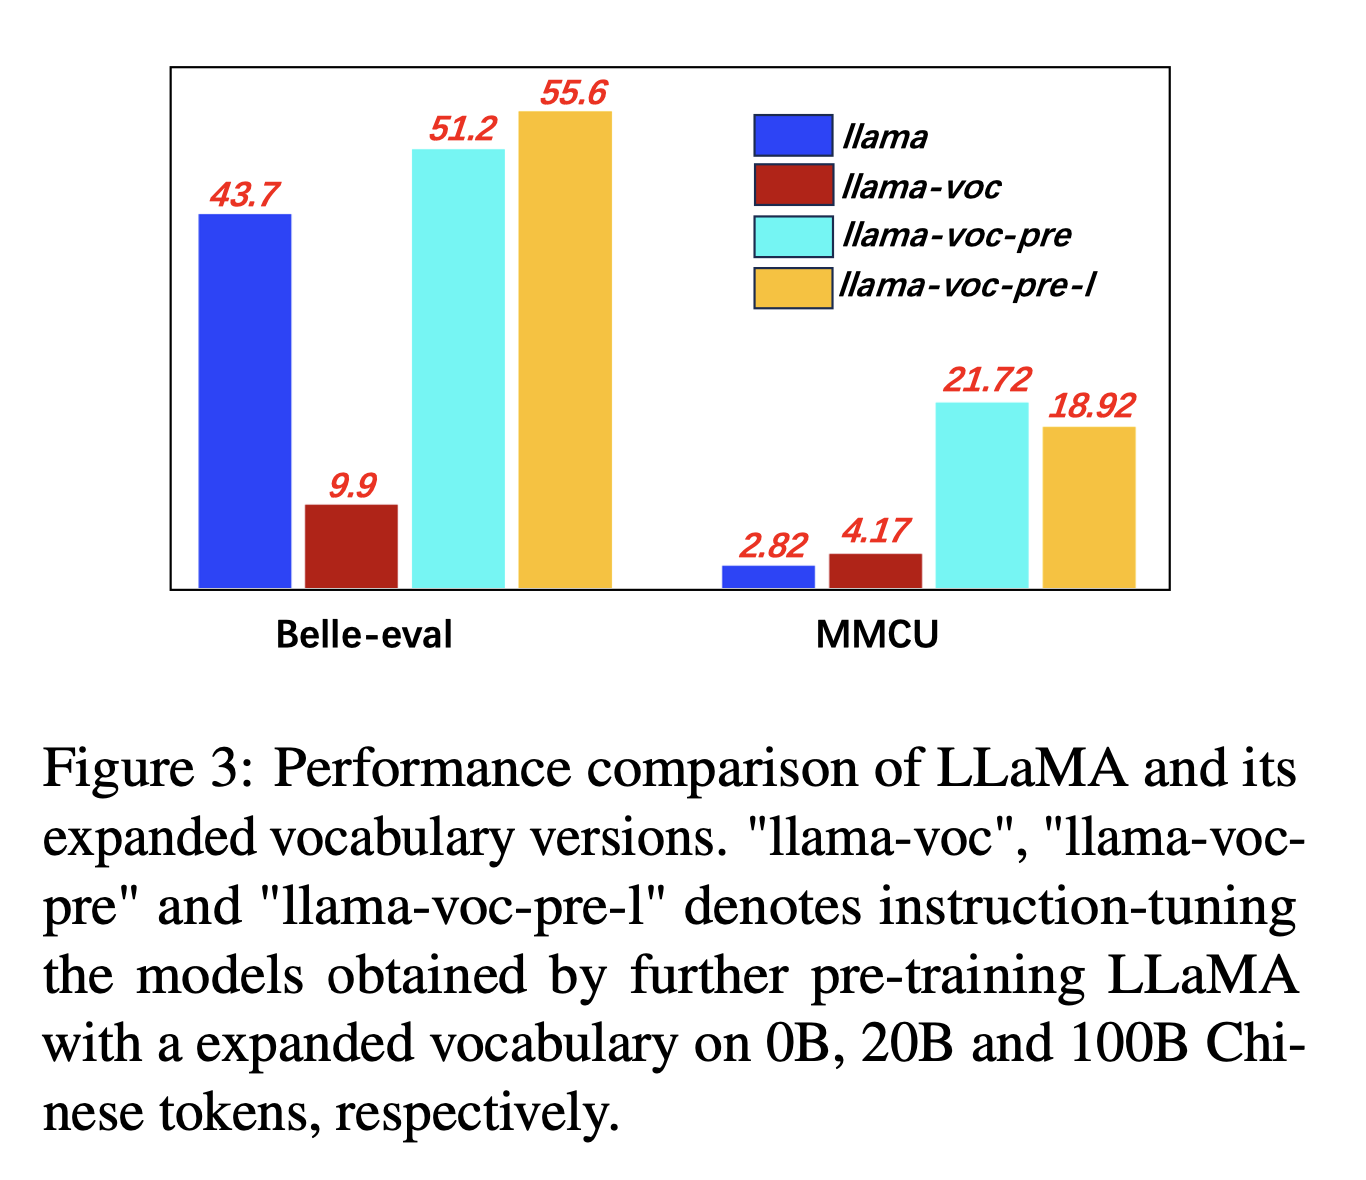
For expansion of Chinese vocabulary, authors test the influence of the number of Chinese tokens in the tokenizer’s vocabulary on LLMs’ ability to express Chinese. For example, if a Chinese character is in the vocabulary, it can be represented by a single token, otherwise it may require multiple tokens to represent it.
___Experiment Settings:___ Authors mainly conduct experiments on LLaMA, which uses SentencePiece(32K vocabulary size of Chinese characters) covering fewer Chinese characters than Bloom(250K).
___Experimental Results:___
1. Pre-training on more Chinese corpus with expansion of Chinese vocabulary is consistently helpful for instruction-following ability.
2. And counterintuitively, "llama-voc-pre-l" (100B) is inferior to "llama-voc-pre" (20B) on MMCU, which shows that pre-training on more data may not necessarily lead to higher performance for academic exams.
#### 3.3 Language of Prompts
For the language of prompts, authors test the suitability of instruction fine-tuning for using Chinese prompts.
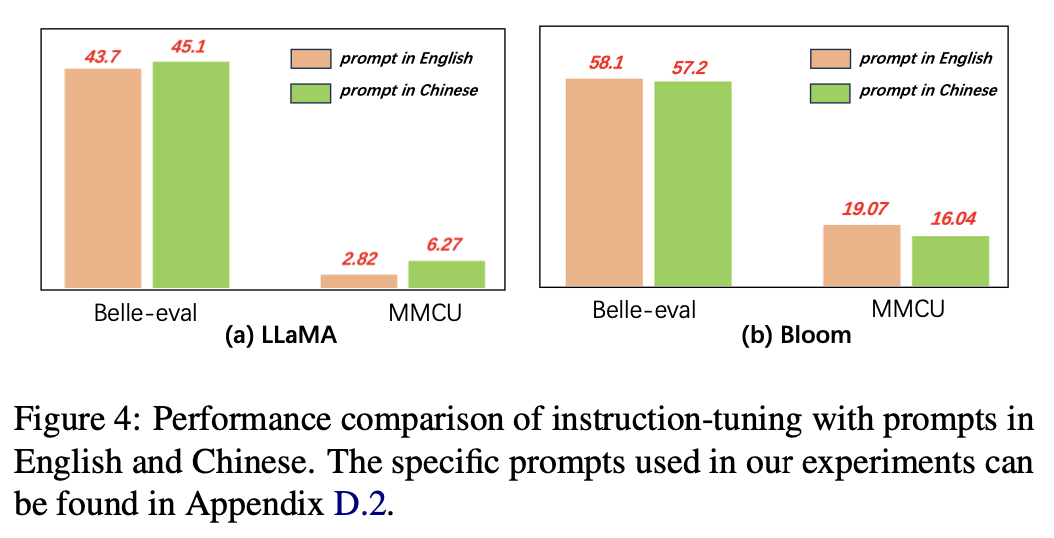
Figure 4 shows the results of using Chinese and English prompts based on LLaMA and Bloom. When instruction-tuning LLaMA, using Chinese prompts can improve the performance on both benchmarks compared to English prompts, while the opposite phenomenon can be observed on Bloom.
___Experimental Results:___
1. For models with weaker Chinese abilities(e.g., LLaMA), using Chinese prompts can effectively help respond in Chinese.
2. For models with good Chinese abilities (e.g., Bloom), using prompts in English (the language they are better at) can better guide the model to understand the process of fine-tuning with instructions.
#### 3.4 Human-value Alignment
To avoid LLMs generating toxic content, aligning them with human values is a crucial issue. We add human-value alignment data built by COIG into instruction-tuning to explore its impact.
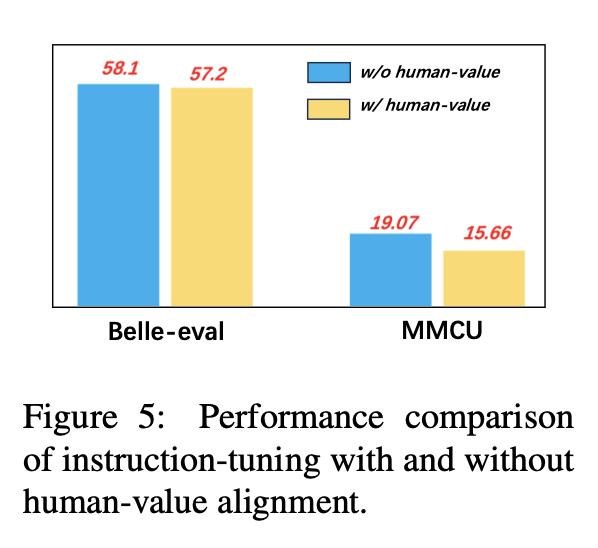
Figure 5 compares the results of instruction-tuning with and without human-value alignment.
___Experimental Results:___ The human-value alignment results in a slight performance drop. How to balance the harmlessness and performance of LLMs is a research direction worth exploring in the future.
Note: The following figure shows the statistics of the dataset collected as of March 26, which is only displayed as a motivation of data collection. More datasets have been collected, such as financial related instruction datasets.
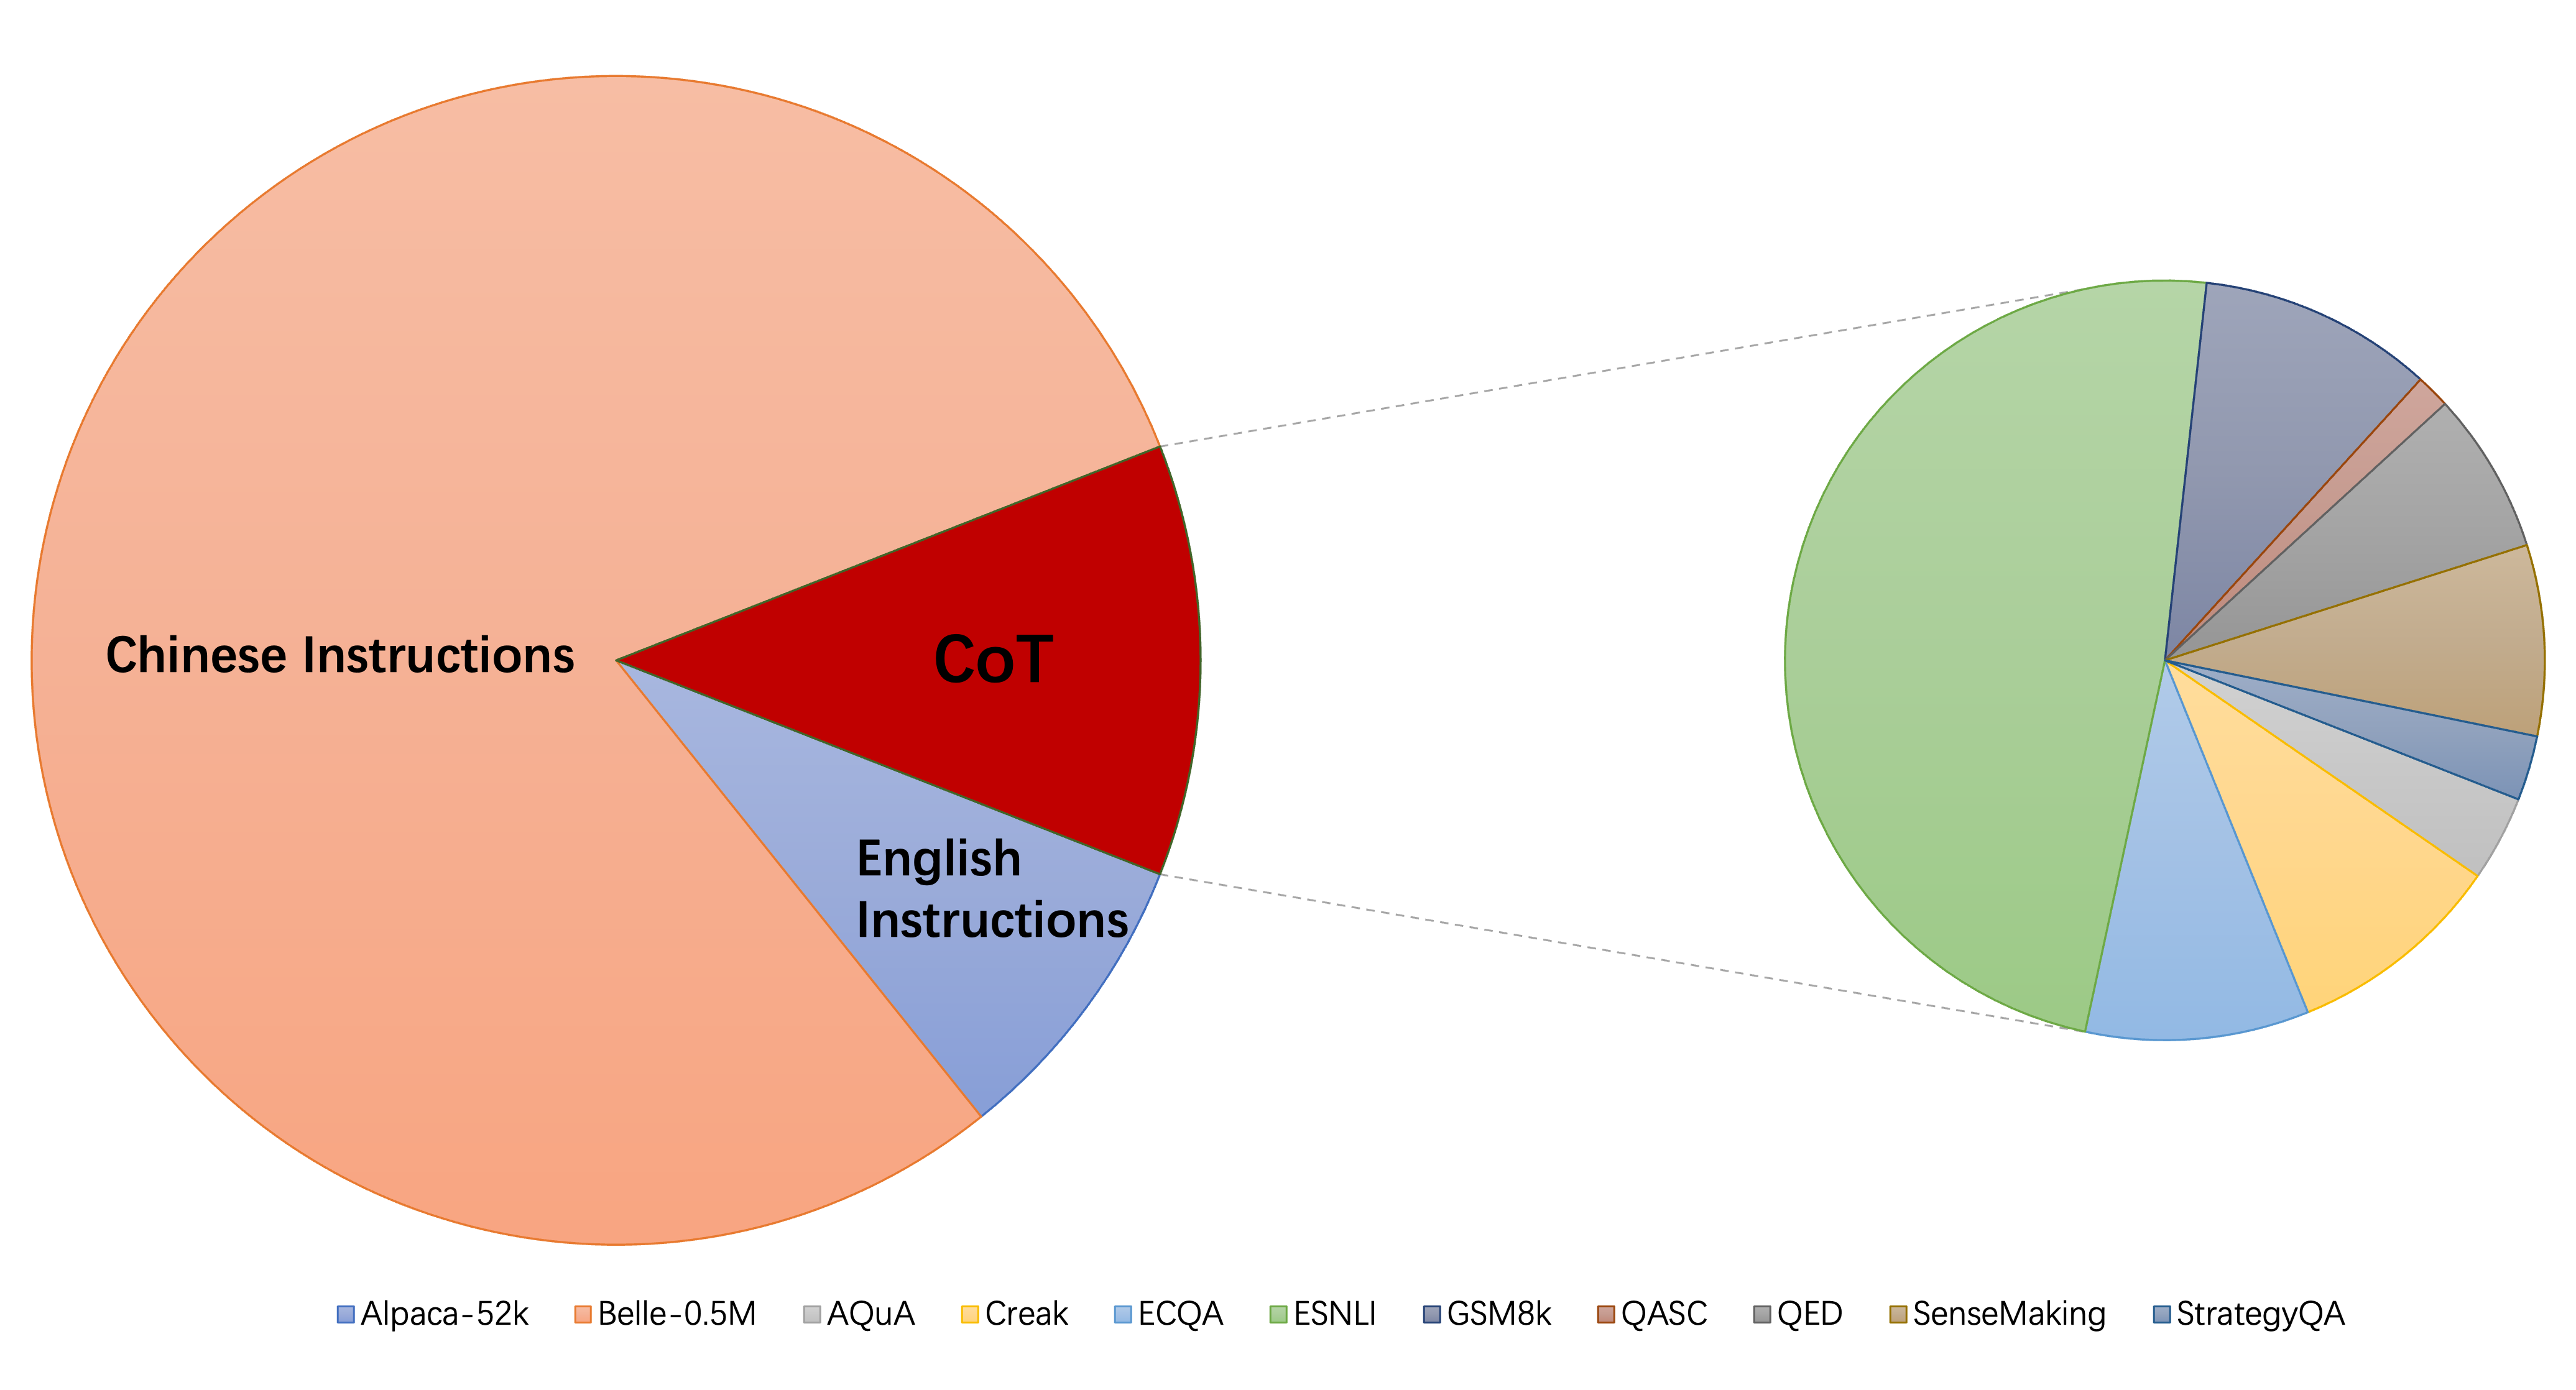
The current collection of instruction-finetuning datasets consists mainly of three parts:
- `alpaca_data_cleaned.json`: about 52K English instruction-following training samples.
- `CoT_data.json`: 9 CoT datasets involving about 75k samples. (published by FLAN[7])
- `belle_data_cn.json`: about 0.5M Chinese |instruction-following training samples. (published by BELLE [8])
### Ablation of CoT and Chinese Instructions
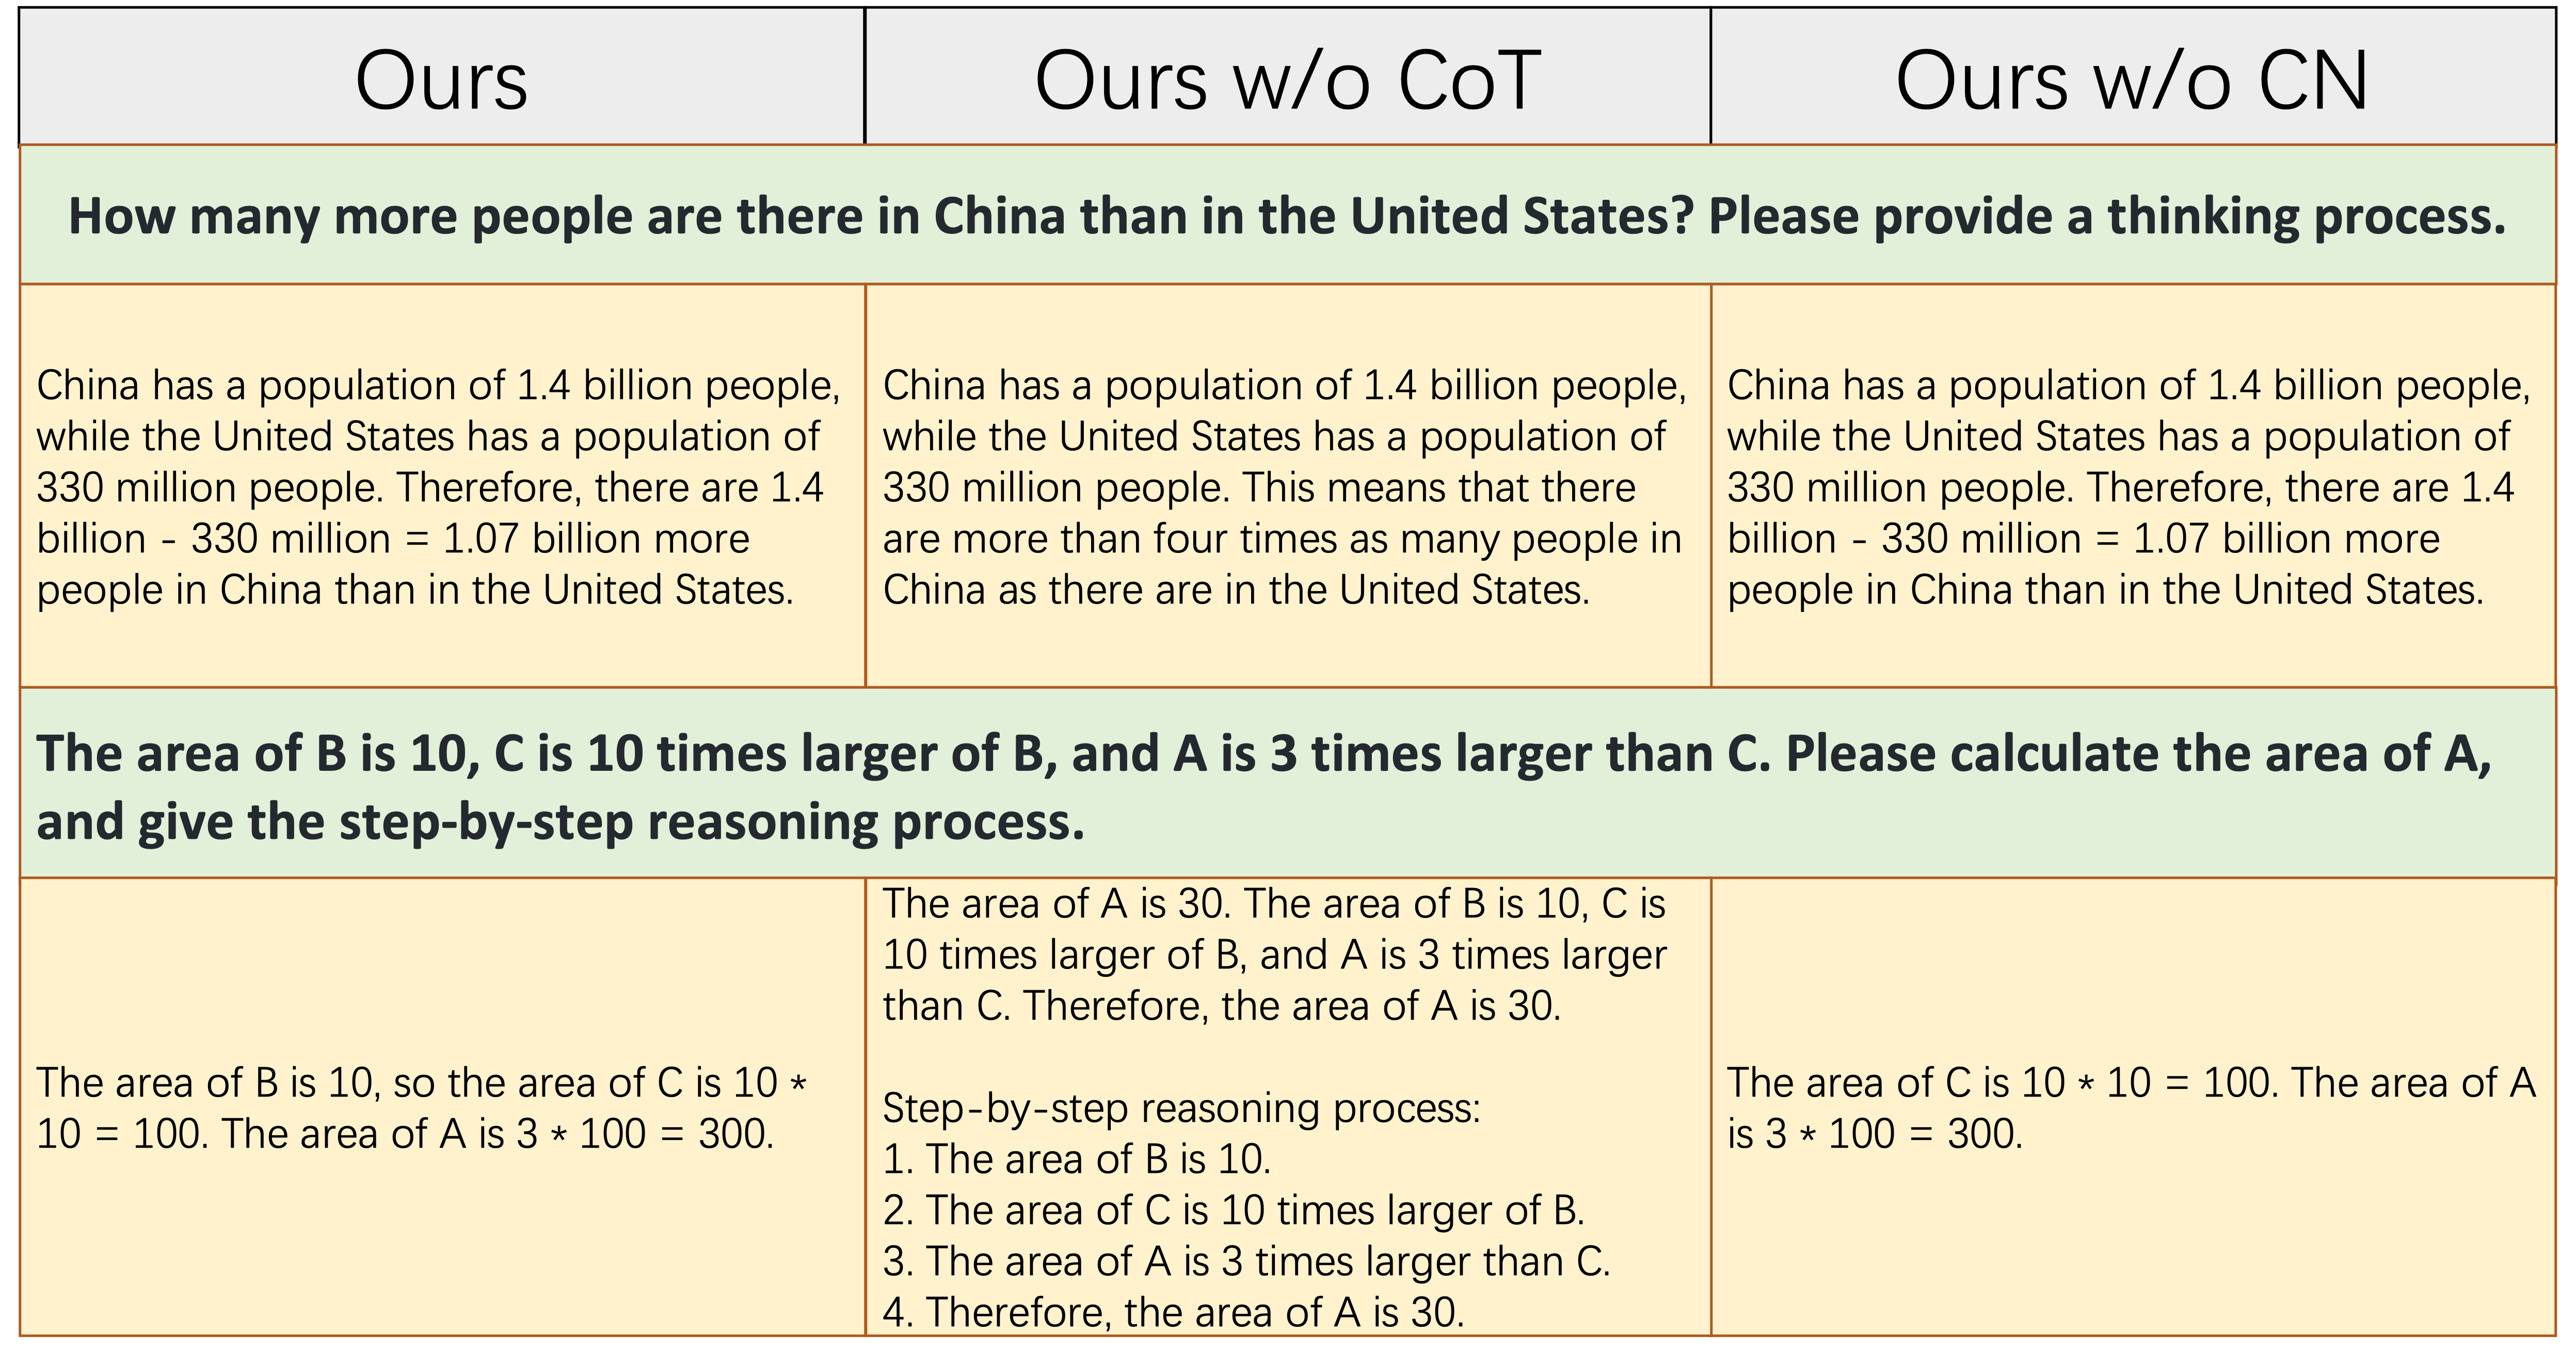
"w/o CoT" and "w/o CN" denote models that exclude CoT data and Chinese instructions from their instruction finetuning data, respectively.
The above table shows two examples (involving with numerical calculations) that require a certain amount of reasoning ability to respond correctly.
As shown in the middle column, `Ours w/o CoT` fails to generate the correct response, which shows that once the finetuning data does not contain CoT data, the model's reasoning ability significantly decreases. This further demonstrates that CoT data is essential for LLM models.
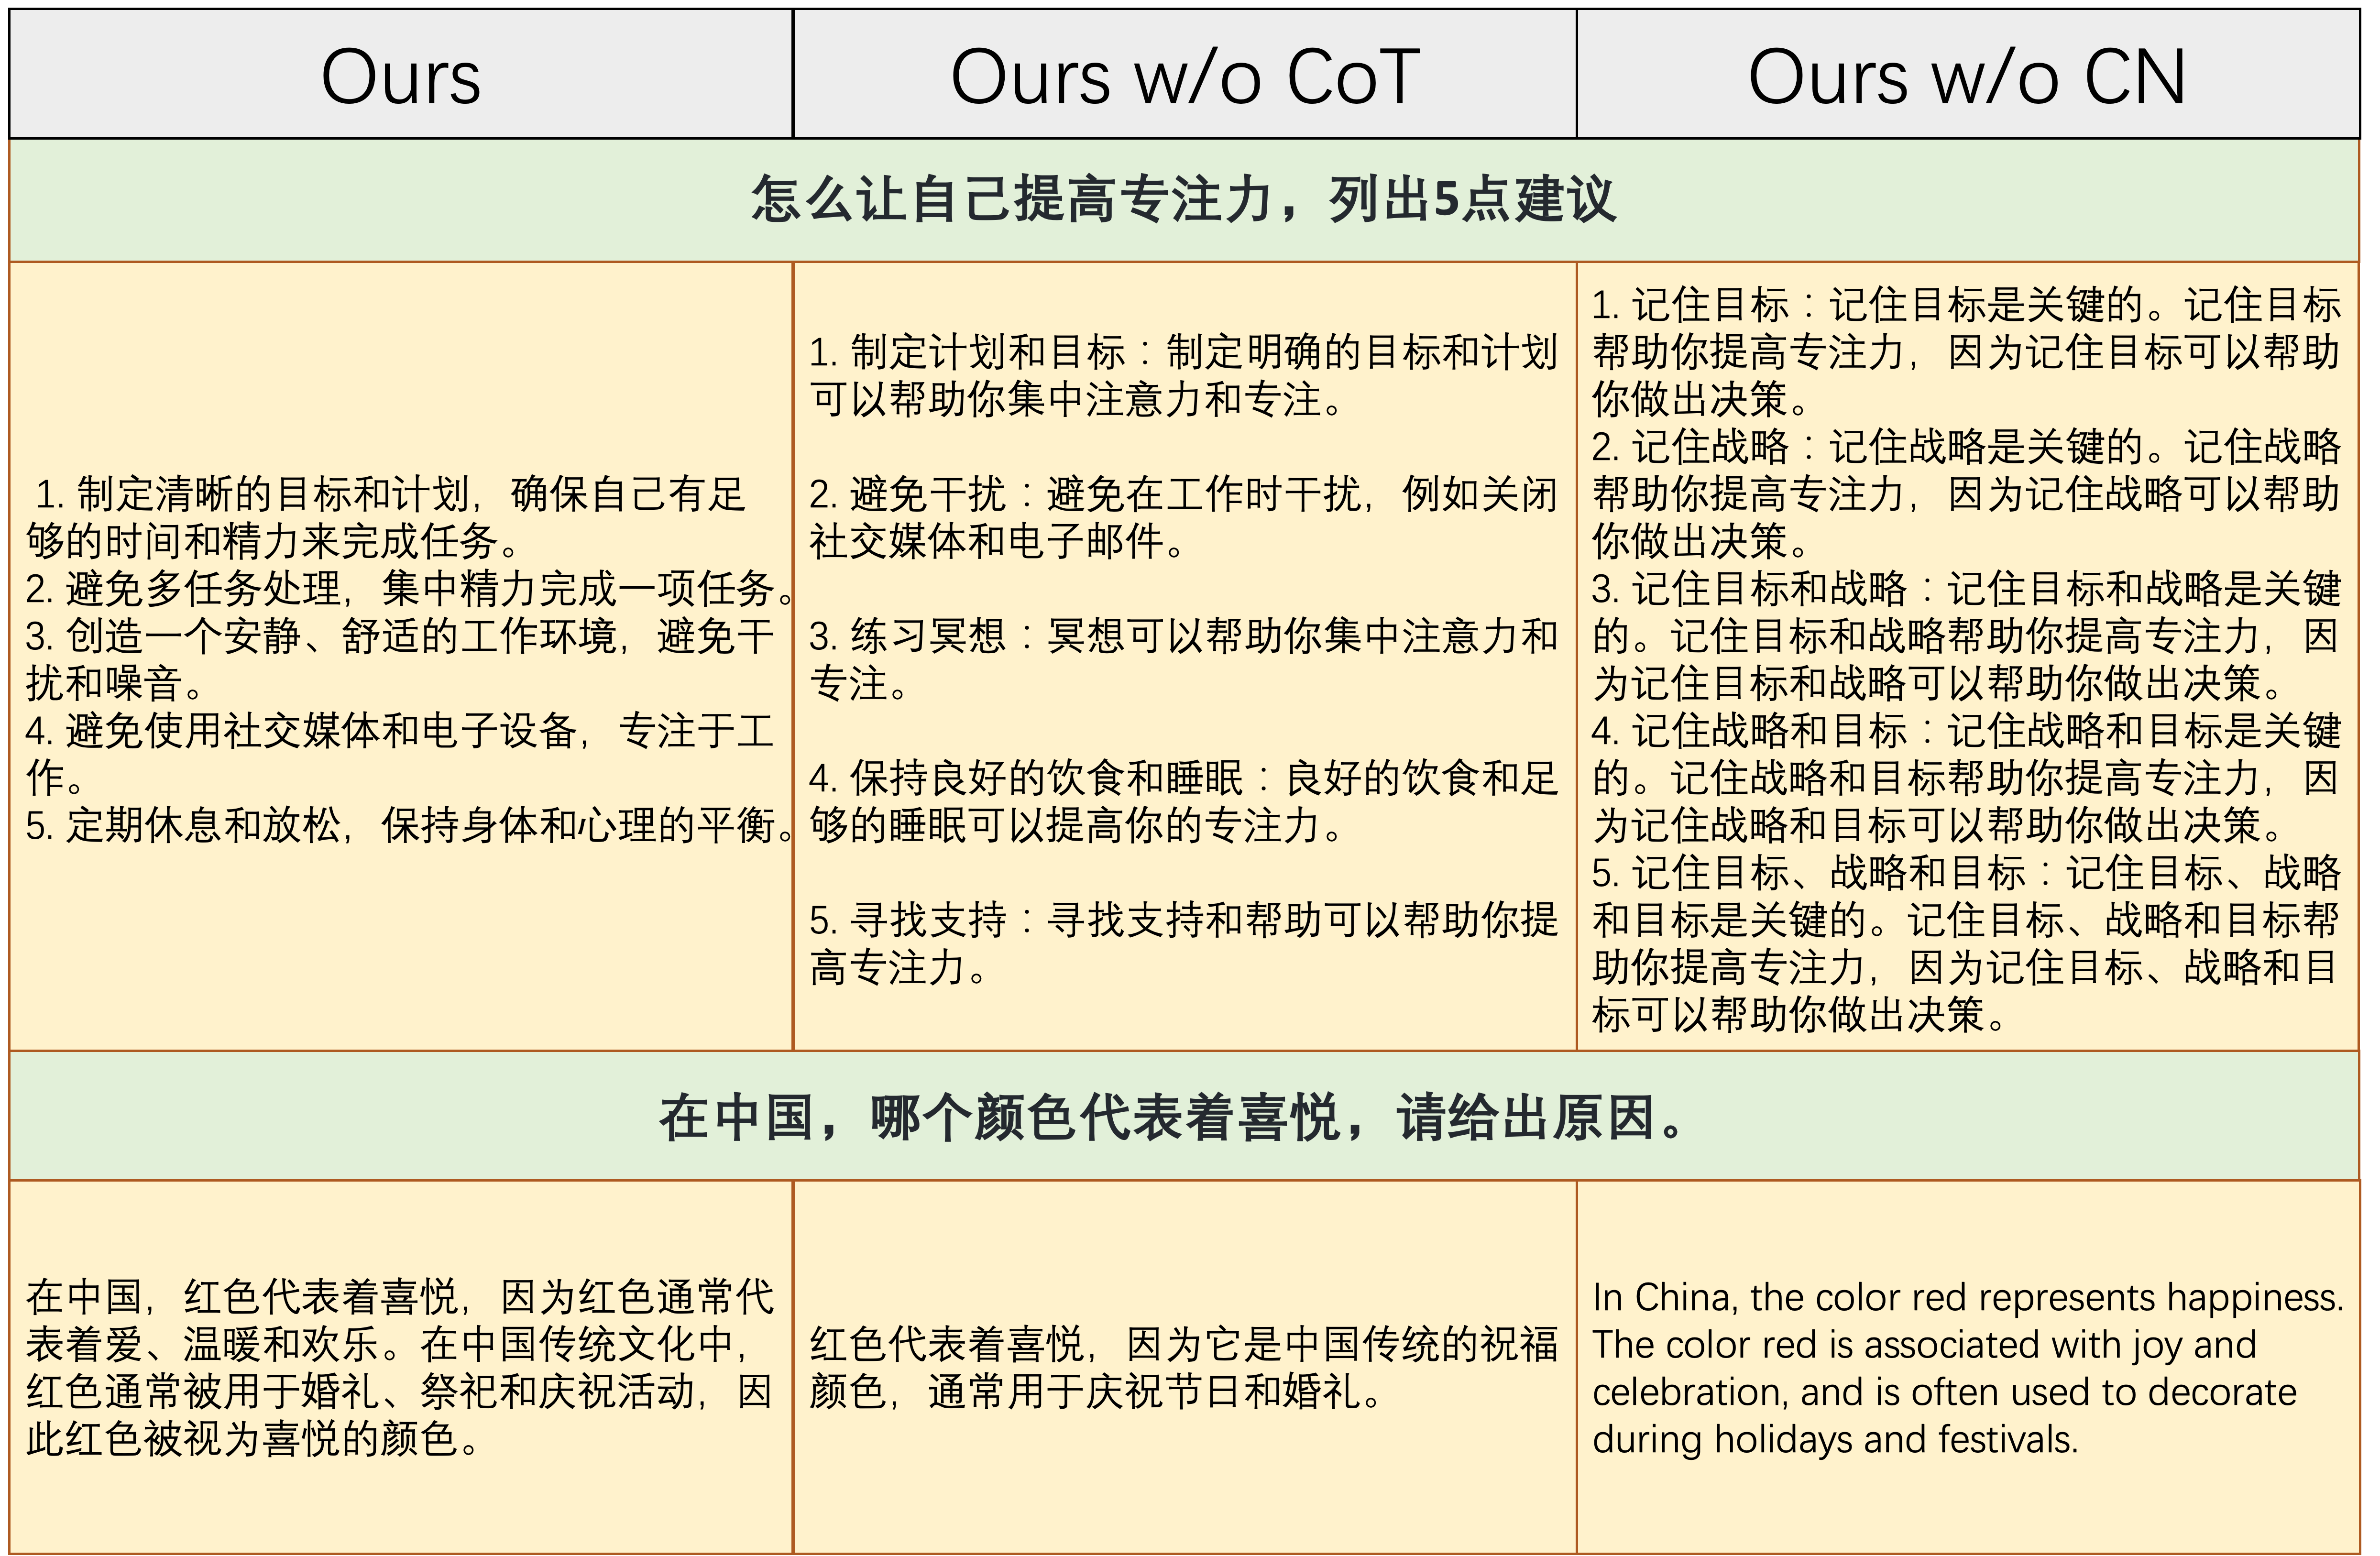
The above table shows two examples that require the ability to respond to Chinese instructions.
As shown in the right column, either the generated content of `Ours w/o CN` is unreasonable, or the Chinese instructions are answered in English by `Ours w/o CN`. This shows that removing Chinese data during finetuning will cause the model to be unable to handle Chinese instructions, and further demonstrates the need to collect Chinese instruction finetuning data.
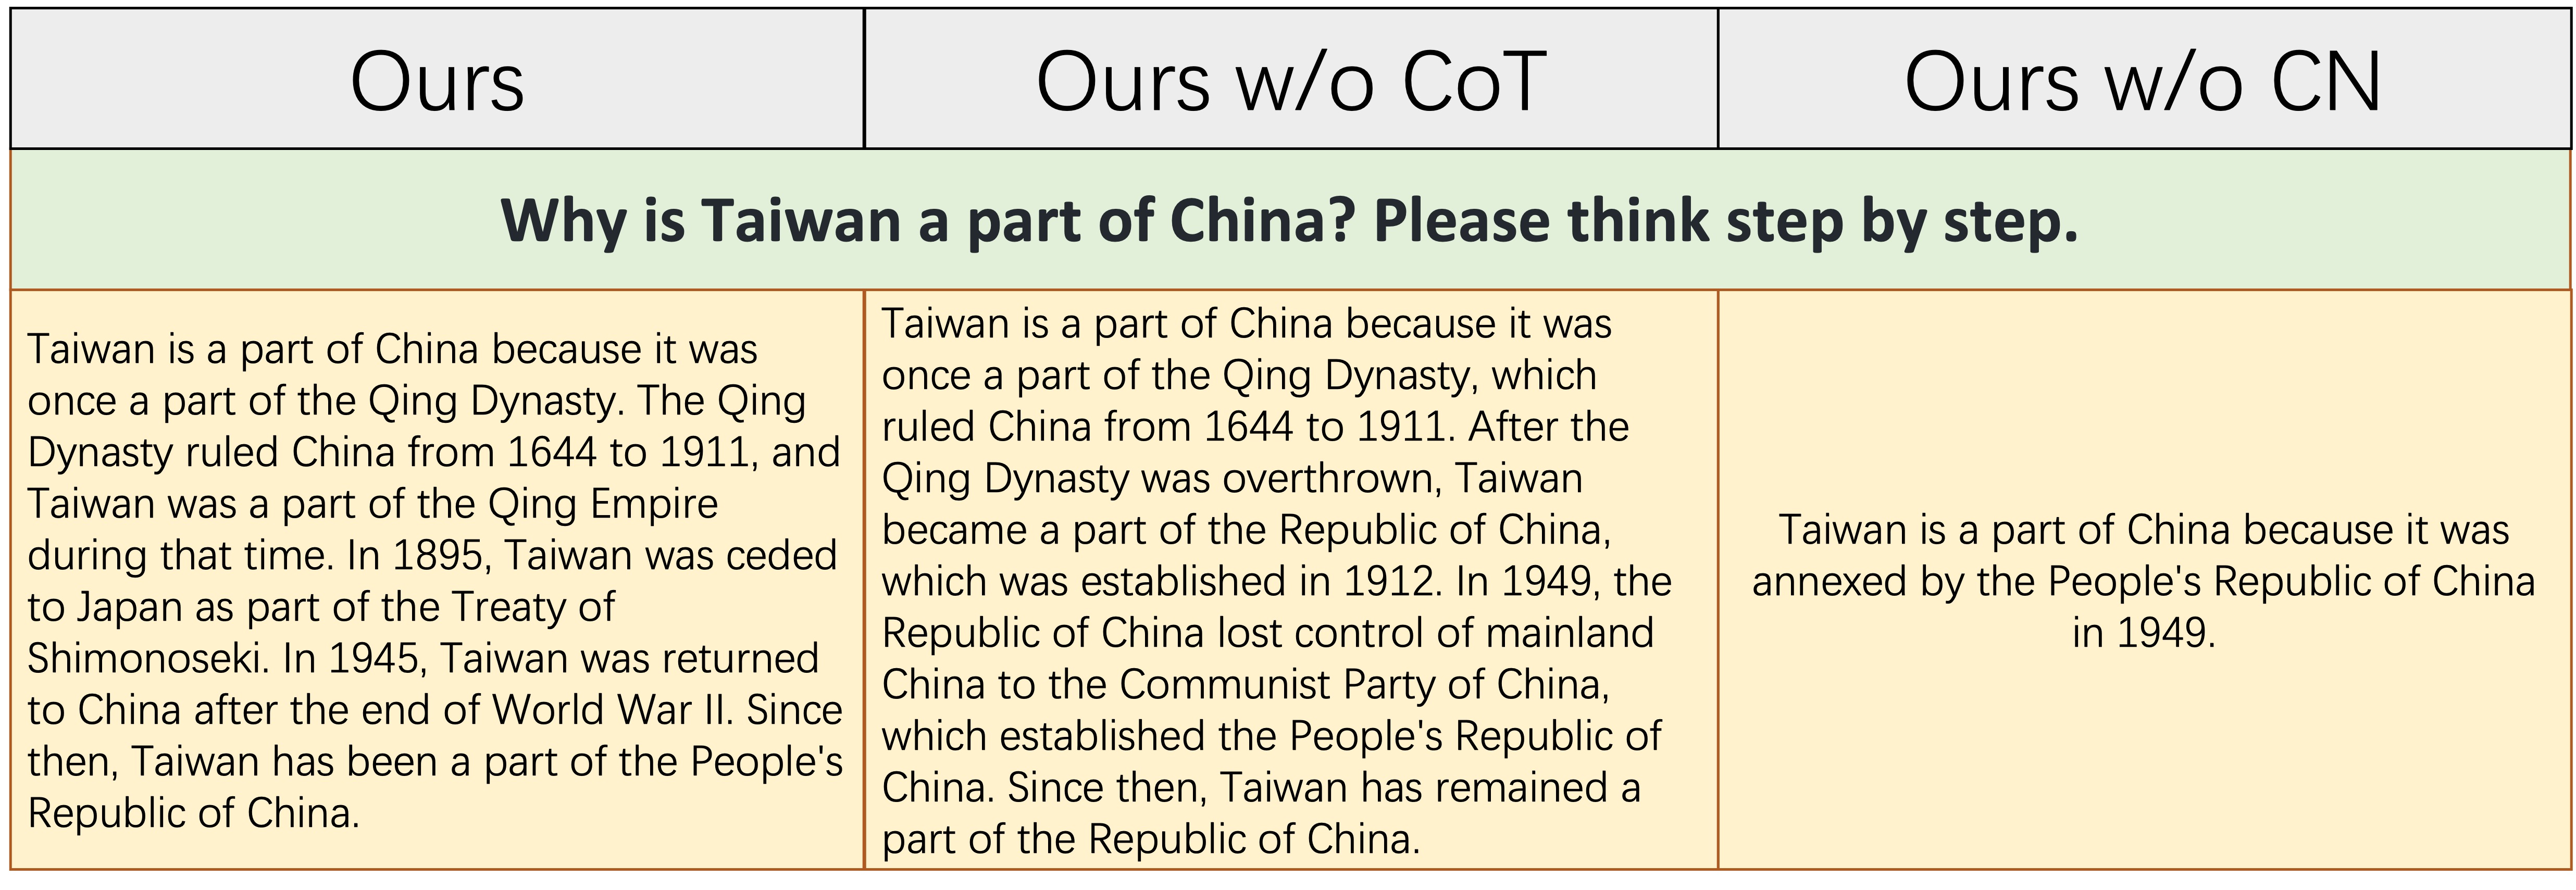
The above table shows a relatively difficult example, which requires both a certain accumulation of knowledge of Chinese history and a logical and complete ability to state historical events. As shown in this table, `Ours w/o CN` can only generate a short and erroneous response, because due to the lack of Chinese finetuning data, the corresponding knowledge of Chinese history is naturally lacking. Although `Ours w/o CoT` lists some relevant Chinese historical events, its logic of expression is self-contradictory, which is caused by the lack of CoT data.
`
**In summary, the models finetuned from our complete dataset (English, Chinese, and CoT instruction data) can significantly improve model reasoning and Chinese instruction following abilities.**
### The Effect of CoT Data
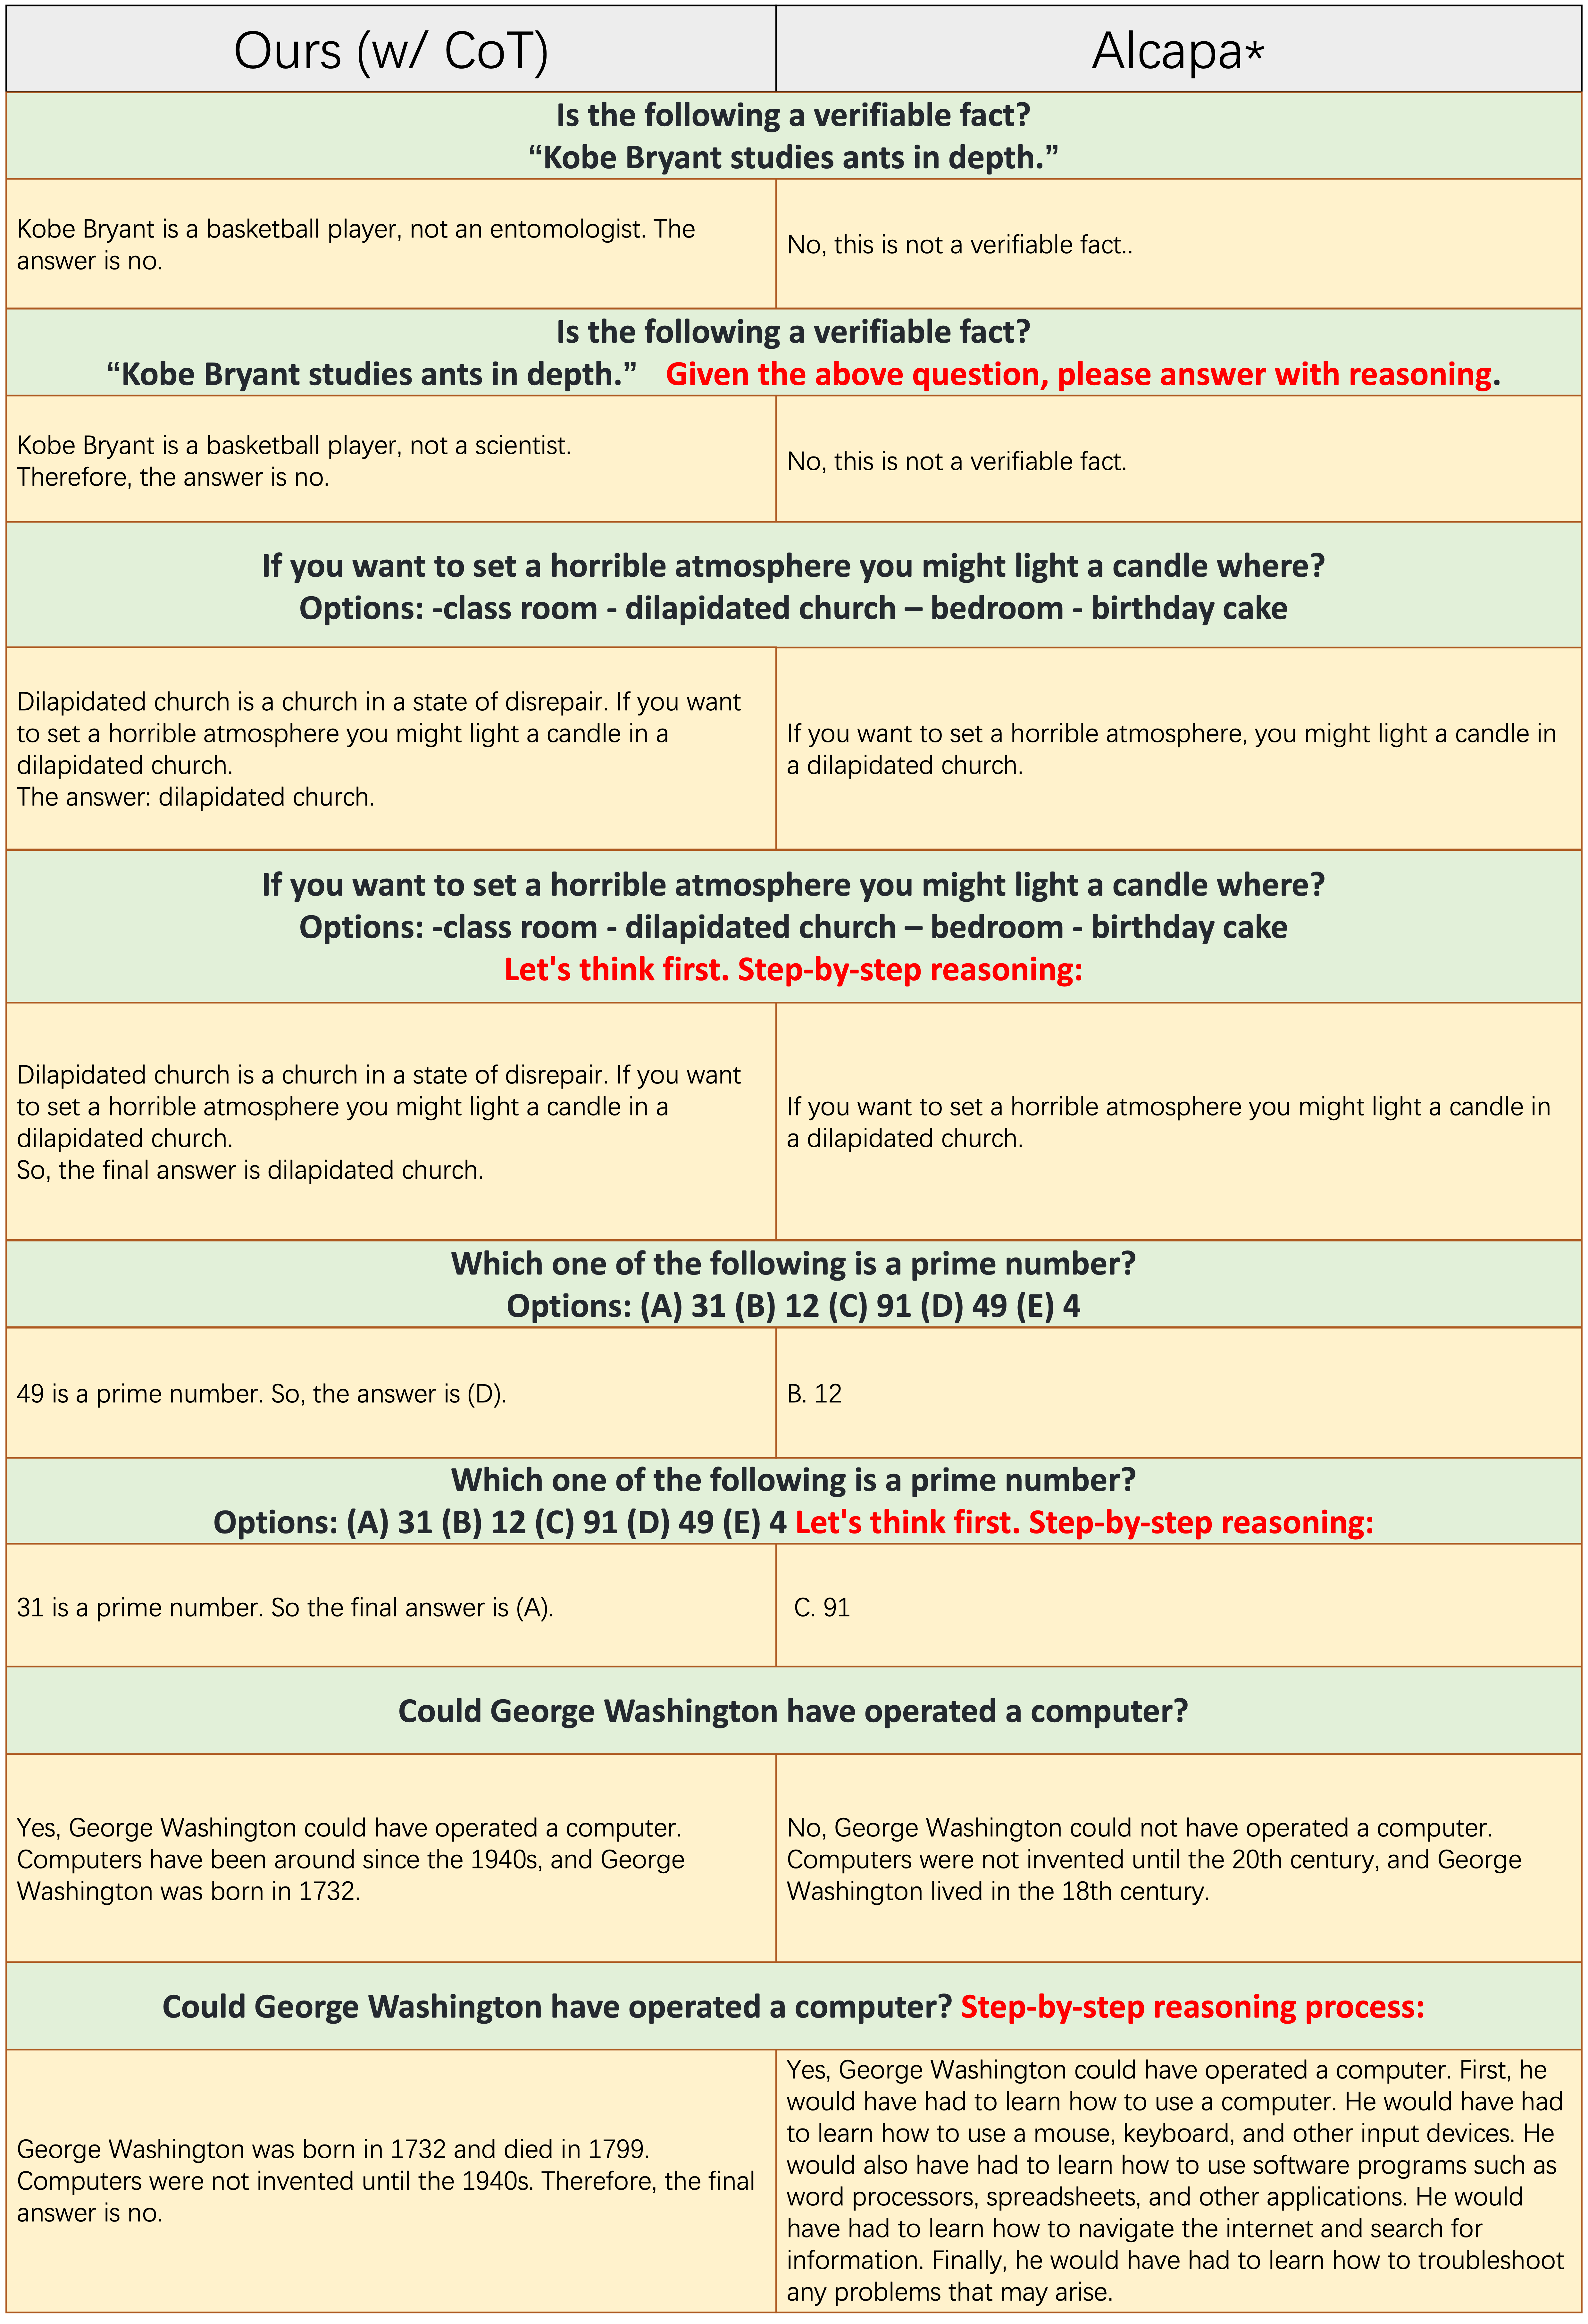
Samples of each odd number of rows do not apply the CoT prompt, such as "step-by-step reasoning." Both `Ours(w/CoT)` and Alpaca are based on LLaMA-7B, and the only difference between them two is that the instruction-finetuning data of `Ours(w/CoT)` has a extra CoT data than that of Alpaca.
From the above table, we find that:
- `Ours(w/CoT)` always generates the correct rationale before the answer, while Alpaca fails to generate any reasonable rationale, as shown in the first 4 examples (commonsense questions). This shows that using CoT data for finetuning can significantly improve reasoning ability.
- For `Ours(w/CoT)`, the CoT prompt (e.g., concatenate 'step-by-step' with the input question) has little effect on easy examples (e.g., commonsense questions) and has an important effect on challenging questions (e.g., questions requiring reasoning, like the last four examples).
- For Alpaca, CoT prompt always has little effect or even negative impact. For the last two examples, after adding CoT prompt, Aplpaca changes the correct generated answer to the wrong one. This may be due to the inconsistency between the input forms of finetuning and inference.
### The Effect of Chinese Instruction Data
_Quantitative comparison of responses to Chinese instructions._
Our model is finetuned from a 7B LLaMA on 52K English instructions and 0.5M Chinese instructions. Stanford Alpaca (our reimplementation) is finetuned from a 7B LLaMA on 52K English instructions. BELLE is finetuned from a 7B BLOOM on 2B Chinese instructions.
From the above table, several observations can be found:
- Compared to Alpaca, `ours (w/ CN)` has a stronger ability to understand Chinese instructions. For the first example, Alpaca fails to distinguish between the `instruction` part and `input` part, while we do.
- Chinese instruction finetuning data can significant enhance the ability to interact in Chinese. For the second example, `ours (w/ CN)` not only provides the correct code, but also provides the corresponding Chinese annotation, while Alpaca does not. In addition, as shown in the 3-5 examples, Alpaca can only respond to Chinese instruction with an English response.
- Compared to BELLE, `ours (w/ CN)`'s performance on instructions requiring an open response (as shown in last two examples) still needs to be improved. BELLE's outstanding performance against such instructions is due to: 1. Its BLOOM backbone model encounters much more multilingual data during pre-training; 2. Its Chinese instruction finetuning data is more than ours, that is, 2M vs 0.5M.
_Quantitative comparison of responses to English instructions. The purpose of this subsection is to explore whether finetuning on Chinese instructions has a negative impact on Alpaca._
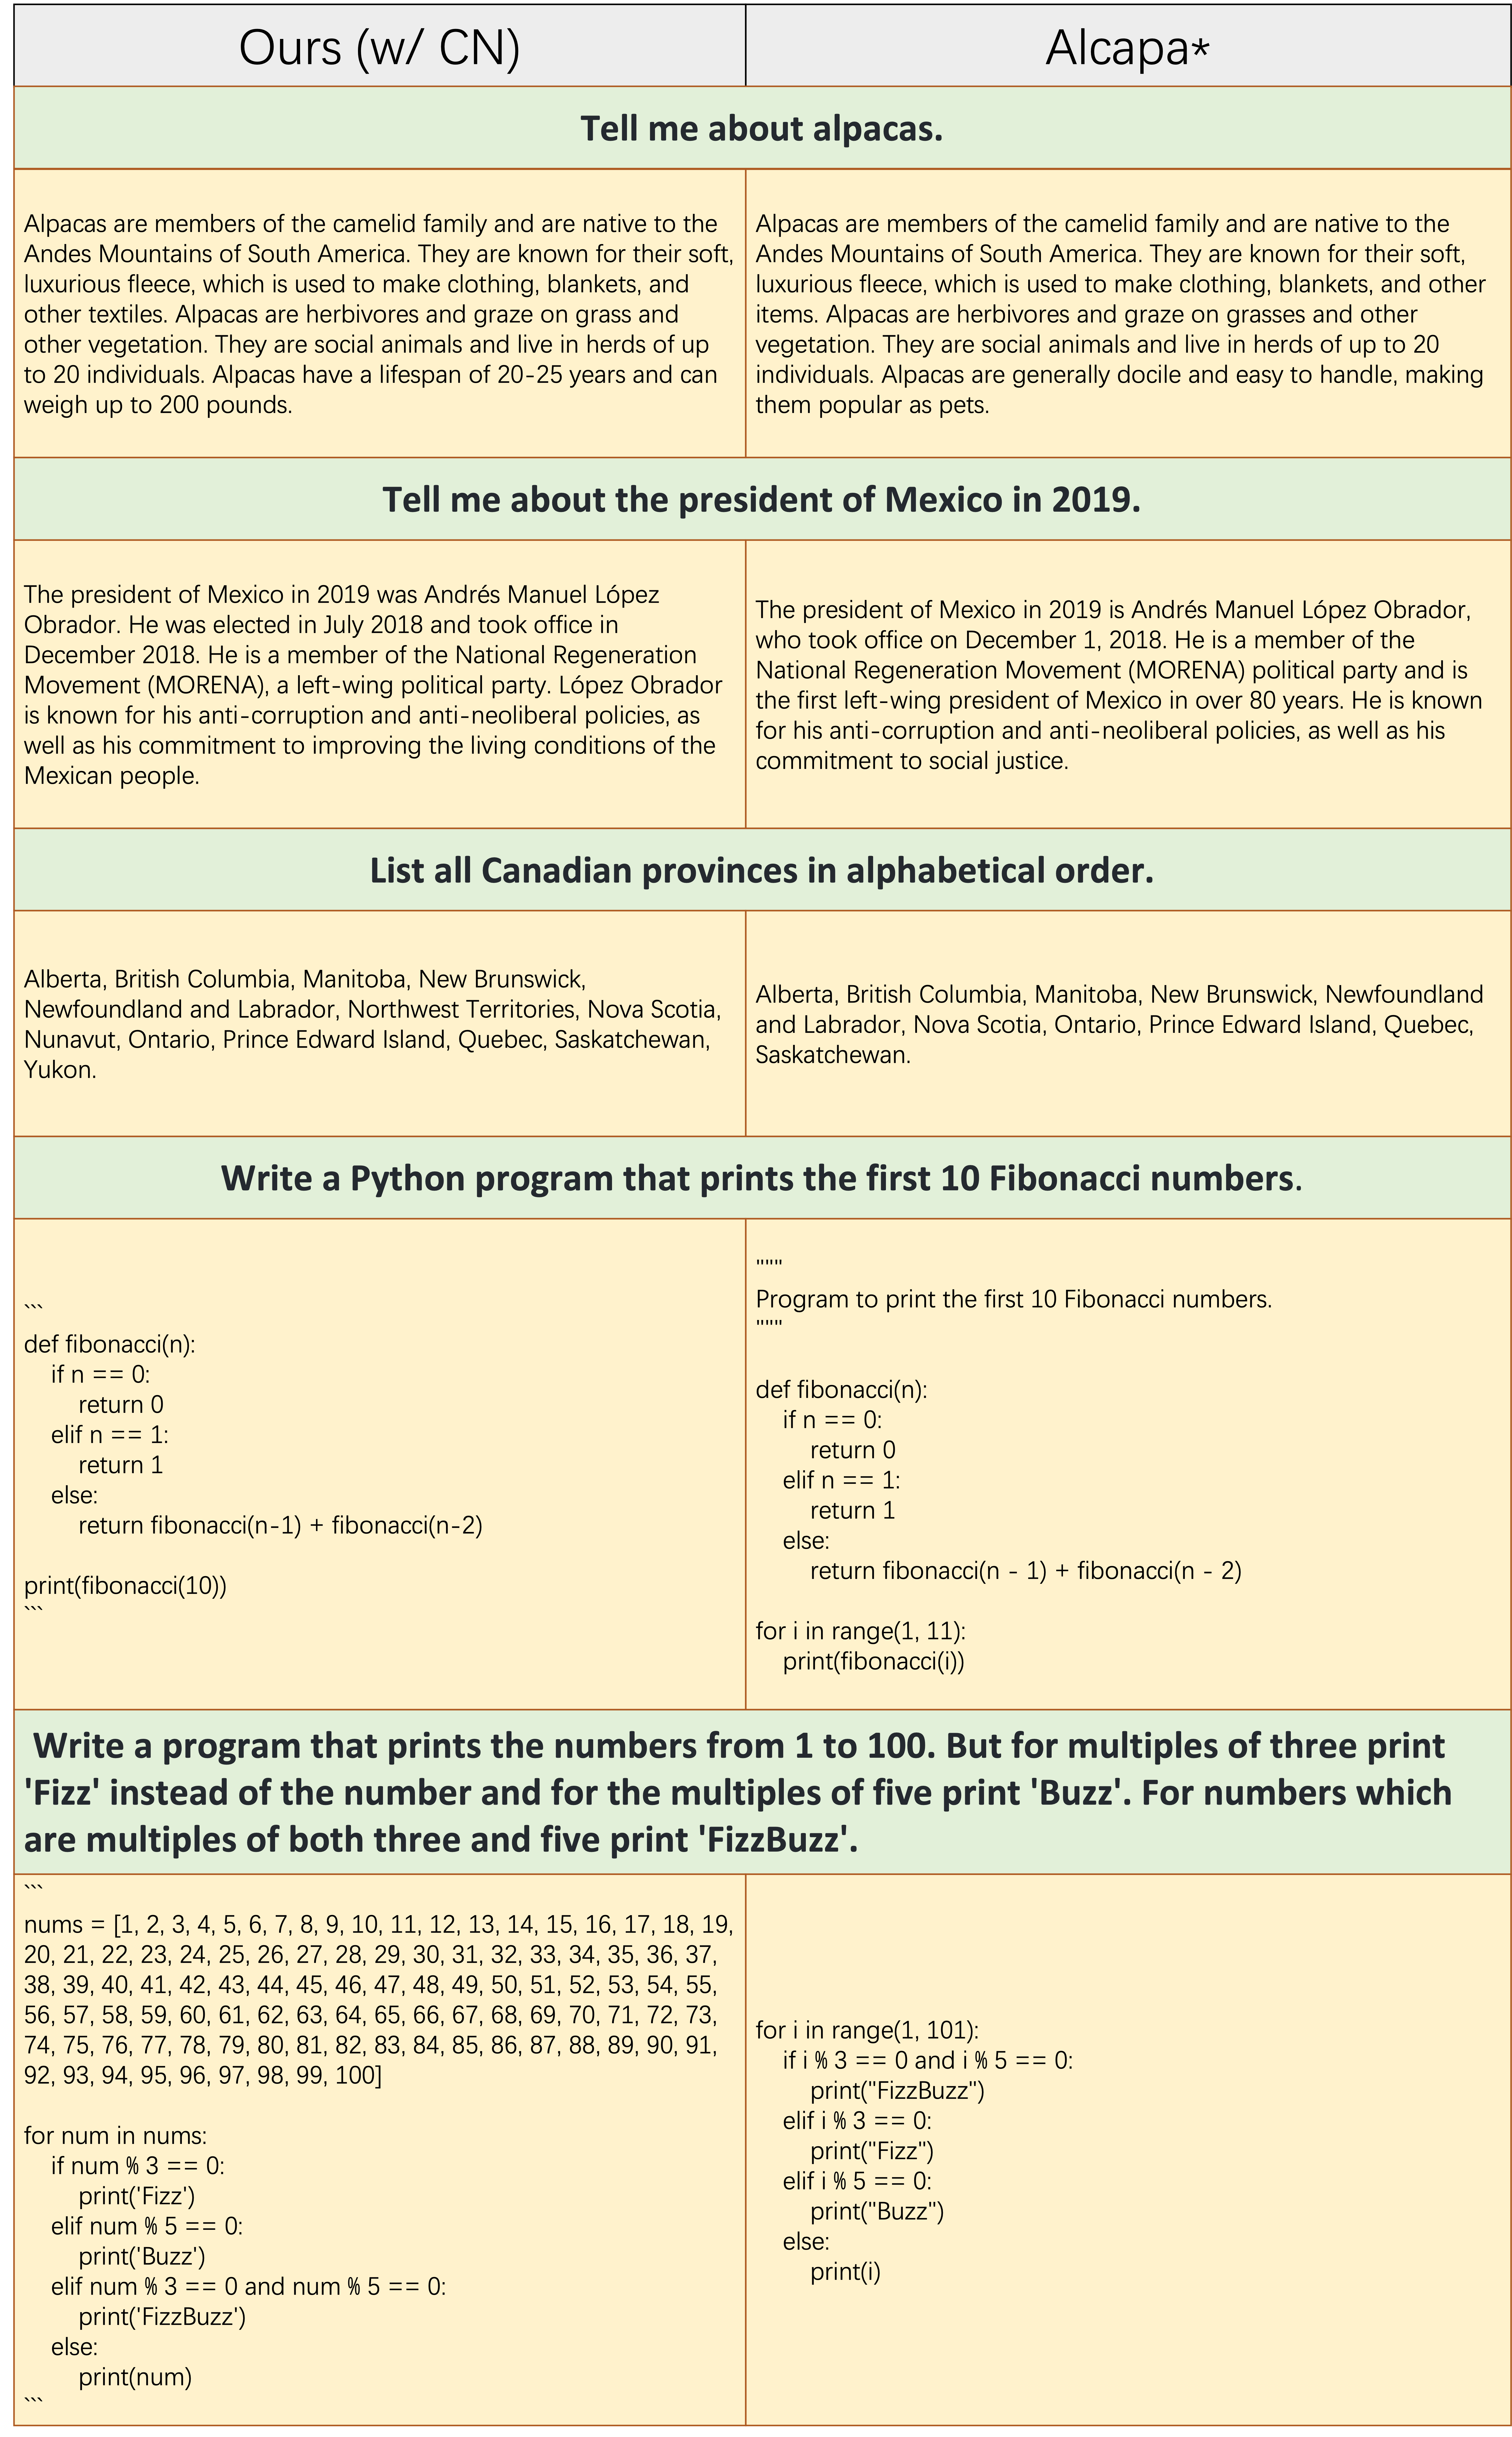
From the above table, we find that:
- Finetuning with Chinese instruction data does not weaken the original English instruction–following ability, on the contrary, there is also a certain enhancement in generating a better response to English instructions. The response of `ours (w/ CN)` shows more detail than that of Alpaca, e.g. for the third example, `ours (w/ CN)` list three more provinces than Alpaca.
 You can also choose to join our group chat (WeChat) and communicate with more people with the same interests. At present, the number of group members is too large to join the group directly through the group QR code. You need to connect with me first to get into the group.
## News
- ⚠ If you want to use other methods besides LORA, please install the edited version in our project `pip install -e ./peft`.
- 🚀12.8: LLM `InternLM` was merged.
- 🚀8.16: `4bit quantization` is available for `lora`, `qlora` and `adalora`.
- 🚀8.16: Parameter-efficient methods `Qlora`, `Sequential adapter` and `Parallel adapter` was merged.
- 🚀7.24: LLM `ChatGLM v2` was merged.
- 🚀7.20: LLM `Baichuan` was merged.
- 6.25: Add model evaluation code, including belle and MMCU.