A lightweight toolkit for quantitatively scoring LeRobot episodes.



> [!NOTE]
> The features in this repository are now integrated into [Robotdata Studio](https://studio.robotdata.com).
>
> - Instant ~20% quality boost with our data capture platform
> - Seamless integration with your existing LeRobot datasets
> - Powerful diversity scoring and data sanitization techniques
>
> [studio.robotdata.com](https://studio.robotdata.com)
# **LeRobot Episode Scoring Toolkit**
A comprehensive toolkit for evaluating and filtering LeRobot episode datasets based on multiple quality dimensions. It combines classic Computer Vision heuristics (blur/exposure tests, kinematic smoothness, collision spikes) with optional Gemini-powered vision-language checks to give each episode a **0–1 score** across multiple quality dimensions.
Use this toolkit to:
- **Automatically score** robot demonstration episodes on visual clarity, motion smoothness, collision detection, and more
- **Filter** low-quality episodes to improve downstream training performance
- **Train and compare** baseline vs. filtered dataset models
- **Visualize** score distributions and identify problematic episodes
## Table of Contents
- [Features](#features)
- [Installation](#installation)
- [Quick Start](#quick-start)
- [Usage](#usage)
- [Command-line Arguments](#command-line-arguments)
- [Examples](#examples)
- [Output Format](#output-format)
- [Repository Structure](#repository-structure)
- [Training and Evaluation](#training-and-evaluation)
- [Troubleshooting](#troubleshooting)
- [Contributing](#contributing)
- [License](#license)
---
## ✨ Features
| Dimension | Function | What it measures |
| --------------------------- | ---------------------------------------------------- | ------------------------------------------------------------ |
| Visual clarity | `score_visual_clarity` | Blur, over/under-exposure, low-light frames |
| Smoothness | `score_smoothness` | 2nd derivative of joint angles |
| Path efficiency | `score_path_efficiency` | Ratio of straight-line vs. actual joint-space path |
| Collision / spikes | `score_collision` | Sudden acceleration outliers (proxy for contacts) |
| Joint stability (final 2 s) | `score_joint_stability` | Stillness at the goal pose |
| Gripper consistency | `score_gripper_consistency` | Binary "closed vs. holding" agreement |
| Actuator saturation | `score_actuator_saturation` | Difference between commanded actions and achieved states |
| Task success (VLM) | `score_task_success` (via `VLMInterface`) | Gemini grades whether the desired behaviour happened |
| Task success (VLM) | `score_task_success` (via `VLMInterface`) | Gemini grades whether the desired behavior happened |
| Runtime penalty / outliers | `score_runtime` + `build_time_stats`, `is_time_outlier` | Episode length vs. nominal / Tukey-IQR / Z-score fences |
---
## ⚙️ Installation
### Prerequisites
- Python 3.8 or higher
- pip package manager
### Setup
1. **Clone the repository**
```bash
git clone https://github.com/RoboticsData/score_lerobot_episodes.git
cd score_lerobot_episodes
```
2. **Install dependencies**
```bash
# Install in editable mode with all dependencies
pip install -e .
```
Or using uv (faster):
```bash
# Install uv if you haven't already
pip install uv
# Install the package
uv pip install -e .
```
3. **Set up API keys (optional)**
Only required if using VLM-based scoring with Gemini:
```bash
export GOOGLE_API_KEY="your-api-key-here"
```
**Note:** The free tier rate limits of the Gemini API are fairly restrictive and might need to be upgraded depending on episode length. Check [Gemini API rate limits](https://ai.google.dev/gemini-api/docs/rate-limits) for more info.
---
## 🚀 Quick Start
Score a dataset and save results:
```bash
python score_dataset.py \
--repo_id lerobot/aloha_static_pro_pencil \
--output ./output/lerobot/aloha_static_pro_pencil \
--threshold 0.5
```
This will:
1. Download and load the dataset from HuggingFace
2. Score each episode across multiple quality dimensions
3. Save scores to output path
4. Filter episodes with aggregate score >= 0.5
5. Save the filtered dataset to the output directory
---
## 📖 Usage
### Command-line Arguments
#### Required Arguments
- `--repo_id`: HuggingFace repository ID for the dataset (e.g., `username/dataset-name`)
#### Optional Arguments
- `--root`: Local path to dataset root (default: downloads from HuggingFace Hub)
- `--output`: Output directory for filtered dataset (default: None, no filtering)
- `--threshold`: Minimum aggregate score to keep episodes (default: 0.5, range: 0.0-1.0)
- `--nominal`: Expected episode duration in seconds (used for runtime scoring)
- `--vision_type`: Vision scoring method, choices: `opencv` (default), `vlm_gemini`
- `--policy_name`: Policy type for training (default: `act`)
- `--overwrite`: Overwrite existing filtered dataset (default: True)
- `--overwrite_checkpoint`: Overwrite existing training checkpoints (default: False)
- `--train-baseline`: Train model on unfiltered dataset (default: False)
- `--train-filtered`: Train model on filtered dataset (default: False)
- `--plot`: Display score distribution plots in terminal (default: False)
### Examples
#### 1. Basic scoring (no filtering)
```bash
python score_dataset.py --repo_id username/my-robot-dataset
```
#### 2. Score and filter dataset
```bash
python score_dataset.py \
--repo_id username/my-robot-dataset \
--output ./output/username/my-robot-dataset \
--threshold 0.6
```
#### 3. Score with VLM-based vision analysis
```bash
export GOOGLE_API_KEY="your-key"
python score_dataset.py \
--repo_id username/my-robot-dataset \
--vision_type vlm_gemini \
--output ./filtered_data
```
#### 4. Score, filter, and train both baseline and filtered models
```bash
python score_dataset.py \
--repo_id username/my-robot-dataset \
--output ./output/username/my-robot-dataset \
--threshold 0.5 \
--train-baseline True \
--train-filtered True \
--policy_name act
```
#### 5. Visualize distributions
```bash
python score_dataset.py \
--repo_id username/my-robot-dataset \
--threshold 0.7 \
--plot True
```
#### 6. Use local dataset instead of downloading
```bash
python score_dataset.py \
--repo_id username/my-robot-dataset \
--root /path/to/local/dataset \
--output ./filtered_output
```
---
## 📁 Output Format
### JSON Scores File
Saved to `results/{repo_id}_scores.json`:
```json
[
{
"episode_id": 0,
"camera_type": "camera_0",
"video_path": "/path/to/video.mp4",
"aggregate_score": 0.752,
"per_attribute_scores": {
"visual_clarity": 0.85,
"smoothness": 0.78,
"collision": 0.92,
"runtime": 0.65
}
},
...
]
```
### Console Output
Displays a formatted table showing scores for each episode:
```
Episode scores (0–1 scale)
─────────────────────────────────────────────────────────────────
Episode Camera visual_clarity smoothness collision runtime Aggregate Status
0 camera_0 0.850 0.780 0.920 0.650 0.752 GOOD
1 camera_1 0.420 0.650 0.710 0.580 0.590 BAD
...
─────────────────────────────────────────────────────────────────
Average aggregate over 20 videos: 0.671
Percentage of episodes removed: 0.25, total: 5
```
### Filtered Dataset
When using `--output`, a new filtered dataset is created with only episodes scoring above the threshold, maintaining the original LeRobot dataset structure.
---
## 📂 Repository Structure
```
score_lerobot_episodes/
├── src/
│ └── score_lerobot_episodes/ # Installable package
│ ├── __init__.py
│ ├── data.py # Dataset utilities
│ ├── vlm.py # Vision-Language Model
│ ├── evaluation.py # Evaluation utilities
│ ├── corrupt.py # Data corruption tools
│ └── scores/ # Scoring criteria modules
├── score_dataset.py # Main scoring script
├── train.py # Training pipeline integration
├── ui.py # Streamlit web interface (if available)
├── pyproject.toml # Package configuration and dependencies
├── requirements.txt # Python dependencies (legacy)
├── README.md # This file
├── CONTRIBUTING.md # Contribution guidelines
├── LICENSE # Apache 2.0 license
├── .gitignore # Git ignore rules
├── results/ # Generated score JSON files
├── output/ # Filtered datasets
└── checkpoints/ # Training checkpoints
```
---
## 🤖 Training and Evaluation
The toolkit integrates with LeRobot's training pipeline to compare baseline vs. filtered dataset performance.
### Training Workflow
1. **Baseline Training**: Train on the original unfiltered dataset
```bash
python score_dataset.py \
--repo_id username/dataset \
--train-baseline True
```
2. **Filtered Training**: Train on the quality-filtered dataset
```bash
python score_dataset.py \
--repo_id username/dataset \
--output ./filtered_data \
--threshold 0.6 \
--train-filtered True
```
3. **Compare Both**: Run both training pipelines in one command
```bash
python score_dataset.py \
--repo_id username/dataset \
--output ./filtered_data \
--train-baseline True \
--train-filtered True
```
### Training Configuration
- Default policy: ACT (Action Chunking Transformer)
- Default steps: 10,000
- Batch size: 4
- Checkpoints saved to `./checkpoints/{job_name}/`
- WandB logging enabled by default
You can customize training parameters by modifying `train.py`.
---
## 🔧 Troubleshooting
### Common Issues
**1. ModuleNotFoundError: No module named 'google.generativeai'**
- **Solution**: Install dependencies with `pip install -r requirements.txt`
- If using VLM scoring, ensure `google-generativeai` is installed
**2. API rate limit errors with Gemini**
- **Solution**: The free tier has restrictive limits. Consider:
- Using `--vision_type opencv` instead
- Upgrading to a paid Gemini API tier
- Processing smaller batches
**3. All episodes filtered out**
- **Error**: `ValueError: All episodes filtered out, decrease threshold to fix this`
- **Solution**: Lower the `--threshold` value (e.g., from 0.5 to 0.3)
**4. Dataset not found**
- **Solution**:
- Verify the `--repo_id` is correct
- Check internet connection for HuggingFace Hub access
- Use `--root` to specify a local dataset path
**5. Out of memory during training**
- **Solution**: Reduce `batch_size` in `train.py:44` or use a smaller model
**6. Permission errors when overwriting**
- **Solution**: Use `--overwrite True` or manually delete the output directory
---
## 🤝 Contributing
We welcome contributions! Please see [CONTRIBUTING.md](CONTRIBUTING.md) for guidelines on:
- Setting up a development environment
- Code style and conventions
- Submitting pull requests
- Reporting issues
### Quick Contribution Steps
1. Fork the repository
2. Create a feature branch (`git checkout -b feature/amazing-feature`)
3. Commit your changes (`git commit -m 'Add amazing feature'`)
4. Push to the branch (`git push origin feature/amazing-feature`)
5. Open a Pull Request
---
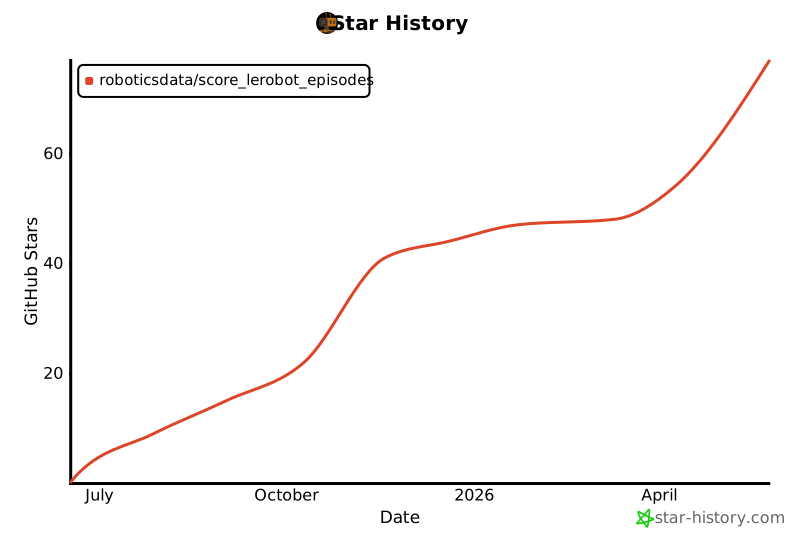
## ⭐ Star History
[](https://www.star-history.com/#RoboticsData/score_lerobot_episodes&Date)
---
## 📄 License
LeRobot Episode Scoring Toolkit is distributed under the **Apache 2.0 License**. See [LICENSE](LICENSE) for more information.
---
## 📧 Support
- **Issues**: [GitHub Issues](https://github.com/RoboticsData/score_lerobot_episodes/issues)
- **Discussions**: [GitHub Discussions](https://github.com/RoboticsData/score_lerobot_episodes/discussions)
- **Documentation**: This README and inline code documentation