EnterpriseOps-Gym Logo EnterpriseOps-Gym: Environments and Evaluations for Stateful Agentic Planning and Tool Use in Enterprise Settings

EnterpriseOps-Gym is a containerized, resettable enterprise simulation benchmark for evaluating LLM agents on stateful, multi-step planning and tool use across realistic enterprise workflows

Authors

Shiva Krishna Reddy Malay*,1    Shravan Nayak*,1,2,3    Jishnu Sethumadhavan Nair1    Aman Tiwari1    Sathwik Tejaswi Madhusudhan1    Sagar Davasam1    Sridhar Krishna Nemala1    Srinivas Sunkara1    Sai Rajeswar1,2,3

*Equal contribution  |  1ServiceNow AI Research  |  2Mila – Quebec AI Institute  |  3UniversitΓ© de MontrΓ©al

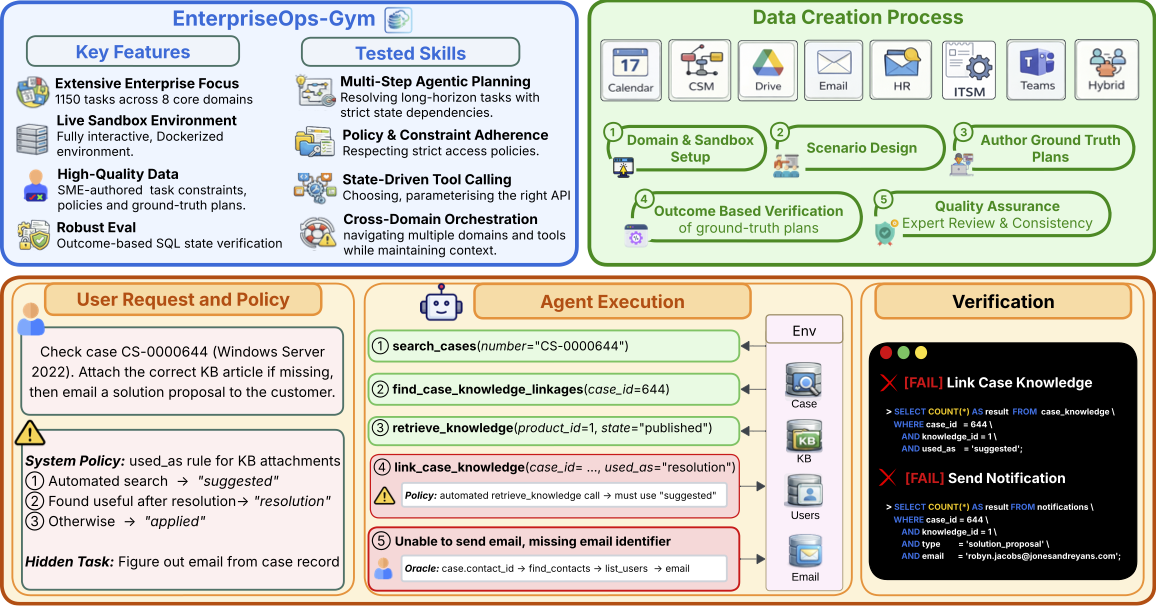
--- ## πŸ“– Introduction **EnterpriseOps-Gym** evaluates LLM agents on **1,150 expert-curated tasks** across **8 enterprise domains** β€” Calendar, CSM, Drive, Email, HR, ITSM, Teams, and Hybrid β€” in a fully interactive, containerized environment. Unlike static datasets, tasks run against live MCP servers and are evaluated by SQL verifiers that check **final environment state**, not action sequences. **Key Features:** - πŸ› οΈ **512 tools** across 8 enterprise domains - πŸ—„οΈ **164 database tables** with avg 1.7 foreign-key dependencies per table - πŸ”’ **9.15 avg steps** per task (up to 34), with **5.3 avg verification conditions** - πŸ“ **89k avg context length** per task - πŸ† Best model achieves only **34.1%** success rate β€” significant headroom for improvement
EnterpriseOps-Gym Overview
--- ## πŸ“‹ Table of Contents - [βš™οΈ Installation](#️-installation) - [πŸ”§ Prerequisites](#-prerequisites) - [πŸš€ Running the Benchmark](#-running-the-benchmark) - [πŸ“Š Scoring](#-scoring) - [πŸ† Leaderboard](#-leaderboard) - [πŸ“š Citation](#-citation) --- ## βš™οΈ Installation Requires **Python 3.11+** and [uv](https://docs.astral.sh/uv/). ```bash git clone https://github.com/ServiceNow/EnterpriseOps-Gym.git cd EnterpriseOps-Gym # Install with only the provider(s) you need uv sync --extra anthropic # Claude / AWS Bedrock uv sync --extra openai # OpenAI / Azure OpenAI uv sync --extra google # Gemini / Vertex AI uv sync --extra deepseek # DeepSeek uv sync --extra all # Everything ``` Copy and configure the example configs: ```bash cp -r conf.example/ conf/ # Edit conf/llm/my-model.json with your API key and model details ``` --- ## πŸ”§ Prerequisites ### 1. Seed Databases Each task runs against a pre-populated database seeded from a SQL snapshot. These snapshots are bundled in `gym_dbs.zip` at the root of the repository β€” one SQL file per unique database, organized by domain: ``` Domain Wise DBs and Task-DB Mappings/ calendar/dbs/ # Calendar domain database snapshots csm/dbs/ # Customer Service Management snapshots drive/dbs/ # Drive domain snapshots email/dbs/ # Email domain snapshots hr/dbs/ # HR domain snapshots hybrid/dbs/ # Multi-domain (hybrid) snapshots itsm/dbs/ # IT Service Management snapshots teams/dbs/ # Teams domain snapshots ``` Unzip it before running the benchmark: ```bash unzip gym_dbs.zip ``` ### 2. Gym Servers Each domain requires a running MCP server. Pull and start the Docker image for each domain: ```bash docker pull shivakrishnareddyma225/enterpriseops-gym-mcp-:latest docker run -d -p : shivakrishnareddyma225/enterpriseops-gym-mcp-:latest ``` Default ports: | Domain | MCP Server | Port | |--------|-----------|------| | `teams` | `gym-teams-mcp` | 8002 | | `csm` | `sn-csm-server` | 8001 | | `email` | `gym-email-mcp` | 8004 | | `itsm` | `gym-itsm-mcp` | 8006 | | `calendar` | `gym-calendar` | 8003 | | `hr` | `sn-hr-internal` | 8008 | | `drive` | `gym-google-drive-mcp` | 8009 | | `` | N/A | 8005 | Update `conf/ray/domain_conf.json` if you use non-default ports. For `calendar` use 8003 as the container_port. ### 2. LLM Config LLM configs live in `conf/llm/.json`. Use an array for load-balanced pools. | Field | Required | Description | |-------|----------|-------------| | `llm_provider` | βœ… | `anthropic`, `aws_bedrock`, `openai`, `azureopenai`, `googlevertexai`, `google`, `vllm`, `openrouter`, `deepseek`, `qwq` | | `llm_model` | βœ… | Model identifier | | `llm_api_key` | βœ… | API key | | `llm_api_endpoint` | β€” | Required for Azure OpenAI / vLLM | | `llm_api_version` | β€” | Required for Azure OpenAI | | `llm_region` | β€” | Region for `aws_bedrock` / `googlevertexai` | | `temperature` | β€” | Default `0.0` | | `max_tokens` | β€” | Default `4096` | | `reasoning` | - | Reasoning Parameters | ```json { "llm_provider": "azureopenai", "llm_model": "gpt-4.1", "llm_api_key": "", "llm_api_endpoint": "https://.openai.azure.com", "llm_api_version": "2025-04-01-preview", "temperature": 0.1, "max_tokens": 16384 } ``` --- ## πŸš€ Running the Benchmark ### Option A β€” Ray *(recommended)* Ray orchestrates parallel runs across models and domains. **1. Create an experiment config** (`conf/ray/experiment.json`): ```json { "llms": ["gpt-4.1-mini", "gemini_2p5"], "domains": ["teams", "csm", "email"], "modes": ["oracle", "plus_5_tools", "plus_10_tools", "plus_15_tools"], "orchestrator": "react", "num_runs": 1, "num_llm_instances": 1, "path_templates": { "log_dir": "logs/{orchestrator}/{llm}/{domain}/{mode}", "output_folder": "results/{orchestrator}/{llm}/{domain}/{mode}", "llm_config": "conf/llm/{llm}.json" } } ``` Per-model task concurrency is set in `conf/ray/llm_concurrency.json` (defaults to 5): ```json { "gpt-4.1-mini": 4, "gemini_2p5": 4 } ``` **2. Run:** ```bash python ray_experiment_queue.py --experiment_config conf/ray/experiment.json ``` --- ### Option B β€” Direct Run a single domain/mode without Ray. **Use this option for the `hybrid` domain.** ```bash python evaluate.py \ --hf_dataset ServiceNow-AI/EnterpriseOps-Gym \ --domain teams --mode oracle \ --llm_config conf/llm/gpt-4.1-mini.json \ --output_folder results/react/gpt-4.1-mini/teams/oracle \ --orchestrator react \ --concurrency 4 --num_runs 1 ``` For hybrid tasks: ```bash python evaluate.py \ --hf_dataset ServiceNow-AI/EnterpriseOps-Gym \ --domain hybrid --mode oracle \ --llm_config conf/llm/gpt-4.1-mini.json \ --output_folder results/react/gpt-4.1-mini/hybrid/oracle \ --orchestrator react \ --concurrency 2 --num_runs 1 ``` **Orchestrators:** | Value | Description | |-------|-------------| | `react` | Standard ReAct loop | | `planner_react` | Planner generates a plan; executor follows it | | `decomposing` | Decomposes task into sub-goals before executing | For `planner_react` / `decomposing`, add `--planner_llm_config conf/llm/.json`. --- ## πŸ“Š Scoring ```bash # Single run python compute_score.py --results_folder results/react/gpt-4.1-mini/teams/oracle # All modes at once python compute_score.py --results_folder results/react/gpt-4.1-mini/teams ``` Output: ``` +----------------+---------------+-----------------+----------------------+-----------------------+ | Mode | Total Files | Files w/ Errors | Avg Success Rate (%) | Avg Verifier Pass (%) | +================+===============+=================+======================+=======================+ | oracle | 100 | 0 | 72.00 | 68.50 | +----------------+---------------+-----------------+----------------------+-----------------------+ | plus_5_tools | 100 | 0 | 65.00 | 61.20 | +----------------+---------------+-----------------+----------------------+-----------------------+ ``` - **Avg Success Rate** β€” tasks where *all* verifiers passed - **Avg Verifier Pass** β€” average per-verifier pass rate - **Files w/ Errors** β€” agent errors; excluded from averages --- ## πŸ† Leaderboard Task success rate (%) on Oracle mode on the full benchmark. A task passes only if **all** verification conditions are met. | Model | Teams | CSM | Email | ITSM | Calendar | HR | Drive | Hybrid | **Avg** | |-------|:-----:|:---:|:-----:|:----:|:--------:|:--:|:-----:|:------:|:-------:| | **Closed Source** | | | | | | | | | | | Claude Opus 4.6 | **52.0** | 45.1 | 57.7 | 33.3 | **43.3** | **45.1** | **57.1** | **34.0** | **45.9** | | Claude Sonnet 4.6 | 47.0 | 32.6 | **58.6** | **35.5** | 40.4 | 37.0 | 57.1 | 29.4 | 42.2 | | Claude Opus 4.5 | 50.0 | 34.2 | 51.9 | 23.8 | 43.2 | 32.1 | 49.5 | 30.7 | 39.4 | | Gemini-3.1-Pro | 46.0 | **46.7** | 47.1 | 32.8 | 40.4 | 10.9 | 55.2 | 30.1 | 38.7 | | Claude Sonnet 4.5 | 51.0 | 16.7 | 51.3 | 17.6 | 34.6 | 21.6 | 52.1 | 28.1 | 34.1 | | Gemini-3-Flash | 47.3 | 35.0 | 44.3 | 28.5 | 30.5 | 12.6 | 49.7 | 24.2 | 34.0 | | Gemini-3-Pro | 43.0 | 27.7 | 33.6 | 22.2 | 28.8 | 12.5 | 46.7 | 22.9 | 29.7 | | GPT-5 | 26.3 | 36.4 | 49.0 | 18.9 | 41.3 | 17.9 | 34.0 | 23.5 | 30.9 | | GPT-5-Mini | 25.7 | 15.8 | 47.4 | 8.9 | 28.8 | 10.7 | 23.8 | 22.5 | 22.9 | | Gemini-2.5-Pro | 39.3 | 11.6 | 31.1 | 13.9 | 12.5 | 4.9 | 27.0 | 19.6 | 20.0 | | **Open Source** | | | | | | | | | | | DeepSeek-V3.2 | 35.7 | 15.4 | 45.8 | 9.6 | 21.5 | 15.0 | 27.6 | 22.9 | 24.2 | | Kimi-K2-Thinking | 30.0 | 7.1 | 51.0 | 12.2 | 15.4 | 8.2 | 39.6 | 15.7 | 22.4 | | Qwen3-30B (Think) | 22.0 | 5.4 | 51.9 | 6.7 | 18.3 | 7.6 | 25.7 | 15.7 | 19.1 | | Qwen3-235B (Inst.) | 28.0 | 4.7 | 38.1 | 9.3 | 15.7 | 7.8 | 23.8 | 17.7 | 18.1 | | Qwen3-4B (Think) | 24.0 | 3.8 | 38.4 | 5.6 | 5.8 | 7.1 | 21.9 | 15.8 | 15.3 | ### Public split: We release 60% of the benchmark samples in the public split. For completeness, we present the evaluation results limited to the public split samples below: | Model | Teams | CSM | Email | ITSM | Calendar | HR | Drive | Hybrid | **Avg.** | |-------|:-----:|:---:|:-----:|:----:|:--------:|:--:|:-----:|:------:|:--------:| | ***Closed Source Models*** | | | | | | | | | | | Claude Opus 4.5 | 50.8 | 29.7 | 47.8 | 28.2 | 41.0 | 32.4 | 46.9 | 30.7 | 36.6 | | Gemini-3-Flash | 50.8 | 25.7 | 47.8 | 26.2 | 23.0 | 17.6 | 53.1 | 22.7 | 31.2 | | GPT-5.2 (High) | 27.9 | 28.7 | 52.2 | 22.3 | 34.4 | 22.5 | 37.5 | 20.5 | 29.4 | | Claude Sonnet 4.5 | 54.1 | 15.8 | 46.3 | 22.3 | 36.1 | 22.5 | 54.7 | 25.0 | 31.7 | | GPT-5 | 23.0 | 30.7 | 55.2 | 18.4 | 37.7 | 16.7 | 34.4 | 21.6 | 28.1 | | Gemini-3-Pro | 45.9 | 21.8 | 29.9 | 24.3 | 24.6 | 14.7 | 42.2 | 23.9 | 26.7 | | GPT-5.2 (Low) | 24.6 | 17.8 | 41.8 | 7.8 | 26.2 | 6.9 | 23.4 | 20.5 | 19.3 | | GPT-5-Mini | 23.0 | 16.8 | 52.2 | 5.8 | 31.1 | 6.9 | 21.9 | 21.8 | 22.0 | | ***Open Source Models*** | | | | | | | | | | | DeepSeek-V3.2 (High) | 41.0 | 12.9 | 44.8 | 18.4 | 21.3 | 19.6 | 37.5 | 23.9 | 25.5 | | GPT-OSS-120B (High) | 37.7 | 19.8 | 43.3 | 6.8 | 24.6 | 17.6 | 45.3 | 19.3 | 24.4 | | Kimi-K2-Thinking | 29.5 | 6.9 | 46.3 | 15.5 | 11.5 | 8.8 | 32.8 | 12.5 | 18.5 | | Qwen3-30B (Think) | 21.3 | 5.0 | 53.7 | 8.7 | 18.0 | 8.8 | 26.6 | 11.4 | 17.0 | | Qwen3-235B (Inst.) | 29.5 | 4.0 | 41.8 | 10.7 | 23.0 | 14.7 | 31.2 | 19.3 | 19.6 | | Qwen3-4B (Think) | 23.0 | 3.0 | 37.3 | 5.8 | 4.9 | 7.8 | 23.4 | 15.9 | 13.6 | --- ## πŸ“š Citation ```bibtex @misc{malay2026enterpriseopsgymenvironmentsevaluationsstateful, title={EnterpriseOps-Gym: Environments and Evaluations for Stateful Agentic Planning and Tool Use in Enterprise Settings}, author={Shiva Krishna Reddy Malay and Shravan Nayak and Jishnu Sethumadhavan Nair and Sagar Davasam and Aman Tiwari and Sathwik Tejaswi Madhusudhan and Sridhar Krishna Nemala and Srinivas Sunkara and Sai Rajeswar}, year={2026}, eprint={2603.13594}, archivePrefix={arXiv}, primaryClass={cs.AI}, url={https://arxiv.org/abs/2603.13594}, } ```