# Stable Audio 3
**A state-of-the-art open platform for fast, high-quality generated audio and music.**
[Technical Report](https://arxiv.org/abs/2605.17991) · [🤗 Models](https://huggingface.co/collections/stabilityai/stable-audio-3) · [🤗 Extra Models](https://huggingface.co/collections/stabilityai/stable-audio-3-extra) · [Discord](https://discord.gg/7QM7mtY9uH) · [Demo](https://huggingface.co/spaces/stabilityai/stable-audio-3) · [Blog Post](https://stability.ai/news-updates/meet-stable-audio-3-the-model-family-built-for-artistic-experimentation-with-open-weight-models)
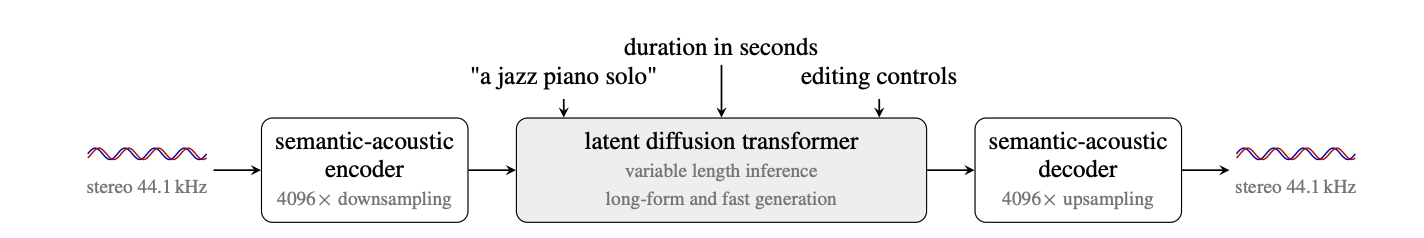
Stable Audio 3 is the next generation of Stable Audio: a focused, streamlined platform for inference and fine-tuning, built on lessons from [stable-audio-tools](https://github.com/Stability-AI/stable-audio-tools). If you're doing foundational research or working with previous Stable Audio models, that repo is still the place to go.
---
## Models
| Model | Model ID | Autoencoder | Hardware | Params | Max length | Use case |
|---|---|---|---|---|---|---|
| [**Stable Audio 3 Small-Music**](https://huggingface.co/stabilityai/stable-audio-3-small-music) | `small-music` | SAME-Small | CPU | 433M | 120s | Lightweight music-only inference, no GPU required |
| [**Stable Audio 3 Small-SFX**](https://huggingface.co/stabilityai/stable-audio-3-small-sfx) | `small-sfx` | SAME-Small | CPU | 433M | 120s | Lightweight sound effects-only inference, no GPU required |
| [**Stable Audio 3 Medium**](https://huggingface.co/stabilityai/stable-audio-3-medium) | `medium` | SAME-Large | GPU (CUDA) | 1.4B | 380s | High Quality, Fast Inference |
| **Stable Audio 3 Large** | — | SAME-Large | API only | 2.7B | 380s | Highest quality, API only. Not supported by this repo, see the [API docs](https://platform.stability.ai/docs/api-reference#tag/Stable-Audio) |
Base (un-post-trained) checkpoints, the SAME autoencoders, and optimized variants are available in the [Extra Models collection](https://huggingface.co/collections/stabilityai/stable-audio-3-extra).
### Performance
| Model | Duration | H200 | H200 + TensorRT | Mac CPU* | Mac CoreML | Peak VRAM† |
|---|---|---|---|---|---|---|
| `small` | 5s | 0.41s | 0.017s | 0.70s | 0.23s | 1.69 GB |
| `small` | 30s | 0.46s | 0.022s | 1.72s | 0.63s | 1.89 GB |
| `small` | 120s | 0.45s | 0.044s | 5.92s | 3.09s | 2.40 GB |
| `medium` | 5s | 0.60s | 0.02s | – | – | 5.07 GB |
| `medium` | 30s | 0.65s | 0.05s | – | – | 5.49 GB |
| `medium` | 120s | 0.78s | 0.13s | – | – | 6.49 GB |
| `medium` | 380s | 1.31s | 0.43s | – | – | 6.52 GB |
\* CPU-only via CoreML (Diffusion Transformer) + TFLite (SAME-S decoder)
† Peak allocated VRAM on H200, unchunked decode. Chunked decoding reduces this — e.g. `medium` at 120s drops from 6.49 GB to ~5.14 GB.
---
## Features
- ⚡ **Fast, state-of-the-art generation** - Generate minutes of audio in milliseconds
- 🎛️ **Three inference modes** — text-to-audio, audio-to-audio editing, and inpainting/continuation
- ↔️ **Variable-length generation** — handles generation of a variety of sequences without wasting inference time and VRAM on unused latents
- 🎯 **Personalization through LoRA fine-tuning** — adapt any model to a target style; stackable, adjustable at runtime
- 💻 **Broad hardware support** — CPU (Small), CUDA/TensorRT (Medium), Apple Silicon via CoreML, Others coming soon
- 🎵 **SAME autoencoder** — new Semantic-Acoustic Music Encoder; stereo, 44.1 kHz, 256-dimensional latents optimized for both generative tractability and high-quality reconstruction
## Installation
Stable Audio 3 uses [uv](https://github.com/astral-sh/uv) for fast, lightweight installs. Install only what you need.
```bash
# Base install (Python API only)
uv sync
# With Gradio UI
uv sync --extra ui
# With LoRA training support
uv sync --extra lora
# Everything
uv sync --extra ui --extra lora
```
### CUDA Version
By default, `uv sync` installs PyTorch built against CUDA 12.6. If you need a different CUDA version, install torch and torchaudio manually first (pinning the same version as `pyproject.toml`), then sync without reinstalling them, for example:
```bash
uv pip install torch==2.7.1 torchaudio==2.7.1 --index-url https://download.pytorch.org/whl/cu118
uv sync --no-install-package torch --no-install-package torchaudio
```
Replace `cu118` with your target version. For torch 2.7.1, available CUDA variants are `cu118`, `cu126`, and `cu128`. Not all versions are published for every CUDA channel — check the [PyTorch install page](https://pytorch.org/get-started/locally/) to confirm your target is available.
### Flash Attention
Stable Audio 3 Medium requires [Flash Attention 2](https://github.com/Dao-AILab/flash-attention).
**Install from a pre-built wheel** (fast, no compilation). The easiest source is the [flash-attention-prebuild-wheels](https://github.com/mjun0812/flash-attention-prebuild-wheels) community repo — browse the releases for a wheel matching your CUDA, PyTorch, and Python versions, then install it directly:
```bash
uv pip install https://github.com/mjun0812/flash-attention-prebuild-wheels/releases/download/v0.7.16/flash_attn-2.6.3+cu126torch2.7-cp310-cp310-linux_x86_64.whl
```
The filename encodes the requirements — `cu126` is CUDA 12.6, `torch2.7` is PyTorch 2.7, `cp310` is Python 3.10. Pick the URL that matches your environment.
If no pre-built wheel matches your setup, build from source. Install `ninja` first to speed up the C++ compile, then set the environment variables for your machine:
```bash
uv pip install ninja
.venv/bin/python -m ensurepip
FLASH_ATTENTION_SKIP_CUDA_BUILD=FALSE \
FLASH_ATTENTION_FORCE_BUILD=TRUE \
TORCH_CUDA_ARCH_LIST="9.0" \
MAX_JOBS=8 \
.venv/bin/pip3 install flash-attn --no-build-isolation --no-binary flash-attn \
--force-reinstall --no-cache-dir --no-deps
```
- `TORCH_CUDA_ARCH_LIST` — set to your GPU's compute capability: `8.0` (A100), `8.6` (A10/RTX 3090), `8.9` (L4/RTX 4090), `9.0` (H100/H200)
- `MAX_JOBS` — number of parallel compile jobs; 4–8 is typical, reduce if you run out of RAM during compilation
**Note:** `flash-attn` is not declared in `pyproject.toml`, so a plain `uv sync` will remove it. Use `uv sync --inexact` to install/update dependencies without removing packages that aren't in the lockfile:
```bash
uv sync --inexact
```
## Quick Start
Launch the Gradio UI:
```bash
uv run python run_gradio.py --model medium
```
This starts a local web interface with a shareable link. To load a LoRA checkpoint:
```bash
uv run python run_gradio.py --model medium --lora-ckpt-path path/to/lora.ckpt
```
## Usage
Stable Audio 3 supports several inference modes. For full details, see [Inference Methods](docs/workflows/inference.md).
**Text-to-Audio** — Generate audio from a text prompt:
```python
from stable_audio_3 import StableAudioModel
model = StableAudioModel.from_pretrained("medium")
audio = model.generate(
prompt="House music that encapsulates the feeling of being at a festival in the sunny weather with all your friends 124 BPM",
duration=250,
)
```
**Audio-to-Audio** — Edit an existing recording using a prompt to steer style and mood:
```python
import torchaudio
from stable_audio_3 import StableAudioModel
model = StableAudioModel.from_pretrained("medium")
init_audio = torchaudio.load("/path/to/audio.wav")
audio = model.generate(
init_audio=init_audio,
init_noise_level=0.9,
prompt="bossa nova bassline",
duration=30,
)
```
**Inpainting / Continuation** — Regenerate a specific region of an audio file while keeping the rest intact:
```python
import torchaudio
from stable_audio_3 import StableAudioModel
model = StableAudioModel.from_pretrained("medium")
inpaint_audio = torchaudio.load("/path/to/audio.wav")
audio = model.generate(
inpaint_audio=inpaint_audio,
inpaint_mask_start_seconds=4.0,
inpaint_mask_end_seconds=8.0,
prompt="punchy kick drum fill",
duration=30,
)
```
To regenerate **multiple non-contiguous regions** in one pass, pass lists to both mask parameters:
```python
audio = model.generate(
inpaint_audio=inpaint_audio,
inpaint_mask_start_seconds=[4.0, 16.0],
inpaint_mask_end_seconds=[8.0, 20.0],
prompt="punchy kick drum fill",
duration=30,
)
```
To extend an audio clip (continuation), set `inpaint_mask_start_seconds` to the length of the source file and choose a longer `duration`. See [Inference Methods](docs/workflows/inference.md) for the full controls reference.
**Encoding / Decoding** — Use the autoencoder directly to encode audio to latents or decode latents back to audio:
```python
import torchaudio
from stable_audio_3 import AutoencoderModel
ae = AutoencoderModel.from_pretrained("same-l")
waveform, sr = torchaudio.load("audio.wav")
latents = ae.encode(waveform, sr)
audio_out = ae.decode(latents)
```
See [Autoencoder Workflows](docs/workflows/autoencoder.md) for encoding batches, chunked processing, and pre-encoding datasets for LoRA training.
## CLI
A `stable-audio` cli is included for running generation without writing any Python.
**Text-to-audio:**
```bash
stable-audio --model small-music -p "lo-fi hip hop beat, 90 BPM" --duration 30 -o beat.wav
```
**Audio-to-audio** — restyle an existing recording:
```bash
stable-audio -p "bossa nova bassline" --init-audio input.wav --init-noise-level 0.8 -o out.wav
```
**Inpainting** — regenerate a region while keeping the rest:
```bash
stable-audio -p "punchy kick drum fill" --inpaint-audio input.wav --inpaint-start 4 --inpaint-end 8 -o out.wav
```
**Continuation** — extend a clip beyond its original length:
```bash
stable-audio -p "dreamy synth outro" --inpaint-audio input.wav --inpaint-start 10 --inpaint-end 30 --duration 30 -o out.wav
```
**With a LoRA:**
```bash
stable-audio -p "orchestral strings" --lora-ckpt-path my_lora.safetensors --lora-strength 0.8 -o out.wav
```
Run `stable-audio --help` for the full list of flags.
## Hardware Support
Stable Audio 3 scales from a laptop to a GPU server.
Optimized inference runtimes are available under [optimized/](optimized) — pick by platform:
| Route | Platforms | Backend | One-liner |
|---|---|---|---|
| [optimized/tflite](optimized/tflite) | **macOS / Linux / Windows**, x86 & ARM | CPU (LiteRT/XNNPACK) | `curl -LsSf https://raw.githubusercontent.com/Stability-AI/stable-audio-3/main/optimized/tflite/bootstrap.sh \| bash`
Windows: `irm https://raw.githubusercontent.com/Stability-AI/stable-audio-3/main/optimized/tflite/bootstrap.ps1 \| iex`
*(the curl\|bash line needs Git Bash or WSL on Windows — stock Windows has no bash)* |
| [optimized/mlx](optimized/mlx) | Apple Silicon Macs | Metal GPU (MLX) | `curl -LsSf https://raw.githubusercontent.com/Stability-AI/stable-audio-3/main/optimized/mlx/bootstrap.sh \| bash` |
| [optimized/tensorRT](optimized/tensorRT) | Linux + NVIDIA GPU | CUDA/TensorRT | `curl -LsSf https://raw.githubusercontent.com/Stability-AI/stable-audio-3/main/optimized/tensorRT/bootstrap.sh \| bash` |
Beyond inference, **[optimized/mlx](optimized/mlx)** and **[optimized/tflite](optimized/tflite)** each ship a **web UI** (`./sa3-gradio`), and **optimized/mlx** also does **LoRA training** on Apple Silicon (pure-MLX, no PyTorch) — see its [LoRA training](optimized/mlx/README.md#lora-training) section, or [underfit](https://github.com/dada-bots/underfit) for a full training dashboard built on it.
## Docs
| Guide | Description |
|-------|-------------|
| [Inference Methods](docs/workflows/inference.md) | Overview of inference modes (text-to-audio, inpainting, etc.) |
| [MLX LoRA training](optimized/mlx/README.md#lora-training) | Finetune on Apple Silicon (pure-MLX); powers underfit's Mac backend |
| [LoRA Training](docs/workflows/lora.md) | Fine-tune with LoRA: setup, training loop, and checkpointing |
| [Autoencoder Workflows](docs/workflows/autoencoder.md) | Encode and decode audio with the VAE directly |
| [Prompting Guide](docs/guides/prompting.md) | Prompt and control signal reference |
| [Model Overview](docs/guides/model-overview.md) | Architecture and design overview |
| [TFLite inference](optimized/tflite/README.md) | Portable CPU inference — macOS / Linux / Windows, x86 & ARM |
| [MLX inference](optimized/mlx/README.md) | Optimized MLX inference for M-series Mac |
| [TensorRT inference](optimized/tensorRT/README.md) | Optimized TensorRT inference for Nvidia GPUs |
---
## Community
- [Harmonai Discord](https://discord.gg/7QM7mtY9uH): Check out our Harmonai Discord server run by the research team. Besides good discussions, we host weekly office hours talking all things AI audio and music and want to hear what you come up with!
- [Underfit](https://github.com/dada-bots/underfit): A LoRA training poweruser dream from Dadabots. If LoRA training in this repo is not enough, check out some experimental tools there like agentic LoRA orchestrations and monitoring.
- [Awesome Stable Audio](https://github.com/Stability-AI/Awesome-Stable-Audio): Curated list of all community-built Stable Audio projects. Includes links to ComfyUI, Fal, as well as a growing list of community integrations and extensions.
---
## Troubleshooting
#### Output audio is a static glitch sound (affects Stable Audio 3 Medium-only)
Likely an issue with flash-attention. Verify it is importable:
```bash
uv run python -c "import flash_attn; from flash_attn import flash_attn_func; print('Version:', flash_attn.__version__, '| flash_attn_func:', flash_attn_func)"
```
If this errors, flash-attn is not installed correctly — see the [Flash Attention install instructions](#flash-attention) above.
---
## License
Please refer to the [Stability AI Community License](https://stability.ai/license)
## Testing
Install dev dependencies:
```bash
uv sync --group dev
```
Run the test suite:
```bash
uv run pytest
```
Save generated audio outputs to `test_audio_outputs/` for manual inspection:
```bash
uv run pytest --save-audio
```
## Citation
For Stable Audio 3, please cite
```BibTeX
@misc{evans2026stableaudio3,
title={Stable Audio 3},
author={Zach Evans and Julian D. Parker and Matthew Rice and CJ Carr and Zack Zukowski and Josiah Taylor and Jordi Pons},
year={2026},
eprint={2605.17991},
archivePrefix={arXiv},
primaryClass={cs.SD},
url={https://arxiv.org/abs/2605.17991}
}
```
For SAME, please cite
```BibTeX
@misc{parker2026SAME,
title={SAME: A Semantically-Aligned Music Autoencoder},
author={Julian D. Parker and Zach Evans and CJ Carr and Zack Zukowski and Josiah Taylor and Matthew Rice and Jordi Pons},
year={2026},
eprint={2605.18613},
archivePrefix={arXiv},
primaryClass={cs.SD},
url={https://arxiv.org/abs/2605.18613}
}
```