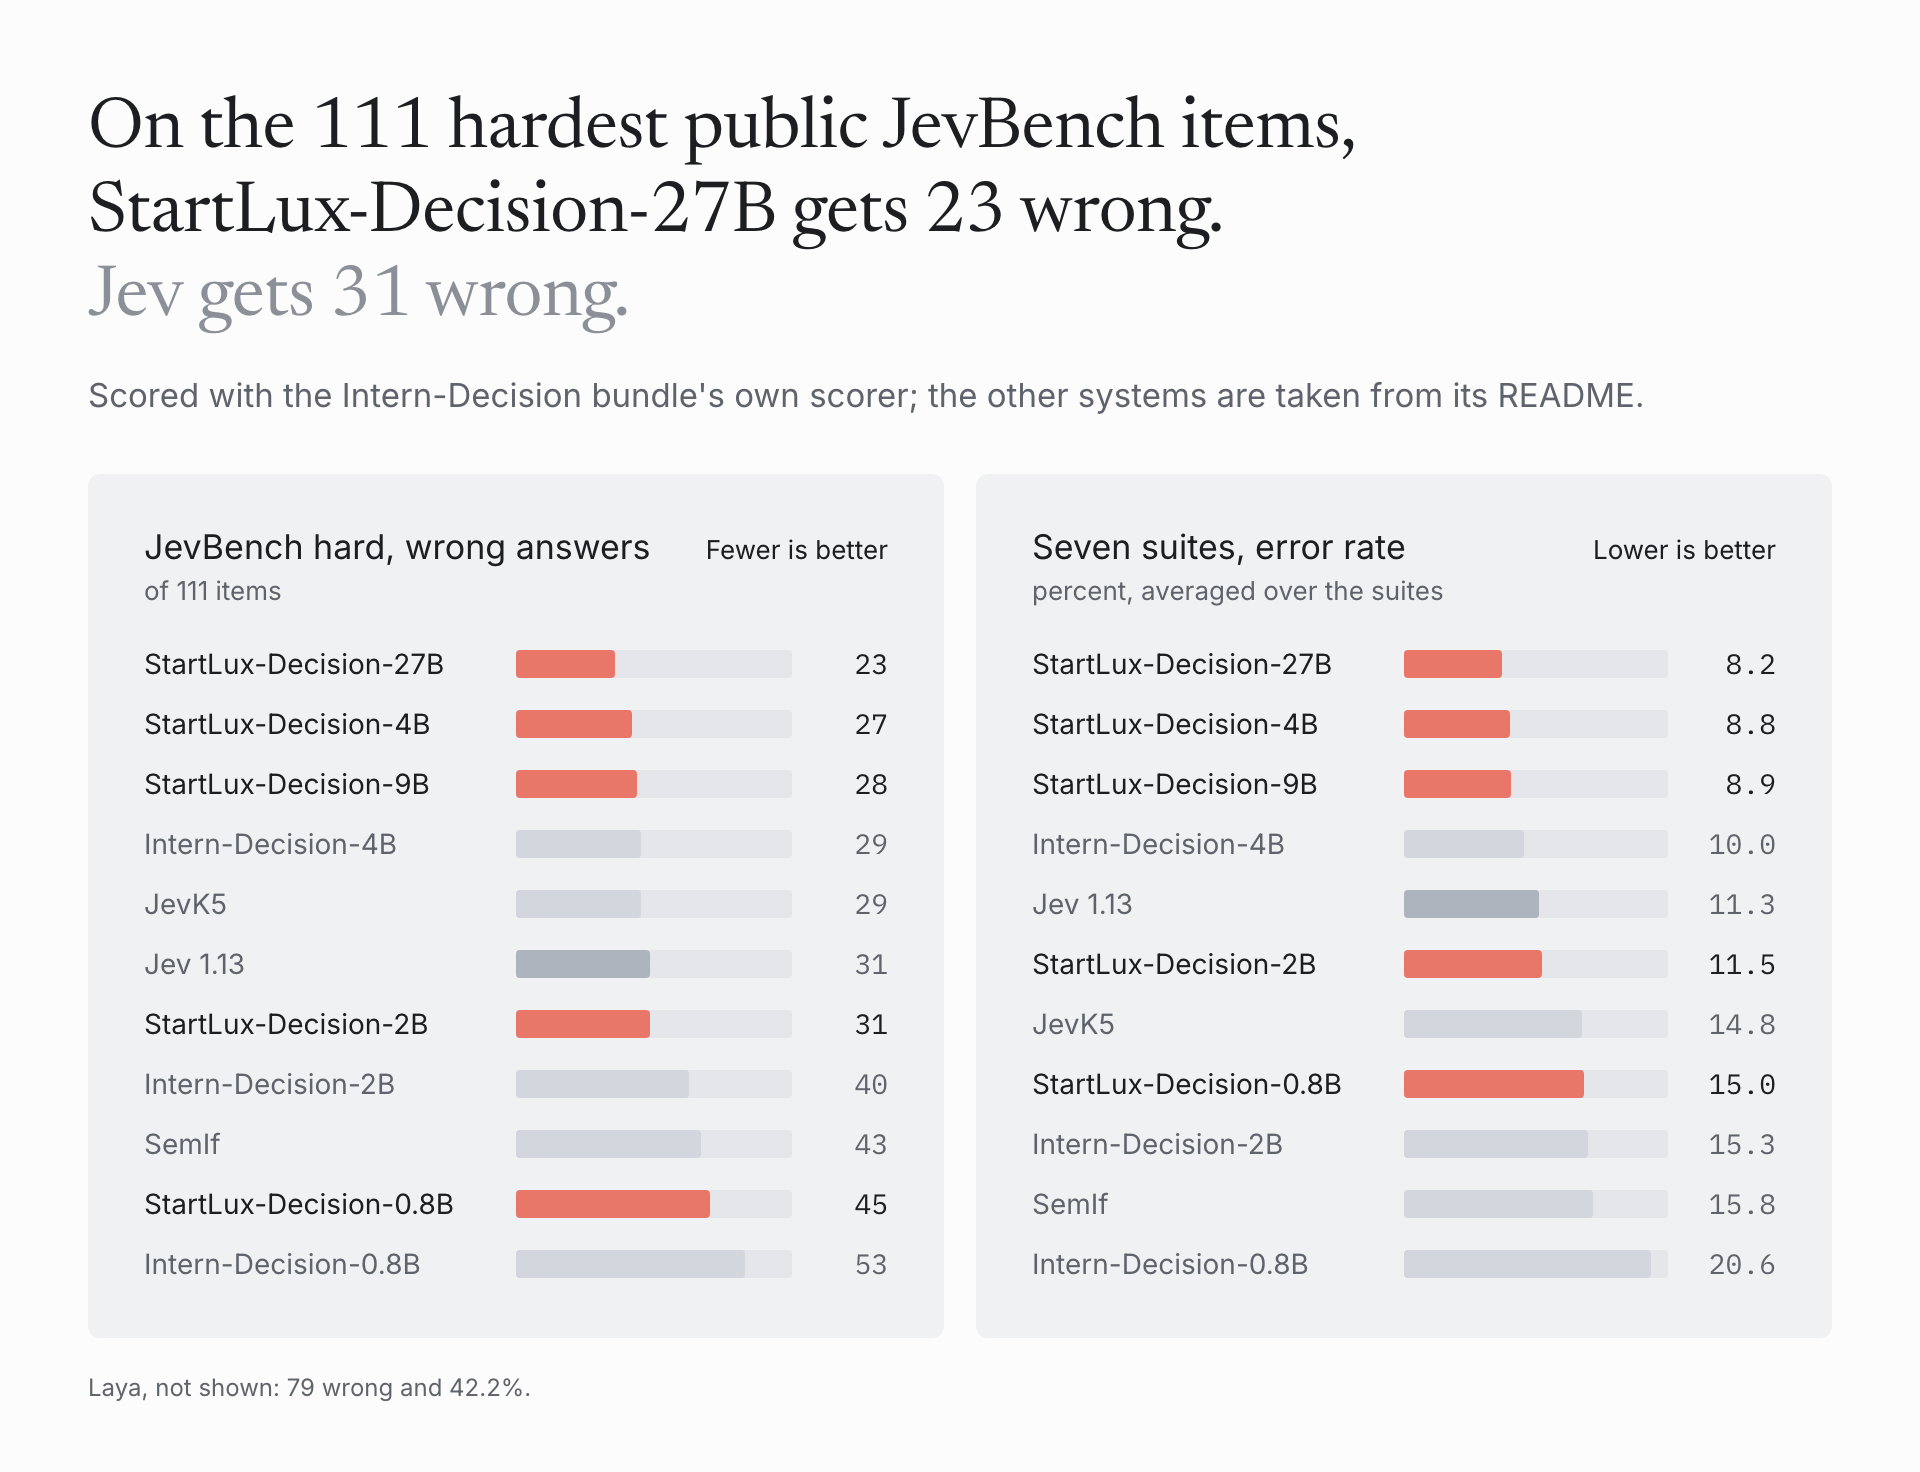
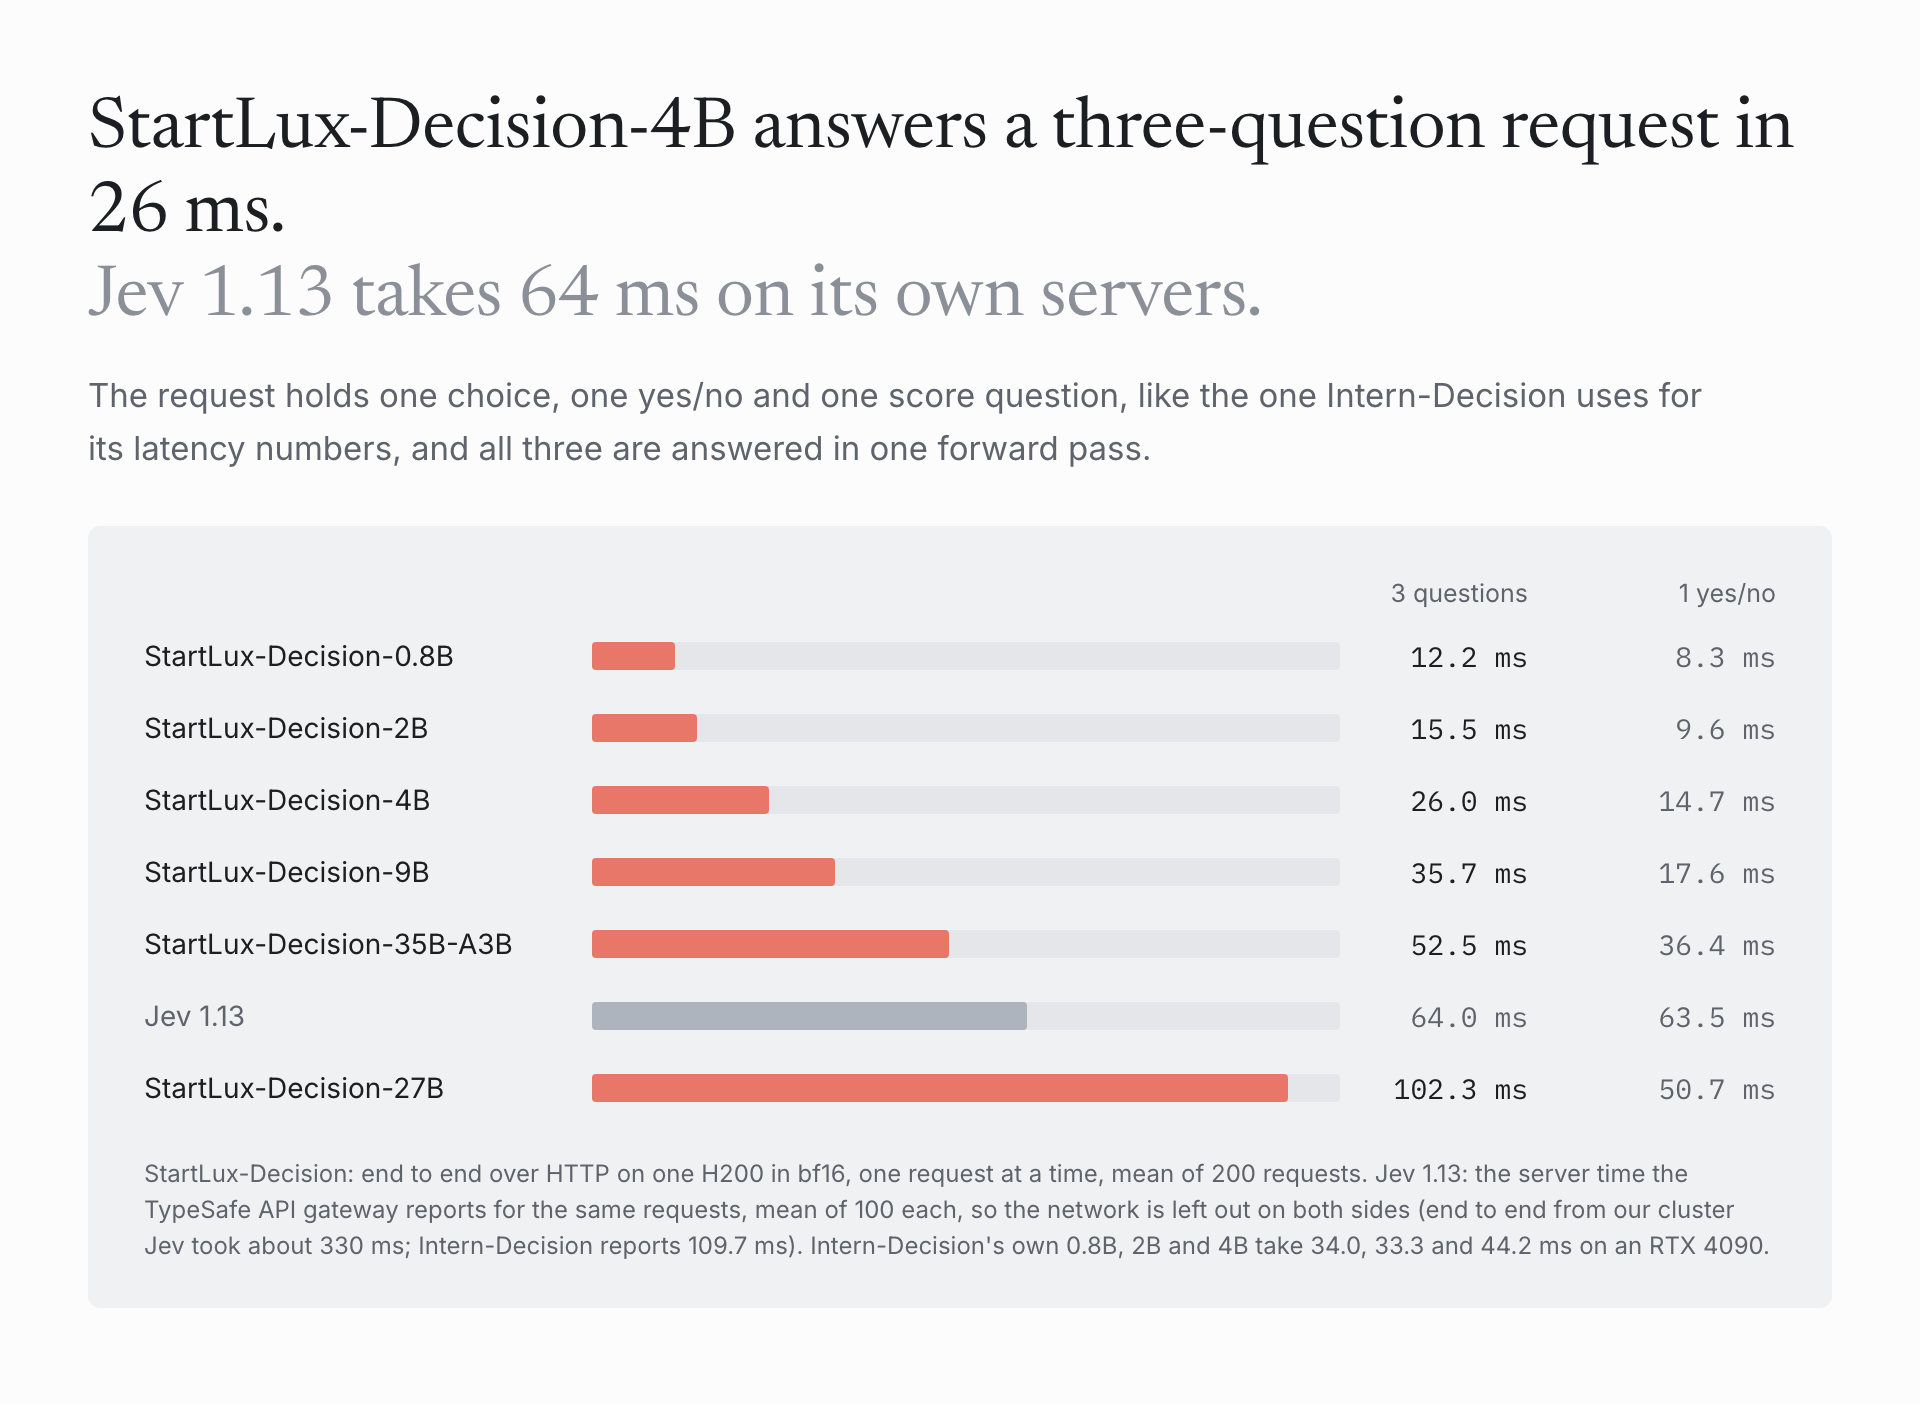
-GGUF`, linked from the table below, and the same repository on
ModelScope under `StartLuxAI/`. The decision procedure is not
in the weights; `python -m startlux_decision.gguf_server` runs it in front of llama-server (see
[docs/inference.md](docs/inference.md#gguf-and-llamacpp)). Against the original weights on the 231 public JevBench items:
| File | Size | Same decision as the original | JevBench public, of 231 |
|:---:|:---:|:---:|:---:|
| StartLux-Decision-0.8B, original weights | | | 177 (76.6%) |
| [`StartLux-Decision-0.8B-BF16.gguf`](https://huggingface.co/startlux-models/StartLux-Decision-0.8B-BF16-GGUF) | 1.52 GB | 99.6% | 178 (77.1%) |
| [`StartLux-Decision-0.8B-Q8_0.gguf`](https://huggingface.co/startlux-models/StartLux-Decision-0.8B-Q8_0-GGUF) | 0.81 GB | 100.0% | 177 (76.6%) |
| [`StartLux-Decision-0.8B-Q4_K_M.gguf`](https://huggingface.co/startlux-models/StartLux-Decision-0.8B-Q4_K_M-GGUF) | 0.53 GB | 93.1% | 172 (74.5%) |
| StartLux-Decision-2B, original weights | | | 195 (84.4%) |
| [`StartLux-Decision-2B-BF16.gguf`](https://huggingface.co/startlux-models/StartLux-Decision-2B-BF16-GGUF) | 3.78 GB | 100.0% | 195 (84.4%) |
| [`StartLux-Decision-2B-Q8_0.gguf`](https://huggingface.co/startlux-models/StartLux-Decision-2B-Q8_0-GGUF) | 2.01 GB | 99.1% | 193 (83.5%) |
| [`StartLux-Decision-2B-Q4_K_M.gguf`](https://huggingface.co/startlux-models/StartLux-Decision-2B-Q4_K_M-GGUF) | 1.27 GB | 94.4% | 199 (86.1%) |
| StartLux-Decision-4B, original weights | | | 204 (88.3%) |
| [`StartLux-Decision-4B-BF16.gguf`](https://huggingface.co/startlux-models/StartLux-Decision-4B-BF16-GGUF) | 8.42 GB | 100.0% | 204 (88.3%) |
| [`StartLux-Decision-4B-Q8_0.gguf`](https://huggingface.co/startlux-models/StartLux-Decision-4B-Q8_0-GGUF) | 4.48 GB | 100.0% | 204 (88.3%) |
| [`StartLux-Decision-4B-Q4_K_M.gguf`](https://huggingface.co/startlux-models/StartLux-Decision-4B-Q4_K_M-GGUF) | 2.71 GB | 98.3% | 201 (87.0%) |
| StartLux-Decision-9B, original weights | | | 200 (86.6%) |
| [`StartLux-Decision-9B-BF16.gguf`](https://huggingface.co/startlux-models/StartLux-Decision-9B-BF16-GGUF) | 17.92 GB | 99.6% | 201 (87.0%) |
| [`StartLux-Decision-9B-Q8_0.gguf`](https://huggingface.co/startlux-models/StartLux-Decision-9B-Q8_0-GGUF) | 9.53 GB | 100.0% | 200 (86.6%) |
| [`StartLux-Decision-9B-Q4_K_M.gguf`](https://huggingface.co/startlux-models/StartLux-Decision-9B-Q4_K_M-GGUF) | 5.63 GB | 98.3% | 201 (87.0%) |
| StartLux-Decision-27B, original weights | | | 209 (90.5%) |
| [`StartLux-Decision-27B-BF16.gguf`](https://huggingface.co/startlux-models/StartLux-Decision-27B-BF16-GGUF) | 53.81 GB | 100.0% | 209 (90.5%) |
| [`StartLux-Decision-27B-Q8_0.gguf`](https://huggingface.co/startlux-models/StartLux-Decision-27B-Q8_0-GGUF) | 28.60 GB | 100.0% | 209 (90.5%) |
| [`StartLux-Decision-27B-Q4_K_M.gguf`](https://huggingface.co/startlux-models/StartLux-Decision-27B-Q4_K_M-GGUF) | 16.55 GB | 96.5% | 208 (90.0%) |
BF16 and Q8_0 give the original answer on 99 to 100% of the items. Q4_K_M keeps 96.5 to 98.3% from 4B up; at 0.8B and
2B it changes more answers, so Q8_0 is the better choice there. The original rows are the same weights run through this
repository's package on the same machine; they differ from the tables above by one or two items of bf16 rounding.
StartLux-Decision-35B-A3B is not available as GGUF yet.
To run one, download its repository (the GGUF file plus the small files the decision server needs), then start
llama.cpp and the server (for another precision, replace `Q8_0`):
```bash
hf download startlux-models/StartLux-Decision-4B-Q8_0-GGUF --local-dir StartLux-Decision-4B-Q8_0-GGUF
cd StartLux-Decision-4B-Q8_0-GGUF && pip install -r requirements.txt
llama-server -m StartLux-Decision-4B-Q8_0.gguf -ngl 99 -c 16384 --parallel 4 --port 8081 &
python -m startlux_decision.gguf_server --model-dir . --llama http://127.0.0.1:8081 --port 8090
```
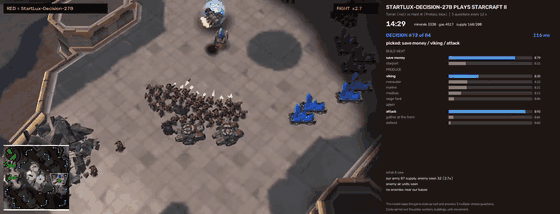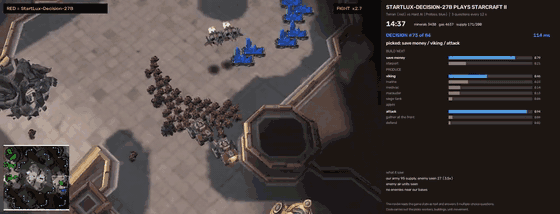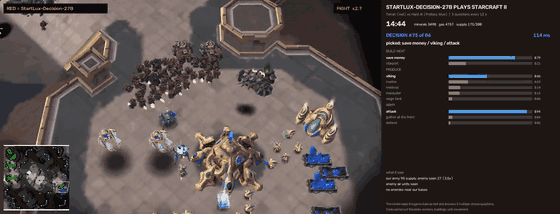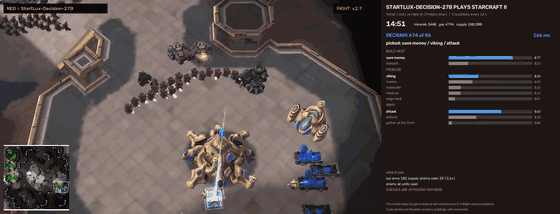
## Games
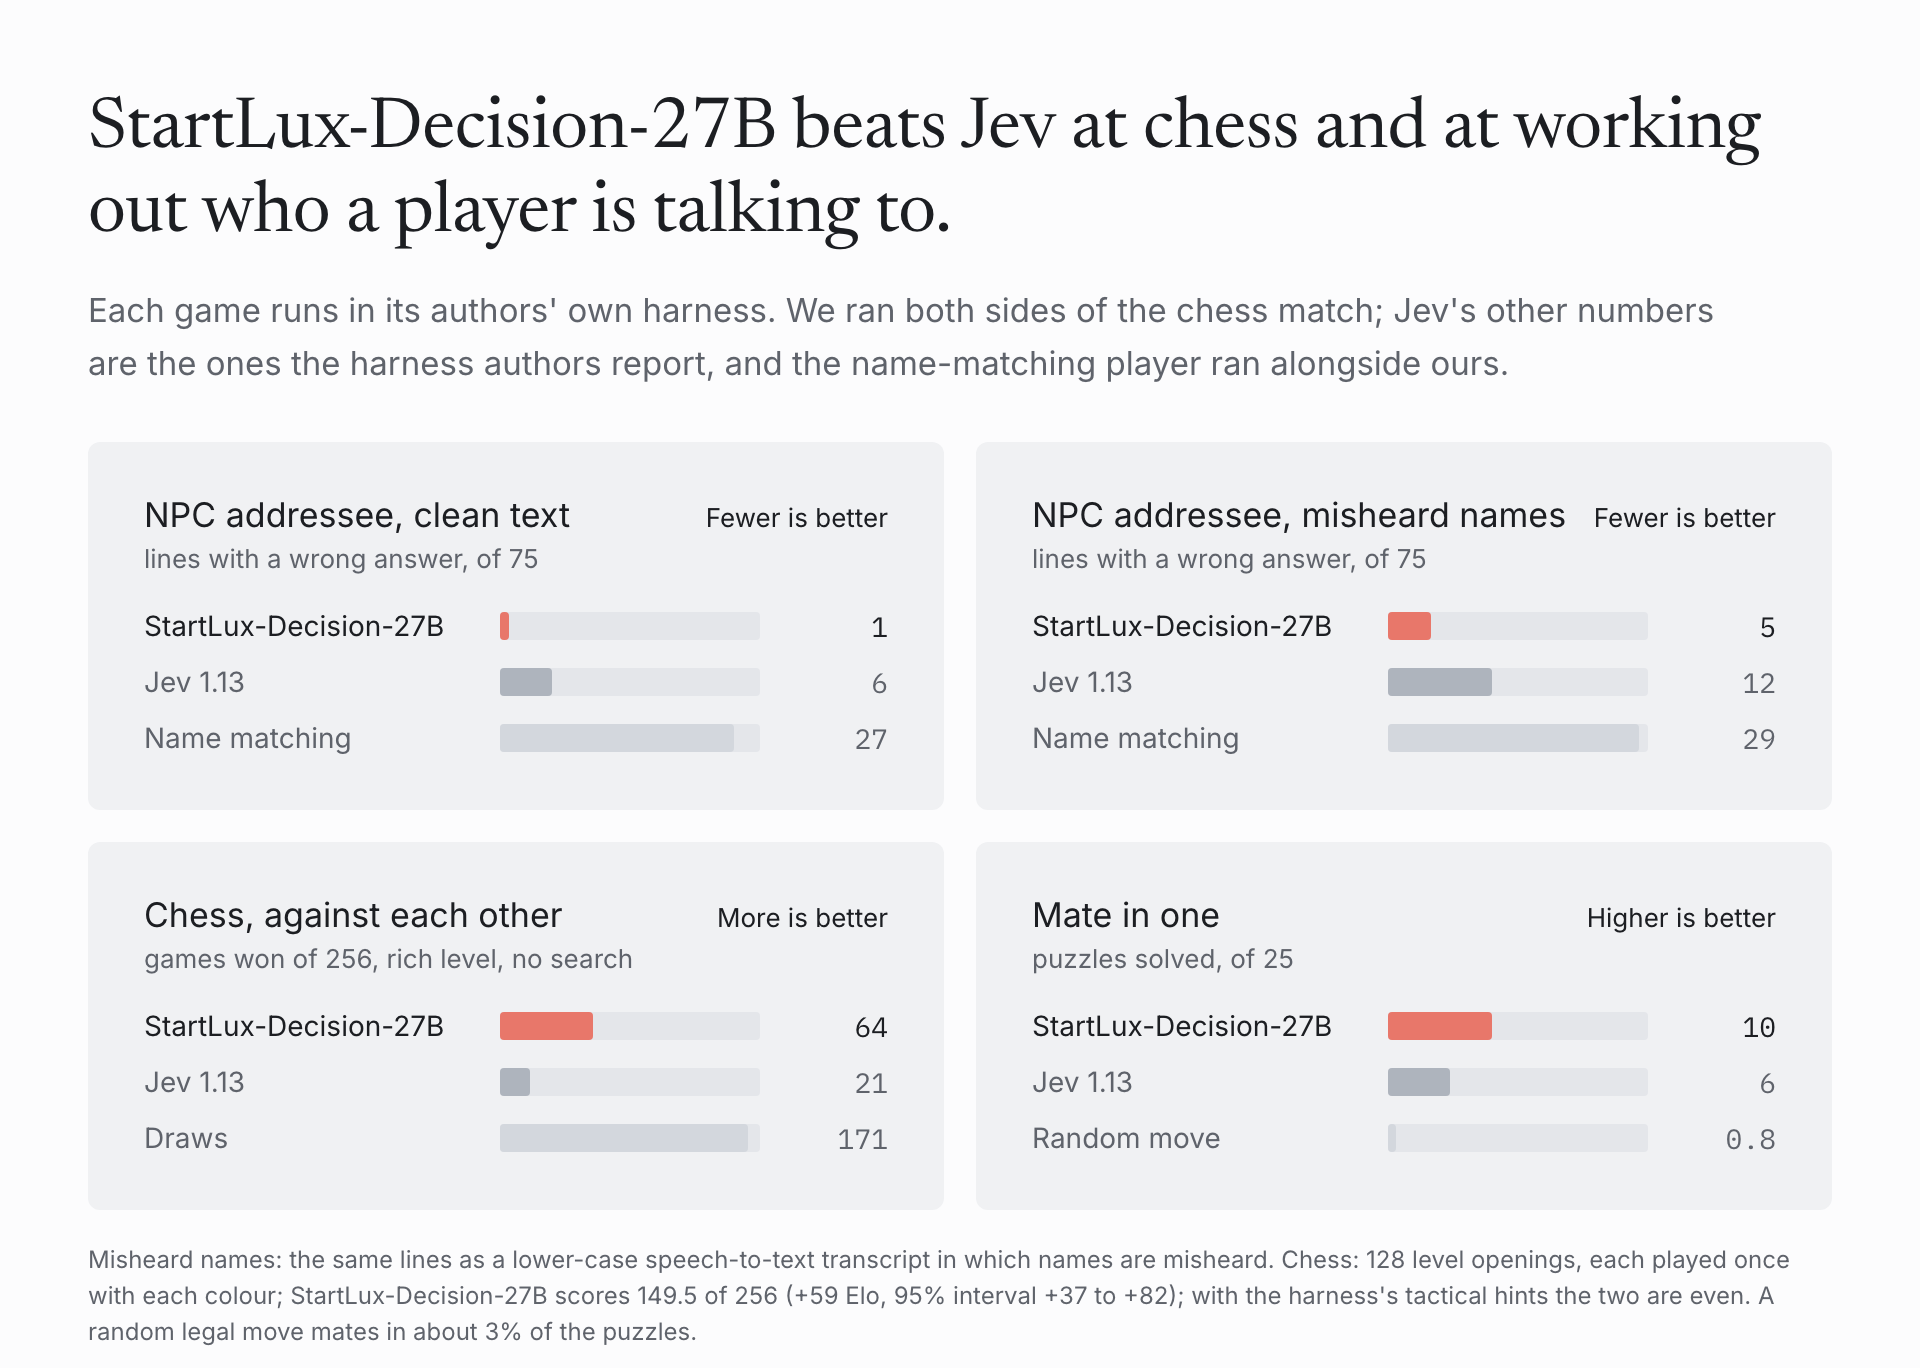
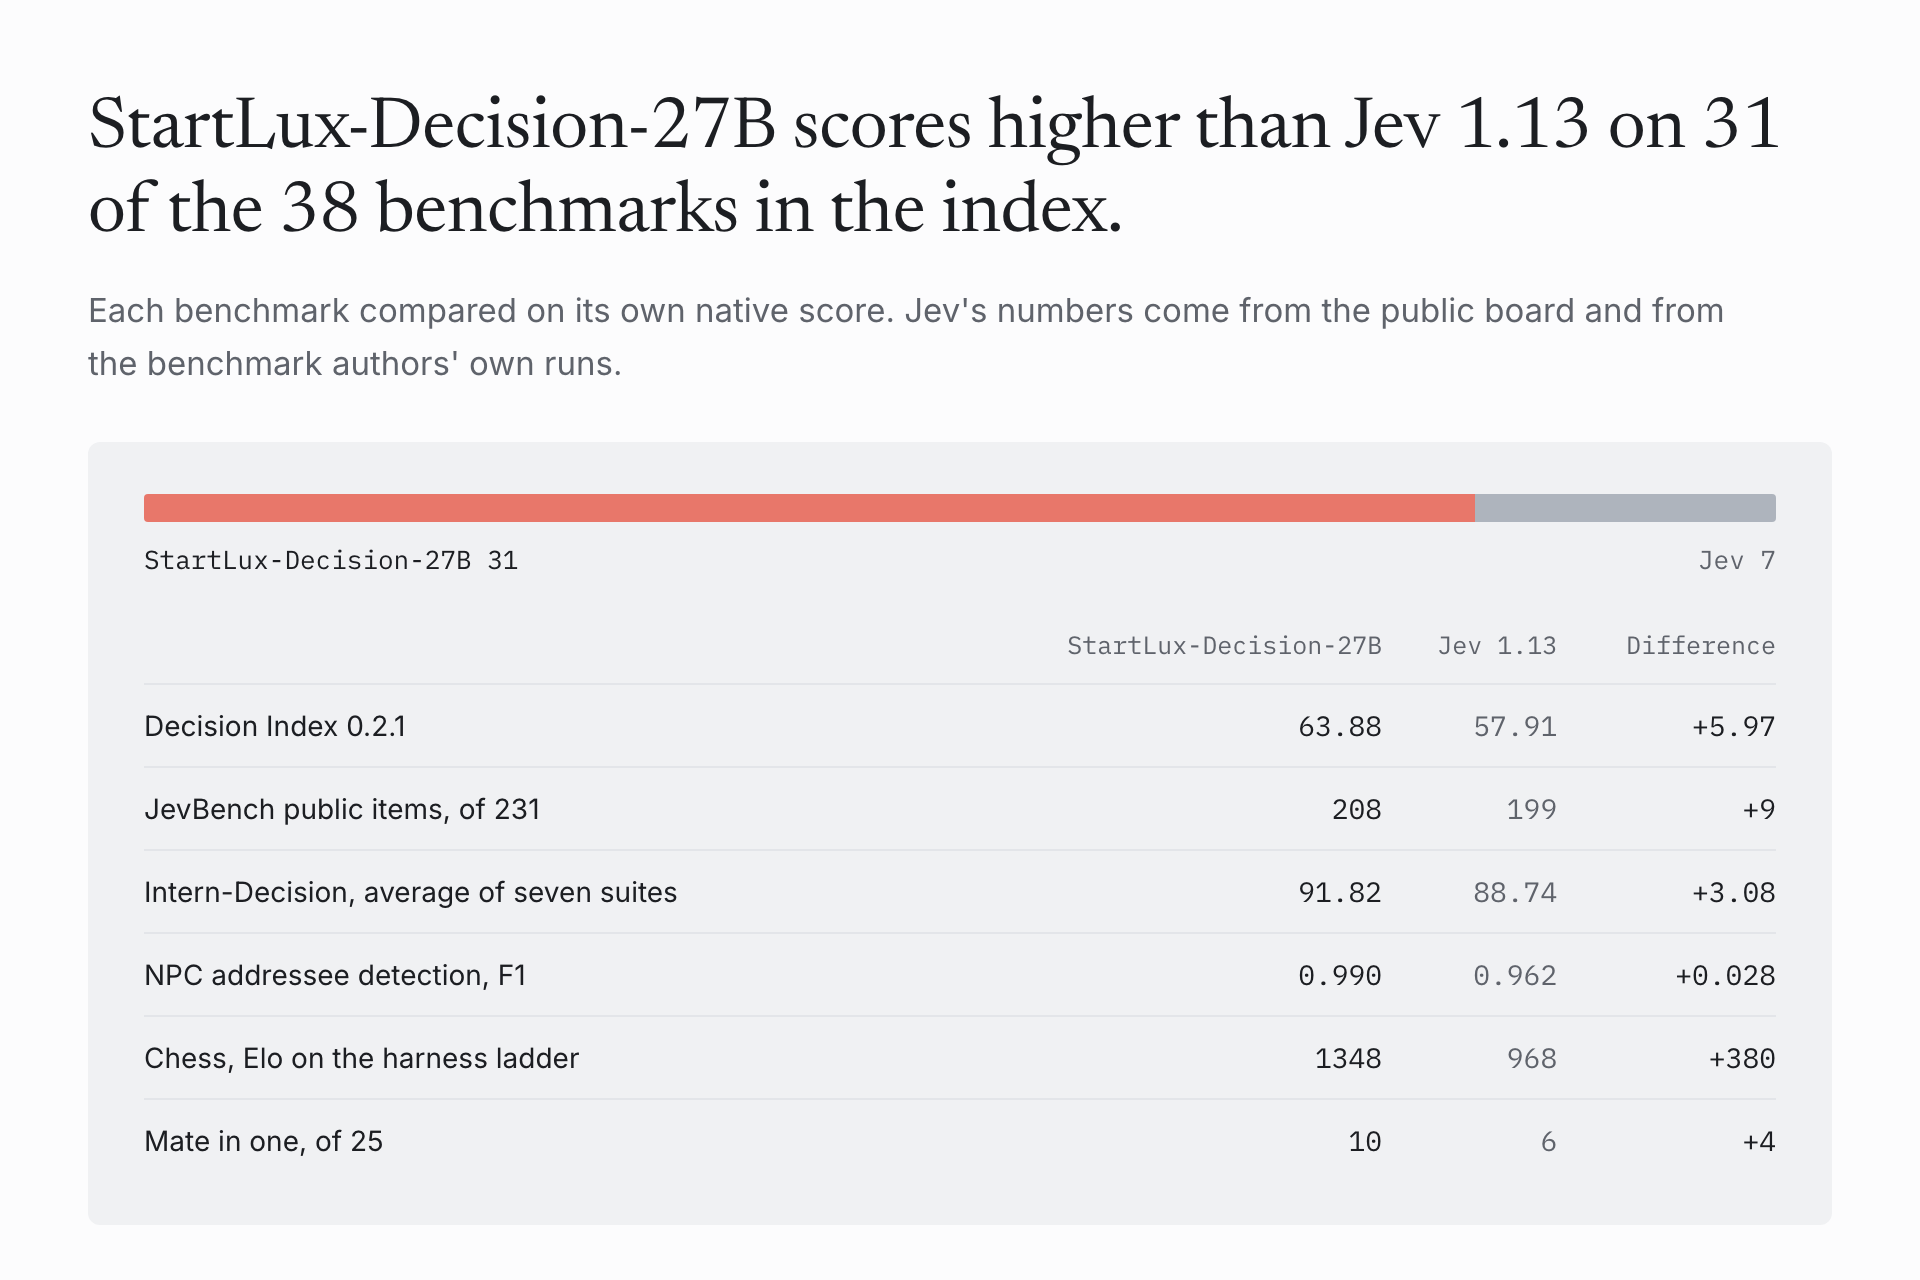
| Game | Measure | StartLux-Decision-27B | Jev 1.13 | Other reference |
|:---:|:---:|:---:|:---:|:---:|
| NPC addressee detection, clean text | lines with a wrong answer, of 75 (fewer is better) | 1 | 6 | name matching: 27 |
| NPC addressee detection, misheard names | lines with a wrong answer, of 75 (fewer is better) | 5 | 12 | name matching: 29 |
| NPC addressee detection, clean text | F1 over the yes/no answers | 0.990 | 0.962 | name matching: 0.820 |
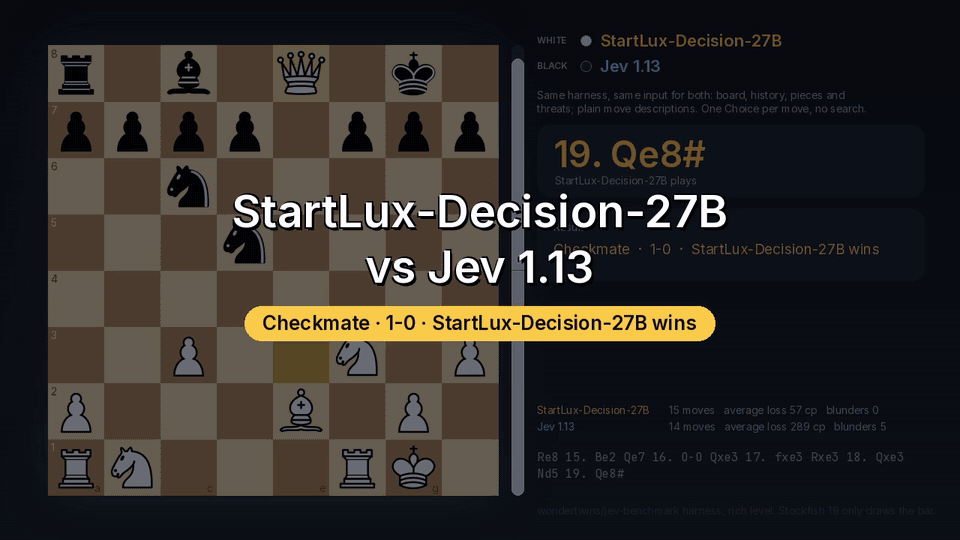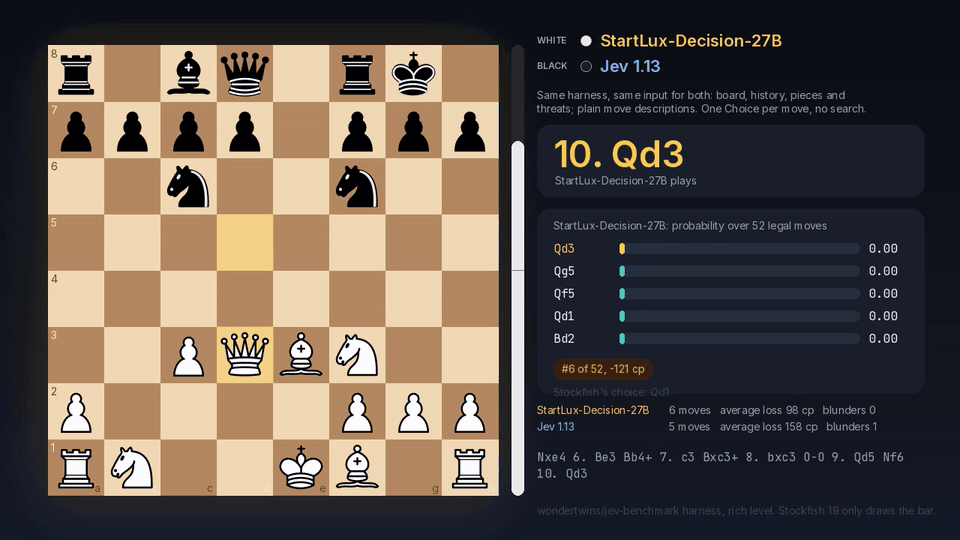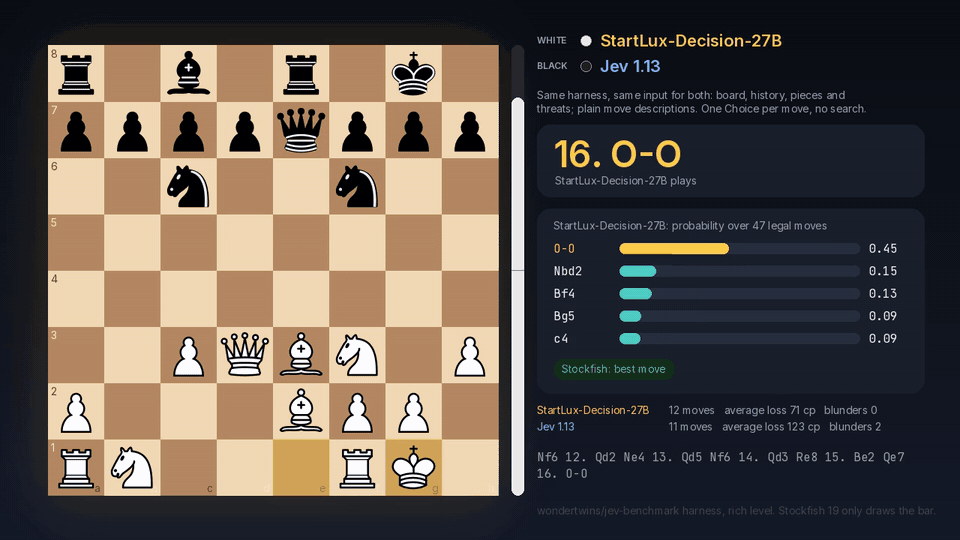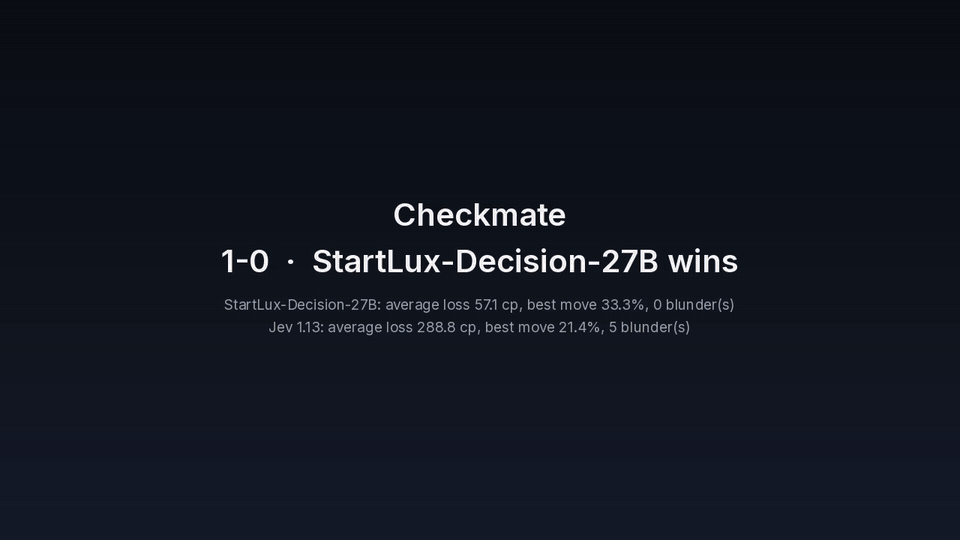
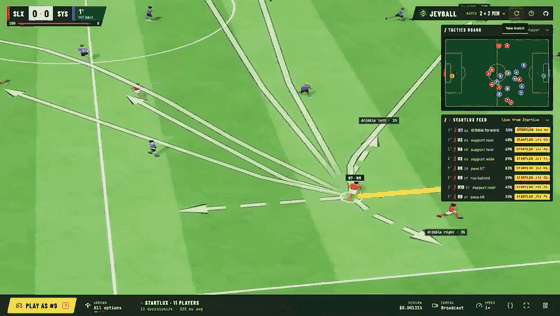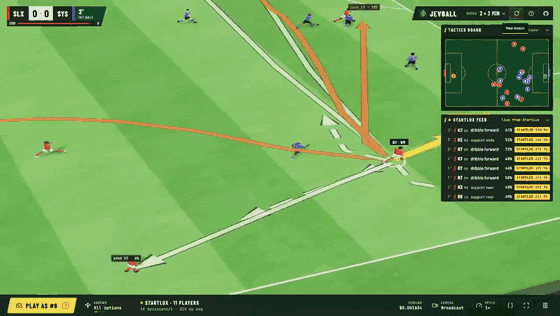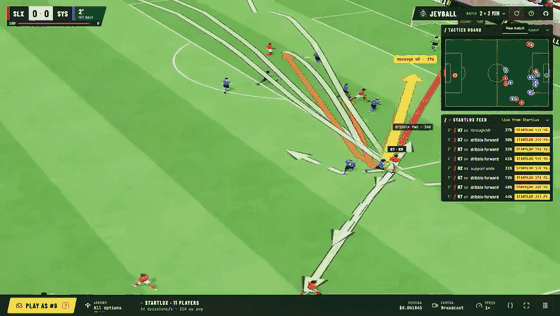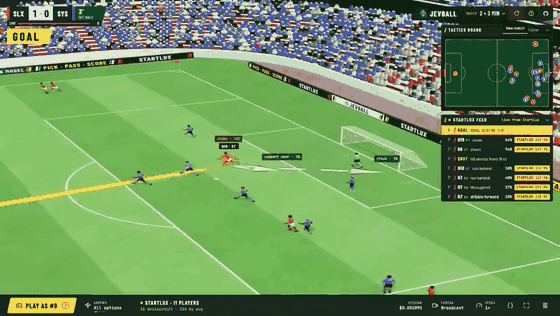
| Chess, against each other | points in 256 games at the rich level, no search | 149.5 | 106.5 | 64 wins, 171 draws, 21 losses |
| Mate in one | puzzles solved, of 25 | 10 | 6 | a random legal move: 3% |
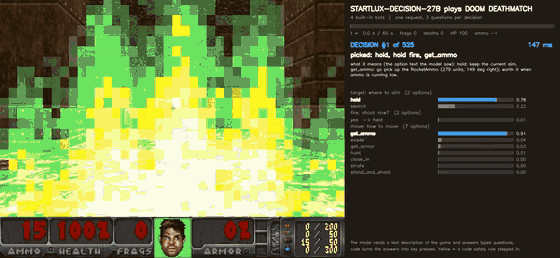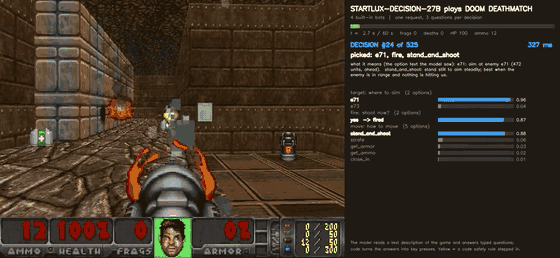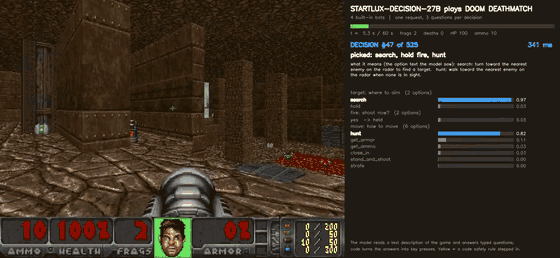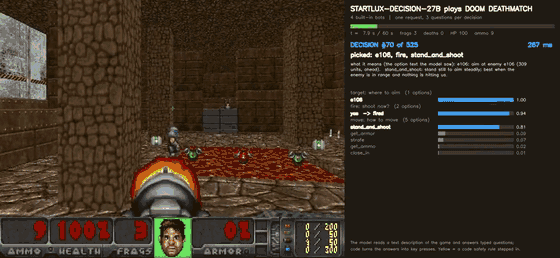
| Dino Run | runs that reach the 300-obstacle cap, of 20 | 20 | 20 | StartLux-Decision-4B and 9B: 20 |
Jev's numbers are the ones its harness authors report, except Dino Run and the chess match, which we ran for Jev
through its API in the same harness as ours. The chess match is 256 games: 128 level openings (within 0.6 pawns by
Stockfish), each played once with each colour, at the harness's default rich level. Games end by the rules or are
adjudicated at ±300 centipawns after 160 plies; since neither side searches, most draws are fivefold repetitions.
StartLux-Decision-27B scores 58.4%, +59 Elo (95% interval +37 to +82), and wins 64 of the 85 decisive games. With the
harness's tactical hints, which give both sides the one-move consequences of every move, the two are even (48.6% and
46.1% over 256 games each); all four conditions are in [docs/results.md](docs/results.md). The misheard-names variant is the same set
of lines as a lower-case speech-to-text transcript in which names are misheard.
The 0.8B and 2B models do much worse on these games. Every game, position and line is in
[results/games](results/games): Elo ladder games with PGN, chess positions and mate-in-one answers, and NPC predictions
per line in all three transcript variants.
## Quick start
The weights are on Hugging Face, as the original checkpoints for this package and as GGUF files for llama.cpp (see [GGUF](#gguf)). Each model folder also carries the inference package from this repository. Every repository is also on ModelScope, with the same name and the same files, under [StartLuxAI](https://modelscope.cn/organization/StartLuxAI): `https://modelscope.cn/models/StartLuxAI/`.
| Model | Original weights | GGUF Q8_0 (recommended) | GGUF Q4_K_M | GGUF BF16 |
|:---:|:---:|:---:|:---:|:---:|
| StartLux-Decision-0.8B | [1.8 GB](https://huggingface.co/startlux-models/StartLux-Decision-0.8B) | [0.81 GB](https://huggingface.co/startlux-models/StartLux-Decision-0.8B-Q8_0-GGUF) | [0.53 GB](https://huggingface.co/startlux-models/StartLux-Decision-0.8B-Q4_K_M-GGUF) | [1.52 GB](https://huggingface.co/startlux-models/StartLux-Decision-0.8B-BF16-GGUF) |
| StartLux-Decision-2B | [4.6 GB](https://huggingface.co/startlux-models/StartLux-Decision-2B) | [2.01 GB](https://huggingface.co/startlux-models/StartLux-Decision-2B-Q8_0-GGUF) | [1.27 GB](https://huggingface.co/startlux-models/StartLux-Decision-2B-Q4_K_M-GGUF) | [3.78 GB](https://huggingface.co/startlux-models/StartLux-Decision-2B-BF16-GGUF) |
| StartLux-Decision-4B | [9.3 GB](https://huggingface.co/startlux-models/StartLux-Decision-4B) | [4.48 GB](https://huggingface.co/startlux-models/StartLux-Decision-4B-Q8_0-GGUF) | [2.71 GB](https://huggingface.co/startlux-models/StartLux-Decision-4B-Q4_K_M-GGUF) | [8.42 GB](https://huggingface.co/startlux-models/StartLux-Decision-4B-BF16-GGUF) |
| StartLux-Decision-9B | [19.4 GB](https://huggingface.co/startlux-models/StartLux-Decision-9B) | [9.53 GB](https://huggingface.co/startlux-models/StartLux-Decision-9B-Q8_0-GGUF) | [5.63 GB](https://huggingface.co/startlux-models/StartLux-Decision-9B-Q4_K_M-GGUF) | [17.92 GB](https://huggingface.co/startlux-models/StartLux-Decision-9B-BF16-GGUF) |
| StartLux-Decision-27B | [55.6 GB](https://huggingface.co/startlux-models/StartLux-Decision-27B) | [28.60 GB](https://huggingface.co/startlux-models/StartLux-Decision-27B-Q8_0-GGUF) | [16.55 GB](https://huggingface.co/startlux-models/StartLux-Decision-27B-Q4_K_M-GGUF) | [53.81 GB](https://huggingface.co/startlux-models/StartLux-Decision-27B-BF16-GGUF) |
```bash
hf download startlux-models/StartLux-Decision-4B --local-dir StartLux-Decision-4B
# or, from ModelScope: modelscope download StartLuxAI/StartLux-Decision-4B --local-dir StartLux-Decision-4B
pip install -r requirements.txt
python -m startlux_decision.check StartLux-Decision-4B # must print "fast kernels: active" (on a Mac: MLX)
python -m startlux_decision.server --model StartLux-Decision-4B --port 8090
```
On Apple Silicon the same commands run the model with MLX; add `--int8` on an M5 or later. See
[Apple Silicon (MLX)](docs/inference.md#apple-silicon-mlx).
```bash
curl -s localhost:8090/v1/systemone -H 'Content-Type: application/json' -d '{
"state": {"ticket": "I was charged twice for order #4411 and the app still shows it as unpaid."},
"questions": {
"team": {"type": "choice", "instructions": "Which team should handle this ticket?",
"criteria": {"billing": "Payments, refunds and invoices",
"shipping": "Delivery and tracking",
"technical": "App, login and account problems"}},
"urgent": {"type": "noul", "instructions": "Should this ticket be answered today?"},
"severity": {"type": "score", "instructions": "How severe is the impact?",
"criteria": ["cosmetic", "annoying", "blocks the customer"]}
}
}'
```
Or in Python:
```python
from startlux_decision import StartLuxDecision
m = StartLuxDecision("StartLux-Decision-4B")
answers, usage = m.decide(state, questions) # one request
many = m.decide_batch([(state, questions), ...]) # many requests, batched together
```
[docs/inference.md](docs/inference.md) covers the request format, the speed-ups and FP8.
[docs/evaluation.md](docs/evaluation.md) explains how to reproduce every number above, including the batched Decision
Index runner. [docs/finetuning.md](docs/finetuning.md) shows how to adapt a model to your own decisions.
## Layout
```
startlux_decision/ inference: prompt rendering, letter readout, CUDA graphs, long inputs, images, MLX for Apple Silicon, HTTP servers (also for GGUF), kernel check
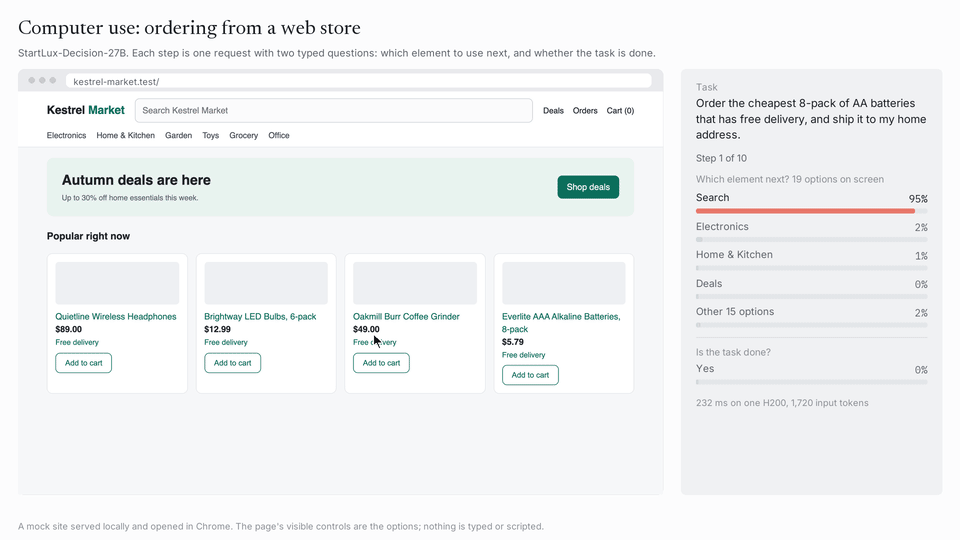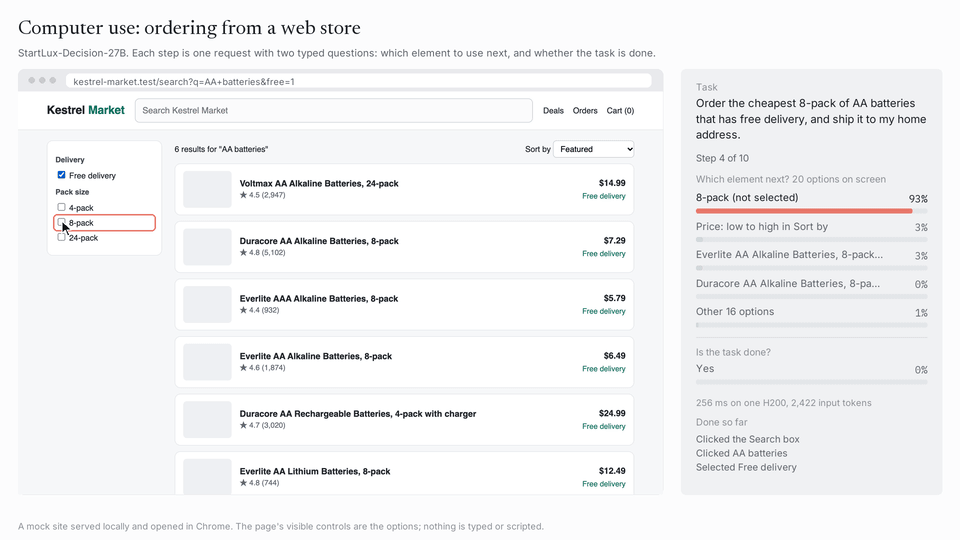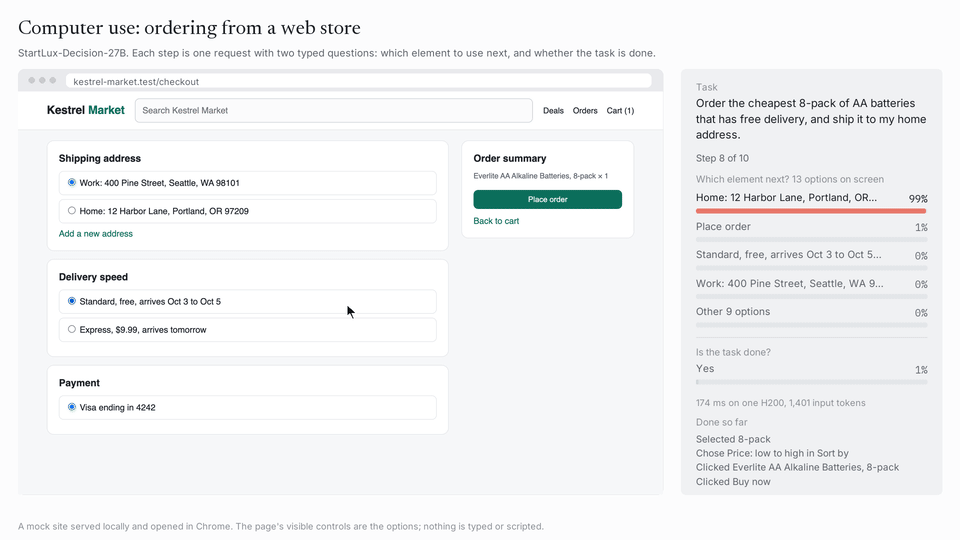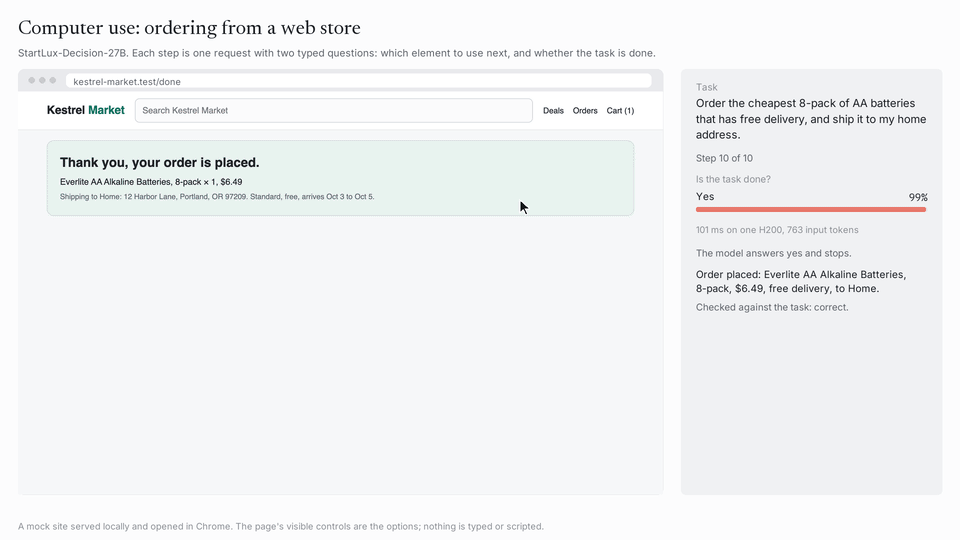
demos/ the computer-use harness and its two mock sites, and the chess match tools
eval/ evaluation: Intern-Decision suites and JevBench public tiers, Typed Decisions, Decision Index, latency
finetune/ LoRA fine-tuning on your own data and temperature calibration
docs/ inference, evaluation, fine-tuning and full results
results/ our numbers as JSON and CSV, per-benchmark Decision Index scores, raw game and computer-use logs
media/ figures and recordings used here
```
## License
The code in this repository is Apache-2.0 ([LICENSE](LICENSE)). The model weights on Hugging Face and ModelScope are released under
[CC BY-NC 4.0](https://creativecommons.org/licenses/by-nc/4.0/): free for research and other non-commercial use, with
attribution. Commercial use requires a separate license from StartLux Labs; contact
[contact@startlux.com](mailto:contact@startlux.com). Benchmark data is fetched from its original sources under their own
terms.