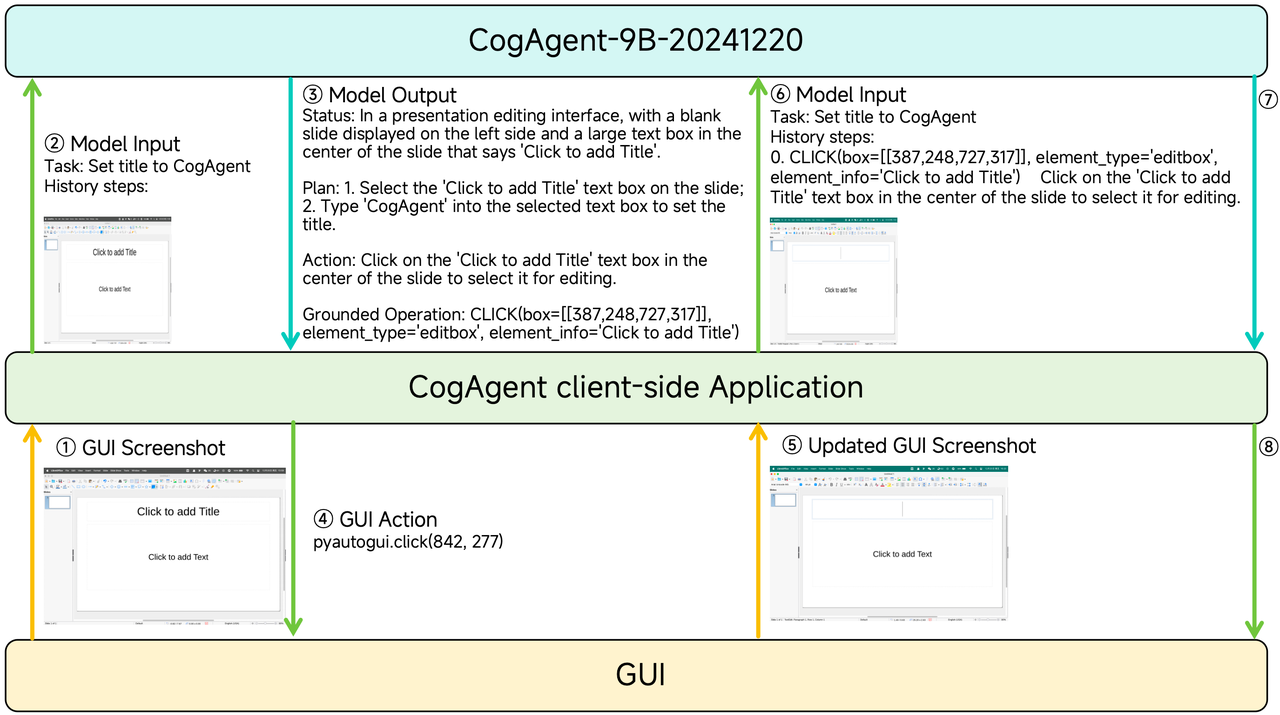
# CogAgent: An open-sourced VLM-based GUI Agent
[中文文档](README_zh.md)
- 🔥 🆕 **December 2024:** We open-sourced **the latest version of the CogAgent-9B-20241220 model**. Compared to the
previous version of CogAgent, `CogAgent-9B-20241220` features significant improvements in GUI perception, reasoning
accuracy, action space completeness, task universality, and generalization. It supports bilingual (Chinese and
English) interaction through both screen captures and natural language.
- 🏆 **June 2024:** CogAgent was accepted by **CVPR 2024** and recognized as a conference Highlight (top 3%).
- **December 2023:** We **open-sourced the first GUI Agent**: **CogAgent** (with the former repository
available [here](https://github.com/THUDM/CogVLM)) and **published the corresponding paper:
📖 [CogAgent Paper](https://arxiv.org/abs/2312.08914)**.
## Model Introduction
| Model | Model Download Links | Technical Documentation | Online Demo |
|:--------------------:|:--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------:|---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|
| cogagent-9b-20241220 | [🤗 HuggingFace](https://huggingface.co/THUDM/cogagent-9b-20241220)
[🤖 ModelScope](https://modelscope.cn/models/ZhipuAI/cogagent-9b-20241220)
[🟣 WiseModel](https://wisemodel.cn/models/ZhipuAI/cogagent-9b-20241220)
[🧩 Modelers (Ascend)](https://modelers.cn/models/zhipuai/cogagent-9b-20241220) | [📄 Official Technical Blog](https://cogagent.aminer.cn/blog#/articles/cogagent-9b-20241220-technical-report)
[📘 Practical Guide (Chinese)](https://zhipu-ai.feishu.cn/wiki/MhPYwtpBhinuoikNIYYcyu8dnKv?fromScene=spaceOverview) | [🤗 HuggingFace Space](https://huggingface.co/spaces/THUDM-HF-SPACE/CogAgent-Demo)
[🤖 ModelScope Space](https://modelscope.cn/studios/ZhipuAI/CogAgent-Demo)
[🧩 Modelers Space (Ascend)](https://modelers.cn/spaces/zhipuai/CogAgent) |
### Model Overview
`CogAgent-9B-20241220` model is based on [GLM-4V-9B](https://huggingface.co/THUDM/glm-4v-9b), a bilingual open-source
VLM base model. Through data collection and optimization, multi-stage training, and strategy improvements,
`CogAgent-9B-20241220` achieves significant advancements in GUI perception, inference prediction accuracy, action space
completeness, and generalizability across tasks. The model supports bilingual (Chinese and English) interaction with
both screenshots and language input. This version of the CogAgent model has already been applied in
ZhipuAI's [GLM-PC product](https://cogagent.aminer.cn/home). We hope the release of this model can assist researchers
and developers in advancing the research and applications of GUI agents based on vision-language models.
### Capability Demonstrations
The CogAgent-9b-20241220 model has achieved state-of-the-art results across multiple platforms and categories in GUI
Agent tasks and GUI Grounding Benchmarks. In
the [CogAgent-9b-20241220 Technical Blog](https://cogagent.aminer.cn/blog#/articles/cogagent-9b-20241220-technical-report),
we compared it against API-based commercial models (GPT-4o-20240806, Claude-3.5-Sonnet), commercial API + GUI Grounding
models (GPT-4o + UGround, GPT-4o + OS-ATLAS), and open-source GUI Agent models (Qwen2-VL, ShowUI, SeeClick). The results
demonstrate that **CogAgent leads in GUI localization (Screenspot), single-step operations (OmniAct), the Chinese
step-wise in-house benchmark (CogAgentBench-basic-cn), and multi-step operations (OSWorld)**, with only a slight
disadvantage in OSWorld compared to Claude-3.5-Sonnet, which specializes in Computer Use, and GPT-4o combined with
external GUI Grounding models.
CogAgent wishes you a Merry Christmas! Let the large model automatically send Christmas greetings to your friends.
Want to open an issue? Let CogAgent help you send an email.
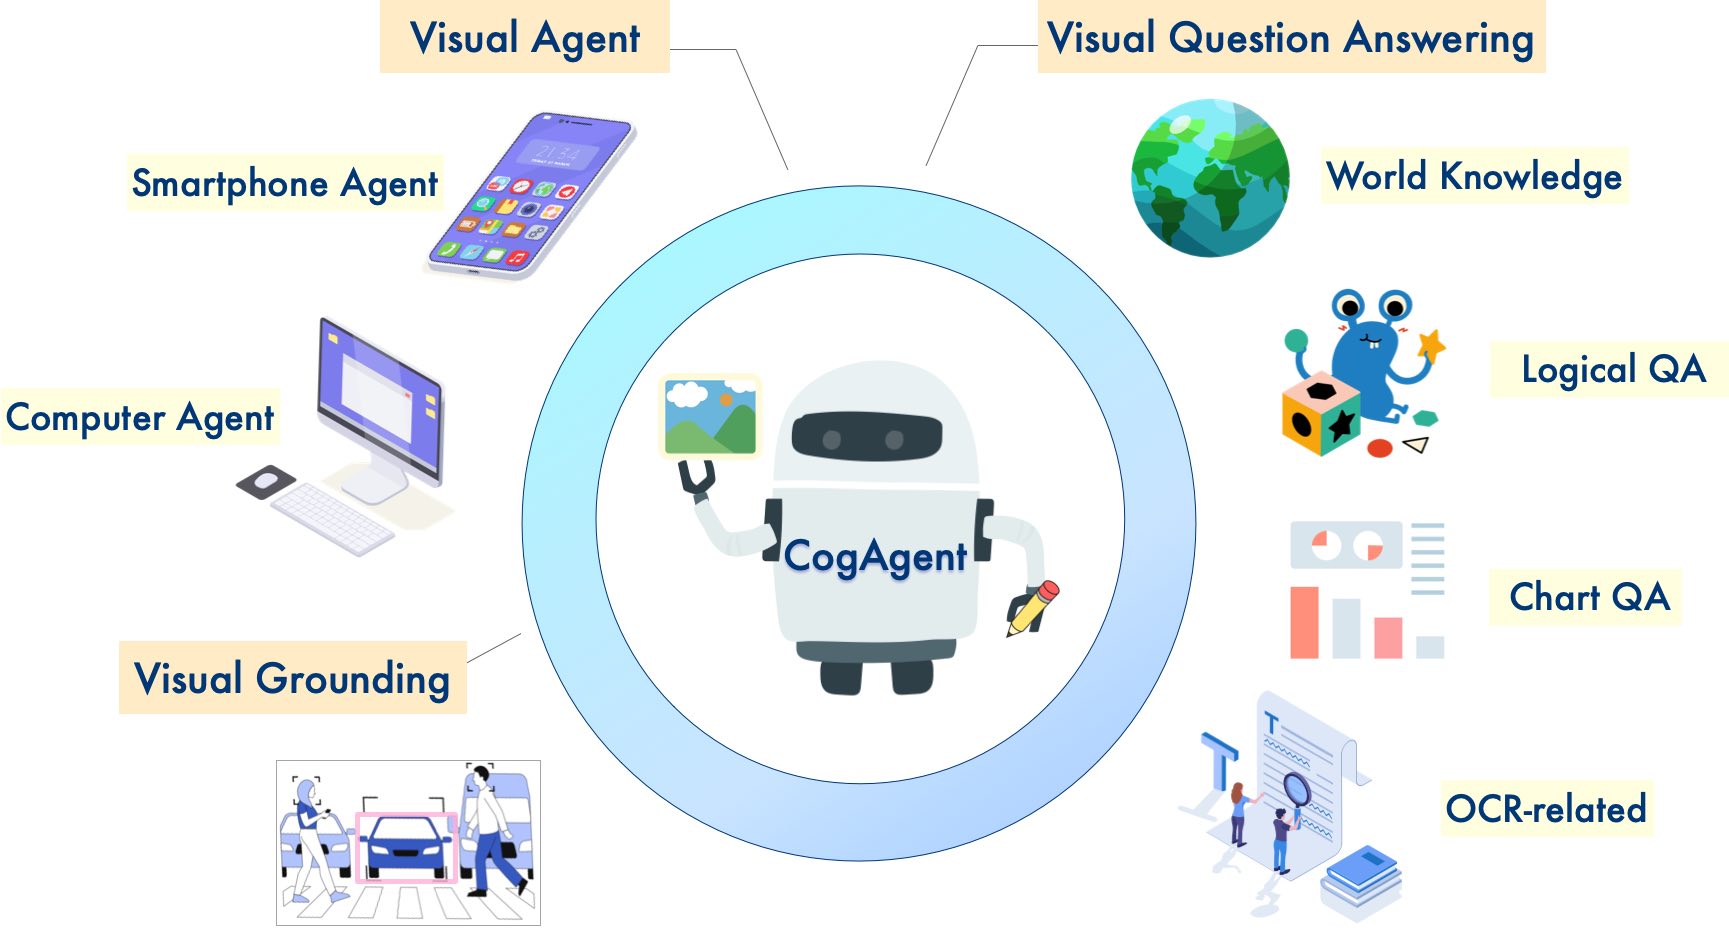
CogVLM📖 Paper: CogVLM: Visual Expert for Pretrained Language Models CogVLM is a powerful open-source Vision-Language Model (VLM). CogVLM-17B has 10B visual parameters and 7B language parameters, supporting image understanding at a resolution of 490x490, as well as multi-round dialogue. CogVLM-17B achieves state-of-the-art performance on 10 classic multimodal benchmarks, including NoCaps, Flicker30k captioning, RefCOCO, RefCOCO+, RefCOCOg, Visual7W, GQA, ScienceQA, VizWiz VQA, and TDIUC. |
CogAgent📖 Paper: CogAgent: A Visual Language Model for GUI Agents CogAgent is an open-source vision-language model improved upon CogVLM. CogAgent-18B has 11B visual parameters and 7B language parameters. It supports image understanding at a resolution of 1120x1120. Building on CogVLM’s capabilities, CogAgent further incorporates a GUI image agent ability. CogAgent-18B delivers state-of-the-art general performance on 9 classic vision-language benchmarks, including VQAv2, OK-VQ, TextVQA, ST-VQA, ChartQA, infoVQA, DocVQA, MM-Vet, and POPE. It also significantly outperforms existing models on GUI operation datasets such as AITW and Mind2Web. |