# ScaleCUA: Scaling Computer Use Agents with Verifiable Task Synthesis and Efficient Online RL

ScaleCUA is an open-source framework for scaling computer use agents (CUAs)
with verifiable task synthesis and efficient online reinforcement learning. It
contains the VeriGen task-generation pipeline, the AgentRL training stack, and
OSWorld / ScienceBoard evaluation code used by the released ScaleCUA agents.
> **Reproducing results?** Follow [`REPRODUCE.md`](REPRODUCE.md) — a step-by-step,
> copy-pasteable guide (for humans or agents) that downloads every required
> resource and runs OSWorld / ScienceBoard evaluation of the released models.
## Overview
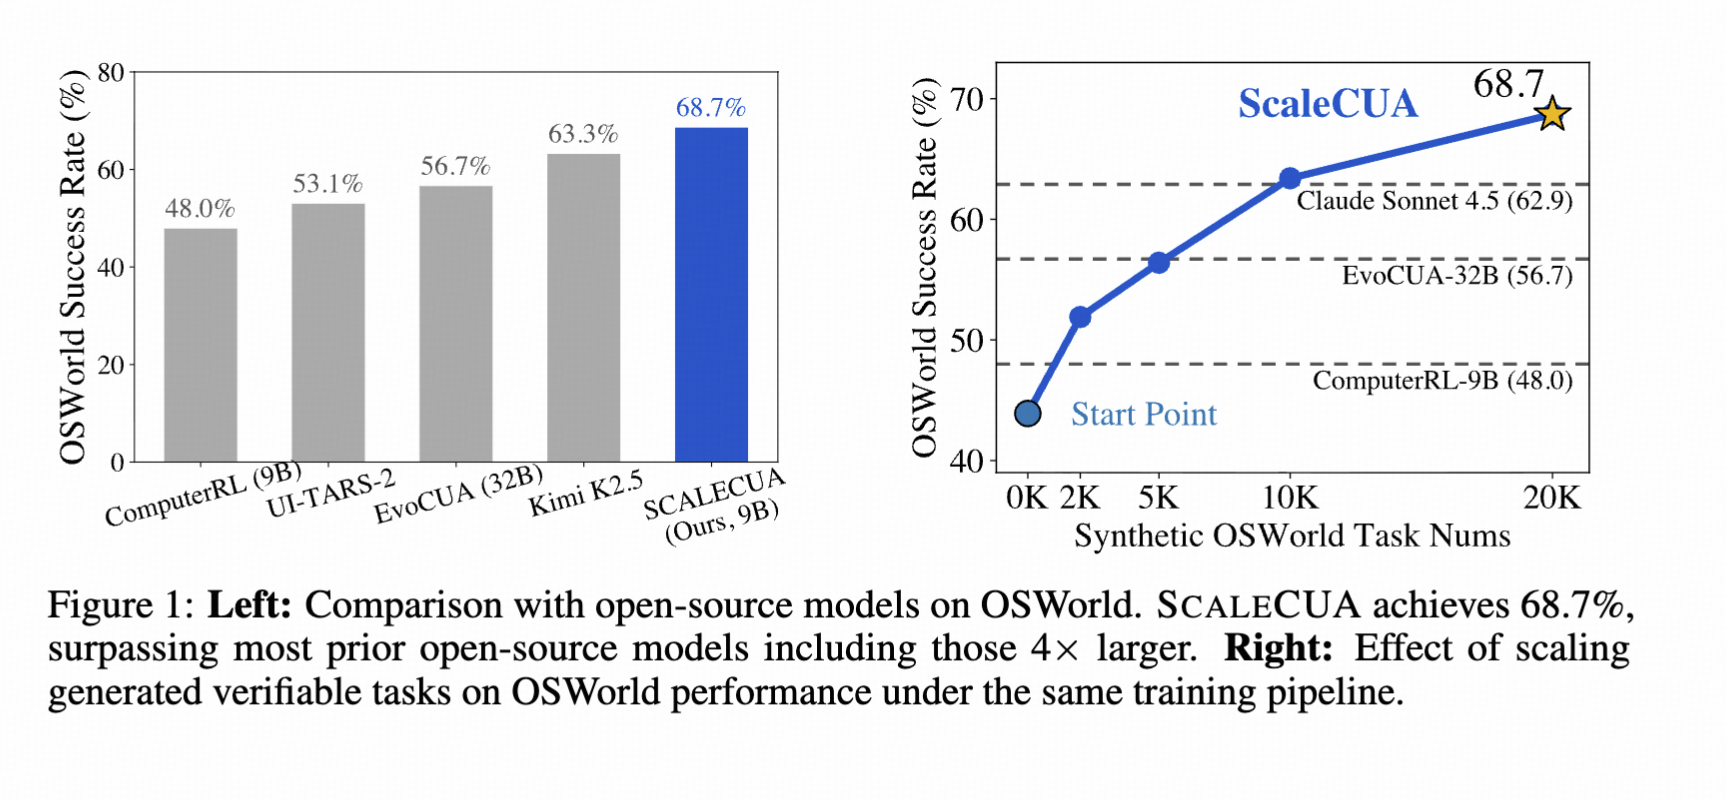
Computer use agents operate directly on screen pixels and UI elements to
automate digital workflows across applications and operating systems. Online
reinforcement learning with verifiable rewards is a promising path to scale
their capabilities, but is bottlenecked by two issues:
- **Verifiable data scarcity.** Unlike math or code, a GUI task does not come
with a built-in deterministic judge. Hand-crafted verifiers do not scale, and
prior synthesis pipelines typically produce trajectory-level data that is
neither verifiable nor difficulty-controlled.
- **Online RL inefficiency.** Uniform sampling wastes rollouts on tasks the
model has already mastered or cannot solve, while naive trajectory- or
step-level packaging of multi-turn rollouts forces an unfavorable trade-off
between rollout latency and training-engine throughput.
ScaleCUA addresses both axes with three components:
1. **VeriGen** synthesizes verifiable GUI tasks by driving LLM agents to
interact with live OS containers under a multi-agent proposer / judger /
checker feedback loop. A shared docker interaction probe lets it run 100+
concurrent workers against 100+ docker environments, yielding 24K+
verifiable tasks and about 3K high-quality RL tasks across OSWorld and
ScienceBoard domains.
2. **Frontier Sampling** maintains an exponential moving average of per-task
success rates and samples tasks near the model's current learning frontier,
with a small fraction reserved for uniform exploration.
3. **Visual Context Segmentation** keeps the most recent *K* screenshots as
visual context while preserving the full textual history. This bounds
visual-token growth and reduces step-wise trajectory packaging overhead,
delivering a 2.83x end-to-end training speedup in our setting.
### Headline Results
| Backbone | OSWorld | ScienceBoard | Released checkpoints |
| --- | ---: | ---: | --- |
| ScaleCUA-GLM-4.6V-Flash | 66.5 | 49.4 | [OSWorld](https://huggingface.co/extreme1228/ScaleCUA-glm4.6v-osworld) / [ScienceBoard](https://huggingface.co/extreme1228/ScaleCUA-glm4.6v-scienceboard) |
| ScaleCUA-Qwen3-VL-8B | 67.7 | 51.9 | [OSWorld](https://huggingface.co/extreme1228/ScaleCUA-qwen3-vl-osworld) / [ScienceBoard](https://huggingface.co/extreme1228/ScaleCUA-qwen3-vl-scienceboard) |
| **ScaleCUA-Qwen3.5-9B** | **68.7** | **54.0** | [OSWorld](https://huggingface.co/extreme1228/ScaleCUA-qwen3.5-osworld) / [ScienceBoard](https://huggingface.co/extreme1228/ScaleCUA-qwen3.5-scienceboard) |
The 9B model surpasses Kimi K2.5 (63.3%), EvoCUA-32B (56.7%), Claude Sonnet
4.5 (62.9%), and Claude Opus 4.6 (52.7% on ScienceBoard), establishing a new
state-of-the-art among open-source computer use agents.
## Model Checkpoints
The released weights are standard model repositories, mirrored on both
Hugging Face and ModelScope. Each model family has separate OSWorld and
ScienceBoard RL checkpoints.
| Backbone | Benchmark | Hugging Face | ModelScope |
| --- | --- | --- | --- |
| GLM-4.6V-Flash | OSWorld | [ScaleCUA-glm4.6v-osworld](https://huggingface.co/extreme1228/ScaleCUA-glm4.6v-osworld) | [ScaleCUA-glm4.6v-osworld](https://modelscope.cn/models/extreme1228/ScaleCUA-glm4.6v-osworld) |
| GLM-4.6V-Flash | ScienceBoard | [ScaleCUA-glm4.6v-scienceboard](https://huggingface.co/extreme1228/ScaleCUA-glm4.6v-scienceboard) | [ScaleCUA-glm4.6v-scienceboard](https://modelscope.cn/models/extreme1228/ScaleCUA-glm4.6v-scienceboard) |
| Qwen3-VL-8B | OSWorld | [ScaleCUA-qwen3-vl-osworld](https://huggingface.co/extreme1228/ScaleCUA-qwen3-vl-osworld) | [ScaleCUA-qwen3-vl-osworld](https://modelscope.cn/models/extreme1228/ScaleCUA-qwen3-vl-osworld) |
| Qwen3-VL-8B | ScienceBoard | [ScaleCUA-qwen3-vl-scienceboard](https://huggingface.co/extreme1228/ScaleCUA-qwen3-vl-scienceboard) | [ScaleCUA-qwen3-vl-scienceboard](https://modelscope.cn/models/extreme1228/ScaleCUA-qwen3-vl-scienceboard) |
| Qwen3.5-9B | OSWorld | [ScaleCUA-qwen3.5-osworld](https://huggingface.co/extreme1228/ScaleCUA-qwen3.5-osworld) | [ScaleCUA-qwen3.5-osworld](https://modelscope.cn/models/extreme1228/ScaleCUA-qwen3.5-osworld) |
| Qwen3.5-9B | ScienceBoard | [ScaleCUA-qwen3.5-scienceboard](https://huggingface.co/extreme1228/ScaleCUA-qwen3.5-scienceboard) | [ScaleCUA-qwen3.5-scienceboard](https://modelscope.cn/models/extreme1228/ScaleCUA-qwen3.5-scienceboard) |
```bash
# Example: download the best OSWorld checkpoint from Hugging Face
pip install -U "huggingface_hub[cli]"
hf download extreme1228/ScaleCUA-qwen3.5-osworld \
--local-dir checkpoints/ScaleCUA-qwen3.5-osworld
# Or download the same checkpoint from ModelScope
pip install -U modelscope
modelscope download --model extreme1228/ScaleCUA-qwen3.5-osworld \
--local_dir checkpoints/ScaleCUA-qwen3.5-osworld
```
All released checkpoints are grouped in the ScaleCUA collection on
[Hugging Face](https://huggingface.co/collections/extreme1228/scalecua-6a4cad5e3c80a230622eaff3)
and [ModelScope](https://modelscope.cn/collections/extreme1228/ScaleCUA).
### SFT start-point checkpoints
For full training reproducibility we also release the supervised fine-tuning
(SFT) checkpoints that serve as the start point for online RL (see
[`scalecua_rl`](scalecua_rl)). These are the `model_path` you initialize RL from.
| Backbone | Benchmark | Hugging Face | ModelScope |
| --- | --- | --- | --- |
| GLM-4.6V-Flash | OSWorld | [ScaleCUA-glm4.6v-osworld-sft](https://huggingface.co/extreme1228/ScaleCUA-glm4.6v-osworld-sft) | [ScaleCUA-glm4.6v-osworld-sft](https://modelscope.cn/models/extreme1228/ScaleCUA-glm4.6v-osworld-sft) |
| GLM-4.6V-Flash | ScienceBoard | [ScaleCUA-glm4.6v-scienceboard-sft](https://huggingface.co/extreme1228/ScaleCUA-glm4.6v-scienceboard-sft) | [ScaleCUA-glm4.6v-scienceboard-sft](https://modelscope.cn/models/extreme1228/ScaleCUA-glm4.6v-scienceboard-sft) |
| Qwen3-VL-8B | OSWorld | [ScaleCUA-qwen3-vl-osworld-sft](https://huggingface.co/extreme1228/ScaleCUA-qwen3-vl-osworld-sft) | [ScaleCUA-qwen3-vl-osworld-sft](https://modelscope.cn/models/extreme1228/ScaleCUA-qwen3-vl-osworld-sft) |
| Qwen3-VL-8B | ScienceBoard | [ScaleCUA-qwen3-vl-scienceboard-sft](https://huggingface.co/extreme1228/ScaleCUA-qwen3-vl-scienceboard-sft) | [ScaleCUA-qwen3-vl-scienceboard-sft](https://modelscope.cn/models/extreme1228/ScaleCUA-qwen3-vl-scienceboard-sft) |
| Qwen3.5-9B | OSWorld | [ScaleCUA-qwen3.5-osworld-sft](https://huggingface.co/extreme1228/ScaleCUA-qwen3.5-osworld-sft) | [ScaleCUA-qwen3.5-osworld-sft](https://modelscope.cn/models/extreme1228/ScaleCUA-qwen3.5-osworld-sft) |
| Qwen3.5-9B | ScienceBoard | [ScaleCUA-qwen3.5-scienceboard-sft](https://huggingface.co/extreme1228/ScaleCUA-qwen3.5-scienceboard-sft) | [ScaleCUA-qwen3.5-scienceboard-sft](https://modelscope.cn/models/extreme1228/ScaleCUA-qwen3.5-scienceboard-sft) |
## Dataset
The VeriGen task release is hosted on both Hugging Face and ModelScope:
```bash
# Hugging Face
pip install -U "huggingface_hub[cli]"
hf download extreme1228/ScaleCUA \
--repo-type dataset \
--local-dir data/ScaleCUA
# ModelScope
pip install -U modelscope
modelscope download --dataset extreme1228/ScaleCUA \
--local_dir data/ScaleCUA
```
The dataset contains the released RL pools at `osworld/rl_tasks` and
`scienceboard/rl_tasks`, plus OSWorld executable judge functions at
`osworld/judge_functions/rl_tasks`. These are the task sources used for the
released RL recipe: 3,212 selected trajectory-guided RL tasks (2,049 OSWorld and
1,163 ScienceBoard) and 24,655 task-only generated candidates are public. Use
[`osworld_env/README.md`](osworld_env/README.md) for the worker configuration
that consumes them.
## Framework
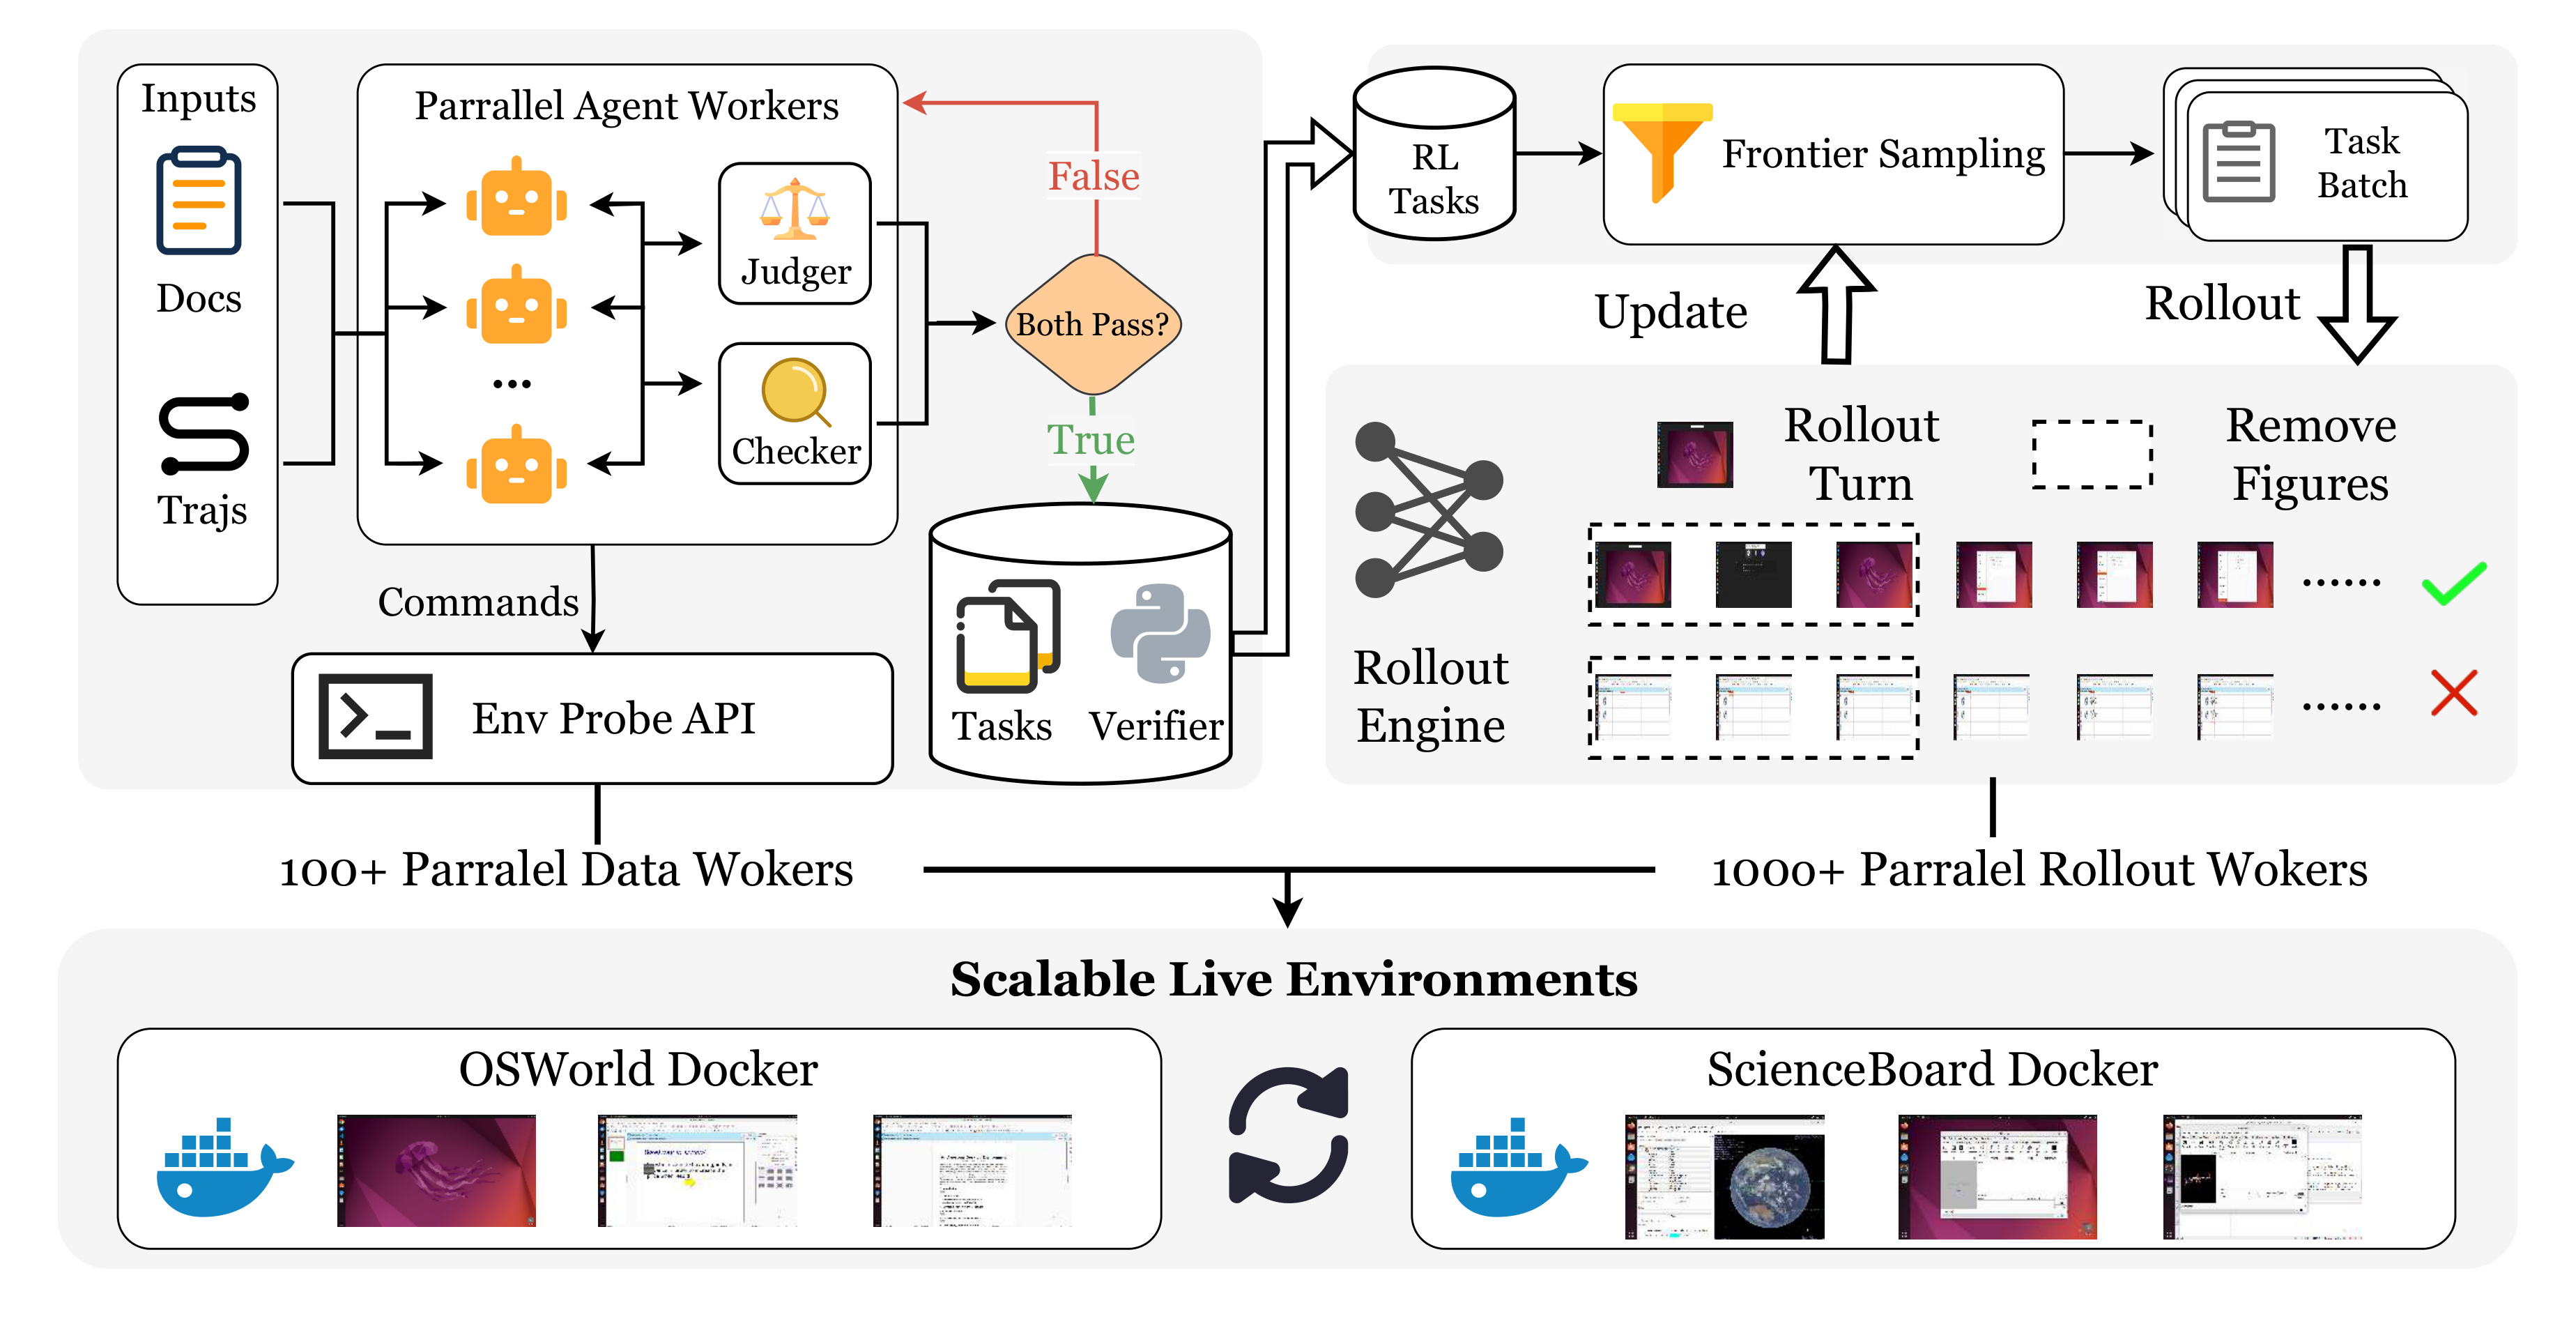
*Figure 1 -- ScaleCUA overview.* VeriGen autonomously synthesizes verifiable
GUI tasks with executable rewards from live OS environments at 100+ parallel
worker scale. Generated tasks flow into the RL pool, where Frontier Sampling
selects each task batch from the model's current capability frontier; rollouts
are streamed by 1000+ parallel rollout workers against scalable OSWorld and
ScienceBoard docker environments and fed back to update per-task EMA scores.
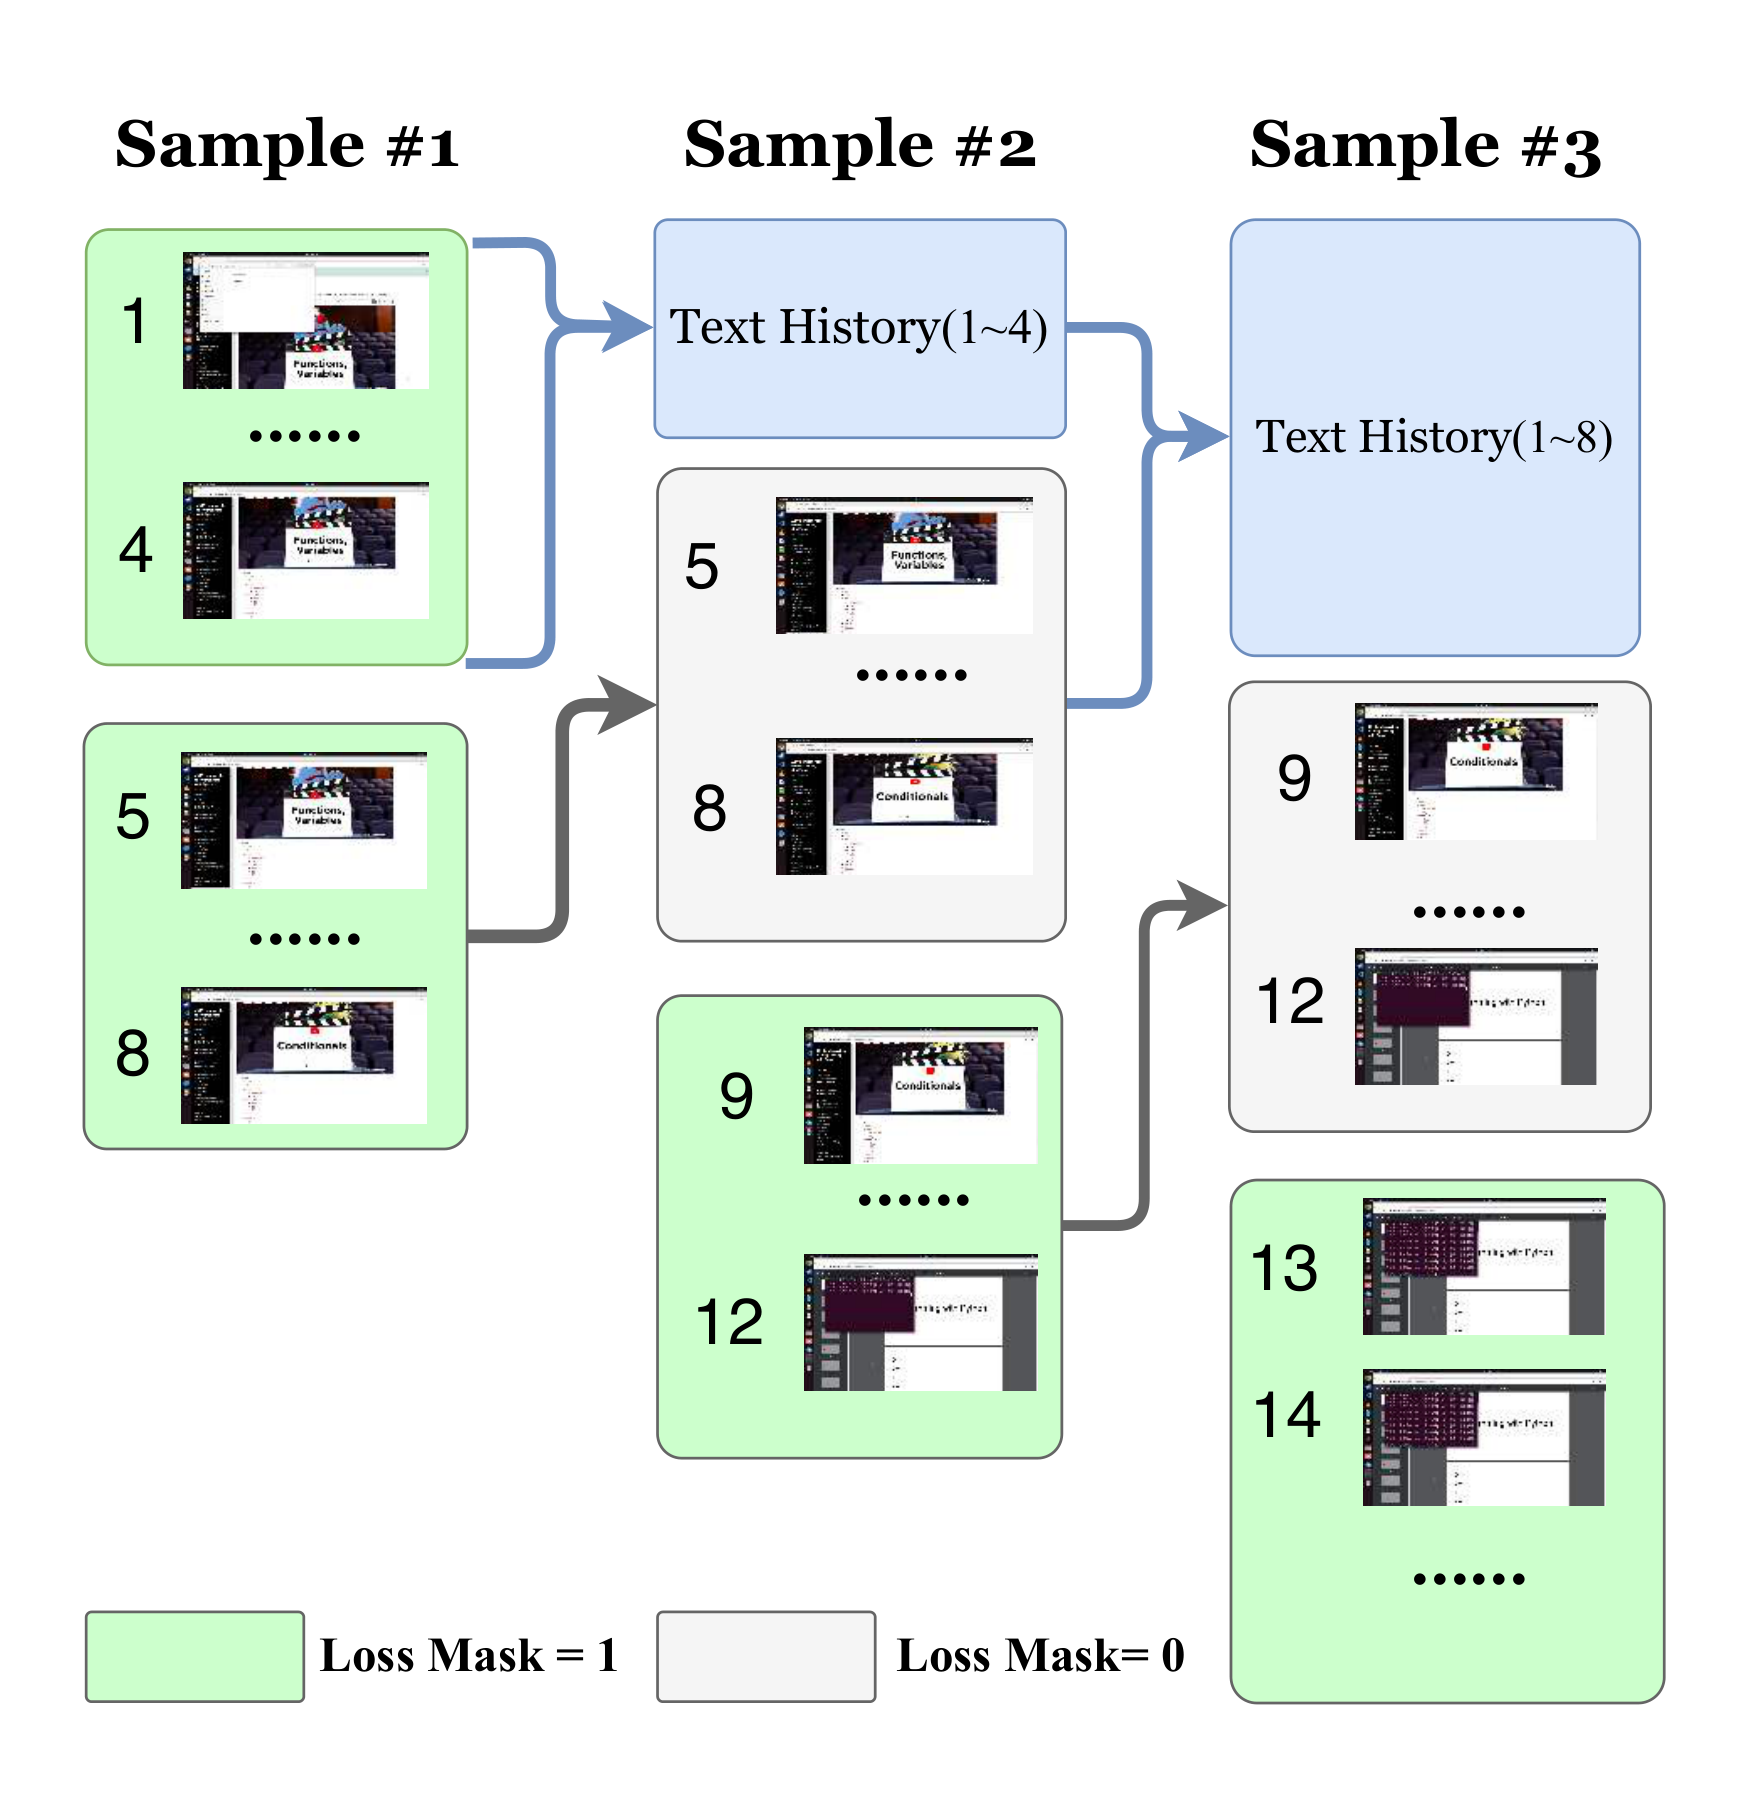
*Figure 2 -- Visual Context Segmentation.* A long-horizon trajectory is split
into sliding-window samples that retain the most recent *K* screenshots as
visual context while keeping the textual history. When the visual window
overflows, the oldest screenshots are dropped and the remaining history is
re-tokenized, capping per-segment visual tokens while preserving cross-step
reasoning context.
## Repository Layout
```text
SCALE-CUA/
├── VeriGen/ # verifiable task and reward synthesis pipeline
├── osworld_eval/ # OSWorld + ScienceBoard evaluation package
├── scalecua_rl/ # AgentRL training framework (trainer + controller)
├── osworld_env/ # online-RL environment layer (worker + controller wiring)
└── assets/ # README figures
```
- **`VeriGen/`** implements iterative multi-agent task synthesis, judge
validation through real docker execution, trajectory-guided augmentation
(split-on-failure / compose-on-success), and the shared environment probe.
- **`scalecua_rl/`** contains the Ray-based asynchronous GRPO trainer, rollout
/ actor / reference worker pools, vLLM rollout engine, Megatron-LM training
engine, Frontier Sampling, and Visual Context Segmentation.
- **`osworld_env/`** is the online-RL environment layer that turns a task index
into a live desktop VM and serves OSWorld / ScienceBoard rollouts to the
trainer (environment worker + controller wiring; the VM container image
defaults to the public `happysixd/osworld-docker`).
- **`osworld_eval/`** contains the ScaleCUA OSWorld and ScienceBoard agents,
task assets, and example launch scripts (`run_scalecua_os.py`,
`run_scalecua_sci.py`).
Runtime artifacts, caches, logs, example results, private environment files,
and local machine paths have been removed from the release. API credentials
are not included; provider keys must be supplied through environment variables.
## Getting Started
Start from the component README that matches your use case:
- [`VeriGen/README.md`](VeriGen/README.md) for task generation, judge
validation, trajectory-guided synthesis, and the parallel docker probe.
- [`osworld_eval/README.md`](osworld_eval/README.md) for OSWorld and
ScienceBoard evaluation with released checkpoints.
- [`scalecua_rl/README.md`](scalecua_rl/README.md) for AgentRL training,
evaluation-only runs, vLLM serving, and controller-based environment
deployment.
- [`osworld_env/README.md`](osworld_env/README.md) for bringing up the online-RL
environment (worker + controller + VM containers) that serves OSWorld /
ScienceBoard rollouts to the trainer.
## Credentials And Local Assets
No API keys are stored in this release. Configure providers via environment
variables, for example:
```bash
export OPENAI_API_KEY=""
export OPENAI_BASE_URL="https://api.openai.com/v1"
```
Some OSWorld tasks additionally depend on Google, Thunderbird, or proxy
settings. The files under `osworld_eval/evaluation_examples/settings/` are
placeholders and must be filled with your own test accounts before running
those tasks.
This release also does not include local OSWorld cache files, downloaded task
assets, VM images, recordings, or previous result folders. For tasks that
depend on local cache or downloaded files, prepare those at the paths expected
by the corresponding OSWorld task configuration.
## Paper And Citation
The ScaleCUA paper is available on [arXiv](https://arxiv.org/abs/2607.11185).
If you use ScaleCUA, please cite:
```bibtex
@misc{lv2026scalecuascalingcomputeruse,
title = {SCALECUA: Scaling Computer Use Agents with Verifiable Task Synthesis and Efficient Online RL},
author = {Bowen Lv and Xiao Liu and Yanyu Ren and Hanyu Lai and Bohao Jing and Hanchen Zhang and Yanxiao Zhao and Shuntian Yao and Jie Tang and Yuxiao Dong},
year = {2026},
eprint = {2607.11185},
archivePrefix = {arXiv},
primaryClass = {cs.AI},
url = {https://arxiv.org/abs/2607.11185}
}
```