[中文文档](./README_CN.md)
MovieRoll: And... Action! ### A Systematic Framework for Rolling Out Long-Form Videos

Yunyang Ge1,2,*,‡, Weijie Kong2,*, Ryan Xu2,*, Yue Wu2, Qi Tian2, Jiangfeng Xiong2
Bin Lin1,2, Mingzhe Zheng2,3, Shenghai Yuan1, Zheyuan Liu1,2, Jian-Wei Zhang2,§, Li Yuan1,†
1 Peking University  ·  2 Tencent Hunyuan  ·  3 The Hong Kong University of Science and Technology
* Equal contribution  ·  § Project leader  ·  † Corresponding author
‡ Work done during internship at Tencent Hunyuan

[![arXiv](https://img.shields.io/badge/arXiv-2611.21339-b31b1b?logo=arxiv)](https://arxiv.org/abs/2611.21339) [![Project Page](https://img.shields.io/badge/Page-Project_Page-2ea44f)](https://tencent-hunyuan.github.io/MovieRoll/) [![Models](https://img.shields.io/badge/%F0%9F%A4%97_Models-Hugging_Face-yellow)](https://huggingface.co/yunyangge/MovieRoll) [![SGLang](https://img.shields.io/badge/Backend-SGLang_Diffusion-orange)](./sglang_movieroll/README.md) [![vLLM-Omni](https://img.shields.io/badge/Backend-vLLM--Omni-blue)](./vllm_omni_movieroll/README.md) [![License](https://img.shields.io/badge/License-Tencent_Hunyuan_Community-green)](./LICENSE)
## 🎬 Video Demo https://github.com/user-attachments/assets/2d4287cd-ae78-4870-8cd9-fec0edb21ecf ## 🔥 News! - **[2026.11.16]** 🚀 Day-0 support for [SGLang Diffusion](./sglang_movieroll/README.md) and [vLLM-Omni](./vllm_omni_movieroll/README.md). - **[2026.11.16]** 🎉 We release the MovieRoll code! ## ✅ TODO List - [x] Release training and inference code - [x] Release model weights - [x] Support SGLang and vLLM-Omni - [ ] Support consumer GPUs (e.g., RTX 4090 and RTX 5090) - [ ] Add Gradio support - [ ] Improve inference efficiency - [ ] Add streaming playback: decode and output video while generation continues ## 🔎 Overview MovieRoll is a systematic framework for rolling out long-form videos, from a supervised Base model to a few-step Distilled model. Its training and inference designs work together to reduce degradation as generation continues. - **Base to Distilled:** window-wise teacher forcing trains MovieRoll-Base; ODE initialization and cumulative long tuning (CuLT-DMD) produce MovieRoll-Distilled. - **Long-rollout generation:** joint window denoising, hierarchical KV caching, and cache recomputation support continuous generation; AnnealCFG reduces guidance toward the clean endpoint in the Base model. - **Single- and multi-event control:** generate from one prompt or an ordered sequence of event prompts, with released text-to-video and image-to-video checkpoints.
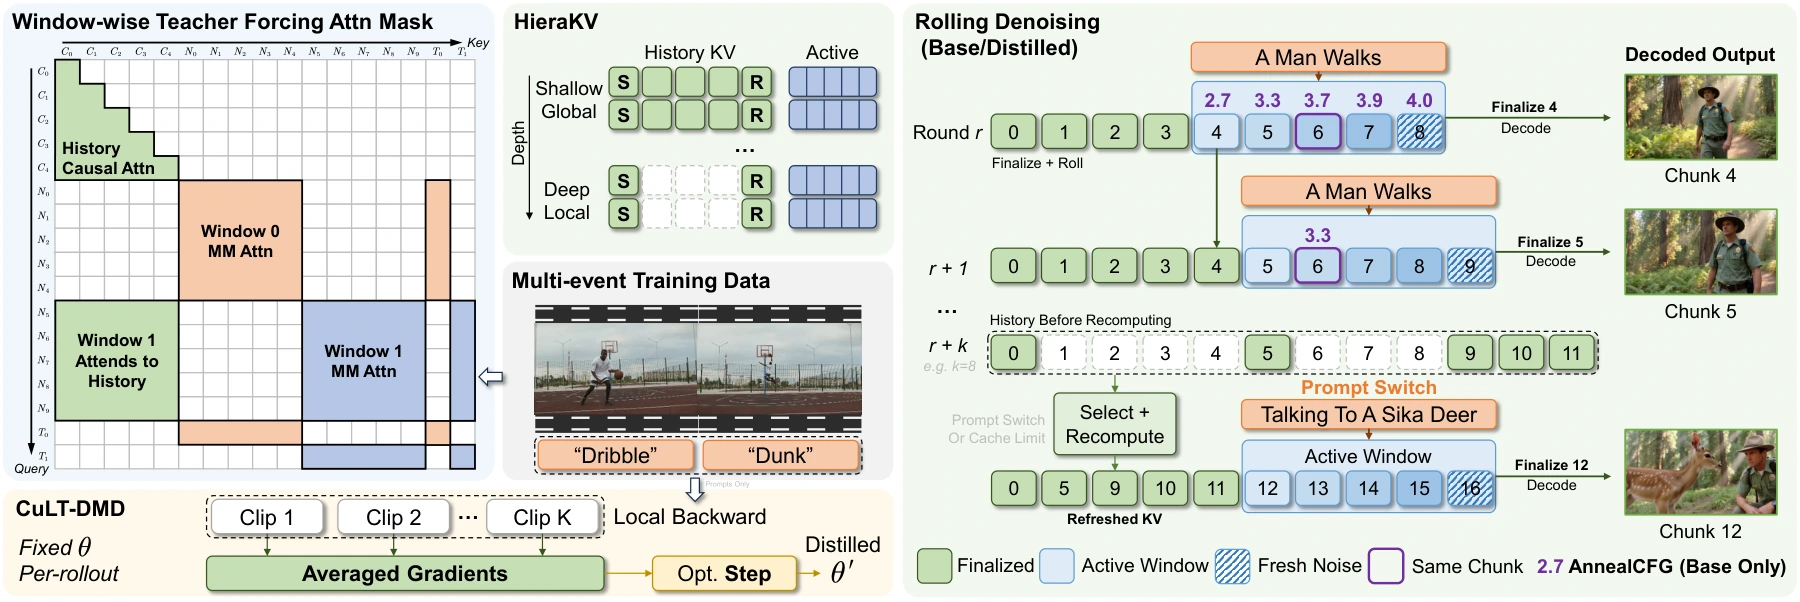
MovieRoll overview: window-wise training, hierarchical KV caching, cumulative long tuning, and rolling generation

## 🎁 Model Zoo | Model | Supported tasks | Resolution (H × W) | Denoising steps | Guidance | Download | |---|---|---|---|---|---| | MovieRoll-Base | T2V (text-to-video), I2V (image-to-video) | 480p (arbitrary aspect ratios) | 50 | AnnealCFG | [base](https://huggingface.co/yunyangge/MovieRoll/tree/main/base) | | MovieRoll-Distilled (T2V) | T2V (text-to-video) | 480 × 864 / 864 × 480 | 5 | No CFG | [distilled/t2v](https://huggingface.co/yunyangge/MovieRoll/tree/main/distilled/t2v) | | MovieRoll-Distilled (I2V) | I2V (image-to-video) | 480 × 864 / 864 × 480 | 5 | No CFG | [distilled/i2v](https://huggingface.co/yunyangge/MovieRoll/tree/main/distilled/i2v) | ## 🛠️ Environment ### Runtime and GPU setup The commands below use Python 3.12, CUDA-enabled PyTorch, and the installed FlashAttention kernels. FlashAttention-3 is built from its `hopper/` directory and needs a Hopper (sm90) GPU such as the H100; check that the kernel build supports your GPU before starting a long run. Run all commands from the repository root after installation. | Launch configuration | Purpose | Settings | |---|---|---| | 8 GPUs | Optional multi-GPU inference | `torchrun --nproc_per_node=8`; `--sp-size 8`, `--shard-world 8` | | 1 GPU | Default Quick Start | `python`; `--sp-size 1`; the full pipeline must fit on the GPU (a 96 GB GPU holds it) | For other GPU counts, `--sp-size` must divide both the GPU count and the model's 16 attention heads; with FSDP, `--shard-world` must also divide the GPU count and be divisible by `--sp-size`. Single-process inference does not use FSDP. The examples use BF16 transformer computation. **CPU offload is not supported by this native inference entry point yet.** Support is planned to enable inference on consumer GPUs. ```bash git clone https://github.com/Tencent-Hunyuan/MovieRoll.git && cd MovieRoll conda create -n movieroll python=3.12 -y && conda activate movieroll pip install -r requirements.txt pip install flash-attn --no-build-isolation # FlashAttention-2, required # FlashAttention-3, also required (Hopper / sm90 GPUs) git clone --recursive https://github.com/Dao-AILab/flash-attention.git cd flash-attention/hopper && pip install . --no-build-isolation && cd ../.. python -c "import flash_attn, flash_attn_interface" # prints nothing when both are installed ```
⚡ Optional: SageAttention SageAttention speeds up sampling by about 1.4×. Install it from the commit below (the `v2.2.0` release has a kernel bug), then add `--attention-backend sage` to an inference command. The videos are very close to the default FlashAttention-3 output, but not bit-identical. ```bash git clone https://github.com/thu-ml/SageAttention.git && cd SageAttention git checkout d1a57a5 && pip install . --no-build-isolation && cd .. ```
### 🧱 Download Checkpoints The MovieRoll weights are hosted at [yunyangge/MovieRoll](https://huggingface.co/yunyangge/MovieRoll). Accept the repository's access conditions and authenticate with `hf auth login` before downloading gated weights. **1. Download one MovieRoll checkpoint.** Set `MODEL` to `base`, `distilled/t2v`, or `distilled/i2v`: ```bash MODEL=distilled/t2v hf download yunyangge/MovieRoll --include "$MODEL/*" --local-dir ./ckpts/movieroll ``` **2. Download the shared VAE and text encoders.** These are required for inference with any of the three checkpoints: ```bash hf download tencent/HunyuanVideo-1.5 --include 'vae/*' --local-dir ./ckpts hf download Qwen/Qwen2.5-VL-7B-Instruct --local-dir ./ckpts/text_encoder/llm hf download google/byt5-small --local-dir ./ckpts/text_encoder/byt5-small modelscope download --model AI-ModelScope/Glyph-SDXL-v2 --local_dir ./ckpts/text_encoder/Glyph-SDXL-v2 ``` ```text ckpts/ ├── vae/ ├── text_encoder/ │ ├── llm/ │ ├── byt5-small/ │ └── Glyph-SDXL-v2/ └── movieroll/ ├── base/ # download if selected └── distilled/ ├── t2v/ # download if selected └── i2v/ # download if selected ``` Each selected model directory contains `config.json` and `model.safetensors`. Its config supplies model-specific sampling defaults; reference copies are in [`movieroll/configs/models/`](./movieroll/configs/models). Training initialization weights are covered in the [training guide](./docs/TRAINING.md). ## 🤖 For Agents You can ask a coding agent with access to this repository to read the relevant task folder under [`agent/`](./agent). Start with its `SKILL.md` (or `SKILL_CN.md` for Chinese), follow the linked references as needed, and carry out your task using those instructions. | Task | Skill folder | |---|---| | Rewrite text-to-video, image-to-video, or multi-event prompts | [streaming-video-prompt-rewrite](./agent/streaming-video-prompt-rewrite) | | Run inference or any training stage | [movieroll-run](./agent/movieroll-run) | | Port MovieRoll's methods to another codebase | [movieroll-port](./agent/movieroll-port) | | Deploy and run inference with SGLang Diffusion | [movieroll-sglang](./agent/movieroll-sglang) | | Deploy and run inference with vLLM-Omni | [movieroll-vllm-omni](./agent/movieroll-vllm-omni) | For example, tell your agent: > Read `agent/movieroll-run/SKILL.md` and its relevant references, then help me run MovieRoll-Distilled text-to-video inference on a single GPU using the prompt in Quick Start. See [`agent/README.md`](./agent/README.md) for more details. ## 🚀 Quick Start After downloading the model weights, run the following command from the repository root to generate a video. ```bash python generate_movieroll.py \ --model ckpts/movieroll/distilled/t2v --sp-size 1 \ --prompt "In a softly lit, modern living room, a surreal event unfolds as a single orange and white clownfish swims gracefully through the air, continuously circling the head of a young man. The man, in his early twenties with dark, curly hair, sits calmly at a wooden desk, wearing a comfortable cream-colored knit sweater. His expression is one of quiet awe, his eyes subtly tracking the fish's rhythmic, looping path around him. The clownfish moves as if through water, its fins gently propelling it forward in a steady, circular motion. Its scales glisten with a wet sheen under the warm, diffused light coming from a large window to the left, and a few stray, glistening water droplets seem to trail in its wake, hanging in the air for a moment before vanishing. In the background, intentionally out of focus, sits a rectangular glass fish tank filled with clear blue water and swaying green aquatic plants, the source of this airborne marvel. The camera remains static in a medium shot, maintaining an eye-level perspective with the seated man. This fixed viewpoint captures both the man's serene reaction and the fish's complete, unending orbit around his head, emphasizing the dreamlike and continuous nature of the scene. Cinematic photography realistic style." \ --seed 4890 --video-length 721 \ --output-dir ./outputs ``` Output: `./outputs/samples/default/rank0_sample_0.mp4`. ## ⚙️ Inference Options Common inference options are listed below. `--model` (or `--dit-weight`) is required; model-dependent defaults such as `--context-noise` come from the selected checkpoint config. ```bash --model ckpts/movieroll/base # required (or --dit-weight for a bare .safetensors), the model folder: base (50 steps with AnnealCFG), distilled/t2v or distilled/i2v (5 steps) --prompt "..." # one prompt for the whole video --prompt-list "..." "..." "..." # several prompts, played one after another in a single video (multi-event) --prompt-csv prompts.csv # a batch: columns index, seed, prompt (or event_1..event_N), optional input_image --input-image first_frame.jpg # image-to-video: the image, scaled and center-cropped to the video size, becomes the first frame (best with distilled/i2v) --video-length 721 # frames, of the form 16k+1: 241 = 10 s, 721 = 30 s, 1441 = 60 s --height 480 --width 864 # resolution, multiples of 16 --seed 930 # noise seed of --prompt / --prompt-list (defaults to --global-seed 930); CSV rows use their seed column --context-noise 0.15 # noise added to the cached history; the model's config sets it: 0.05 (base), 0.15 (distilled/t2v), 0 (distilled/i2v) --attention-backend fa3 # fa3, or sage for SageAttention (about 1.4x faster) --vae-parallel-mode none # sp: split the VAE decode (PS-VAE) across each sequence-parallel group --sp-size 8 # sequence-parallel group size; 8 for eight GPUs, 1 for a single GPU --shard-world 8 # FSDP shard group size; must divide the number of GPUs (with fewer than 8, use that number) --num-videos-per-prompt 1 # videos per prompt, each with its own noise --output-type video # video (mp4), pt (decoded tensor) or latent (distilled only) --output-dir ./outputs # where the videos are written ``` Example `--prompt-csv` files, single- and multi-event, for the base and distilled models, are in [`example/`](./example). ### ✍️ Prompt Rewriting MovieRoll works best with long, detailed prompts: a fixed or subject-tracking camera, motion that can keep going, and one consistent setting across events. The prompt-rewrite skills in [`agent/`](./agent) turn a short idea, or a list of events, into prompts of that kind: - [`SKILL.md`](./agent/streaming-video-prompt-rewrite/SKILL.md) for English prompts - [`SKILL_CN.md`](./agent/streaming-video-prompt-rewrite/SKILL_CN.md) for Chinese prompts Both live in [`agent/streaming-video-prompt-rewrite`](./agent/streaming-video-prompt-rewrite) and a coding agent can load either (for Claude Code, copy the folder into `.claude/skills/`). The matching `system_prompt.md` / `system_prompt_CN.md` also works as a system prompt for any LLM (its base section plus one mode's section, or `build_system_prompt(mode)` in `scripts/validate_prompt.py`), and the same script checks the rewritten prompts in either language. ## ⚡ Inference Backends The examples above use the native MovieRoll entry point. For framework integration, follow the corresponding backend guide; each guide includes its own environment, model assembly, and inference commands. | Backend | Documentation | |---|---| | SGLang Diffusion | [Setup and inference](./sglang_movieroll/README.md) | | vLLM-Omni | [Setup and inference](./vllm_omni_movieroll/README.md) | ## 🎓 Training MovieRoll is trained in four stages: ``` HunyuanVideo-1.5 480p T2V └─① Streaming SFT, single-event ──▶ MovieRoll-Base └─② Streaming SFT, multi-event ──▶ multi-event Base └─③ ODE initialization ──▶ few-step student ├─④ CuLT-DMD ──▶ MovieRoll-Distilled (text-to-video) └─④ CuLT-DMD with ACS ──▶ MovieRoll-Distilled (image-to-video) ``` See the [training guide](./docs/TRAINING.md) for data preparation, stage-specific configurations, and launch commands. ## 🙏 Acknowledgement - [HunyuanVideo-1.5](https://github.com/Tencent-Hunyuan/HunyuanVideo-1.5) - [LongLive](https://github.com/NVlabs/LongLive) - [Self Forcing](https://github.com/guandeh17/Self-Forcing) - [Causal Forcing](https://github.com/thu-ml/Causal-Forcing) - [Helios](https://github.com/PKU-YuanGroup/Helios) - [Rolling Forcing](https://github.com/TencentARC/RollingForcing) - [FlashAttention](https://github.com/Dao-AILab/flash-attention) - [SageAttention](https://github.com/thu-ml/SageAttention) - [SGLang](https://github.com/sgl-project/sglang) - [vLLM-Omni](https://github.com/vllm-project/vllm-omni) - [Qwen2.5-VL](https://github.com/QwenLM/Qwen2.5-VL) - [Glyph-ByT5](https://github.com/AIGText/Glyph-ByT5) ## ⭐ Star History [![Star History Chart](https://api.star-history.com/svg?repos=Tencent-Hunyuan/MovieRoll&type=Date)](https://star-history.com/#Tencent-Hunyuan/MovieRoll&Date) ## 📄 License MovieRoll was forked from [HunyuanVideo-1.5](https://github.com/Tencent-Hunyuan/HunyuanVideo-1.5) at commit `60783e7` and is released under the same [TENCENT HUNYUAN COMMUNITY LICENSE AGREEMENT](./LICENSE). ## 📚 Citation If you find our work useful, please cite: ```bibtex @misc{ge2026movierollsystematicframeworkrolling, title={MovieRoll: A Systematic Framework for Rolling Out Long-Form Videos}, author={Yunyang Ge and Weijie Kong and Ryan Xu and Yue Wu and Qi Tian and Jiangfeng Xiong and Bin Lin and Mingzhe Zheng and Shenghai Yuan and Zheyuan Liu and Jian-Wei Zhang and Li Yuan}, year={2026}, eprint={2611.21339}, archivePrefix={arXiv}, primaryClass={cs.CV}, url={https://arxiv.org/abs/2611.21339}, } ``` ## 📬 Contact For questions or collaboration, please contact [yunyang@stu.pku.edu.cn](mailto:yunyang@stu.pku.edu.cn).