## 📣Latest News
- [26/09/01] We've released the [hy4 preview MIX-STQ1_0 version](https://huggingface.co/AngelSlim/Hy4-preview-GGUF)! Compressed from 1.5TB to 214 GiB with only a 0.7% performance drop on SWE-bench Pro. Using [Prima.cpp](https://github.com/OpenCPIL/prima.cpp), we ran this 214 GB model on a Laptop 4090 (32GB RAM, 16GB VRAM) + a Server with 4x A4000 (32GB RAM, 16GB VRAM each), hitting 1.02 tokens/s. See the [blog](https://opencpil.github.io/prima.cpp/blog/hunyuan4-770b-local-devices) and the deployment [guideline](docs/source/_extra/hy4_preview_gguf_guideline.md)! 🔥🔥🔥
- [26/07/29] We have open-sourced **AngelSpec**, a torch-native, disaggregated speculative-decoding **training framework** with support for a variety of draft methods, led by **DFly** and **MTP + TTT**, and released the **MTP** and **DFly** drafter weights for **Hy3-A21B** — DFly delivers up to **2.40× average end-to-end speedup** over AR, and **D-cut** adds up to **+15.7%** throughput at high concurrency. [[Paper]](https://arxiv.org/abs/2607.25852) | [[GitHub]](https://github.com/Tencent/AngelSpec) | [[Docs]](https://angelspec.readthedocs.io/) | [[Hugging Face]](https://huggingface.co/collections/AngelSlim/angelspec) 🔥🔥🔥
- [26/07/20] We now support scale-only **quantization-aware distillation on Megatron-Core** for Qwen3-MoE and Hy3, with TP/EP/CP/SP distributed training. [[Docs]](docs/source/features/qad/mcore_qad.md)
- [26/07/06] We now support FP8-Static quantization , SmoothQuant for **Hy3** (MoE A21B).[[Docs]](https://github.com/Tencent/AngelSlim/tree/main/scripts/ptq)
- [26/06/04] We have released **Stem**, a sparse attention algorithm that accelerates the **Prefill** stage of long-context LLMs by dynamically selecting top-k key blocks for block-sparse attention, significantly reducing latency while preserving generation quality. [[Docs]](https://angelslim.readthedocs.io/zh-cn/latest/features/sparse_attention/stem.html)
- [26/06/01] We have released **DFlare**, a block-diffusion speculative decoding framework with layer-wise fusion that achieves up to **5.52× end-to-end speedup**. [[Docs]](https://angelslim.readthedocs.io/zh-cn/latest/features/speculative_decoding/dflare.html)
- [26/05/27] We have released **D-Cut**, an adaptive verification depth pruning technique for speculative decoding. [[Docs]](https://angelslim.readthedocs.io/zh-cn/latest/dcut.html)
- [26/05/20] We support Distillation for full-precision HuggingFace models and **quantized QAT-style** models, as detailed in the [distillation documentation](https://angelslim.readthedocs.io/zh-cn/latest/features/distill/index.html).
- [26/05/08] We have released STQ1_0 kernel for 1.25-bit model and given a PR to llama.cpp [PR #22836](https://github.com/ggml-org/llama.cpp/pull/22836) ! If you have any questions or suggestions for STQ_0, welcome to comment under the PR !🔥🔥🔥
- [26/04/29] We have released 2-bit and 1.25-bit versions of Tencent Hy-MT1.5-1.8B Translation Model: [Hy-MT1.5-1.8B-2bit](https://huggingface.co/AngelSlim/Hy-MT1.5-1.8B-2bit) and [Hy-MT1.5-1.8B-1.25bit](https://huggingface.co/AngelSlim/Hy-MT1.5-1.8B-1.25bit). Additionally, we have make an [offline translation demo](https://huggingface.co/AngelSlim/Hy-MT1.5-1.8B-1.25bit/blob/main/Hy-MT-demo.apk) for you to try out. We invite you to give it a spin! 🔥🔥🔥
- [26/04/23] We now support FP8-Static quantization for **Hy3-preview** (MoE A20B).
- [26/03/25] We have released **DAQ**, the quantization algorithm that preserves the knowledge acquired while the update of parameters is relatively small during post-training training.[[Paper]](https://arxiv.org/abs/2603.22324) | [[Docs]](docs/source/features/quantization/daq.md)
- [26/02/09] We have released HY-1.8B-2Bit, 2bit on-device large language model,[[Huggingface]](https://huggingface.co/AngelSlim/HY-1.8B-2Bit).
- [26/01/13] We have released v0.3. We support the training and deployment of Eagle3 for all-scale LLMs/VLMs/Audio models, as detailed in the [guidance documentation](https://angelslim.readthedocs.io/zh-cn/latest/features/speculative_decoding/eagle/index.html). And We released **Sherry**, the hardware-efficient 1.25 bit quantization algorithm [[Paper]](https://arxiv.org/abs/2601.07892) | [[Code]](https://github.com/Tencent/AngelSlim/tree/sherry/Sherry)🔥🔥🔥
Previous News
- [25/11/05] We have released v0.2. Quantization support for new models, such as `GLM-4.6`, `Qwen3-VL` and `Qwen3-Omni`, open-sources the Eagle3 speculative decoding training framework, and updates the Diffusion model quantization tools.
- [25/09/30] We have released **SpecExit**, the reasoning early-exit algorithm: [[Paper]](http://arxiv.org/abs/2509.24248) | [[Docs]](https://angelslim.readthedocs.io/zh-cn/latest/features/speculative_decoding/spec_exit.html) | [[vLLM Code]](https://github.com/vllm-project/vllm/pull/27192)
- [25/09/26] We have released **TEQUILA**, the ternary quantization algorithm [[Paper]](https://arxiv.org/abs/2509.23809) | [[Code]](https://github.com/Tencent/AngelSlim/tree/tequila/TernaryQuant)
- [25/09/24] We now support the PTQ quantization of NVFP4 for the Qwen3 series models. We also opensource [Qwen3-32B-NVFP4](https://huggingface.co/AngelSlim/Qwen3-32B_nvfp4) and [Qwen3-235B-A22B-NVFP4](https://huggingface.co/AngelSlim/Qwen3-235B-A22B_nvfp4) weights.
- [25/09/01] We now support FP8 quantization of the [Hunyuan-MT-7B](https://huggingface.co/tencent/Hunyuan-MT-7B-fp8) translation model. And enabled Torch inference and Benchmark evaluation for Eagle3. And implemented support for quantization and Cache for [FLUX](https://github.com/Tencent/AngelSlim/tree/main/configs/flux). And support quantization for the [Seed-OSS](https://github.com/Tencent/AngelSlim/tree/main/configs/seed_oss).
- [25/08/06] We now support quantization for `Hunyuan 0.5B/1.8B/4B/7B` and multimodal model `Qwen2.5VL 3B/7B/32B/72B`, including `FP8/INT4` algorithms, and quantization for `DeepSeek-R1/V3` and `Kimi-K2`, including `FP8-Static` and `W4A8-FP8` algorithms. We also opensource `Hunyuan 1.8B/4B/7B` series Eagle3 model weight.
- [25/07/04] We now support quantization for `Hunyuan/Qwen2.5/Qwen3/DeepSeek-R1-Distill-Qwen` and other models, including `INT8/FP8/INT4` algorithms. We also opensource `Qwen3` series Eagle3 model weight.
## 🌟Key Features
- **Highly Integrated**: This toolkit integrates mainstream compression algorithms into a unified framework, offering developers one-click access with exceptional ease of use.
- **Continuous Innovation**: Beyond integrating widely-used industry algorithms, we are continuously researching better compression algorithms, which will be gradually open-sourced in the future.
- **Performance-Driven**: We continuously optimize end-to-end performance in model compression workflows and algorithm deployment, such as enabling quantization of models like Qwen3-235B and DeepSeek-R1 on a single GPU.
## 💼Technical Overview
## 🛎️How to Use
### 1. Install AngelSlim
We recommend using `pip` to install the latest stable version of `AngelSlim`:
```shell
pip install angelslim
```
Alternatively, you can clone the repository and install from source in editable mode:
```shell
cd AngelSlim && python setup.py install
```
> **Note:** AngelSlim integrates the speculative-decoding training framework [AngelSpec](https://github.com/Tencent/AngelSpec) as a git submodule (under `third_party/AngelSpec/`). Clone with `--recursive`, or initialize in an existing clone:
>
> ```shell
> # Clone with submodules
> git clone --recursive https://github.com/Tencent/AngelSlim.git
> # Or, in an already-cloned repo
> git submodule update --init --recursive
> ```
For more detailed installation instructions and platform-specific guidance, please refer to the [Installation Documentation](https://angelslim.readthedocs.io/zh-cn/latest/getting_started/installation.html).
### 2. Quick Start
#### 2.1 Speculative Decoding
AngelSlim's speculative-decoding training is powered by **[AngelSpec](https://github.com/Tencent/AngelSpec)** (git submodule under `third_party/AngelSpec/`) — a torch-native framework for **training** speculative-decoding draft models, featuring a rich set of draft architectures, target-model support, and production-scale training. It supports a variety of draft methods, led by **DFly** and **MTP + TTT**.
It follows a **disaggregated design**: inference engines run the frozen target model and extract multi-layer hidden states, which a [Mooncake](https://github.com/kvcache-ai/Mooncake) store streams over RDMA (no disk staging) to the FSDP2 training workers, while a controller handles batching, backpressure, and evaluation. Inference and training run on separate GPU pools and scale independently.
**Capabilities:**
- **Multi-backend inference** — vLLM (first-class), SGLang, and HuggingFace.
- **Long-sequence training** — Ulysses sequence parallelism (USP) for 128k+ contexts.
- **Document-aware sequence packing** — with cross-document attention isolation.
- **Online evaluation** — spec-decode acceptance rate measured during training.
- **Multi-node** — large MoE target models sharded across nodes over Mooncake RDMA.
- **Vocabulary pruning** — shrink the draft `lm_head` to a smaller token set at train or convert time.
```shell
# Initialize the submodule (see Install section above)
git submodule update --init --recursive
cd third_party/AngelSpec
# Install AngelSpec + the vLLM backend
pip install -e ".[vllm]"
# Hidden-state transport (not pulled in by the extras; install separately)
pip install mooncake-transfer-engine
# Single-node quickstart (4 GPUs: 2 inference + 2 training)
./examples/qwen3-8b-single-node/run.sh
```
For more details, see the [technical report](https://arxiv.org/abs/2607.25852), [AngelSpec docs](https://angelspec.readthedocs.io/), [AngelSpec README](https://github.com/Tencent/AngelSpec/blob/main/README.md), and [Hugging Face weights](https://huggingface.co/collections/AngelSlim/angelspec).
#### 2.2 LLM/VLM/Audio Model Quantization
After installing `AngelSlim`, you can launch static FP8 quantization for the Qwen3-1.7B model with the following one-command script:
```shell
python3 tools/run.py -c configs/qwen3/fp8_static/qwen3-1_7b_fp8_static.yaml
```
This example produces quantized model weights by performing PTQ calibration on a model loaded from HuggingFace.
For **Hy3-preview** (MoE A20B) FP8-Static quantization:
```shell
python tools/run.py -c configs/hunyuan/fp8_static/hunyuanv3_a20b_fp8_static_c8.yaml
```
Code-based Start
To perform dynamic `FP8` quantization on `Qwen3-1.7B`:
```python
from angelslim.engine import Engine
slim_engine = Engine()
# Prepare model
slim_engine.prepare_model(model_name="Qwen", model_path="Qwen/Qwen3-1.7B",)
# Initialize compressor
slim_engine.prepare_compressor("PTQ", default_method="fp8_dynamic")
# Compress model
slim_engine.run()
# Save compressed model
slim_engine.save("./output")
```
For more details, please refer to the [Quick Start Documentation](https://angelslim.readthedocs.io/zh-cn/latest/getting_started/quickstrat.html).
#### 2.3 Diffusion Model Quantization
Use the `scripts/diffusion/run_diffusion.py` for quantization and inference:
```shell
# Online quantization and inference
python scripts/diffusion/run_diffusion.py \
--model-name-or-path black-forest-labs/FLUX.1-schnell \
--quant-type fp8-per-tensor \
--prompt "A cat holding a sign that says hello world" \
--height 1024 --width 1024 --steps 4 --guidance 0.0 --seed 0
```
For more quantization inference methods, please refer to [the Diffusion Model Quantization Documentation](https://angelslim.readthedocs.io/zh-cn/latest/features/diffusion/quantization.html).
#### 2.4 Token Compression (VLM)
AngelSlim provides a universal metadata-driven framework for vision token pruning and merging. You can quickly verify a compression strategy (e.g., **VisionZip**) with a smoke test:
```shell
python tools/test_universal_pruning.py \
--model_path "Qwen/Qwen2.5-VL-3B-Instruct" \
--config "configs/qwen2_5_vl/pruning/visionzip_r0.9.yaml"
```
For more details on implementing new strategies, please refer to the [Token Compressor Documentation](https://angelslim.readthedocs.io/zh-cn/latest/features/token_compressor/index.html).
### 3. Deployment and Testing
#### 3.1 Offline Inference
To test offline inference with a quantized model loaded via `transformers`.
Run script details
```shell
python scripts/deploy/offline.py $MODEL_PATH "Hello, my name is"
```
Where `MODEL_PATH` is the path to the quantized model output.
#### 3.2 API Service Deployment
After specifying the quantized model path `MODEL_PATH`, you can deploy an OpenAI-compatible API service using **vLLM** and **SGLang** inference frameworks.
Run script details
- **vLLM**
Use the following script to launch a [vLLM](https://github.com/vllm-project/vllm) server, recommended version `vllm>=0.8.5.post1`. For MOE INT8 quantized models, vllm>=0.9.0 is required.
```shell
bash scripts/deploy/run_vllm.sh --model-path $MODEL_PATH --port 8080 -d 0,1,2,3 -t 4 -p 1 -g 0.8 --max-model-len 4096
```
Where `-d` is the visible devices, `-t` is tensor parallel size, `-p` is pipeline parallel size, and `-g` is the GPU memory utilization.
- **SGLang**
Use the following script to launch a [SGLang](https://github.com/sgl-project/sglang) server, recommended version `sglang>=0.4.6.post1`.
```shell
bash scripts/deploy/run_sglang.sh --model-path $MODEL_PATH --port 8080 -d 0,1,2,3 -t 4 -g 0.8
```
#### 3.3 Service Invocation
Invoke requests via [OpenAI's API format](https://platform.openai.com/docs/api-reference/introduction).
Run script details
```shell
bash scripts/deploy/openai.sh -m $MODEL_PATH -p "Hello, my name is" --port 8080 --max-tokens 4096 --temperature 0.7 --top-p 0.8 --top-k 20 --repetition-penalty 1.05 --system-prompt "You are a helpful assistant."
```
where `-p` is the input prompt.
#### 3.4 Performance Evaluation
Evaluate the performance of quantized model using [lm-evaluation-harness](https://github.com/EleutherAI/lm-evaluation-harness), recommended version`lm-eval>=0.4.8`.
Run script details
```shell
bash scripts/deploy/lm_eval.sh -d 0,1 -t 2 -g 0.8 -r $RESULT_PATH -b "auto" --tasks ceval-valid,mmlu,gsm8k,humaneval -n 0 $MODEL_PATH
```
where `RESULT_PATH` is the directory for saving test results, `-b` is batch size, `--tasks` specifies the evaluation tasks, and `-n` is the number of few-shot examples.
For more detaileds, please refer to the [Deployment Documentation](https://angelslim.readthedocs.io/zh-cn/latest/deployment/deploy.html).
## 📈 Benchmark
### 1. Speculative Decoding
The results below come from **[AngelSpec](https://github.com/Tencent/AngelSpec)** — a torch-native, disaggregated speculative-decoding training framework, integrated into AngelSlim as a git submodule (see §2.1), with support for a variety of draft methods, led by **DFly** and **MTP + TTT**. [[Paper]](https://arxiv.org/abs/2607.25852) | [[Docs]](https://angelspec.readthedocs.io/) | [[Hugging Face]](https://huggingface.co/collections/AngelSlim/angelspec)
**✨ Highlights**
- **🏗️ Full-stack open source** — the AngelSpec training framework plus Hy3-A21B **MTP** / **DFly** drafter weights and training code, all released at once.
- **🚀 DFly leads across the board** — on Hy3-A21B, DFly delivers the highest throughput across all concurrency levels (4–64) and all six benchmarks — **1.98–2.40×** average speedup over the AR baseline (peak **2.86×** on code / math), and **10.5–11.8%** faster than DFlash.
- **📈 Substantially higher accepted length** — DFly reaches a mean accepted length of **4.79** — **+30%** over DFlash (3.69) and **~1.6×** over MTP (3.00) — up to **5.52** on HumanEval.
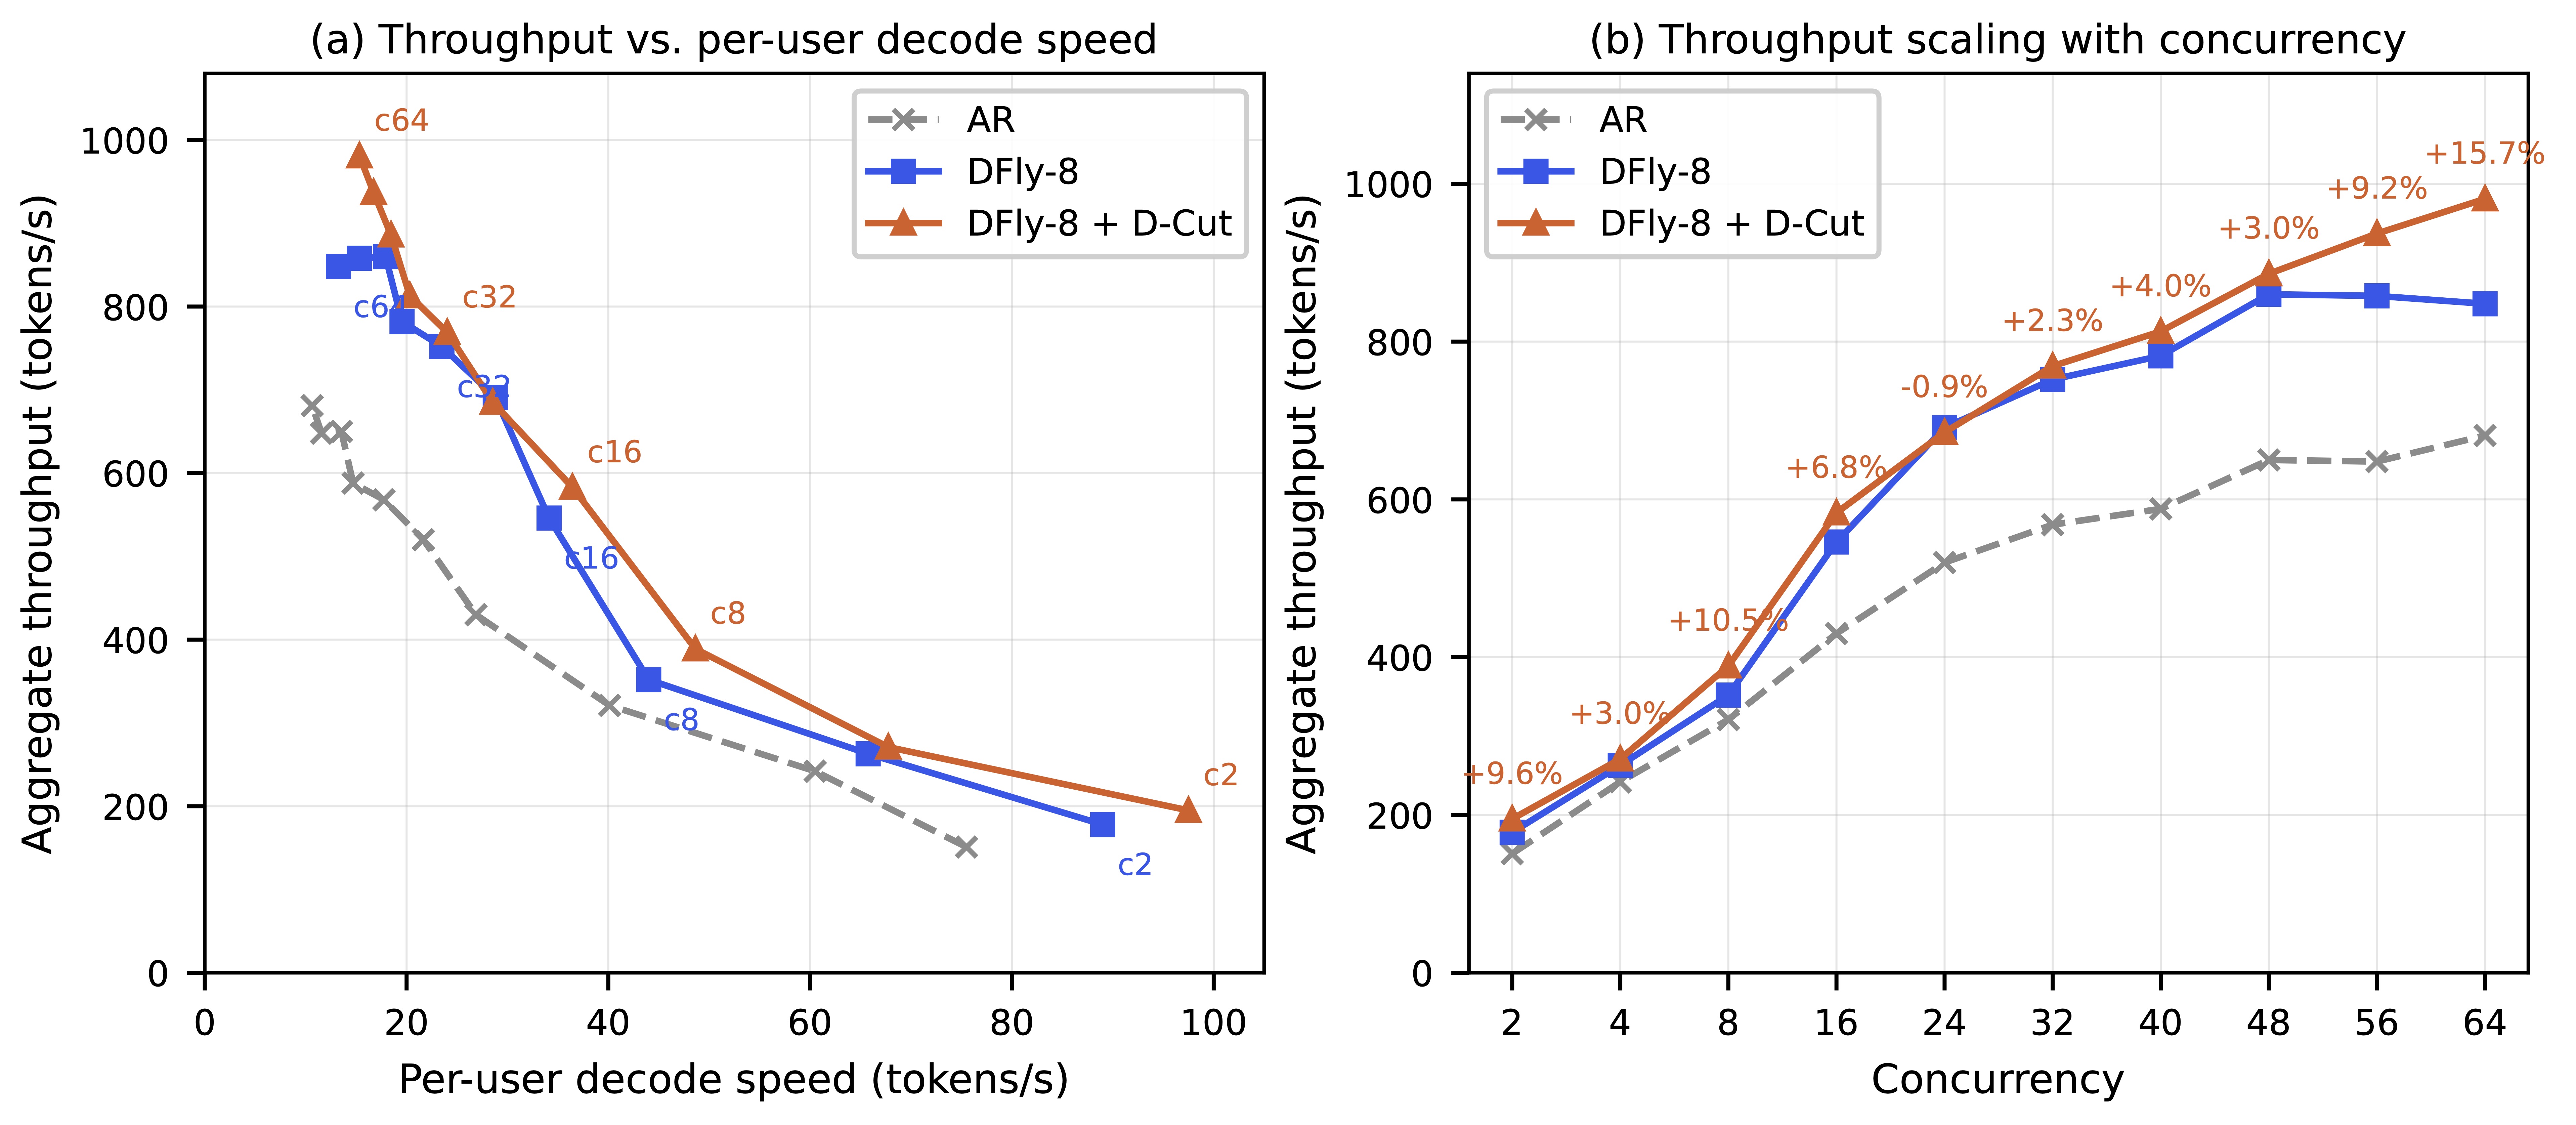
- **⚡ D-cut squeezes high concurrency** — on live traffic of a 295B model, it adds up to **+15.7%** throughput in the high-concurrency regime at near-zero cost (mean accepted length 2.50 → 2.46).
- **💬 MTP + TTT cracks chat** — fixes the train/inference mismatch: mean acceptance rate **52.8% → 66.4%**, mean accepted length **2.58 → 2.99**.
#### 1.1 🏆 Drafter Showdown — DFly Leads the Pack
**Draft quality — mean accepted length.** Measured on **Qwen3-8B** and **Hy3-A21B** across math / code / chat (temperature = 1, no thinking); **bold** marks the best drafter per target per benchmark. **DFly** leads on average — **5.41** on Qwen3-8B and **4.79** on Hy3-A21B — and tops nearly every benchmark, well ahead of DFlash and MTP.
Target Model
Drafter
Math
Code
Chat
Avg.
Math500
GSM8K
HumanEval
MBPP
LiveCodeBench
MT-Bench
Qwen3-8B
MTP
3.53
3.56
3.33
3.22
3.25
2.57
3.24
DFlash
4.97
5.54
4.77
4.50
4.46
3.16
4.57
DSpark
5.87
6.25
5.56
5.25
5.20
3.77
5.32
DFly
6.06
6.42
5.60
5.34
5.36
3.67
5.41
Hy3-A21B
MTP
3.30
3.30
3.13
3.04
2.84
2.40
3.00
DFlash
4.01
4.23
4.36
4.05
3.10
2.38
3.69
DFly
5.23
5.53
5.52
5.41
4.07
2.96
4.79
**End-to-end throughput on Hy3-295B-A21B.** Output-token throughput (Tok/s) and speedup (Spd.) over the AR baseline (TP=8, temperature 1, concurrency c4–c64; each cell = 3×120s windows). **Bold** marks the best speedup per benchmark at each concurrency; `MTP-3` uses 3 speculative tokens, `DFlash-8` / `DFly-8` use block length 8. **DFly-8** wins the average at every concurrency — **1.98×–2.40×** over AR, peaking at **2.86×** on HumanEval.
Conc.
Method
GSM8K
Math500
HumanEval
MBPP
LiveCodeBench
MT-Bench
Avg.
Tok/s
Spd.
Tok/s
Spd.
Tok/s
Spd.
Tok/s
Spd.
Tok/s
Spd.
Tok/s
Spd.
Tok/s
Spd.
c4
AR
287.9
1.00×
293.9
1.00×
279.7
1.00×
294.4
1.00×
284.5
1.00×
290.0
1.00×
288.4
1.00×
MTP-3
495.5
1.72×
517.0
1.76×
473.6
1.69×
476.7
1.62×
414.0
1.46×
384.5
1.33×
460.2
1.60×
DFlash-8
569.5
1.98×
587.9
2.00×
588.1
2.10×
575.7
1.96×
408.4
1.44×
371.6
1.28×
516.9
1.79×
DFly-8
635.4
2.21×
643.9
2.19×
647.2
2.31×
661.5
2.25×
455.2
1.60×
384.0
1.32×
571.2
1.98×
c8
AR
426.3
1.00×
435.7
1.00×
400.3
1.00×
433.7
1.00×
413.4
1.00×
421.8
1.00×
421.8
1.00×
MTP-3
756.9
1.78×
791.5
1.82×
717.4
1.79×
729.1
1.68×
620.8
1.50×
590.1
1.40×
701.0
1.66×
DFlash-8
857.0
2.01×
860.1
1.97×
866.2
2.16×
866.2
2.00×
609.1
1.47×
545.5
1.29×
767.4
1.82×
DFly-8
964.8
2.26×
959.5
2.20×
974.1
2.43×
1001.5
2.31×
641.3
1.55×
565.8
1.34×
851.2
2.02×
c16
AR
650.7
1.00×
670.6
1.00×
594.8
1.00×
667.9
1.00×
617.2
1.00×
628.1
1.00×
638.2
1.00×
MTP-3
1146.6
1.76×
1174.0
1.75×
1076.1
1.81×
1103.3
1.65×
893.5
1.45×
876.6
1.40×
1045.0
1.64×
DFlash-8
1446.1
2.22×
1430.4
2.13×
1433.3
2.41×
1440.4
2.16×
970.5
1.57×
901.0
1.43×
1270.3
1.99×
DFly-8
1623.8
2.50×
1607.5
2.40×
1595.4
2.68×
1677.8
2.51×
1046.7
1.70×
961.5
1.53×
1418.8
2.22×
c32
AR
918.6
1.00×
1000.8
1.00×
850.8
1.00×
1018.7
1.00×
893.2
1.00×
921.1
1.00×
933.9
1.00×
MTP-3
1923.8
2.09×
1989.8
1.99×
1780.7
2.09×
1863.6
1.83×
1394.2
1.56×
1469.4
1.60×
1736.9
1.86×
DFlash-8
2261.8
2.46×
2334.3
2.33×
2170.6
2.55×
2339.3
2.30×
1489.9
1.67×
1453.4
1.58×
2008.2
2.15×
DFly-8
2527.4
2.75×
2608.9
2.61×
2429.1
2.86×
2741.3
2.69×
1602.6
1.79×
1549.4
1.68×
2243.1
2.40×
c64
AR
1156.9
1.00×
1381.3
1.00×
1197.6
1.00×
1513.9
1.00×
1229.6
1.00×
1306.9
1.00×
1297.7
1.00×
MTP-3
2932.0
2.53×
3170.0
2.29×
2639.6
2.20×
3011.3
1.99×
2050.4
1.67×
2350.0
1.80×
2692.2
2.08×
DFlash-8
2523.4
2.18×
2947.1
2.13×
2655.2
2.22×
2671.8
1.76×
2015.8
1.64×
1815.8
1.39×
2438.2
1.89×
DFly-8
2827.8
2.44×
3301.8
2.39×
2965.0
2.48×
3130.9
2.07×
2195.0
1.79×
1936.6
1.48×
2726.2
2.11×
#### 1.2 ⚡ D-cut — Breaking the Concurrency Ceiling
When concurrency climbs, target verification becomes the bottleneck and rejected draft suffixes clog the batch. **D-cut** treats verification as a shared batch budget — ranking each request's verification depth by expected gain / cost, deepening drafts when the system is idle and trimming them when it's slammed. The payoff lands exactly where DFly plateaus: past concurrency 48, D-cut keeps turning load into throughput, up to **+15.7%** over DFly at near-zero quality cost (accepted length 2.50 → 2.46).
### 2. Quantization
The performance test results for selected models are shown below. For the complete benchmark, refer to the [Benchmark documentation](https://angelslim.readthedocs.io/zh-cn/latest/performance/quantization/benchmarks.html)
#### 2.1 Hunyuan Series Models
Benchmark results for the `Hunyuan-Instruct` model with `FP8`, `INT4-AWQ` and `INT4-GPTQ` quantization algorithms on datasets including`OlympiadBench`, `AIME 2024` and `DROP`:
Model
Quantization
OlympiadBench
AIME 2024
DROP
GPQA-Diamond
Hunyuan-A13B-Instruct
BF16
82.7
87.30
91.1
71.2
FP8-Static
83.0
86.7
91.1
-
Int4-GPTQ
82.7
86.7
91.1
-
Int4-AWQ
82.6
85.6
91.0
-
Hunyuan-7B-Instruct
BF16
76.5
81.1
85.9
60.1
FP8-Static
76.6
80.9
86.0
60.1
Int4-GPTQ
76.2
81.0
85.7
60.0
Int4-AWQ
76.4
80.9
85.9
60.1
Hunyuan-4B-Instruct
BF16
73.1
78.3
78.2
61.1
FP8-Static
73.1
76.6
78.3
60.2
Int4-GPTQ
72.9
-
78.1
58.1
Int4-AWQ
72.8
-
78.2
-
Hunyuan-1.8B-Instruct
BF16
63.4
56.7
76.7
47.2
FP8-Static
62.5
55.2
75.1
47.7
Int4-GPTQ
60.9
-
73.0
44.4
Int4-AWQ
61.7
-
71.7
43.6
Hunyuan-0.5B-Instruct
BF16
29.6
17.2
52.8
23.3
FP8-Static
29.6
17.2
51.6
22.5
Int4-GPTQ
26.8
-
50.9
23.3
Int4-AWQ
26.3
-
48.9
23.3
#### 2.2 Qwen3 Series Models
Benchmark results for Qwen3 series models with `FP8-Static`, `FP8-Dynamic`, `INT4-GPTQ`, and `INT4-AWQ` quantization algorithms on datasets including `CEVAL`, `MMLU`, `GSM8K`, and `HUMANEVAL`:
Model
Quantization
CEVAL
MMLU
GSM8K
HUMANEVAL
Qwen3-0.6B
BF16
45.84
47.21
42.99
19.51
FP8-Static
45.99
46.87
38.06
18.90
FP8-Dynamic
45.99
46.93
38.29
20.73
INT8-Dynamic
45.17
46.95
41.17
21.34
Qwen3-8B
BF16
79.27
74.78
87.79
63.41
FP8-Static
78.23
74.79
86.96
62.20
FP8-Dynamic
78.45
74.75
87.64
62.80
INT8-Dynamic
78.01
74.84
86.96
67.07
INT4-GPTQ
77.19
73.26
86.43
62.20
INT4-AWQ
76.15
73.59
86.96
63.41
Qwen3-14B
BF16
83.06
78.90
88.40
55.49
FP8-Static
82.62
78.57
89.46
57.32
FP8-Dynamic
82.24
78.92
88.32
52.44
INT8-Dynamic
81.87
78.13
86.28
56.10
INT4-GPTQ
81.05
78.02
87.34
57.93
INT4-AWQ
82.02
77.68
84.23
61.59
Qwen3-32B
BF16
86.55
82.00
74.53
37.80
FP8-Static
86.92
81.78
70.20
39.63
FP8-Dynamic
86.55
81.89
70.43
38.41
INT4-GPTQ
86.18
81.01
-
43.29
INT4-AWQ
86.18
81.54
-
36.59
Qwen3-30B-A3B
BF16
83.66
79.36
89.99
31.71
FP8-Static
83.95
79.47
89.01
31.10
FP8-Dynamic
84.10
79.40
89.16
32.93
INT8-Dynamic
83.36
79.48
89.16
34.15
Qwen3-235B-A22B
BF16
89.60
86.28
85.29
27.44
FP8-Static
89.67
86.19
86.96
27.44
FP8-Dynamic
89.67
86.18
85.22
28.05
INT8-Dynamic
88.93
86.20
86.20
23.78
#### 2.3 DeepSeek Series Models
Benchmark results for DeepSeek-R1-0528 series models with `FP8-Block-Wise` and `W4A8-FP8` quantization algorithms on datasets including `GPQA Diamond`、`AIME 2024`、`SimpleQA` and `LiveCodeBench`:
Model
Quantization
GPQA Diamond
AIME 2024
SimpleQA
LiveCodeBench
DeepSeek-R1-0528
FP8-Block-Wise
78.28
88.67
27.8
77.1
W4A8-FP8
77.37
88.67
26.83
78.86
Note
> - The above results are based on the average of 5 test runs deployed with TRT-LLM
> - The hyperparameters used during evaluation are as follows:
> ```json
>{
> "top_k": 20,
> "top_p": 0.6,
> "temperature": 0.7,
> "output_seq_len": 32768,
> "max_input_seq_len": 16384
>}
>```
#### 2.4 Qwen-VL Series Models
**Qwen3-VL Benchmark**
Benchmark results for Qwen3VL series models with `BF16`、`FP8-Static` and `FP8-Dynamic` quantization algorithms on datasets including `MMMU_VAL`、`DocVQA_VAL` and `ChartQA_TEST`:
Model
Quantization
MMMU_VAL
DocVQA_VAL
ChartQA_TEST
Qwen3-VL-32B-Instruct
BF16
60.11
96.08
94.64
FP8-Static
61.22
96.00
94.64
FP8-Dynamic
60.78
96.19
94.72
Qwen3-VL-30B-A3B-Instruct
BF16
50.44
95.28
95.36
FP8-Dynamic
50.67
95.25
95.20
Qwen2.5VL Benchmark
Benchmark results for Qwen2.5VL series models with `BF16`、`FP8-Static`、`FP8-Dynamic`、`INT4-GPTQ`、`INT4-AWQ` quantization algorithms on datasets including `MMMU_VAL`、`DocVQA_VAL` and `ChartQA_TEST`:
Model
Quantization
MMMU_VAL
MMLDocVQA_VALU
ChartQA_TEST
Qwen2.5VL-3B
BF16
47.11
78.57
80.32
FP8-Static
47.33
79.34
79.68
FP8-Dynamic
45.99
46.93
38.29
INT4-GPTQ
46.56
77.20
78.96
INT4-AWQ
45.78
-
79.60
Qwen2.5VL-7B
BF16
45.44
89.71
84.64
FP8-Static
47.00
89.83
85.92
FP8-Dynamic
47.22
89.80
88.64
INT4-GPTQ
46.67
90.45
-
INT4-AWQ
45.67
89.28
-
Qwen2.5VL-32B
BF16
57.00
90.03
-
FP8-Static
57.00
89.88
-
FP8-Dynamic
56.44
89.88
-
INT4-GPTQ
55.22
89.80
-
INT4-AWQ
55.22
90.30
-
Qwen2.5VL-72B
BF16
58.78
94.39
85.60
FP8-Static
57.89
94.41
85.84
FP8-Dynamic
58.67
94.38
85.60
INT4-GPTQ
57.56
94.46
86.48
INT4-AWQ
58.78
94.19
87.28
#### 2.5 Qwen-Omni Series Models
**Qwen3-Omni Text to Text Benchmark**
Benchmark results for Qwen3-Omni series models in BF16, FP8-Static, and FP8-Dynamic on aime25, gpqa_diamond, and mmlu_redux are as follows:
Model
Quantization
aime25
gpqa_diamond
mmlu_redux
Qwen3-Omni-30B-A3B-Instruct
BF16
73.32
56.77
88.09
FP8-Static
71.33
56.57
87.91
FP8-Dynamic
73.33
55.15
88.07
Note
> - The above evaluation results were obtained by deploying with the vLLM framework and averaging over 5 runs (vLLM only supports the thinker component).
> - The hyperparameters used during evaluation are as follows:
> ```json
>{
> "top_p": 0.95,
> "temperature": 0.6,
> "do_sample": true,
> "max-model-len 65536": 65536
>}
>```
#### 2.6 Other Models
Other models such as GLM-4.6, Qwen2.5, and Seed-OSS have been evaluated on benchmarks like `CEVAL`, `MMLU`, and `GSM8K` using quantization strategies including `FP8-Static`, `FP8-Dynamic`, `INT4-GPTQ`, and `INT4-AWQ`.
Benchmark Experiment Details
Model
Quantization
CEVAL
MMLU
GSM8K
Qwen2.5-1.5B-Instruct
BF16
67.01
60.05
54.28
FP8-Static
66.27
60.23
-
FP8-Dynamic
66.79
60.08
51.71
Qwen2.5-7B-Instruct
BF16
81.20
74.55
79.98
FP8-Static
81.13
74.03
79.30
FP8-Dynamic
80.31
74.07
79.00
INT4-GPTQ
79.05
73.05
74.75
INT4-AWQ
79.35
73.22
79.38
Qwen2.5-32B-Instruct
BF16
87.30
83.21
81.73
FP8-Static
87.59
83.08
81.58
FP8-Dynamic
87.30
83.04
81.58
INT4-GPTQ
86.70
82.45
82.03
INT4-AWQ
87.00
82.64
-
DeepSeek-R1-Distill-Qwen-7B
BF16
53.49
53.80
75.74
FP8-Static
53.57
54.17
76.19
FP8-Dynamic
52.97
54.13
74.15
INT4-GPTQ
51.86
52.44
75.89
INT4-AWQ
53.49
53.70
-
DeepSeek-R1-Distill-Qwen-14B
BF16
77.71
74.28
85.67
FP8-Static
77.56
74.66
86.73
FP8-Dynamic
76.82
74.63
87.11
INT4-GPTQ
74.29
72.37
84.61
INT4-AWQ
74.81
73.00
86.05
DeepSeek-R1-Distill-Qwen-32B
BF16
84.18
80.89
87.41
FP8-Static
83.43
80.90
87.57
FP8-Dynamic
83.73
81.10
86.43
INT4-GPTQ
84.10
79.80
86.73
INT4-AWQ
82.84
80.15
87.19
### 3. Token Compression (VLM)
We evaluated various vision token compression strategies on the **Qwen2.5-VL-3B-Instruct** model across multiple multimodal benchmarks. You can replicate these results using the following command:
```shell
python tools/run_pruning_eval.py \
--model_path "Qwen/Qwen2.5-VL-3B-Instruct" \
--configs "configs/qwen2_5_vl/pruning/visionzip_r0.9.yaml" \
--tasks "textvqa" \
--output_dir "./results/visionzip_test"
```
Detailed Benchmark Results (Qwen2.5-VL-3B-Instruct)
Method
AI2D
ChartQA
DocVQA
MMBCN
MMB
MME
MMStar
OCRBench
POPE
SQA
VQAText
Avg
Baseline
79.11
83.56
92.48
73.28
77.32
1517
56.05
80.10
87.41
80.81
78.79
100.0%
Retain 25% Tokens (75% Compression Ratio)
FastV
72.70
70.04
75.98
63.40
66.92
1437
47.39
36.60
86.42
79.33
73.51
86.02%
VisionZip
74.19
71.32
70.11
67.35
71.22
1452
49.37
42.50
85.51
81.36
68.12
87.34%
HiPrune
73.83
72.76
72.10
67.27
72.34
1449
48.93
41.30
85.86
80.91
69.27
87.67%
VisionSelector
75.19
73.72
90.24
68.81
72.59
1521
49.97
61.80
85.36
80.37
76.86
93.62%
DivPrune
73.06
62.96
78.46
67.10
71.82
1459
48.38
51.40
86.81
80.22
68.91
88.15%
DART
71.08
65.20
79.72
65.38
71.05
1428
48.78
41.80
80.97
80.91
68.25
86.17%
VisPruner
74.29
68.20
72.52
67.35
70.88
1458
49.74
44.80
86.59
81.46
69.62
87.87%
SCOPE
75.84
74.00
82.40
68.81
72.94
1471
50.35
56.00
86.62
80.96
74.04
91.98%
IDPruner
75.94
75.84
90.00
69.42
73.80
1505
49.49
64.90
86.26
80.42
76.90
94.42%
Retain 10% Tokens (90% Compression Ratio)
FastV
65.87
29.72
36.89
48.37
51.98
1257
37.28
13.90
79.50
77.05
57.75
65.30%
VisionZip
67.65
51.60
37.88
59.62
63.06
1338
42.82
21.40
81.14
80.47
51.56
72.75%
HiPrune
67.75
53.20
41.15
59.45
63.14
1326
41.08
20.30
80.90
80.96
53.31
73.00%
VisionSelector
70.50
65.92
79.94
59.97
64.69
1374
42.86
45.20
82.66
80.61
71.57
84.42%
DivPrune
67.71
43.12
58.03
61.25
65.12
1389
40.43
27.90
82.24
79.18
56.87
75.50%
DART
67.49
47.56
60.23
57.99
63.83
1299
42.18
23.40
74.20
78.63
58.02
74.09%
VisPruner
67.75
47.92
48.65
59.28
63.32
1305
41.51
22.50
78.74
79.77
54.95
73.19%
SCOPE
69.75
56.24
55.01
64.26
67.18
1390
44.35
30.80
83.34
80.47
62.58
79.37%
IDPruner
71.79
63.32
79.38
63.57
68.21
1438
44.05
45.50
84.51
80.57
70.02
85.71%
## 📝 License
The code for this project is open-sourced under the [License for AngelSlim](LICENSE).
## 🔗 Citation
```
@article{angelslim2026,
title={AngelSlim: A more accessible, comprehensive, and efficient toolkit for large model compression},
author={Hunyuan AI Infra Team},
journal={arXiv preprint arXiv:2602.21233},
year={2026}
}
```
## 💬 Technical Discussion
* AngelSlim is developed by the Tencent Hunyuan AI Infra team, with new features being iteratively updated. If you have any questions or suggestions, please submit them on [GitHub Issues](https://github.com/Tencent/AngelSlim/issues) or join our [WeChat discussion group](./docs/source/assets/angel_slim_wechat.png).
* ⭐ Star this repo to follow our latest progress. And if you are interested in joining us for an internship or full-time position, send your resume to: lucayu@tencent.com.