WeChat Vision # WeVisOne-VL ### Unified Visual Perception from Objects to Pixels

Project Page Paper WeVisOne-VL-2B WeVisOne-VL-4B 2B Demo 4B Demo License

**English** | [็ฎ€ไฝ“ไธญๆ–‡](README_zh-CN.md)
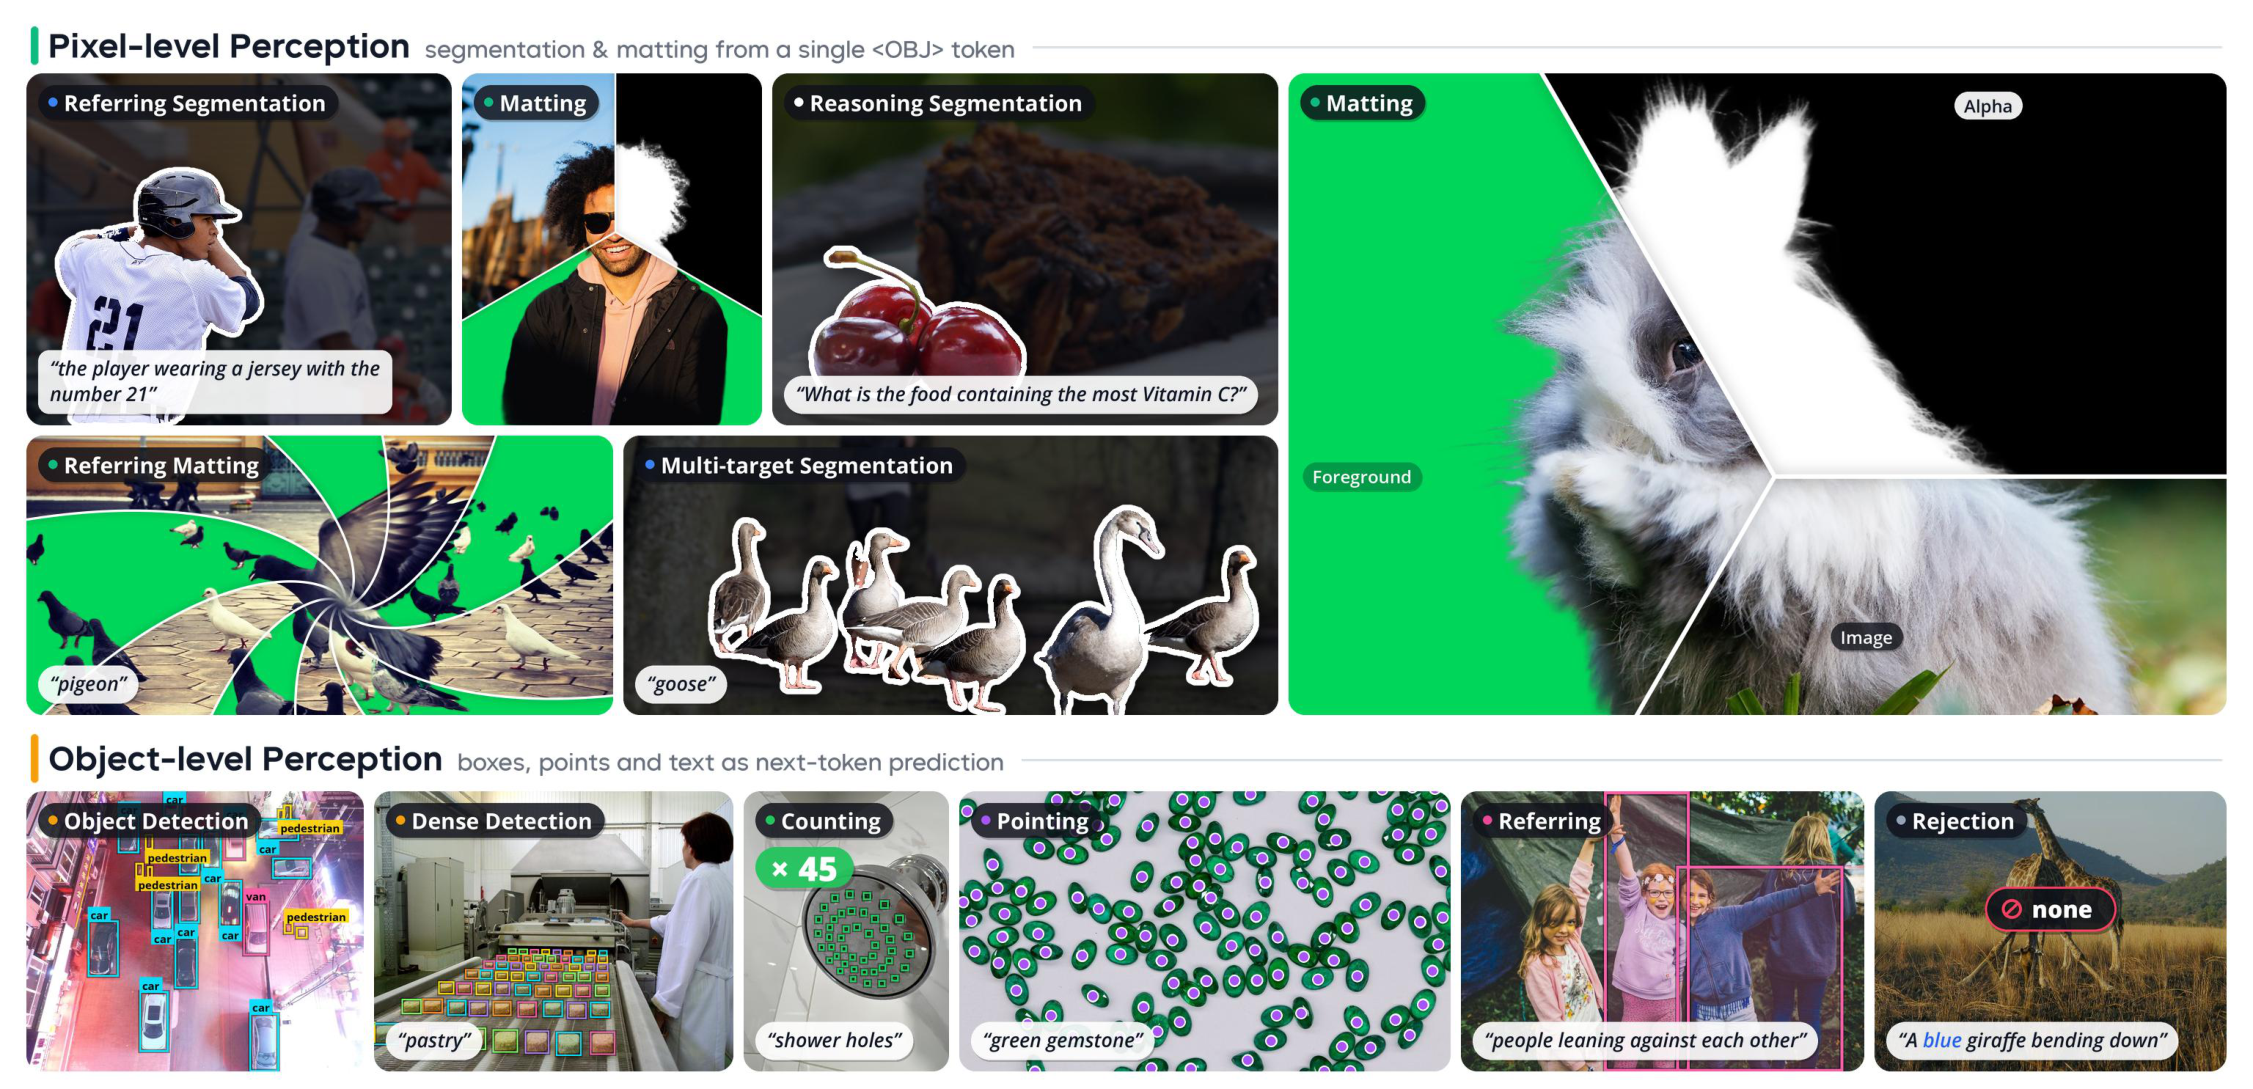
> **WeVisOne-VL** (**We**Chat **Vis**ion All-in-**One**) is a vision-language foundation model that unifies **object-level** perception (object detection, referring localization, counting, pointing, and OCR) and **pixel-level** perception (referring segmentation and promptable alpha matting) through structured next-token prediction and a lightweight 9.6M-parameter pixel decoderโ€”enabling localization at any user-specified granularity from points and boxes to binary masks and continuous alpha mattes, while reliably rejecting absent-target queries. ![Overview of WeVisOne-VL](assets/teaser.png) ## โœจ Highlights - ๐ŸŽฏ **All-in-One**: detection, referring, counting, pointing, OCR, segmentation and matting in a single model. - ๐Ÿชถ **Lightweight Pixel Decoder**: a 9.6M-parameter decoder outputs masks and alpha mattes, with no SAM required. - ๐Ÿšซ **Reliable Rejection**: returns `None` for absent targets instead of hallucinating. ## ๐Ÿ“ข News - **[2026-10]** ๐ŸŽฎ The demo is ready to try: [2B](https://huggingface.co/spaces/hugging-apps/wevisone-vl-2b) / [4B](https://huggingface.co/spaces/hugging-apps/wevisone-vl-4b). - **[2026-10] ๐Ÿ”ฅ๐Ÿ”ฅ We also open-sourced [Mask2Alpha](https://github.com/Tencent/WeVisOne-VL/tree/mask2alpha), the matting annotator used in the WeVisOne-VL Data Engine to turn binary masks into high-quality alpha mattes!** Check out the [`mask2alpha`](https://github.com/Tencent/WeVisOne-VL/tree/mask2alpha) branch. - **[2026-10]** ๐ŸŽ‰ We release the technical report, model weights (2B & 4B), inference package, Cookbooks, and evaluation pipeline! ## ๐Ÿ“ TODO - [x] Inference package and Cookbooks - [x] Gradio web demo - [x] Benchmark evaluation pipeline - [x] Model weights (2B & 4B) on Hugging Face - [x] Release our matting annotator - [ ] Fine-tuning code ## ๐Ÿ† Performance at a Glance Headline numbers for **WeVisOne-VL-4B** against the strongest open baseline in each benchmark (Qwen3-VL / Qwen3.5 up to 9B, Rex-Omni, LocateAnything, and task-specific segmentation / matting models). | Task | Benchmark | Metric | Best Baseline | **WeVisOne-VL-4B** | | ------------------ | -------------------- | ----------- | ------------- | ------------------ | | ๐Ÿ“ฆ Detection | LVIS | F1 Mean โ†‘ | 50.7 | **55.3** | | ๐Ÿ“ฆ Dense Detection | Dense200 | F1 Mean โ†‘ | 58.7 | **71.3** | | ๐Ÿ’ฌ Referring | RefCOCOg test | F1 Mean โ†‘ | 77.6 | **81.8** | | ๐Ÿšซ Rejection | WeRef-Bench | Rej. Rate โ†‘ | 73.0 | **96.4** | | ๐Ÿ”ข Counting | PixMo-Count test | Acc โ†‘ | 82.8 | **89.6** | | ๐Ÿ“ Pointing | PointBench | Acc โ†‘ | 69.9 | **71.9** | | ๐Ÿ”ค OCR | TotalText | F1 Mean โ†‘ | 43.3 | **52.0** | | ๐ŸŽญ Referring Seg. | ReasonSeg val | gIoU โ†‘ | 65.0 | **71.2** | | โœ‚๏ธ Box Matting | P3M-500-NP | MAD โ†“ | 15.4 | **7.3** | | โœ‚๏ธ Text Matting | WeRefMat (Referring) | MAD โ†“ | 22.4 | **9.8** | #### ๐Ÿ“Š Full Benchmark Results (click each task to expand) F1 for detection, referring and OCR is averaged over IoU thresholds 0.5:0.95 ("Mean"). Greedy decoding, โ‰ค 1,960 visual tokens per image.
Object Detection (F1 Mean) | Method | COCO | LVIS | Dense200 | VisDrone | | ------------------ | -------- | -------- | -------- | -------- | | GroundingDINO-T | 56.6 | 38.8 | 33.1 | 38.5 | | Qwen3-VL-8B | 47.8 | 42.9 | 13.8 | 29.5 | | Qwen3.5-9B | 49.5 | 43.7 | 18.0 | 31.3 | | Rex-Omni-3B | 52.9 | 46.9 | 58.3 | 35.8 | | LocateAnything-3B | 54.7 | 50.7 | 58.7 | 39.9 | | **WeVisOne-VL-2B** | 55.2 | 53.3 | 61.4 | 40.4 | | **WeVisOne-VL-4B** | **57.1** | **55.3** | **71.3** | **44.7** |
Referring Object Detection (F1 Mean / Rejection Rate %) | Method | RefCOCOg test | RefCOCOg Rej | WeRef Mean | WeRef Rej | HumanRef | Ref-L4 | | ------------------ | ------------- | ------------ | ---------- | --------- | -------- | -------- | | Qwen3-VL-8B | 74.9 | 22.5 | 36.7 | 18.3 | 71.6 | 72.4 | | Qwen3.5-9B | 74.6 | 15.2 | 50.7 | 70.7 | 77.8 | 72.0 | | Rex-Omni-3B | 74.3 | 0.5 | 50.3 | 43.3 | 79.9 | 65.2 | | LocateAnything-3B | 77.6 | 0.6 | 51.7 | 73.0 | 78.7 | 74.3 | | **WeVisOne-VL-2B** | 78.2 | 50.2 | 73.2 | 92.9 | 77.4 | 75.1 | | **WeVisOne-VL-4B** | **81.8** | **67.4** | **78.7** | **96.4** | **80.7** | **78.1** |
Object Counting (Exact-match Accuracy %) | Method | CountQA | PixMo-Count test | CLOC test | KubriCount testB | MixCount test | | ------------------ | -------- | ---------------- | --------- | ---------------- | ------------- | | Qwen3.5-9B | 41.6 | 80.4 | 22.4 | 19.1 | 7.0 | | Rex-Omni-3B | 37.6 | 71.9 | 22.3 | 18.8 | 11.4 | | LocateAnything-3B | 52.4 | 82.8 | 23.9 | 22.4 | 15.2 | | **WeVisOne-VL-2B** | 47.9 | 88.1 | 26.9 | 32.4 | 32.2 | | **WeVisOne-VL-4B** | **57.1** | **89.6** | **28.3** | **40.1** | **40.4** |
Object Pointing | Method | PointBench | PixMo-Points | COCO | LVIS | Dense200 | VisDrone | | ------------------ | ---------- | ------------ | -------- | -------- | -------- | -------- | | Qwen3-VL-8B | 62.5 | 72.2 | 77.5 | 67.7 | 42.2 | 46.4 | | Rex-Omni-3B | 69.9 | 72.9 | 80.5 | 70.8 | 82.5 | 58.9 | | LocateAnything-3B | 56.9 | 68.6 | 83.9 | 76.6 | **87.6** | 60.4 | | **WeVisOne-VL-2B** | 62.9 | 73.2 | **85.8** | 78.9 | 83.2 | 62.4 | | **WeVisOne-VL-4B** | **71.9** | **74.7** | 85.4 | **79.5** | 87.0 | **64.4** |
OCR โ€” Text Grounding & Recognition (F1 Mean) | Method | HierText | ICDAR2015 | TotalText | SROIE | | --------------------- | -------- | --------- | --------- | -------- | | PP-OCRv5 (specialist) | 30.5 | 25.6 | 25.7 | 58.6 | | Qwen3-VL-8B | 25.7 | 27.1 | 35.4 | 43.3 | | Rex-Omni-3B | 28.0 | 28.1 | 40.6 | 44.8 | | LocateAnything-3B | 29.4 | 24.1 | 43.3 | 40.3 | | **WeVisOne-VL-2B** | 30.5 | 42.6 | 42.5 | 62.1 | | **WeVisOne-VL-4B** | **39.0** | **47.8** | **52.0** | **68.1** |
Referring Segmentation (cIoU; ReasonSeg uses gIoU) | Method | RefCOCO testA | RefCOCO+ testA | RefCOCOg test | ReasonSeg val | Ref-ZOM cIoU | Ref-ZOM Rej | | ------------------ | ------------- | -------------- | ------------- | ------------- | ------------ | ----------- | | LISA-13B (ft) | 78.8 | 70.2 | 70.5 | 65.0 | - | - | | GSVA-7B | 78.9 | 69.6 | 73.3 | 50.5 | 66.6 | 41.9 | | UniPixel-7B | 83.0 | 80.1 | 77.1 | 60.5 | 62.9 | 0.3 | | Youtu-VL-4B | 82.0 | 79.6 | 76.6 | - | 61.0 | 1.3 | | **WeVisOne-VL-2B** | 82.9 | 79.0 | 74.9 | 60.9 | **73.4** | 62.4 | | **WeVisOne-VL-4B** | **84.5** | **81.1** | **77.8** | **71.2** | 72.2 | **86.0** |
Promptable Matting (MAD ร—10ยณ โ†“) | Method | P3M-500-NP (Box) | AM-2K (Box) | PPM-100 (Box) | WeRefMat (Category) | WeRefMat (Referring) | | ------------------------- | ---------------- | ----------- | ------------- | ------------------- | -------------------- | | Matte Anything | 24.4 | 13.2 | 10.5 | - | - | | SAM2-Matting (SAM3) | 15.4 | 12.1 | 10.8 | 70.8 | 51.9 | | Qwen3.5-9B + SAM2-Matting | - | - | - | 77.8 | 22.4 | | **WeVisOne-VL-2B** | **6.6** | 5.7 | **5.3** | 17.7 | 15.8 | | **WeVisOne-VL-4B** | 7.3 | **5.0** | 6.1 | **16.4** | **9.8** |
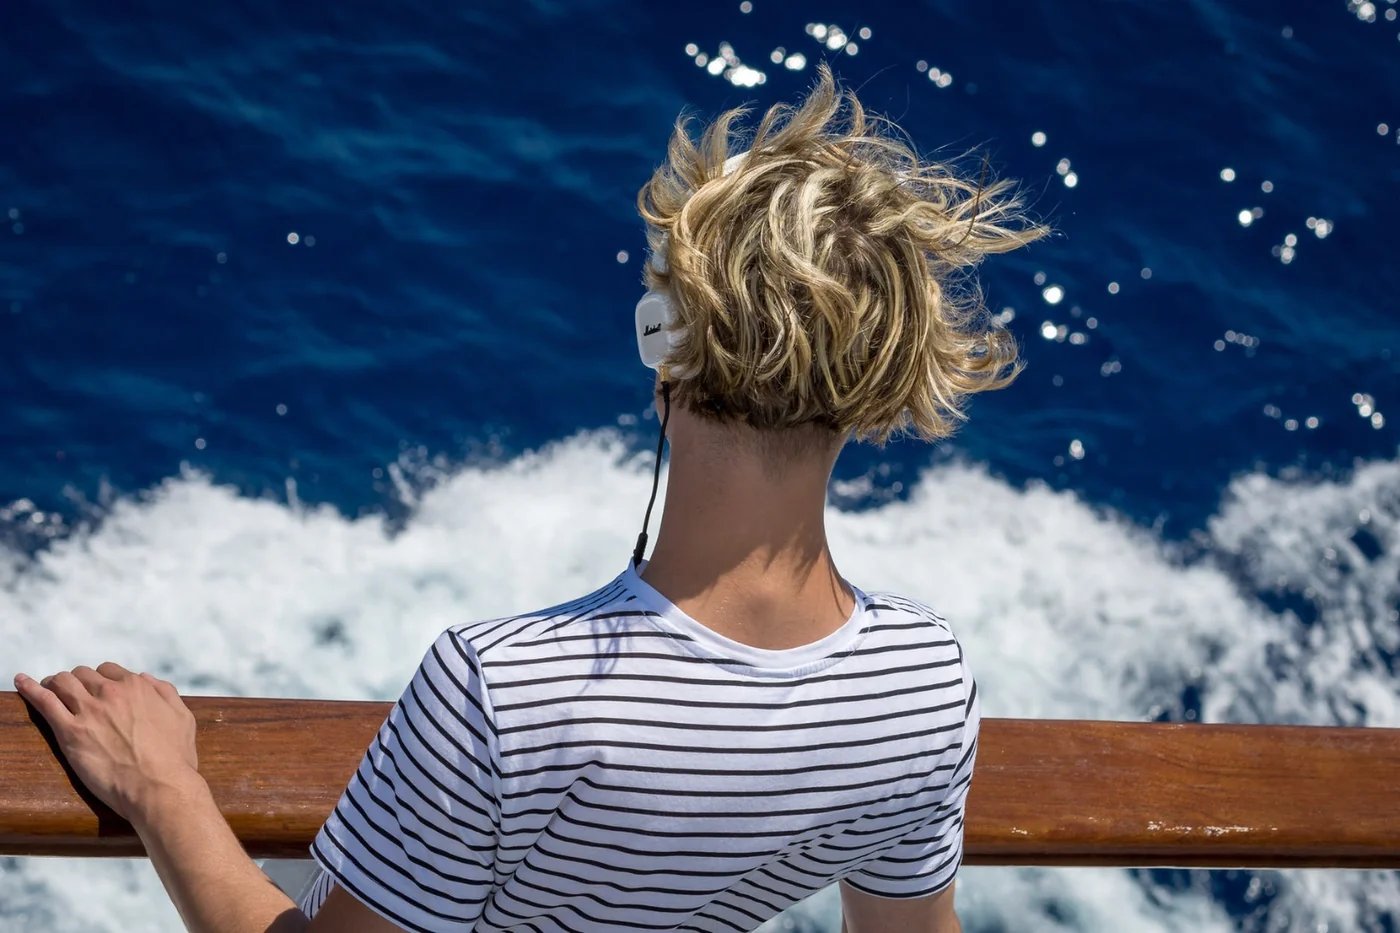
See the technical report for all splits and metrics, and [evaluation/README.md](evaluation/README.md) to reproduce the public benchmarks. ## ๐Ÿ—๏ธ How It Works **1. Data Engine.** A knowledge-graph-driven engine discovers concepts, localizes them with complementary experts verified by a VLM, and extends the verified boxes to masks and alpha mattes. Over 100M images are annotated this way. ![Data engine](assets/method/wde_overview.jpg) **2. Unified Task Formulation.** Every task is written as structured text, with coordinate tokens `<0>` โ€ฆ `<1000>` for boxes and points, `None` for absent targets, and an `` token after each box for pixel-level outputs. ![Unified task formulation](assets/method/task_formulation.jpg) **3. Model Architecture.** A 9.6M-parameter pixel decoder combines the hidden state of each `` token, its predicted box and multi-level Qwen3-VL ViT features to predict a full-resolution mask or alpha matte. ![Pixel decoder architecture](assets/method/pixel_decoder.jpg) ## ๐Ÿš€ Quick Start ### Installation ```bash git clone https://github.com/Tencent/WeVisOne-VL.git && cd WeVisOne-VL conda create -n wevisone-vl python=3.10 -y && conda activate wevisone-vl pip install -r requirements.txt && pip install -v -e . ``` ### Inference ```python from PIL import Image from wevisone_vl import WeVisOneVL from wevisone_vl.visualization import save_result model = WeVisOneVL("tencent/WeVisOne-VL-4B", backend="transformers") # or backend="vllm" # model = WeVisOneVL("tencent/WeVisOne-VL-2B", backend="transformers") # Use 2B instead # Object-level: open-vocabulary detection image = Image.open("demo/examples/images/livingroom.jpg").convert("RGB") result = model.predict(image, task="detection", query=["sofa", "pillow", "coffee table", "lamp"]) save_result("outputs/detection", image, result) # Pixel-level: promptable alpha matting image = Image.open("demo/examples/images/seabreeze.jpg").convert("RGB") result = model.predict(image, task="matting", query="person") save_result("outputs/matting", image, result) ```

Input ยท query="person"

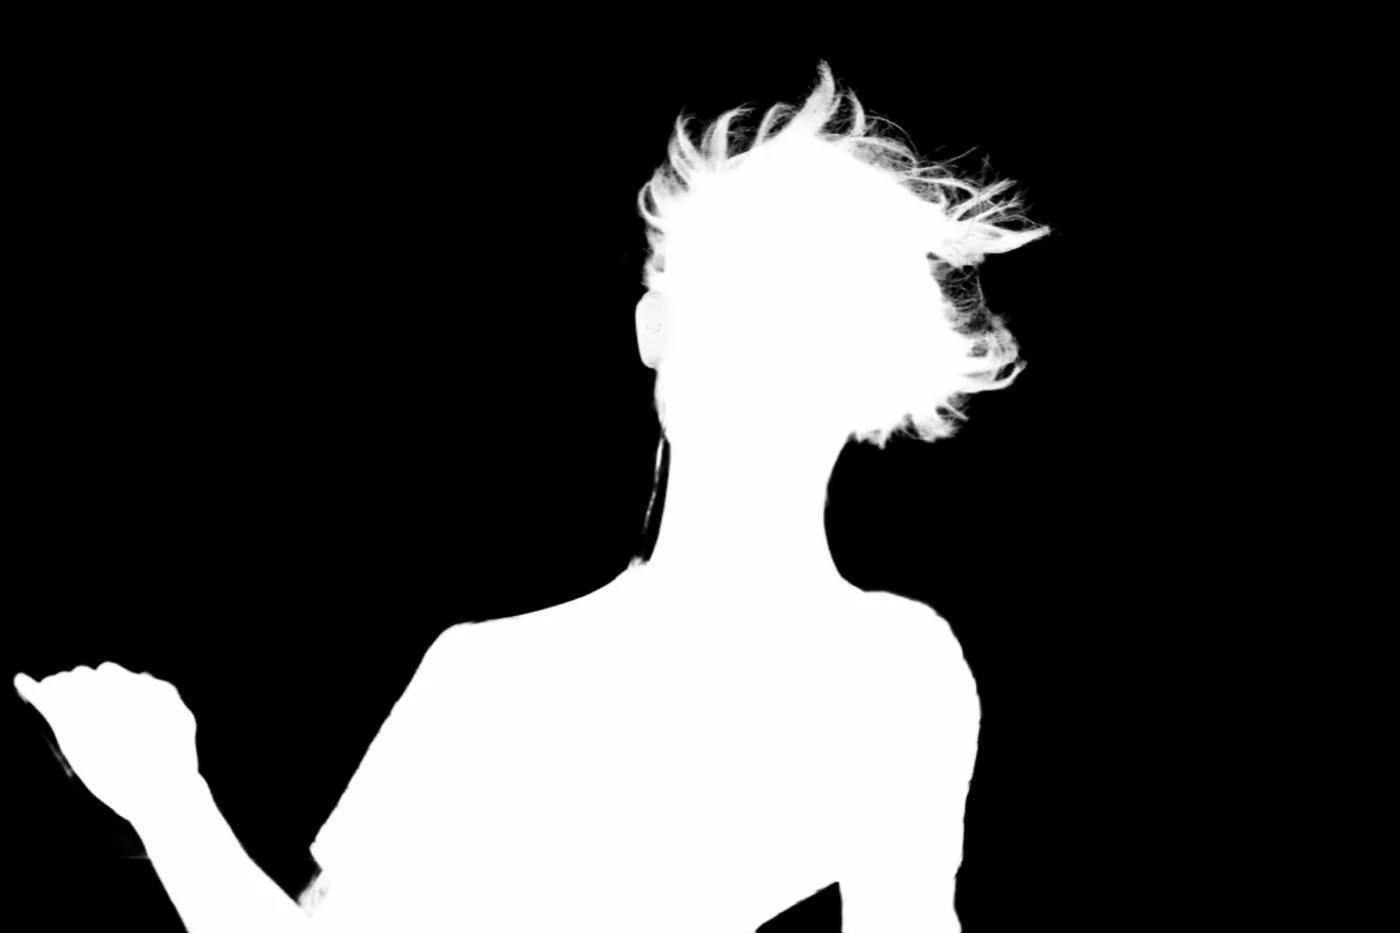
Predicted alpha matte

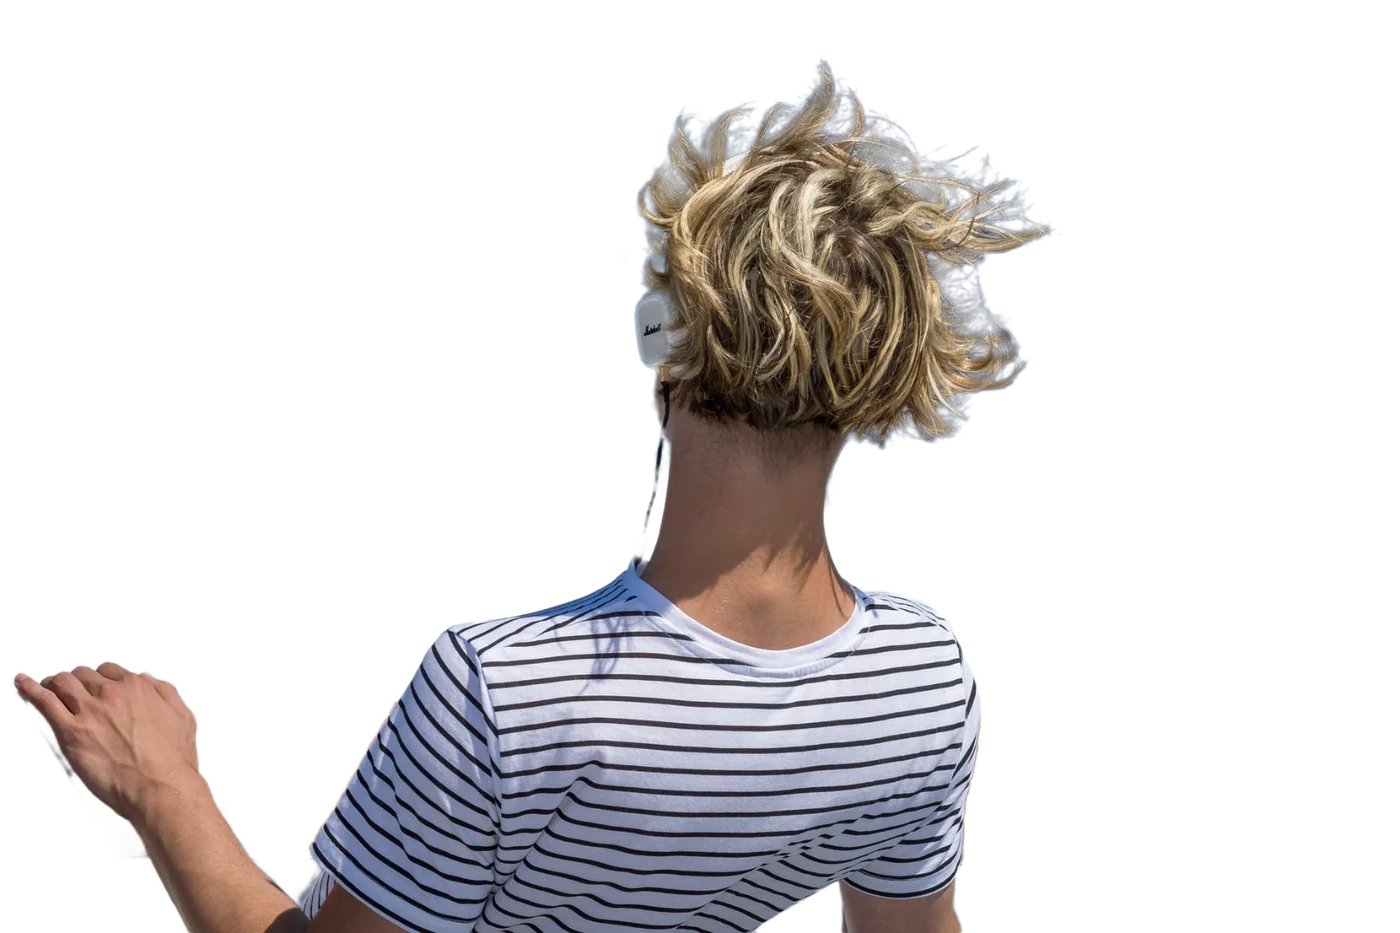
Cutout
### Supported Tasks | | `task` | `query` | Output | | --- | --------------------------- | --------------------- | ---------------------- | | ๐Ÿ“ฆ | `detection` | category list | boxes | | ๐Ÿ’ฌ | `referring` | referring expression | boxes or `None` | | ๐Ÿ“ | `point` | category / expression | points | | ๐Ÿ”ข | `count_box` / `count_point` | category / expression | boxes / points + count | | ๐Ÿ”ค | `ocr` / `ocr_grounding` | โ€“ / text to find | text + boxes | | ๐ŸŽญ | `segmentation` | category / expression | boxes + binary masks | | โœ‚๏ธ | `matting` | category / expression | boxes + alpha mattes | > [!TIP] > `device` (`"auto"`, `"cuda:0"`, `"npu:0"`, `"cpu"`), `dtype`, `min_pixels` / `max_pixels`, and the usual decoding arguments (`max_new_tokens`, `temperature`, ...) are also available. The [Cookbooks](#-cookbooks) walk through each task in detail. ## ๐Ÿ““ Cookbooks | Tutorial | Covers | | --------------------------------------------------------------------------- | ---------------------------------------- | | ๐Ÿ“ฆ [Object-level pipeline](tutorials/01_object_level_pipeline.ipynb) | Detection, Referring, Counting, Pointing | | ๐Ÿ”ค [OCR pipeline](tutorials/02_ocr_pipeline.ipynb) | OCR, Text Grounding | | ๐ŸŽญ [Pixel-level pipeline](tutorials/03_segmentation_matting_pipeline.ipynb) | Segmentation, Matting | ## ๐ŸŽฎ Gradio Demo Try the hosted demo: [2B](https://huggingface.co/spaces/hugging-apps/wevisone-vl-2b) / [4B](https://huggingface.co/spaces/hugging-apps/wevisone-vl-4b) Launch the demo locally: ```bash CUDA_VISIBLE_DEVICES=0 python demo/app.py --model tencent/WeVisOne-VL-4B # Or use 2B: # CUDA_VISIBLE_DEVICES=0 python demo/app.py --model tencent/WeVisOne-VL-2B ```
More launch options ```bash # vLLM backend on a custom port, with a public share link CUDA_VISIBLE_DEVICES=0 python demo/app.py \ --model tencent/WeVisOne-VL-4B --backend vllm \ --server-name 0.0.0.0 --server-port 8080 --share ```
## ๐Ÿ“Š Evaluation See [evaluation/README.md](evaluation/README.md). ## ๐Ÿ–ผ๏ธ Representative Visualizations Side-by-side comparisons with strong baselines. Click a task to expand or collapse it.
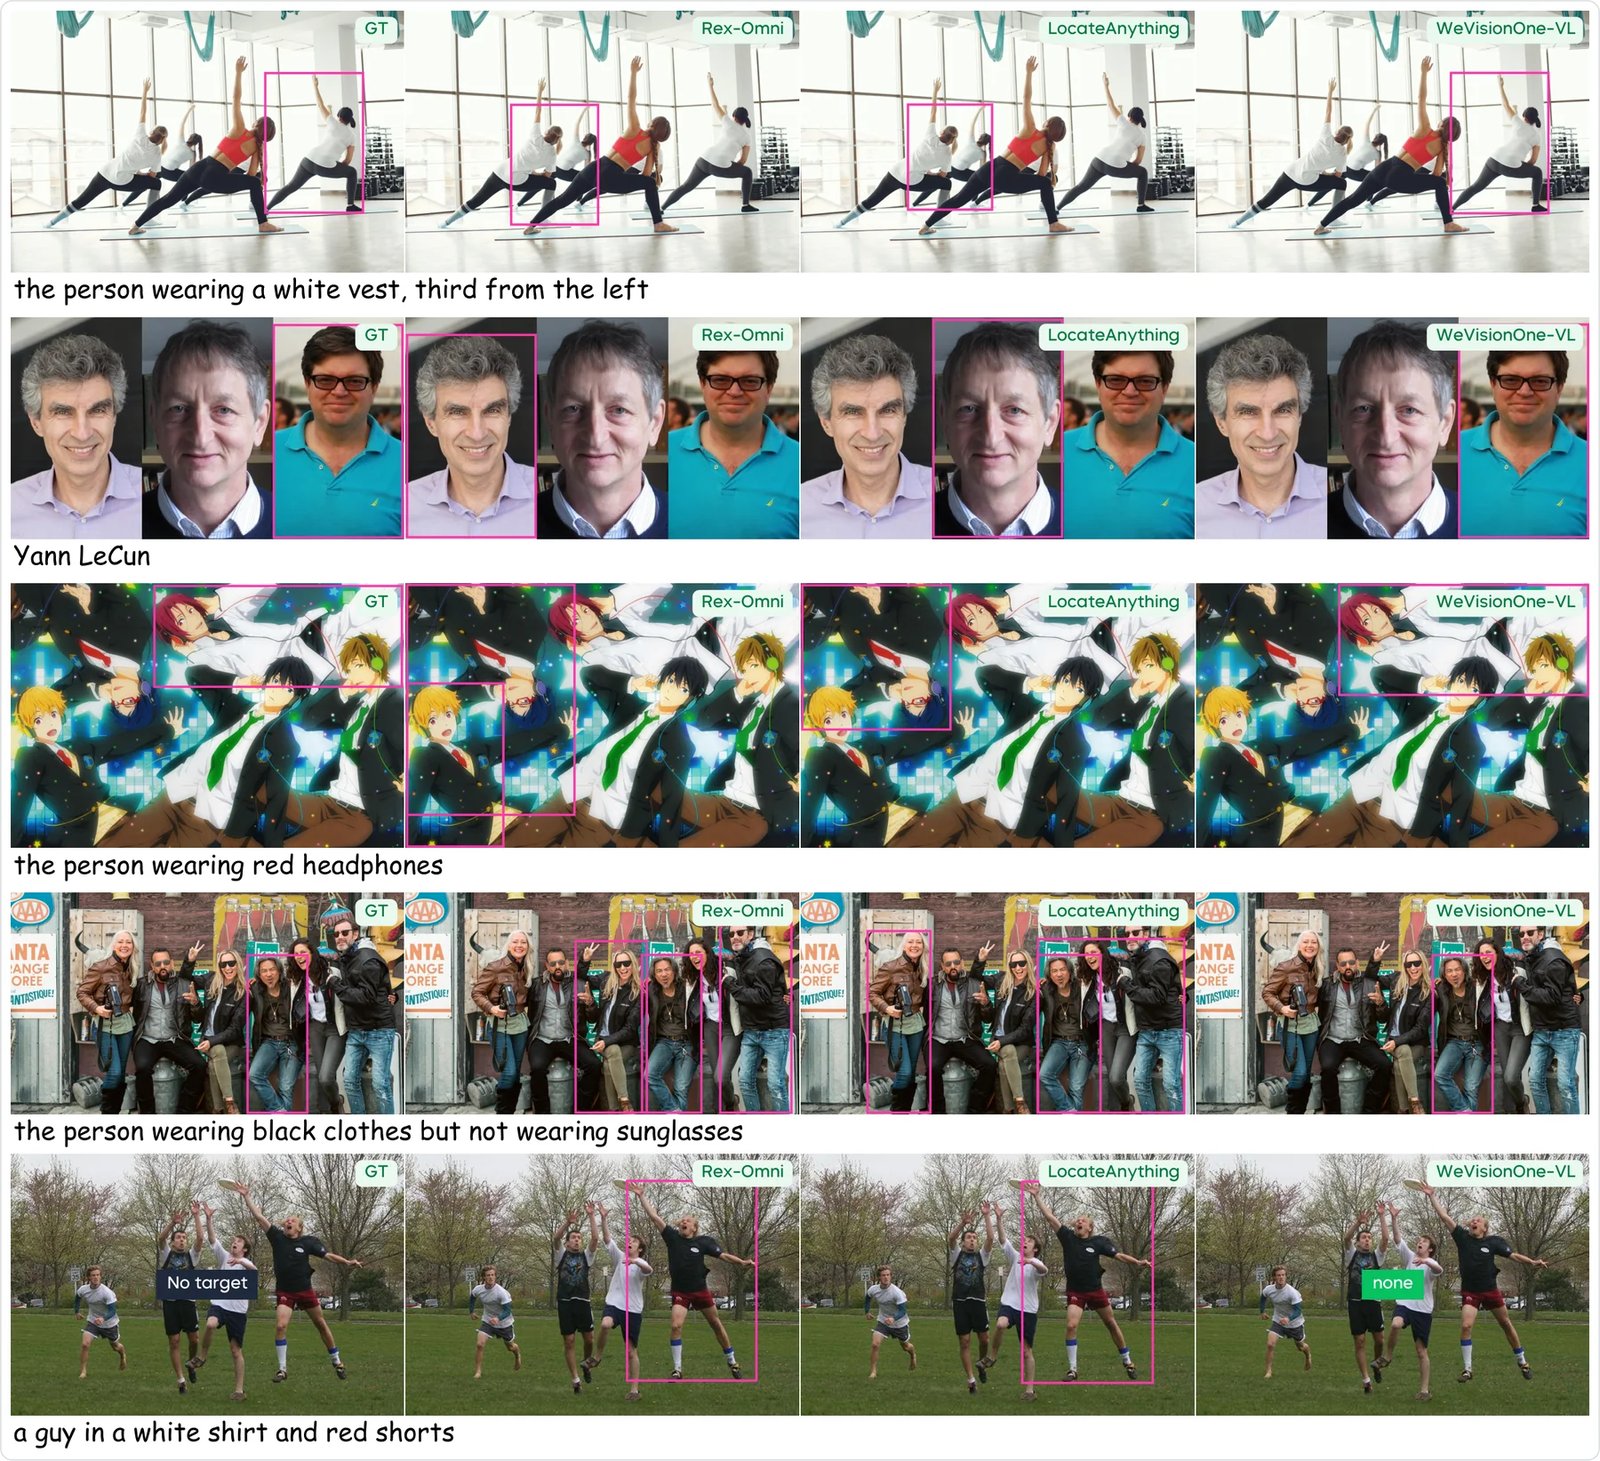
Referring Detection โ€” locating the objects described by a natural-language expression
Referring detection comparison
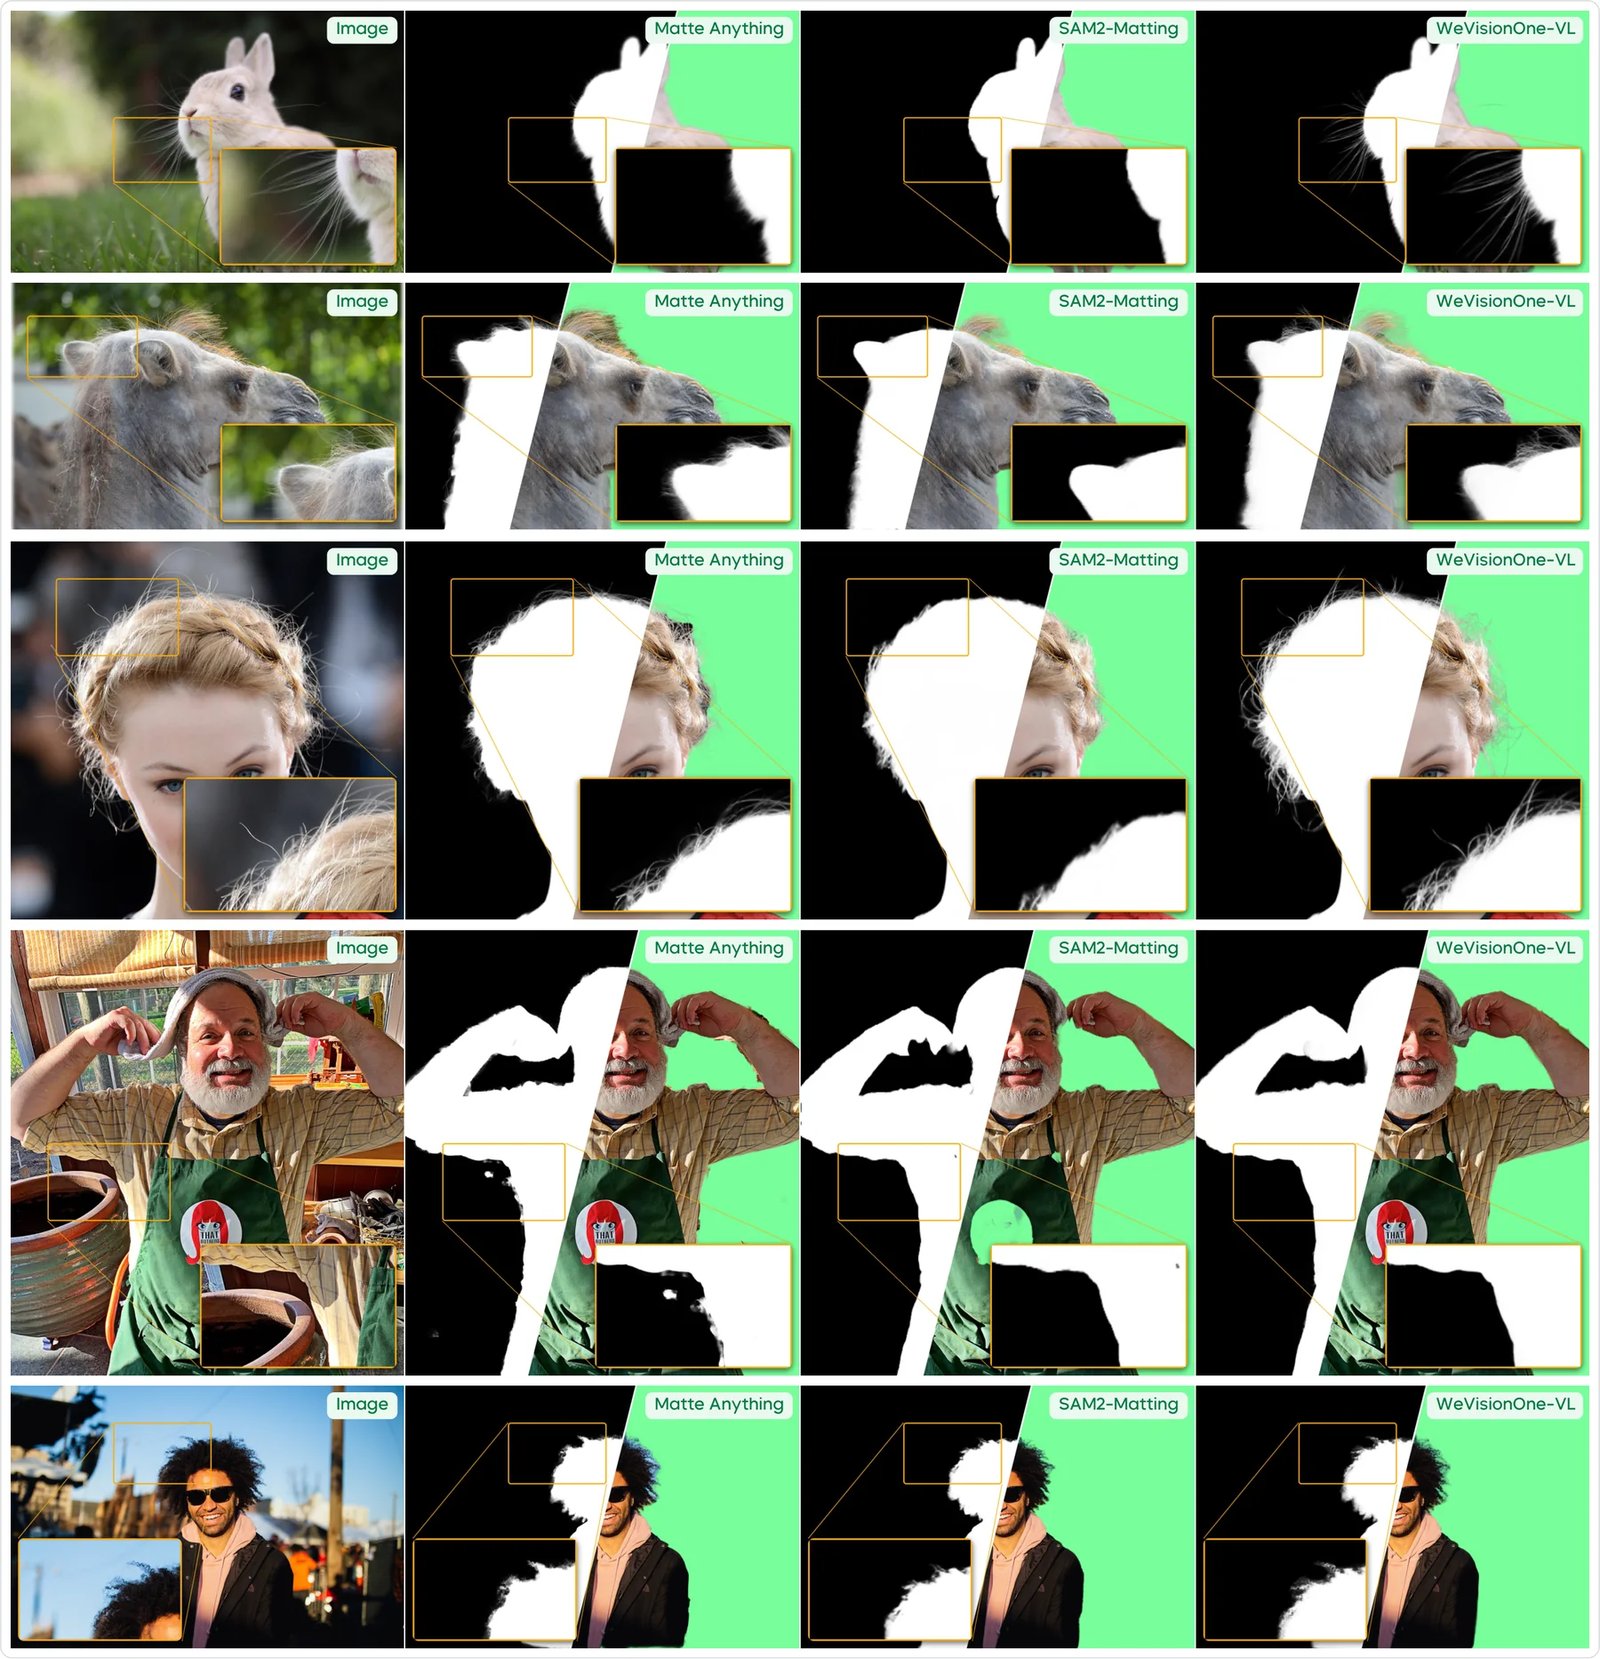
Box-prompted Matting โ€” predicting the alpha matte of the target inside a given box
Box-prompted matting comparison
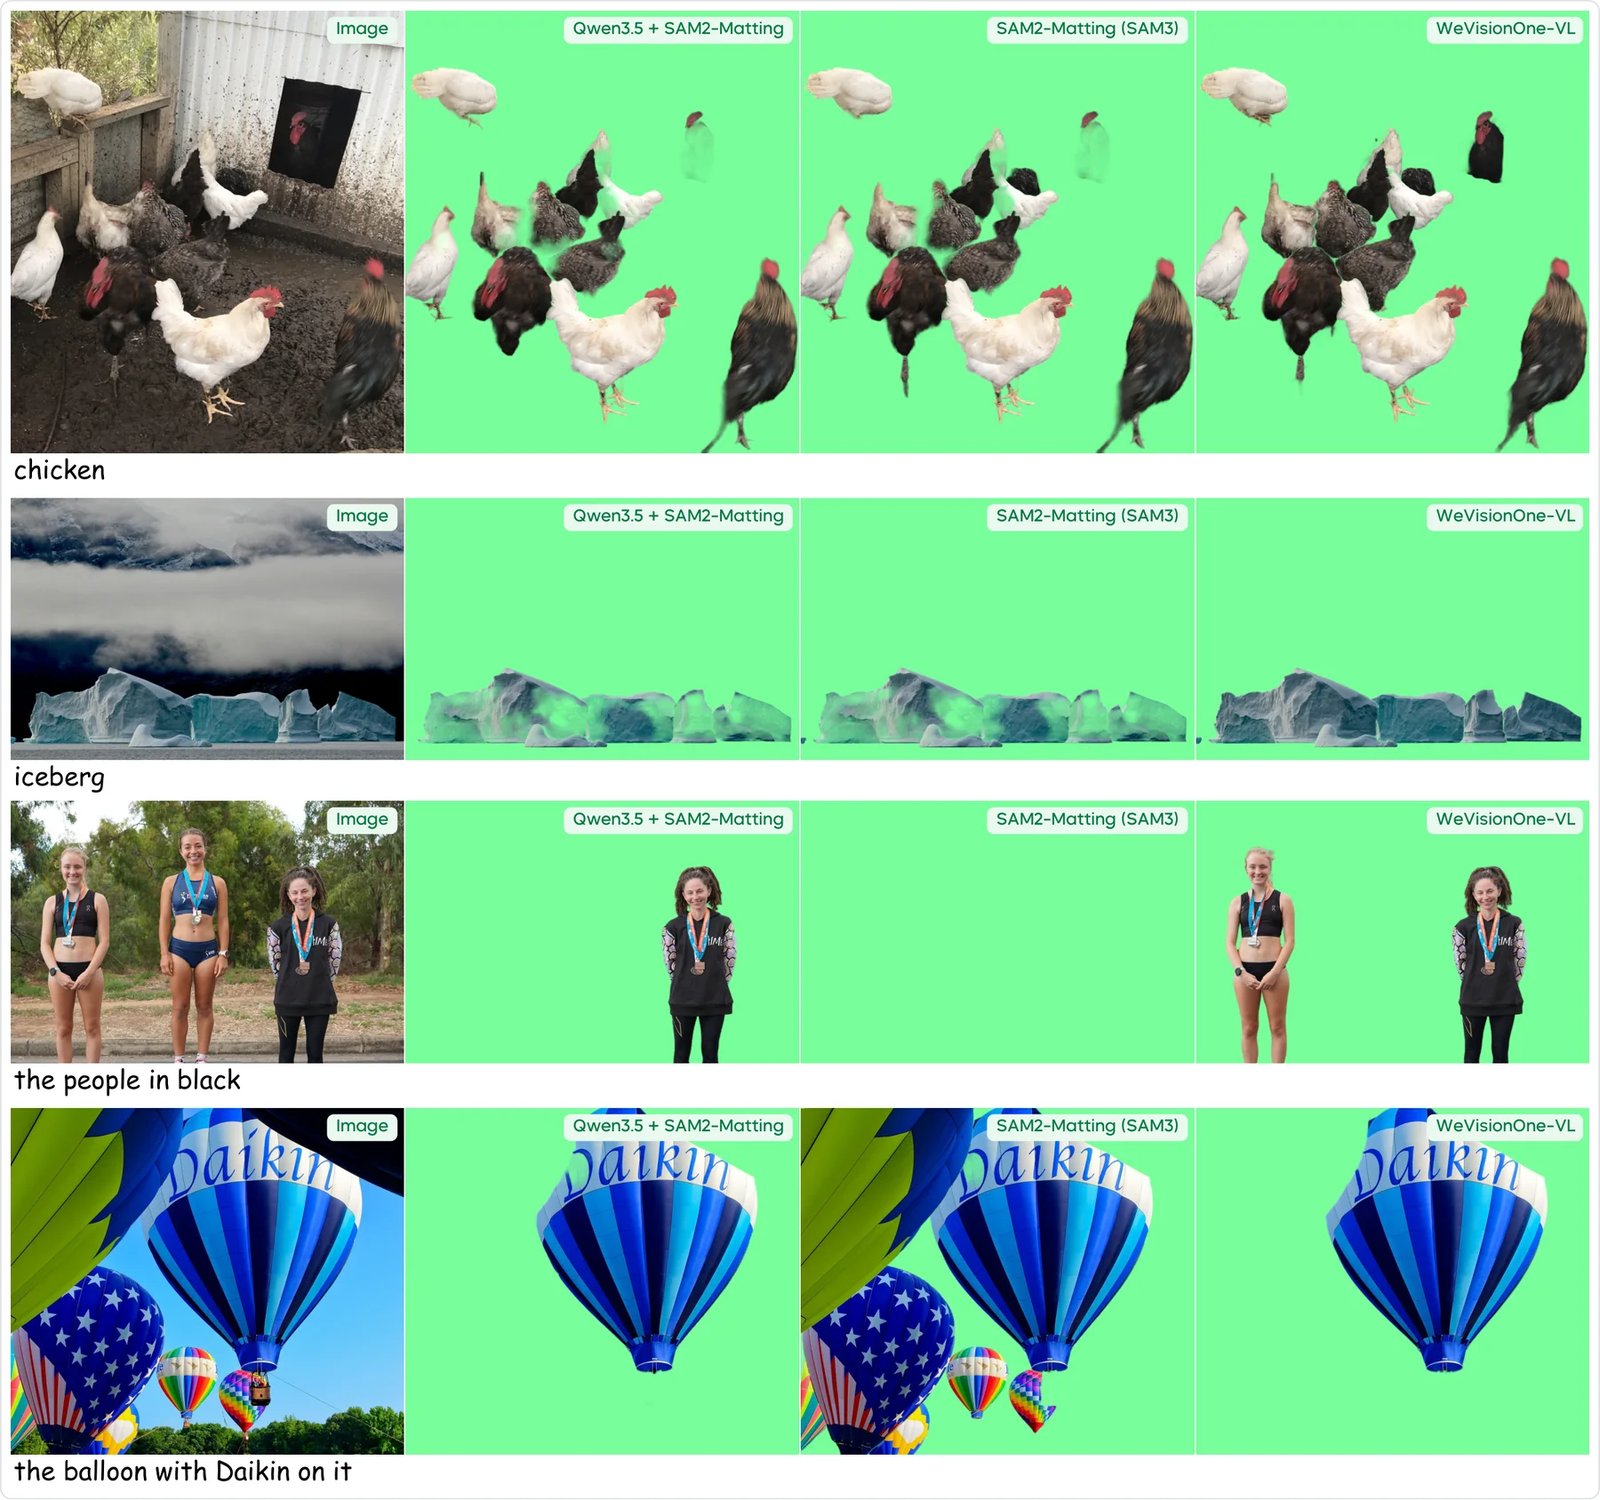
Text-prompted Matting โ€” predicting the alpha matte of the target specified by a category name or referring expression
Text-prompted matting comparison
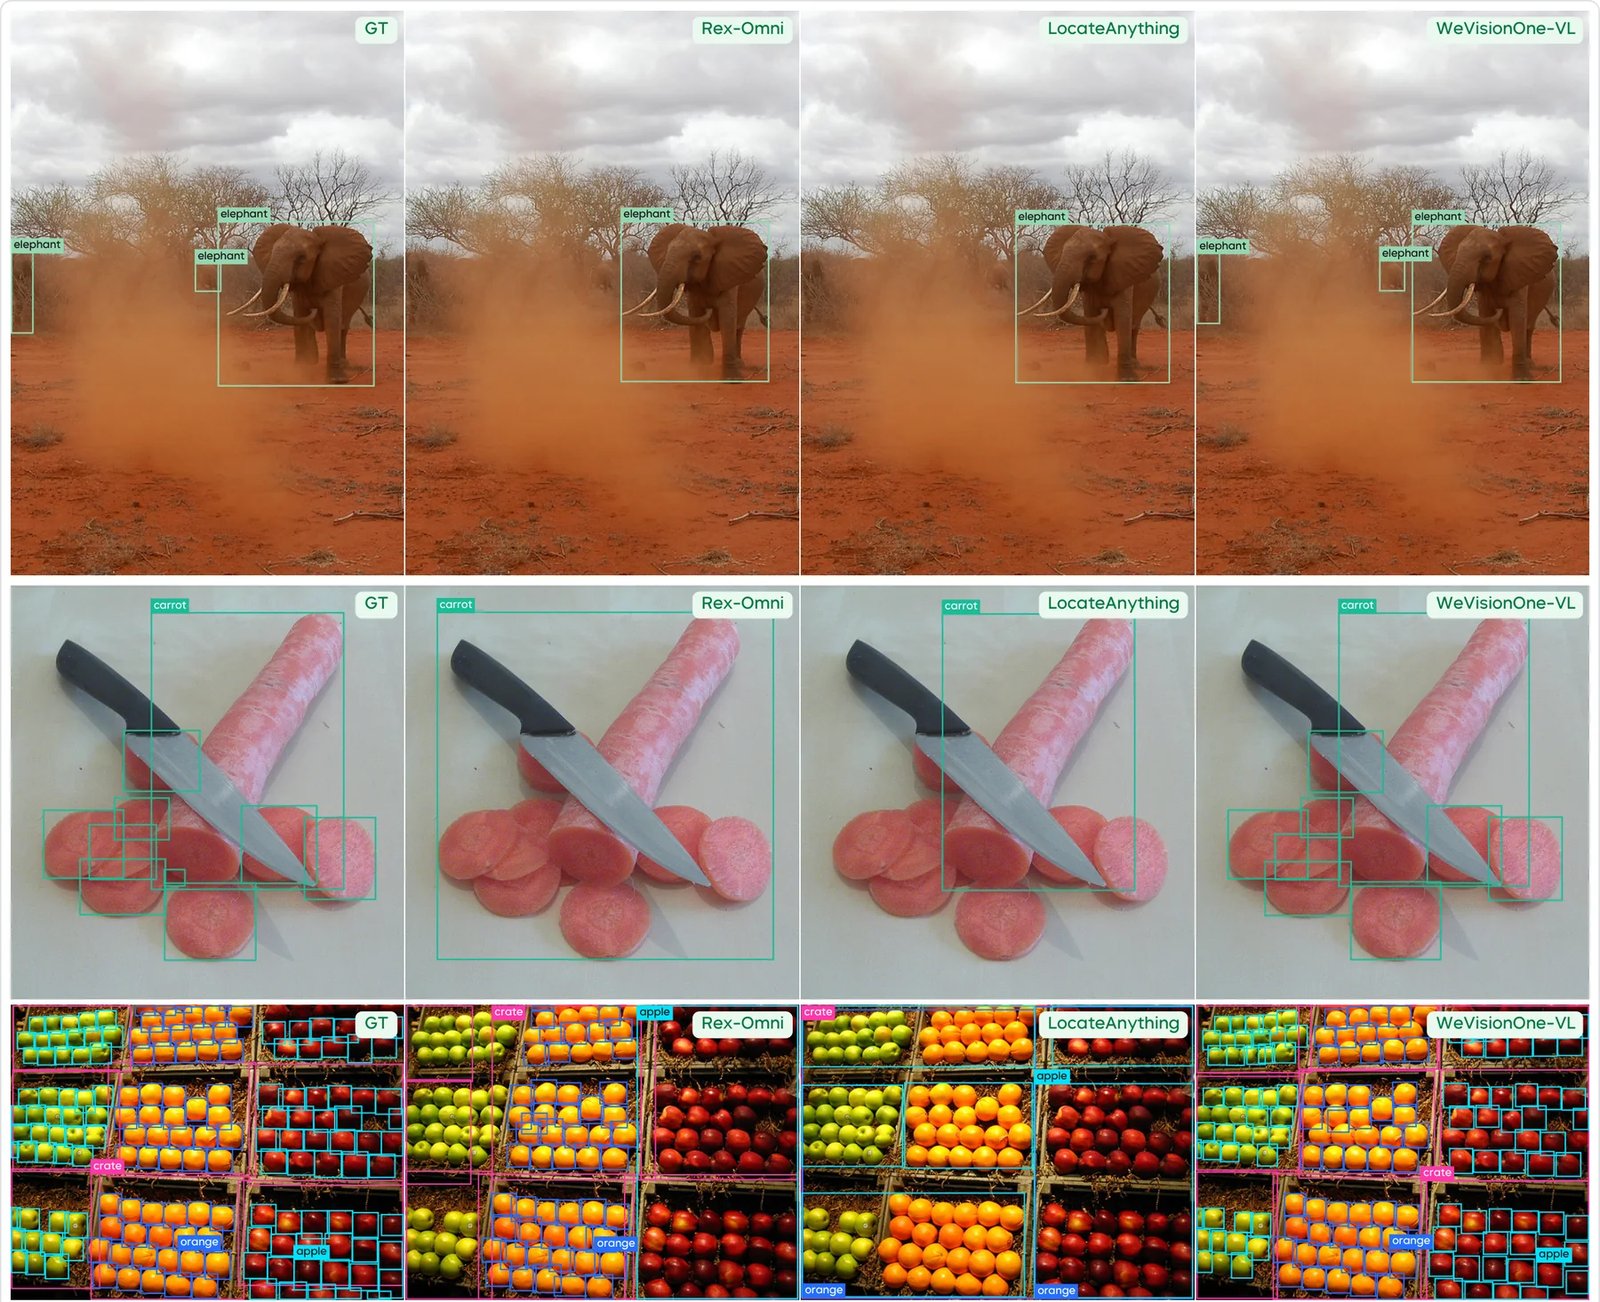
Object Detection โ€” locating all instances of the given categories with boxes
Object detection comparison
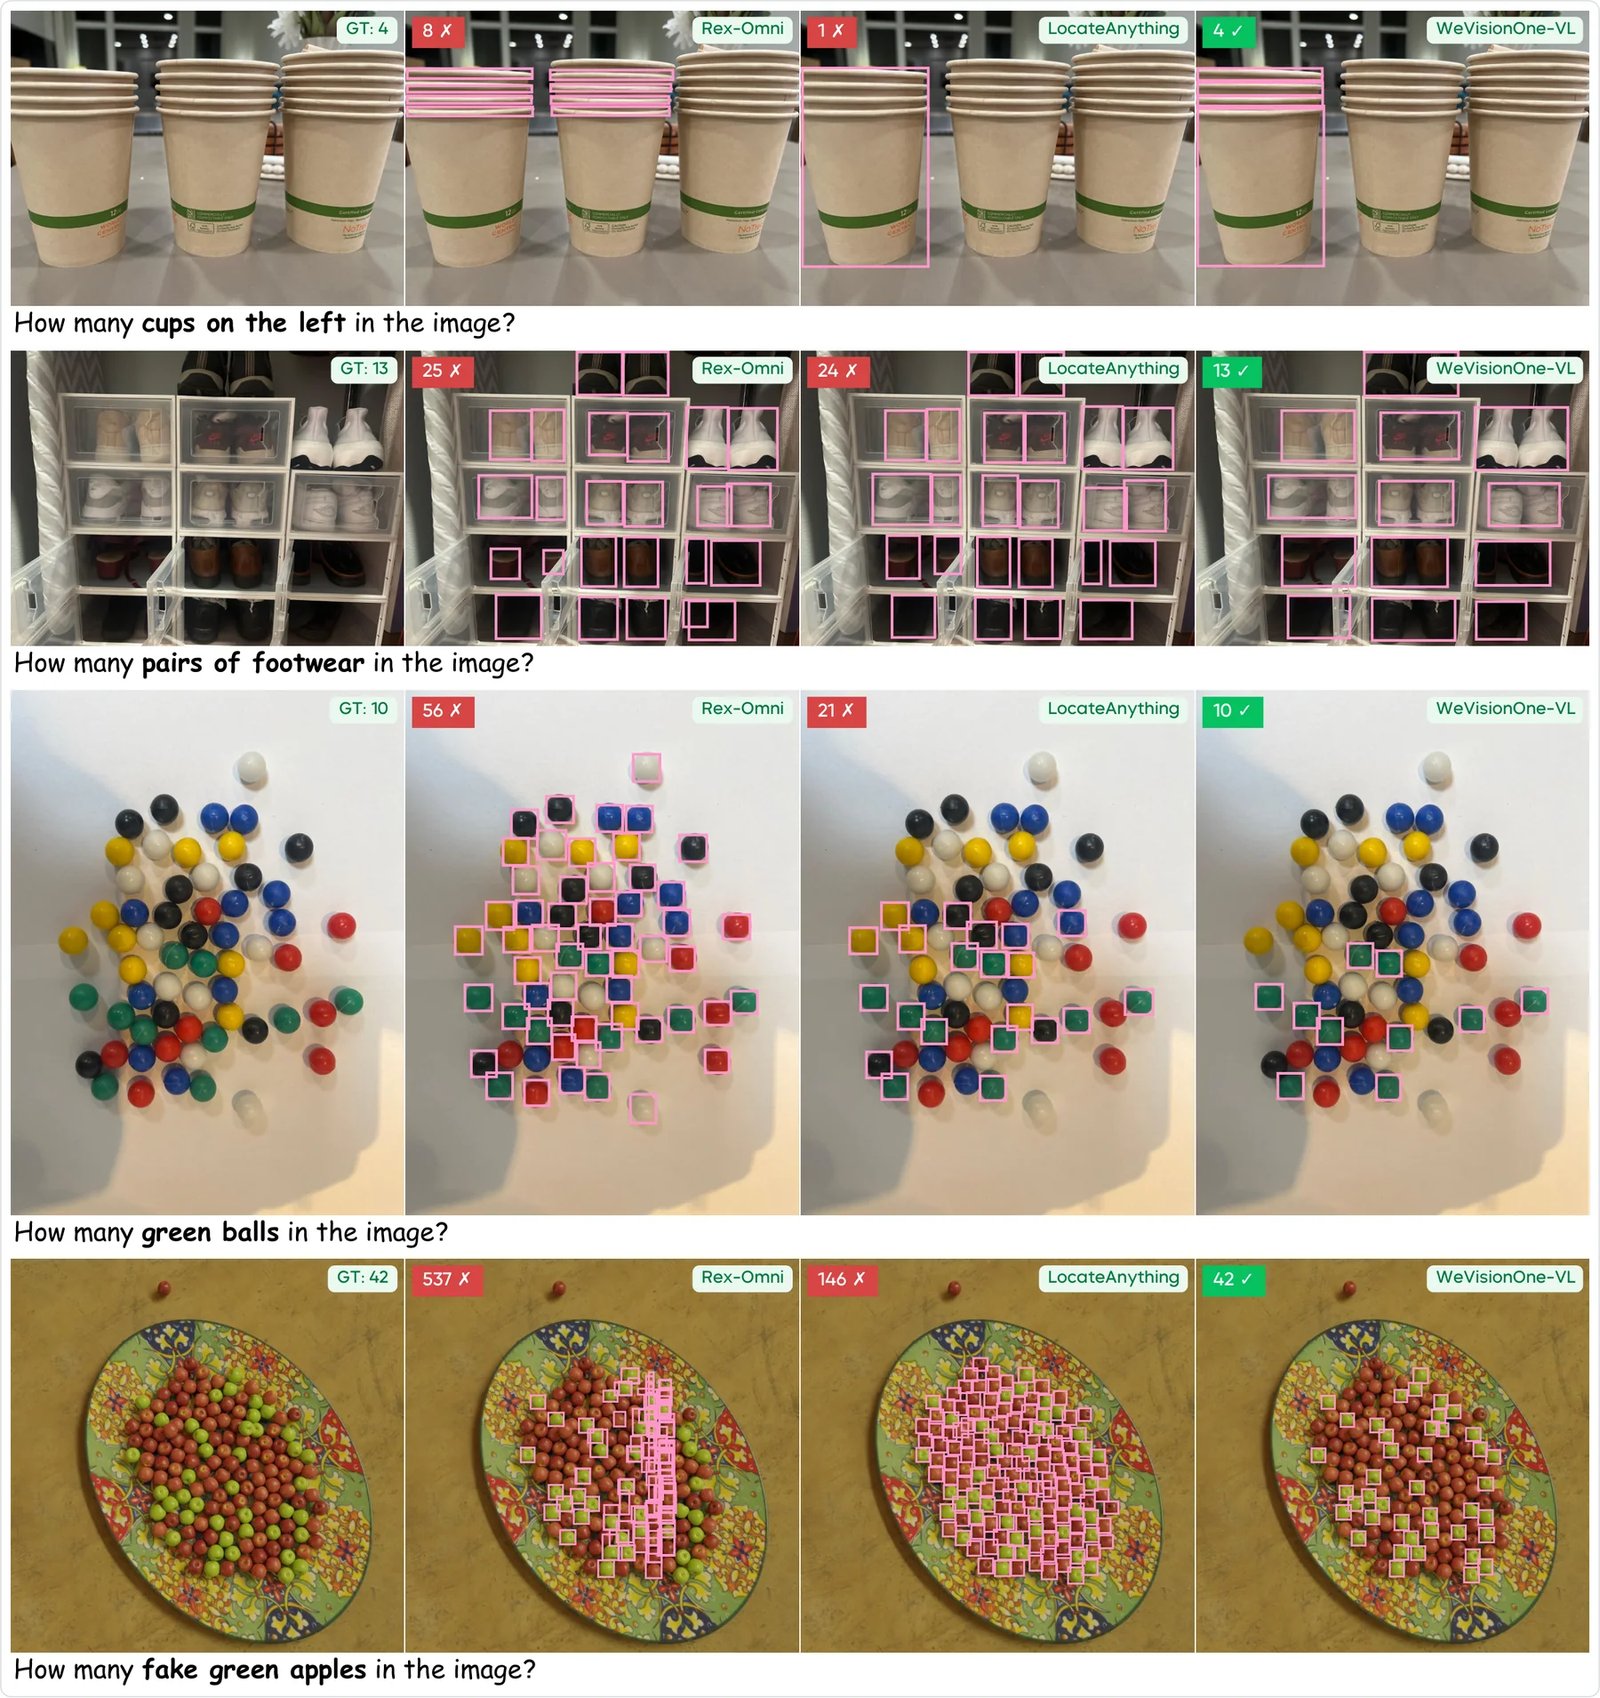
Object Counting โ€” counting the instances that match a category or expression
Object counting comparison
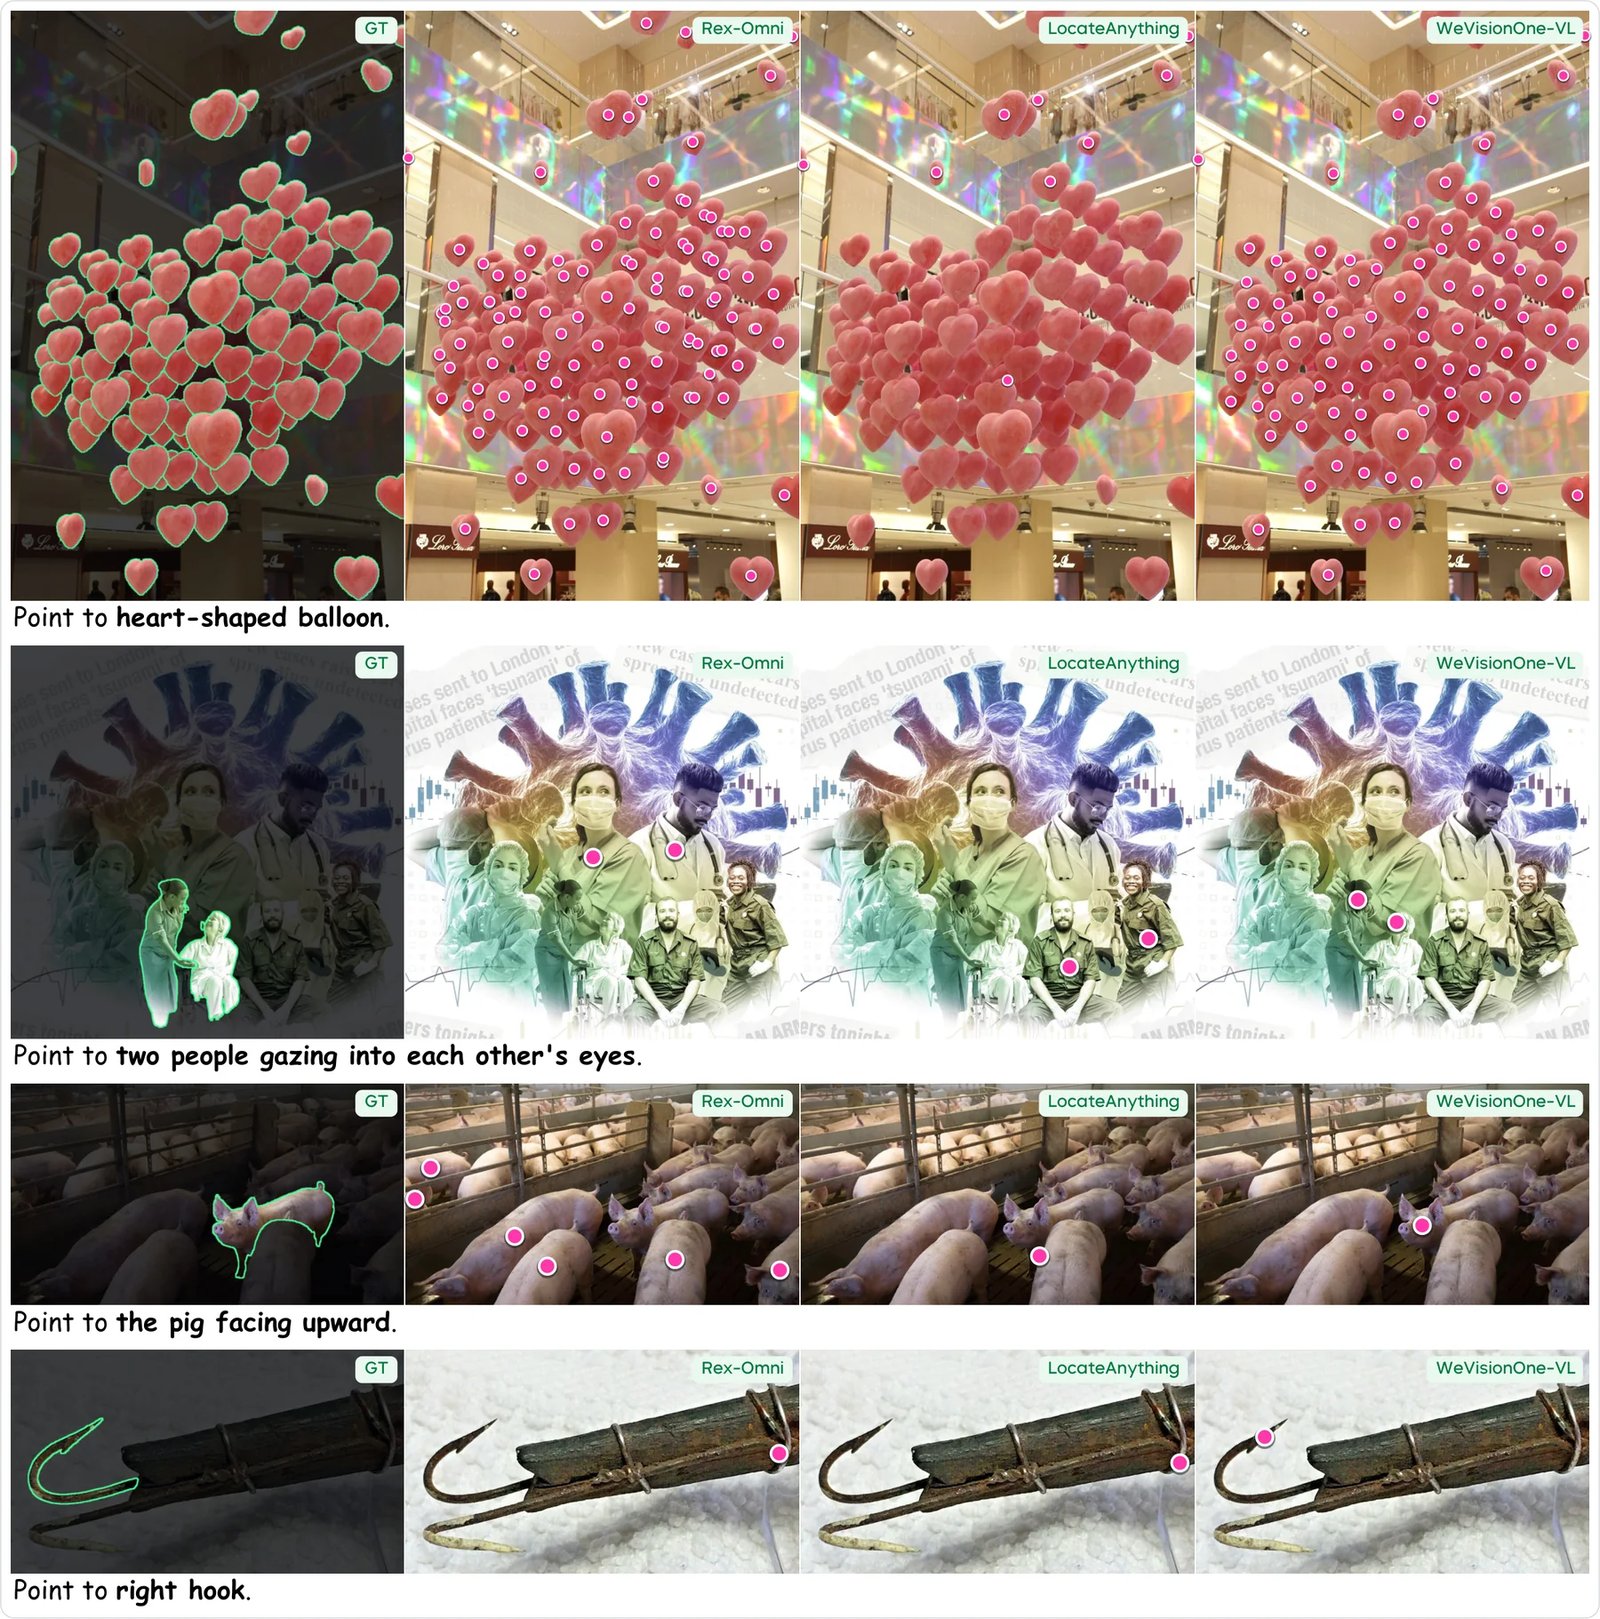
Object Pointing โ€” marking each queried object with a point
Object pointing comparison
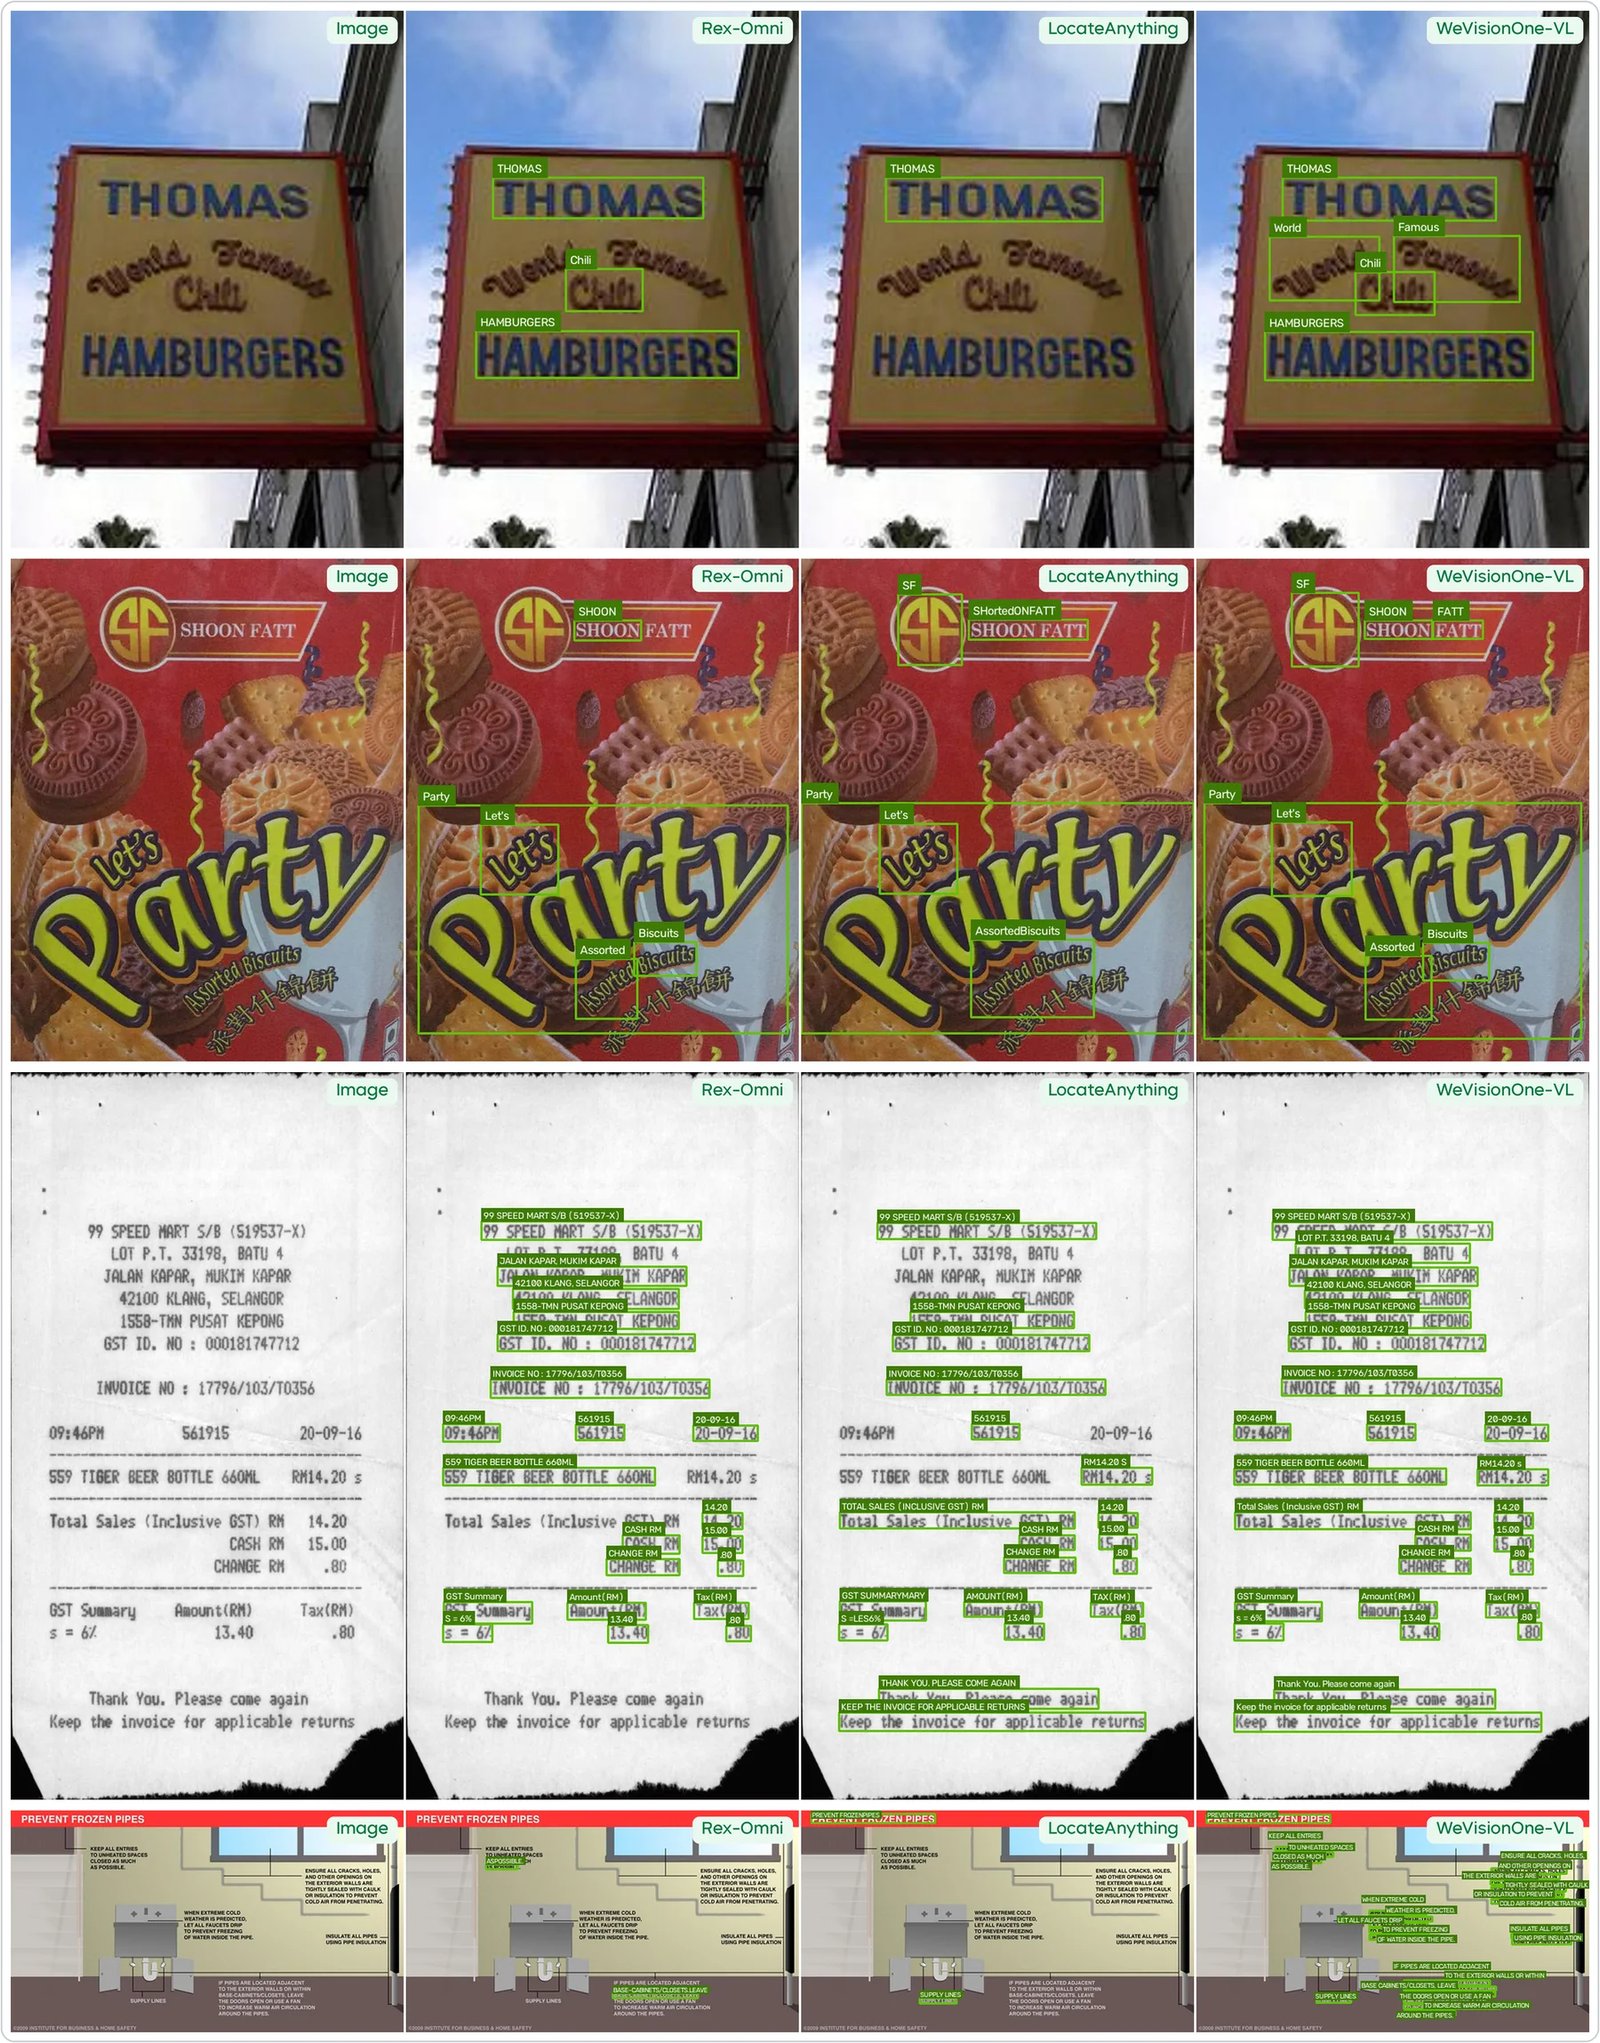
OCR โ€” locating and recognizing text in the image
OCR comparison
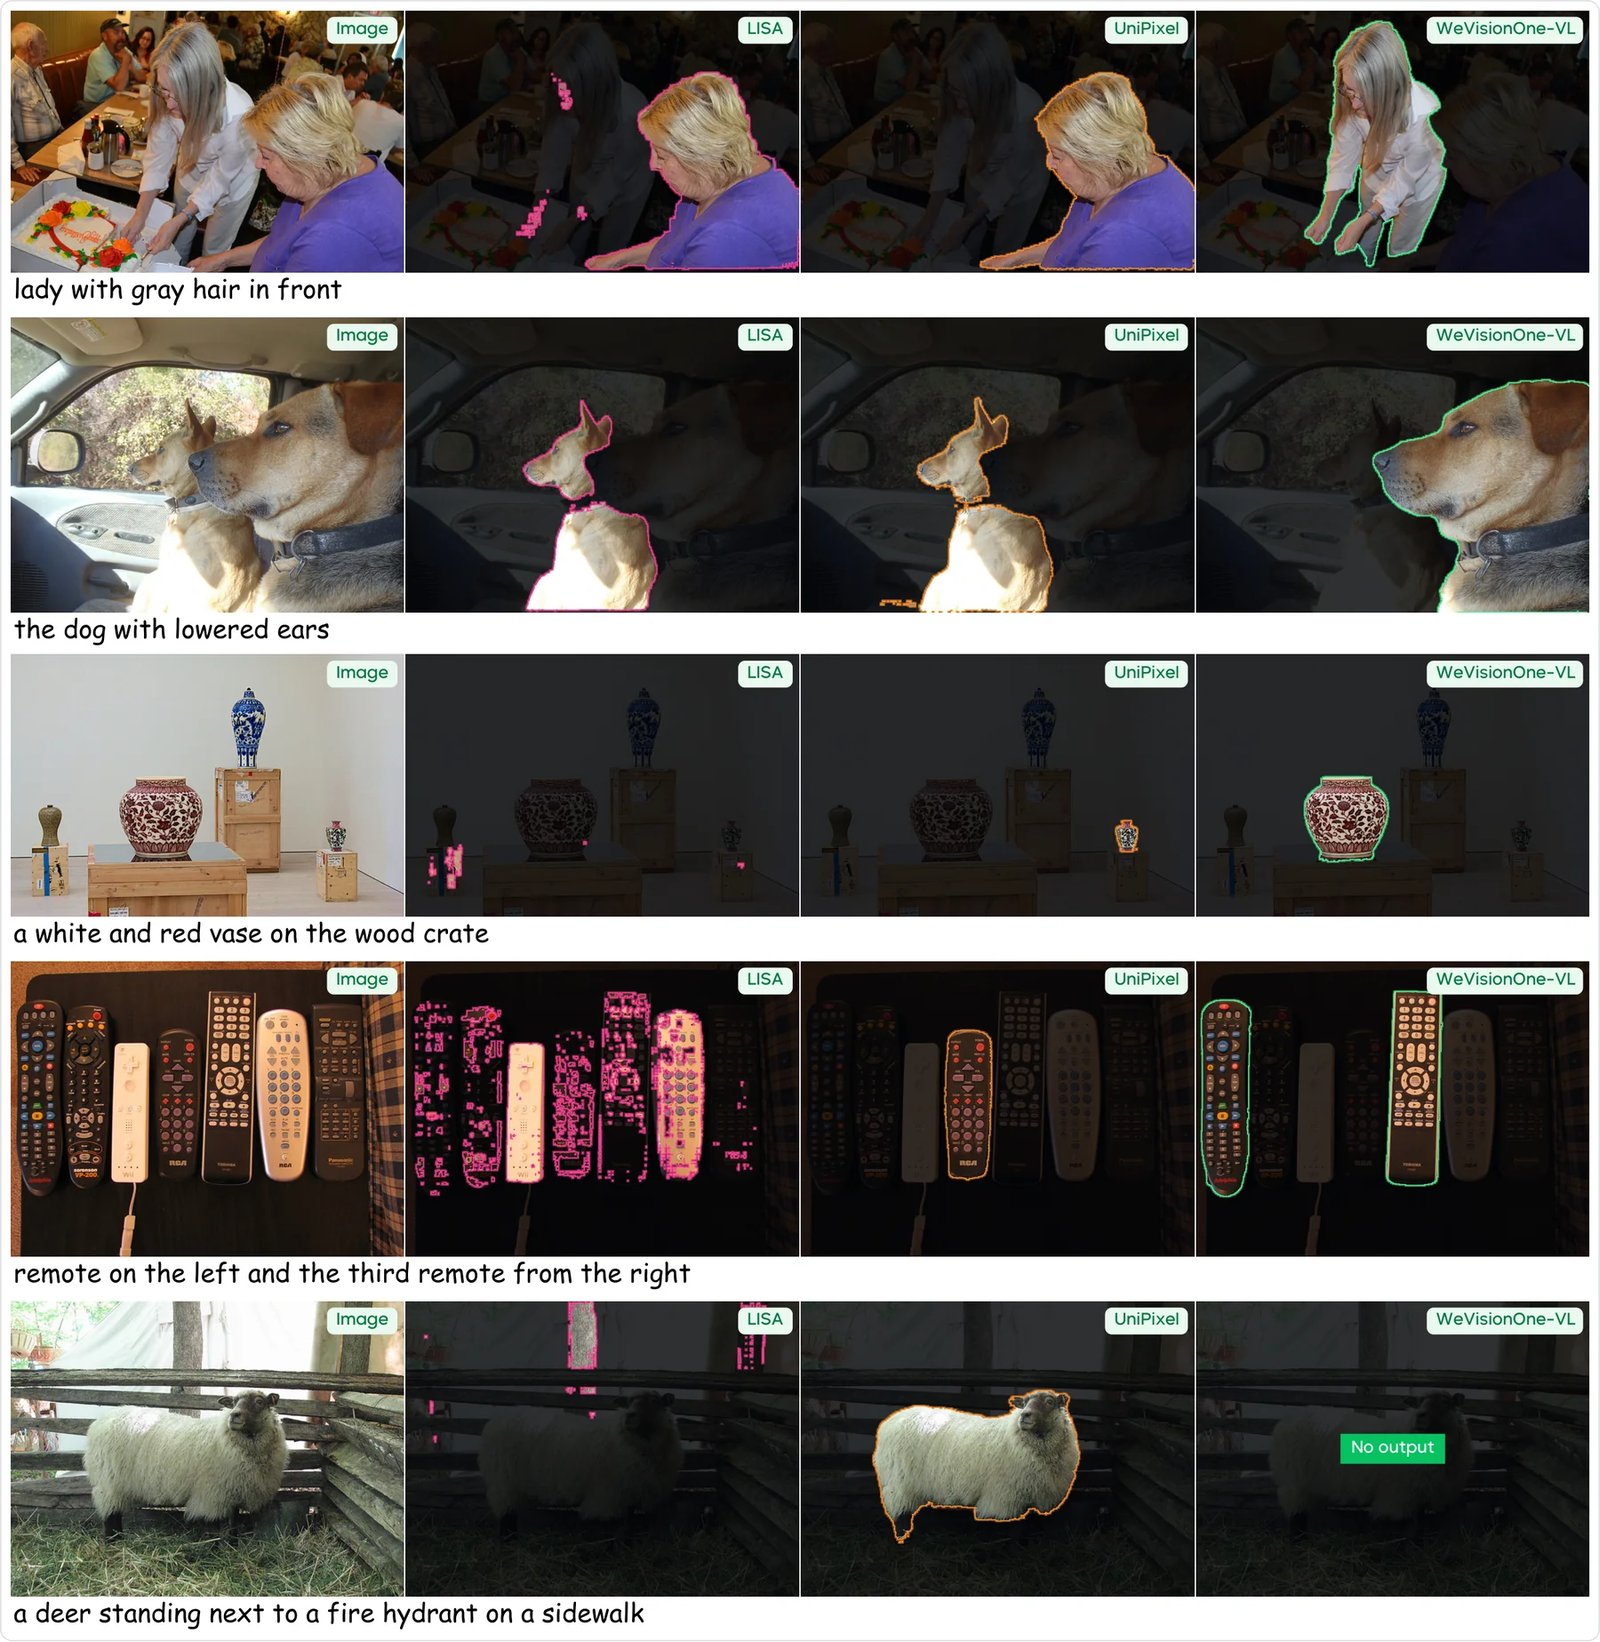
Referring Segmentation โ€” segmenting the objects described by a natural-language expression
Referring segmentation comparison
## ๐Ÿ“œ License Tencent-authored code in this repository is released under the [Apache License 2.0](LICENSE). Third-party components keep their original licenses; please check the corresponding source files. ## ๐Ÿ“– Citation If WeVisOne-VL is helpful to your work, please consider giving us a โญ and citing: ```bibtex @article{liang2026wevisone, title={WeVisOne-VL: Unified Visual Perception from Objects to Pixels}, author={Liang, Tianming and Pan, Junyi and Li, Yuxi and Fu, Canmiao and Huang, Zhipeng and Sun, Chong and Li, Chen and Lyu, Jing}, journal={arXiv preprint arXiv:2610.31329}, year={2026} } ```