SaaS-Bench: Can Computer-Use Agents Leverage Real-World SaaS to Solve Professional Workflows?
[](https://arxiv.org/abs/2605.15777)
[](https://unipat.ai/blog/SaaS-Bench)
[](https://unipat.ai/benchmarks/SaaS-Bench)
[](https://github.com/UniPat-AI/SaaS-Bench)
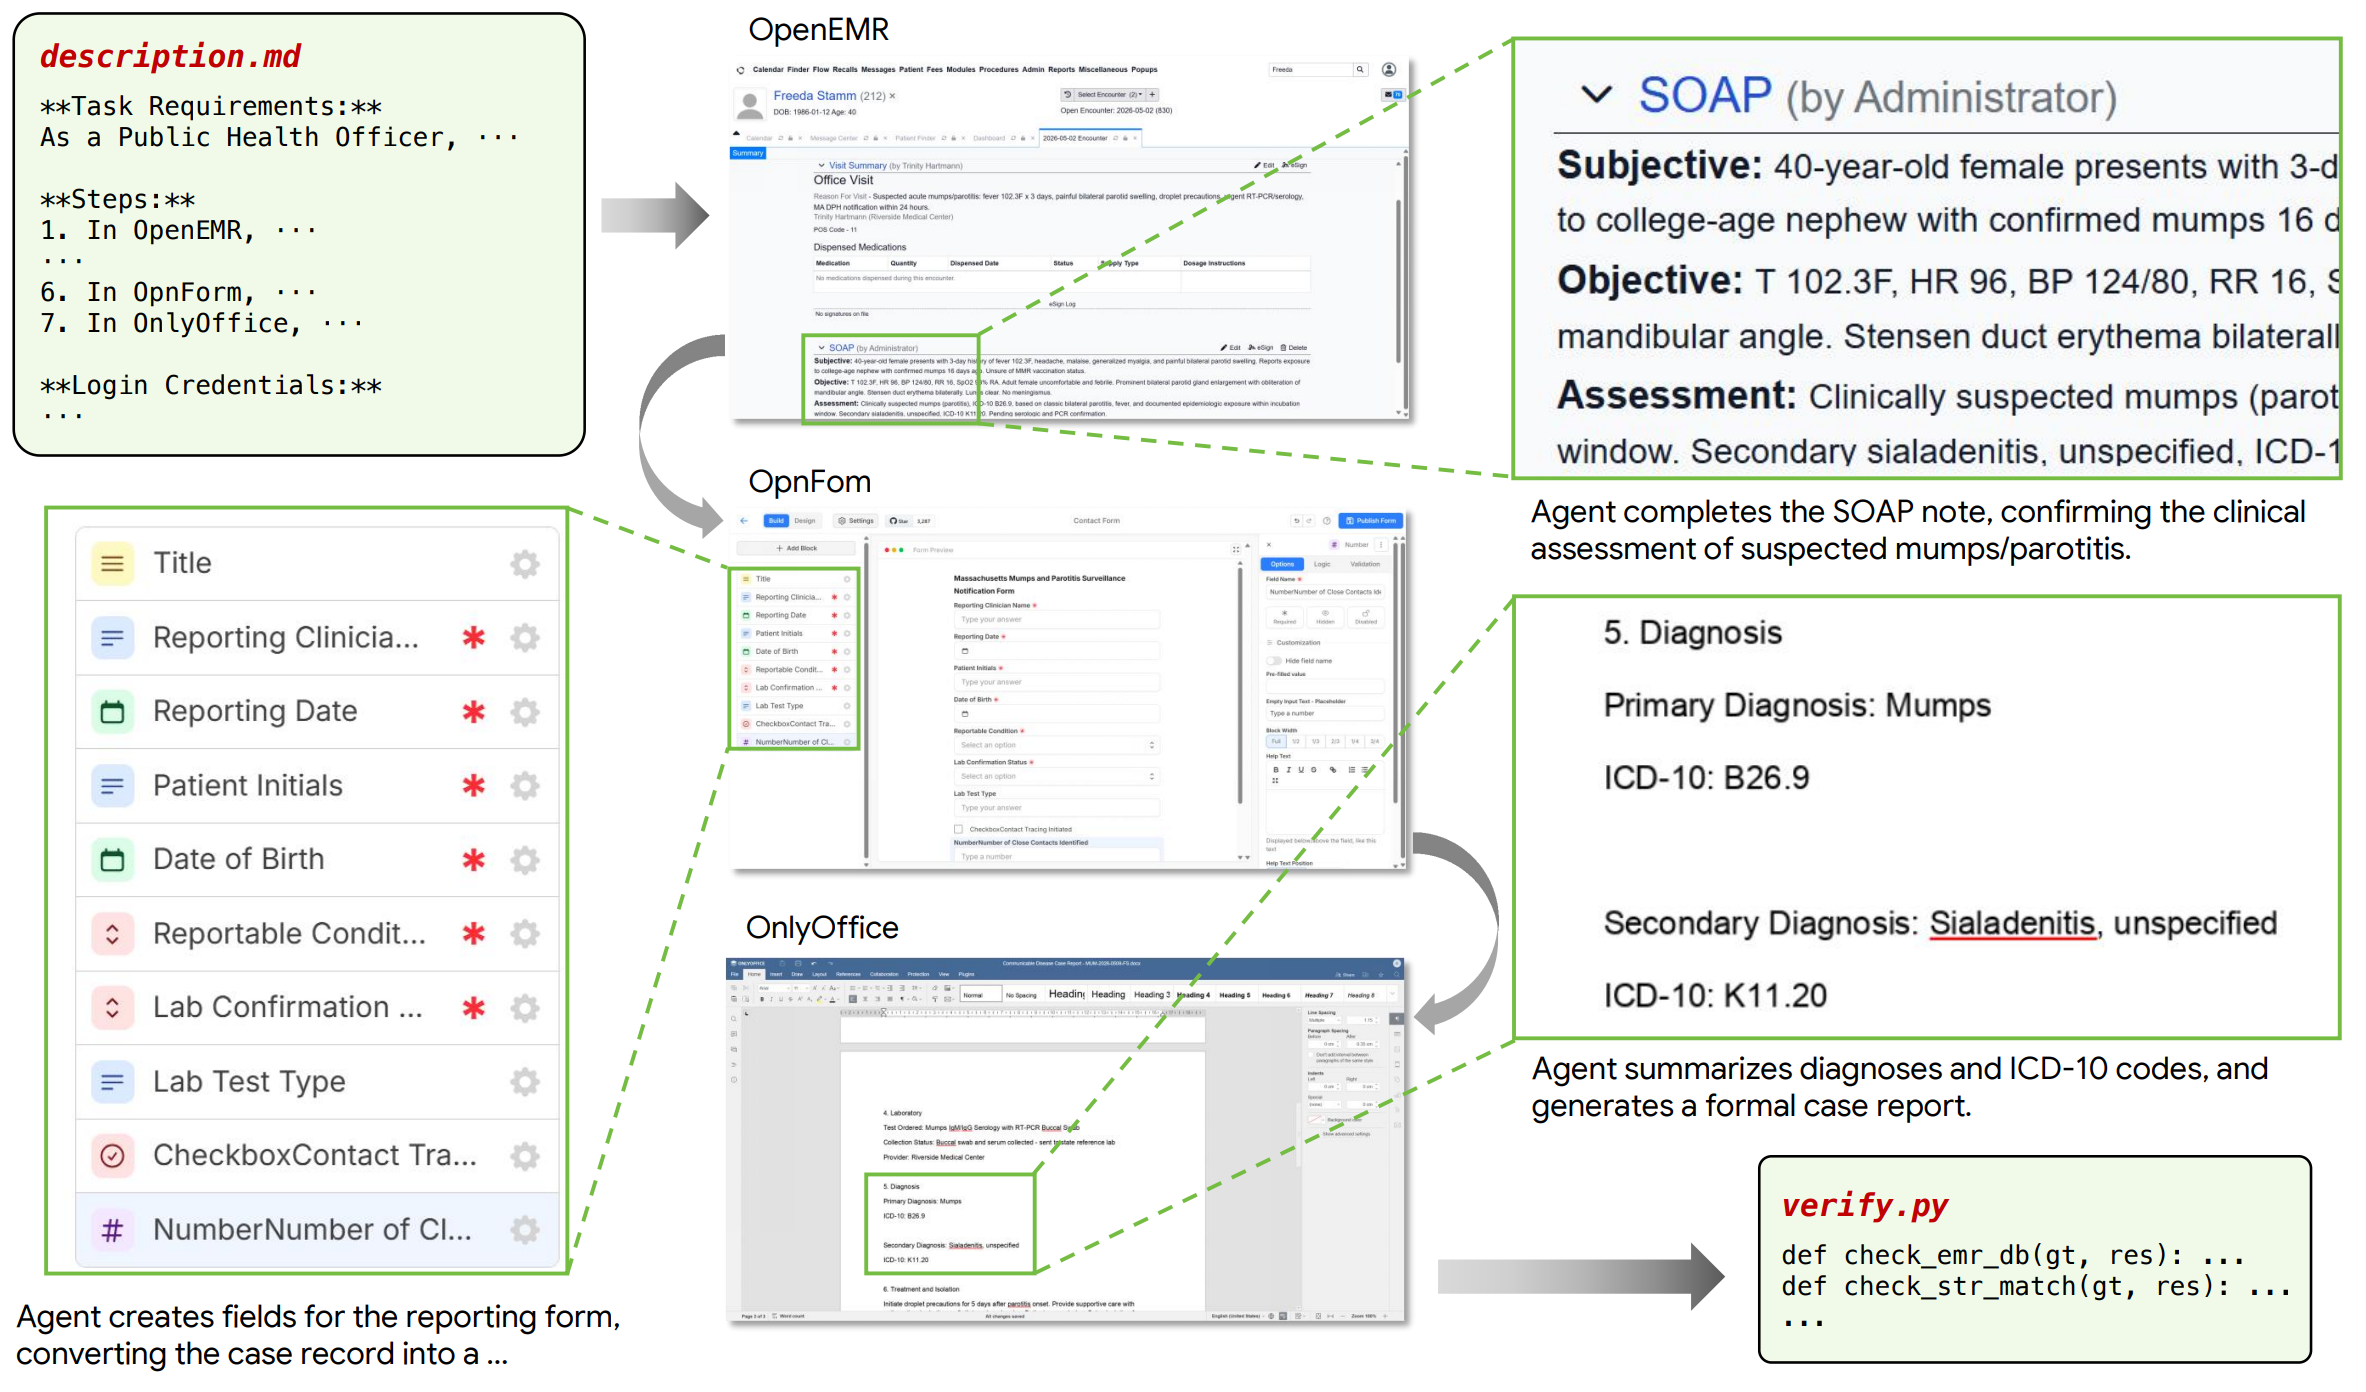 One task, three applications. The agent works from
description.md alone; verify.py scores what it actually left behind in each app's database.
---
## Overview
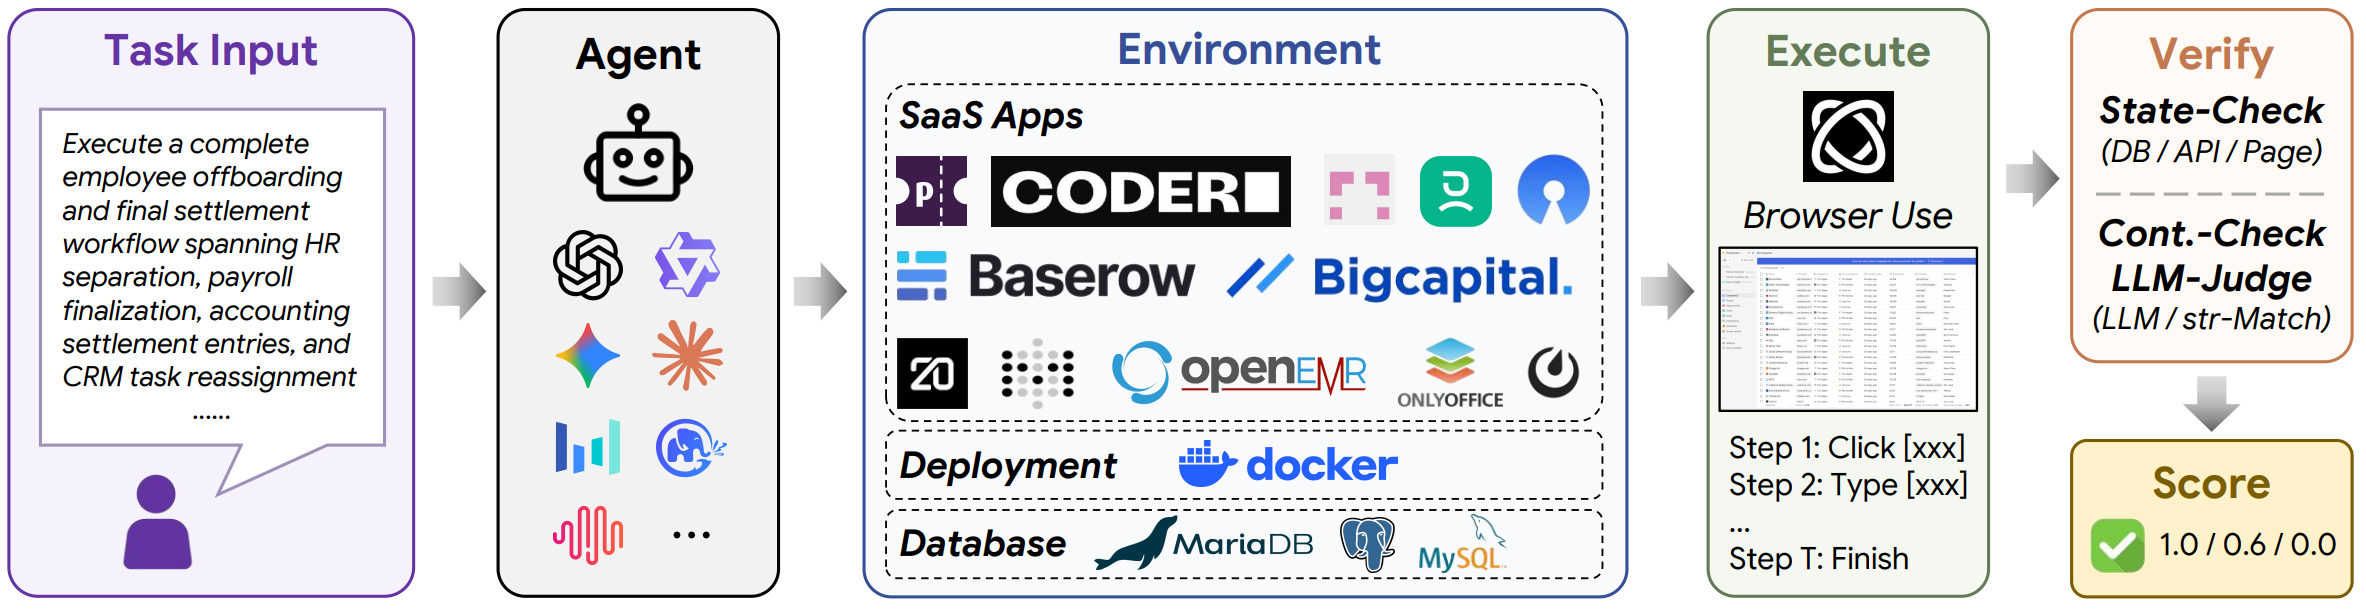
A benchmark for evaluating LLM agents on **real, self-hosted SaaS
applications**. Each task asks the agent to drive a browser through a
multi-step business workflow (project management, accounting, HR, document
authoring, etc.); a per-task verifier inspects the running application's
state to score the result.
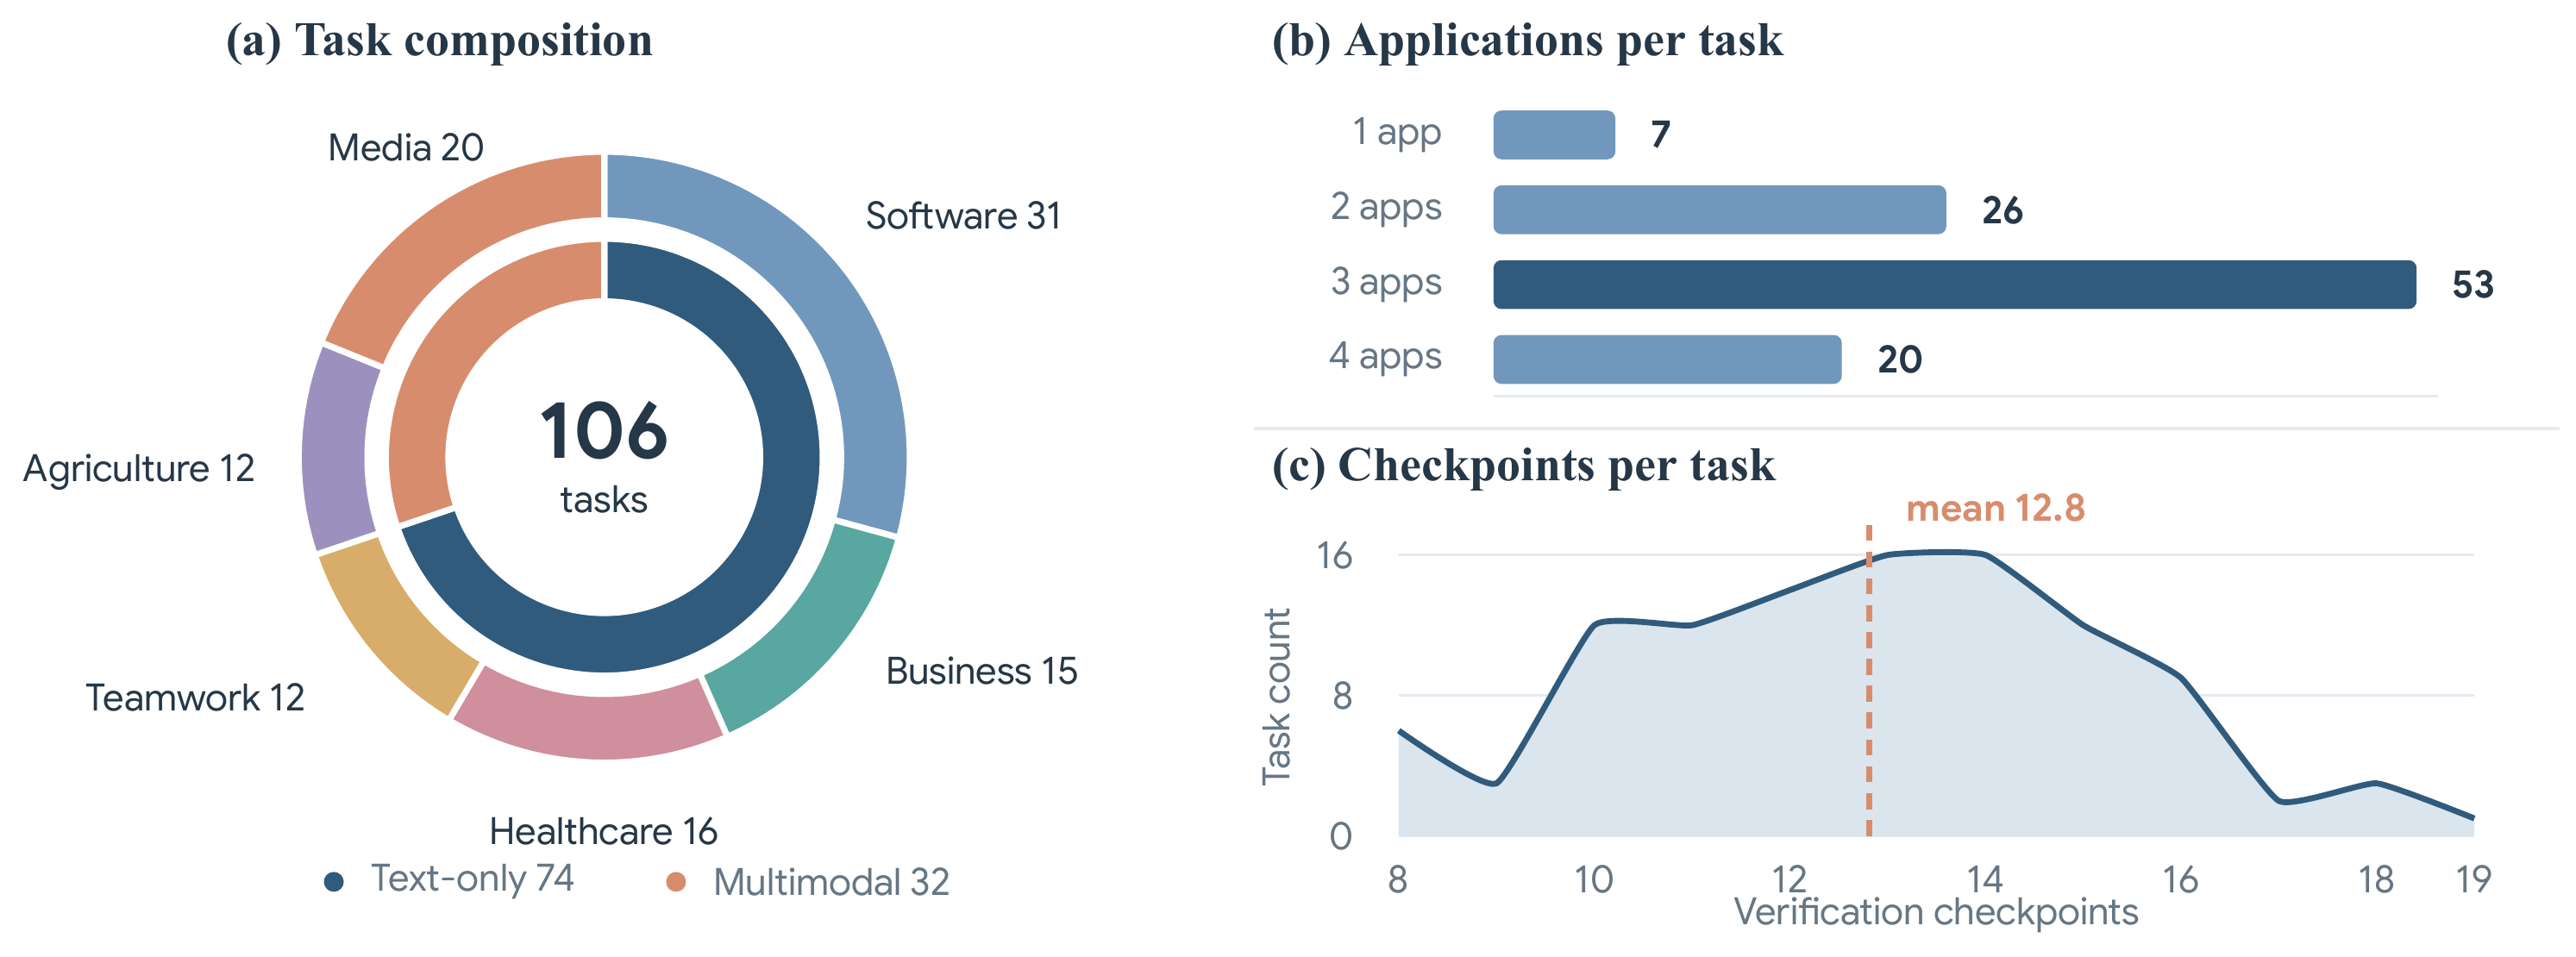 Multi-m tasks consume image / audio / PDF inputs from
`tasks/multi-m/inputs/`; verifiers locate them via paths relative to
`verify.py`. Those files ship in this repository — there is nothing extra to
download for the multimodal track.
The reference agent is built on [browser-use](https://github.com/browser-use/browser-use)
and talks to any OpenAI-compatible chat-completions endpoint. You can swap
in your own agent — only the `verify.py` contract is load-bearing.
## Optional: run the apps on Kubernetes
The default path starts every task's apps with `docker run` on the machine that
also drives the agent. That works well for one host, but it caps concurrency at
the local port range and puts the browser, the apps and the verifier on the same
box.
The same scenarios and verifiers can instead run as ephemeral per-run
environments in **your own** Kubernetes cluster, behind a small REST API
(`prepare` / `prompt` / `grade` / `release` / `catalog`). The client then only
needs a URL and a bearer token, so an agent written in any language can be
graded against real app state over plain HTTP.
- **Deployment guide** — [`docs/kubernetes.md`](docs/kubernetes.md)
- **Bring-your-own agent guide** — [`docs/agent-byo.md`](docs/agent-byo.md)
- **API reference** — `GET /docs` on your deployment (Swagger UI)
```bash
export PLAYGROUND_URL=https://api.