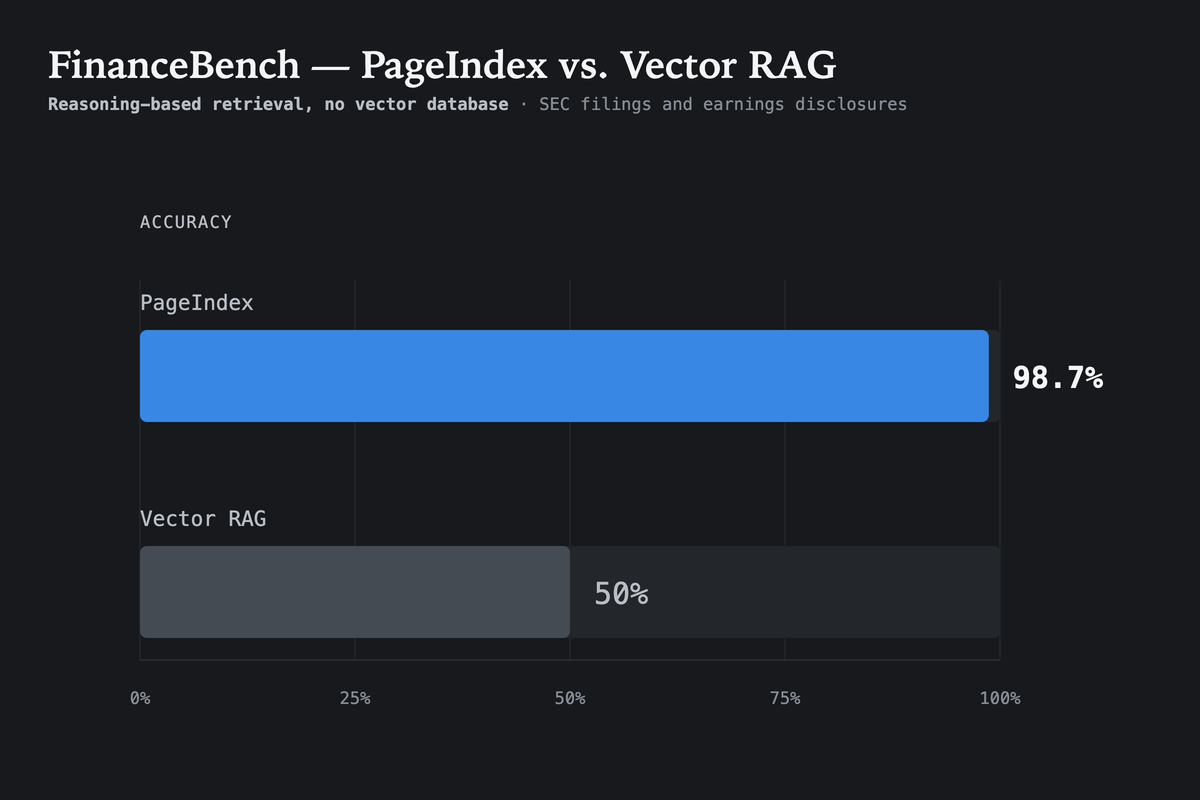
Reasoning-based RAG ◦ No Vector DB, No Chunking ◦ Context-Aware Retrieval ◦ Reads Like a Human
Reasoning-based RAG ◦ No Vector DB, No Chunking ◦ Context-Aware Retrieval ◦ Reads Like a Human
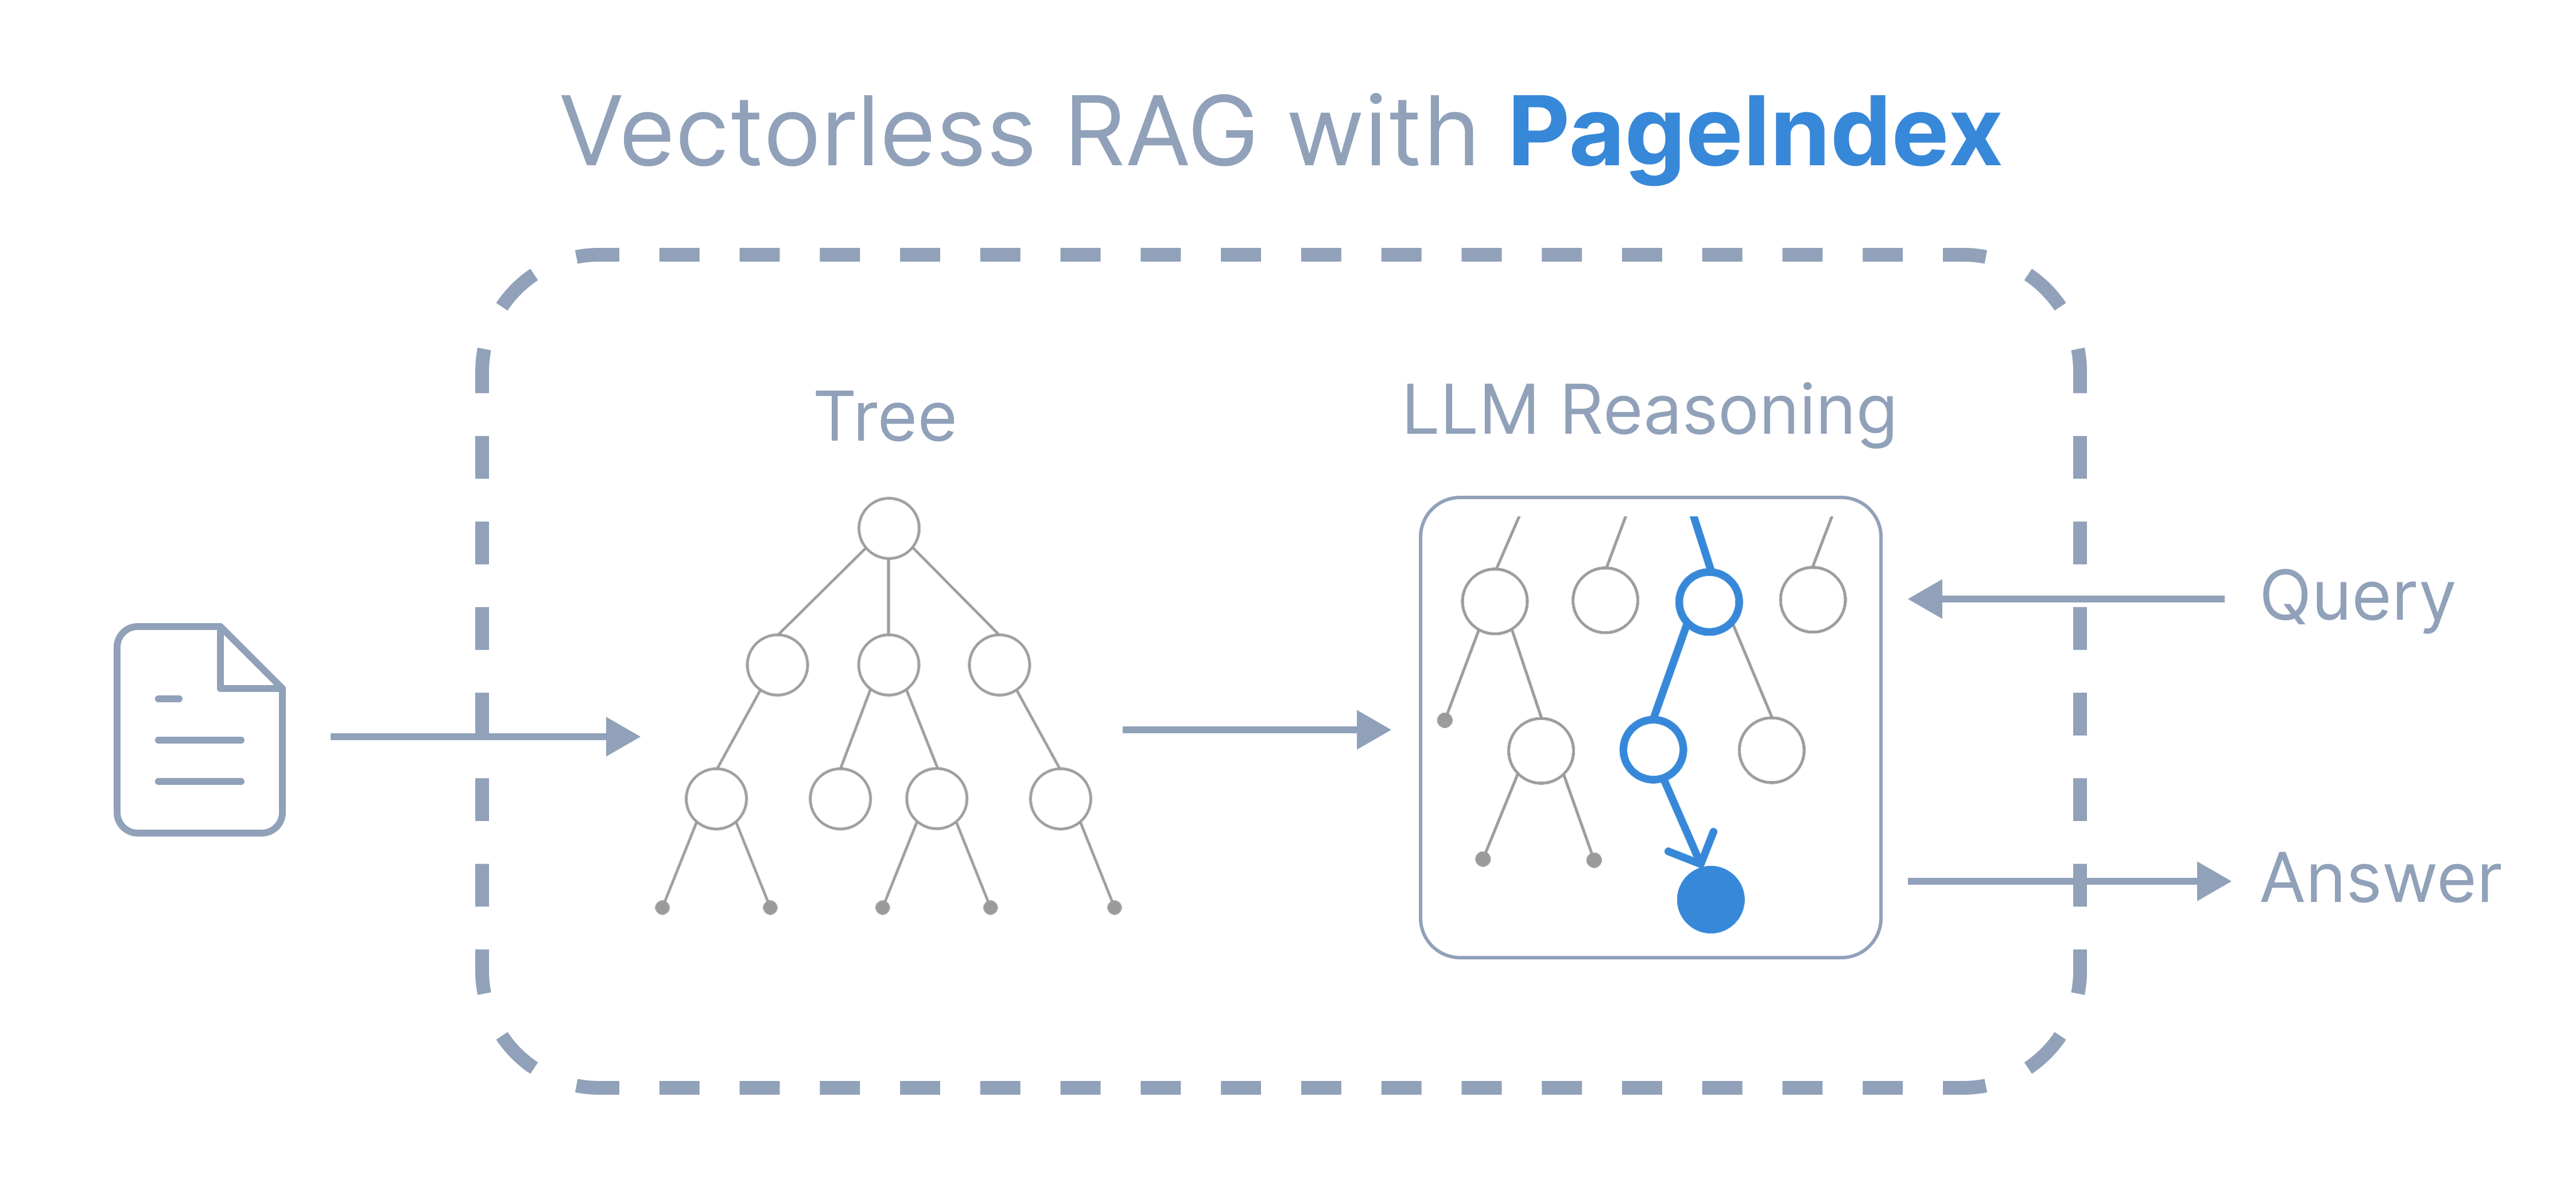
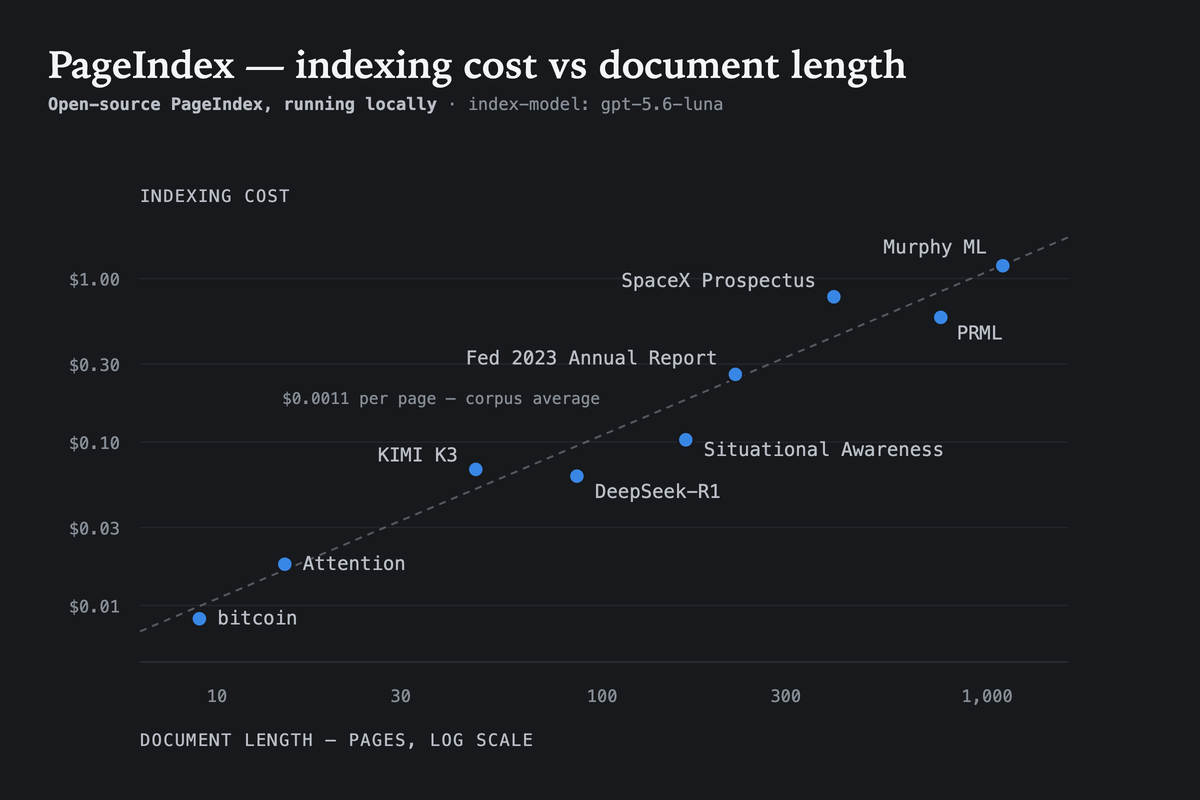
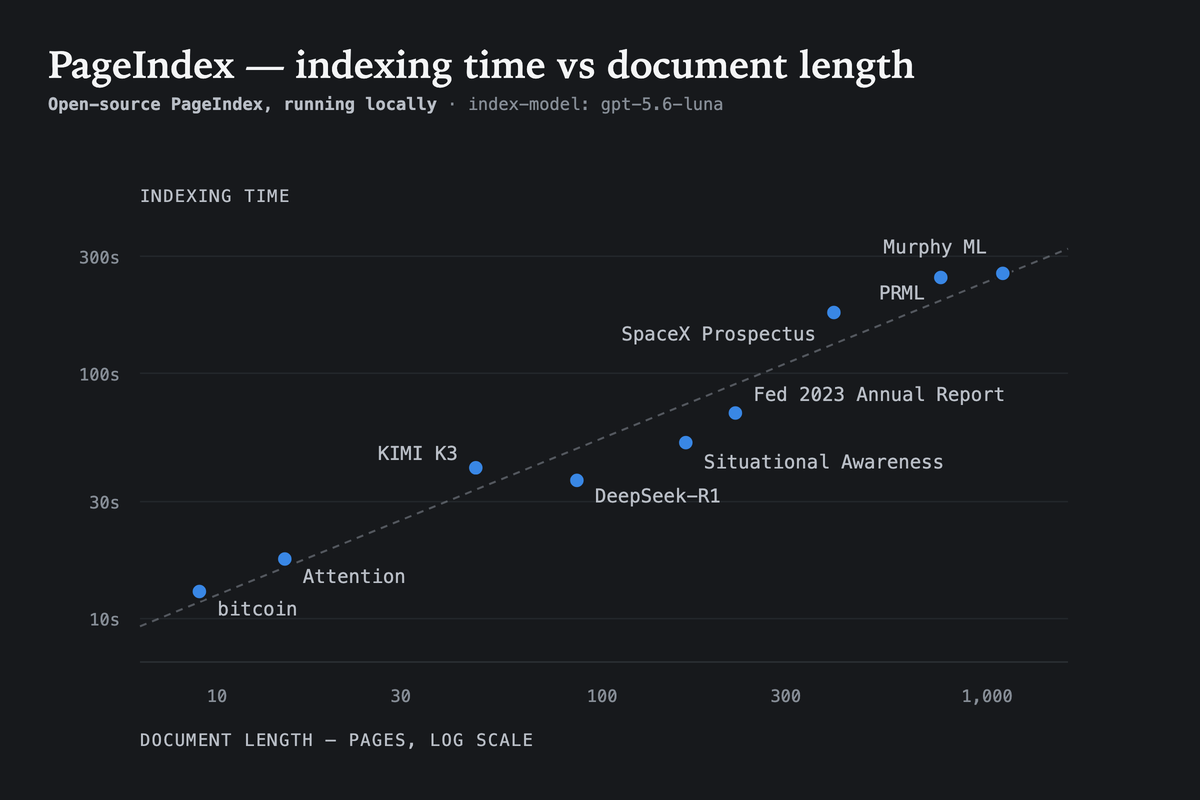
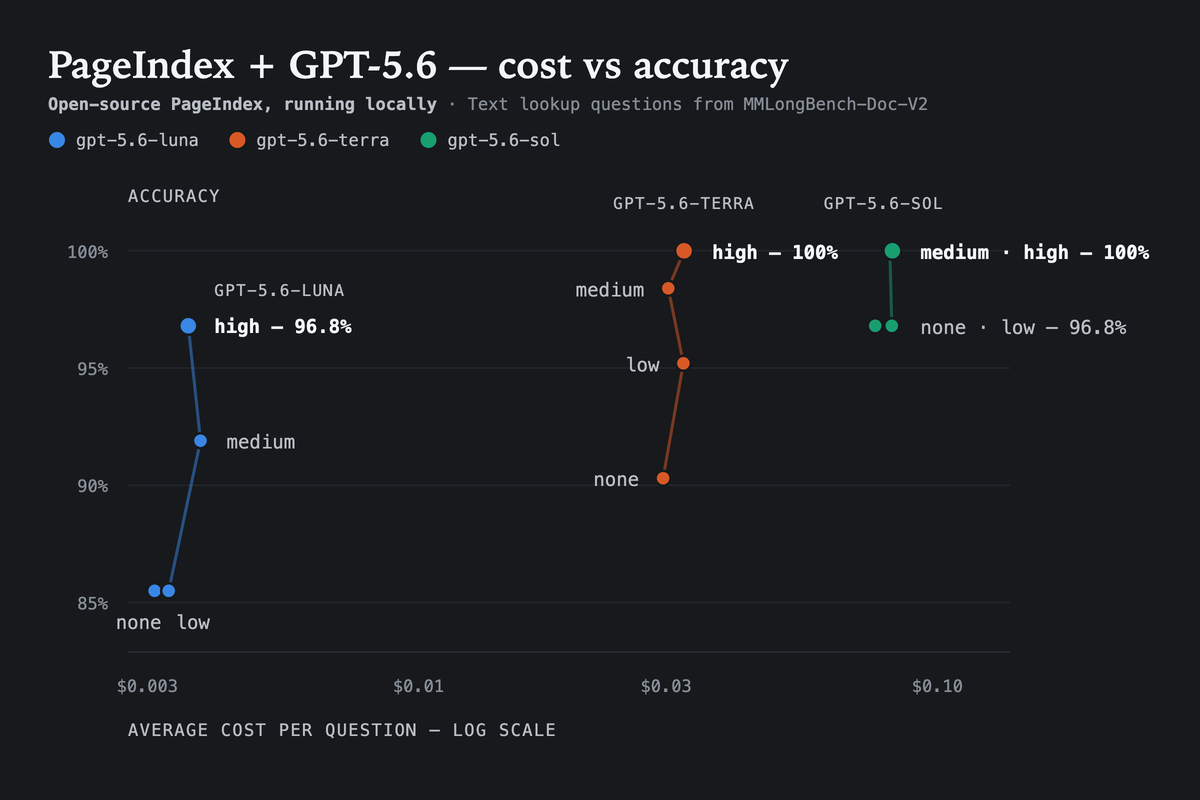
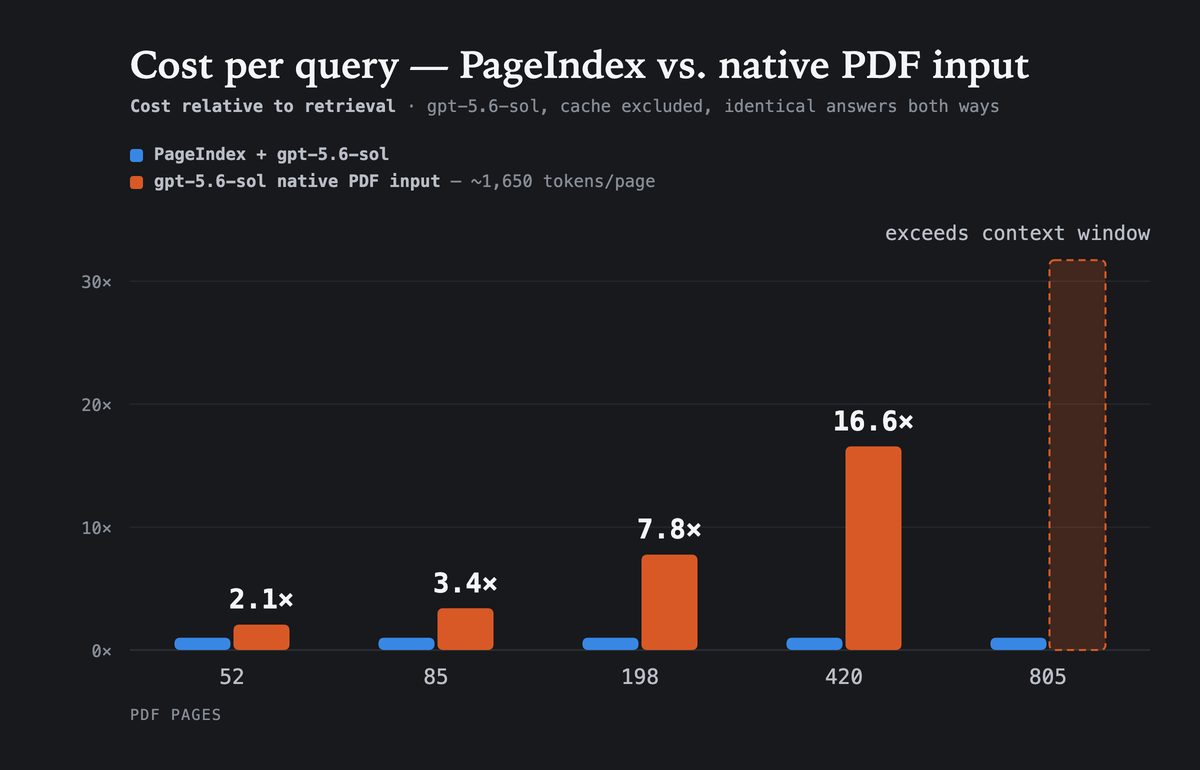
PageIndex is a vectorless, reasoning-based RAG engine that mirrors how humans read, delivering traceable, explainable, and context-aware retrieval, with no vector DBs or chunking.### Compare with Vector RAG | | Vector RAG | **PageIndex** | |---|---|---| | **Index** | vector index | tree index | | **Retrieval** | semantic similarity search | LLM reasoning over the tree | | **Result** | opaque, “vibe retrieval” | traceable to explicit references | | **Context** | query embedding only | full context: conversation history, domain knowledge, etc. | It is ideal for financial reports, legal documents, regulatory filings, technical manuals, medical literature, academic textbooks, and any other long, complex professional document. # Quickstart ```bash pip install -U pageindex ``` ```python import os from pageindex import PageIndexClient os.environ["OPENAI_API_KEY"] = "your-openai-key" client = PageIndexClient( index="gpt-5.6-luna", # model to build the tree index chat="gpt-5.6-sol", # model to search the tree ) doc_id = client.submit_document("report.pdf")["doc_id"] answer = client.chat("What was the 2023 operating margin?", doc_id=doc_id) print(answer) ``` ### Model Recommendations - **`index=`: a basic model is sufficient.** The tree structure itself is extracted from the document layout without an LLM; the index model only summarizes and refines it, which a basic model does well. - **`chat=`: use the best model you can afford.** The chat model searches the tree to retrieve information. See [Query cost and accuracy](#query-cost-and-accuracy). ### [Use PageIndex through the SDK client →](https://docs.pageindex.ai/getting-started) Configure other models, streaming, multi-document search, citations, and more. ### [Integrate PageIndex with your own agent →](https://docs.pageindex.ai/sdk/agents) Drop PageIndex tools into the OpenAI Agents SDK, the Claude Agent SDK, or any other framework. # Benchmarks ### Local indexing cost and time Building a tree locally runs **about $0.001 per page** with `gpt-5.6-luna` as the index model, so a 1,000-page textbook costs a little over a dollar and a few minutes, once, and every later question reuses it. PageIndex is designed not to rely heavily on the model used at index time, so in our experiments a basic model does not hurt quality.