Vocalinux # Vocalinux **Voice dictation for Linux** [![Ubuntu](https://img.shields.io/badge/Ubuntu-24.04+-E95420?logo=ubuntu&logoColor=white)](docs/DISTRO_COMPATIBILITY.md) [![Debian](https://img.shields.io/badge/Debian-12+-A81D33?logo=debian&logoColor=white)](docs/DISTRO_COMPATIBILITY.md) [![Fedora](https://img.shields.io/badge/Fedora-42+-51A2DA?logo=fedora&logoColor=white)](docs/DISTRO_COMPATIBILITY.md) [![Arch](https://img.shields.io/badge/Arch-rolling-1793D1?logo=archlinux&logoColor=white)](docs/DISTRO_COMPATIBILITY.md) [![openSUSE](https://img.shields.io/badge/openSUSE-Tumbleweed-73BA25?logo=opensuse&logoColor=white)](docs/DISTRO_COMPATIBILITY.md) [![Privacy: on-device](https://img.shields.io/badge/privacy-on--device-success)](https://github.com/VocaHQ/vocalinux#privacy-and-security) [![X11 & Wayland](https://img.shields.io/badge/display-X11%20%7C%20Wayland-lightgrey)](https://github.com/VocaHQ/vocalinux#features) [![License: AGPL-3.0](https://img.shields.io/badge/License-AGPL--3.0-blue.svg)](https://www.gnu.org/licenses/agpl-3.0) [![Python 3.11+](https://img.shields.io/badge/python-3.11+-blue.svg)](https://www.python.org/downloads/) [![GitHub release](https://img.shields.io/github/v/release/VocaHQ/vocalinux)](https://github.com/VocaHQ/vocalinux/releases) [![AppImage](https://img.shields.io/badge/AppImage-x86__64%20%7C%20aarch64-2C5BB4)](https://github.com/VocaHQ/vocalinux/releases/latest) [![.deb](https://img.shields.io/badge/.deb-Debian%20%7C%20Ubuntu-A81D33?logo=debian&logoColor=white)](https://github.com/VocaHQ/vocalinux/releases/latest) [![.rpm](https://img.shields.io/badge/.rpm-Fedora-EE0000?logo=fedora&logoColor=white)](https://github.com/VocaHQ/vocalinux/releases/latest) [![Flatpak](https://img.shields.io/badge/Flatpak-vocahq%20remote-4A90D9?logo=flatpak&logoColor=white)](#flatpak-any-distro) [![Snap](https://img.shields.io/badge/Snap-edge-82BEA0?logo=snapcraft&logoColor=white)](https://snapcraft.io/vocalinux) [![AUR](https://img.shields.io/aur/version/vocalinux)](https://aur.archlinux.org/packages/vocalinux) [![PyPI](https://img.shields.io/pypi/v/vocalinux)](https://pypi.org/project/vocalinux/) [![Nix flake](https://img.shields.io/badge/Nix-flake-5277C3?logo=nixos&logoColor=white)](packaging/nix/README.md) [![Discord](https://img.shields.io/discord/1538633755877580810?logo=discord&logoColor=white&label=Discord)](https://discord.gg/t6muquAJbm) [![VocaHQ](https://img.shields.io/badge/VocaHQ-vocahq.com-1a7f4e)](https://vocahq.com) [![Follow on X](https://img.shields.io/badge/Follow%20%40vocahq-000000?style=flat&logo=x&logoColor=white)](https://x.com/vocahq) [Website](https://vocalinux.com) · [Install](#install) · [Docs](#documentation) · [Releases](https://github.com/VocaHQ/vocalinux/releases)
Vocalinux turns speech into typed text in whatever app has focus. It is a free, AGPL-3.0-licensed desktop app for X11 and Wayland. After you download a model, local engines (whisper.cpp by default, plus OpenAI Whisper, Faster Whisper, VOSK, and Parakeet) run speech-to-text on your machine. An optional remote HTTP API is off unless you configure it. No Voca account is required. Models download once. After that, speech-to-text stays on your machine. **Current release:** [v0.18.3](https://github.com/VocaHQ/vocalinux/releases/tag/v0.18.3). Patch: "new line" and "new paragraph" voice commands finally type real line breaks, hotkeys work again on GNOME Shell X11, packaged builds stop crashing on older CPUs, the Snap package can publish again, and Transcribe File's download dialog stops locking the transcript. Details: [docs/UPDATE.md](docs/UPDATE.md). ## Features - **On-device after model download**: Local engines; speech-to-text stays on your machine - **X11 and Wayland**: Text injection via xdotool, IBus, wtype, ydotool, or clipboard fallback - **Several engines**: whisper.cpp (default), OpenAI Whisper, Faster Whisper, VOSK, Parakeet, plus optional remote HTTP API or local VocaGateway from Settings (not on-device) - **GPU acceleration**: Vulkan for AMD, Intel, and NVIDIA with whisper.cpp - **Toggle or push-to-talk**: New installs default to hold Right Alt; existing configs keep their shortcut - **System tray + settings**: Searchable sidebar, Speech Model simple setup with Advanced as an island, status icons, audio feedback - **Start on login**: XDG autostart (desktop session, not a systemd service) - **Packaging**: install script, `.deb` / `.rpm`, AppImage, AUR, PyPI, Snap (`--edge`), Flatpak (release bundles and local build; not on Flathub), Nix flake ## Screenshots Vocalinux in action. Full gallery on the [website screenshots page](https://vocalinux.com/screenshots/). ### Product
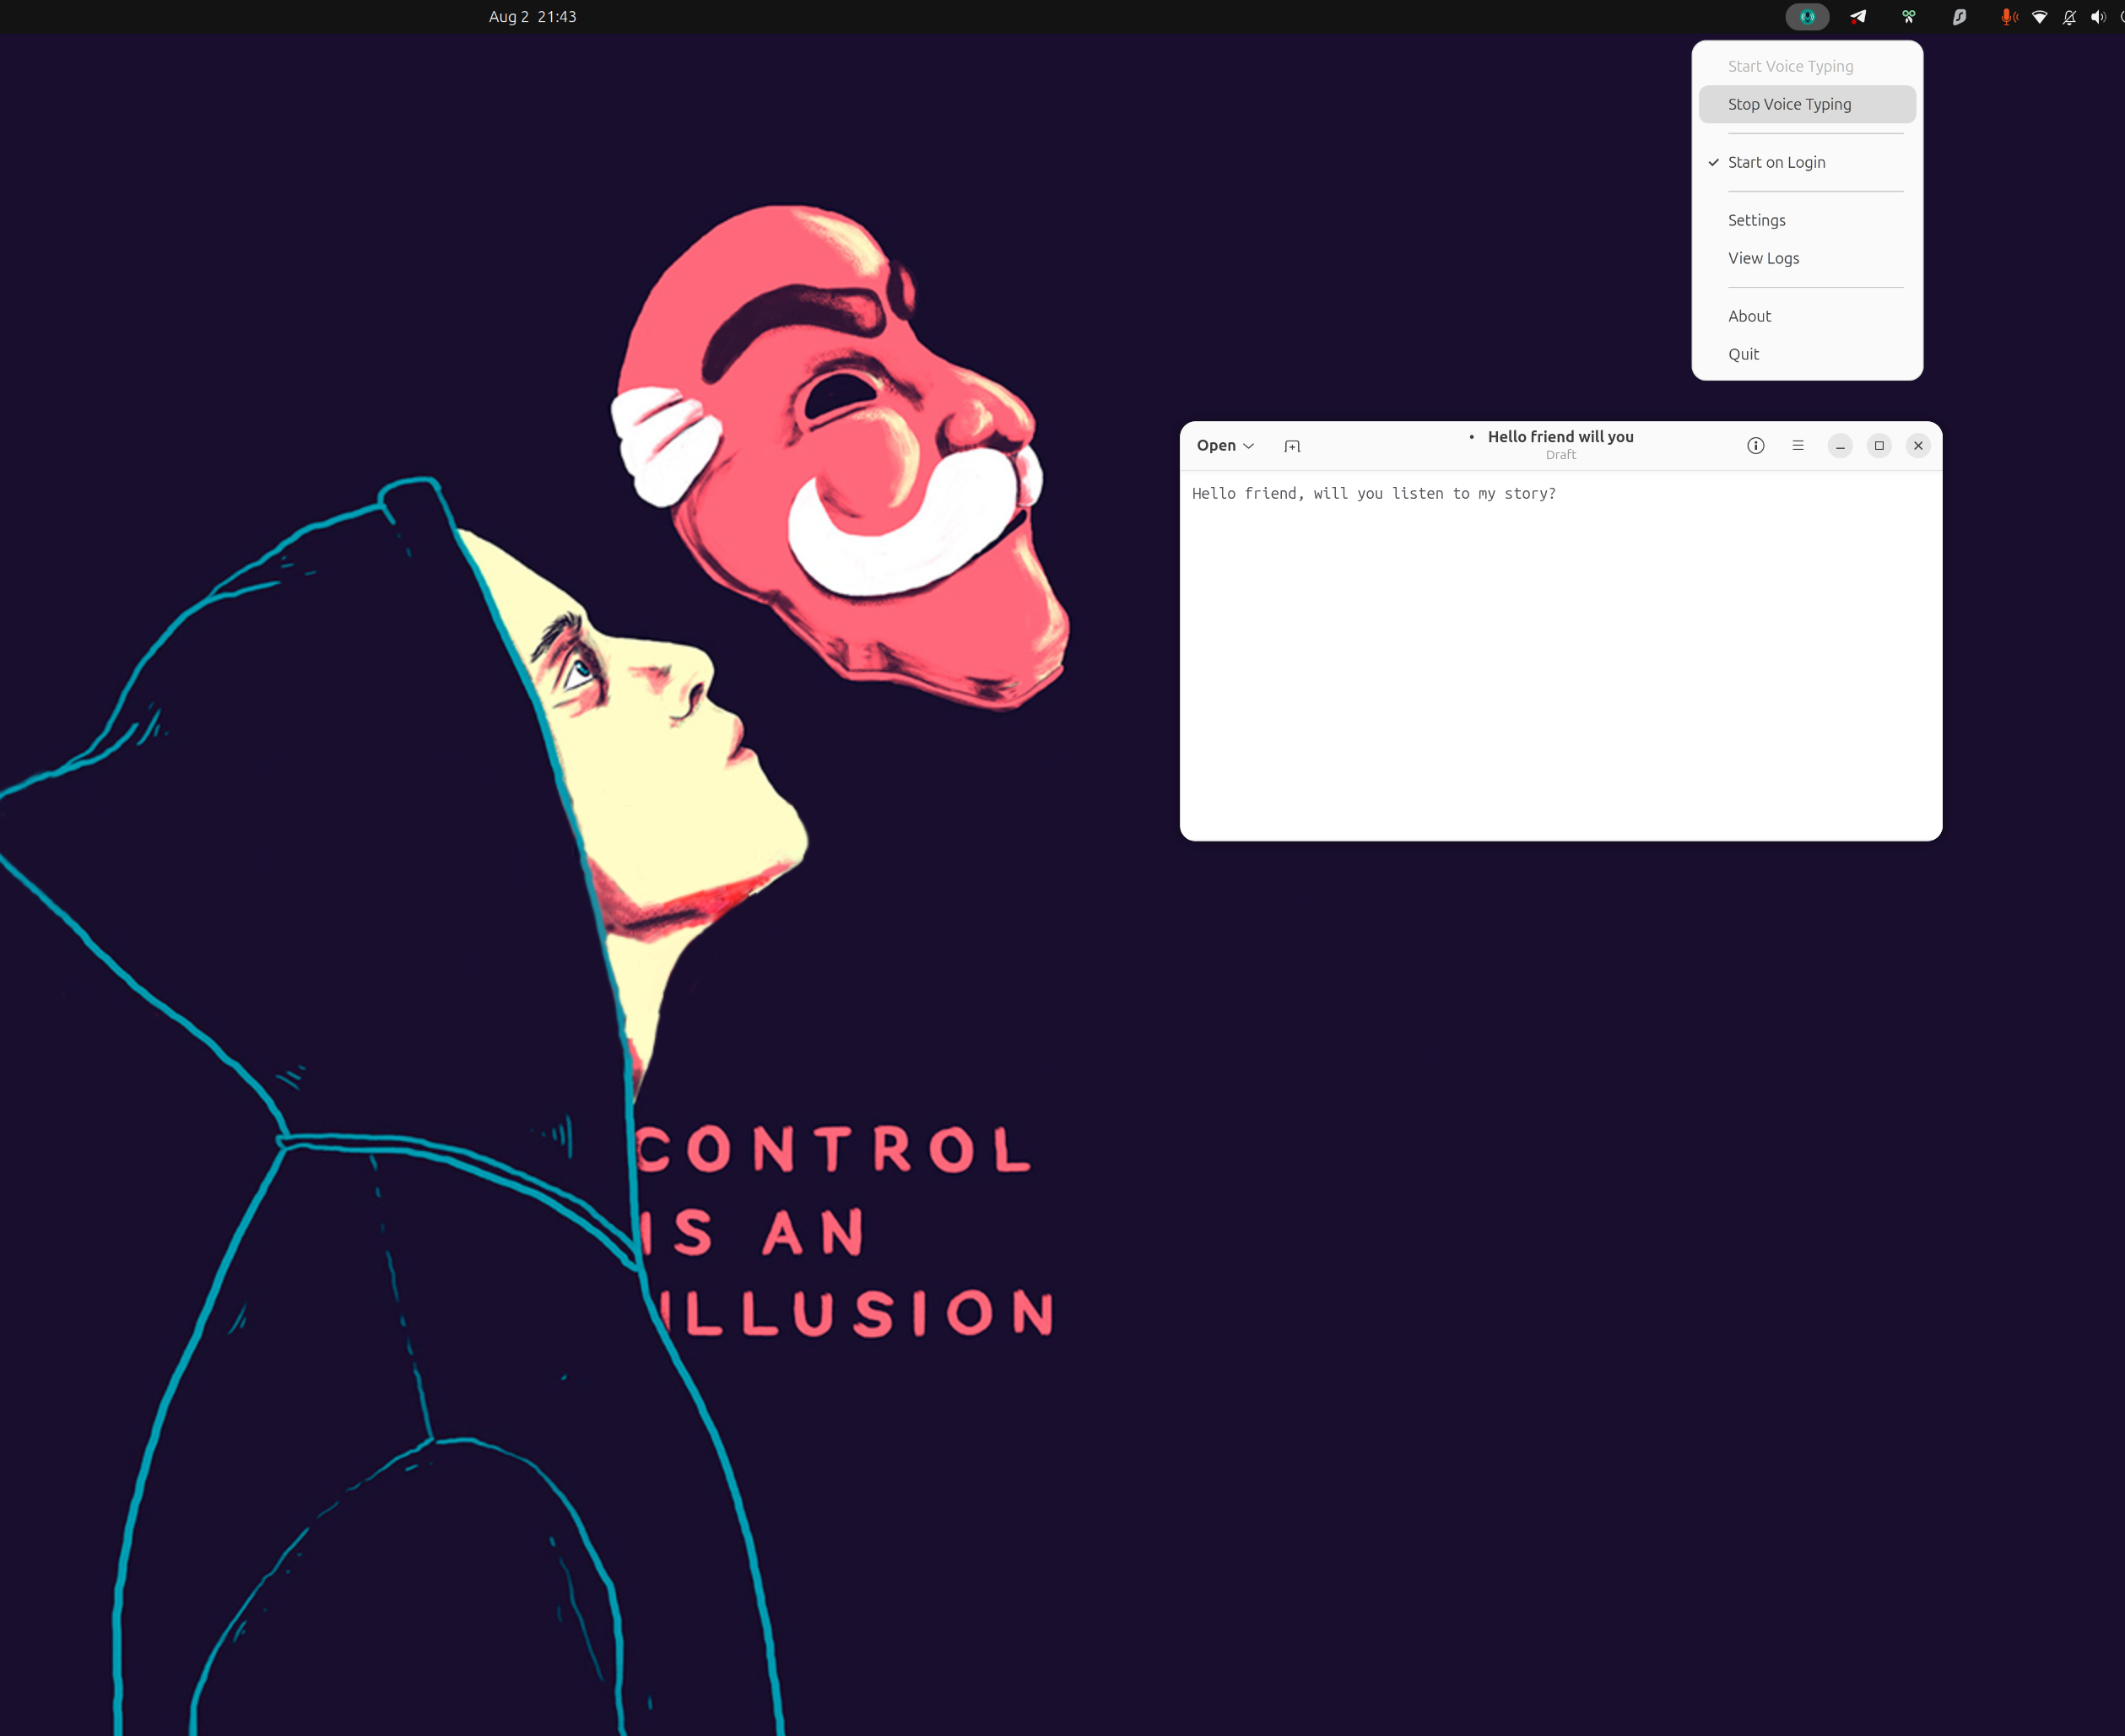
Transcription in Action
Real-time voice-to-text transcription
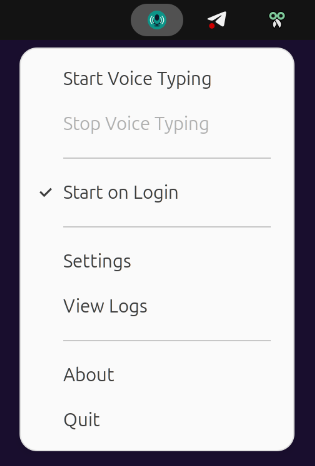
System Tray
System tray with listening indicator
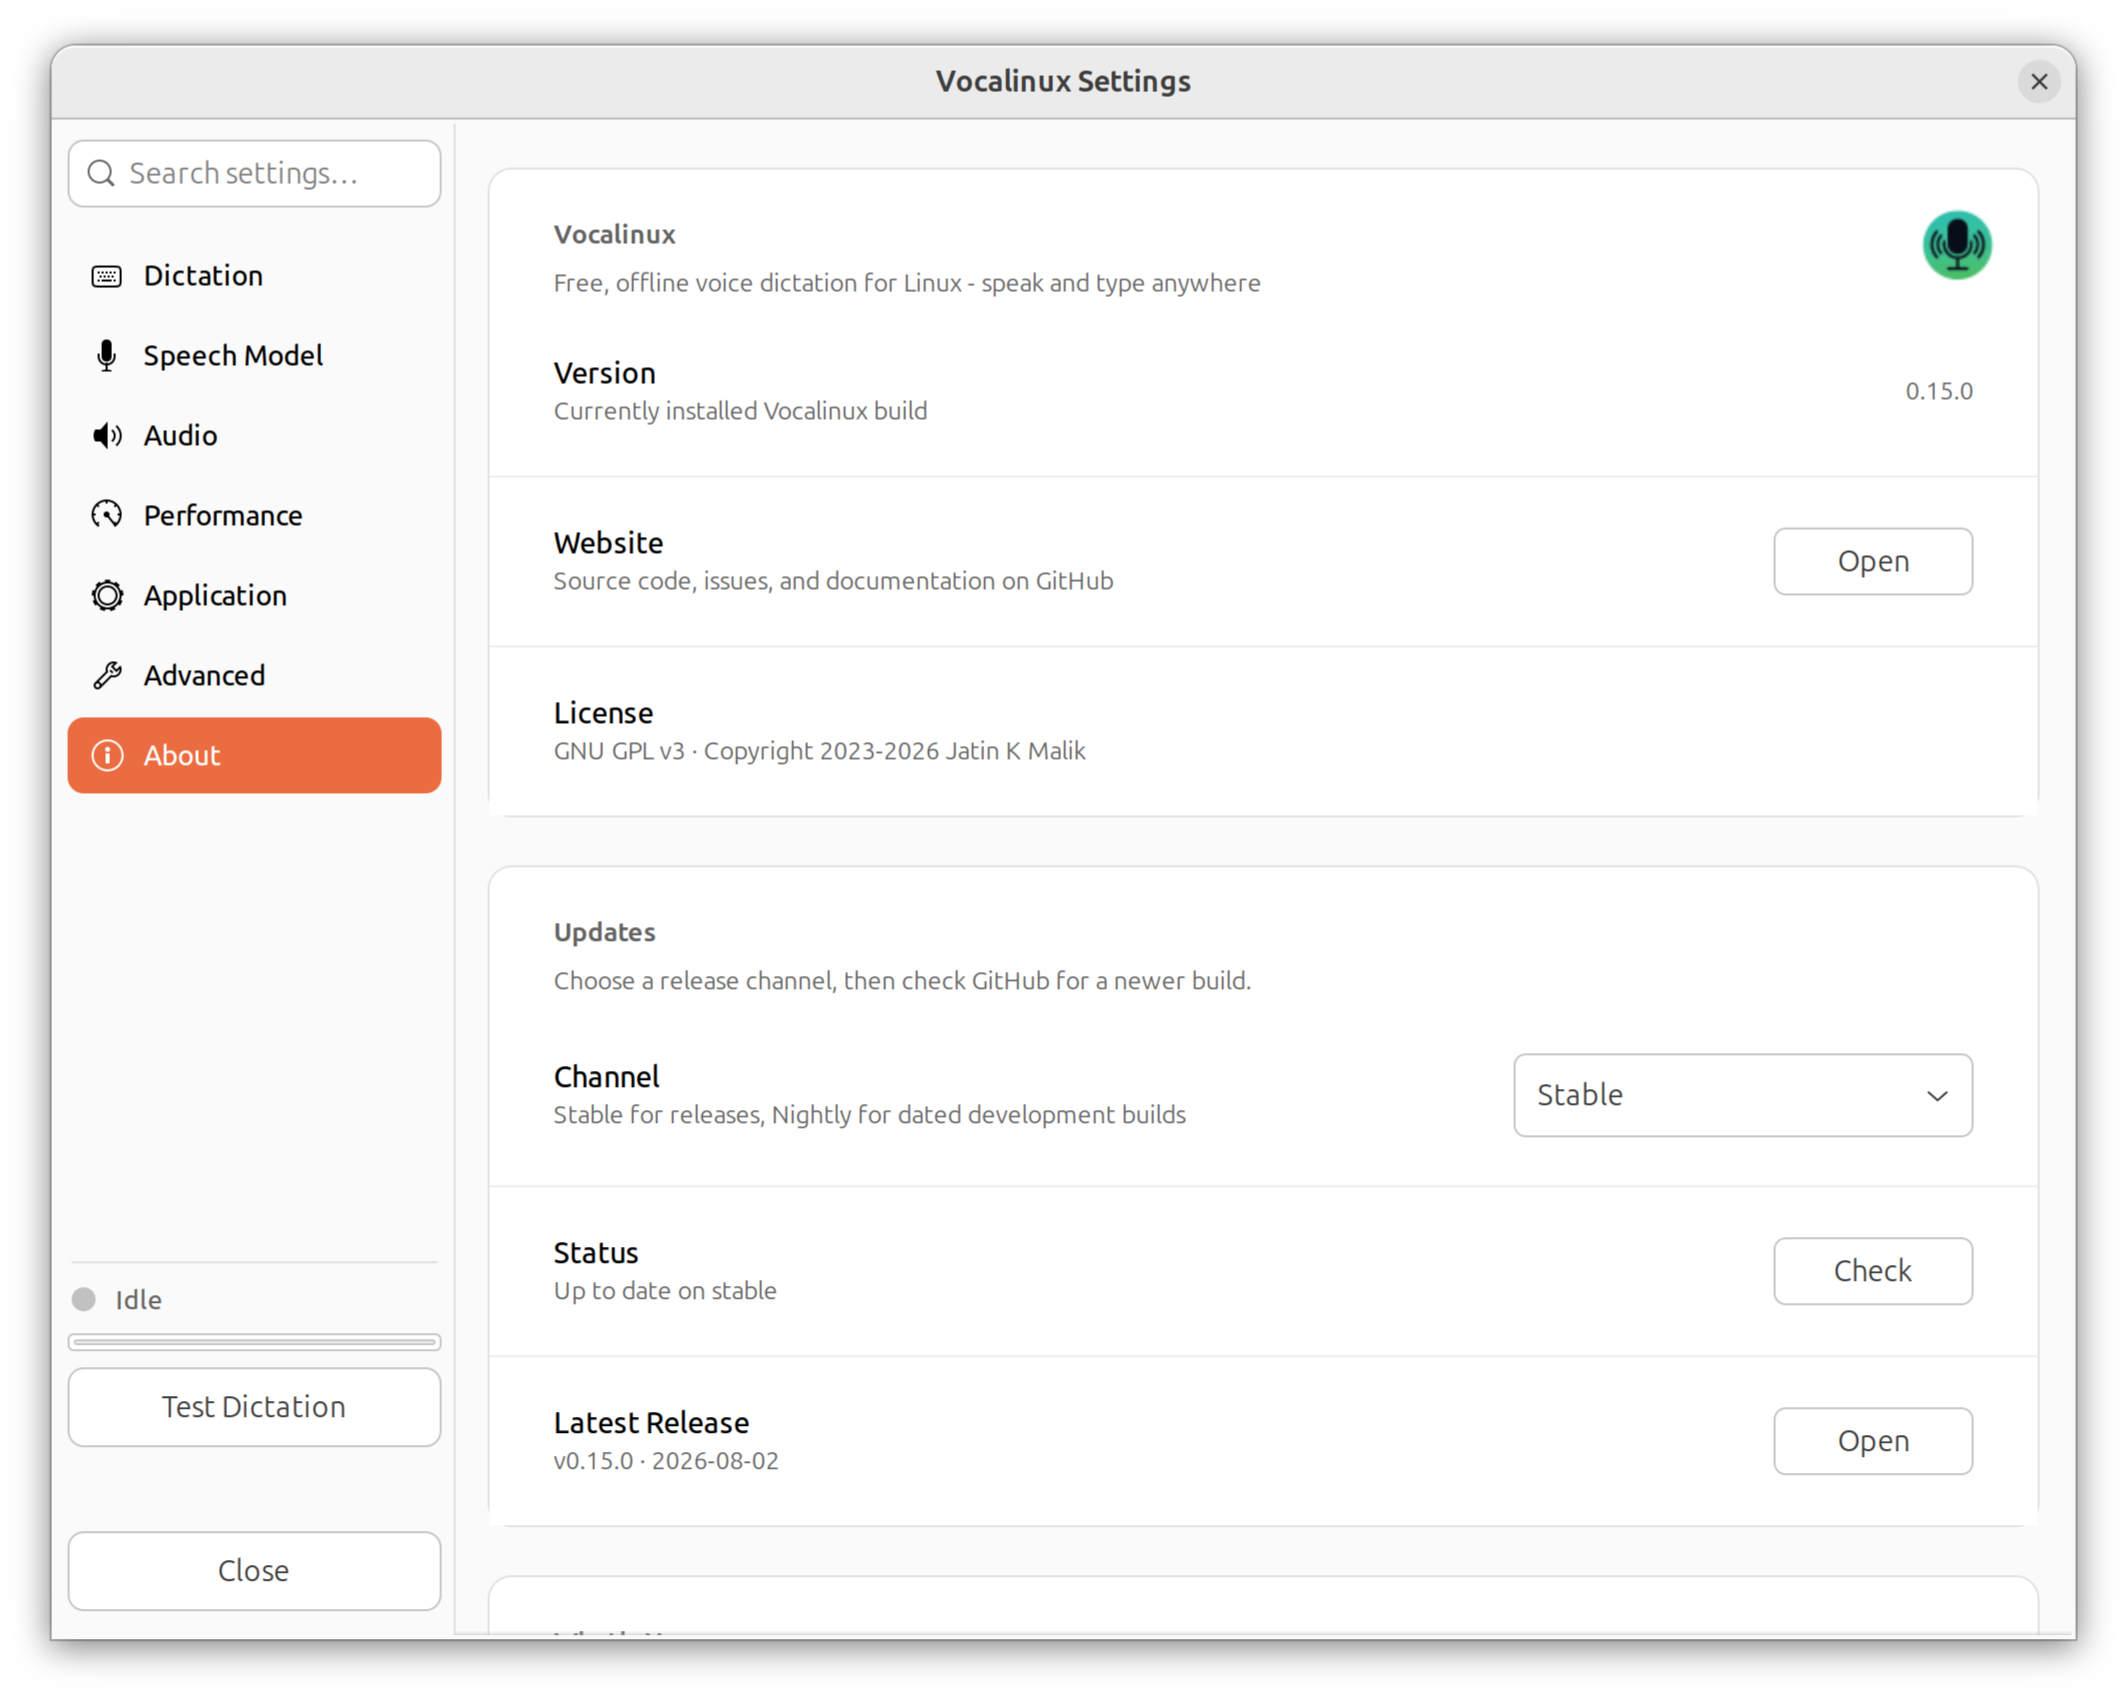
About View
About & Updates in Settings
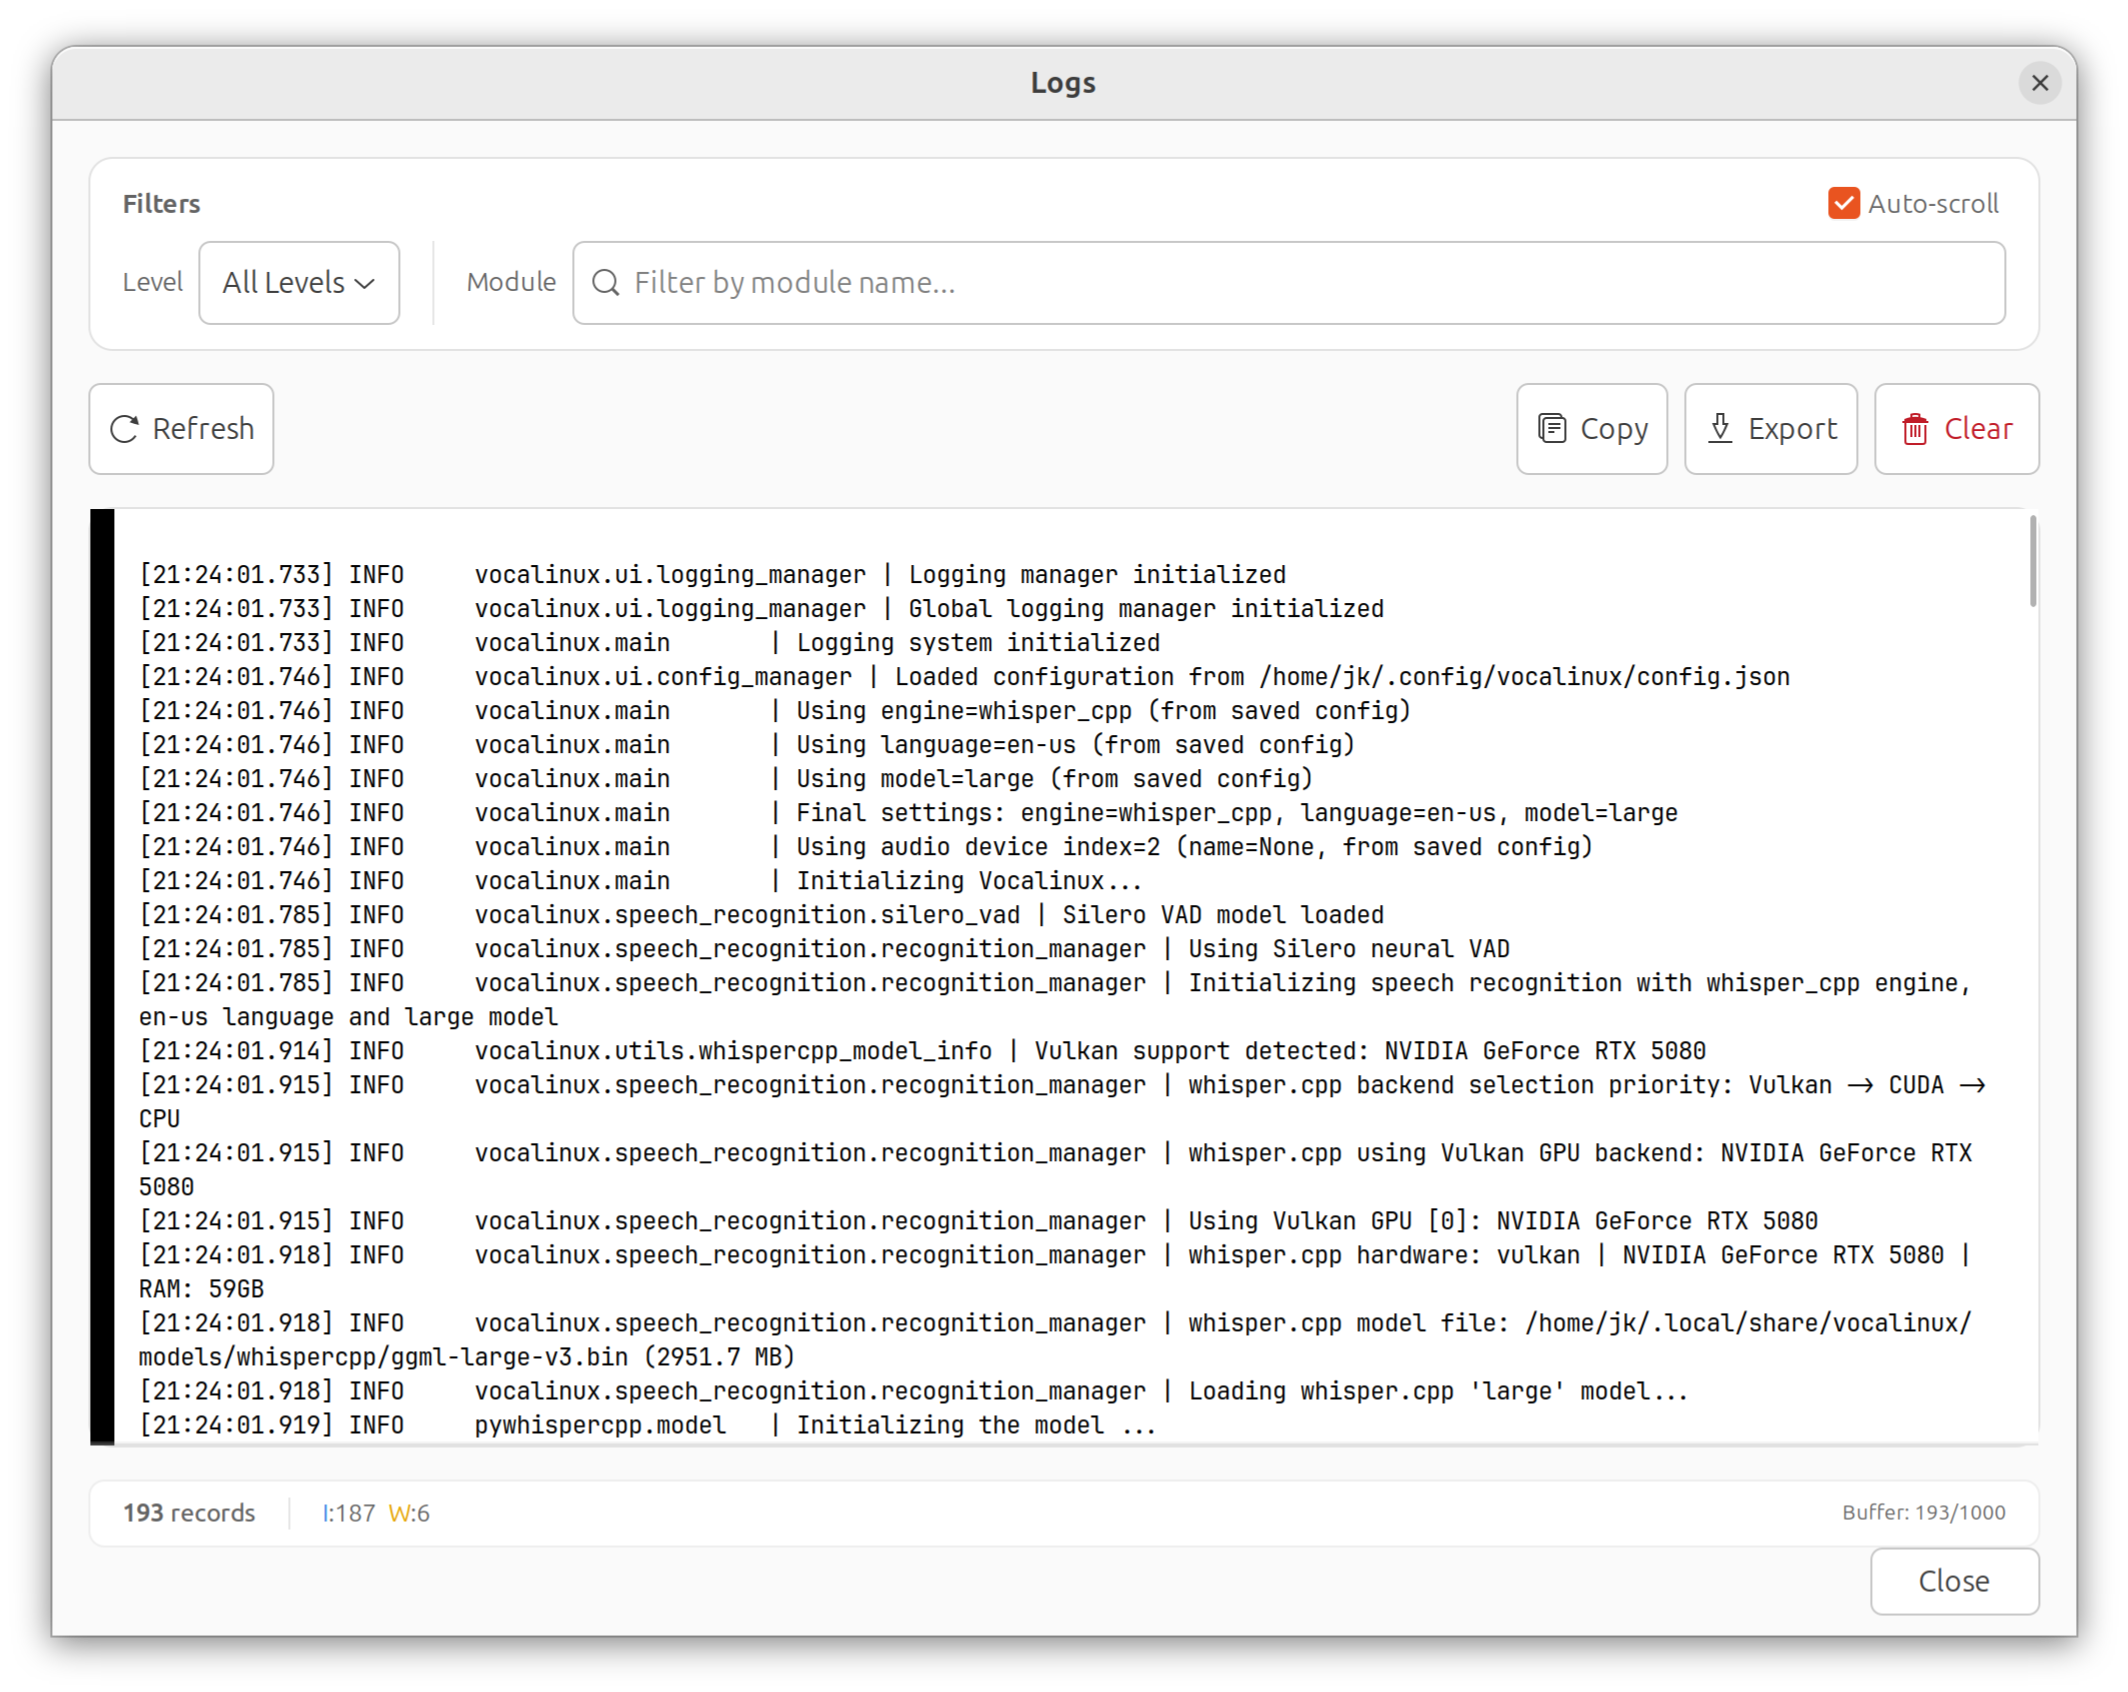
Log Viewer
Log viewer for debugging
### Settings
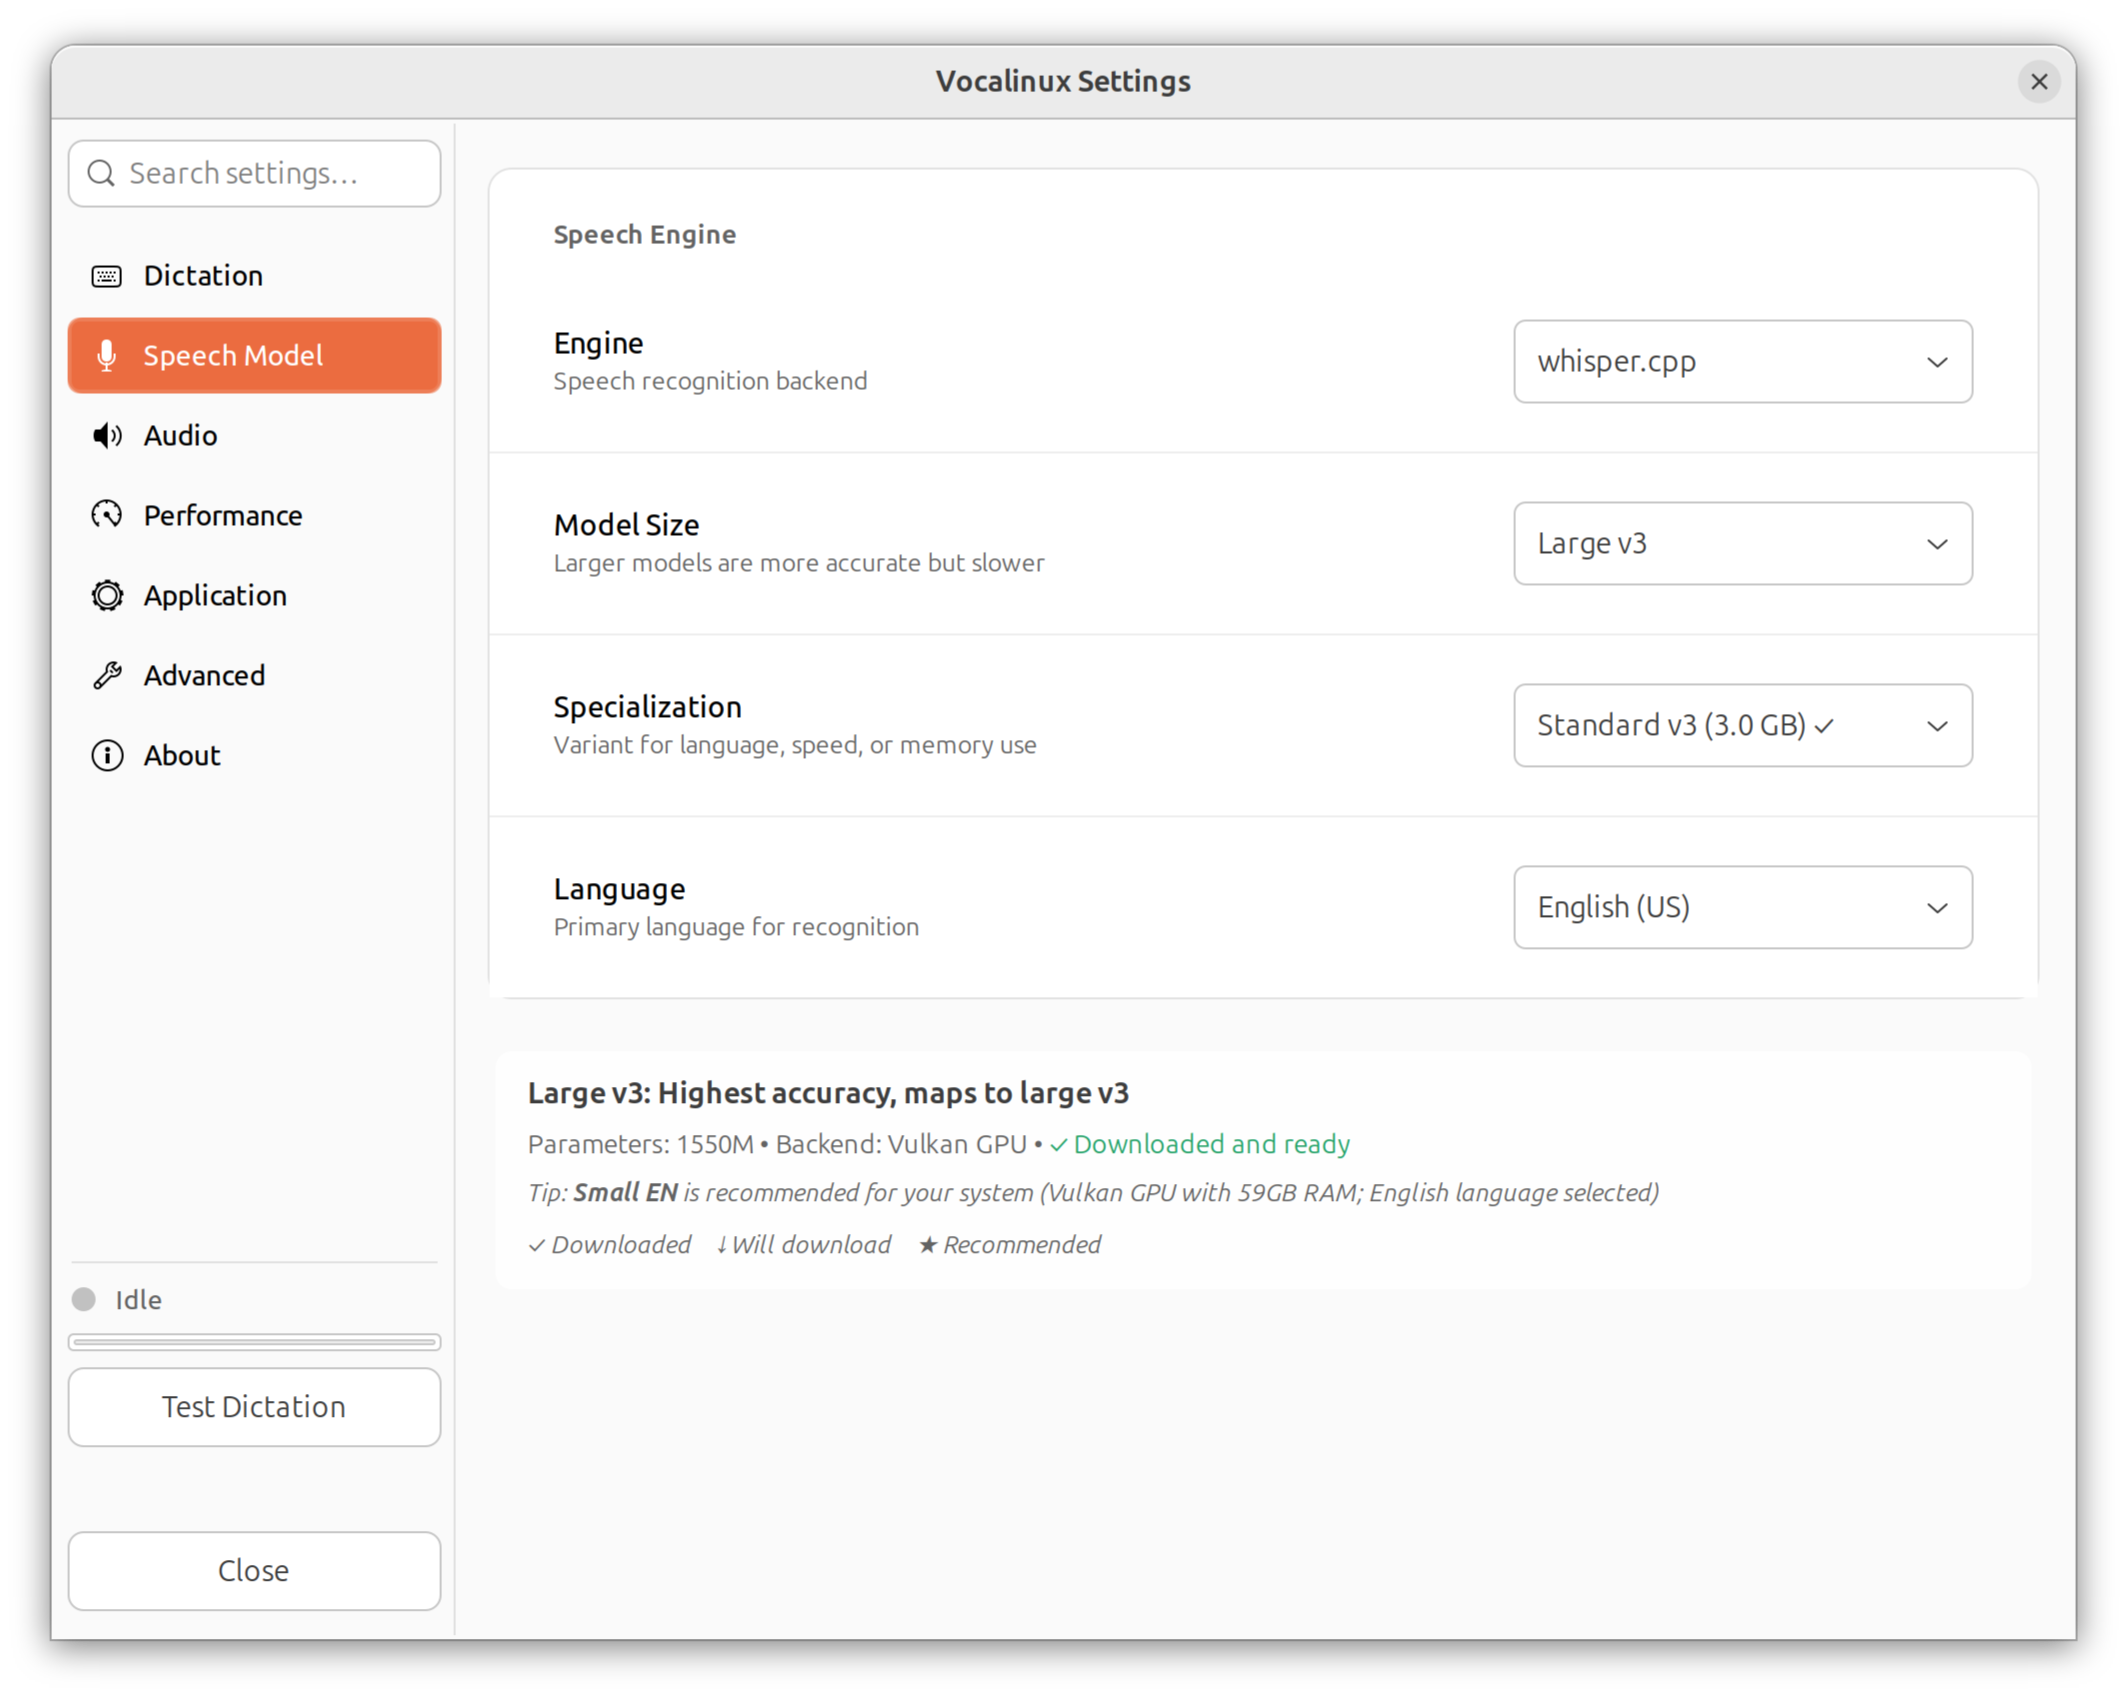
Speech Engine settings
Speech Engine
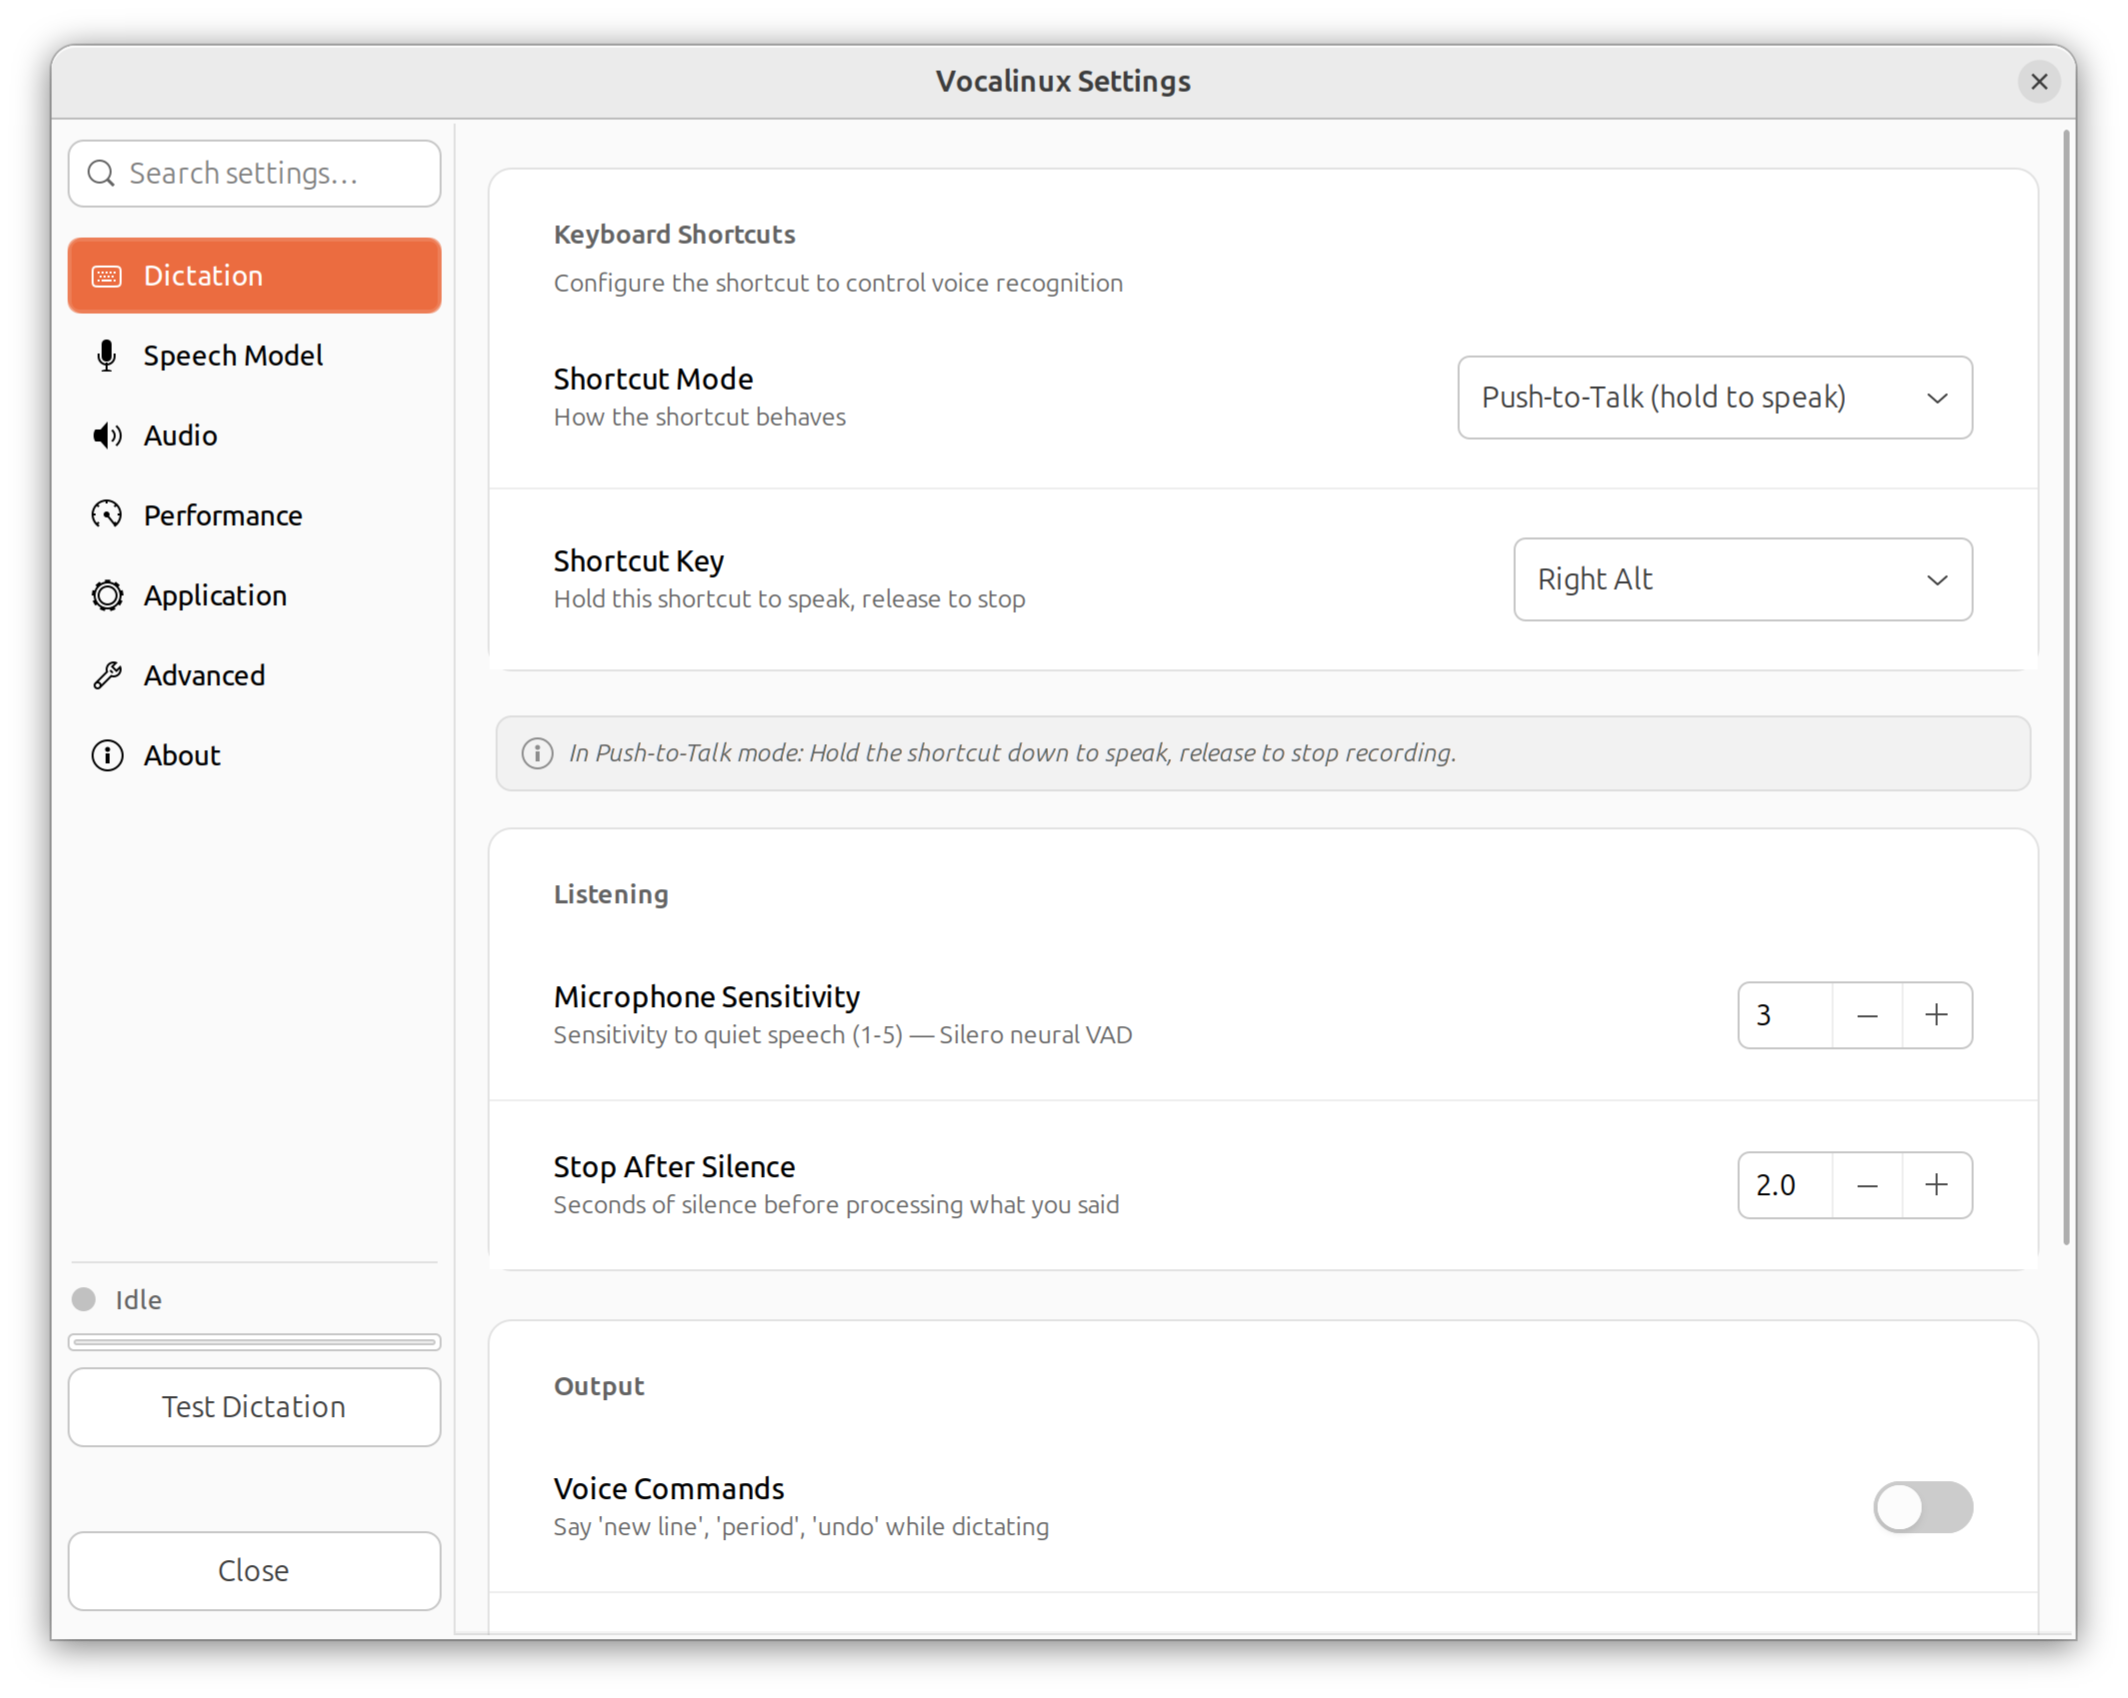
Recognition settings
Recognition
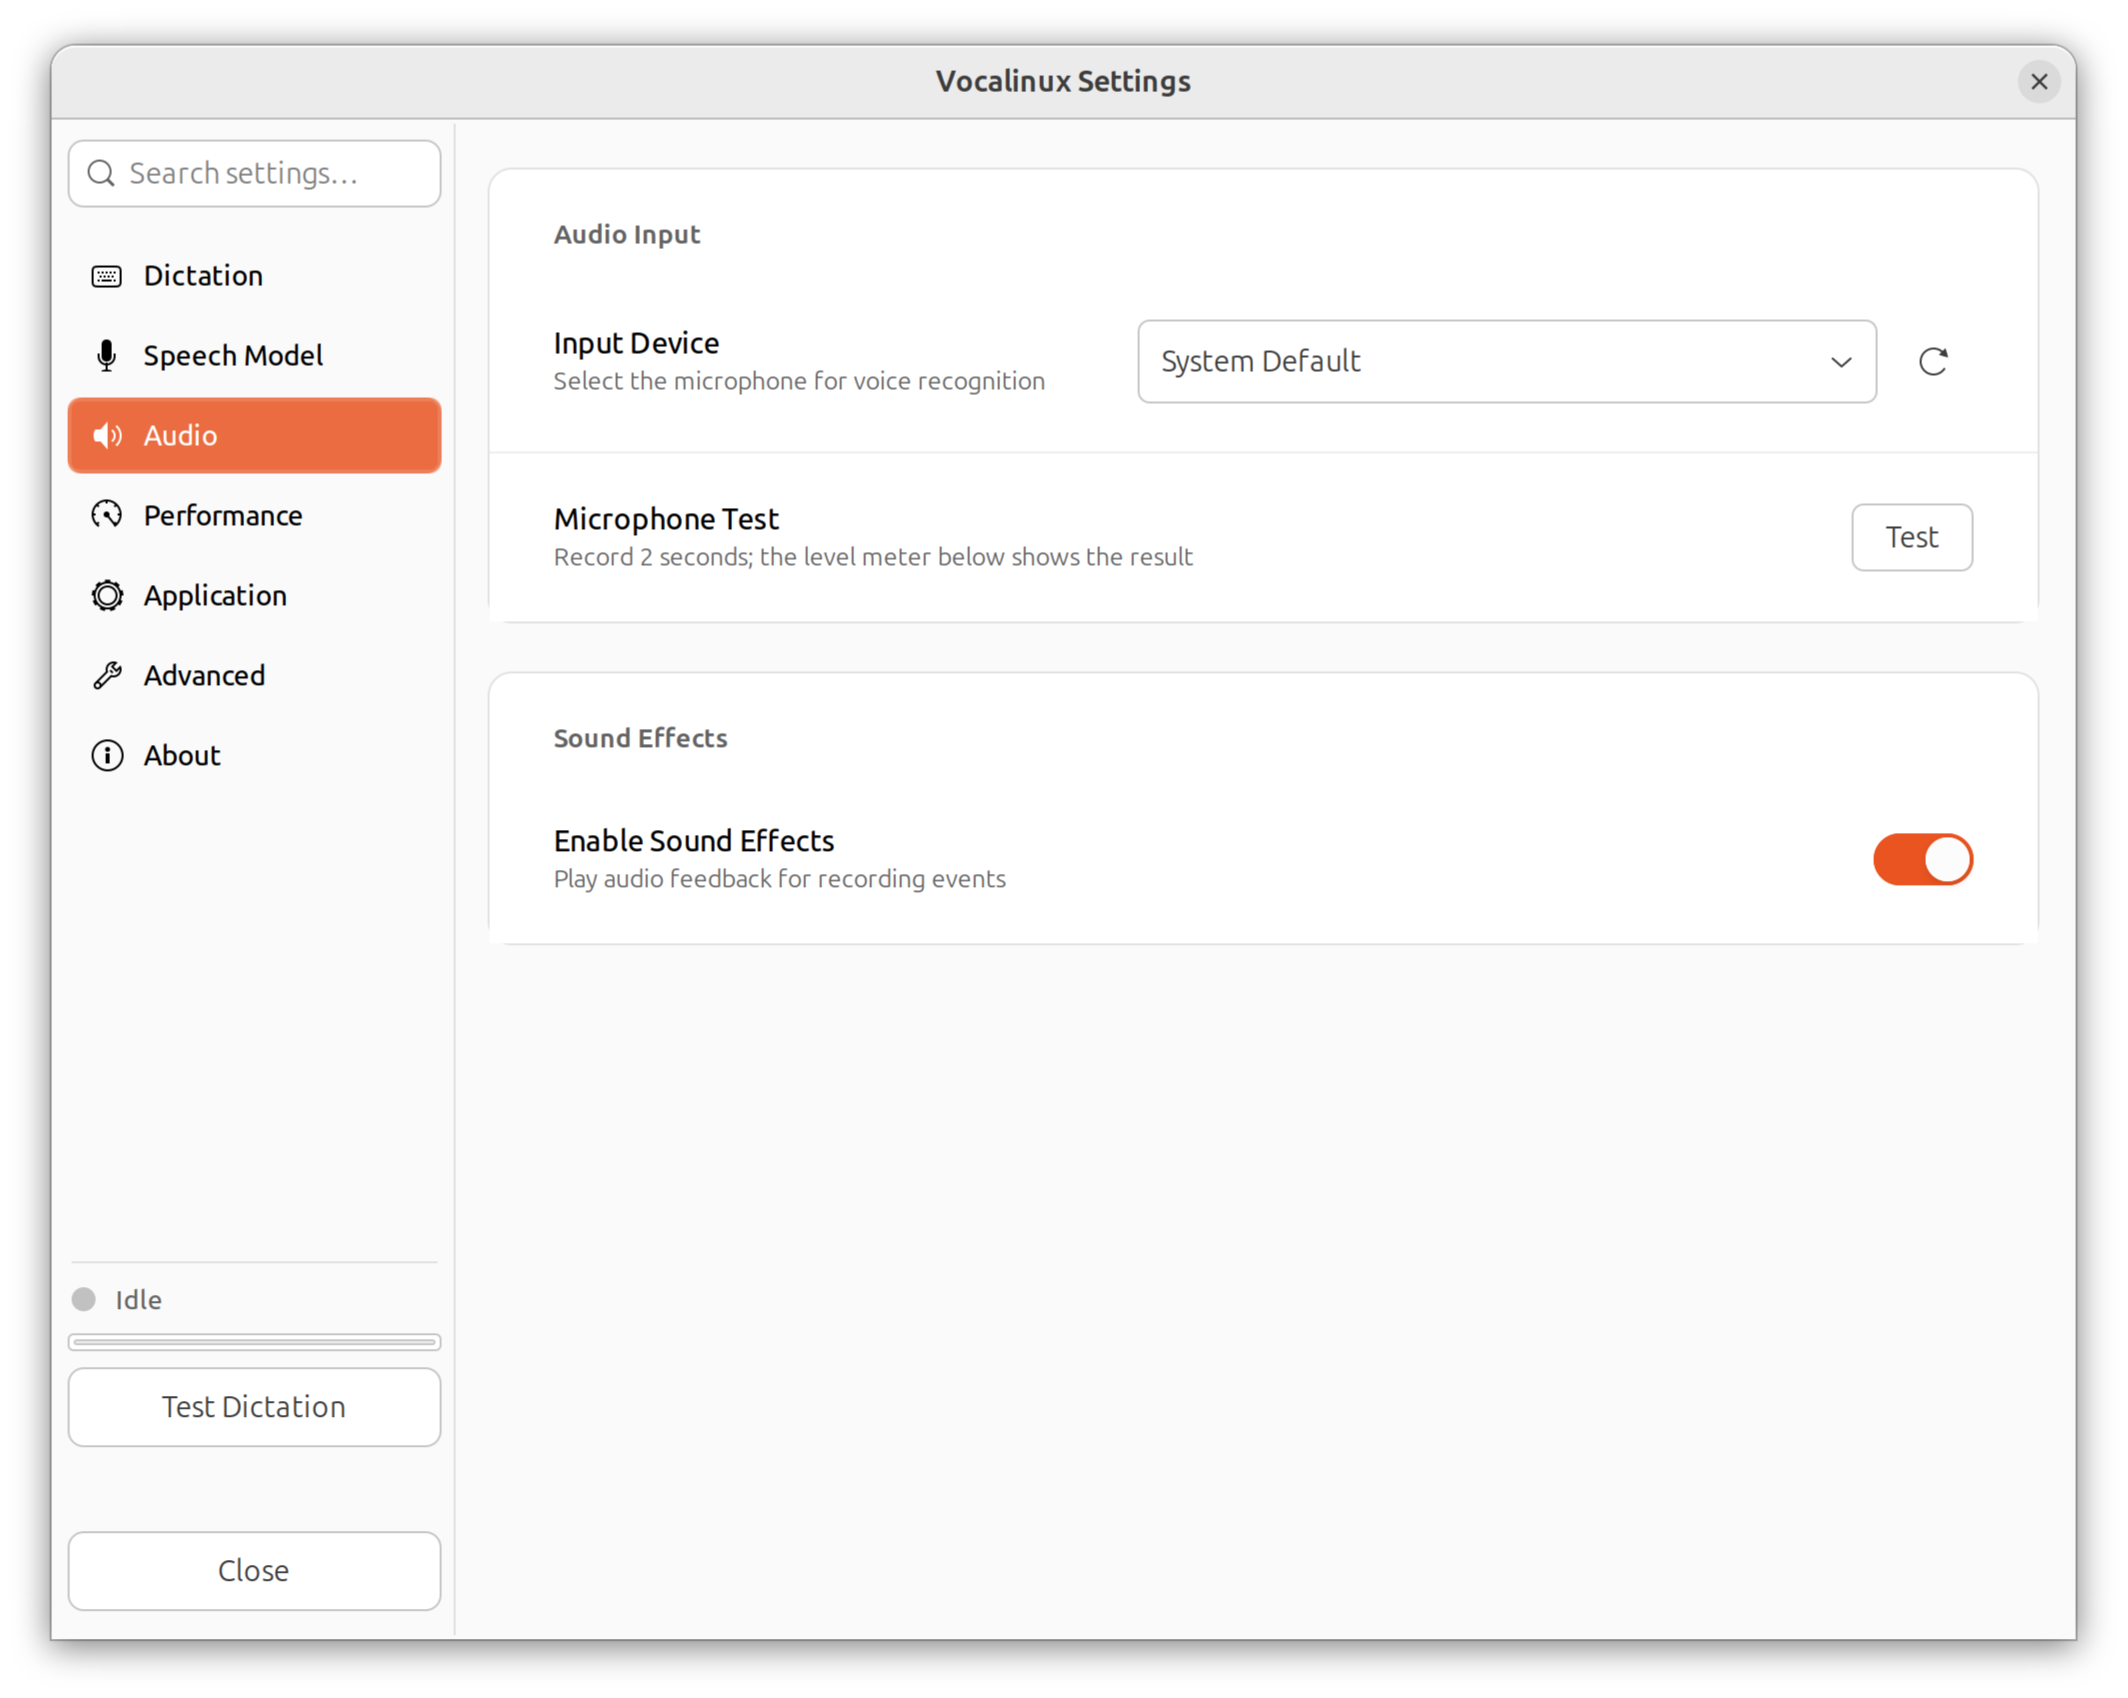
Audio settings
Audio
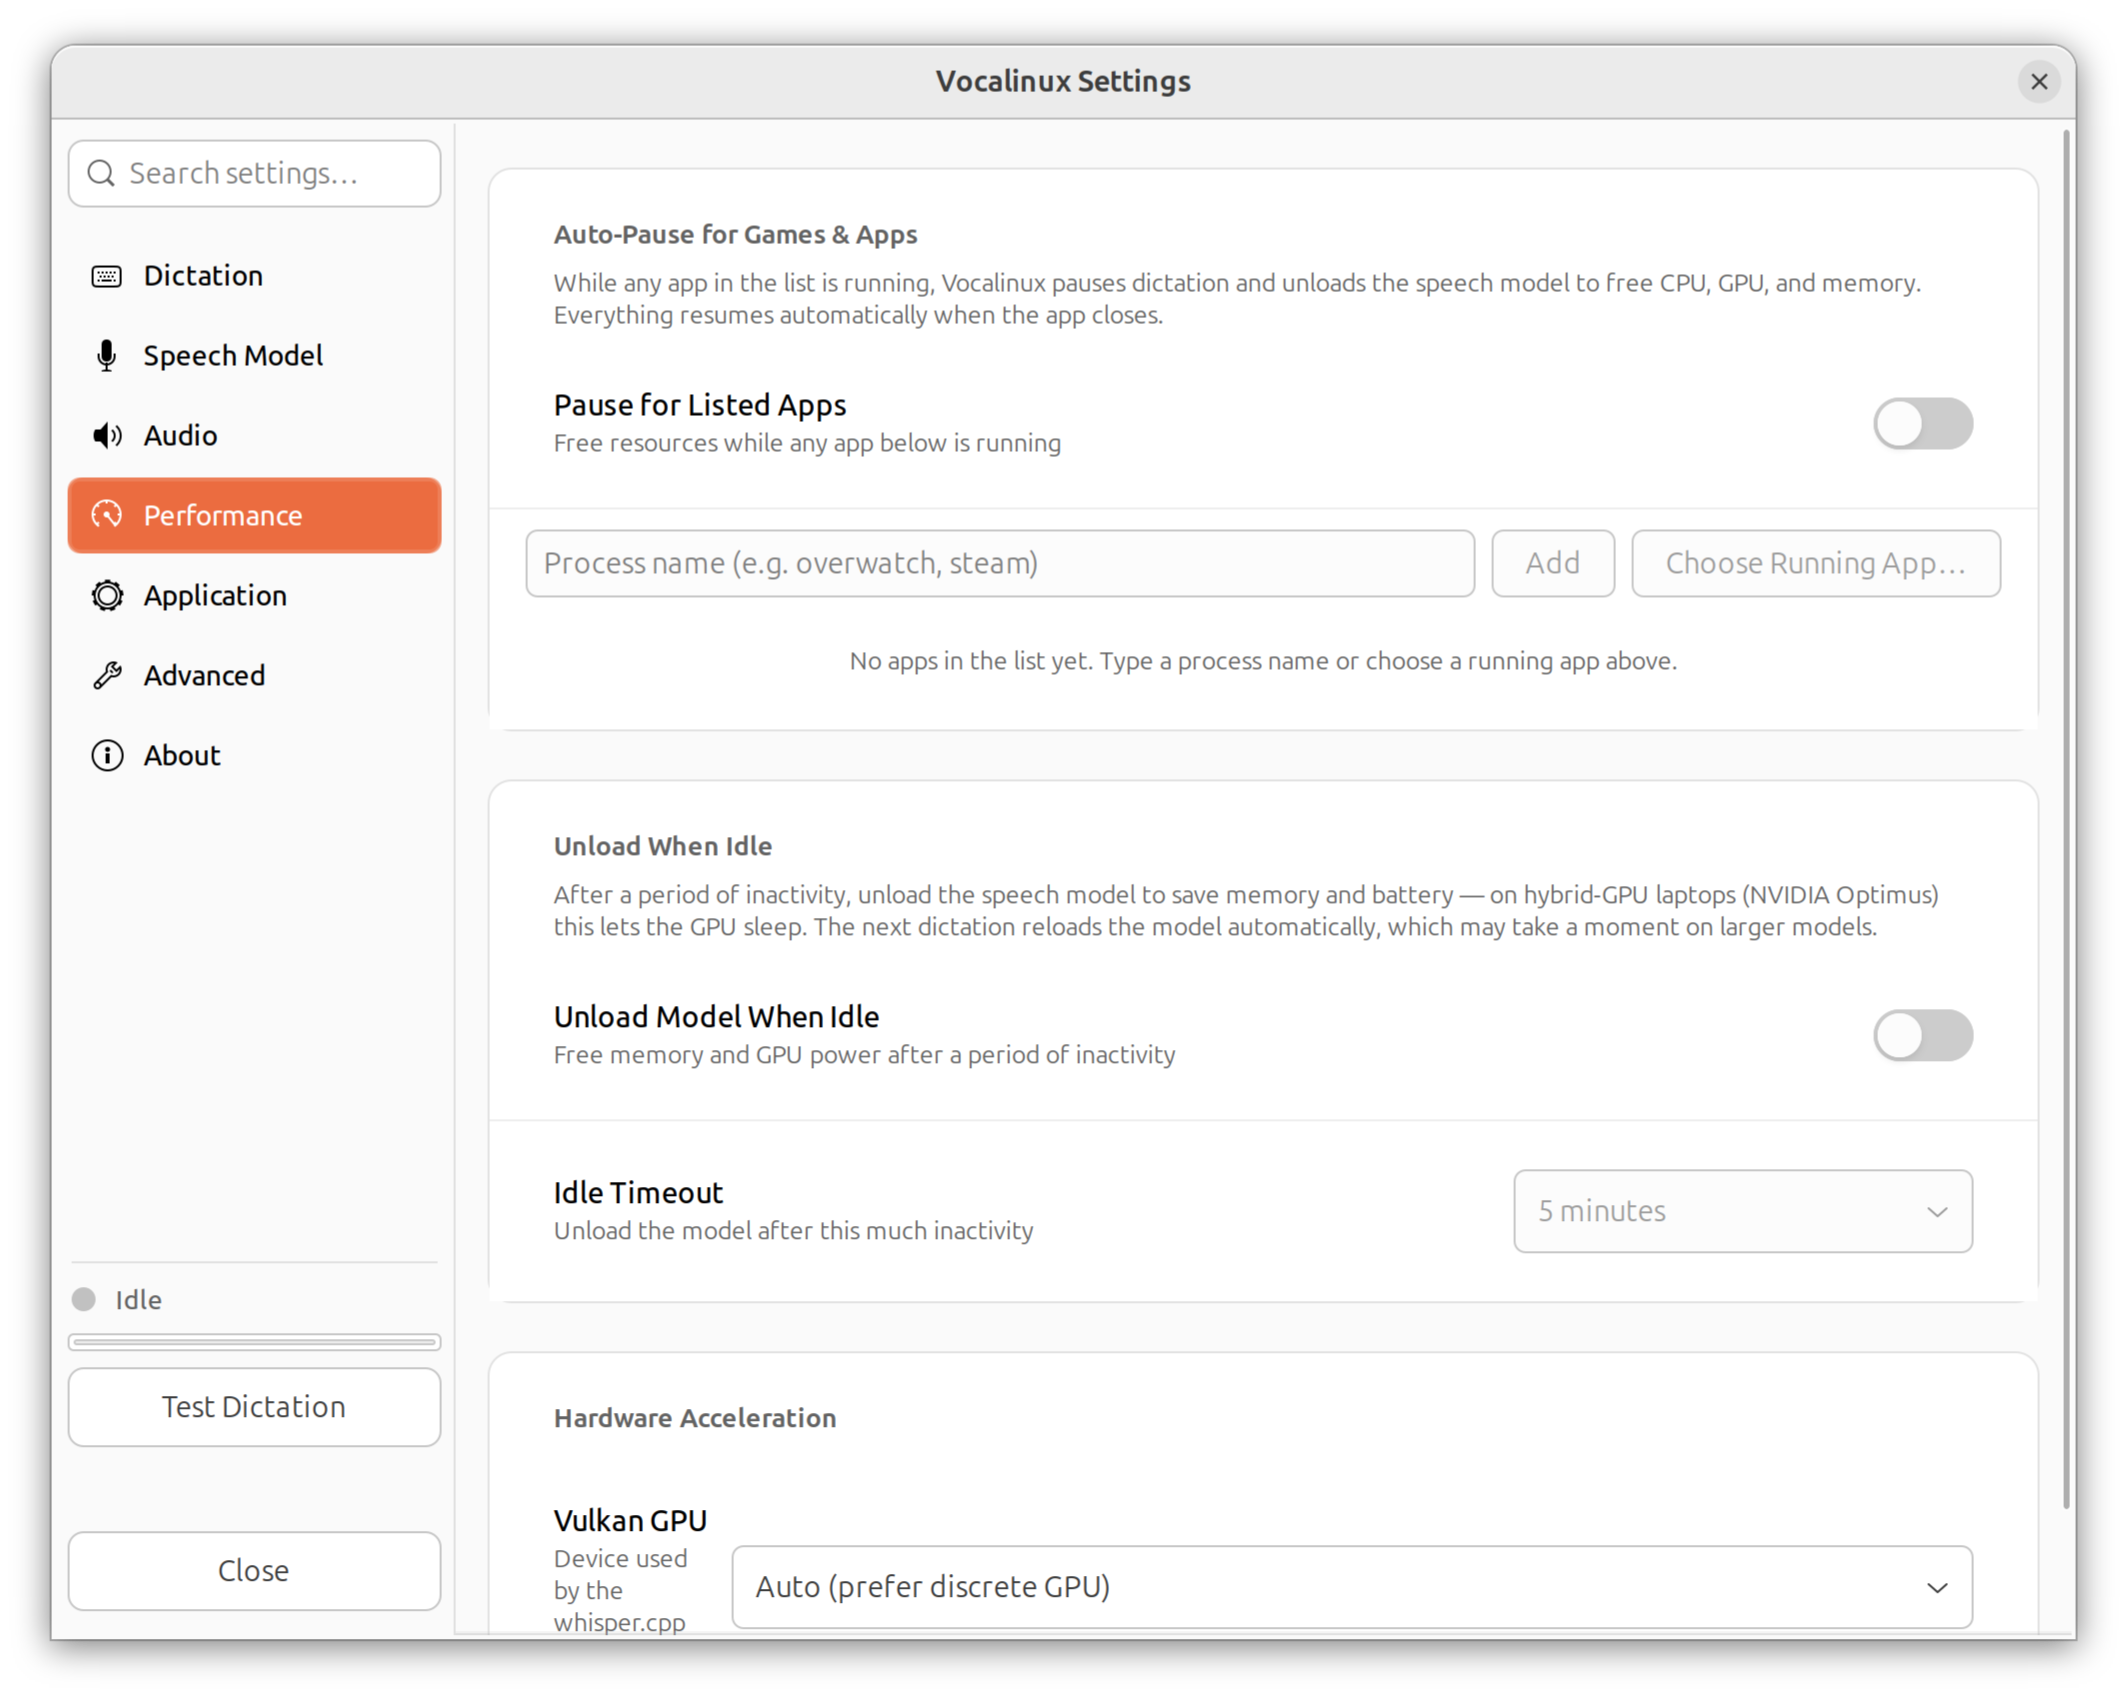
Performance settings
Performance
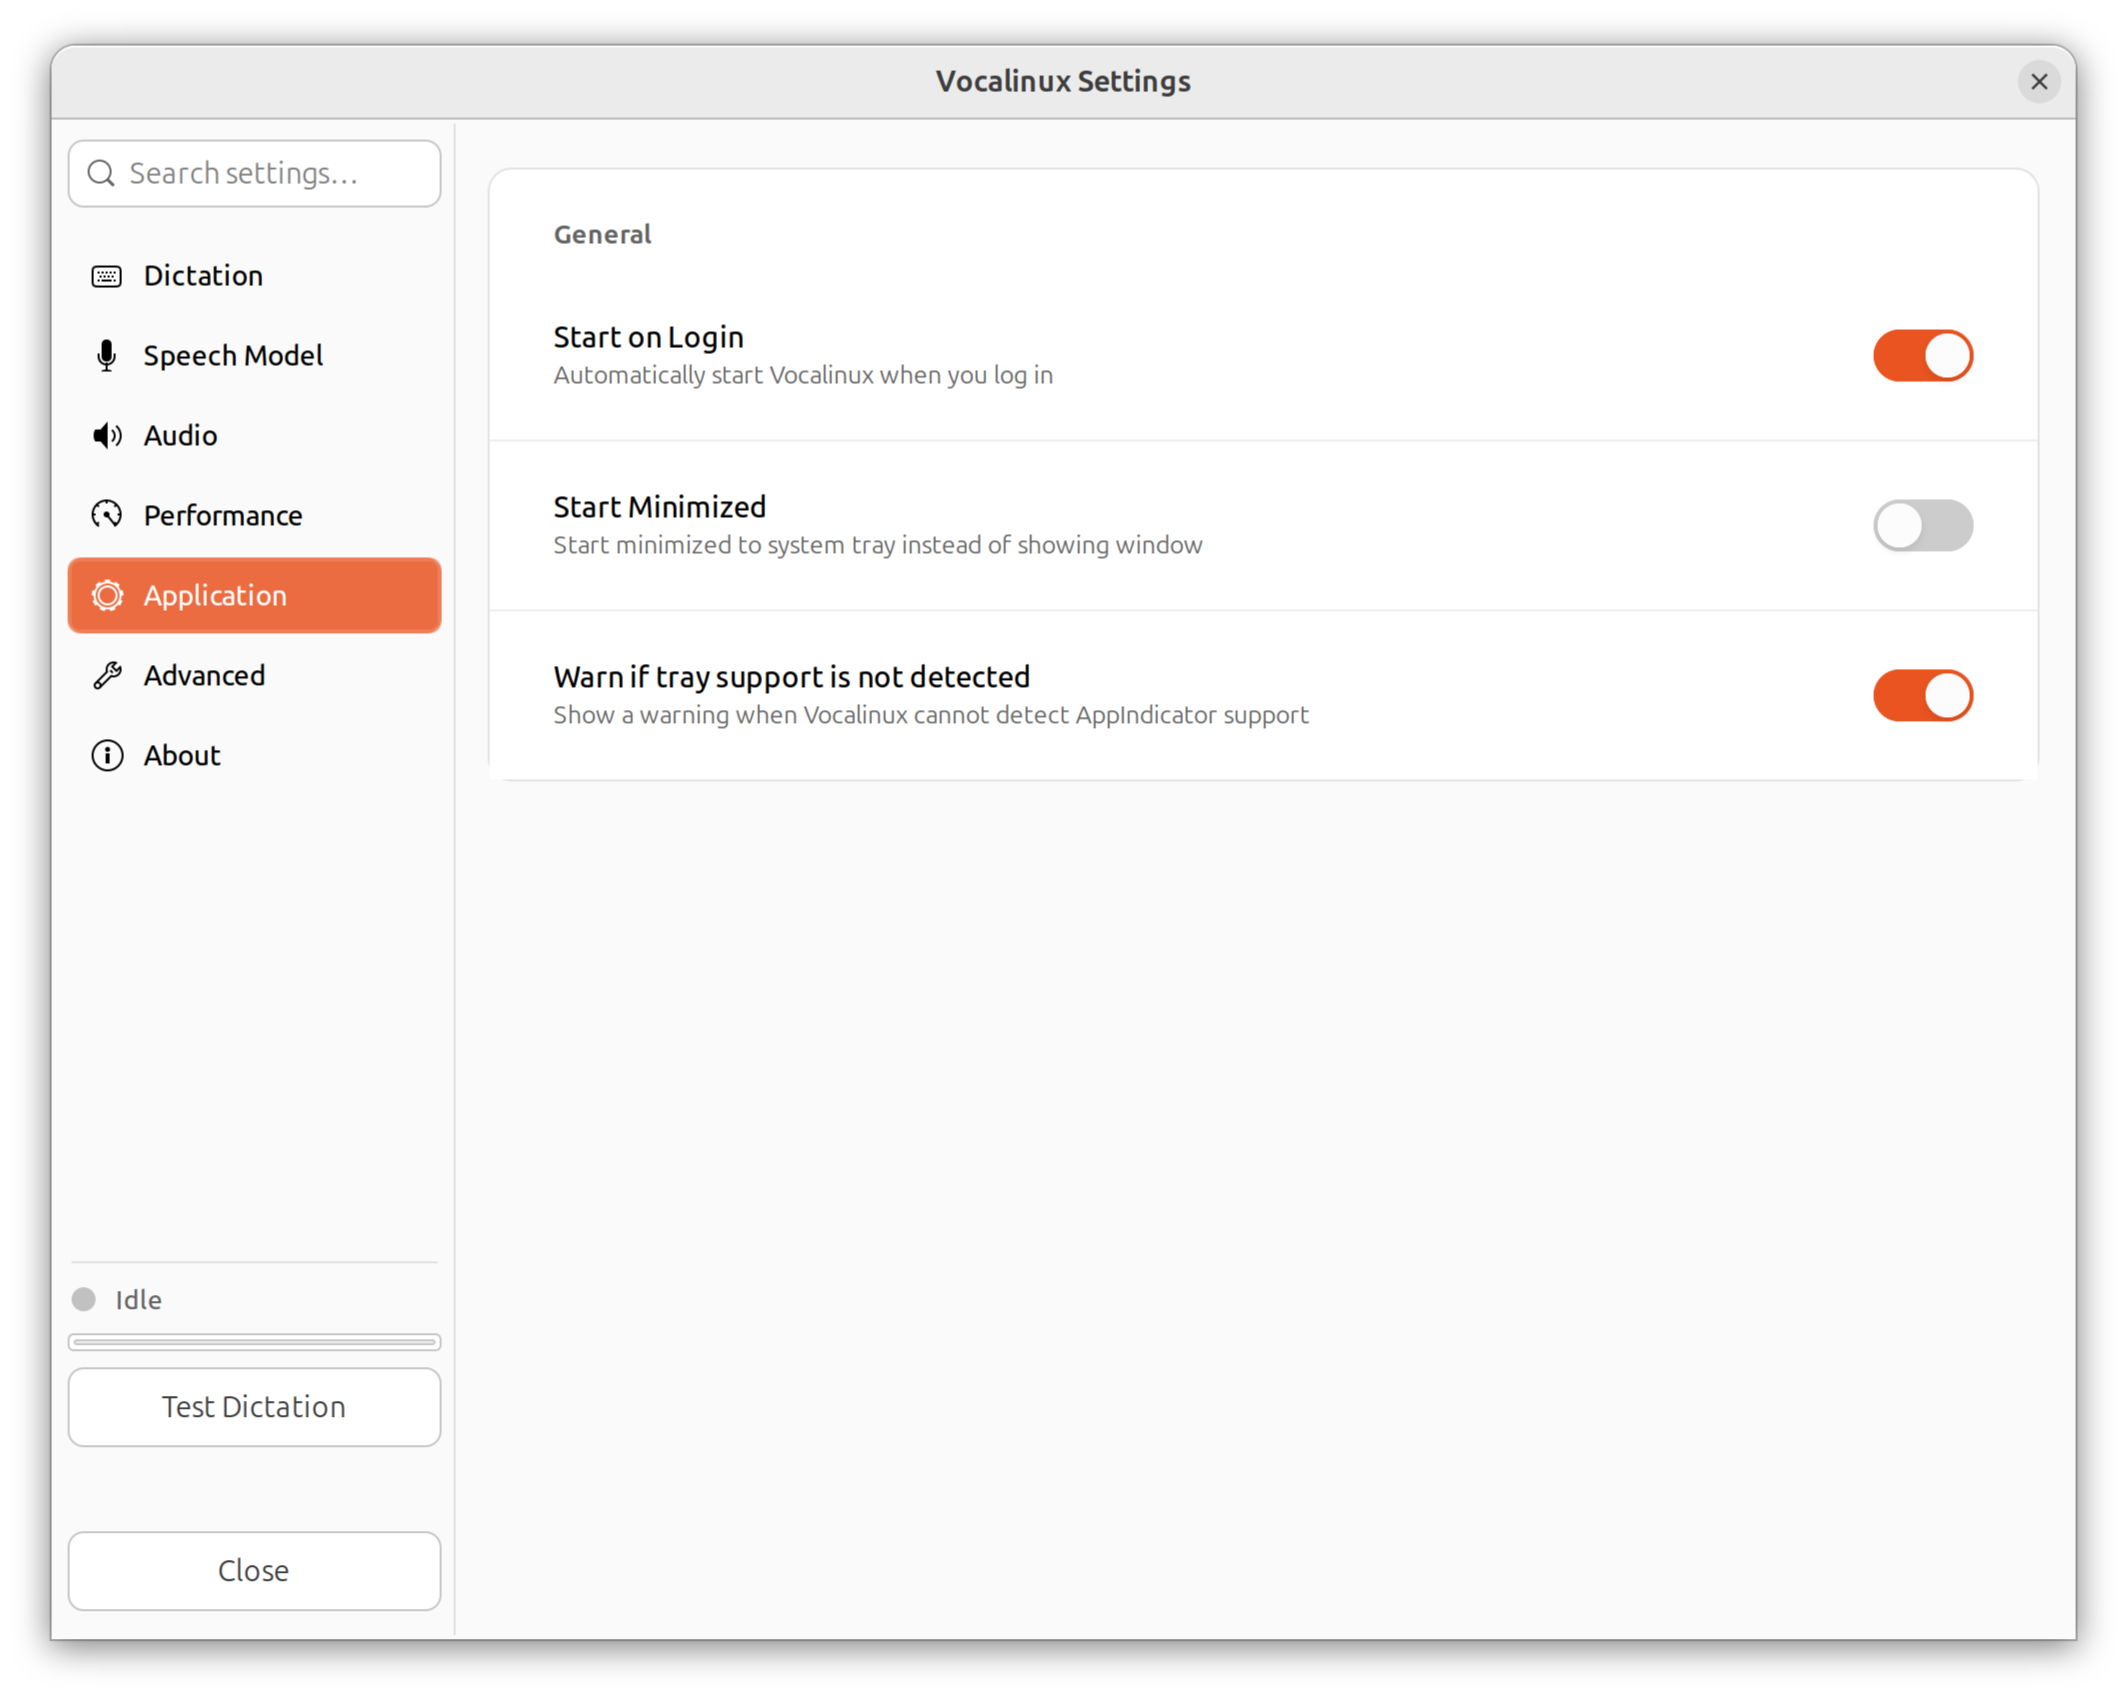
General settings
General
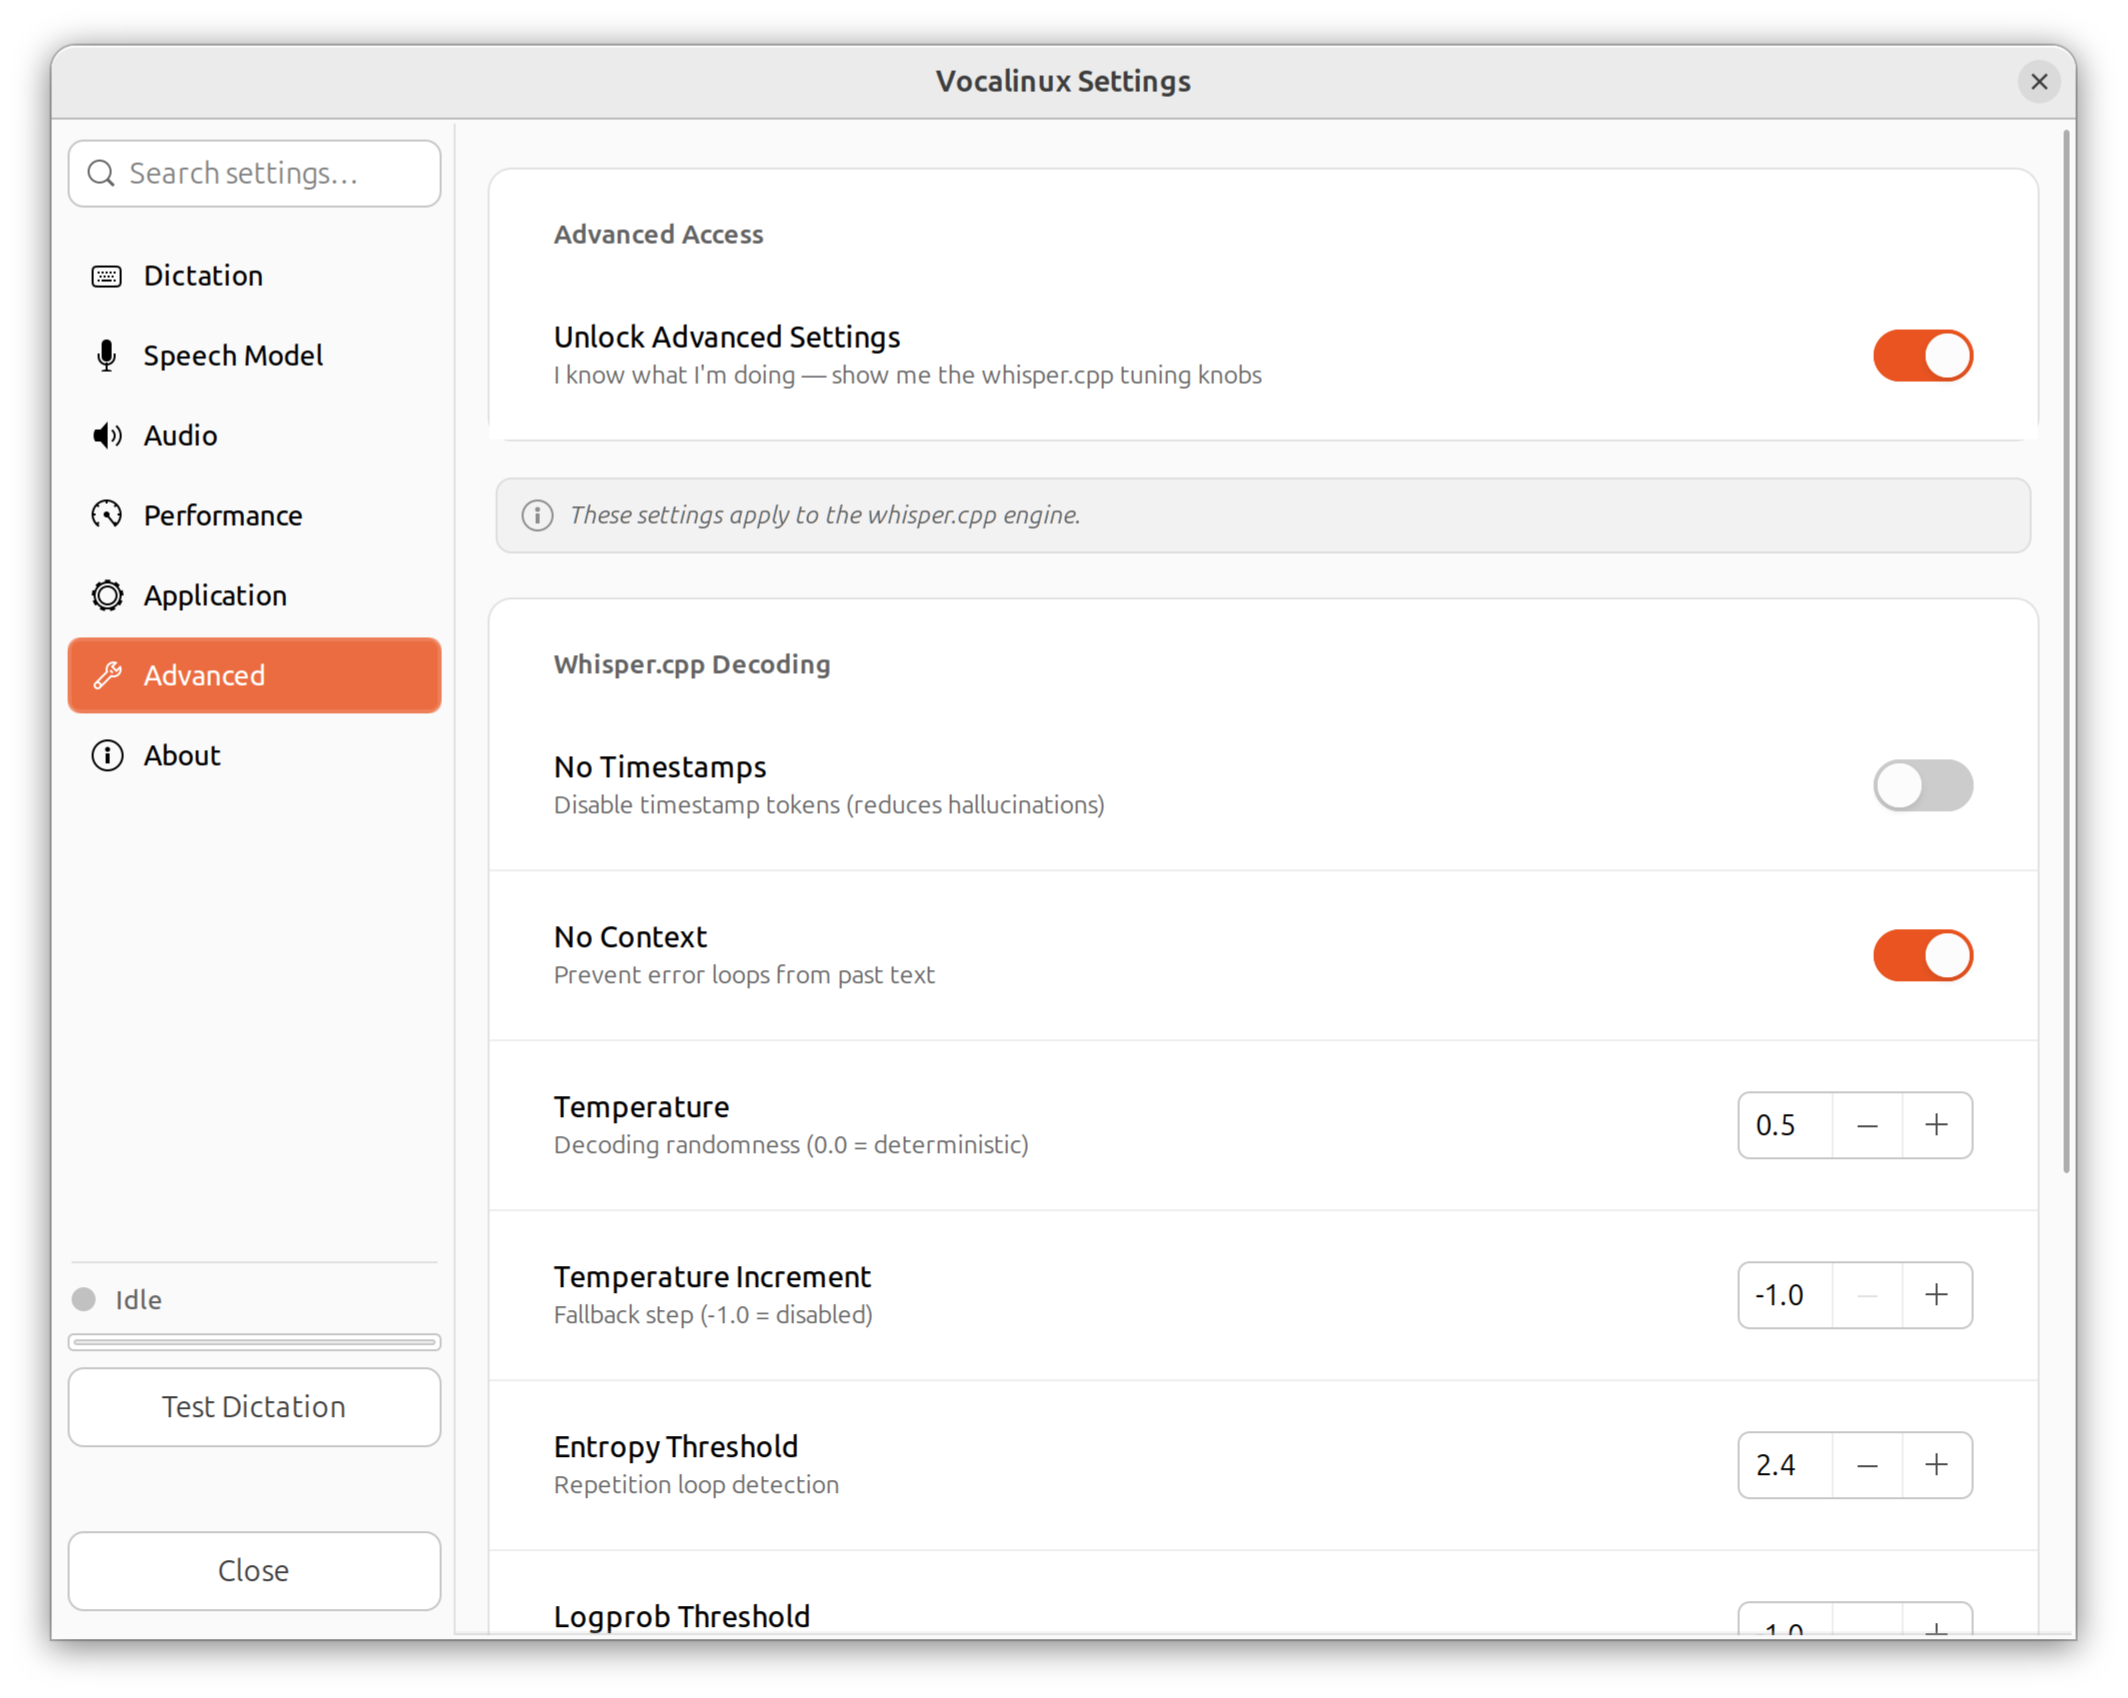
Advanced tuning and settings
Advanced
Dictation overlay listening
Floating overlay while listening (green)
Dictation overlay processing
Floating overlay while processing (amber)
## Install ### Recommended (interactive installer) ```bash curl -fsSL https://raw.githubusercontent.com/VocaHQ/vocalinux/main/install.sh -o /tmp/vl.sh bash /tmp/vl.sh ``` Prefer to review the script first: open `/tmp/vl.sh` before running it, or clone the repo and run `./install.sh` locally. The installer detects hardware, recommends an engine, downloads a default model (~74MB for whisper.cpp tiny), installs neural VAD when ONNX Runtime is available, and sets up desktop integration. Typical install time with whisper.cpp is about 1-2 minutes. | Engine | When to use | |--------|-------------| | **whisper.cpp** (default) | Best default; Vulkan GPU on AMD, Intel, and NVIDIA | | **Whisper** (OpenAI) | PyTorch path; NVIDIA/CUDA | | **Faster Whisper** | CPU-friendly Whisper via CTranslate2 / INT8 | | **VOSK** | Low RAM / minimal footprint | | **Parakeet** | CPU; NVIDIA NeMo ASR via sherpa-onnx; 25 European languages | | **Remote API** | Offload to a server you configure | Non-interactive options: ```bash bash /tmp/vl.sh --auto # whisper.cpp defaults bash /tmp/vl.sh --auto --engine=whisper # OpenAI Whisper bash /tmp/vl.sh --auto --engine=faster_whisper # Faster Whisper (CPU) bash /tmp/vl.sh --auto --engine=vosk # VOSK only bash /tmp/vl.sh --auto --engine=parakeet # Parakeet (CPU) ``` For a specific release tag, see [GitHub Releases](https://github.com/VocaHQ/vocalinux/releases) or `./install.sh --tag=v0.18.3`. ### Arch Linux (AUR) ```bash yay -S vocalinux ``` See [docs/AUR.md](docs/AUR.md). ### AppImage Download the `x86_64` or `aarch64` AppImage from [Releases](https://github.com/VocaHQ/vocalinux/releases), mark it executable, and run it. Built against glibc 2.35 (Debian 12+, Ubuntu 22.04+, Fedora 36+, Arch, Tumbleweed). Host text-injection tools (`xdotool` on X11; `wtype` / `ydotool` / clipboard tools on Wayland) are still required. Current AppImages rebuild whisper.cpp with Vulkan and use the host GPU driver. Prefer the installer when you want system deps, a CUDA build, and models set up automatically. ### Distro packages (.deb / .rpm) Download the `.deb` (Debian 12+, Ubuntu 24.04+) or `.rpm` (Fedora) matching your CPU from [Releases](https://github.com/VocaHQ/vocalinux/releases) and install with `sudo apt install ./vocalinux_*.deb` or `sudo dnf install ./vocalinux-*.rpm`. Thin packages: Python and GTK come from the distro. No auto-update; CPU whisper.cpp. Details in [docs/INSTALL.md](docs/INSTALL.md). ### Flatpak (any distro) Install and auto-update via the self-hosted VocaHQ remote (`flatpak update` picks up each release): ```bash flatpak install https://vocahq.github.io/vocalinux-flatpak/com.vocalinux.Vocalinux.flatpakref ``` The `.flatpakref` adds the `vocahq` remote and resolves the GNOME runtime through Flathub. Manually instead: ```bash flatpak remote-add --if-not-exists flathub https://dl.flathub.org/repo/flathub.flatpakrepo flatpak remote-add --if-not-exists vocahq https://vocahq.github.io/vocalinux-flatpak/vocahq.flatpakrepo flatpak install vocahq com.vocalinux.Vocalinux ``` Or sideload a GitHub Release bundle (`Vocalinux--x86_64.flatpak` or `-aarch64.flatpak`) after the Flathub GNOME runtime is present — bundles do not auto-update: ```bash flatpak install --user ./Vocalinux--x86_64.flatpak ``` Local build: ```bash flatpak install flathub org.gnome.Platform//50 org.gnome.Sdk//50 flatpak-builder --user --install --force-clean build-dir \ packaging/flatpak/com.vocalinux.Vocalinux.yml flatpak run com.vocalinux.Vocalinux ``` Ships whisper.cpp with Vulkan. It is **not on Flathub** (submission [flathub#9368](https://github.com/flathub/flathub/pull/9368) closed 2026-07-23 on policy grounds). Details: [packaging/flatpak/README.md](packaging/flatpak/README.md). ### Snap (Ubuntu Snap Store) Listing: [snapcraft.io/vocalinux](https://snapcraft.io/vocalinux). `stable` is promoted from `candidate` after QA. Tagged releases also attach `vocalinux__amd64.snap` on GitHub. ```bash sudo snap install vocalinux --edge sudo snap connect vocalinux:audio-record # if mic is not auto-connected sudo snap connect vocalinux:raw-input # global keyboard shortcuts (evdev) sudo snap connect vocalinux:hardware-observe # list keyboards (/proc/bus/input/devices) ``` Native Wayland typing uses the RemoteDesktop portal: the compositor asks once on first dictation, nothing to connect. The recipe ships **no `uinput` plug** and no ydotool; the Store denied the super-privileged grant, which held the 0.17.0+ revisions and left **v0.16.2 (rev 7)** on edge. On KDE Plasma, KWin's portal can mistype letter case ([KDE bug 489021](https://bugs.kde.org/show_bug.cgi?id=489021)); set Virtual Keyboard to "IBus Wayland" so dictation types correctly. GitHub `.snap` files through v0.18.2 declare `uinput`, so KDE users who want ydotool can sideload that build and connect the plug manually: ```bash sudo snap install --dangerous ./vocalinux_0.18.2_amd64.snap sudo snap connect vocalinux:uinput # only in the v0.18.x sideload; the recipe no longer ships it ``` ### Nix / NixOS (flake) ```bash nix run github:VocaHQ/vocalinux # try it nix profile install github:VocaHQ/vocalinux ``` The flake also ships `nixosModules.vocalinux` and `homeManagerModules.vocalinux` for declarative installs (`programs.vocalinux.enable = true`). The bundled pywhispercpp builds with Vulkan GPU inference. Details: [packaging/nix/README.md](packaging/nix/README.md). ### From source ```bash git clone https://github.com/VocaHQ/vocalinux.git cd vocalinux ./install.sh # or pick the engine up front ./install.sh --engine=whisper_cpp ./install.sh --engine=vosk ./install.sh --engine=parakeet --auto ``` ### After installation ```bash vocalinux # if ~/.local/bin is on PATH # or ~/.local/share/vocalinux/venv/bin/vocalinux ``` You can also launch Vocalinux from your application menu. ### Nightly builds Daily builds from `main` appear on [Releases](https://github.com/VocaHQ/vocalinux/releases). Use the latest stable or beta release for production; nightlies are untested. ## Requirements | | | |--|--| | **OS** | Linux (Ubuntu 24.04+, Debian 12+, Fedora 42+, Arch, openSUSE Tumbleweed) | | **Python** | 3.11 or newer | | **Display** | X11 or Wayland | | **Hardware** | Microphone; GPU optional (Vulkan) | The distro must ship Python 3.11+ because Vocalinux uses distro PyGObject (`python3-gi`). Ubuntu 22.04 (Python 3.10) and Debian 11 (3.9) are below that floor. Distribution notes: [docs/DISTRO_COMPATIBILITY.md](docs/DISTRO_COMPATIBILITY.md). ## Usage ### Dictation 1. **Push-to-talk (default on new installs):** hold Right Alt (Option on Mac-layout keyboards) and speak 2. Speak into the microphone 3. **Release** to stop, or switch to **Toggle mode** in Settings (double-tap a key to start/stop) Existing configs keep their saved shortcut. ### Voice commands English phrases always work. With a non-English recognition language, matching punctuation / line-break phrases in that language are also recognized (Italian *virgola* / *punto*, French *virgule* / *point*, etc.). | Command | Action | |---------|--------| | "new line" | Line break | | "period" / "full stop" / "dot" | `.` | | "comma" | `,` | | "question mark" | `?` | | "exclamation mark" | `!` | | "delete that" | Delete last sentence | | "capitalize" | Capitalize next word | ### CLI ```bash vocalinux --help vocalinux --version vocalinux --debug vocalinux --engine whisper_cpp # default vocalinux --engine whisper vocalinux --engine faster_whisper vocalinux --engine vosk vocalinux --engine parakeet vocalinux --engine remote_api vocalinux --model medium vocalinux --model medium.en-q5_0 # exact whisper.cpp variant vocalinux --model large-v3-turbo vocalinux --wayland vocalinux --start-minimized ``` ### Autostart **Start on Login** creates an XDG autostart desktop entry (`~/.config/autostart/`). It does not install a systemd unit. Enable from the first-run dialog, tray menu, or Settings. ### Configuration Stored at `~/.config/vocalinux/config.json`. Prefer the Settings dialog for day-to-day changes. **Settings → Speech Model** starts with a simple setup; expand **Advanced** for engine, size, and specialization. Set `post_processing.script_path` to an executable to transform each transcription result (stdin → stdout) before it is injected; leave empty to disable. Neural VAD (Silero) is used when `onnxruntime` is available; install via `pip install "vocalinux[vad]"` for manual/PyPI installs. The installer attempts this automatically. ## Documentation | Document | Description | |----------|-------------| | [Installation](docs/INSTALL.md) | Installer, AppImage, AUR, Flatpak, Snap, Nix flake, running | | [Manual / PyPI install](docs/INSTALL_MANUAL.md) | Package lists and pip workflows | | [Troubleshooting](docs/TROUBLESHOOTING.md) | Common failures | | [User guide](docs/USER_GUIDE.md) | Dictation, engines, models, tips | | [Update guide](docs/UPDATE.md) | Upgrade steps and release notes | | [Changelog](CHANGELOG.md) | Release history pointers | | [Support](SUPPORT.md) | Where to get help | | [Distribution compatibility](docs/DISTRO_COMPATIBILITY.md) | Distro matrix and session notes | | [Remote HTTP API](docs/HTTP_REMOTE.md) | Offload transcription to a server | | [Local VocaGateway (optional)](docs/GATEWAY_EMBED.md) | Start a local gateway from Settings; not on-device | | [Contributing](CONTRIBUTING.md) | Dev setup, style, PR process | | [Security](SECURITY.md) | Supported versions and vulnerability reporting | | [Docs index](docs/README.md) | Full documentation map | ## Privacy and security - Local engines process audio on-device after you download a model; no Voca account required - Optional remote API is off by default and only used when you configure a server - Model downloads are checked against pinned checksums Report vulnerabilities privately per [SECURITY.md](SECURITY.md). ## Development ```bash git clone https://github.com/VocaHQ/vocalinux.git cd vocalinux ./install.sh --dev source venv/bin/activate pytest python -m vocalinux.main --debug ``` See [CONTRIBUTING.md](CONTRIBUTING.md) for the two-venv layout, `just` recipes, and PR guidelines. ## Roadmap Shipped: graphical settings, multi-language support, whisper.cpp default, Vulkan GPU, Wayland/IBus, Flatpak packaging, AppImage, `.deb` / `.rpm` packages, in-app update checker, Parakeet and Faster Whisper engines, Snap recipe. Planned: - [ ] Application-specific voice commands - [ ] User-customizable voice command map - [ ] Flathub publication (not currently listed; see #167) ## Voca ecosystem Vocalinux is part of [VocaHQ](https://vocahq.com). On-device speech-to-text first, one app per platform. Optional [VocaGateway](https://vocagateway.vocahq.com) is self-hosted and not on-device. | Platform | Project | Website | GitHub | |----------|---------|---------|--------| | Linux | **VocaLinux** | [vocalinux.com](https://vocalinux.com) | [VocaHQ/vocalinux](https://github.com/VocaHQ/vocalinux) | | macOS | **VocaMac** | [vocamac.com](https://vocamac.com) | [VocaHQ/vocamac](https://github.com/VocaHQ/vocamac) | | Windows | **VocaWin** | [vocawin.com](https://vocawin.com) | [VocaHQ/vocawin](https://github.com/VocaHQ/vocawin) | | Phone | **VocaPhone** | [vocaphone.vocahq.com](https://vocaphone.vocahq.com) | [VocaHQ/vocaphone](https://github.com/VocaHQ/vocaphone) | | Gateway | **VocaGateway** | [vocagateway.vocahq.com](https://vocagateway.vocahq.com) | [VocaHQ/vocagateway](https://github.com/VocaHQ/vocagateway) | Talk to us: [Discord](https://discord.gg/t6muquAJbm) · [X @vocahq](https://x.com/vocahq) · [hello@vocahq.com](mailto:hello@vocahq.com) ## Contributing Bug reports, docs, and code are welcome. Start with [CONTRIBUTING.md](CONTRIBUTING.md) and [good first issues](https://github.com/VocaHQ/vocalinux/issues?q=is%3Aissue+is%3Aopen+label%3A%22good+first+issue%22). - [Report a bug](https://github.com/VocaHQ/vocalinux/issues/new?template=bug_report.md) - [Request a feature](https://github.com/VocaHQ/vocalinux/issues/new?template=feature_request.md) - [Discussions](https://github.com/VocaHQ/vocalinux/discussions) ### Contributors Thanks to everyone who has contributed code, docs, or fixes: Vocalinux contributors ## Repository mirrors GitHub is the primary forge for issues, PRs, CI, and releases. | Role | URL | |------|-----| | Primary | https://github.com/VocaHQ/vocalinux | | Read-only mirror (Codeberg) | https://codeberg.org/jatinkrmalik/vocalinux | Open issues and pull requests on GitHub only. ## License This project is licensed under the **GNU Affero General Public License v3.0** ([AGPL-3.0](LICENSE)), aligning with the other [VocaHQ](https://github.com/VocaHQ) distribution projects. You may use, study, modify, and redistribute the software under AGPL-3.0. If you run a modified version as a network service, AGPL also requires that you make the corresponding source available. ## Star Chart [![Star History Chart](https://api.star-history.com/chart?repos=VocaHQ/vocalinux&type=date&legend=top-left&sealed_token=ZWyQQLhSORoR4mKf6UXMGFSCBXRxM_yEZgc8MFCH_ysBjaFUm_OCH-bI3TD7OivczEzm-ADRIpF9xCWFOMHvBPW95eQBxzfRMpNksChz7rN_eiqL7AIMDw)](https://www.star-history.com/?type=date&repos=VocaHQ%2Fvocalinux) ### Optional Orukeet model With the Parakeet engine installed, Settings → Speech Model → Parakeet also offers `orukeet-v0.1.0`. It uses the existing local sherpa-onnx recognizer for 25 European languages; the recommended Parakeet model and default whisper.cpp engine stay unchanged. The download comes from a pinned revision of [oruk/orukeet on Hugging Face](https://huggingface.co/oruk/orukeet). Vocalinux checks every file against its bundled SHA-256 pins and checks the publisher's release manifest against those same pins. The manifest download participates in Hugging Face's normal model-download accounting. Cached recognition works offline and does not send audio or usage events. The model occupies about 641 MiB; its CC BY-SA 4.0 weights license and NVIDIA attribution are included.