Spark-X2.5
[](https://join.slack.com/t/tokenspark/shared_invite/zt-432qf8l2f-5~dLyXv8uETr0P0UuC07nw)
[](https://discord.gg/kTDE2Hg8aw)
[](https://www.youtube.com/@SparkLLM)
[](https://dev.to/sparkllm)
[](https://bsky.app/profile/sparkllm.bsky.social)
[](https://x.com/sparkllm)
[](https://www.zhihu.com/people/zhiikz7qh7m)
[](https://github.com/XHToken/community/blob/main/docs/images/xhtoken-wechat.jpg)
Welcome to the GitHub repository of Spark-X2.5 open model series. You can find official information about Spark-X2.5, and post your questions [here(Issues)](https://github.com/XHToken/Spark-X2.5/issues).
## Introduction
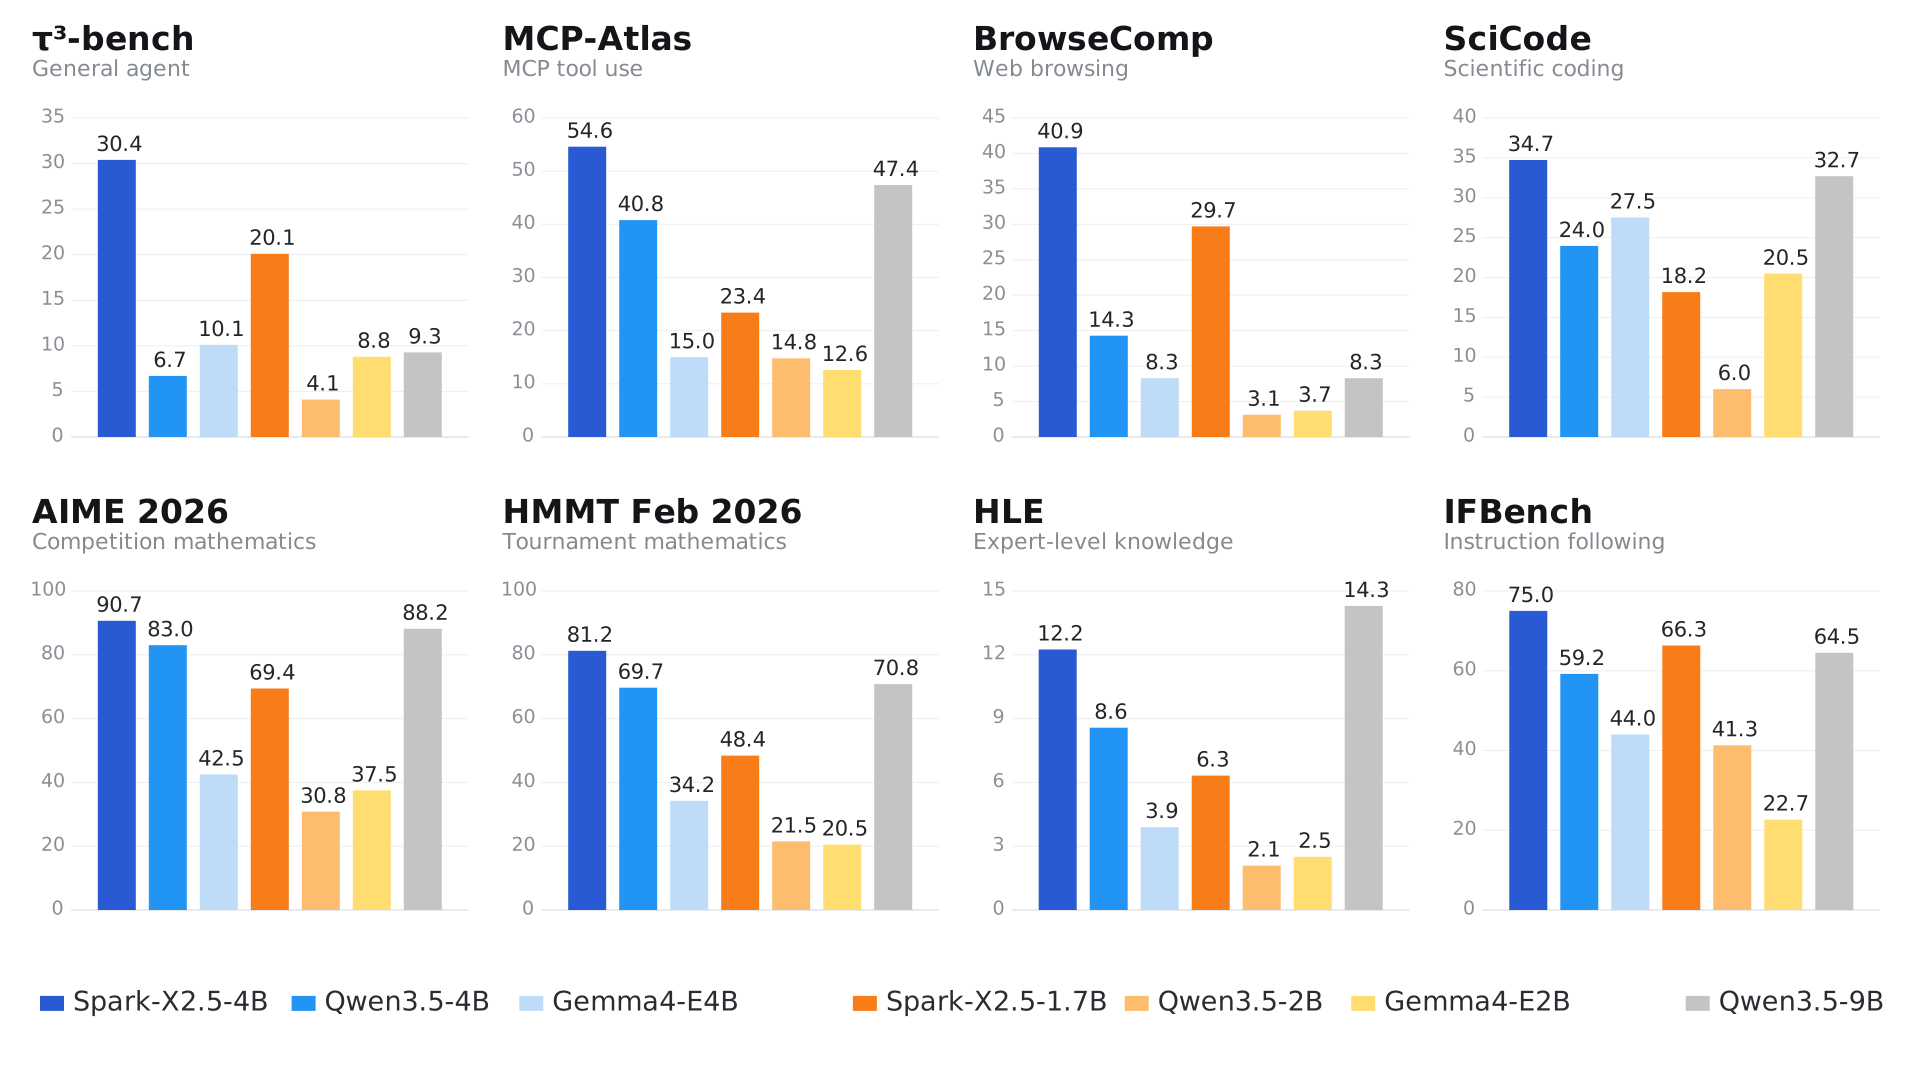
Today, we are introducing Spark-X2.5-4B and Spark-X2.5-1.7B, two compact, general-purpose language models designed to make capable AI more practical, efficient, and accessible. The models deliver strong performance across a broad range of everyday tasks—including conversation, writing, translation, reasoning, coding, tool use, and agentic workflows—achieving leading results among open-source models of comparable size. Spark-X2.5 combines an efficiency-oriented architecture with native context windows of up to 1M tokens, and support for more than 200 languages.
**Technical Highlights**:
- **Efficient Architecture and Native 1M-token Context**: The models use a hybrid attention architecture that combines one full-attention layer with three sliding-window attention layers. This design substantially reduces the computational overhead typically associated with long-context models while natively supporting a context window of up to 1M tokens.
- **Strong Coding and Agent Capabilities**: The models are deeply integrated with popular agent harnesses, including Codex, Claude Code, OpenClaw, and Hermes. They deliver state-of-the-art performance among models of comparable size across everyday coding, agentic workflows, reasoning, and instruction-following tasks.
- **Broad Hardware and Software Compatibility**: The models support a wide range of hardware platforms, including NVIDIA, Huawei, Hygon, HOUMO.AI, etc. It is compatible with leading inference frameworks such as vLLM, SGLang, llama.cpp, MLX, and can be deployed quickly through platforms including Ollama and LM Studio. The models can also be customized using popular fine-tuning frameworks such as LLaMA-Factory. Across multiple hardware platforms, they deliver superior TTFT, TOPT, and overall inference efficiency compared with similarly sized models.
- **Advanced Training Algorithms**: The models were trained on Huawei Ascend clusters. Large-scale reinforcement learning and post-training techniques such as MOPD significantly enhance its reasoning, coding, agentic, and instruction-following capabilities.
## Release
- [2026/09/04] 🚀 Released FP8 and INT8 quantized versions of Spark-X2.5-4B and Spark-X2.5-1.7B.
- [2026/09/03] 🤝 Added deployment support for vLLM and SGLang on Ascend NPU.
- [2026/09/02] 🚀 Added [AtomGit](https://ai.atomgit.com/collections/2095030878254981121) as a new distribution channel.
- [2026/09/01] 🚀 Global launch of the Spark-X2.5 model series on [Hugging Face](https://huggingface.co/collections/XHToken/spark-x25), [ModelScope](https://www.modelscope.cn/collections/XHToken/Spark-X25), [Ollama](https://ollama.com/SparkLLM), [Modelers](https://modelers.cn/user/XHToken), and [SCNet](https://www.scnet.cn/ui/aihub/models/XHToken/Spark-X2.5-4B).
## Model Downloads
The Spark-X2.5-4B and Spark-X2.5-1.7B are available on the following platforms. Choose the most suitable download source for your region and environment:
| Platform | Download | Description |
| --- | --- | --- |
| Hugging Face | [Spark-X2.5 in Huggingface](https://huggingface.co/collections/XHToken/spark-x25) | Official Hugging Face model collection for Spark-X2.5 |
| ModelScope | [Spark-X2.5 in ModelScope](https://www.modelscope.cn/collections/XHToken/Spark-X25) | Recommended download source for users in China |
| Modelers | [Spark-X2.5 in Modelers](https://modelers.cn/user/XHToken) | Recommended download source for users with Ascend chips |
| Ollama | [Spark-X2.5 in Ollama](https://ollama.com/SparkLLM) | Download and run the model locally with Ollama |
| SCNet | [Spark-X2.5 in SCNet](https://www.scnet.cn/ui/aihub/models/XHToken/Spark-X2.5-4B) | Recommended download source for users with Hygon chips |
| AtomGit | [Spark-X2.5 in AtomGit](https://ai.atomgit.com/collections/2095030878254981121) | Recommended download source for users in China |
> If Hugging Face is slow or unavailable in your region, try ModelScope, Modelers, SCNet or AtomGit instead.
## Benchmarks
| Benchmark |
Spark‑X2.5‑4B |
Spark‑X2.5‑1.7B |
Qwen3.5‑9B |
Qwen3.5‑4B |
Qwen3.5‑2B |
Gemma4‑12B |
Gemma4‑E4B |
Gemma4‑E2B |
| Agent |
|---|
| BFCL‑V4 | 65.1 | 46.9 | 66.1* | 50.3* | 43.6* | 37.4 | 36.9 | 30.2 |
| τ²‑bench | 75.1 | 65.3 | 79.1* | 79.9* | 48.8* | 69.0* | 42.2* | 24.5* |
| τ³‑bench | 30.4 | 20.1 | 9.3 | 6.7 | 4.1 | 13.3 | 10.1 | 8.8 |
| MCP‑Atlas | 54.6 | 23.4 | 47.4* | 40.8* | 14.8 | 30.5* | 15.0* | 12.6 |
| MCP‑Mark | 14.2 | 2.3 | 13.4 | 12.5 | – | – | – | – |
| Workspace Bench | 31.2 | 18.9 | 25.5 | 21.3 | 7.7 | – | – | – |
| VitaBench2.0 | 25.2 | 8.3 | 15.6 | 18.2 | 5.2 | 12.4 | 4.8 | 4.4 |
| BrowseComp | 40.9 | 29.7 | 8.3 | 14.3 | 3.1 | 10.0 | 8.3 | 3.7 |
| Code |
|---|
| SWE‑Bench Pro | 44.4 | 10.4 | 33.8* | 29.4* | 1.9 | 21.9* | 4.0* | – |
| SWE‑Bench Verified | 41.6 | 28.3 | 53.1* | 38.8* | 6.8 | 44.2* | 14.0* | – |
| SWE‑Bench Multilingual | 53.3 | 23.3 | 43.3 | 27.7 | 5.0 | 32.5* | – | – |
| SciCode | 34.7 | 18.2 | 32.7* | 24.0 | 6.0 | 39.8 | 27.5 | 20.5 |
| Math |
|---|
| Gaokao 2026 | 133.4 | 114.8 | 135.5 | 130.3 | 94.0 | 130.6 | 102.4 | 81.8 |
| AIME 2026 | 90.7 | 69.4 | 88.2 | 83.0 | 30.8 | 82.1* | 42.5* | 37.5* |
| HMMT Feb 2026 | 81.2 | 48.4 | 70.8 | 69.7 | 21.5 | 65.6 | 34.2 | 20.5 |
| IMO‑AnswerBench | 74.2 | 45.4 | 69.8 | 68.5 | – | 57.2 | 26.9 | 22.6 |
| General & Knowledge |
|---|
| IFEval | 93.0 | 89.5 | 91.5* | 89.8* | 78.6* | 94.8 | 45.3 | 34.8 |
| IFBench | 75.0 | 66.3 | 64.5 | 59.2 | 41.3* | 73.5* | 44.0* | 22.7 |
| AA‑LCR | 56.3 | 24.3 | 63.0* | 57.0* | 25.6* | 55.3* | 34.7 | 18.3 |
| HLE | 12.3 | 6.3 | 14.3 | 8.6 | 2.1 | 13.1 | 3.9 | 2.5 |
| GPQA | 67.4 | 43.8 | 77.2 | 67.2 | 44.6 | 72.8 | 54.5 | 43.8 |
> - \* denotes reported results from publicly‑released model cards / papers and - denotes scores not yet available.
> - All evaluations are conducted in thinking mode. The recommended sampling parameters for Spark-X2.5 are temperature=1.0, top_p=0.95, and top_k=-1.
> - Gaokao 2026 consists of the five 2026 Chinese GAOKAO examinations (National I,National II, Beijing, Shanghai, Tianjin), each graded out of 150 points.
## Quickstart
The examples below serve a local Spark-X2.5-4B checkpoint. Set `MODEL_PATH` to its absolute path before starting a container:
```bash
export MODEL_PATH=/absolute/path/to/Spark-X2.5-4B
```
### SGLang
#### Install SGLang
##### For NVIDIA GPUs:
Use the pre-built image that tracks the Spark-X2.5 runtime:
```bash
docker pull lmsysorg/sglang:nightly-dev-cu13-20260827-20621aa1
```
##### For Ascend NPUs:
```bash
# A3 daily build
export SGLANG_IMAGE=quay.io/ascend/sglang:main-cann9.0.0-a3
# A2 daily build (use this instead on A2 hardware)
export SGLANG_IMAGE=quay.io/ascend/sglang:main-cann9.0.0-910b
docker pull "$SGLANG_IMAGE"
```
#### Run Inference
The following commands start an OpenAI-compatible API server configured for a maximum context length of 1,048,576 tokens. This setting requires sufficient device memory; reduce `--context-length` when necessary.
#### Server
```bash
docker run --rm -it \
--gpus '"device=0"' \
--ipc=host \
-p 30000:30000 \
-v "$MODEL_PATH":/root/Spark-X2.5-4B:ro \
lmsysorg/sglang:nightly-dev-cu13-20260827-20621aa1 \
python -m sglang.launch_server \
--model-path /root/Spark-X2.5-4B \
--served-model-name spark2.5 \
--tool-call-parser spark25 \
--reasoning-parser qwen3 \
--tp-size 1 \
--mem-fraction-static 0.8 \
--context-length 1048576 \
--chat-template /root/Spark-X2.5-4B/chat_template.jinja \
--host 0.0.0.0 \
--port 30000
```
##### Ascend NPU:
```bash
docker run -it --rm -e ASCEND_USE_FIA=1 --network=host --ipc=host --shm-size=16g \
--device=/dev/davinci0 --device=/dev/davinci1 --device=/dev/davinci2 --device=/dev/davinci3 \
--device=/dev/davinci4 --device=/dev/davinci5 --device=/dev/davinci6 --device=/dev/davinci7 \
--device=/dev/davinci8 --device=/dev/davinci9 --device=/dev/davinci10 --device=/dev/davinci11 \
--device=/dev/davinci12 --device=/dev/davinci13 --device=/dev/davinci14 --device=/dev/davinci15 \
--device=/dev/davinci_manager \
--device=/dev/devmm_svm \
--device=/dev/hisi_hdc \
--volume /usr/local/sbin:/usr/local/sbin \
--volume /usr/local/Ascend/driver:/usr/local/Ascend/driver \
--volume /usr/local/Ascend/firmware:/usr/local/Ascend/firmware \
--volume /etc/ascend_install.info:/etc/ascend_install.info \
--volume /var/queue_schedule:/var/queue_schedule \
--volume ~/.cache/:/root/.cache/ \
--volume "$MODEL_PATH:/root/Spark-X2.5-4B:ro" \
--entrypoint=python \
"$SGLANG_IMAGE" \
-m sglang.launch_server \
--model-path /root/Spark-X2.5-4B \
--served-model-name spark2.5 \
--tool-call-parser spark25 \
--reasoning-parser qwen3 \
--tp-size 1 \
--mem-fraction-static 0.8 \
--context-length 1048576 \
--chat-template /root/Spark-X2.5-4B/chat_template.jinja \
--host 0.0.0.0 \
--port 30000
```
#### Client
Thinking is enabled by default by both the chat template and the Qwen3 reasoning parser. To disable thinking for a specific request, set `"chat_template_kwargs": {"enable_thinking": false}`.
```bash
curl -s http://localhost:30000/v1/chat/completions \
-H "Content-Type: application/json" \
-d '{
"model": "spark2.5",
"messages": [
{
"role": "user",
"content": "安徽的省会在哪里?"
}
],
"max_tokens": 131072,
"temperature": 1,
"top_k": -1,
"top_p": 0.95,
"repetition_penalty": 1,
"presence_penalty": 0,
"frequency_penalty": 0
}'
```
### vLLM
#### Deploy vLLM
vLLM provides an official Docker image for NVIDIA GPU deployment:
```bash
docker run --rm --gpus all \
--ipc=host \
-p 30000:30000 \
-v "$MODEL_PATH:/models/Spark-X2.5-4B:ro" \
vllm/vllm-openai:latest \
--model /models/Spark-X2.5-4B \
--port 30000 \
--trust-remote-code \
--served-model-name spark25 \
--tensor-parallel-size 1 \
--gpu-memory-utilization 0.7 \
--enable-prefix-caching \
--chat-template /models/Spark-X2.5-4B/chat_template.jinja
```
For Ascend NPUs, choose an official image for the fastest setup.
##### Ascend A2:
```bash
export IMAGE=quay.io/ascend/vllm-ascend:nightly-main
docker pull "$IMAGE"
export DEVICE=/dev/davinci0
export MODEL_CACHE="${HOME}/.cache"
mkdir -p "$MODEL_CACHE"
docker run --rm \
--name vllm-ascend \
--shm-size=1g \
--device "$DEVICE" \
--device /dev/davinci_manager \
--device /dev/devmm_svm \
--device /dev/hisi_hdc \
-v /usr/local/dcmi:/usr/local/dcmi \
-v /usr/local/bin/npu-smi:/usr/local/bin/npu-smi \
-v /usr/local/Ascend/driver/lib64/:/usr/local/Ascend/driver/lib64/ \
-v /usr/local/Ascend/driver/version.info:/usr/local/Ascend/driver/version.info \
-v /etc/ascend_install.info:/etc/ascend_install.info \
-v "$MODEL_CACHE:/root/.cache" \
-p 8000:8000 \
-it "$IMAGE" bash
```
##### Ascend A3:
```bash
export IMAGE=quay.io/ascend/vllm-ascend:nightly-main-a3
docker pull "$IMAGE"
export DEVICE0=/dev/davinci0
export DEVICE1=/dev/davinci1
export MODEL_CACHE="${HOME}/.cache"
mkdir -p "$MODEL_CACHE"
docker run --rm \
--name vllm-ascend \
--shm-size=1g \
--device "$DEVICE0" \
--device "$DEVICE1" \
--device /dev/davinci_manager \
--device /dev/devmm_svm \
--device /dev/hisi_hdc \
-v /usr/local/dcmi:/usr/local/dcmi \
-v /usr/local/bin/npu-smi:/usr/local/bin/npu-smi \
-v /usr/local/Ascend/driver/lib64/:/usr/local/Ascend/driver/lib64/ \
-v /usr/local/Ascend/driver/version.info:/usr/local/Ascend/driver/version.info \
-v /etc/ascend_install.info:/etc/ascend_install.info \
-v "$MODEL_CACHE:/root/.cache" \
-p 8000:8000 \
-it "$IMAGE" bash
```
##### Ascend 950DT:
```bash
export IMAGE=quay.io/ascend/vllm-ascend:nightly-main-a5
docker pull "$IMAGE"
export MODEL_CACHE="${HOME}/.cache"
mkdir -p "$MODEL_CACHE"
docker run --rm \
--name vllm-ascend \
--net=host \
--shm-size=1g \
--device /dev/davinci0 \
--device /dev/davinci_manager \
--device /dev/devmm_svm \
--device /dev/hisi_hdc \
-v /usr/local/dcmi:/usr/local/dcmi \
-v /usr/local/Ascend/driver/tools/hccn_tool:/usr/local/Ascend/driver/tools/hccn_tool \
-v /usr/local/bin/npu-smi:/usr/local/bin/npu-smi \
-v /usr/local/Ascend/driver/lib64/:/usr/local/Ascend/driver/lib64/ \
-v /usr/local/Ascend/driver/version.info:/usr/local/Ascend/driver/version.info \
-v /etc/ascend_install.info:/etc/ascend_install.info \
-v "$MODEL_CACHE:/root/.cache" \
-it "$IMAGE" bash
```
Install the Spark plugin inside the container:
```bash
pip install uv
uv venv ~/spark2_5
source ~/spark2_5/bin/activate
git clone https://github.com/XHToken/Spark-plugin.git
cd ./Spark-plugin
uv pip install .
```
#### Server
```bash
vllm serve "/models/Spark-X2.5-4B" \
--port "30000" \
--trust-remote-code \
--served-model-name spark25 \
--tensor-parallel-size 1 \
--gpu-memory-utilization 0.7 \
--enable-prefix-caching \
--chat-template /models/Spark-X2.5-4B/chat_template.jinja
```
#### Client
```bash
curl -s http://127.0.0.1:30000/v1/chat/completions \
-H "Content-Type: application/json" \
-d '{
"model": "spark25",
"messages": [{"role": "user", "content": "安徽的省会在哪里?"}],
"temperature": 1.0,
"top_k": -1,
"top_p": 0.95
}'
```
### MLX
Spark-MLX-LLM runs the original Spark-X2.5 Hugging Face checkpoints locally. It supports Apple silicon GPU, Linux CPU, and NVIDIA CUDA on Linux. No GGUF conversion is required.
#### Installation
```bash
git clone https://github.com/XHToken/Spark-MLX-LLM.git
cd Spark-MLX-LLM
python3 -m venv .venv
source .venv/bin/activate
# Apple silicon
python -m pip install -e .
# Linux CPU
python -m pip install -e '.[cpu]'
# Linux with CUDA 12
python -m pip install -e '.[cuda12]'
# Linux with CUDA 13
python -m pip install -e '.[cuda13]'
```
#### Run Inference
```bash
spark-mlx-generate \
--device gpu \
--dtype bfloat16 \
--model XHToken/Spark-X2.5-1.7B \
--prompt "安徽的省会在哪里?" \
--max-tokens 512 \
--temp 0
```
### Ollama
#### Build
```bash
git clone https://github.com/XHToken/llama.cpp.git llama.cpp-spark
git clone https://github.com/ollama/ollama.git ollama-spark
cd ollama-spark
export OLLAMA_LLAMA_CPP_SOURCE="$(cd ../llama.cpp-spark && pwd)"
cmake -S . -B build
cmake --build build --parallel 8
```
#### Create and Run
Create the model definition, then start the Ollama server in one terminal:
```bash
printf 'FROM /absolute/path/to/your.gguf\n' > ./Modelfile.spark
./ollama serve
```
Create and run the model from another terminal:
```
./ollama create Spark-X2.5-1.7B -f ./Modelfile.spark
./ollama run Spark-X2.5-1.7B
```
### LM Studio
#### Build
```bash
git clone https://github.com/XHToken/llama.cpp.git llama.cpp-spark
cd llama.cpp-spark
cmake -S . -B build
cmake --build build --parallel 8
```
#### Set Up LM Studio
1. Close LM Studio.
2. Back up the selected runtime directory:
```text
/extensions/backends//
```
3. Copy the `llama.cpp-spark` build output into the selected runtime directory, overwriting the existing files.
4. Place the GGUF model in the following directory:
```text
/models///
```
Example runtime directory on macOS:
```text
./build/bin/* -> ~/.lmstudio/extensions/backends/llama.cpp-mac-arm64-apple-metal-advsimd-/
```
#### Run with LM Studio
Open My Models, select the Spark-X2.5 model, click Load, then start a new Chat.
#### Run with the lms cli
```bash
# Replace `` with a model listed by `lms ls`.
lms load
lms chat
```
### Fine-Tuning
We recommend using [Llama-Factory](https://github.com/XHToken/LlamaFactory) to fine-tune the model.
## License
The Spark-X2.5 model series is licensed under the [Apache 2.0 License](LICENSE).
## Citation
If you find our work helpful, feel free to give us a cite.
```bibtex
@misc{sparkx2.5,
title = {Spark-X2.5 4B&1.7B: Pushing the Limits of Agentic Capabilities in On-Device Models},
author = {SparkLLM Team},
year = {2026}
}
```