



📄 This is the official implementation of the paper:
SegChange-R1: LLM-Augmented Remote Sensing Change Detection
Fei Zhou
Neusoft Institute Guangdong, China & Airace Technology Co.,Ltd., China
If you like SegChange-R1, please give us a ⭐!
Remote sensing change detection is used in urban planning, terrain analysis, and environmental monitoring by analyzing feature changes in the same area over time. In this paper, we propose a large language model (LLM) augmented inference approach (SegChange-R1), which enhances the detection capability by integrating textual descriptive information and guides the model to focus on relevant change regions, accelerating convergence. We designed a linear attention-based spatial transformation module (BEV) to address modal misalignment by unifying features from different times into a BEV space. Furthermore, we introduce DVCD, a novel dataset for building change detection from UAV viewpoints. Experiments on four widely-used datasets demonstrate significant improvements over existing method.  ## 🚀 Updates - ✅ **[2024.06.01]** Open source code - ✅ **[2025.06.22]** Upload to [arXiv](https://arxiv.org/abs/2506.17944)。 ## Model Zoo 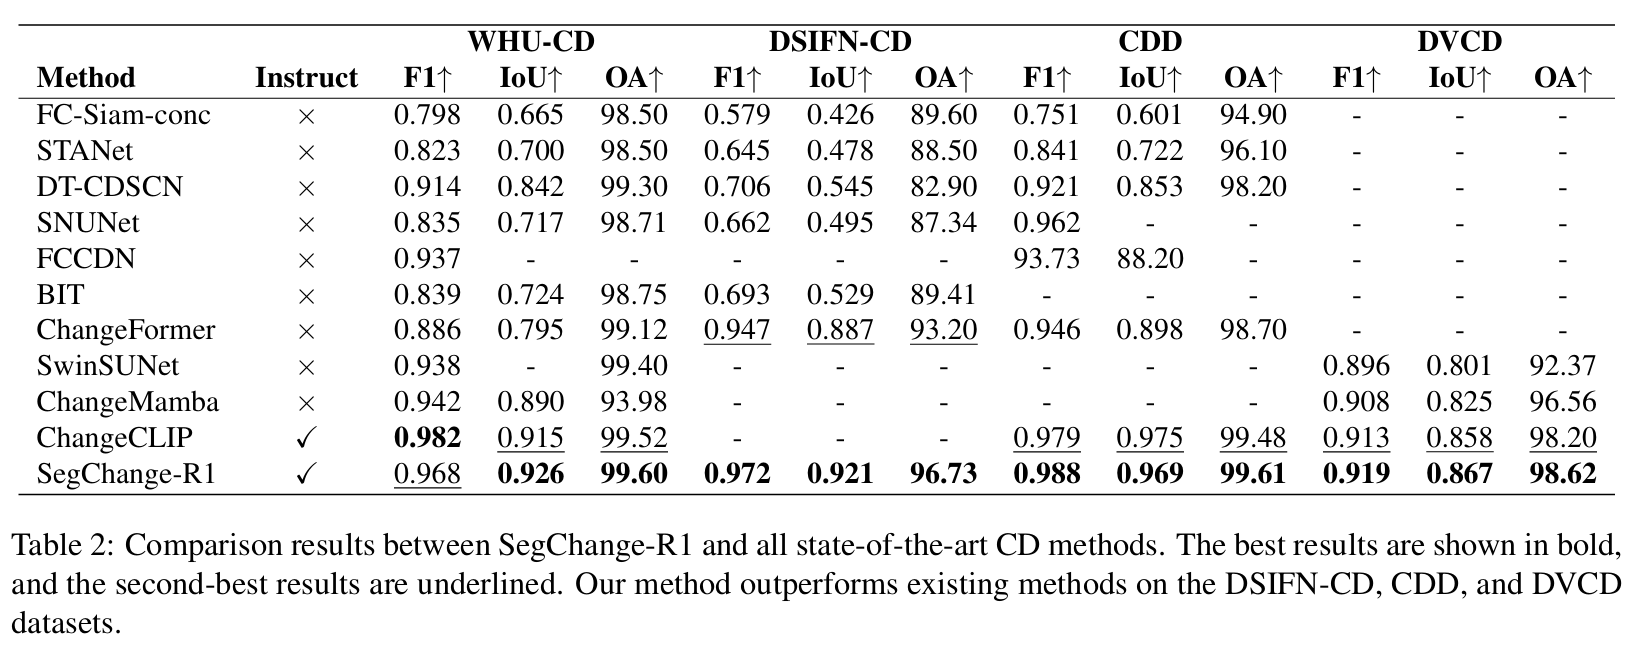 ## Quick Start ### System Requirements - Python 3.12 - CUDA + PyTorch - HuggingFace - Stable network connection - High-quality proxy IPs (important) ### Installation #### 1. Create a virtual environment ```bash conda create -n segchange python=3.12 -y conda activate segchange ``` #### 2. Install dependencies ```bash pip install -r requirements.txt ``` #### 3. Configuring HuggingFace Images ```bash vim ~/.bashrc export HF_ENDPOINT="https://hf-mirror.com" source ~/.bashrc ``` ### Data Preparation Two dataset structure formats are supported: #### 1. Default The structure of the dataset is as follows: ```text data/ ├── train/ │ ├── A/ # First phase training image │ ├── B/ # Second phase training image │ ├── label/ # Training Label (Change Mask) │ └── prompts.txt # The training set text describes the prompt ├── val/ │ ├── A/ │ ├── B/ │ ├── label/ │ └── prompts.txt └── test/ ├── A/ ├── B/ ├── label/ └── prompts.txt ``` Change the `data_format` parameter file [configs](./configs/config.yaml) to `default`. #### 2. Custom The structure of the dataset is as follows: ```text data/ ├── A/ # First phase training image │── B/ # Second phase training image │── label/ # Label (Change Mask) │── list # List file │ ├── train.txt # A list of training sets │ ├── val.txt # A list of validation sets │ └── test.txt # A list of test sets └── prompts.txt # Text description prompts ``` Change the `data_format` parameter file [configs](./configs/config.yaml) to `custom`. ### Training #### Generate word embedding files Use [Text Generation](./examples/text_gen.py) and change the 'desc_embs' parameter file [configs](./configs/config.yaml) to 'None' to execute the script. ```bash python ./examples/text_gen.py -c ./configs/config.yaml ``` If you want to detect changes in multiple categories, you need to manually label the category description text. #### Command-line training ```bash python train.py -c ./configs/config.yaml ``` ### testing ```bash python test.py -c ./configs/config.yaml ``` ### Inference TIF ```bash python infer.py -c ./configs/config.yaml ``` ### app demo ```bash cd examples/gradio_app chmod +x ./run.sh bash run.sh ``` ### DEDICATION Submit issues and code improvements. Make sure to follow the project's code style and contribution guidelines. ## LICENSE This project uses [Apache License 2.0](LICENSE) ### Citation If you use RT-FINE in your research, please cite: