A Suno-style web interface for any self-hosted MiniMax-Music3 server.
Write a style prompt and lyrics, queue takes, watch them render, and keep a local library with a waveform player.
Talks the standard POST /v1/audio/speech route, so it works with sgl-omni serve out of the box.




Try it: demo-minimax-music.adambh.dev — a read-only demo with pre-rendered songs (Create simulates a render).
## Features
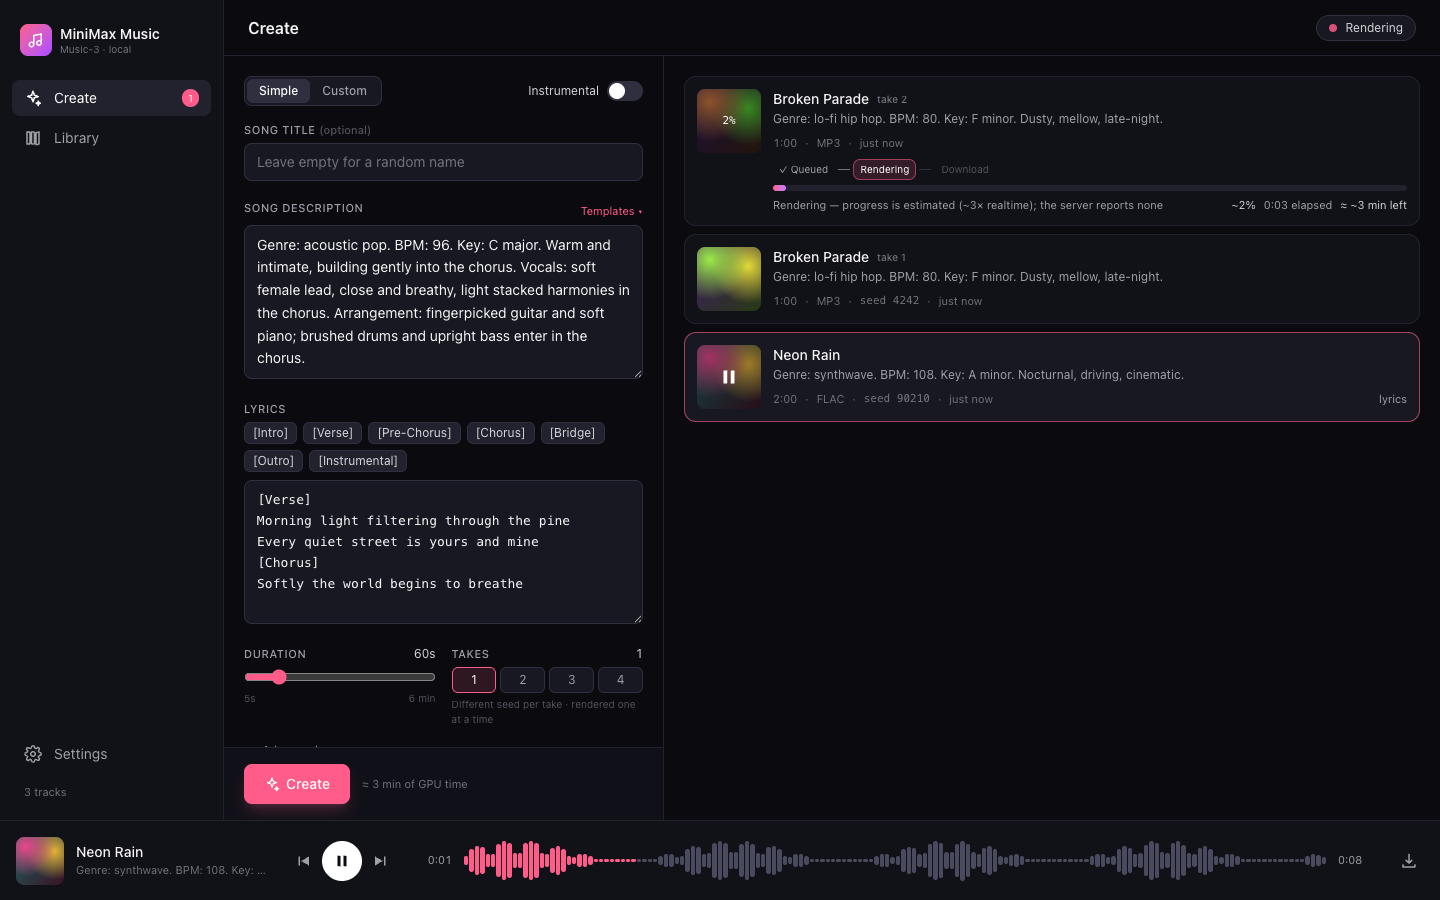
- **Create panel** — Simple or Custom mode, song title (random name like “Velvet Horizon” if left empty), style description, lyrics editor with `[Verse]` / `[Chorus]` / … tag chips, instrumental toggle, duration 5–360 s, 1–4 takes per submit (each take gets `seed + i`), advanced seed. Output is WAV, as the official route documents (FLAC/MP3 appear in the selector but disabled).
- **Templates** — a built-in default plus your own saved templates (style, lyrics, duration), stored server-side.
- **Prompt enhancement** — the magic wand at the top right of the prompt field rewrites your description into a structured MiniMax Music 3 caption (Global Metadata / Vocal Details / Arrangement) using MiniMax's own [`music-caption-rewriter`](https://github.com/MiniMax-AI/MiniMax-Music3/tree/main/skills/music-caption-rewriter) skill. It runs on any OpenAI-compatible chat model with tool calling that you configure in Settings (or `LLM_API` / `LLM_MODEL`); the music server is not involved. Skill files are fetched from GitHub on first use and cached in `data/skill-cache/`. Undo restores your original text.
- **Lyrics writing** — a second wand on the lyrics field writes original lyrics from the song description with the same LLM, sized to the chosen duration and using the model's section tags (`[Verse]`, `[Chorus]`, …). It replaces the current lyrics; Undo restores them. Hidden for instrumentals.
- **Render queue** — the UI server renders one track at a time against the blocking `/v1/audio/speech` route and shows queued / rendering / done with elapsed time and an estimated bar (~3× realtime — the official API reports no progress). Cancel while queued or rendering, retry on error. Queued tracks survive a UI-server restart (they are re-queued in order); a render that was in flight is marked as interrupted.
- **Live progress + play while rendering** — when the server is the bundled `inference/server.py` (it advertises `capabilities: ["stream"]` on `/health`), progress is real for every render (Generating → Rendering, ETA from the measured rate). Tick *Play while rendering* under Advanced and the audio is streamed as it's rendered too: press play on a track that is still rendering, the waveform grows as windows arrive, the player buffers when it catches up with the renderer and swaps to the final file seamlessly. Stock `sgl-omni` keeps the estimated bar.
- **Library** — every finished render is saved into `data/tracks/` with its metadata (prompt, lyrics, seed, format). Cards show duration, seed and how long the render took. Search, download, delete, "reuse settings".
- **Track panel** — click a card to open a Suno-style side panel: big cover with play, status/progress, Download / Reuse / Retry / Delete, full style prompt and lyrics, and details (duration, seed, render time, created/finished). Esc closes it.
- **Player** — sticky bottom bar with waveform (decoded client-side), seek, prev/next, keyboard space to play/pause.
- **Health pill** — offline / loading model / idle (· live progress) / rendering · N queued (probes `GET /v1/models` and the optional `GET /health`).
- **Settings page** — point the app at your inference server (URL + optional API key) from the UI, with a "Test connection" button. Environment variables, when set, take precedence and lock those fields. A *Compatibility mode* debug switch makes the UI treat any server as stock `sgl-omni` (no `/health`, no streaming) to check the plain contract still works.
- Responsive down to phone width. No external services required; everything runs on your machine or tailnet (prompt enhancement is optional and uses the LLM you configure, plus a one-time fetch of the skill from GitHub).
## Architecture
```
browser ──/api/*──▶ server/ (Express 5) ──POST /v1/audio/speech──▶ MiniMax-Music3 server
│ one render at a time; audio response → disk sgl-omni serve (:8000) — blocking WAV
│ or SSE progress + PCM windows when advertised inference/server.py (:7862) — + stream
└─▶ data/library.json · data/templates.json · data/settings.json · data/tracks/*.wav
```
| Package | What |
|---|---|
| `web/` | Vite + React 19 + TypeScript + Tailwind 4 single-page app. Talks only to `/api/*`. |
| `server/` | Express 5 + TypeScript. Owns the library, proxies generation, serves the built SPA. |
| `inference/` | Optional single-GPU MiniMax-Music3 server (Python, diffusers) exposing the same API as `sgl-omni serve`. |
## Requirements
- Node.js 20 or newer for the UI.
- A MiniMax-Music3 inference server exposing `POST /v1/audio/speech` — the bundled single-GPU one below (Python 3.10+, CUDA GPU with ~24 GB VRAM), or MiniMax's own `sgl-omni serve` (two GPUs). See [Upstream API](#upstream-api).
## Quick start
**1. Start an inference server** (skip if you already have one).
```bash
git clone https://github.com/adambenhassen/minimax-music-ui.git
cd minimax-music-ui
# bundled single-GPU server — same API as sgl-omni, plus live progress
python -m venv .venv && source .venv/bin/activate # Windows: .venv\Scripts\activate
pip install -r inference/requirements.txt
python inference/server.py --port 7862 # first start downloads the weights (tens of GB); /health answers 503 until loaded
```
Or MiniMax's reference server: `sgl-omni serve --model-path MiniMaxAI/MiniMax-Music3 --port 8000` (see the [model card](https://huggingface.co/MiniMaxAI/MiniMax-Music3)). Details and options for the bundled one: [`inference/README.md`](inference/README.md).
**2. Start the UI** (a second terminal).
```bash
npm install
npm run build
npm start
# → http://localhost:8787
```
The UI talks to `http://127.0.0.1:7862` by default — exactly where the bundled server listens — so it works right away. For any other address open **Settings** in the sidebar and enter the URL (and API key, if the server needs one). Prefer configuring from the environment? `MUSIC_API` / `MUSIC_API_KEY` override Settings and lock the fields — see [Configuration](#configuration).
### Docker
Prebuilt multi-arch images (amd64 + arm64) are published to GitHub Container Registry on every release:
```bash
docker run -d -p 8787:8787 -v "$PWD/data:/data" ghcr.io/adambenhassen/minimax-music-ui:latest
# → http://localhost:8787 — then set the inference server URL in Settings
```
Or build locally:
```bash
docker compose up -d --build # → http://localhost:8787, library persisted in ./data
# or
docker build -t minimax-music-ui .
docker run -d -p 8787:8787 -v "$PWD/data:/data" minimax-music-ui
```
Optional: set `MUSIC_API` / `MUSIC_API_KEY` in the environment (`-e MUSIC_API=…`, or a `.env` next to `docker-compose.yml`) to pin the inference server; that locks the fields in Settings. From inside Docker, an inference server on the host is `http://host.docker.internal:7862`.
### Configuration
The inference server address is resolved in this order:
1. `MUSIC_API` / `MUSIC_API_KEY` environment variables — always win; the Settings page shows them locked
2. Values saved from the **Settings** page (`data/settings.json`, written with mode `0600`)
3. Default `http://127.0.0.1:7862`
| Variable | Default | Description |
|---|---|---|
| `UI_TOKEN` | – | Optional shared token that protects every `/api/*` route; use a random value of at least 32 characters. The UI prompts for it after its first unauthorized API request and exchanges it at `POST /api/auth` for an HttpOnly session cookie. Scripts should send `Authorization: Bearer $UI_TOKEN`. |
| `MUSIC_API` | – | Base URL of the inference server, path prefix allowed, e.g. `http://host:8000` (overrides Settings) |
| `MUSIC_API_KEY` | – | Sent as `Authorization: Bearer …` if the inference server was started with `--api-key` (overrides Settings) |
| `LLM_API` | – | OpenAI-compatible base URL incl. `/v1` for prompt enhancement, e.g. `https://api.openai.com/v1`, `http://localhost:11434/v1` (overrides Settings) |
| `LLM_API_KEY` | – | Bearer key for `LLM_API`, if it needs one (overrides Settings) |
| `LLM_MODEL` | – | Chat model with tool calling, e.g. `gpt-4.1-mini` (overrides Settings) |
| `UPSTREAM_TIMEOUT_MS` | `0` | Max wait for a render's response (and between its chunks); `0` = no limit. The official route sends nothing until the song is done, so long songs need minutes |
| `PORT` | `8787` | Port for the UI server |
| `DATA_DIR` | `./data` | Where `library.json`, `templates.json`, `settings.json` and `tracks/` live |
| `STATIC_DIR` | `web/dist` (if built) | Directory of the built SPA to serve |
When `UI_TOKEN` is unset, the server logs that the UI is unauthenticated. Non-GET/HEAD API requests also require an `Authorization` or `X-Requested-With` header to block cross-site writes; the web client sends `X-Requested-With`. During development, the Vite proxy adds the configured `UI_TOKEN` to safe reads and writes carrying `X-Requested-With`.
## Development
```bash
npm run dev # server on :8787 (tsx watch) + Vite on :5173 with /api proxied
npm run dev:fake # same, plus a fake inference API on :7999 — no GPU needed
npm test # server tests against the fake upstream and web tests
npm run typecheck # both packages
```
The fake upstream (`server/test/fakeUpstream.ts`) implements `GET /v1/models` and a blocking `POST /v1/audio/speech`. Options for the standalone runner:
```bash
FAKE_AUDIO=/path/to/real.wav FAKE_RENDER_MS=8000 npm run fake -w server
FAKE_LOADING=1 npm run fake -w server # exposes /health → 503, UI shows "Loading model…"
FAKE_STREAM=1 npm run fake -w server # advertises streaming; SSE progress + 4 s PCM windows
FAKE_PORT=7998 npm run fake -w server # listen elsewhere (default 7999)
```
## Public demo image (read-only)
`Dockerfile.demo` bakes a showcase library into the normal image and sets `DEMO=1`: the library is read-only, Settings/Templates can't be changed, and **Create simulates a render** (progress bar, then one of the showcase songs is handed out) — per visitor, in memory, no GPU involved. A banner and the health pill say so.
```bash
demo/prepare.sh server/data # copy finished WAV tracks + trimmed library.json → demo/data
docker build -t minimax-music-ui .
docker build -f Dockerfile.demo -t minimax-music-ui-demo .
docker run --read-only -p 8787:8787 minimax-music-ui-demo
```
## UI server API
When `UI_TOKEN` is set, all API routes require a bearer token or the session cookie from `POST /api/auth`, except `POST /api/auth` itself and `GET /api/ping`. The auth endpoint accepts `{"token":"..."}` and sets an `HttpOnly; SameSite=Strict; Path=/api` cookie (plus `Secure` over HTTPS). The UI prompts when an API request is unauthorized, then reuses the cookie; scripts can use the bearer header directly.
| Method | Path | Description |
|---|---|---|
| `GET` | `/api/ping` | Public liveness check; does not contact the inference server |
| `POST` | `/api/auth` | `{token}` → 204 and an authenticated session cookie; 401 for an incorrect token |
| `GET` | `/api/health` | `demo` (read-only demo, see above), `upstreamReachable` (via `/v1/models`), `ready` (false only if an optional upstream `/health` answers 503), `capabilities` from that `/health`, `enhance` (an LLM is configured), queue state |
| `GET` | `/api/library` | Tracks, newest first |
| `POST` | `/api/generate` | `{title?, prompt, lyrics?, duration, seed?, format, takes}` → created tracks (queued) |
| `POST` | `/api/lyrics` | `{prompt, duration?}` → `{lyrics}` written from the description and sized to the duration; 409 until an LLM is configured, 502/504 on LLM failure or timeout |
| `POST` | `/api/enhance` | `{prompt, lyrics?, instrumental?}` → `{prompt}` rewritten by the caption-rewriter skill; 409 until an LLM is configured, 502/504 on LLM failure or timeout |
| `GET` | `/api/tracks/:id/audio` | Stream audio (`?download` for an attachment); for a track still rendering, the audio so far with a valid header (Range supported) |
| `DELETE` | `/api/tracks/:id` | Cancel (dequeue or abort the render), delete file and entry |
| `GET` | `/api/templates` | Saved templates |
| `POST` | `/api/templates` | `{name, prompt, lyrics?, duration?, format?}` — same name overwrites |
| `DELETE` | `/api/templates/:id` | Remove a template |
| `GET` | `/api/settings` | Effective inference URL, whether a key is set, `compat` flag, LLM URL/model and whether its key is set, and which fields are env-locked (keys are never returned) |
| `PUT` | `/api/settings` | `{musicApi?, apiKey?, compat?, llmApi?, llmApiKey?, llmModel?}` — `""` clears a key or LLM field; env-locked fields are rejected; `compat: true` skips `/health` and never streams |
| `POST` | `/api/settings/test` | Probe a candidate `{musicApi?, apiKey?}` against `/v1/models` without saving |
## Upstream API
The server speaks the standard MiniMax-Music3 contract (the same one `sgl-omni serve` exposes), relative to `MUSIC_API`:
| Method | Path | |
|---|---|---|
| `GET` | `/v1/models` | Reachability probe. Optional — a 404 still counts as "up". If present, the first listed id is used as `model`; otherwise `MiniMaxAI/MiniMax-Music3` (the model card's example) |
| `POST` | `/v1/audio/speech` | `{model: , input: , instructions: