

Framework | Dataset | Getting Started | Page Main
 ## Dataset
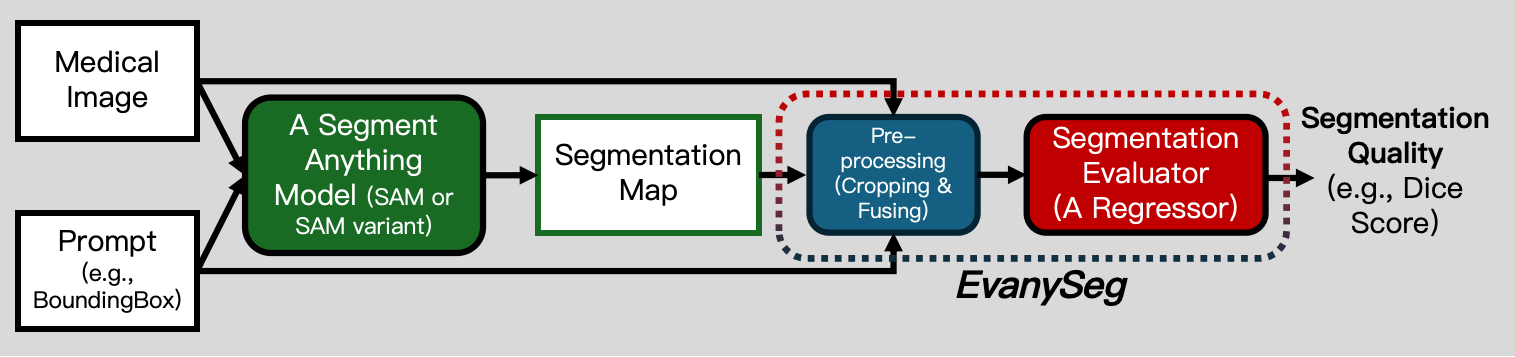
The EvanySeg model was trained based on 2D images, accompanied by object-level ground truth masks. Segmentation predictions for training the EvanySeg model were generated using SAM, MedSAM, and SAM-Med2D.
The filesystem hierarchy of the dataset is as follows:
```
📁 EvanySeg
├── 📁 checkpoints
├── 📁 result
├── 📁 datasets
│ ├── 📁 preprocess
│ │ └── 📁 train_sam_Polyp
│ │ ├── 📁 crop_image
│ │ │ 0_SAM_Polyp_train_175.png
│ │ ├── 📁 crop_mask
│ │ │ 0_SAM_Polyp_train_175.png
│ │ └── 📁 crop_predict
│ │ │ 0_SAM_Polyp_train_175.png
│ └── 📁 raw
│ └── 📁 Polyp
│ └── 📁 train
│ ├── 📁 images
│ │ 175.png
│ └── 📁 masks
│ 175.png
```
The processed data naming rules are as follows:
```
├─crop_images
{i}_{model_name}_{directory}_{part}_{sample_name}
```
Note: "i" represents the index of the connected domain being processed in the current iteration, "model_name" indicates the model SAM and its variants, "directory" represents the directory name of the dataset such as Polyp, "part" indicates the subdirectory, sample_name, "sample_name" indicates the original name of the image
## Getting Started
Download the datasets and pre-trained models to the corresponding folders, and configure the environment.If you plan to train your own dataset,please preprocess it first using the preprocessing.py file.
#### Download
Please download the EvanySeg result checkpoints to the result directory from [ResNet101_Bbox_Dice](https://drive.google.com/file/d/1Hj7LwH8zIJUaiQmDOkHM6JUgxkoTyGpu/view?usp=drive_link)、[ViT-B_Bbox_Dice](https://drive.google.com/file/d/1S_s8zUgv8V2F8LP_h_4HM96j1LWHzjBB/view?usp=drive_link) and [ViT-B_Bbox_Dice_HD](https://drive.google.com/file/d/1vo1zFWHhtpWUB7UA3hJ3eaUnL0LaFexK/view?usp=drive_link). (Currently, only part of the models have been open-sourced, and we will continue to open-source the remaining models in the future.)
The example datasets are provided [Train.zip](https://drive.google.com/file/d/1gkh0gqIf_oeLUuKo2zYbecAb1vcZdLcH/view?usp=drive_link) and [Test.zip](https://drive.google.com/file/d/1oxuHYhFLc0x2Yx7x9Lh73XljPK8ixnr_/view?usp=drive_link)
Other required model download Offical links (models related to ViT and SAM) : SAM:[SAM model](https://dl.fbaipublicfiles.com/segment_anything/sam_vit_h_4b8939.pth) , MedSAM:[MedSAM](https://drive.google.com/file/d/1UAmWL88roYR7wKlnApw5Bcuzf2iQgk6_/view?usp=drive_link) , SAM-Med2D:[SAM-Med2D](https://drive.google.com/file/d/1ARiB5RkSsWmAB_8mqWnwDF8ZKTtFwsjl/view) , ViT-Base: [ViT-Base](https://huggingface.co/google/vit-base-patch16-224/tree/main) , ViT-Large: [ViT-Large](https://huggingface.co/google/vit-large-patch16-224/tree/main) .
#### Installation
Recommendation: Python version around 3.9, please do not use a version that is too high.
```python
pip install torch torchvision torchaudio --index-url https://download.pytorch.org/whl/cu124
pip install -r requirements.txt
```
#### Test
```python
python test.py
```
#### Train
```python
python train.py
```