# defluff
> *The deterministic slop check for AI-generated prose. Point it at a changelog, a doc, or an agent's own output and get back the filler phrases to cut — plus a CI exit code and a pinnable score, identical on every run. No model, no API key.*
[](https://github.com/ahmedak/defluff/actions/workflows/ci.yml)
[](https://pypi.org/project/defluff/)
[](https://pypi.org/project/defluff/)
[](LICENSE)
[](https://github.com/ahmedak/defluff/commits/main)
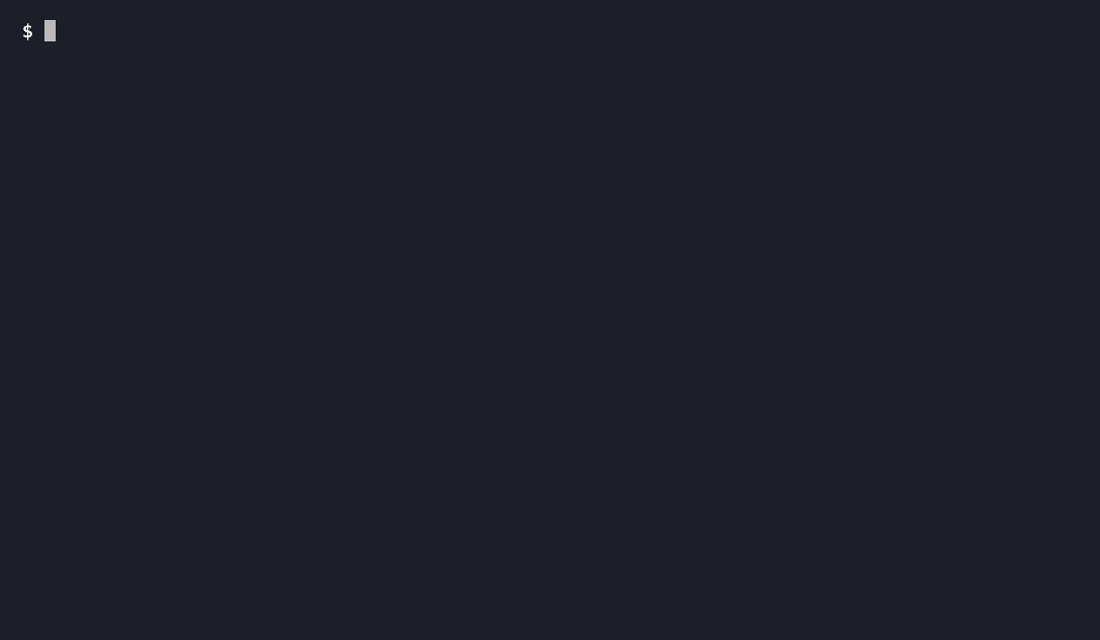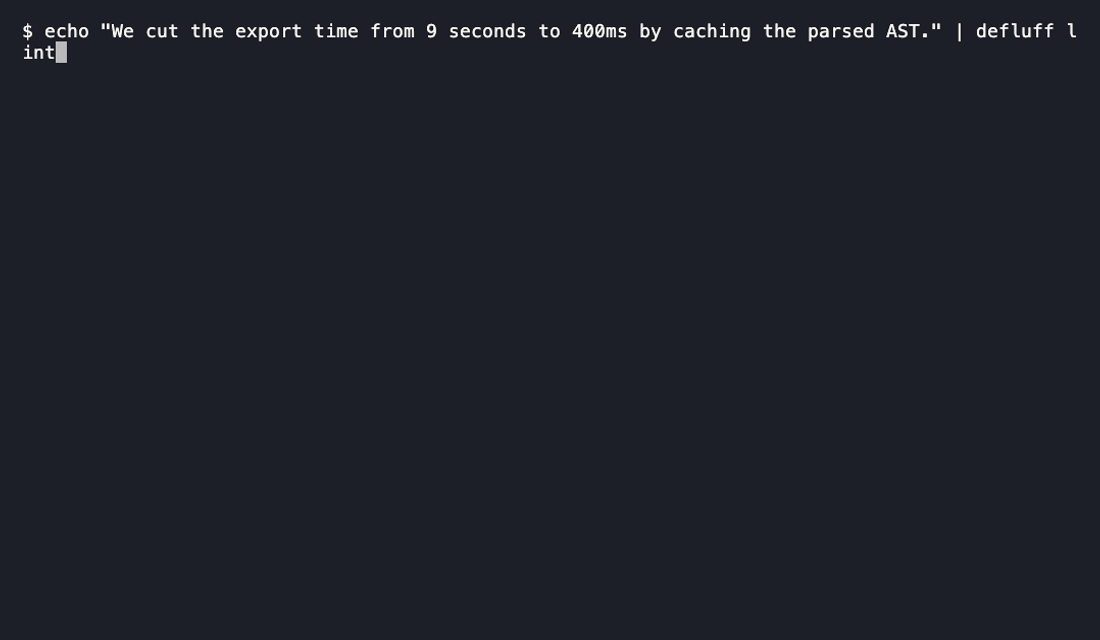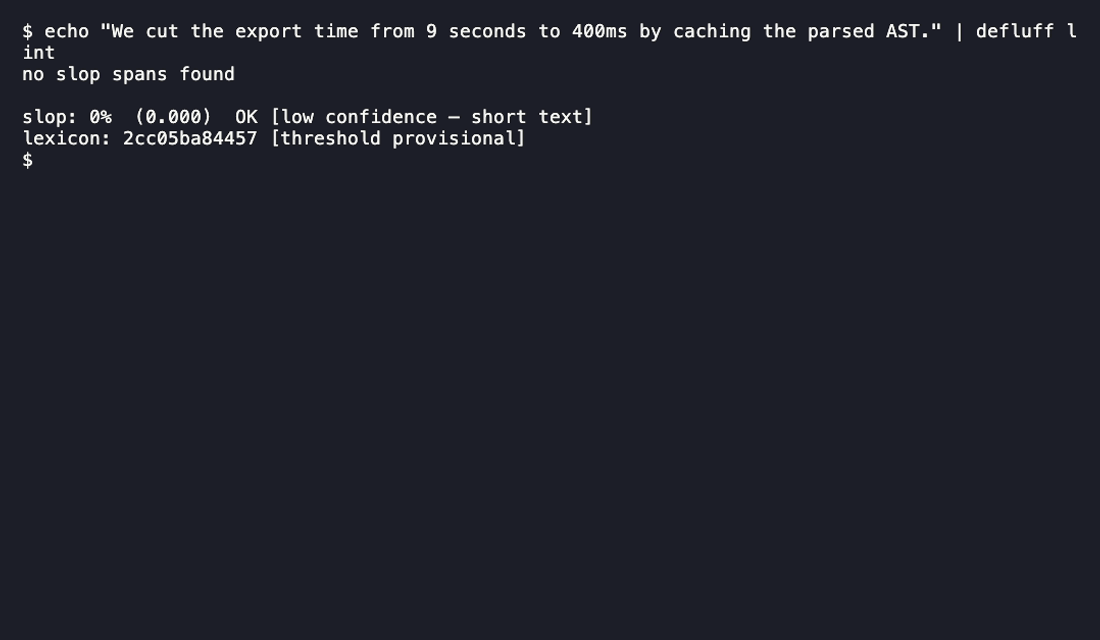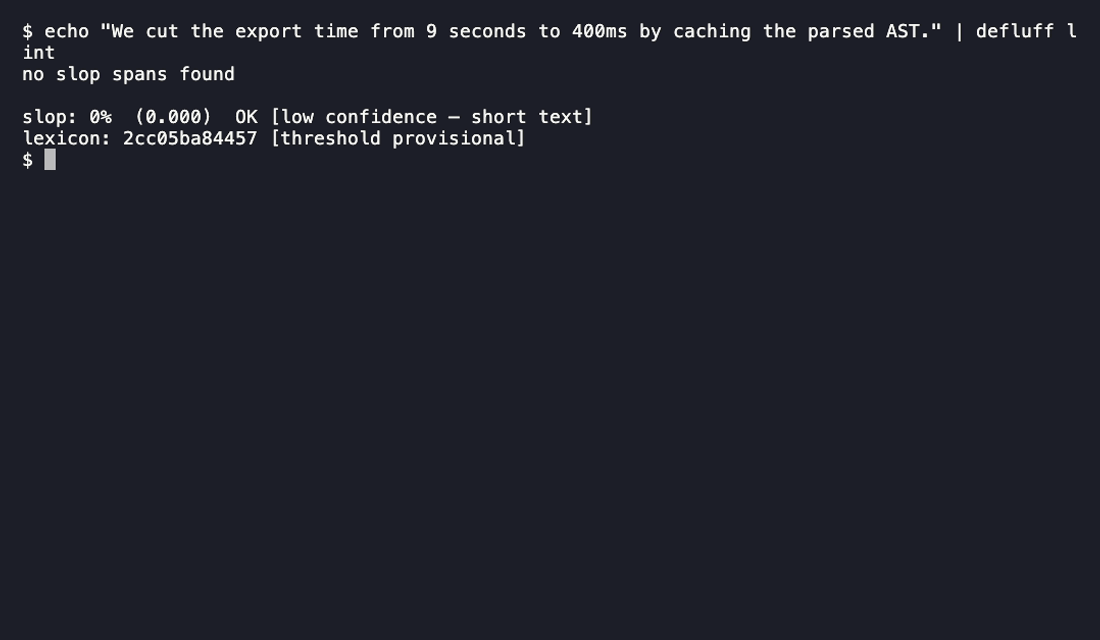
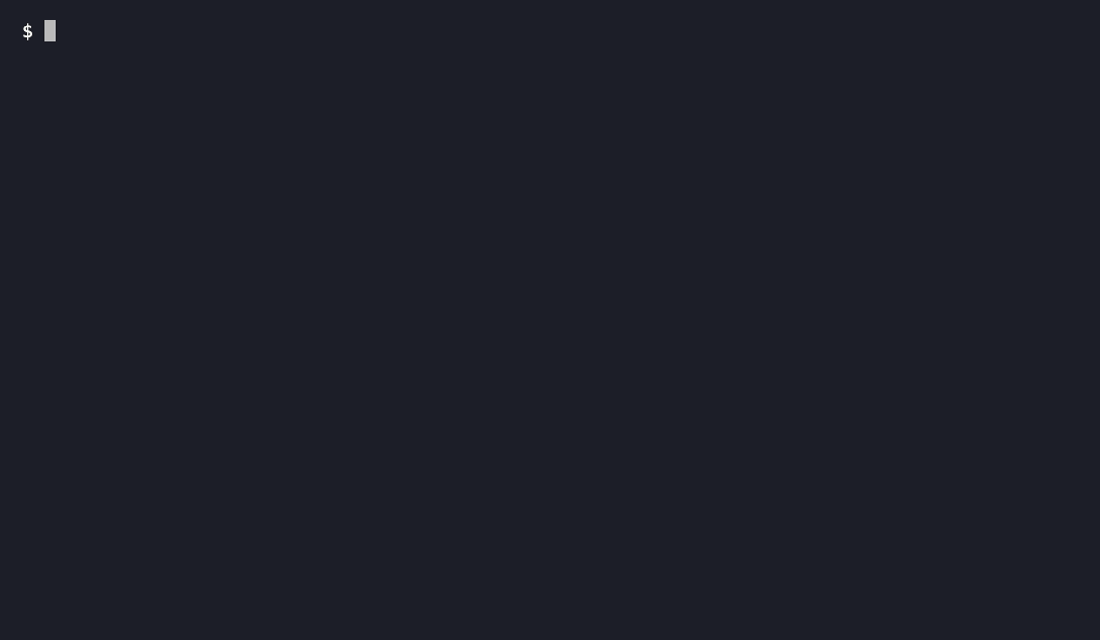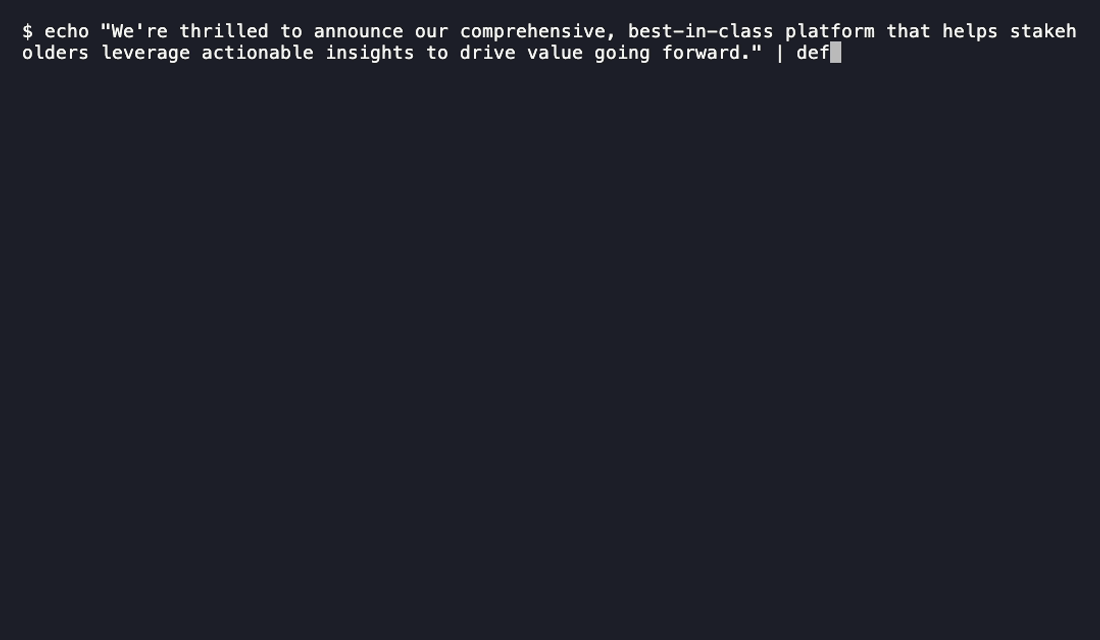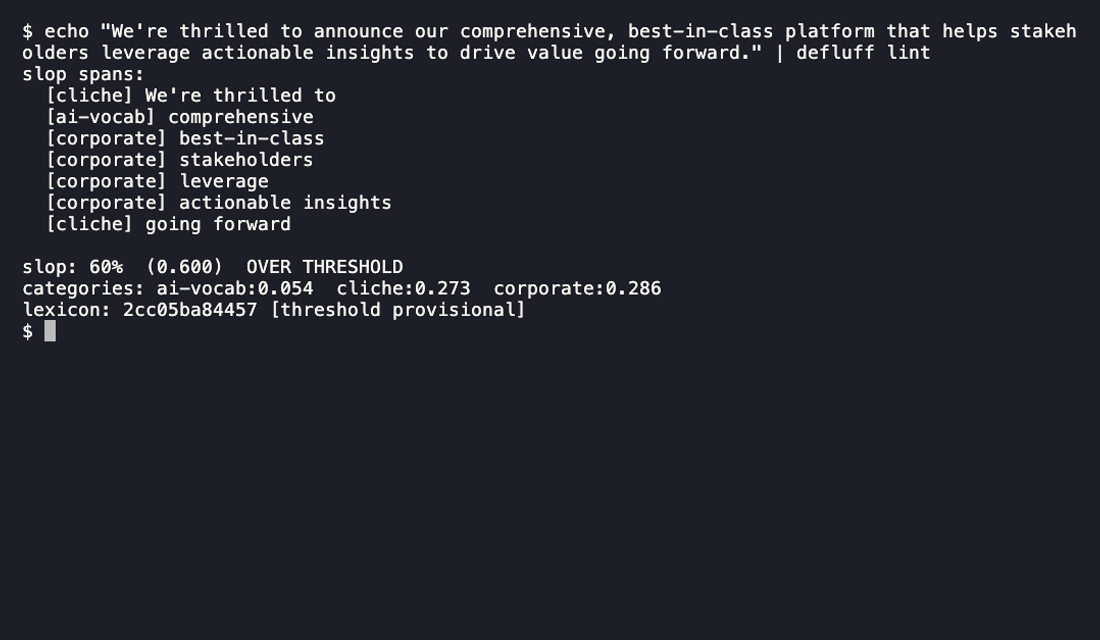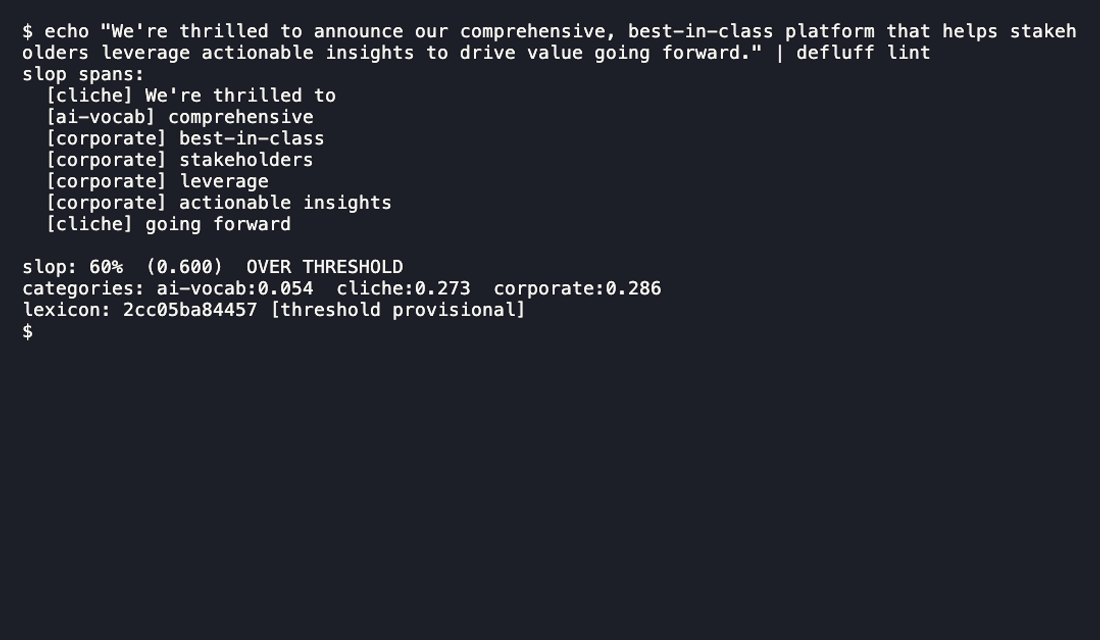 Every flagged span carries no information, so cutting them loses nothing. Clean text, same tool, passes straight through:
 What makes defluff worth installing over a one-off `grep` is the [engine around the list](#the-list-isnt-what-this-is-about--the-engine-is): bring your own phrases, per-project overlays, and an MCP server your agents pick up with no wiring.
---
## Install
```bash
pip install defluff
```
Or on macOS/Linux via Homebrew:
```bash
brew install ahmedak/defluff/defluff
```
That's it. No model download. No API key. Runs anywhere Python does.
---
## Quick start
```bash
# Lint a file — exit 1 on slop, 0 when clean
defluff lint essay.md
# Pipe text
cat draft.md | defluff lint
# Get a bare score for scripts (0.0 – 1.0)
defluff score essay.md
# Machine-readable JSON for downstream tooling
defluff lint essay.md --json
```
---
## MCP server
Exposes three tools so any MCP-aware agent can self-check prose without bespoke wiring — including its own draft, before returning it.
Zero-install via `uvx` (recommended) — pulls the package and the `mcp` extra on first run:
```json
{
"mcpServers": {
"defluff": {
"command": "uvx",
"args": ["--from", "defluff[mcp]", "defluff-mcp"]
}
}
}
```
Or install it and run the entry point directly:
```bash
pip install "defluff[mcp]"
defluff-mcp
```
```json
{
"mcpServers": {
"defluff": { "command": "defluff-mcp" }
}
}
```
Published to the [MCP Registry](https://registry.modelcontextprotocol.io) as `io.github.ahmedak/defluff` (see `server.json`).
mcp-name: io.github.ahmedak/defluff
| Tool | Args | Returns |
|------|------|---------|
| `slop_detect` | `text: str` | `slop_score`, `spans` (text, category, weight, offsets), `categories`, `lexicon_version` |
| `slop_add` | `pattern: str, category: str, scope: "user"\|"project"` | adds a phrase to the lexicon overlay |
| `slop_ignore` | `pattern: str, scope: "user"\|"project"` | suppresses a phrase (e.g. domain jargon) |
---
## Common use cases
- **Agent self-correction** — call `slop_detect` on a draft and revise the flagged phrases before returning it. Zero wiring, one session, no second model in the loop.
- **CI gate on generated content** — fail the build when an AI-drafted changelog or doc ships full of "furthermore" and "robust." Deterministic + exit codes + a [pinnable lexicon](#lexicon-overlays-and-versioning) is what an LLM-judge gate can't give you.
- **Writing assistant feedback** — highlight the exact phrases an editor would cut, instead of a vague "this sounds AI."
- **A reward *component* for fine-tuning** — see [reward loops](#use-in-reward-loops-experimental) for caveats; on its own it's gameable.
---
## Why defluff?
Every "AI detector" tries to classify *whether* text was AI-generated — a hard, unreliable problem. defluff asks a different question: **does this text contain removable filler?** That's deterministic, and it's true whether a human or an LLM wrote "at the end of the day."
`proselint` is the closest prior art — deterministic, no model — but emits yes/no warnings rather than a tunable density score, and isn't built around a list you swap, overlay, or pin.
A `grep` over a word list gives you raw hits. defluff gives you what you'd otherwise have to build around that list:
- **An MCP server** — agents self-check with zero wiring.
- **Markdown- and code-aware** — strips code fences, inline code, and URLs first.
- **Whole-word matching** — `"foster"` won't fire inside `"fostering"`.
- **A normalized score** instead of a hit count — filler *density*, so one threshold works on a tweet or a 5,000-word doc.
- **Overlap handling** — "at the end of the day" overlapping "end of the day" counts each word once (longest-match-wins).
- **Exit codes, JSON, and char-offset spans** — drop into CI, pre-commit, and editor tooling.
- **A pinnable lexicon hash** — prove the ruler didn't move between runs.
### Bring your own slop
```bash
defluff lint draft.md --lexicon team-slop.md
```
```
# team-slop.md
- circle back
- low-hanging fruit
- boil the ocean
paradigm shift
```
One phrase per line (`#` comments and `-`/`*` markers ignored). These layer on top of the built-in defaults and report under a neutral `custom` category. For real categories and per-phrase weights, use a `.json` list (see [Lexicon overlays](#lexicon-overlays-and-versioning)).
### Ready-made domain packs
```bash
defluff lint post.md --pack marketing-growth
defluff lint post.md --pack marketing-growth,ai-llm # stack several
```
| Pack | Catches | Pack | Catches |
|------|---------|------|---------|
| `corporate-linkedin` | office jargon | `crypto-web3` | crypto hype |
| `startup-vc` | pitch-deck speak | `pr-press-release` | press-release boilerplate |
| `marketing-growth` | hype copy | `academic` | research hedging |
| `ai-llm` | LLM tells | `wellness-selfhelp` | influencer-speak |
| `social-media` | X/Twitter engagement-bait | | |
List them with `defluff packs`. High-false-positive terms (e.g. `pivot`, `detox`) ship commented-out so they're inert until you opt in. See the [packs README](src/defluff/data/packs/README.md).
### Batteries-included defaults
~130 curated patterns across five weighted categories, case-insensitive, whole-word matched:
| Category | What it catches | Examples |
|----------|----------------|---------|
| `ai-vocab` | Words disproportionately overused by LLMs | *delve, tapestry, nuanced, pivotal, robust, showcase* |
| `cliche` | Hollow idioms that add no information | *at the end of the day, move the needle, circle back, game changer* |
| `hedge` | Empty qualifiers | *it should be noted that, needless to say, basically, essentially* |
| `corporate` | Buzzword inflation | *leverage, synergy, actionable insights, cutting-edge, scalable* |
| `transition` | Filler connectives LLMs reach for by default | *furthermore, moreover, in conclusion, first and foremost* |
### Rhetorical patterns (beyond the list)
Some AI tells are sentence *shapes*, not fixed phrases — the **antithesis**: `it's not X, it's Y`, `not just a list but a runtime`. A regex pattern layer catches these under a `rhetoric` category:
| Mode | What it looks for | Default | Why |
|------|-------------------|---------|-----|
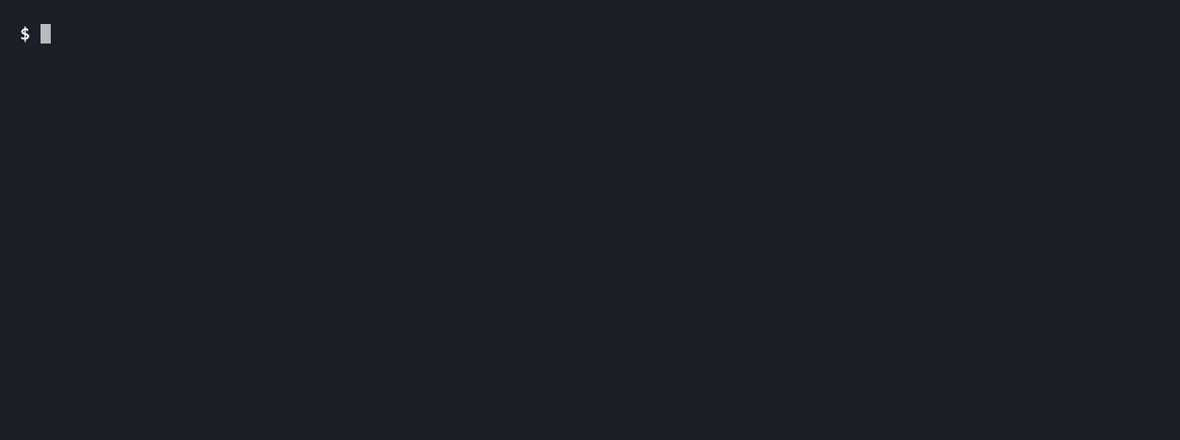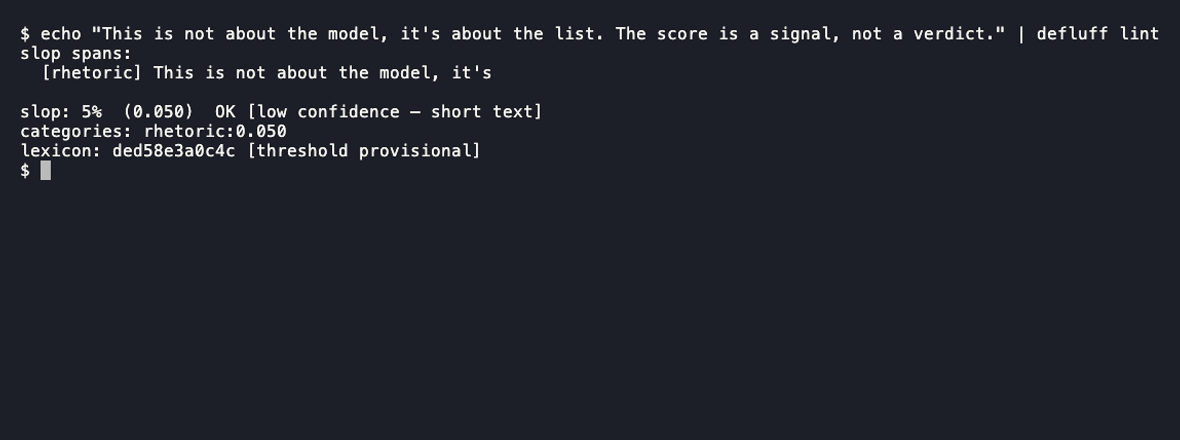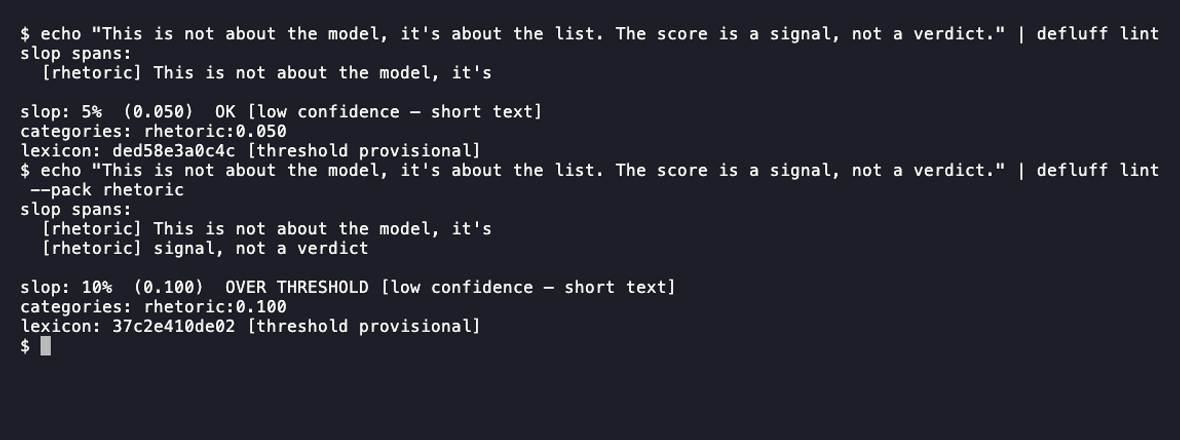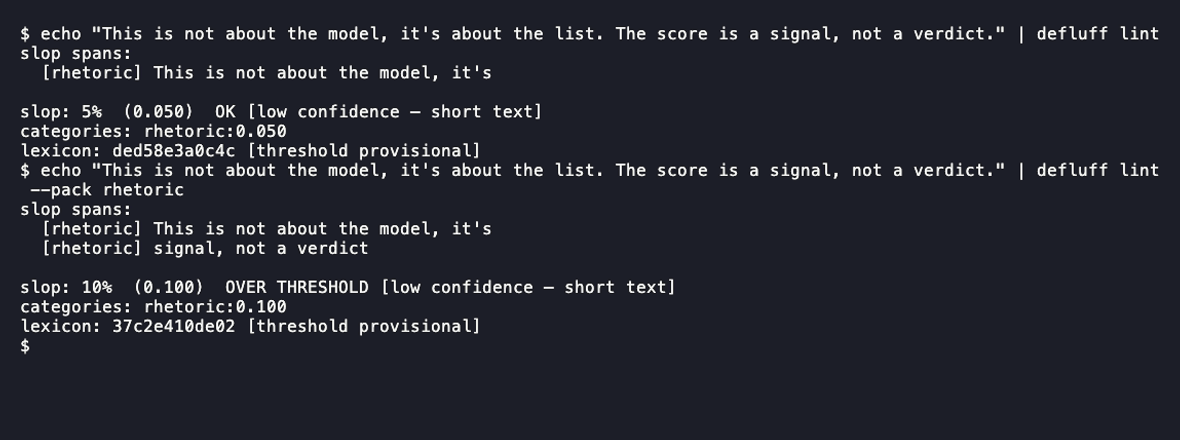
| **Compound** *(confident)* | full shape: `it's not X, it's Y` · `not just X but Y` | **on** | the second clause proves the rhetorical move — rarely a false alarm |
| **Fragment** *(guessing)* | bare `X, not Y` — e.g. `a signal, not a verdict` | **off**, `--pack rhetoric` | also fires on plain corrections (`shipped Tuesday, not Wednesday`) |
Each match counts as one unit toward the score regardless of length. Turning on fragment mode changes the lexicon hash.
```bash
defluff lint draft.md # compound antithesis caught by default
defluff lint draft.md --pack rhetoric # also catch the punchy "X, not Y" fragment
defluff lint draft.md --category rhetoric # gate CI on antithesis alone
```
 ---
## Python API
```python
import defluff
report = defluff.detect("It is worth noting that we should leverage synergies.")
print(report.slop_score) # 0.0 – 1.0
print(report.spans) # flagged phrase locations + categories
score = defluff.score(text) # bare float
clean = defluff.is_slop(text) # bool at default threshold
lex = defluff.load_lexicon() # pin for reproducible runs
score = defluff.score(text, lexicon=lex)
```
`SlopReport` fields:
| Field | Type | Notes |
|-------|------|-------|
| `slop_score` | `float` | Clamped `[0, 1]` — use for thresholds |
| `slop_density` | `float` | Raw unclamped — better gradient for reward loops |
| `spans` | `list[Span]` | Per hit: `text`, category, weight, char offsets *into the cleaned text* (see [Limitations](#limitations)) |
| `categories` | `dict[str, float]` | Per-category density |
| `n_words` | `int` | Token count |
| `low_confidence` | `bool` | `True` when `n_words < 20` |
| `lexicon_version` | `str` | SHA prefix of resolved entry set |
---
## Lexicon overlays and versioning
The bundled lexicon is the baseline; layer on top without editing the package:
```bash
# "synergy" is slop on this machine
defluff lexicon add "synergy" --category corporate --scope user
# "leverage" is fine in this repo (finance context) — commit this with the repo
defluff lexicon rm "leverage" --scope project
git add .defluff/ignore.json && git commit -m "allow 'leverage' in finance context"
```
- **User overlay** (`~/.config/defluff/`) — machine-wide, not committed
- **Project overlay** (`.defluff/` at git root) — per-repo, commit it for your whole team
Writes are atomic and cross-process locked; a corrupt overlay is warned and skipped — `detect()` never crashes.
Every resolved lexicon (bundled + overlays + packs) carries a short content hash, printed on every run (`lexicon: 2cc05ba84457`) and exposed as `SlopReport.lexicon_version`. Pass `lexicon=defluff.load_lexicon()` once and every call scores against the same ruler — pinnable for CI baselines and RL rewards, and auditable since the hash changes if and only if the resolved entry set changes. Each release ships a dated lexicon with a changelog ([`CHANGELOG.md`](CHANGELOG.md)); `ai-vocab` is expected to turn over release to release, `cliche`/`hedge`/`corporate`/`transition` are near-stable.
---
## Reading the output and setting the threshold
1. **The spans** — the exact filler phrases, with category. Deterministic, reliable. Act on these.
2. **The score** — `slop_score` = flagged words ÷ total, weighted by category (`ai-vocab` counts a little more, `transition` a little less). `0.20` ≈ "a fifth of this text is listed filler." Usually `0.0–1.0`; can edge slightly above on text that's almost nothing but slop. Instead of being a quality quantfier, its just a **tripwire** that drives the CI exit code.
Pick a threshold based on how filler-dense the text is *allowed* to be:
| `--threshold` | Meaning | Good for |
|---------------|---------|----------|
| `0.05` | ~5% filler — strict | marketing copy, landing pages, customer-facing text |
| `0.08` *(default)* | ~8% filler — a tripwire for triage | general prose, blog drafts |
| `0.12–0.20` | only flag heavy padding | technical docs that legitimately use `robust`, `scalable`, `in order to` |
The default `0.08` is **provisional** — hand-chosen, not yet calibrated on a labeled corpus (hence the `[threshold provisional]` tag). For a hard CI gate, set your own threshold and suppress your domain's vocabulary first (below).
---
## Use in CI
> Technical writing — API docs, ADRs, RFCs — legitimately uses words like `robust`, `scalable`, `in order to`. Suppress your project's domain vocabulary first:
>
> ```bash
> defluff lexicon rm "scalable" --scope project
> defluff lexicon rm "in order to" --scope project
> git add .defluff/ignore.json && git commit -m "defluff: allow domain vocabulary"
> ```
>
> Then gate only on the categories you trust, not all five:
```yaml
- name: Check AI-generated content for slop
# --category ai-vocab,hedge gates only on the highest-precision categories
run: cat generated_output.md | defluff lint --category ai-vocab,hedge --threshold 0.1
```
Exit code `1` fails the step, `0` passes.
---
## Use with pre-commit
```yaml
# .pre-commit-config.yaml
repos:
- repo: local
hooks:
- id: defluff
name: defluff slop check
entry: defluff lint
language: system
types: [markdown]
```
---
## Use in reward loops (experimental)
A deterministic, non-differentiable scalar for filler density can be a small *component* of a reward mix — but it's gameable alone: a model optimized purely against a fixed phrase list learns to paraphrase the filler rather than remove it. Pair it with a real quality signal (human or LLM judge); we don't yet have a published training run showing it helps.
```python
lex = defluff.load_lexicon() # pin once
reward = lambda text: -defluff.detect(text, lexicon=lex).slop_density # unclamped, better gradient
delta = defluff.compare(draft_v1, draft_v2, lexicon=lex)
# {"score_a": 0.31, "score_b": 0.18, "delta": -0.13,
# "improved": [...], "regressed": [...]} # set diff of flagged phrases, not a semantic diff
```
---
## CLI reference
```bash
defluff lint [FILE] [--json] [--threshold FLOAT] [--category CATS] [--lexicon PATH] [--pack NAMES] [--no-project-overlay]
defluff score [FILE] [--pack NAMES] [--no-project-overlay]
defluff packs # list bundled domain packs
defluff lexicon list [--category CATEGORY] [--scope SCOPE] [--json]
defluff lexicon add PATTERN --category CATEGORY [--scope SCOPE] [--weight FLOAT]
defluff lexicon rm PATTERN [--scope SCOPE]
```
- `--category` — comma-separated; only spans in those categories count toward the exit-code decision (still reports all hits). Valid: `ai-vocab`, `cliche`, `hedge`, `corporate`, `transition`, `custom`, `rhetoric`.
- `--lexicon PATH` — layers your phrases on top of the defaults. `.txt`/`.md` is one phrase per line (lands in `custom`); `.json` carries explicit categories and weights.
- `--pack NAMES` — comma-separated [domain packs](#ready-made-domain-packs). `rhetoric` is reserved for the pattern pack, enabling the opt-in `X, not Y` antithesis fragment.
Exit codes for `defluff lint`: `0` = clean · `1` = slop · `2` = bad input.
---
## Accuracy
defluff is a deterministic matcher, not a trained classifier, so the metric that matters is **precision** — when it flags something, is it actually removable filler? On a 50-example hand-labeled set ([`eval/validation.jsonl`](eval/validation.jsonl)) spanning clear slop, clean prose, and *jargon-as-content traps* (e.g. "the **robust** standard errors", "**pivotal** trials"), at the default threshold:
| Metric | Score | Reading |
|--------|------:|---------|
| **Precision** | **1.00** | 0 false positives — clean prose and legitimate jargon were not flagged |
| **Recall** | **0.65** | bounded by lexicon coverage |
Reproduce: `python eval/score.py eval/validation.jsonl`
Misses are novel buzzwords the lexicon hasn't seen yet (e.g. "operationalize the ideation funnel") — the known limit of a list-based matcher, not noise. Recall on listed filler is 1.00 and will rise as the lexicon grows, but won't reach 1.00 against open-ended novel jargon without a semantic layer.
Caveats: the set is small and labeled by the author — a sanity check on precision, not an independently adjudicated benchmark.
---
## Limitations
- **It matches a known list by design — it doesn't *understand* text.** Novel buzzwords are missed; this is the trade for being deterministic, local, and reproducible (no model, no API key, [pinnable hash](#lexicon-overlays-and-versioning)). Pair with an LLM judge if you need semantic detection of novel filler.
- **Domain jargon is contextual.** `"leverage"` in a finance document is real content. Read the flagged spans; suppress false positives with `defluff lexicon rm` (adds to an ignore list, doesn't delete from the bundled lexicon).
- **Span offsets are into the cleaned text.** defluff strips code fences, inline code, URLs, and markdown markup before matching, so offsets won't line up with your original document — match on `span.text`, not raw offsets, against marked-up source.
- **`custom` is read-only-via-file.** Phrases from a `--lexicon` file land in `custom`, but `defluff lexicon add --category custom` is rejected — `add` only takes the five curated categories.
- **English only** in v0.
- **Short texts** (< 20 words) get `low_confidence: true` — the denominator is floored at 20 so one phrase can't read as 100% slop on a two-sentence input.
---
## Contributing
The easiest contribution is adding a missed filler phrase:
1. Add it to `src/defluff/data/lexicon-v1.json` with the right category
2. `pytest` — smoke tests catch boundary errors
3. PR with one or two examples of the phrase in the wild
See [CONTRIBUTING.md](CONTRIBUTING.md) for code setup and guidelines.
---
## License
MIT