🧪 Apple Metal and Intel OpenVINO backends are in testing, with AMD ROCm in development. NVIDIA is the only backend shipped today.
English | 简体中文
The fastest GPU document parser — OCR · layout · tables · formulas → Markdown, at 200–559 images/s on one GPU.
C++ / CUDA / TensorRT / PP-OCRv6 — Linux + NVIDIA GPU
🎉 v3.0 — now powered by PP-OCRv6
New medium / small / tiny tiers · higher accuracy · faster defaults · breaking changes
⭐ Star TurboOCR on GitHub — it helps others (and agents) find it.




Quick Start ·
Accuracy ·
Benchmarks ·
Models ·
v3 changes ·
API ·
Docs
---
An extremely fast GPU **document parser** — not just OCR. PP-OCRv6 detection +
recognition, plus layout, tables (→ HTML), formulas (→ LaTeX) and reading-order
**Markdown**, the whole pipeline on a single multi-stream CUDA/TensorRT engine,
locally (no VLM), behind HTTP and gRPC. Whole-page OCR runs at **up to 559 images/s
on receipts** (one RTX 5090), and full structured parsing (layout + tables + formulas)
at **~20 pages/s** — where VLM document parsers like PaddleOCR-VL run ~1 page/s. On
forms and receipts it is accurate and 15–90× faster than classic OCR engines.
- 🚀 **559 img/s (receipts) · 520 (forms) · 200+ (dense docs) on one RTX 5090 — fastest by default
- 🎯 **Accurate on forms & receipts** — competitive with PaddleOCR-VL, PaddleOCR-Python, RapidOCR, EasyOCR and Tesseract ([benchmarks](#benchmarks))
- 🧠 **PP-OCRv6** — one model covers Latin + Chinese + Japanese; pick `tiny` (default) / `small` / `medium`
- 🌐 **More scripts** — Arabic, Cyrillic, Korean, Thai, Greek via retained PP-OCRv5 recognizers
- 📄 **PDF native** — pages rendered and OCR'd in parallel, optional page-image export & auto-rotation
- 🧩 **Layout + reading order** — PP-DocLayoutV3 (25 classes) and the order it predicts itself (column-aware XY-cut as fallback), opt-in per request
- 🔢 **Tables & formulas** — opt-in SLANet+ table → HTML and PP-FormulaNet-S formula → LaTeX, emitted alongside the text ([how to enable](#tables--formulas))
- 🔤 **Word boxes** — `?words=1` adds every word of a line with its own box, cut at the line's real ink gaps
- 🐳 **One-line Docker deploy** with TensorRT engines auto-built on first start, **Prometheus** metrics on `/metrics`
Full documentation: **[docs/](docs/index.md)**
---
## Quick Start
**Requirements:** Linux, NVIDIA driver 595+, Turing or newer GPU (RTX 20-series / GTX 16-series+). Plan for ~4 GB VRAM text-only and ~8 GB for the full pipeline (layout + tables + formulas); each extra `PIPELINE_POOL_SIZE` replica adds roughly another full set, so lower it on smaller cards.
```bash
docker run --gpus all -p 8000:8000 -p 50051:50051 \
-v trt-cache:/home/ocr/.cache/turbo-ocr \
ghcr.io/aiptimizer/turboocr:latest
```
First startup builds TensorRT engines from ONNX. This takes about 90 seconds on a
5090 GPU and up to an hour on older ones. Set `TRT_OPT_LEVEL=3` to cut build time
3 to 5x with a small speed regression. The named volume caches the engines, so
subsequent starts are instant. During the build, requests return a connection
refused error from nginx until the backend is ready. nginx (port 8000)
reverse-proxies to Drogon (port 8080), and both start automatically.
```bash
curl -X POST http://localhost:8000/ocr/raw \
--data-binary @document.png -H "Content-Type: image/png"
```
```json
{"results": [{"text": "Invoice Total", "confidence": 0.97, "bounding_box": [[42,10],[210,10],[210,38],[42,38]]}]}
```
### Start it with the stages you want
All weights are baked into the image — just set the backend env var to load a
stage (no paths needed). Layout is on by default; each extra stage still only
runs when the request asks for it.
```bash
# text + layout (default)
docker run --gpus all -p 8000:8000 -p 50051:50051 \
-v trt-cache:/home/ocr/.cache/turbo-ocr ghcr.io/aiptimizer/turboocr:latest
# + tables (→ HTML) add -e TABLE_BACKEND=slanext
# + formulas (→ LaTeX) add -e FORMULA_BACKEND=ppformulanet_s
# + both add -e TABLE_BACKEND=slanext -e FORMULA_BACKEND=ppformulanet_s
# bigger / other language add -e OCR_MODEL=medium (tiny | small | medium | arabic | eslav | korean | thai | greek)
```
Then opt in per request (combine freely; `tables`/`formulas` auto-enable layout):
```bash
curl -X POST "http://localhost:8000/ocr/raw?layout=1&tables=1&formulas=1" \
--data-binary @paper.png -H "Content-Type: image/png"
# PDF: POST /ocr/pdf · PDF → Markdown: POST /ocr/pdf?markdown=1 · page → Markdown: POST /ocr/markdown · gRPC: port 50051
```
`GET /capabilities` reports which stages a running server has loaded.
→ [Docker & deployment](docs/build/docker.md) · [Build from source](docs/build/native.md)
---
## Getting higher accuracy
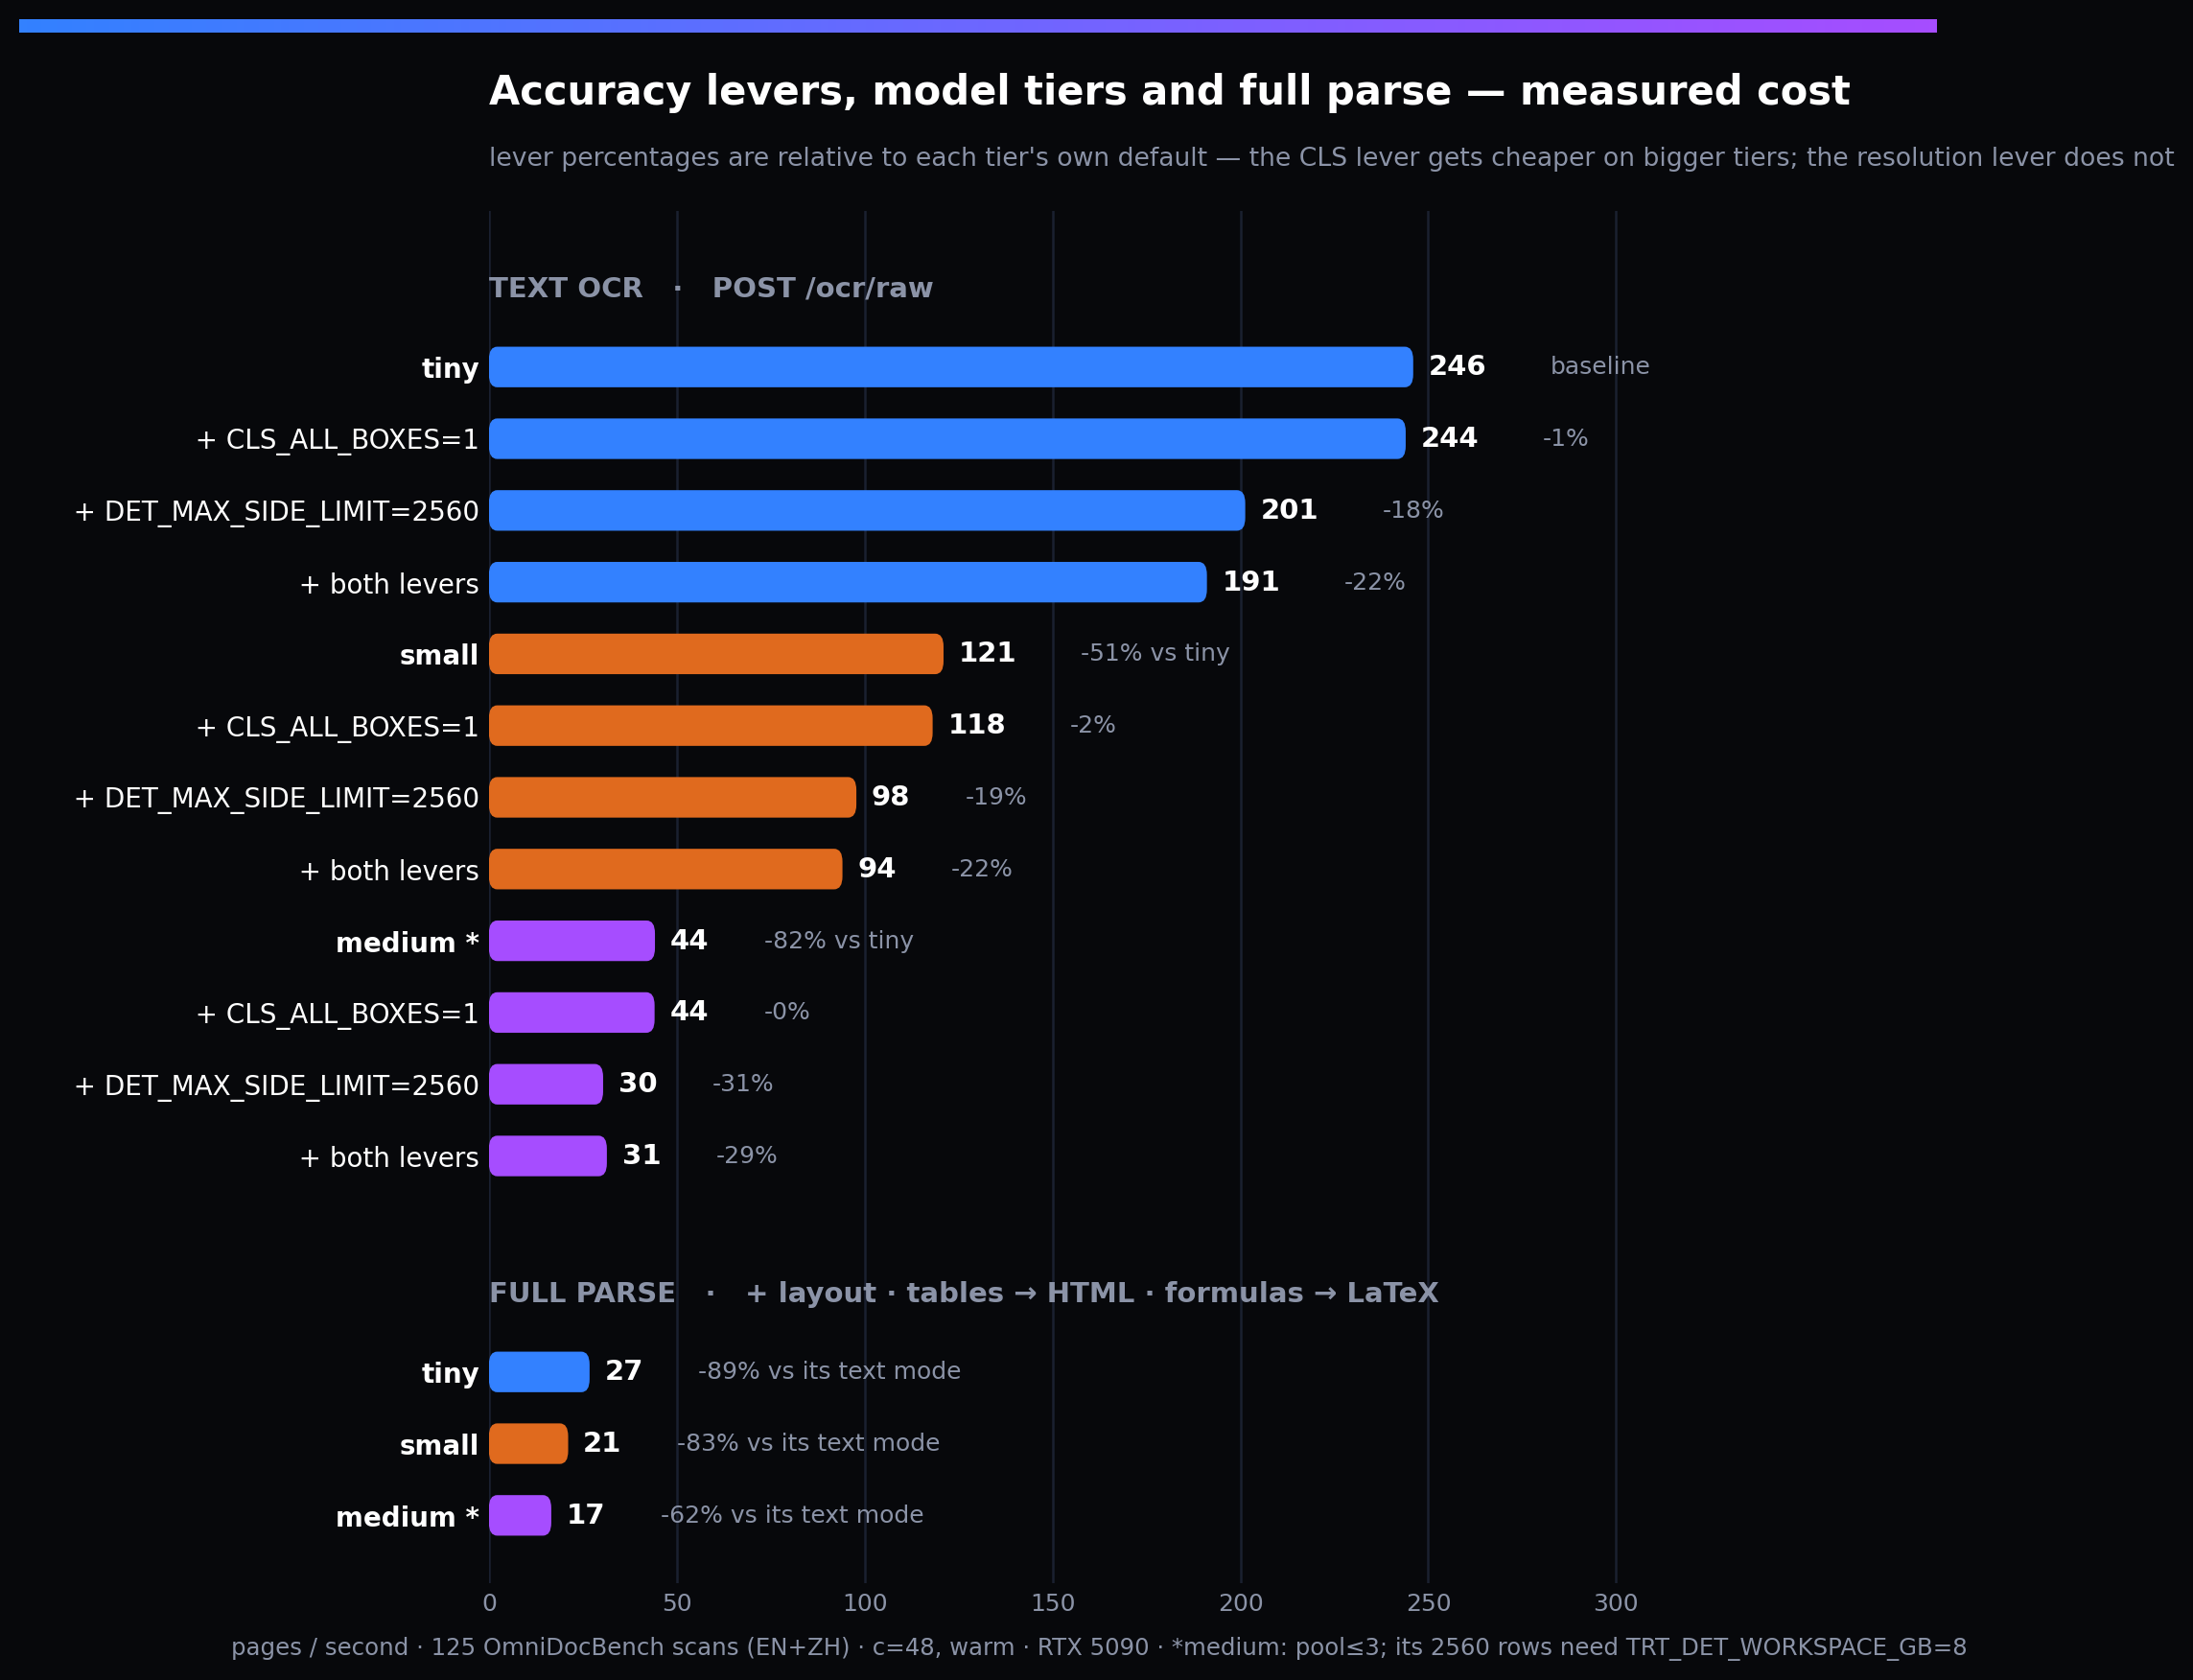
The defaults maximize throughput. Three levers trade speed for accuracy:
**1. Bigger model tier** — `-e OCR_MODEL=small` or `medium`. Same languages, same API; `small` fixes most of tiny's misreads (lost spaces, stylized fonts) at ~half the speed, `medium` is the most accurate.
**2. Higher detection resolution** — images whose long side exceeds 1280 px are downscaled before *detection* (recognition always reads full-res crops), so small text on phone screenshots or dense scans can go undetected. Raise the cap:
```bash
-e DET_MAX_SIDE_LIMIT=2560 # one-time engine rebuild, then cached
```
**3. Orientation on every line** — by default the 0°/180° classifier only checks vertical-looking lines, so an upside-down *horizontal* line is never corrected. For scans with mixed or rotated lines:
```bash
-e CLS_ALL_BOXES=1 # check every line (small throughput cost)
-e CLS_ONNX=x1_0 # optional: full-width classifier variant
```
What each of these costs, measured (every combination, plus full parse with tables + formulas):
---
## Benchmarks
On a single RTX 5090, vs every common OCR engine:
- **Forms & receipts (English):** accurate (FUNSD 92% / CORD 93% word-F1 on the medium tier) and **15–90× faster** than every other engine — up to **559 img/s** (receipts) on the default tiny tier. FUNSD/CORD are English/Latin-script datasets; the EN+ZH full-document numbers below include Chinese.
- **Full document parsing (EN+ZH):** **0.90** Overall on a **125-doc OmniDocBench subset** at **20 pages/s**, within ~5 points of PaddleOCR-VL (0.95, same subset) which runs at ~1 pg/s — fully local, no API. (Subset including Chinese pages, not the full 1651-page set.)
→ [Full benchmarks & methodology](docs/benchmarks/comparison.md)
---
## Models
The pipeline is a small stack of specialised models, not one monolith. Text
detection + recognition + line orientation always run; everything else is
opt-in and only loads when configured. Each stage links to its own model page.
| Stage | Model / arch | Size | Selected by | Docs |
|---|---|---:|---|---|
| **Text detection** | PP-OCRv6 det (DB, three tiers) | 1.7 / 9.4 / 59 MB | `OCR_MODEL` tier (`tiny`/`small`/`medium`) | [detection](docs/models/detection.md) |
| **Text recognition** | PP-OCRv6 rec (CRNN + CTC, Latin + Chinese + Japanese) | 4.3 / 20 / 73 MB | `OCR_MODEL` tier — default `tiny` | [recognition](docs/models/recognition.md) · [selection](docs/models/selection.md) |
| **Line orientation** | PP-LCNet textline angle classifier (0°/180° per line) | ~1 MB | always on (vertical lines only; every line with `CLS_ALL_BOXES=1`) | [classification](docs/models/classification.md) |
| **Page orientation** | PP-LCNet_x1_0_doc_ori (0/90/180/270 whole page) | ~7 MB | per request via `/ocr/pdf?autorotate=1` | [http api](docs/api/http.md) |
| **Layout** | PP-DocLayoutV3 (RT-DETR-L, 25 classes) | ~124 MB | per request via `?layout=1`; disable with `DISABLE_LAYOUT=1` | [layout](docs/models/layout.md) |
| **Table → HTML** | SLANet-Plus (TRT FP16 CNN encoder + hand-written C++ GRU decoder) | ~5 MB | `TABLE_BACKEND=slanext` *(encoder auto-resolved from the bundle)* | [table](docs/models/table.md) |
| **Formula → LaTeX** | PP-FormulaNet-S, in-process pure-C++ (ORT-CUDA-13, no Python) | ~294 MB | `FORMULA_BACKEND=ppformulanet_s` | [formula](docs/models/formula.md) |
The three OCR tiers (`tiny`/`small`/`medium`) trade speed for accuracy, not language
coverage — all cover Latin + Chinese + Japanese ([Getting higher accuracy](#getting-higher-accuracy)).
Other scripts use retained PP-OCRv5 recognizers, also via `OCR_MODEL`: `arabic`,
`eslav` (Cyrillic), `korean`, `thai`, `greek`. The legacy v5 Latin det/rec can also
be swapped in for A/B comparison — see [Running legacy PP-OCRv5](docs/build/legacy-ppocrv5.md).
→ [Model selection guide](docs/models/selection.md)
---
## Tables & formulas
Table and formula recognition are **strictly opt-in, per request**. The router
only loads a backend when one is configured at startup, *and* a stage runs only
when the request explicitly asks for it with `?tables=1` and/or `?formulas=1`
(gRPC: the `tables` / `formulas` request fields). `layout` alone never triggers
them, so the default path pays nothing. When requested (and a backend is loaded),
the response gains `tables` (HTML + cell quads) and/or `formulas` (LaTeX) arrays.
`tables=1`/`formulas=1` auto-enable layout. Asking for a stage the server wasn't
started with is a hard error (`400 TABLE_BACKEND_DISABLED` / `FORMULA_BACKEND_DISABLED`),
never a silent empty result — check `GET /capabilities` for what a server supports.
(`/ocr/markdown` always includes both, best-effort, since a faithful Markdown export
needs them.)
| Capability | Enable at startup | Recognizer |
|---|---|---|
| Formula → LaTeX | `FORMULA_BACKEND=ppformulanet_s` | PP-FormulaNet-S |
| Table → HTML | `TABLE_BACKEND=slanext` (encoder auto-resolved from the bundle) | SLANet-Plus |
Startup + request examples are in [Quick Start](#quick-start) above.
→ [Tables](docs/models/table.md) · [Formulas](docs/models/formula.md)
---
## Upgrading to v3
v3 renames the server binaries, moves the default engine to PP-OCRv6, and changes
several defaults (timeouts, detection resize, input caps). If you are coming from
v2.x, read the full migration guide: **[Upgrading to v3 — breaking changes](docs/build/upgrading-v3.md)**.
---
## API
One binary serves HTTP and gRPC from a shared GPU pipeline pool.
| Endpoint | Purpose |
|---|---|
| `POST /ocr/raw` | OCR raw image bytes (fastest) |
| `POST /ocr` | OCR base64 image in JSON |
| `POST /ocr/pixels` | Zero-decode raw pixel buffer |
| `POST /ocr/batch` | Batch of images |
| `POST /ocr/pdf` | PDF → text (optional page images & auto-rotate); `?markdown=1` → whole PDF as Markdown |
| `POST /ocr/markdown` | Page → faithful Markdown (GPU build; requires layout) |
| `POST /infer` | OCR + layout / reading-order / blocks in one structured response |
| `GET /capabilities` | Runtime feature & route discovery |
| `GET /metrics` | Prometheus metrics |
| `GET /health` · `/health/live` · `/health/ready` | Liveness / readiness probes |
All OCR endpoints accept `?layout=1` (region detection + reading order),
`?words=1` (word-level boxes inside every line), and `?tables=1` / `?formulas=1`
to additionally run table → HTML / formula → LaTeX on detected regions (strict
opt-in — see [Tables & formulas](#tables--formulas)).
→ [HTTP API](docs/api/http.md) · [gRPC API](docs/api/grpc.md) · [Monitoring](docs/api/monitoring.md)
---
## Configuration
Everything is configured by environment variable (and an equivalent CLI flag).
Common ones:
| Variable | Default | Description |
|---|---|---|
| `OCR_MODEL` | `tiny` | `tiny` / `small` / `medium`, or a PP-OCRv5 script model |
| `DISABLE_LAYOUT` | `0` | `1` skips the layout model (~300–500 MB VRAM) |
| `LAYOUT_MERGE_MODE` | `all` | Nested-box policy: `all` (keep every box) / `outer` (outer regions only) / `inner` (innermost only). Old `large`/`small`/`union` accepted as aliases. |
| `LAYOUT_KEEP_NESTED_CHILDREN` | `0` | Only affects `outer`/`inner` modes: `1` still keeps the model's nested child regions (`figure_title`, `footnote`, `formula_number`, `paragraph_title`) instead of dropping them inside a parent. Formulas are always kept; no effect under default `all`. |
| `CLS_ALL_BOXES` | `0` | `1` runs the 0°/180° orientation classifier on every text line instead of only vertical-looking ones — for scans with mixed or upside-down lines. |
| `REQUEST_TIMEOUT_MS` | `60000` | Per-request inference deadline; on overrun returns `504` and frees the slot. `0` = unbounded (pre-v3 behaviour). |
| `IDLE_CONNECTION_TIMEOUT_S` | `120` | How long one HTTP request may run (the server and the bundled nginx close a connection silent that long); raise it for long PDFs, `0` = no limit |
| `PIPELINE_POOL_SIZE` | auto | Concurrent GPU pipelines |
→ [Full configuration reference (35+ variables)](docs/build/config.md)
---
## Building from Source
```bash
# Docker (recommended)
docker build -f docker/Dockerfile.gpu -t turboocr .
docker run --gpus all -p 8000:8000 -p 50051:50051 \
-v trt-cache:/home/ocr/.cache/turbo-ocr turboocr
# Native (PP-OCRv6 models auto-fetched into ./models/ on first build)
cmake -B build # finds CUDA and TensorRT itself; -DTENSORRT_DIR= to point at an unpacked tarball
cmake --build build -j$(nproc)
LD_LIBRARY_PATH=/usr/local/tensorrt/lib ./build/turboocr-server
```
Needs GCC 13.3+/C++20, CUDA + TensorRT 10.2+, OpenCV 4.x, Drogon 1.9+, gRPC.
Wuffs and PDFium are vendored in `third_party/`.
→ [Build guide & GPU-architecture notes](docs/build/native.md)
---
## Acknowledgements
Built on open-source work:
- **[PaddleOCR](https://github.com/PaddlePaddle/PaddleOCR)** (Baidu) — PP-OCRv6 / PP-OCRv5 detection, recognition, and classification models, plus PP-DocLayoutV3 layout detection. This project would not exist without their research and pre-trained weights.
- **[Drogon](https://drogon.org)** — high-performance async C++ HTTP framework.
- **[Wuffs](https://github.com/google/wuffs)** — fast PNG decoder by Google (vendored).
- **[PDFium](https://pdfium.googlesource.com/pdfium/)** — PDF rendering and text extraction (vendored).
## License
MIT. See [LICENSE](LICENSE).
⭐ Star TurboOCR on GitHub
Sponsored by Miruiq — AI-powered data extraction from PDFs and documents — and DiaIQ.