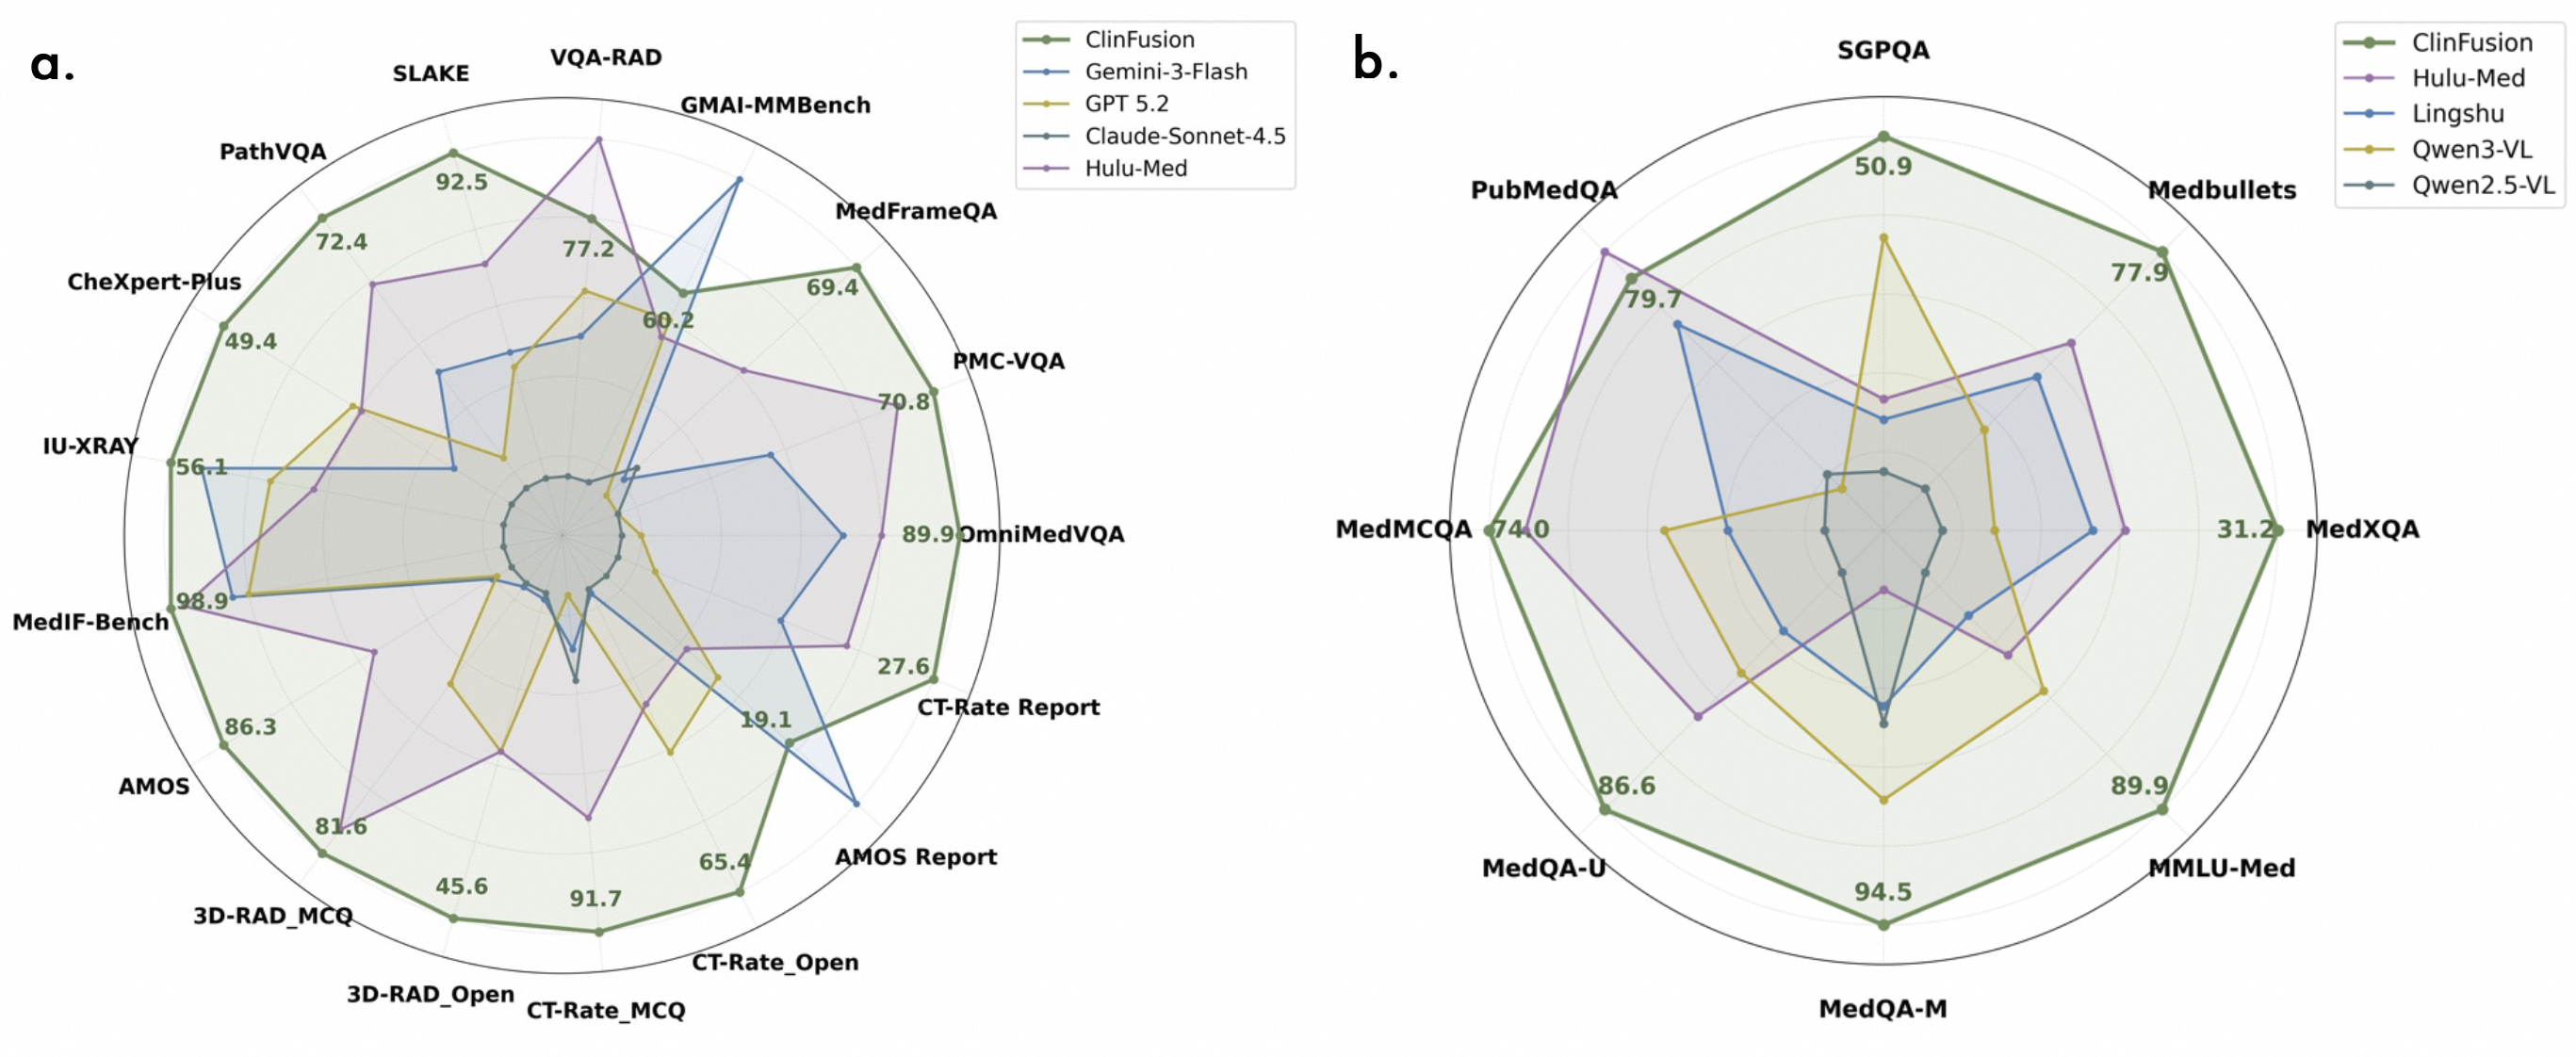
(a) Performance on multimodal medical benchmarks. (b) Performance on text-only medical benchmarks.
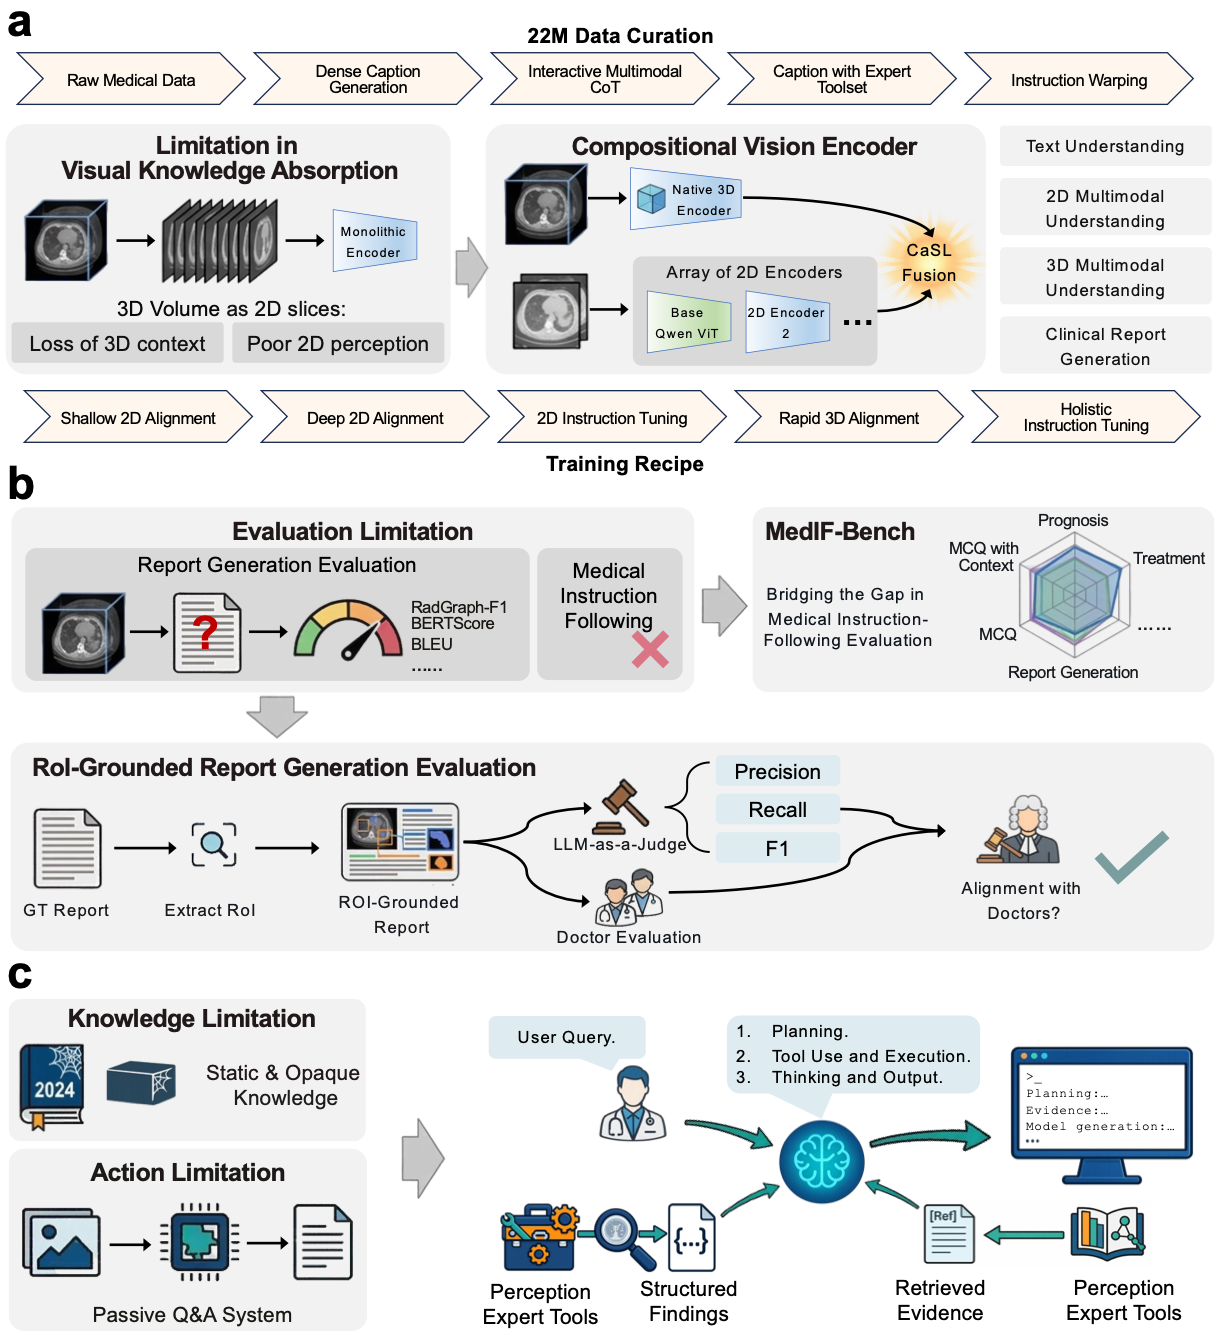
(a) Data curation, compositional vision encoder, and training recipe. (b) Vision-grounded evaluation framework (MedIF-Bench and RoI-grounded report evaluation). (c) Agentic tool use for retrieval-augmented clinical workflows.
--- ## 🔥 News - **[2026-08-16]** 📦 The full evaluation suite is out! We have released **ClinFusion-Eval-Data** on [](https://huggingface.co/datasets/Alibaba-DAMO-Academy/ClinFusion-Eval-Data) — 211K evaluation records over 22 medical benchmarks, plus the 509 GiB media archive of 2D images and native 3D CT volumes for one-command reproduction. 🔬 - **[2026-07-29]** 🔥 Try ClinFusion-8B in your browser! [](https://huggingface.co/spaces/Alibaba-DAMO-Academy/clinfusion-medical-vlm) — no installation required. 🕹️ (Both English and Chinese are supported but English might be better.) - **[2026-07-28]** 🎉 Our paper **ClinFusion: A Vision-Centric Multimodal LLM System for Holistic Medical Understanding** is now on [arXiv](https://arxiv.org/abs/2607.24743)! We have open-sourced the code and released the model weights (ClinFusion-8B / ClinFusion-32B) on [Hugging Face](https://huggingface.co/collections/Alibaba-DAMO-Academy/clinfusion). 🚀 --- ## 📋 Table of Contents - [🔧 Installation](#-installation) - [📥 Model Download](#-model-download) - [📊 ClinFusion-Eval-Data Download](#-clinfusion-eval-data-download) - [📈 Running ClinFusion-Eval](#-running-clinfusion-eval) - [🚀 Model Inference with Your Own Data](#-model-inference-with-your-own-data) - [🛠️ More Customized Usage](#️-more-customized-usage) - [📄 Related Projects (Clin Series)](#-related-projects) - [📄 Citation](#-citation) - [🙏 Acknowledgements](#-acknowledgements) --- ## 🔧 Installation ### Prerequisites: Download Pre-built Flash-Attention Flash-Attention cannot be installed directly via pip and must be provided as a pre-built wheel. Download the wheel that matches your environment from: > **https://mjunya.com/flash-attention-prebuild-wheels/** Choose the wheel matching your **CUDA version**, **PyTorch version**, and **Python version** (e.g., `flash_attn-2.8.3+cu128torch2.8-cp311-cp311-linux_x86_64.whl` for CUDA 12.8 + PyTorch 2.8 + Python 3.11), and place it in the **project root directory**. Make sure the filename in `requirements.txt` matches the wheel you downloaded. If not, update the last line of `requirements.txt` accordingly. ### One-Click Install We provide an installation script that automatically sets up the environment using [`uv`](https://github.com/astral-sh/uv): ```bash # Install and activate in one step source install_from_scratch.sh # Or install only (prints activation command afterwards) bash install_from_scratch.sh ``` The script will: 1. Install the `uv` package manager (if not already installed) 2. Create a Python 3.11 virtual environment (you should specify the environment path first `ENV_DIR` in `install_from_scratch.sh`) 3. Validate local wheel paths and install all dependencies from `requirements.txt` --- ## 📥 Model Download ### Prerequisites: Download Vision Encoders ClinFusion uses multiple vision encoders. Please download them first: ```bash export HF_ENDPOINT=https://hf-mirror.com # 🦕 DINOv2 huggingface-cli download --resume-download facebook/dinov2-large \ --repo-type model \ --local-dir cache/models/dinov2-large # 🔬 ConvNeXt huggingface-cli download --resume-download laion/CLIP-convnext_large_d_320.laion2B-s29B-b131K-ft-soup \ --repo-type model \ --local-dir cache/models/CLIP-convnext_large_d_320.laion2B-s29B-b131K-ft-soup ``` ### Download Base LLM ```bash export HF_ENDPOINT=https://hf-mirror.com # Qwen3-VL-8B-Instruct (for 8B model) huggingface-cli download --resume-download Qwen/Qwen3-VL-8B-Instruct \ --repo-type model \ --local-dir cache/models/Qwen3-VL-8B-Instruct # Qwen3-VL-32B-Instruct (for 32B model) huggingface-cli download --resume-download Qwen/Qwen3-VL-32B-Instruct \ --repo-type model \ --local-dir cache/models/Qwen3-VL-32B-Instruct ``` ### Download ClinFusion Checkpoints ```bash export HF_ENDPOINT=https://hf-mirror.com # ClinFusion-8B huggingface-cli download --resume-download Alibaba-DAMO-Academy/ClinFusion-8B \ --repo-type model \ --local-dir cache/models/ClinFusion-8B # ClinFusion-32B huggingface-cli download --resume-download Alibaba-DAMO-Academy/ClinFusion-32B \ --repo-type model \ --local-dir cache/models/ClinFusion-32B ``` --- ## 📊 ClinFusion-Eval-Data Download The evaluation annotations (the four `*.jsonl` files) already ship with this repository under `eval/Evaluation/datasets/`. The media they reference — 2D images and native 3D CT volumes — are released separately on the Hub as [ClinFusion-Eval-Data](https://huggingface.co/datasets/Alibaba-DAMO-Academy/ClinFusion-Eval-Data), split into 102 shards of `mm_data.tar` (509.25 GiB in total, since the Hub caps single files at 50 GB). ### Step 1: Download the media shards ```bash export HF_ENDPOINT=https://hf-mirror.com huggingface-cli download --resume-download Alibaba-DAMO-Academy/ClinFusion-Eval-Data \ --repo-type dataset \ --local-dir cache/data ``` ### Step 2: Reassemble and extract ```bash cd cache/data cat mm_data.tar.part-* | wc -c # expect 546797690880 cat mm_data.tar.part-* | tar xf - # -> cache/data/mm_data/ ``` ### Step 3: Point the evaluation at the media Media paths inside the jsonl files are relative (`mm_data/...`) and are resolved from the repository root, so link the extracted tree there: ```bash cd ClinFusion ln -s cache/data/mm_data mm_data ``` > [!TIP] > Reassembly needs ~1 TB of free space while the shards and the extracted tree coexist; delete `mm_data.tar.part-*` once extraction succeeds to halve that. Both the download and the extraction can be resumed by re-running the same commands. --- ## 📈 Running ClinFusion-Eval ### Step 1: Configure API Keys and Python Path Fill in the API keys in `eval/api_keys/api_key.ak`. Modify the `base_url:` in your yaml file to specify the base URL of the API. Modify the python path `python_executable:` in your yaml file to specify the python path in your environment. ### Step 2: Run Evaluation ```bash cd ClinFusion ``` | Benchmark Type | Command | |---|---| | 🖼️ **2D & Textual** | `bash eval/tools/launch_eval_clinfusion_2d_general.sh` | | 🧊 **3D Volumetric** | `bash eval/tools/launch_eval_clinfusion_3d.sh` | | 📝 **Instruction-Following** | `bash eval/tools/launch_eval_clinfusion_if.sh` | > [!TIP] > **3D evaluation can be time-consuming.** We provide a **lite version** for faster iteration. Switch by modifying `eval_data_path` in `eval/Evaluation/config_templates/clinfusion/config_3d_clinfusion.yaml`: > > ```yaml > # Full version > eval_data_path: "eval/Evaluation/datasets/3d_eval_data_ct-rate_amos_3d-rad.jsonl" > # Lite version (recommended for quick testing) > eval_data_path: "eval/Evaluation/datasets/3d_eval_data_ct-rate_amos_3d-rad_lite.jsonl" > ``` --- ## 🚀 Model Inference with Your Own Data This section explains how to run ClinFusion inference on your own data. Before running, modify `python_executable:` in your YAML config file to point to your Python environment. ### 📝 Data Format All input data should be in **JSONL format** (one JSON object per line). Each entry must contain a `messages` field with the following structure: ```json { "messages": { "prompt": "Your question or instruction here.", "image": ["path/to/image1.jpg", "path/to/image2.png"], "nifti": ["path/to/volume.nii.gz"] } } ``` - **`prompt`** *(required)*: The text query or instruction for the model. - **`image`** *(optional)*: A list of paths to 2D image files (e.g., `.jpg`, `.png`). Omit this field for text-only or 3D-only inputs. - **`nifti`** *(optional)*: A list of paths to 3D NIfTI volumes (`.nii.gz`). Omit this field for text-only or 2D-only inputs. > [!NOTE] > You can include any additional fields (e.g., `source`, `index`, `ground_truth`) in each JSON object for your own bookkeeping — they will be preserved in the output file alongside the model's generation. ### 🖼️ 2D Medical Images Prepare a JSONL file where each line contains a `messages` field with `prompt` and `image`: ```json {"messages": {"prompt": "What imaging modality was used in the diagnosis?\nA. X-ray\nB. Ultrasound\nC. MRI\nD. CT scan\n\nPut your final single letter choice in \\boxed{}.", "image": ["assets/example_data/PMC3610355_fig14.jpg"]}} {"messages": {"prompt": "Where does the image represent in the body?", "image": ["assets/example_data/xmlab508_source.jpg"]}} ``` It is placed in `eval/test/example_data_2d_general.jsonl`. Then create a YAML config file (see `eval/test/test_clinfusion_2d_general.yaml` as a template) and run: ```bash cd ClinFusion bash eval/tools/launch_inference.sh eval/test/test_clinfusion_2d_general.yaml ``` Key config fields to modify: | Field | Description | |---|---| | `python_executable` | Path to your Python binary | | `input_data_path` | Path to your JSONL data file | | `final_output_path` | Directory for output results | | `model_path` | Path to store the ClinFusion checkpoint | ### 💬 Language-Only (Text) For text-only questions (no images), simply omit both `image` and `nifti` fields: ```json {"messages": {"prompt": "A 41-year-old man presents to his primary care provider after seeing bright red blood in the toilet bowl after his last 2 bowel movements. He reports that he also noticed some blood mixed with his stool. The patient denies abdominal pain or any changes in his stool habits. He notes a weight loss of 8 pounds in the last 2 months with no changes in his diet or exercise habits. Which of the following is the most appropriate next step in management?\nA. Abdominal CT\nB. Colonoscopy\nC. Ultrasound of abdomen\nD. Barium enema"}} ``` It is placed in `eval/test/example_data_2d_general.jsonl`. Run with the same 2D general config: ```bash cd ClinFusion bash eval/tools/launch_inference.sh eval/test/test_clinfusion_2d_general.yaml ``` ### 🧊 3D Volumetric Data For 3D CT/MRI volumes, use the `nifti` field instead of `image`. ClinFusion automatically converts NIfTI volumes into 2D slices for processing via `nifti_to_image_slices`. ```json {"messages": {"prompt": "What can be inferred about the left iliac artery from the CT image?\nA. There is a significant dilation\nB. It is obscured by nearby structures\nC. It extends into an intramural hematoma\nD. There is a discontinuity in the vessel wall", "nifti": ["assets/example_data/amos_0326.nii.gz"]}} ``` It is placed in `eval/test/example_data_3d.jsonl`. Run with the 3D config: ```bash cd ClinFusion bash eval/tools/launch_inference.sh eval/test/test_clinfusion_3d.yaml ``` ### 📤 Output Format Results are saved to `