## Overview
**skill-up** is a CLI for evaluating Agent Skills, agents, and their workspaces. It runs declarative cases against an Agent Engine, grades the response and workspace changes, and produces reports locally or in CI.
- **Skill evaluation** measures a Skill's behavior across cases and can compare runs with and without the Skill.
- **Agent evaluation** runs the same cases without installing a Skill, so you can assess an engine or custom agent on its own.
- **Workspace evaluation** checks how an agent works with files and repositories, using case fixtures or an existing local workspace.
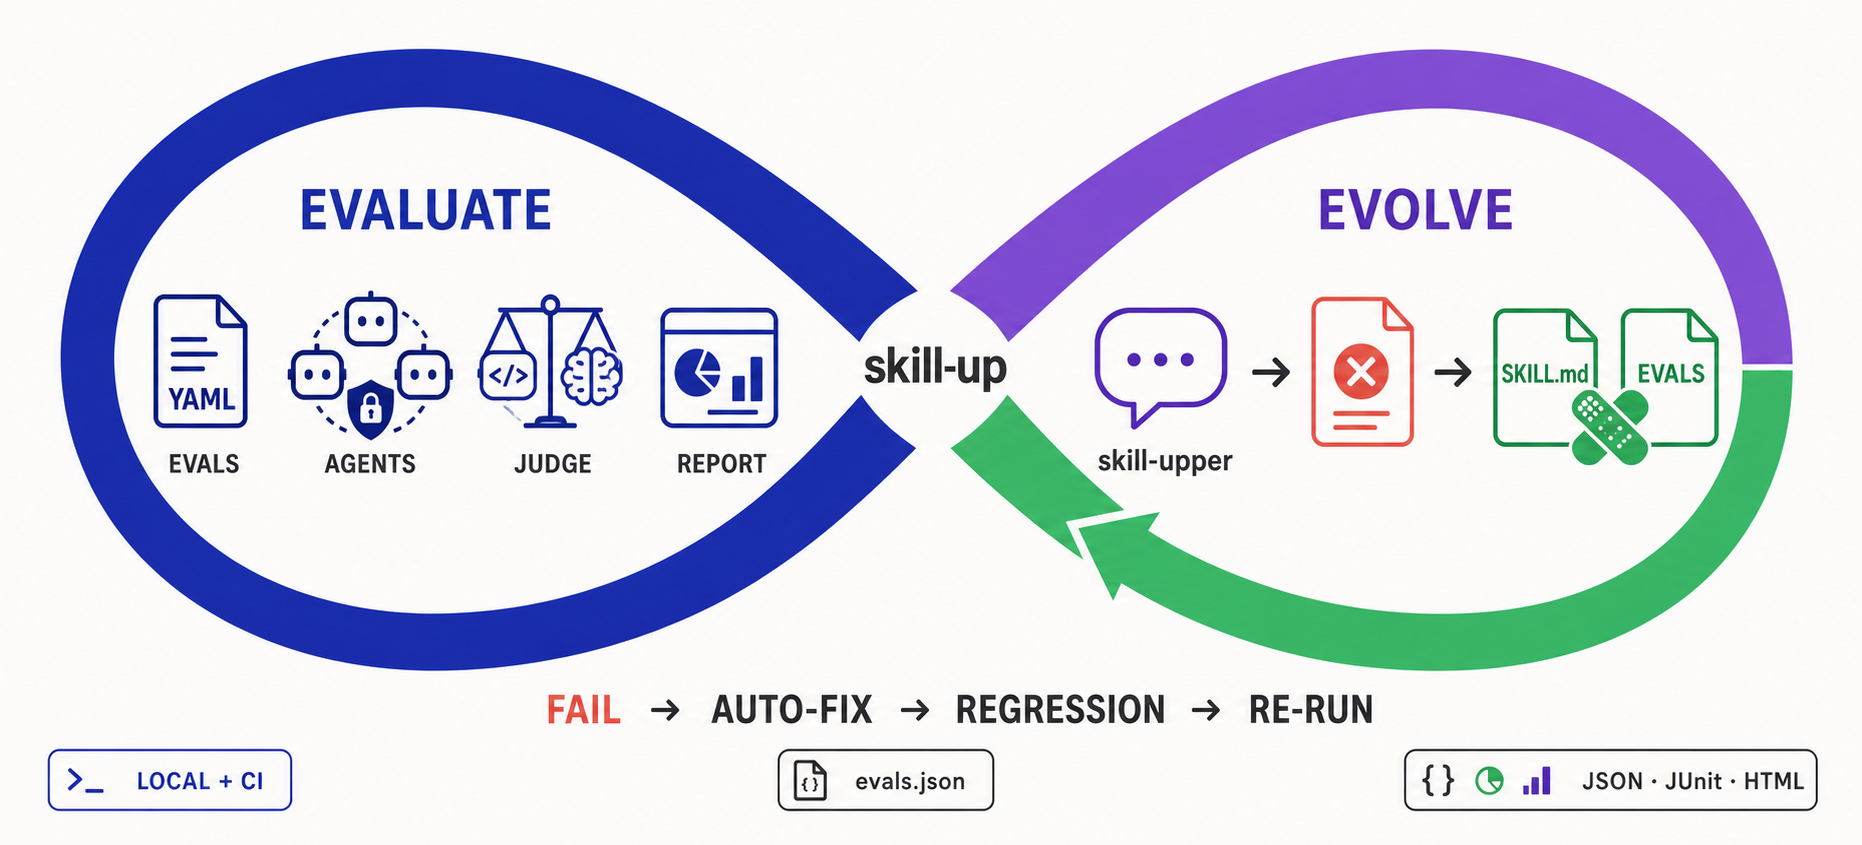
- **Skill evolution** uses **skill-upper** to inspect failures, repair or expand the eval suite, and rerun skill-up through conversation.
## Features
- **Eval-to-Evolution Loop with skill-upper**: Create evals through natural conversation, diagnose failures, automatically repair or expand cases, and rerun skill-up until the eval suite evolves.
- **Declarative Eval Config**: Define evaluation environment, engine, model, and cases through YAML (`eval.yaml` + `cases/*.yaml`).
- **Environment Provisioning**: Prepare a local, Docker, or OpenSandbox runtime for each case, install configured real or mocked MCP servers into supported Agent Engines, and upload `context.repo_fixture` and `context.files` into the workspace.
- **Skill-Optional Runs and Workspace Cases**: Evaluate an agent without a Skill, prepare repository fixtures per case, or run against an existing local workspace with `--workspace`.
- **Multi-Engine Support**: Works with Qoder CLI, Claude Code, and Codex as built-in Agent Engines, plus user-defined agents via `engine.custom` (local commands or HTTP services — see [docs/design/custom-engine.md](docs/design/custom-engine.md)).
- **DeepSeek Harness Plugin**: Use the bundled `skill-upper` Skill, opt-in durable observation capture, approval-gated regression cases, isolated runs, and status comparison to verify evidence-backed Skill improvements. See [`plugins/dsh-skill-up`](plugins/dsh-skill-up/README.md).
- **Multi-Turn Conversations and User Simulation**: Run fixed turns, mix scripted and simulated replies, or let an independent user model drive follow-ups and decide when to stop.
- **Role-Specific Engines and Models**: Configure the evaluated agent, Agent Judge, and user simulator separately, including independent judging of custom agents.
- **Flexible Judging**: Supports `rule_based`, `script`, and `agent_judge` evaluation strategies.
- **Structured Reports**: Outputs Anthropic-compatible `grading.json`, `benchmark.json`, `benchmark.md`, plus `result.json`, JUnit XML, and HTML reports.
- **Anthropic Compatible**: Import `evals.json` via `skill-up import`, or auto-detect with `--auto`.
- **CI-Ready**: Designed for local development and continuous integration pipelines.
## Why skill-up
[Harness engineering](https://openai.com/index/harness-engineering/) treats an agent's environment, tools, constraints, and feedback loops as parts of the system to design and improve. [Behavioral evals](https://developers.googleblog.com/the-anatomy-of-harness-engineering-how-to-evaluate-iterate-and-guard-ai-coding-agents/) make expected agent actions observable and help catch regressions. `skill-up` contributes evaluation and feedback to this work: repeatable prompts and workspace setups, checks on responses, tool calls, and file changes, and structured reports.
For Skills, the official [Agent Skills evaluation guide](https://agentskills.io/skill-creation/evaluating-skills) describes a further loop: run with and without the Skill, grade outputs, aggregate results, and iterate. `skill-up` supports these workflows:
- Replaces ad hoc run folders with a declarative `eval.yaml` + `cases/*.yaml` format.
- Closes the improvement loop: skill-upper can interpret failed reports, repair or add eval cases, and drive the next skill-up run through conversation.
- Automates workspace setup, optional Skill installation, Agent Engine invocation, judging, and report generation.
- Supports multiple engines (`claude_code`, `codex`, `qodercli`, `qwen_code`) instead of tying the workflow to one client.
- Keeps compatibility with Anthropic-style `evals.json` while adding richer judges, CI-friendly commands, and structured reports.
## Quick Start: Evolve a Skill with skill-upper
For Skill evolution, use **skill-upper**, the Agent Skill shipped in this
repository. It lets your AI agent create evals, run skill-up,
understand failures, fix the Skill or its evals, add regression coverage, and
repeat the loop through conversation.
For repository development, `skills/skill-upper/` is the only editable source.
Plugin bundles are generated into ignored build directories rather than tracked
copies or symlinks; run `make bundle-plugins` when preparing them locally.
`make package-plugins VERSION=