Molmo 2: State-of-the-art video understanding, pointing, and tracking


This repository is for training and using Ai2's open vision language models, Molmo2 and MolmoPoint.
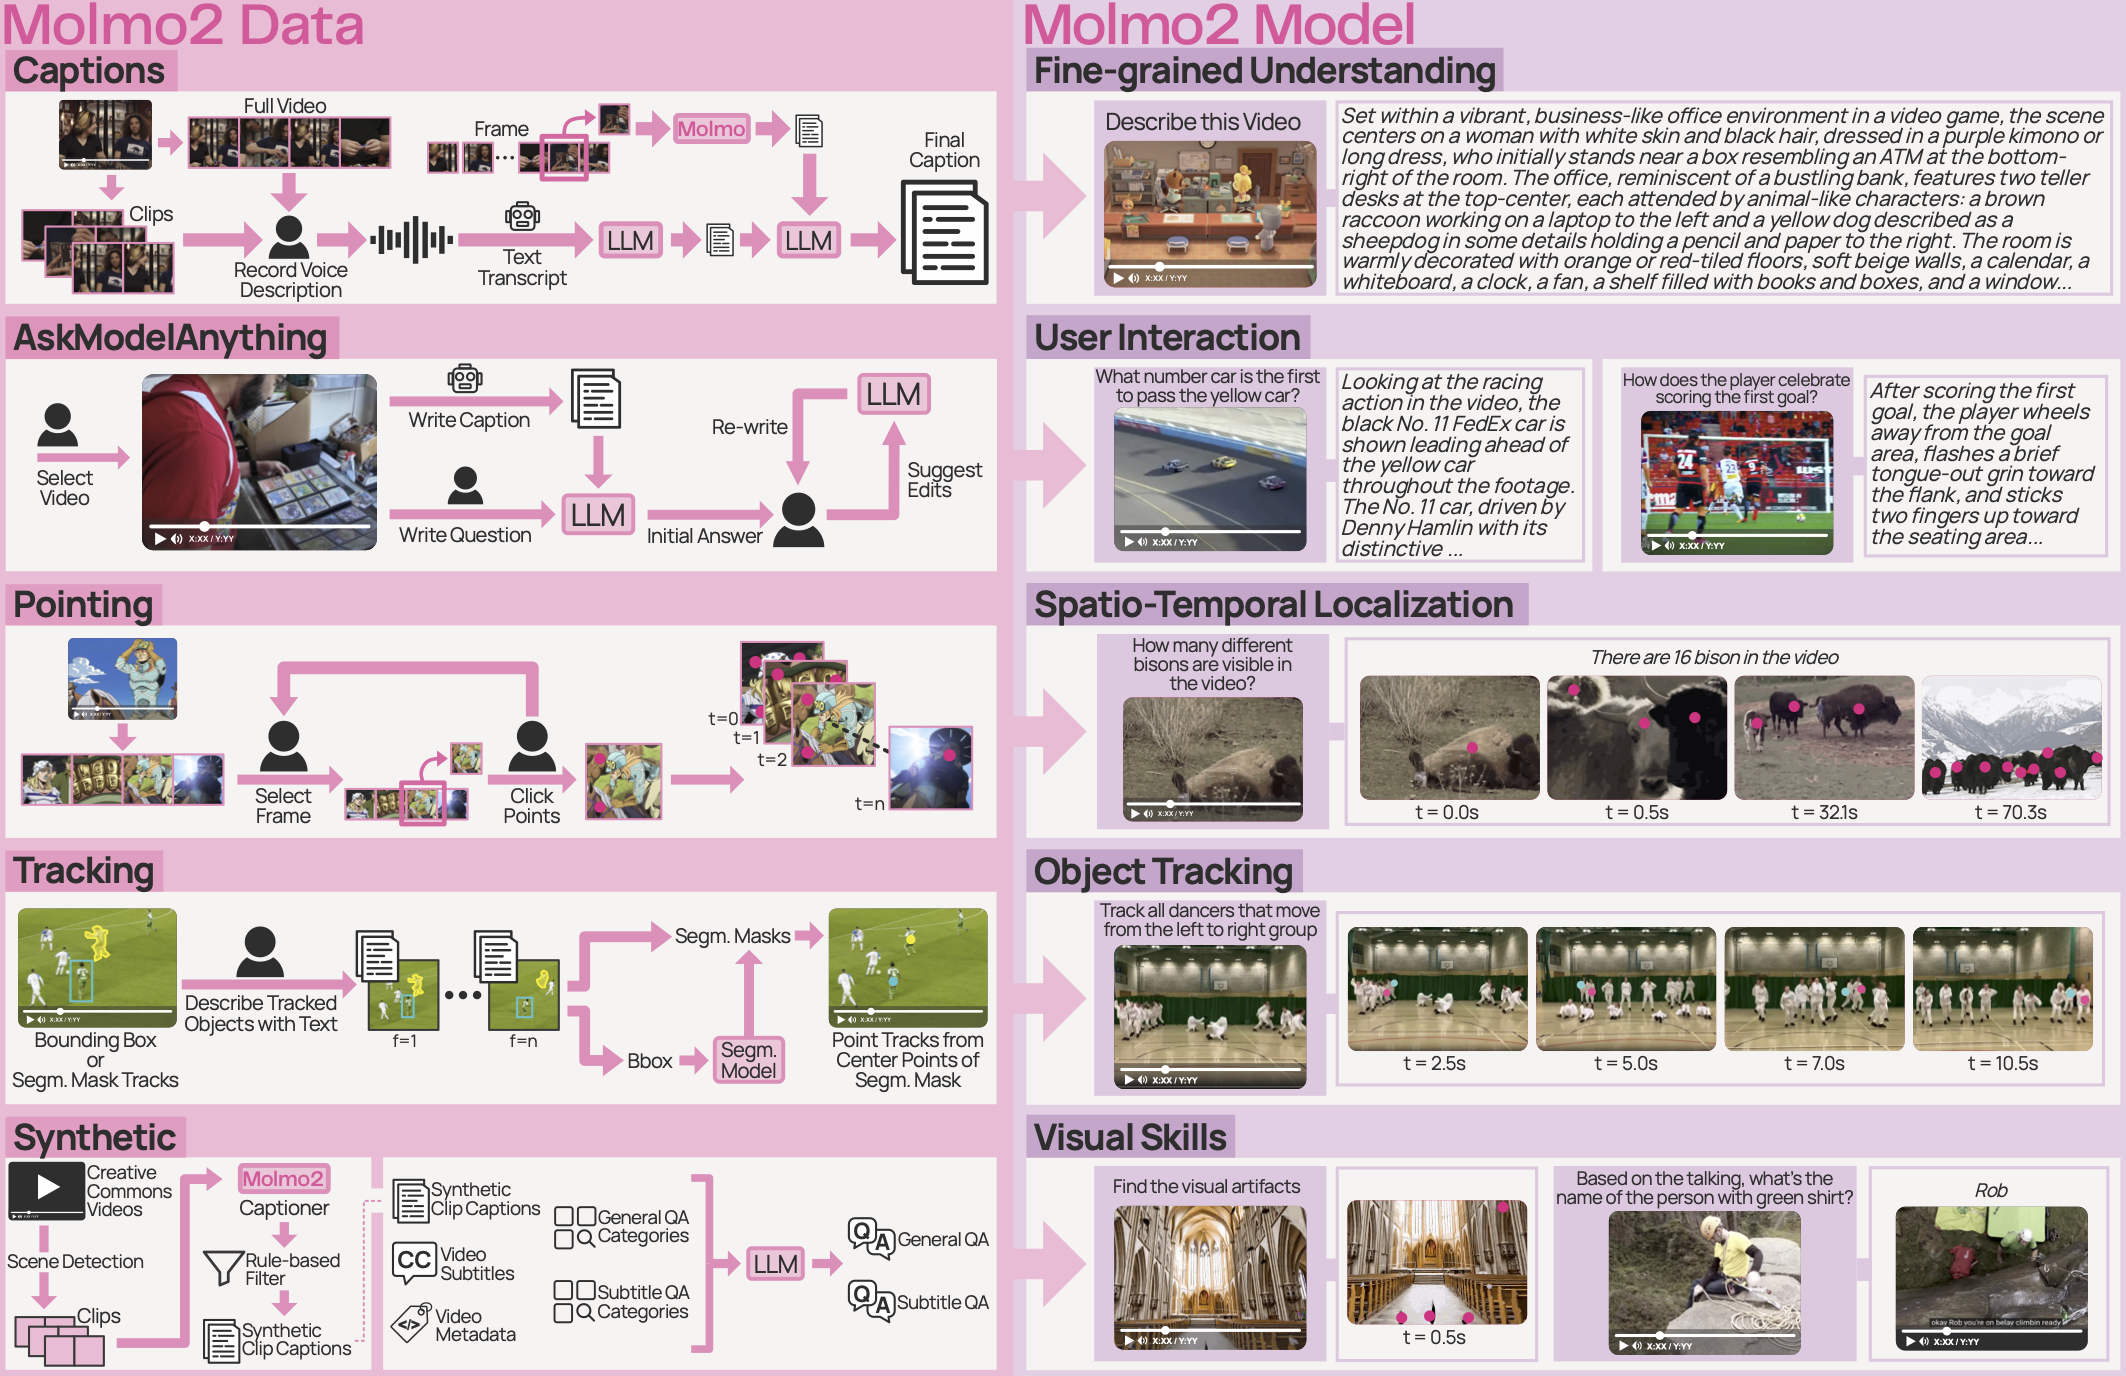
Molmo2 is state-of-the-art among open-source models and demonstrates exceptional new capabilities in point-driven grounding in single image, multi-image, and video tasks as shown below.
MolmoPoint is an extension with a new architecture for pointing.
This README is mostly concerned with Molmo2, see [MolmoPoint](MOLMO_POINT_README.md)
for how to train MolmoPoint.
See our [blog post](https://allenai.org/blog/molmo2) or our [paper](https://arxiv.org/abs/2601.10611) for more details about Molmo2.
Huggingface models can be found [here](https://huggingface.co/collections/allenai/molmo2).
## Table of Contents
- [Setup](#setup)
- [Installation](#installation)
- [Docker](#docker)
- [Downloading Data](#downloading-data)
- [Downloading Pretrained Models](#downloading-pretrained-models)
- [Visualizing Data](#visualizing-data)
- [Environment](#environment)
- [Training and Evaluations](#training-and-evaluations)
- [Checkpoints](#checkpoints)
- [Pre-Training](#pre-training)
- [SFT Training](#sft-training)
- [Long-Context SFT Training](#long-context-sft-training)
- [Evaluation](#evaluation)
- [Context Parallel](#context-parallel)
- [Transformers and vLLM](#transformers-and-vllm)
- [Convert Checkpoint to Hugging Face Format](#convert-checkpoint-to-hugging-face-format)
- [Transformers Inference](#transformers-inference)
- [Image Inference Example](#image-inference-example)
- [Video Inference Example](#video-inference-example)
- [MolmoPoint Transformers Inference](#molmopoint-transformers-inference)
- [Image Inference Example](#image-inference-example)
- [Video Inference Example](#video-inference-example)
- [Fast Inference with vLLM](#fast-inference-with-vllm)
- [Install Vision Process Package](#install-vision-process-package)
- [Install vLLM (\>= 0.15.0)](#install-vllm--0150)
- [Run vLLM inference (Gradio Demo)](#run-vllm-inference-gradio-demo)
- [Code](#code)
- [Data Pipeline](#data-pipeline)
- [Message Trees](#message-trees)
- [Packing](#packing)
# Setup
## Installation
We recommend using python >= 3.11
First install [PyTorch](https://pytorch.org) according to the instructions specific to your operating system.
To install dependencies, run:
```bash
git clone https://github.com/allenai/molmo2.git
cd molmo2
pip install torchcodec
pip install -e .[all]
```
It's recommended to install torchcodec separately since it has some complex dependencies that
can break if installed in combination with the others as done using `install -e .[all]`
### Docker
We provide a container with the dependencies (but not the code) pre-installed, pull it with:
`docker pull ghcr.io/allenai/molmo2:latest`
## Downloading Data
Molmo2 uses a mix of huggingface datasets and custom data stored in `MOLMO_DATA_DIR`.
For example, if you want to store the data in `/data/molmo` you could set
```bash
export MOLMO_DATA_DIR=/data/molmo
export HF_HOME=/data/molmo/huggingface
```
See [here](https://huggingface.co/docs/huggingface_hub/guides/manage-cache) for more info on where the huggingface data is stored.
We provide a script to download most datasets:
```bash
python3 scripts/download_datasets.py all --n_proc 8
```
Downloading can be resumed if canceled or an error occurs mid-download.
Some datasets need to be manually downloaded, often due licensing agreements. See the relevant classes
for their locations and download instructions. These include:
- DocQA, InfoQA, and SceneText need to be downloaded from https://rrc.cvc.uab.es.
- LVBench needs to be downloaded from https://huggingface.co/datasets/zai-org/LVBench.
- MLVU and LongVideoBench have HuggingFace user agreements that must be accepted before the download scripts will work
- The nturgbd subset of MVBench needs to be manually downloaded.
- Tracking datasets that require manual download: Ref-YT-VOS, YTVIS, ReVOS, LaSOT, Molmo2VideoTrack, and etc. See `olmo/data/academic_video_track_datasets.py` and `olmo/data/molmo2_video_track_datasets.py` for download instructions.
The download scripts will throw an error and provide instructions if those files are not found.
To download a specific dataset provide the dataset or class name as follows:
```bash
python3 scripts/download_datasets.py ChartQa --n-procs 12
```
You can also **download by group**:
```bash
# Download image academic benchmarks
python3 scripts/download_datasets.py image_academic
# Download multiple specific datasets
python3 scripts/download_datasets.py text_vqa doc_qa chart_qa
# Download video academic benchmarks
python3 scripts/download_datasets.py video_academic
# Download all video tracking datasets (MOT + SOT)
python3 scripts/download_datasets.py video_tracking --n-procs 8
```
Available groups: `image_academic`, `video_academic`, `pixmo`, `image_pointing`, `video_pointing`, `video_tracking`, `demo`.
## Downloading Pretrained Models for Training from scratch
Pretrained models can be downloaded and prepared with `scripts/prepare_pretrained_model.py`
For example:
```bash
python scripts/prepare_pretrained_model.py qwen3_4b_instruct
python scripts/prepare_pretrained_model.py siglip2
```
This will download the checkpoint, convert it into a compatible format, and save a sharded version
in the location specified by the corresponding config `olmo/model_configs.py` for fast loading.
## Visualizing Data
Once downloaded, datasets can be visualized by using the `scripts/dataset_visualize.py` script:
```bash
python3 scripts/dataset_visualize.py chart_qa /path/to/viz/dir
```
This script will build a HTML file to show what the data looks like after pre-processing.
## Environment
Generally training runs should use these flags:
```
HF_DATASETS_OFFLINE=1
OLMO_SHARED_FS=1
HF_ACCESS_TOKEN=YOUR_HF_KEY
OPENAI_API_KEY=YOUR_OPENAI_API_KEY
WANDB_API_KEY=YOUR_WANDB_KEY
OMP_NUM_THREADS=8
```
`HF_DATASETS_OFFLINE` stops HF from sending tons of requests to the HF dataset hub even though the data
is already download.
`OLMO_SHARED_FS` tell the codes to assume, for multi-nodes jobs, you are saving to a shared
file system.
`HF_ACCESS_TOKEN` might be used to download the tokenizer, `OPENAI_API_KEY` might be used in some evaluations,
and `WANDB_API_KEY` is for wandb logging.
`OMP_NUM_THREADS` is for torch.
# Training and Evaluations
Molmo2 training has three stages:
1. **Pre-Training** — Train on image captioning, NLP, and image pointing using `launch_scripts/pretrain.py`. Start from pretrained LLM + ViT weights.
2. **SFT** — Multitask supervised fine-tuning on the full mixture (QA, pointing, tracking, video, etc.) using `launch_scripts/sft.py`. Start from a pretrained checkpoint.
3. **Long-Context SFT** — Continue SFT with longer sequences (36k+ tokens, 384 frames) for improved video understanding. Uses the same `launch_scripts/sft.py` with increased `--seq_len`.
Each stage produces a checkpoint that feeds into the next. We release checkpoints at each stage (see below).
## Checkpoints
We release model weights after pre-training, SFT, and long-context SFT in a format compatible
with this codebase. The Long-Context SFT Checkpoint matches the hugging face repo checkpoints,
but have a slightly different format. The config files are backwards-compatible with
this repo but might not match exactly.
To use these checkpoints download them, untar them, and they can be evaluated or used as a starting point for fine-tuning.
For example:
```
wget https://storage.googleapis.com/oe-training-public/Molmo2-1225/Molmo2-8B.tar
tar -xf Molmo2-8B.tar
```
## Pre-Training
The main pretraining script is `scripts/run_trainer.py`. To train a model you can either construct a config
file to pass to it, or call one of the higher-level scripts in `launch_scripts` which
will construct a low-level config from some higher-level settings and then invoke the train script for you.
For pretraining, we use `launch_scripts/pretrain.py`. This will run the first stage of training on
image captioning, NLP, and image pointing - see the paper for details.
To start a debugging run:
```bash
torchrun --nproc-per-node=1 launch_scripts/pretrain.py debug --save_folder=/path/to/save/folder
```
To train with the Qwen3 4B Instruct LLM and the SigLIP vision encoder:
```bash
WANDB_API_KEY=key torchrun --nproc-per-node=8 launch_scripts/pretrain.py qwen3_4b_instruct \
--wandb.name=run_name --wandb.entity=entity --wandb.project=project \
--save_folder=/path/to/save/folder
```
Molmo2-8B uses `qwen3_8b`, Molmo2-4B uses `qwen3_4b_instruct`, and Molmo2-O-7B uses `olmo3_7b_instruct`.
Under-the-hood, the `launch_scripts/pretrain.py` constructs a `TrainerConfig` object
and then runs it. For fine-grained control, CLI args can be used to override parts of
the `TrainerConfig`, for example, to run without wandb, use:
```bash
torchrun --nproc-per-node=8 launch_scripts/pretrain.py qwen2_7b \
--wandb=null --save_folder=/path/to/save/folder
```
See `TrainerConfig` for a full list of configurable args.
The script defaults matches Molmo 2's default, the `LLM` flags determines which version of Molmo 2
is being trained.
Note: use `--data.num_workers=1` if you encounter a DataLoader "Bus error" (or increase shared memory)
## SFT Training
Multitask training can be done with `launch_scripts/sft.py`, for example:
```bash
WANDB_API_KEY=key torchrun --nproc-per-node=8 launch_scripts/sft.py /path/to/pretrained/model molmo2 \
--wandb.name=run_name --wandb.entity=entity --wandb.project=project \
--save_folder=/path/to/save/folder
```
Here `/path/to/pretrained/model` points to a model checkpoint to start from (typically a pretrained model)
and `molmo2` refers to what training mixture to use.
To launch a debug run:
```bash
torchrun --nproc-per-node=1 launch_scripts/sft.py /path/to/pretrained/model debug --debug --save_folder=dbg --save_overwrite
```
This will run a lightweight version of the model and a small dataset to allow easier debugging.
For MolmoPoint, we used `launch_scripts/sft.py /path/to/pretrained/molmo_point/model molmo_point` instead.
## Long-Context SFT Training
Long-context training is done with the same script. If you have B200s you can run it like this:
```bash
torchrun --nproc-per-node=8 launch_scripts/sft.py /path/to/sft/checkpoint molmo2 \
--max_duration=2000 --device_batch_size=1 --data.num_workers=4 --seq_len=36864 \
--model.mm_preprocessor.video.max_frames=384 --model.llm.max_sequence_length=36864
```
For smaller memory GPUs or for even higher frame counts, you might require [context parallelism](#context-parallel).
## Evaluation
Evaluation can be done with the `launch_scripts/eval.py` script.
Note that the vLLM version of Molmo will be significantly faster for inference, but most of
our numbers were reported using the results of this local evaluation.
To eval on a single task:
```bash
torchrun --nproc-per-node 8 launch_scripts/eval.py Molmo2-4B --task=chart_qa --save_to_checkpoint_dir
```
This will save the metrics and predictions in the save directory. Future calls to the
eval script will re-use cached metrics if they exist. See `EvalConfig` for additional config options.
The `--loss` flag can be used to compute the loss instead of doing generation.
### Multi-Task Evaluation
To run groups of evals, use `launch_scripts/eval_molmo2.py` with `--tasks`:
```bash
PYTORCH_CUDA_ALLOC_CONF=expandable_segments:True NCCL_TIMEOUT_MINUTES=20 \
torchrun --nproc-per-node 8 launch_scripts/eval_molmo2.py Molmo2-4B \
--tasks=video --save_to_checkpoint_dir --num_workers=4
```
You can pass a comma-separated list of groups or individual task names (e.g. `--tasks=short_video,tracking`).
### Supported Evaluation Groups
| Group | Benchmarks |
|---|---|
| `single_image` | COCO VQA, TextVQA, ChartQA, DocQA, InfoQA, AI2D, MMMU, RealWorldQA, MathVista, CountBench, PixMo Count, PointingEval v2, PointBench |
| `single_image_test` | Test splits of image tasks + A-OKVQA (MC & DA) |
| `multi_image` | MuirBench, MMIU, BLINK |
| `short_video` | MVBench, TOMATO, MotionBench, TempCompass, PerceptionTest, EgoSchema, NeXTQA |
| `long_video` | VideoMME (w/ and w/o subtitles), LongVideoBench (w/ and w/o subtitles), LVBench, MLVU, VixMo Caps, VideoEvalPro |
| `video` | `short_video` + `long_video` |
| `video_no_subtitle` | `short_video` + long video benchmarks without subtitles |
| `video_subtitle` | Long video benchmarks with subtitles only |
| `video_pointing` | VixMo Points (count & point eval), MeViS point tracking |
| `image_pointing` | CountBench, PixMo Count, PointingEval v2, PointBench |
| `tracking` | MeViS, Ref-YT-VOS, Ref-DAVIS17, ReasonVOS, Molmo2VideoTrack |
| `test_video` | Test-split video benchmarks (MLVU, PerceptionTest, EgoSchema, MotionBench, LongVideoBench) |
Individual task names (e.g. `chart_qa`, `mvbench`, `mevis_track_eval_1fps:test`) can also be passed directly.
### Evaluation Tips
- `NCCL_TIMEOUT_MINUTES=20` can be needed if evaluating long video benchmarks where individual
processes can finish at very different times.
- `PYTORCH_CUDA_ALLOC_CONF=expandable_segments:True` is a torch setting that can reduce the chance of OOM errors.
- Memory costs can also be reduced by using the `load_bf16` flag to keep the weights in bfloat16.
We don't use this by default but it generally does not affect performance.
- Both commands can be run with multi-node configuration using `--nnodes` and `--node_rank` as usual with torchrun.
## Context Parallel
Context Parallelism (CP) shards long sequences across multiple GPUs, enabling training on very long videos
(e.g., 384 frames) that would not fit in a single GPU's memory. Each GPU processes a portion of the
sequence and images, communicating during attention to produce the same result as full-sequence training.
To enable CP, set `--cp_degree` and the matching parallelism config. For example, with CP degree 2 on 8 GPUs
(4 data-parallel x 2 context-parallel):
```bash
torchrun --nproc-per-node=8 launch_scripts/sft.py /path/to/checkpoint molmo2 \
--cp_degree=2 \
--parallelism.context_parallel_config.degree=2 \
--parallelism.context_parallel_config.attention_type=ulysses \
--save_folder=/path/to/save/folder
```
Key flags:
- `--cp_degree`: Sets the CP world size in both the packer and parallelism config
- `--parallelism.context_parallel_config.degree`: Must match `cp_degree`
- `--parallelism.context_parallel_config.attention_type`: `ulysses` (default) or `ring`
- `--model.apply_cp_to_vision_backbone=true`: Also shard image encoding across CP ranks
For a detailed explanation of how CP is implemented in this codebase, see [docs/context_parallel.md](docs/context_parallel.md).
# Transformers and vLLM
## Convert Checkpoint to Hugging Face Format
You must first convert a Molmo checkpoint into a HF–compatible format. You can convert a checkpoint by running:
```bash
# N: 36864 for Molmo2-4B and Molmo2-8B, 65536 for Molmo2-O-7B
python3 -m olmo.hf_model.convert_molmo2_to_hf \
/path/to/your/checkpoint/dir \
/path/to/output/dir \
--override_max_model_len N
```
## Transformers Inference
### Image Inference Example
```python
from transformers import AutoProcessor, AutoModelForImageTextToText
from PIL import Image
import requests
import torch
checkpoint_dir = "allenai/Molmo2-8B" # or path to a converted HF checkpoint
model = AutoModelForImageTextToText.from_pretrained(
checkpoint_dir,
trust_remote_code=True,
dtype="auto",
device_map="auto",
)
processor = AutoProcessor.from_pretrained(
checkpoint_dir,
trust_remote_code=True,
padding_side="left",
)
image_messages = [
{
"role": "user",
"content": [
{"type": "text", "text": "Describe this image."},
{"type": "image", "image": Image.open(requests.get(
"https://picsum.photos/id/237/536/354", stream=True
).raw)},
]
}
]
inputs = processor.apply_chat_template(
image_messages,
tokenize=True,
add_generation_prompt=True,
return_tensors="pt",
return_dict=True,
padding=True,
)
inputs = {k: v.to("cuda") for k, v in inputs.items()}
with torch.inference_mode(), torch.autocast("cuda", dtype=torch.bfloat16):
output = model.generate(**inputs, max_new_tokens=200)
generated_tokens = output[0, inputs["input_ids"].size(1):]
print(processor.decode(generated_tokens, skip_special_tokens=True))
```
### Video Inference Example
```python
video_path = "https://storage.googleapis.com/oe-training-public/demo_videos/many_penguins.mp4"
video_messages = [
{
"role": "user",
"content": [
dict(type="text", text="Which animal appears in the video?"),
dict(type="video", video=video_path),
]
}
]
inputs = processor.apply_chat_template(
video_messages,
tokenize=True,
add_generation_prompt=True,
return_tensors="pt",
return_dict=True,
padding=True,
)
inputs = {k: v.to("cuda") for k, v in inputs.items()}
with torch.inference_mode(), torch.autocast("cuda", dtype=torch.bfloat16):
output = model.generate(**inputs, max_new_tokens=200)
generated_tokens = output[0, inputs['input_ids'].size(1):]
print(processor.decode(generated_tokens, skip_special_tokens=True))
```
For more examples, please refer to `olmo/hf_model/test_molmo2.py`.
## Fast Inference with vLLM
### Install Vision Process Package
To run vLLM inference offline, we recommend installing our vision processing package, `molmo-utils`, which follows the design of `qwen-vl-utils`.
This package loads images and videos and prepares them for use with the Molmo2 HF processor.
Install with:
```bash
pip install --no-cache-dir "molmo-utils[torchcodec]"
```
### Install vLLM (>= 0.15.0)
Molmo2 is officially supported in vLLM starting from v0.15.0.
Please install vLLM 0.15.0 or later.
You can find the detailed installation guide in the [official documentation](https://docs.vllm.ai/en/latest/getting_started/installation).
### Run vLLM inference (Gradio Demo)
To demonstrate how to run vLLM inference with Molmo2, we provide a Gradio demo script.
To launch this demo, you will need:
- The converted Hugging Face checkpoint directory
- The original Molmo2 checkpoint directory
Run:
```bash
python3 -m scripts.unified_demo \
/path/to/your/hf/checkpoint/dir \
--annotations \
--cloudflare_tunnel \
--original_ckpt_home /path/to/your/original/checkpoint/dir
```
**Arguments**
- `/path/to/your/hf/checkpoint/dir`
Path to the converted Hugging Face checkpoint directory.
- `--original_ckpt_home`
Path to the original Molmo2 checkpoint directory.
- `--annotations`
Enable visualization of pointing or tracking outputs.
- `--cloudflare_tunnel`
Expose the Gradio app through a public Cloudflare tunnel.
After launching, the Gradio interface will be available locally or via the Cloudflare tunnel.
# Code
Here we review the code structure to make this repo easier to understand. There are essentially four high-level pieces:
- **Models**: Models extend `BaseModel` and include a `forward` and `generate` method. Model configs extend `BaseModelConfig`
and also provide a model-compatible preprocessor and a collator for use in the data pipeline.
- **Data**: Data is provided by classes that extend `olmo.data.dataset.Dataset`. During training or inference, data from these
class are put through the model's preprocessor and collator, and the results are passed into either the
`forward` or `generate` method. This, along with batching and packing, are orchestrated by `DataLoaderConfig` and `IterableDatasetMixture`.
- **Trainer**: `Trainer` runs the main train loop, including wandb logging, in-loop evaluations, checkpointing, etc.
- **Evaluation**: Evaluators extend `Evaluator` and provide a `evaluate` methods that provide metrics
given model predictions and example metadata. Evaluation is orchestrated by `ModelEvaluator` or within
the `Trainer` using `InfDatasetEvaluator` or `LossDatasetEvaluator` for inference and loss evaluations
respectively.
At a high level, examples are fetched from datasets, passed through the model's preprocessor,
grouped into batches, passed into the model's collator, and then into the model's `forward` to compute
logits that used to compute a loss (in `Trainer`), or into the model's `generate` function to generate text which can then be
used in evaluation (in `InfDatasetEvaluator`).
## Data Pipeline
Data preprocessing/loading is the most complex part of this process and likely the one new users will be
the least familiar with, so we review it in more detail here. Data loading has four stages:
1. **Dataset** — First an example is fetched from a `Dataset` object. The example will be dictionary with string keys. Examples
from a `Dataset` are preferred to be left "raw" in that they typically include minimal preprocessing, which
maximizes the flexibility models have in their preprocessors.
For example, pointing examples include a `points` and `label` field but not the input
or output text the model will be trained on so models perform model-specific point preprocessing. Examples have
a `style` field that contain a string name identifying what kind of example it is so preprocessors
can do tailored preprocessing if needed.
Examples can also have a `metadata` field that contains data that might be needed during evaluation.
2. **Formatting** — The example is passed through the model's preprocessor, which typically has two stages. The
first is formatting where the example will be converted into a list of strings. This is done by
`DataFormatter` and include things like converting points into string, applying prompt templates,
formatting multiple-choice questions / answers, etc. The output of this stage is:
- A list of messages, alternating human-assistant-human-assistant
- Possibly a video, image, or list of images as the multi-modal input
3. **Tokenization** — Next the model's preprocessor will tokenize the formatted output into tensors, typically including
input tokens, output tokens, and token weights, etc. Visual input will be tokenized into
one or more fixed-sized crops and a special `token_pooling` array that maps how patches in those crops
correspond to input tokens to the model. The output of this stage is a dictionary of tensors. This is done
by `MultimodalPreprocessor`.
4. **Collation** — The model's collator will take one or more of these dictionaries and output another dictionary of tensors
as the batched model input. The collator might pad or truncate some of the tensors to fixed shape in order to support static compilation.
Now the batch is ready to be used in the model's `generate` or `forward`
### Message Trees
This pipeline also supports *message trees* where one multi-modal input has multiple annotations associated with it.
This allows training on multiple modalities at once, which can greatly increase training efficiency.
To support this `Dataset` examples can include a **`message_lists`** field that contains multiple annotation about the
same image or video. This is represented a list of dictionaries, where each dictionary can contain a raw or
unprocessed example as before. `DataFormatter` will handle this by formatting each example in the list separately
(producing a list-of-lists of strings). The `MultimodalPreprocessor` will flatten these messages into
one token sequence. A **`subsegment_id`** field will be added to construct the attention mask that prevents
annotations from cross-attentioning to each other.
### Packing
After the preprocessor has run, but before collation, examples can be packed together into a single
sequence. This reduces padding and boosts training efficiency. Packing setup is done by `PackingConfig` and run within `IterableDatasetMixture`.
Packed examples use the **`subsegment_id`** to demark which tokens belong to which examples.
When packing, the trainer will keep track a light-weight snapshot of the state of the packers and
save it during checkpointing to allow proper recovery from checkpoints.
# Citation
```
@article{molmo2openweightsdata,
title={Molmo2: Open Weights and Data for Vision-Language Models with Video Understanding and Grounding},
author={Christopher Clark and Jieyu Zhang and Zixian Ma and Jae Sung Park and Mohammadreza Salehi and Rohun Tripathi and Sangho Lee and Zhongzheng Ren and Chris Dongjoo Kim and Yinuo Yang and Vincent Shao and Yue Yang and Weikai Huang and Ziqi Gao and Taira Anderson and Jianrui Zhang and Jitesh Jain and George Stoica and Winson Han and Ali Farhadi and Ranjay Krishna},
year={2026},
journal={arXiv preprint arXiv:2601.10611}
}
```