# vla-evaluation-harness
[](https://github.com/allenai/vla-evaluation-harness/actions/workflows/ci.yml)
[](https://pypi.python.org/pypi/vla-eval)
[](LICENSE)
[](https://www.python.org/)
[](https://github.com/astral-sh/ruff)
[](https://ghcr.io/allenai/vla-evaluation-harness)
| | |
|:--|:--|
| **Benchmarks** | [](configs/benchmarks/libero/) [](configs/benchmarks/simpler/) [](configs/benchmarks/calvin/) [](configs/benchmarks/maniskill2/) [](configs/benchmarks/libero_pro/) [](configs/benchmarks/libero_plus/) [](configs/benchmarks/robocasa/) [](configs/benchmarks/robocasa365/) [](configs/benchmarks/vlabench/) [](configs/benchmarks/mikasa/) [](configs/benchmarks/robotwin/) [](configs/benchmarks/rlbench/) [](configs/benchmarks/robocerebra/) [](configs/benchmarks/libero_mem/) [](configs/benchmarks/behavior1k/) [](configs/benchmarks/kinetix/) [](configs/benchmarks/robomme/) [](configs/benchmarks/molmospaces/) [](configs/benchmarks/duobench/) [](configs/benchmarks/robodojo/)  |
| **Models (official)** | [](configs/model_servers/openvla/) [](configs/model_servers/pi0/) [](configs/model_servers/pi0/) [](configs/model_servers/groot/) [](configs/model_servers/oft/) [](configs/model_servers/xvla/) [](configs/model_servers/cogact/) [](configs/model_servers/rtc/) [](configs/model_servers/vlanext/) [](configs/model_servers/molmobot/)  |
| **Models ([dexbotic](https://github.com/dexmal/dexbotic))**  | [](configs/model_servers/db_cogact/) |
| **Models ([starVLA](https://github.com/starVLA/starVLA))**  | [](configs/model_servers/starvla/) [](configs/model_servers/starvla/) [](configs/model_servers/starvla/) [](configs/model_servers/starvla/) |
| **Models ([🤗 LeRobot](https://github.com/huggingface/lerobot))**  | [](configs/model_servers/lerobot/) [](configs/model_servers/lerobot/) [](configs/model_servers/lerobot/) [](configs/model_servers/lerobot/) [](configs/model_servers/lerobot/) [](configs/model_servers/lerobot/) [](configs/model_servers/lerobot/) [](configs/model_servers/lerobot/) [](configs/model_servers/lerobot/) |
✓ [reproduced](docs/reproductions/) | ◇ integrated, awaiting first reproduction | · planned
**One framework to evaluate any VLA model on any robot simulation benchmark.**
### Latest News
- [2026/09] [Push-T example](examples/pusht_train_eval/): a self-contained project that trains on its own environment and evaluates it with `vla_eval.evaluate` during training. `pip install vla-eval` is all it needs, no clone of this repo.
- [2026/09] [v0.6.0](https://github.com/allenai/vla-evaluation-harness/releases/tag/v0.6.0) released. Python API for training-time evaluation, Charliecloud runtime, and `docker.build`.
- [2026/08] [v0.5.0](https://github.com/allenai/vla-evaluation-harness/releases/tag/v0.5.0) released. RoboDojo, the RoboCasa/RoboCasa365 split, and the CPU render backend.
- [2026/07] [v0.4.0](https://github.com/allenai/vla-evaluation-harness/releases/tag/v0.4.0) released. Recording on by default, pinned reproducible Docker rebuilds, DuoBench, and the LeRobot bridge below.
- [2026/07] 🤗 [LeRobot](https://github.com/huggingface/lerobot) bridge: serve any single-obs-step LeRobot `PreTrainedPolicy` (π₀ / π₀.₅, GR00T N1.7, X-VLA, MolmoAct2, and the FastWAM / VLA-JEPA / LingBot-VA world models) with [one config](configs/model_servers/lerobot/), pinned at [v0.6.0](https://github.com/huggingface/lerobot/releases/tag/v0.6.0). Four checkpoints [reproduce their published LIBERO scores](docs/reproductions/lerobot.md): π₀.₅ 100%, GR00T N1.7 99%, MolmoAct2 97%, VLA-JEPA 96%.
- [2026/06] [v0.3.0](https://github.com/allenai/vla-evaluation-harness/releases/tag/v0.3.0) released. SQLite recording + `vla-eval merge`, wandb/trackio tracking, and a watchdog for wedged benchmarks.
- [2026/05] [v0.2.0](https://github.com/allenai/vla-evaluation-harness/releases/tag/v0.2.0) released. 18 benchmarks x 13 model servers, the largest open VLA evaluation matrix. Browse [`configs/`](configs/) to get started.
- [2026/05] [Leaderboard](https://allenai.github.io/vla-evaluation-harness/leaderboard/) rebuilt: 2,456 models x 18 benchmarks, schema-validated pipeline, updated monthly.
- [2026/04] [v0.1.0](https://github.com/allenai/vla-evaluation-harness/releases/tag/v0.1.0) released. 6 VLA models [reproduced](docs/reproductions/) within 2pp of published scores.
- [2026/04] Batch parallel eval: 2,000 LIBERO episodes in 18 min on 1x H100 ([details](#batch-parallel-evaluation)).
### Why vla-evaluation-harness?
| | |
|:--|:--|
| **Batch Parallel Evaluation** | Episode sharding + batched GPU inference → **47× throughput** (2 000 LIBERO episodes in 18 min on 1× H100). [Details](#batch-parallel-evaluation) |
| **Zero Setup** | Benchmarks in Docker and model servers as single-file [uv scripts](https://docs.astral.sh/uv/guides/scripts/), avoiding dependency conflicts. |
| **AI-Assisted Integration** | Shared agent skills for [adding benchmarks](skills/add-benchmark/), [model servers](skills/add-model-server/), and [running evaluations](skills/run-evaluation/). |
| **[Leaderboard](https://allenai.github.io/vla-evaluation-harness/leaderboard/)** | The largest unified VLA comparison: 2,456 models × 18 benchmarks, aggregated from 2,087 papers. |
---
## Motivation
VLA models are evaluated on LIBERO, CALVIN, SimplerEnv, ManiSkill, and others, but each benchmark has its own dependencies, observation format, and evaluation protocol. In practice, every research team ends up maintaining private eval forks per benchmark. Results diverge. Bug fixes don't propagate. No one tests under real-time conditions where the environment keeps moving during inference.
**vla-evaluation-harness** integrates the model once, integrates the benchmark once, and the full cross-evaluation matrix fills itself.
**How**: our abstraction layer fully decouples models from benchmarks.
- Benchmarks run inside **Docker**, giving exact reproducibility without dependency conflicts.
- Model servers are standalone **[uv scripts](https://docs.astral.sh/uv/guides/scripts/)** with inline dependency declarations and no manual setup.
See [Architecture](docs/architecture.md) for how the pieces connect.
---
## Installation
Requires Python 3.8+ and SQLite 3.24+ with JSON support for recording. A uv-managed
Python build includes a suitable SQLite; system Python builds may not.
```bash
pip install vla-eval
```
Or from source (pinned to the latest stable release):
```bash
git clone --branch v0.7.0 https://github.com/allenai/vla-evaluation-harness.git
cd vla-evaluation-harness
uv sync --python 3.11 --all-extras --dev --group leaderboard
```
---
## Quick Start
Two terminals: one for the model server (GPU), one for the benchmark client.
```bash
# Terminal 1: model server (runs on host with GPU)
vla-eval serve --config configs/model_servers/db_cogact/libero.yaml
# Terminal 2: run evaluation (benchmark runs in Docker by default).
# Wait for the model server to finish loading first; ``GET /health`` returning HTTP 200 is the ready signal.
vla-eval run --config configs/benchmarks/libero/smoke_test.yaml
```
Results are saved to `results/` as JSON. The benchmark runs inside Docker by default; pass `--no-docker` for local development.
No Docker daemon? `--runtime charliecloud` runs the same image without root; see [Container runtimes](docs/runtimes.md).
For full evaluation (10 tasks x 50 episodes):
```bash
vla-eval run --config configs/benchmarks/libero/spatial.yaml
```
Other benchmarks and models follow the same pattern. Pick a benchmark and a compatible model server from [`configs/`](configs/):
```bash
# SimplerEnv + X-VLA
vla-eval serve --config configs/model_servers/xvla/simpler_widowx.yaml
vla-eval run --config configs/benchmarks/simpler/widowx_vm.yaml
# CALVIN + DB-CogACT
vla-eval serve --config configs/model_servers/db_cogact/calvin.yaml
vla-eval run --config configs/benchmarks/calvin/eval.yaml
# LIBERO + π₀.₅ via 🤗 LeRobot (works for any LeRobot PreTrainedPolicy checkpoint)
vla-eval serve --config configs/model_servers/lerobot/pi05_libero.yaml
vla-eval run --config configs/benchmarks/libero/object.yaml
```
Each benchmark and model server directory has a README with setup details, supported configs, and Docker image info. See [Reproduction Reports](docs/reproductions/) for verified scores.
> **Need faster runs?** See [Batch Parallel Evaluation](#batch-parallel-evaluation) for up to 47x throughput.
### From Python (evaluate while training)
The same run is one function call, with the model served from the calling process:
```python
import vla_eval
results = vla_eval.evaluate(MyModelServer(model), "configs/benchmarks/libero/smoke_test.yaml")
print(results[0]["mean_success"])
```
[Python API](docs/python-api.md) documents the arguments. [examples/pusht_train_eval](examples/pusht_train_eval/)
is a complete training script that does this every N steps on an environment vla-eval does not ship.
---
## Batch Parallel Evaluation
A full evaluation takes hours sequentially. Two layers of parallelism bring this down to minutes:
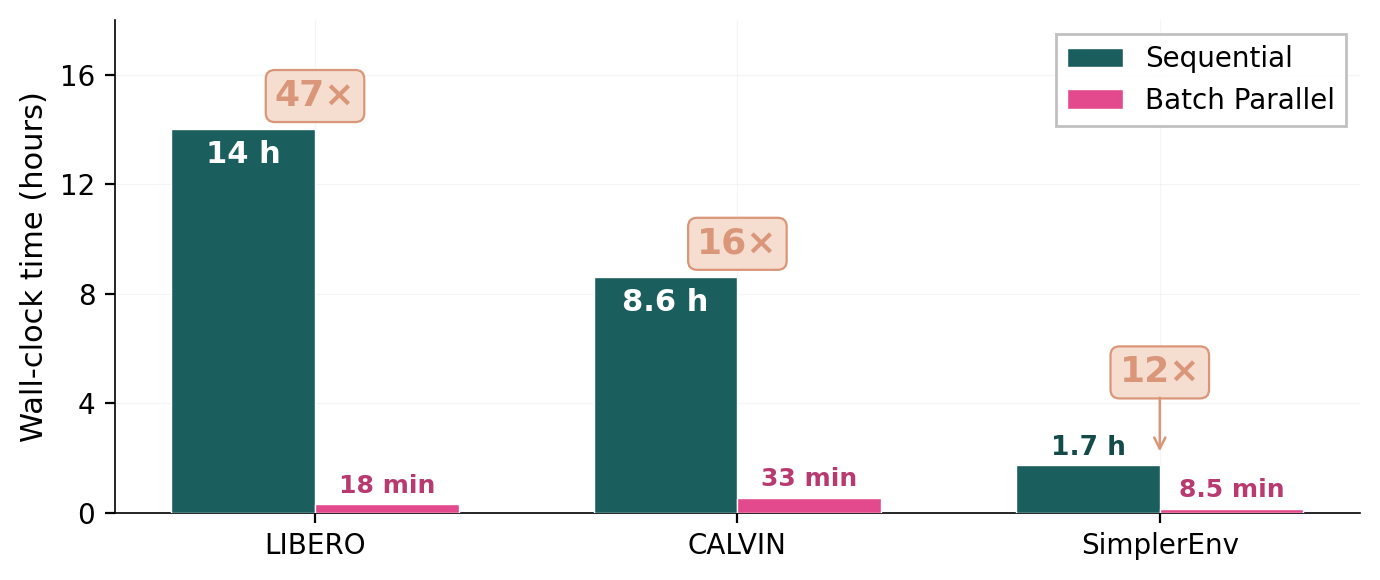
**Episode sharding** splits `(task, episode)` pairs across N independent processes ([RFC-0006](docs/rfcs/0006-episode-sharding.md)). Each shard connects to the same model server, where a [`BatchPredictModelServer`](docs/rfcs/0007-batch-predict-model-server.md) **batches their inference requests** into a single forward pass. The two axes multiply together.
### Episode Sharding (environment parallelism)
```bash
# Option A: use the helper script (launches all shards + auto-exports)
./scripts/run_sharded.sh -c configs/benchmarks/libero/spatial.yaml -n 50
# Option B: manual launch
EVAL_ID=$(uuidgen)
vla-eval run -c configs/benchmarks/libero/spatial.yaml --eval-id "$EVAL_ID" --shard-id 0 --num-shards 4 &
vla-eval run -c configs/benchmarks/libero/spatial.yaml --eval-id "$EVAL_ID" --shard-id 1 --num-shards 4 &
# ... (each shard is a separate process)
wait
vla-eval export "results/recording-$EVAL_ID.sqlite"
```
Shards claim work items from a queue in the shared recording DB (`--no-save`: fixed round-robin split). A shard whose first three episodes all error exits with code 3; `--requeue-unhealthy` gives its items to the other shards. Re-run a shard with the same eval ID to resume its unfinished items; export keeps the last committed attempt per item and lists unfinished ones.
Benchmark containers run as root by default, so `output_dir` ends up root-owned and the host-side `vla-eval export` fails with `Permission denied`. Set `docker.user: host` in the eval YAML (or an explicit `":"`) to run the containers as the invoking user.
### Batch Model Server (GPU parallelism)
Enable batching in the model server config by setting `max_batch_size > 1`:
```yaml
args:
max_batch_size: 16 # max observations per GPU forward pass (>1 enables batching)
max_wait_time: 0.05 # seconds to wait before dispatching a partial batch
```
### Tuning & Combined Effect
We tune parallelism via a demand/supply methodology: **demand λ(N)** measures environment throughput as a function of shards, **supply μ(B)** measures model throughput as a function of batch size. The operating point satisfies λ(N) < 80% · μ(B\*) to prevent queue buildup.
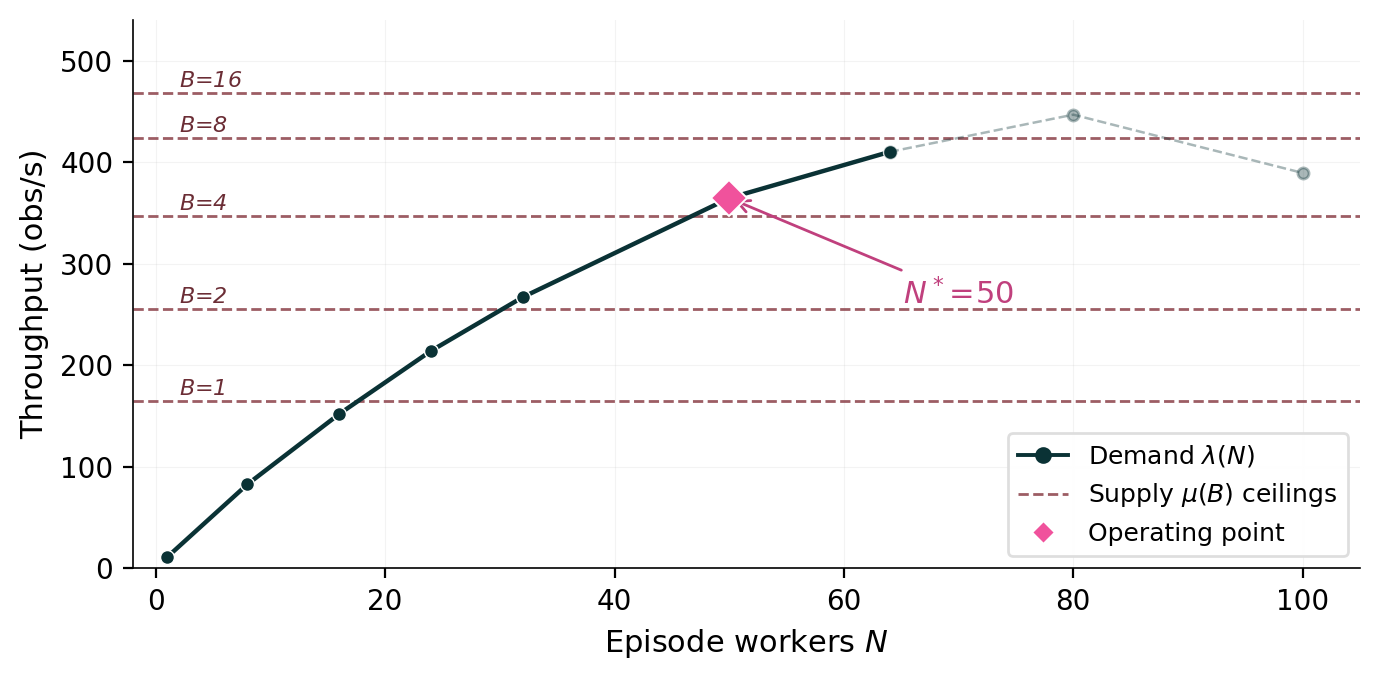
Sharding and batching multiply together (DB-CogACT 7B, LIBERO Spatial, 1× H100-80GB):
| | Sequential | Batch Parallel (50 shards, B=16) |
|:--|:---:|:---:|
| Wall-clock | ~14 h | **~18 min** |
| Throughput | ~11 obs/s | ~486 obs/s |
**2 000 episodes, 47× faster.** The included benchmarking tools (`experiments/bench_demand.py`, `experiments/bench_supply.py`) measure λ and μ for any model + benchmark combination. See the [Tuning Guide](docs/tuning-guide.md) for worked examples and `max_wait_time` derivation.
---
## Docker Images
All benchmark environments are packaged as standalone Docker images, based on `base` unless noted.
| Image | Size | Benchmark | Python | Base |
|-------|------|-----------|--------|------|
| [`base`](https://ghcr.io/allenai/vla-evaluation-harness/base) | 3.3 GB | — | — | `nvidia/cuda:12.1.1-runtime-ubuntu22.04` |
| `rlbench` 🔒 | 4.7 GB | RLBench | 3.8 | [`base`](https://ghcr.io/allenai/vla-evaluation-harness/base) |
| [`simpler`](https://ghcr.io/allenai/vla-evaluation-harness/simpler) | 4.9 GB | SimplerEnv | 3.10 | [`base`](https://ghcr.io/allenai/vla-evaluation-harness/base) |
| [`duobench`](https://ghcr.io/allenai/vla-evaluation-harness/duobench) | 5.6 GB | DuoBench | 3.11 | [`base`](https://ghcr.io/allenai/vla-evaluation-harness/base) |
| [`libero`](https://ghcr.io/allenai/vla-evaluation-harness/libero) | 6.0 GB | LIBERO | 3.8 | [`base`](https://ghcr.io/allenai/vla-evaluation-harness/base) |
| [`libero-pro`](https://ghcr.io/allenai/vla-evaluation-harness/libero-pro) | 6.2 GB | LIBERO-Pro | 3.8 | [`base`](https://ghcr.io/allenai/vla-evaluation-harness/base) |
| [`robocerebra`](https://ghcr.io/allenai/vla-evaluation-harness/robocerebra) | 6.4 GB | RoboCerebra | 3.8 | [`base`](https://ghcr.io/allenai/vla-evaluation-harness/base) |
| [`calvin`](https://ghcr.io/allenai/vla-evaluation-harness/calvin) | 9.6 GB | CALVIN | 3.8 | [`base`](https://ghcr.io/allenai/vla-evaluation-harness/base) |
| [`maniskill2`](https://ghcr.io/allenai/vla-evaluation-harness/maniskill2) | 9.8 GB | ManiSkill2 | 3.10 | [`base`](https://ghcr.io/allenai/vla-evaluation-harness/base) |
| [`kinetix`](https://ghcr.io/allenai/vla-evaluation-harness/kinetix) | 10.0 GB | Kinetix | 3.11 | [`base`](https://ghcr.io/allenai/vla-evaluation-harness/base) |
| [`mikasa-robo`](https://ghcr.io/allenai/vla-evaluation-harness/mikasa-robo) | 10.1 GB | MIKASA-Robo | 3.10 | [`base`](https://ghcr.io/allenai/vla-evaluation-harness/base) |
| [`libero-mem`](https://ghcr.io/allenai/vla-evaluation-harness/libero-mem) | 11.3 GB | LIBERO-Mem | 3.8 | [`base`](https://ghcr.io/allenai/vla-evaluation-harness/base) |
| [`libero-plus`](https://ghcr.io/allenai/vla-evaluation-harness/libero-plus) | 14.8 GB | LIBERO-Plus | 3.8 | [`base`](https://ghcr.io/allenai/vla-evaluation-harness/base) |
| [`robomme`](https://ghcr.io/allenai/vla-evaluation-harness/robomme) | 17.0 GB | RoboMME | 3.11 | [`base`](https://ghcr.io/allenai/vla-evaluation-harness/base) |
| [`vlabench`](https://ghcr.io/allenai/vla-evaluation-harness/vlabench) | 17.7 GB | VLABench | 3.10 | [`base`](https://ghcr.io/allenai/vla-evaluation-harness/base) |
| [`robocasa`](https://ghcr.io/allenai/vla-evaluation-harness/robocasa) | 21.4 GB | RoboCasa | 3.10 | [`base`](https://ghcr.io/allenai/vla-evaluation-harness/base) |
| `behavior1k` 🔒 | 23.6 GB | BEHAVIOR-1K (2025 challenge protocol) | 3.10 | [`base`](https://ghcr.io/allenai/vla-evaluation-harness/base) |
| [`robotwin`](https://ghcr.io/allenai/vla-evaluation-harness/robotwin) | 28.6 GB | RoboTwin 2.0 | 3.10 | [`base`](https://ghcr.io/allenai/vla-evaluation-harness/base) |
| [`molmospaces`](https://ghcr.io/allenai/vla-evaluation-harness/molmospaces) | 31.4 GB | MolmoSpaces-Bench | 3.11 | [`base`](https://ghcr.io/allenai/vla-evaluation-harness/base) |
| [`robocasa365`](https://ghcr.io/allenai/vla-evaluation-harness/robocasa365) | 35.6 GB | RoboCasa365 | 3.11 | [`base`](https://ghcr.io/allenai/vla-evaluation-harness/base) |
| `robodojo` 🔒 | 36.3 GB | RoboDojo | 3.11 | [upstream Isaac Sim 5.1](https://github.com/RoboDojo-Benchmark/RoboDojo) |
🔒 = build-locally only; the Dockerfile gates the build behind a licence opt-in (`docker/build.sh --accept-license `) and the image isn't published to ghcr.io.
**Pull** (recommended):
```bash
docker pull ghcr.io/allenai/vla-evaluation-harness/libero:latest
```
**Build locally** (see [docker/build.sh](docker/build.sh)):
```bash
docker/build.sh # build all (gated images skipped)
docker/build.sh libero # build one
docker/build.sh behavior1k --accept-license behavior1k # build a gated image
```
**Build from your own Dockerfile**: set `docker.build: ` (compose semantics, optional `dockerfile:`) in the benchmark config. The image is built when missing, or on `--build`. The [Push-T example](examples/pusht_train_eval/benchmark/eval.yaml) uses it.
---
## Observability
Two systems capture eval data. Both key on `eval_id` so recordings and tracker runs stay linked.
### Recording
Benchmark entries persist episode results and step rows by default, with videos off. Add a top-level `recording:` key only when you want to override that policy; use `--record-video` or set `record_video: true` when you want per-episode mp4s.
```yaml
benchmarks:
- benchmark: ...
recording:
record_video: true
video_fps: 10
```
Recording writes `/recording-.sqlite`: per-step rows, episode results, and eval metadata. `vla-eval export` materializes per-episode JSONL + aggregate JSON from the DB. Single-shard runs auto-export; sharded runs call `vla-eval export` once after all shards exit. `--no-save` skips recording entirely.
Use `vla-eval export DB [-o DIR]` to export recorded results (default: DB parent). All writers need write access to the DB and its directory; shared storage must support SQLite locking and sync.
When `filename_stem` is omitted, per-episode artifacts use a benchmark-scoped path:
`{benchmark_safe_name}/task{task_idx:04d}_ep{episode_id:04d}_{status}`. Custom stems can still reference serializable task fields such as `{name}` plus `{status}`.
### Tracking (wandb / trackio)
Mirror aggregate metrics to a remote dashboard:
```yaml
tracking:
report_to: wandb # "wandb" | ["wandb", "trackio"] | "all" | "none"
```
The harness injects `id=` + `resume="allow"` so live (`vla-eval run`) and export (`vla-eval export`) paths converge on the same run. All other settings, including project, entity, and API key, come from the backend's native env vars (`WANDB_*`, `TRACKIO_*`). See the [W&B env reference](https://docs.wandb.ai/guides/track/environment-variables) for details. Install the backend yourself: `pip install wandb` / `pip install trackio`.
Under sharding, aggregate emission defers to `vla-eval export`; per-episode tracking is live-path only.
---
## Documentation
| Document | Description |
|----------|-------------|
| [Architecture](docs/architecture.md) | Component descriptions, protocol, episode flow, configuration |
| [Render Backends](docs/render-backends.md) | Running the simulator on the CPU (`--render cpu`) to free the GPU for the model |
| [Container runtimes](docs/runtimes.md) | Docker vs Charliecloud (`--runtime charliecloud`, no daemon, no root) |
| [Python API](docs/python-api.md) | `evaluate()` / `run()` / `serve_background()` for calling the harness from a training script |
| [Push-T example](examples/pusht_train_eval/) | Train with LeRobot and evaluate with vla-eval during training, on your own environment |
| [Tuning Guide](docs/tuning-guide.md) | Measuring λ / μ and deriving `max_wait_time` for batch-parallel runs |
| [Contributing](CONTRIBUTING.md) | Dev setup, adding benchmarks/models, PR workflow |
| [Reproduction Reports](docs/reproductions/) | Per-model evaluation results and reproducibility verdicts |
| [RFCs](docs/rfcs/README.md) | Design proposals with rationale and status tracking |
| [Design Philosophy](docs/design-philosophy.md) | Freshness, Convenience, Layered Abstraction, Quality, Reproducibility, Openness |
---
## Contributing
See [CONTRIBUTING.md](CONTRIBUTING.md) for dev setup and PR workflow.
PRs for any 🔜 item in the support matrix are welcome.
---
## Citation
If you find this work useful, please cite:
```bibtex
@article{choi2026vlaeval,
title={vla-eval: A Unified Evaluation Harness for Vision-Language-Action Models},
author={Choi, Suhwan and Lee, Yunsung and Park, Yubeen and Kim, Chris Dongjoo and Krishna, Ranjay and Fox, Dieter and Yu, Youngjae},
journal={arXiv preprint arXiv:2603.13966},
year={2026}
}
```
## License
Apache 2.0
## Agent skills
The skills in `skills/` support Codex, Claude Code, and other
[npx skills](https://github.com/vercel-labs/skills) clients. Use them from a harness
checkout; installing a skill does not install the harness or simulator dependencies.
```bash
# Discover available skills from this checkout.
npx skills add . --list
# Install into another project from a local checkout.
npx skills add /path/to/vla-evaluation-harness --agent codex claude-code --skill '*'
# Install a selected skill from the public repository after this change lands.
npx skills add worv-ai/vla-evaluation-harness-public --agent codex --skill add-benchmark
```
`.agents/skills` and `.claude/skills` point to the same source. Shared repository
instructions live in `AGENTS.md`; `CLAUDE.md` imports them for Claude Code.