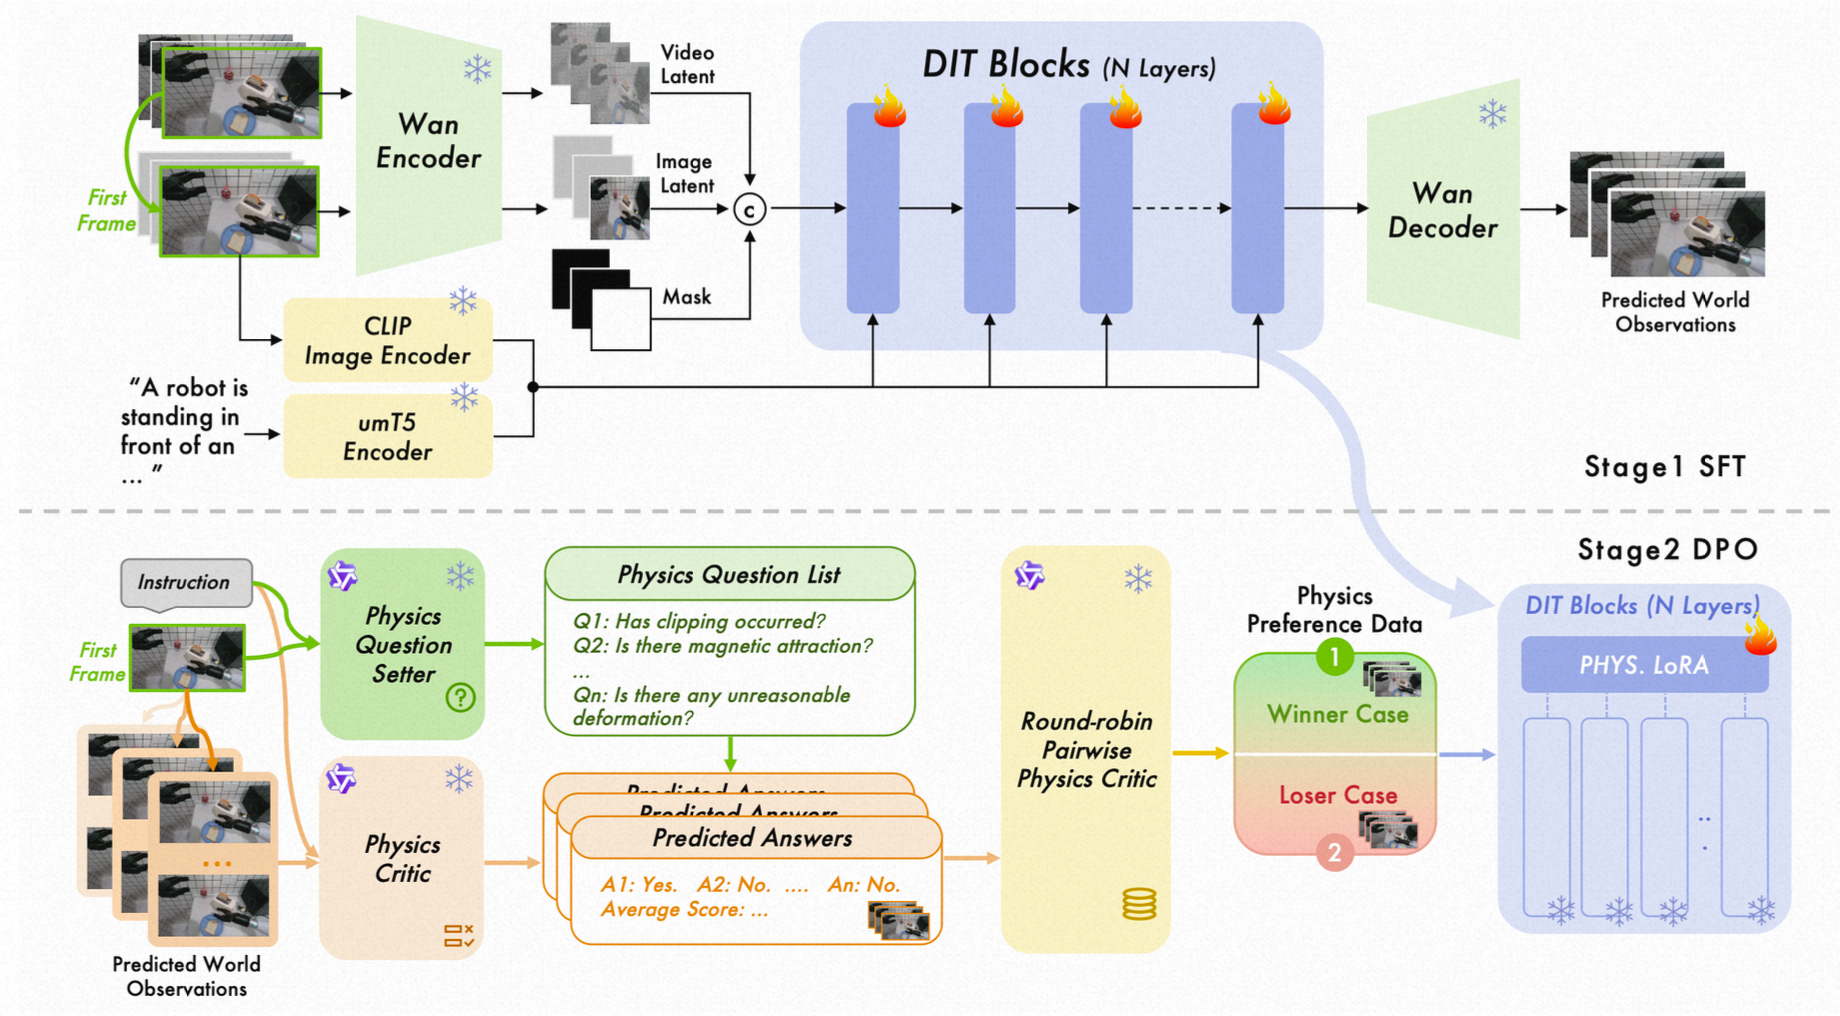
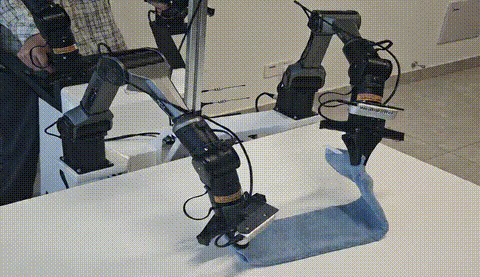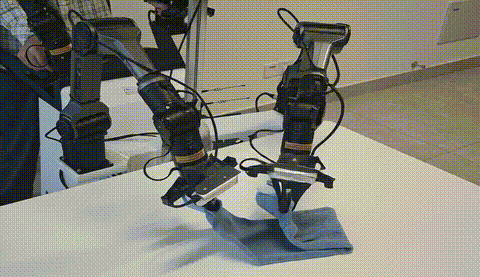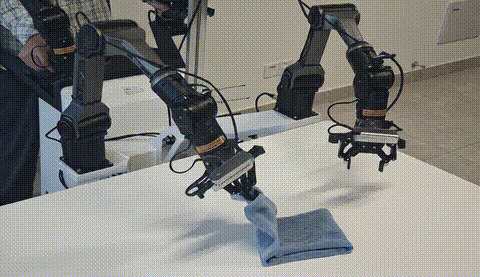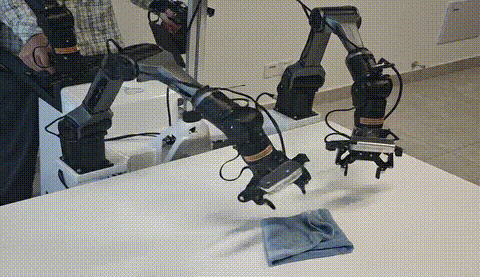
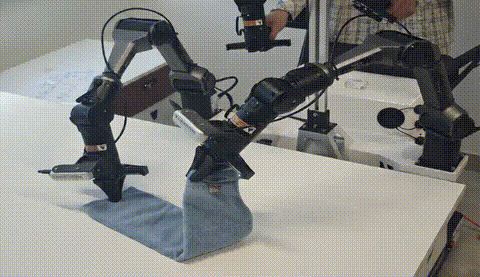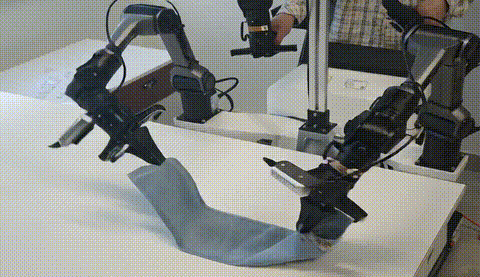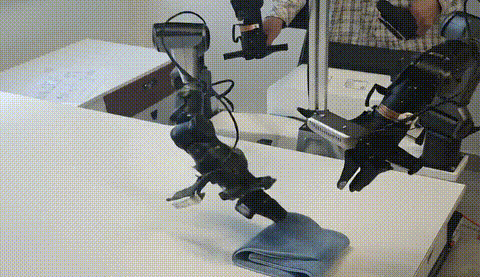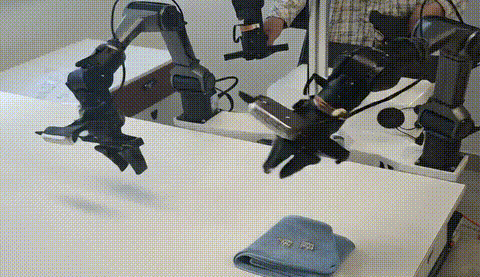
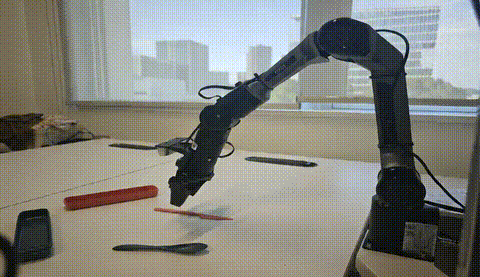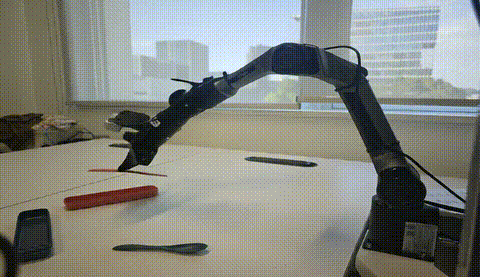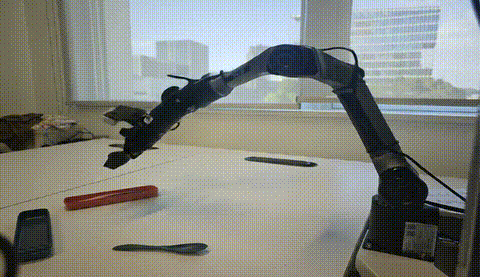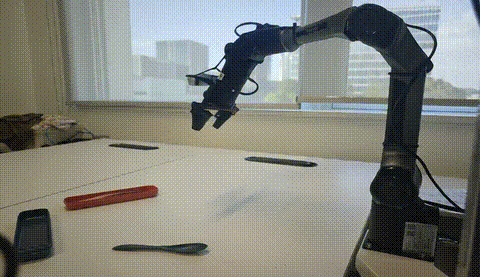
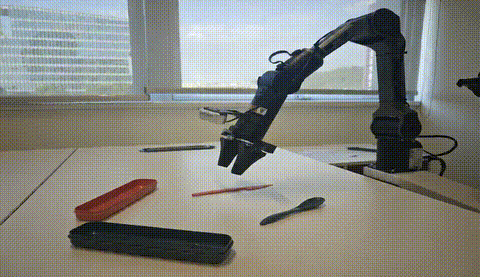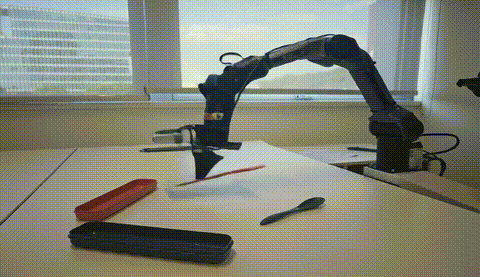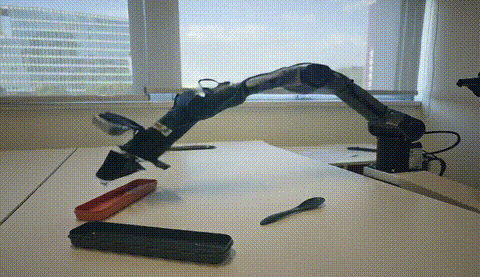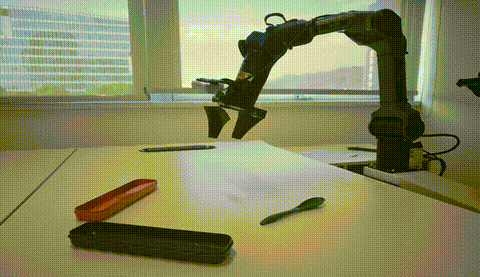
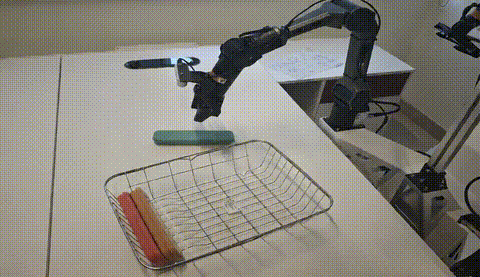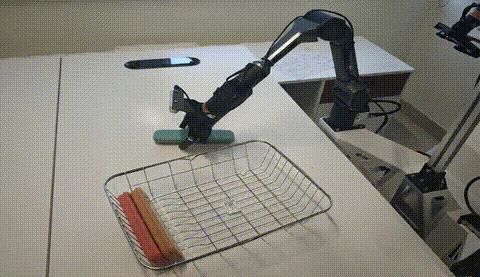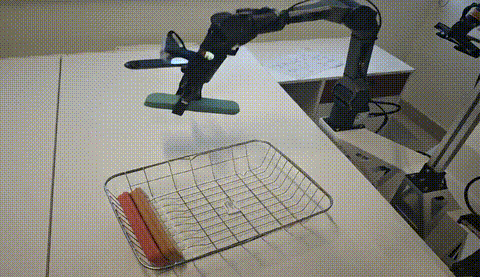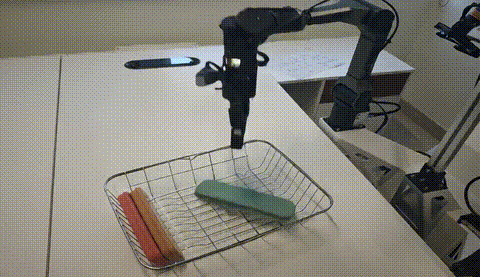
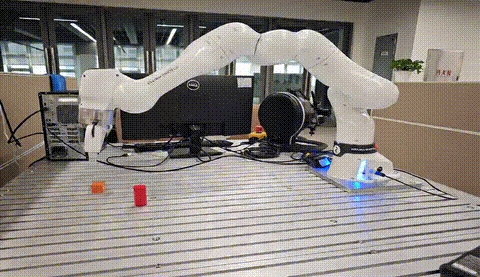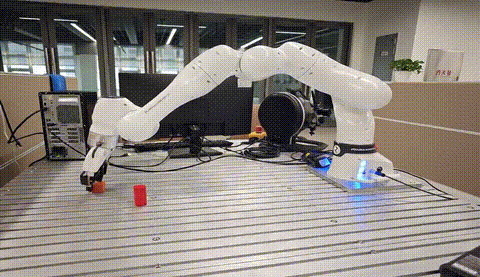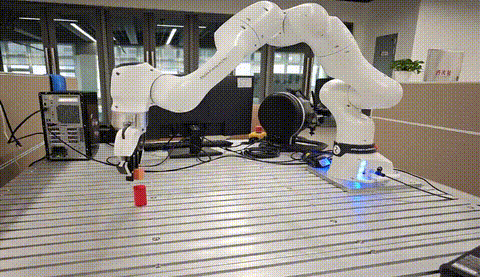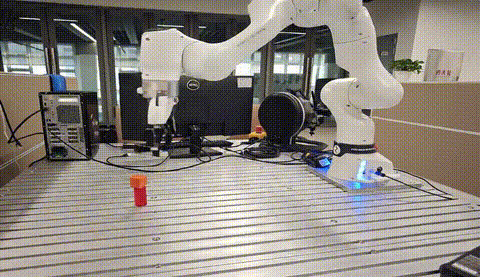
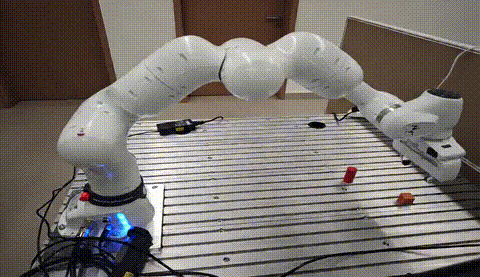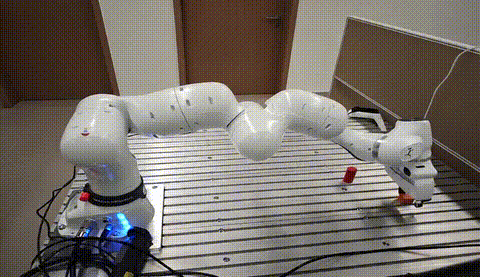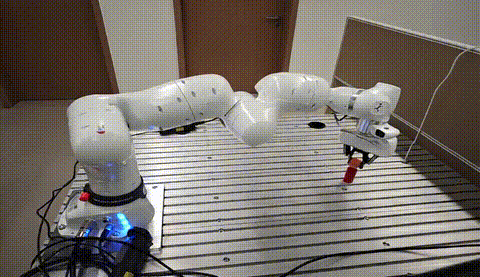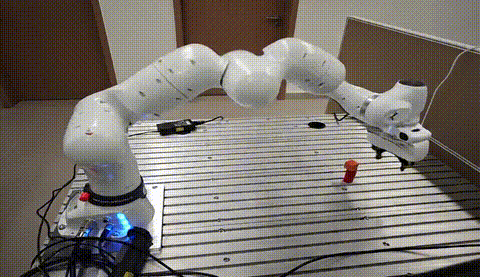
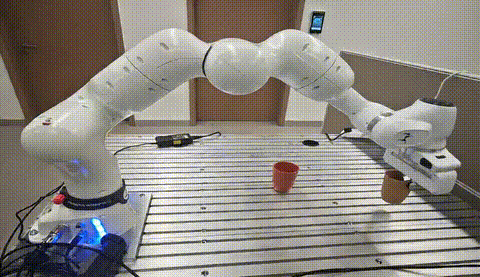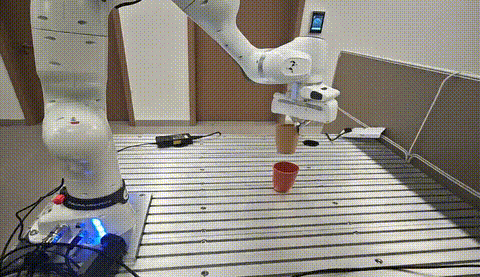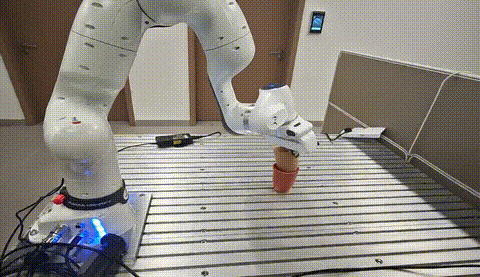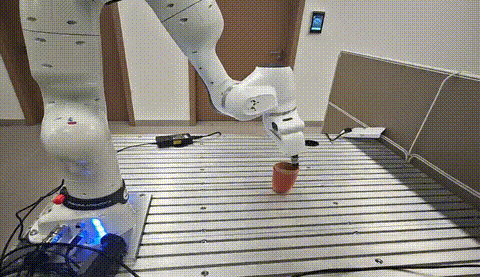
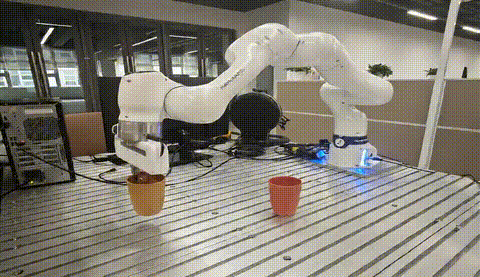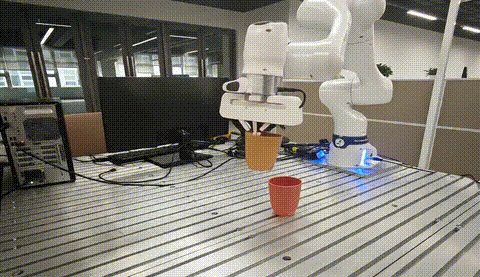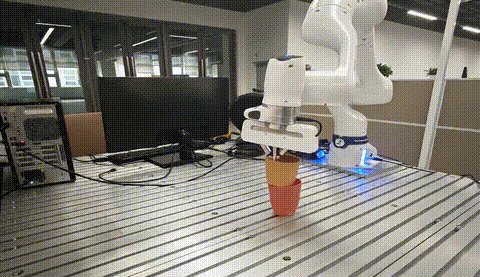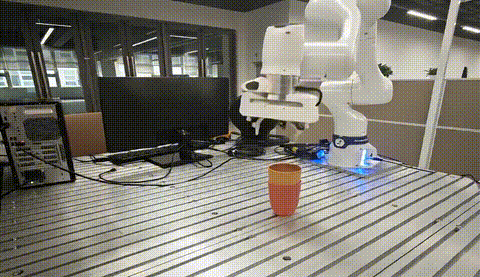
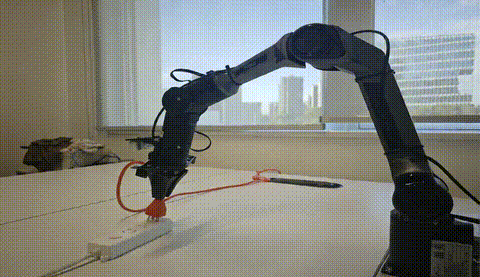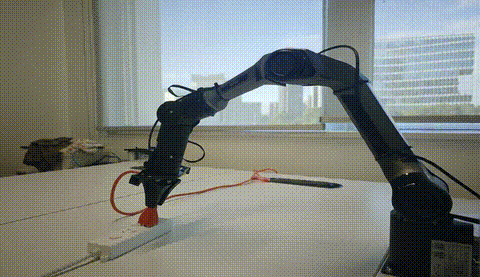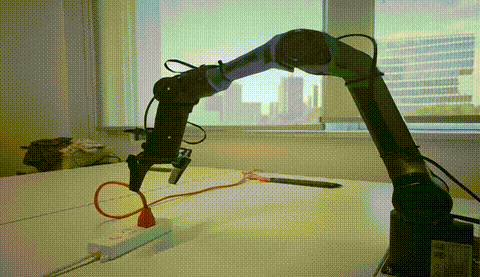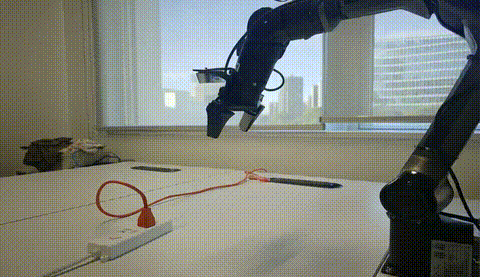
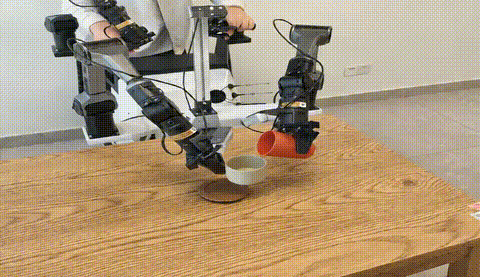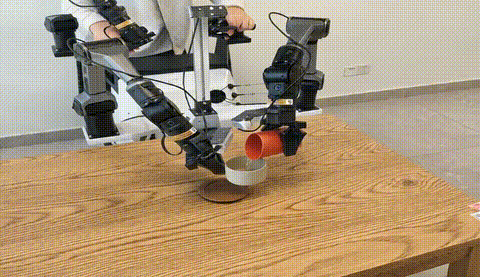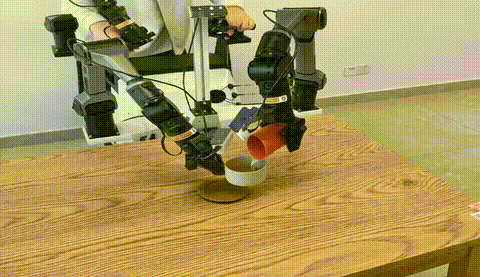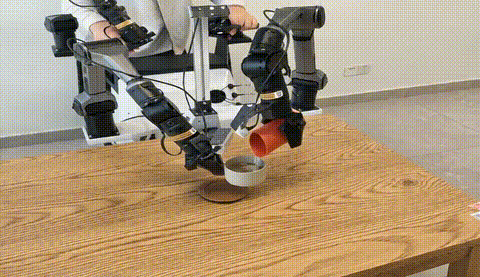
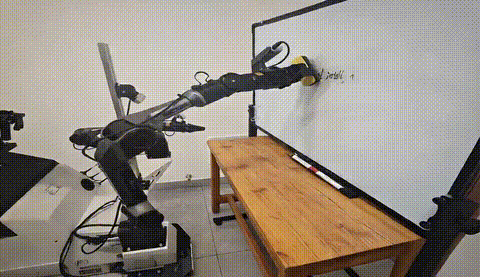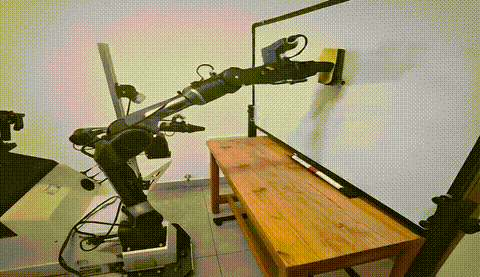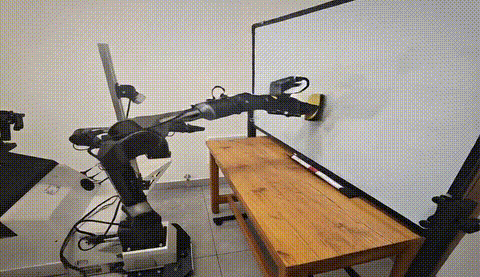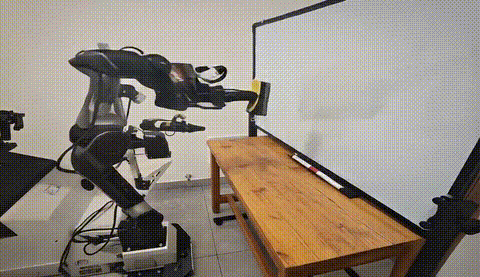
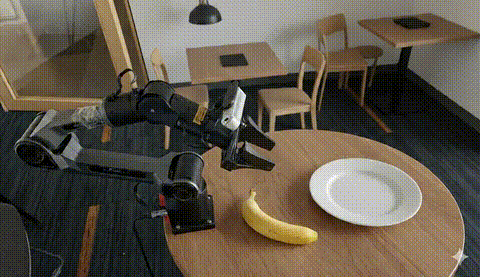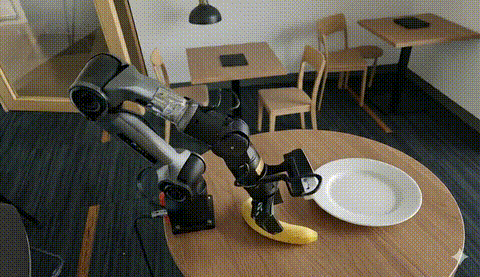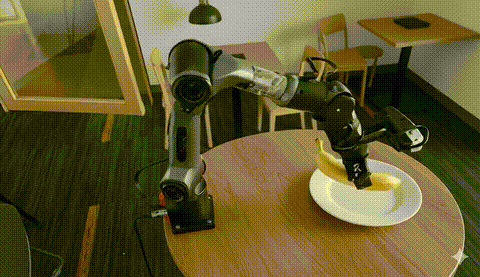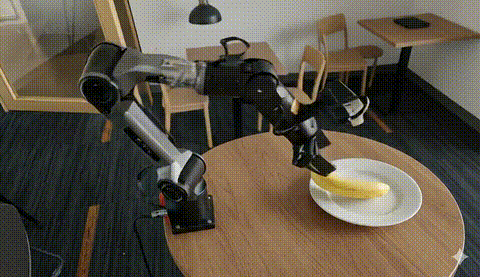
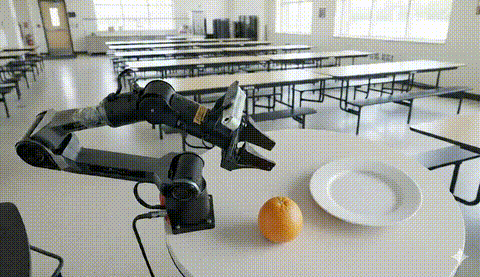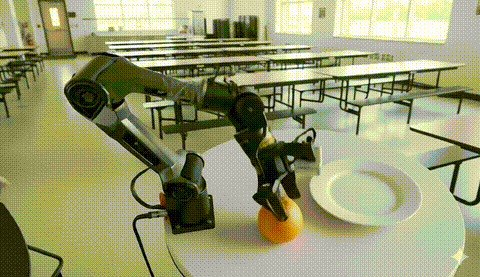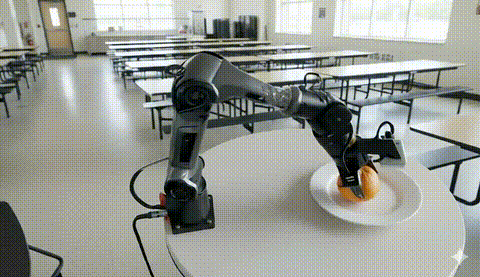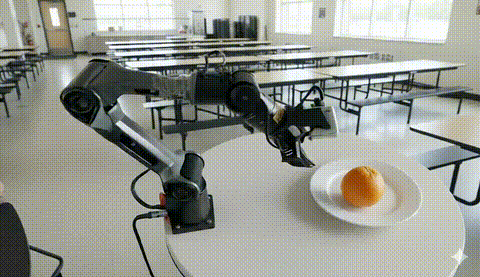
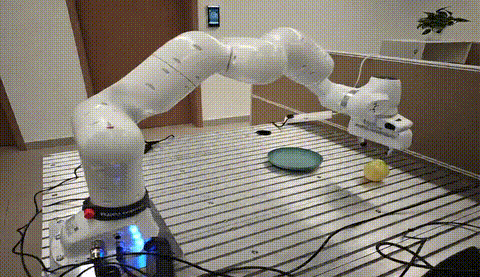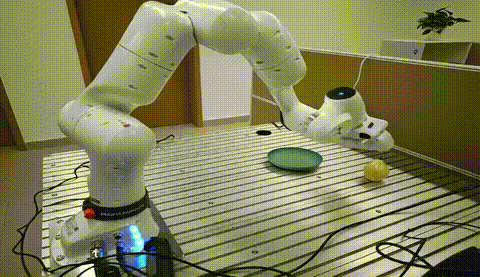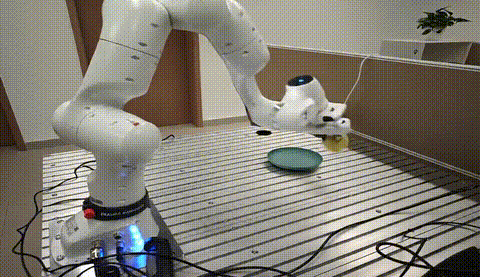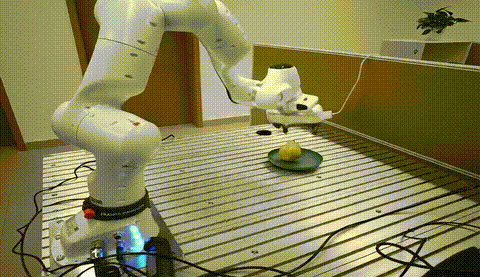
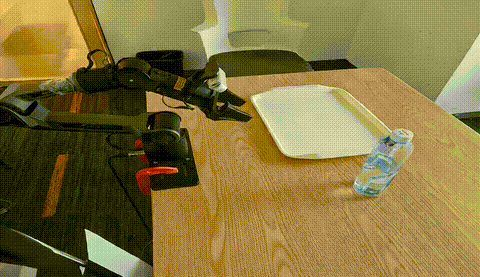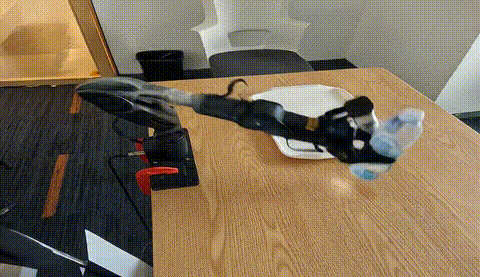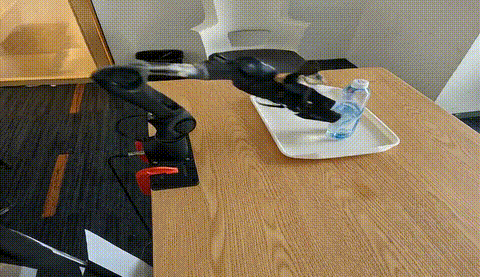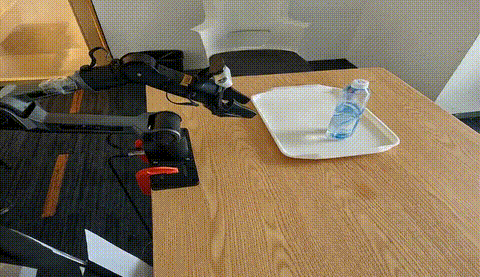
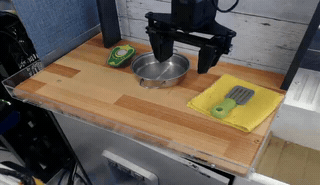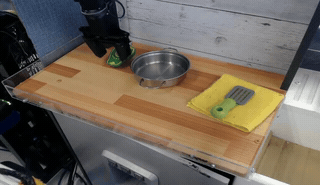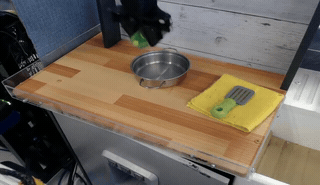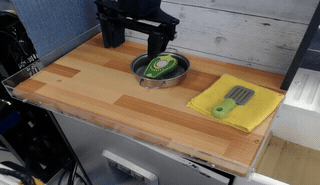
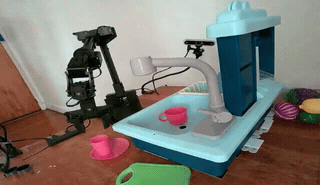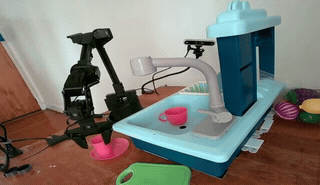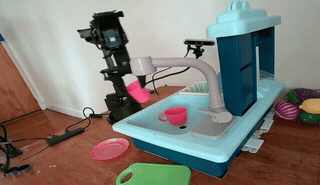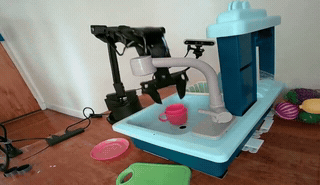
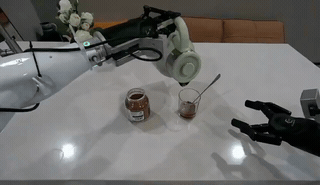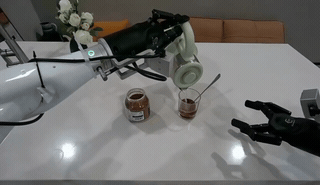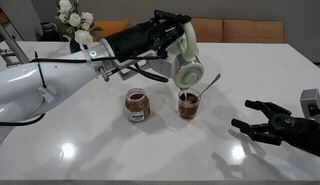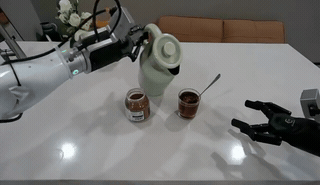
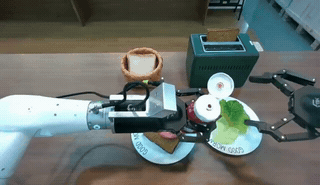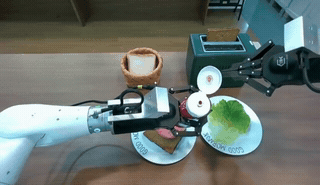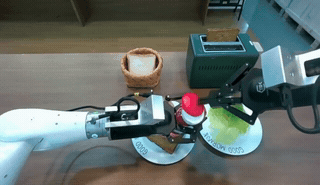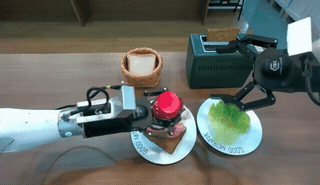
> **ABot-PhysWorld** is a physically consistent, action-controllable video world model for robotic manipulation, built on a 14-billion-parameter Diffusion Transformer. It integrates physics-aware training, memory-efficient preference optimization, and precise spatial action injection to generate realistic and physically plausible robot-object interactions — even in zero-shot settings.
## 🗞️ News
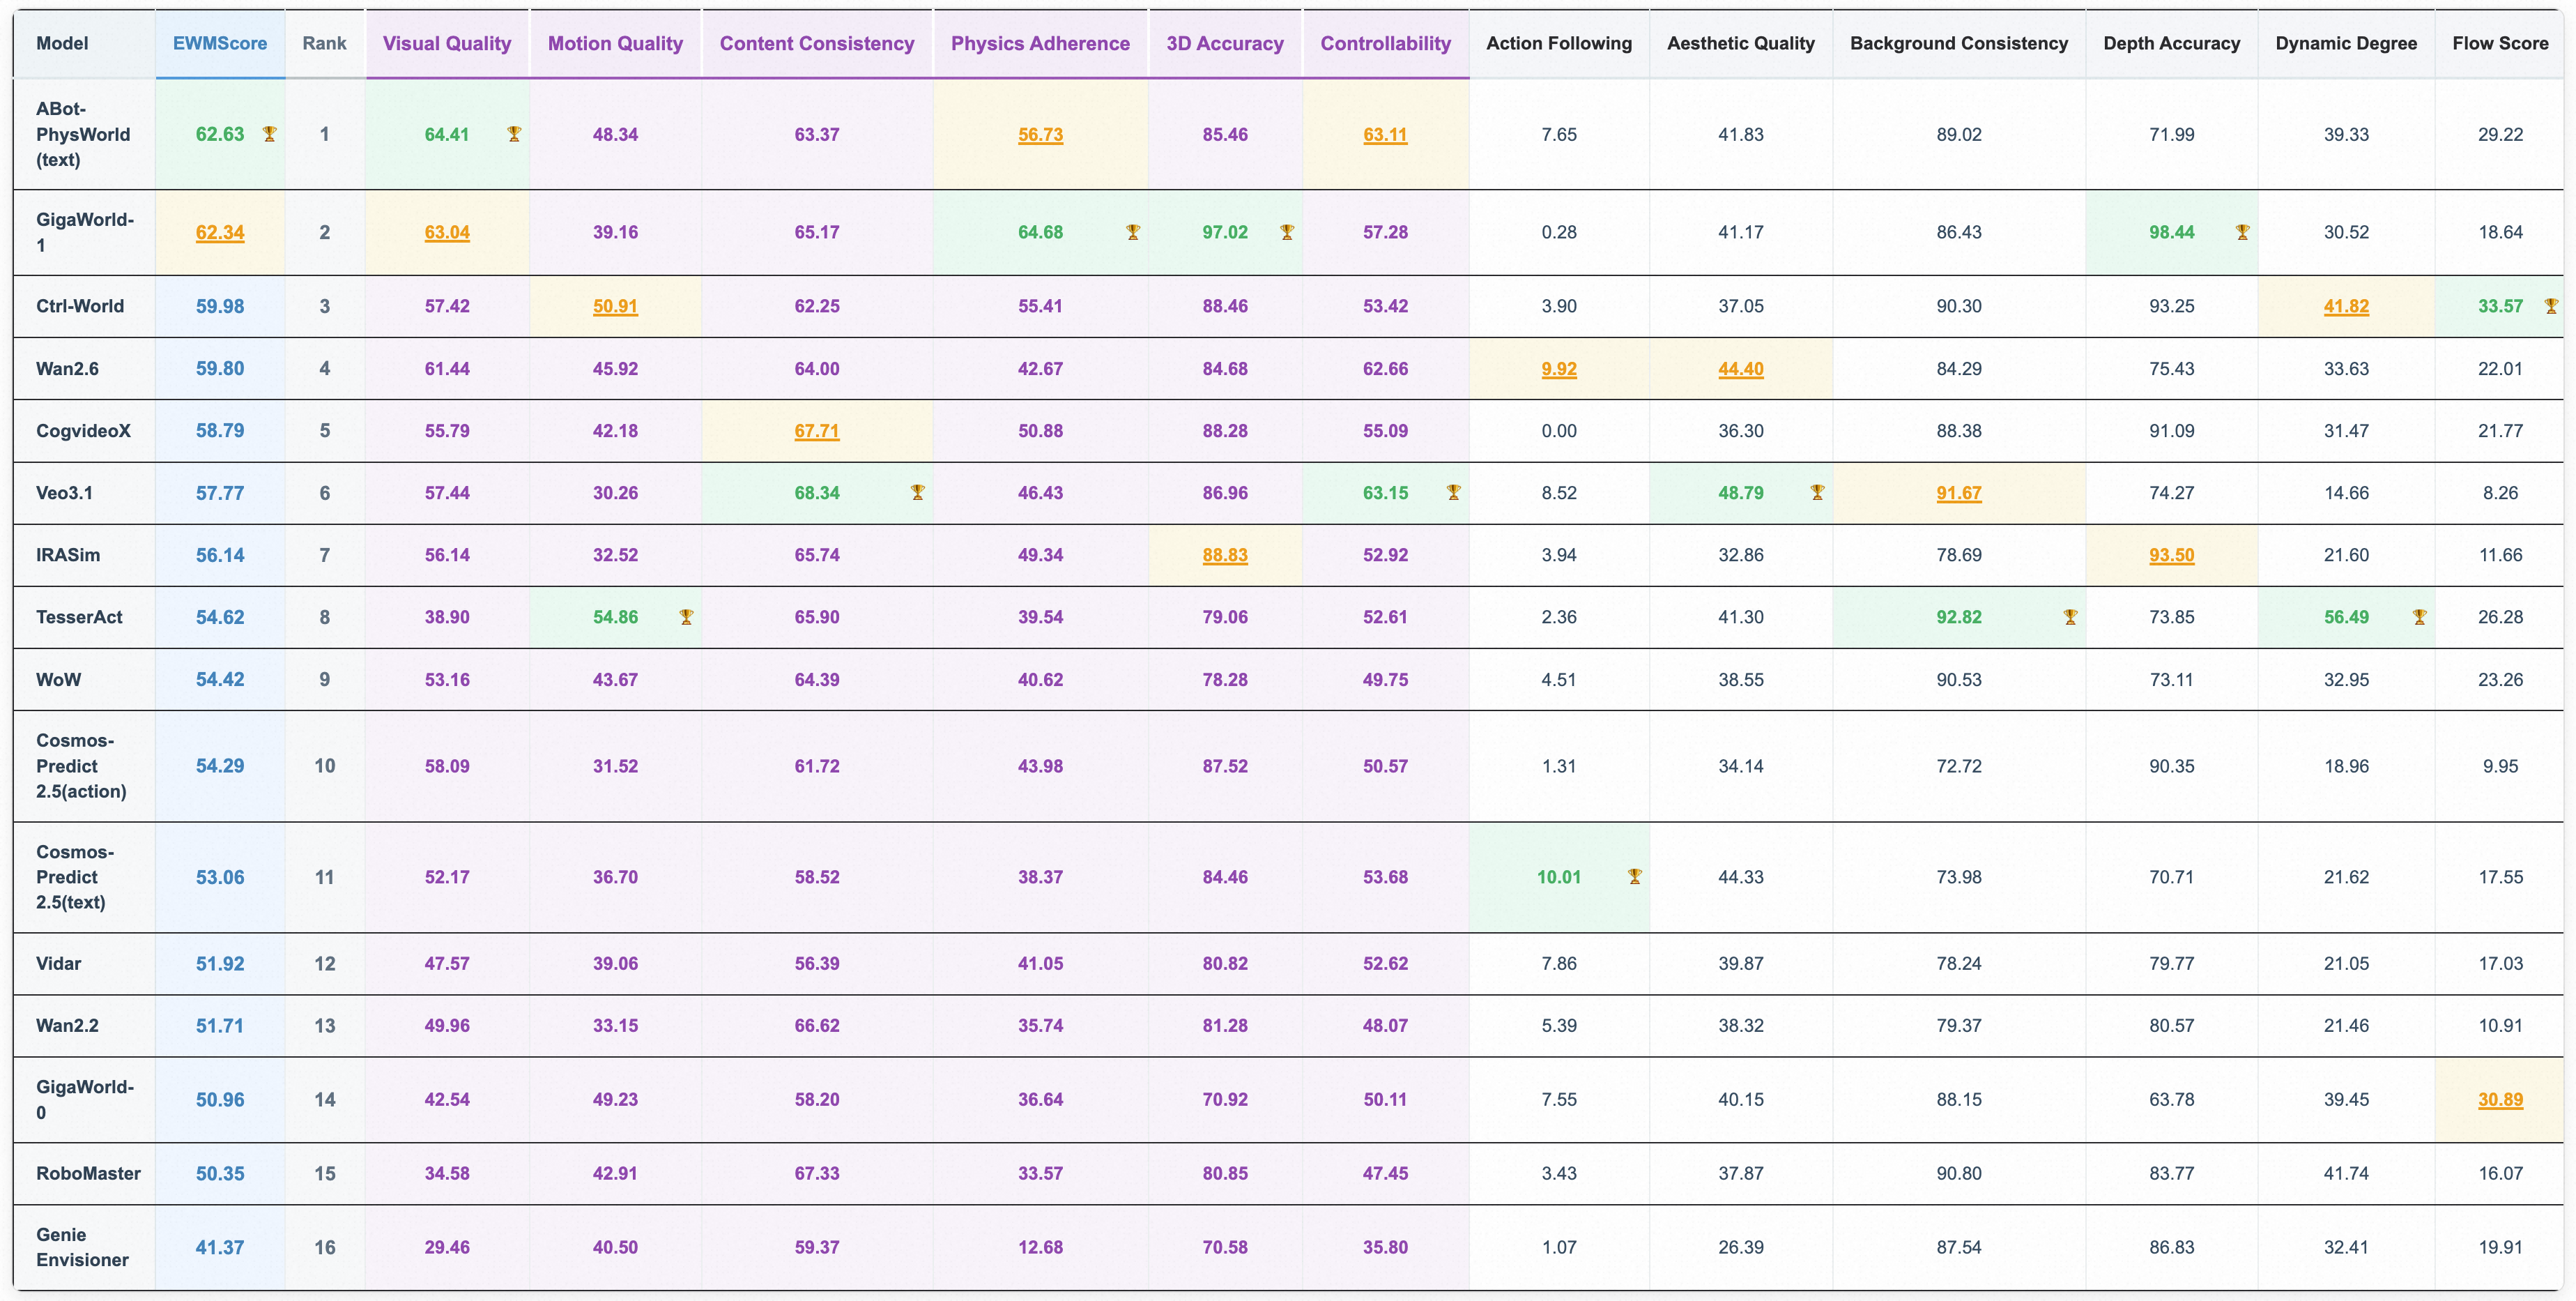
- **[2026-04]** 🏆 **1st Place on [WorldArena Leaderboard](https://huggingface.co/spaces/WorldArena/WorldArena)!** ABot-PhysWorld achieves the top rank on the WorldArena benchmark.
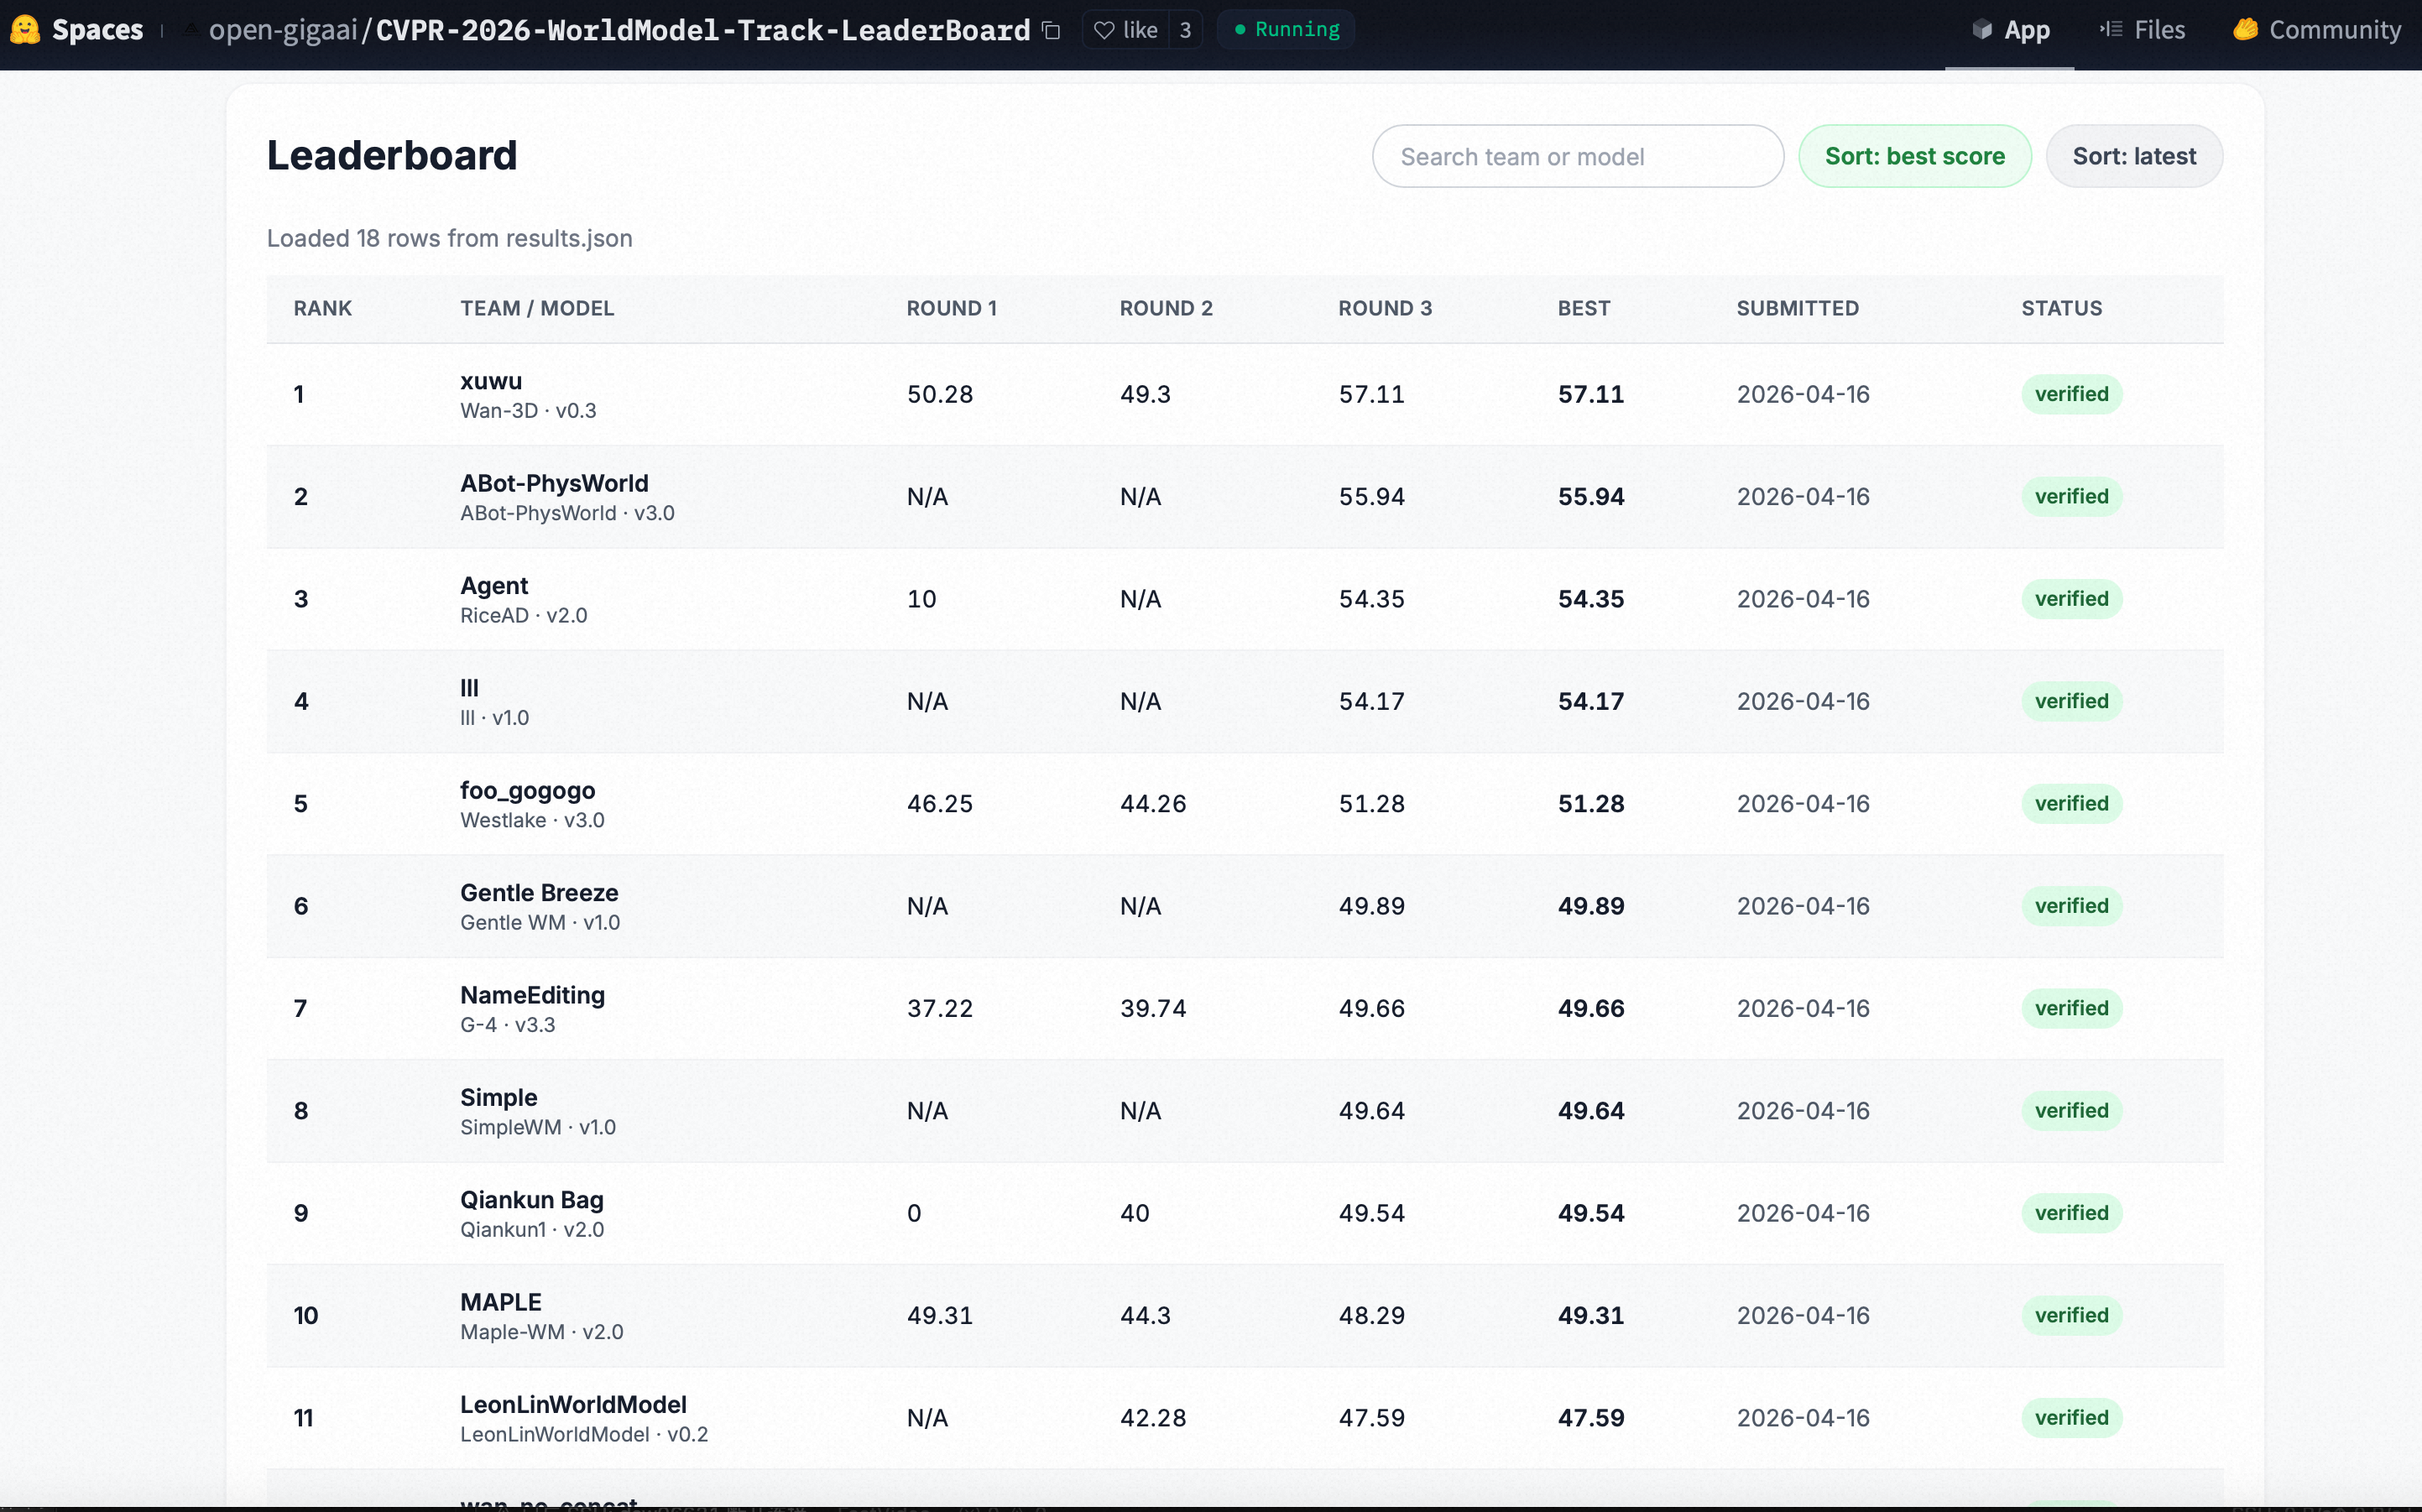
- **[2026-04]** 🥈 **2nd Place on [GigaBrain Challenge CVPR 2026 – World Model Track](https://huggingface.co/spaces/open-gigaai/CVPR-2026-WorldModel-Track-LeaderBoard)!** ABot-PhysWorld secures the runner-up position in the CVPR 2026 GigaBrain Challenge World Model Track.
- **[2026-04]** 🎮 **A2V code released!** Action-to-Video training and inference via VACE parallel context blocks. See [`training/README_A2V.md`](training/README_A2V.md) and [`inference/README_A2V.md`](inference/README_A2V.md).
- **[2026-04]** 🧪 **DPO training released!** Direct Preference Optimization pipeline for physics-aware alignment with LoRA. See [`training/README_DPO.md`](training/README_DPO.md).
- **[2026-03]** 🎉 **Training code released!** Full-parameter SFT training scripts for fine-tuning on custom robot manipulation datasets. See [`training/`](training/).
- **[2026-03]** 📦 **SFT training data released!** The v1 SFT training dataset is available on [ModelScope](https://www.modelscope.cn/datasets/amap_cvlab/ABot-PhysWorld_SFT_Training_Data_v1).
- **[2026-03]** 🔬 **Benchmark released!** EZS-Bench evaluation toolkit and data are open-sourced. See [`EZS-Bench/`](EZS-Bench/).
- **[2026-03]** 🚀 **Inference code released!** Generate robot manipulation videos with the pre-trained model. See [`inference/`](inference/).
### 🏆 Competition Results
#### WorldArena Leaderboard – 🥇 1st Place
👆 Click the image to view the live leaderboard on HuggingFace
#### GigaBrain Challenge CVPR 2026 – World Model Track – 🥈 2nd Place
👆 Click the image to view the live leaderboard on HuggingFace
## Table of Contents
- [📚 Key Contributions](#-key-contributions)
- [🚀 EZS-Bench](#-ezs-bench)
- [📊 Evaluation](#-Evaluation)
- [🖼️ Qualitative Results](#️-qualitative-results)
- [🛠️ Usage](#️-usage)
- [🏋️ Training](#️-training)
- [🎮 A2V (Action-to-Video)](#-a2v-action-to-video)
- [🧪 DPO Training](#-dpo-training)
- [📜 Citing](#-Citing)
## 📚 Key Contributions
1. **Industrial-Grade Data Pipeline**
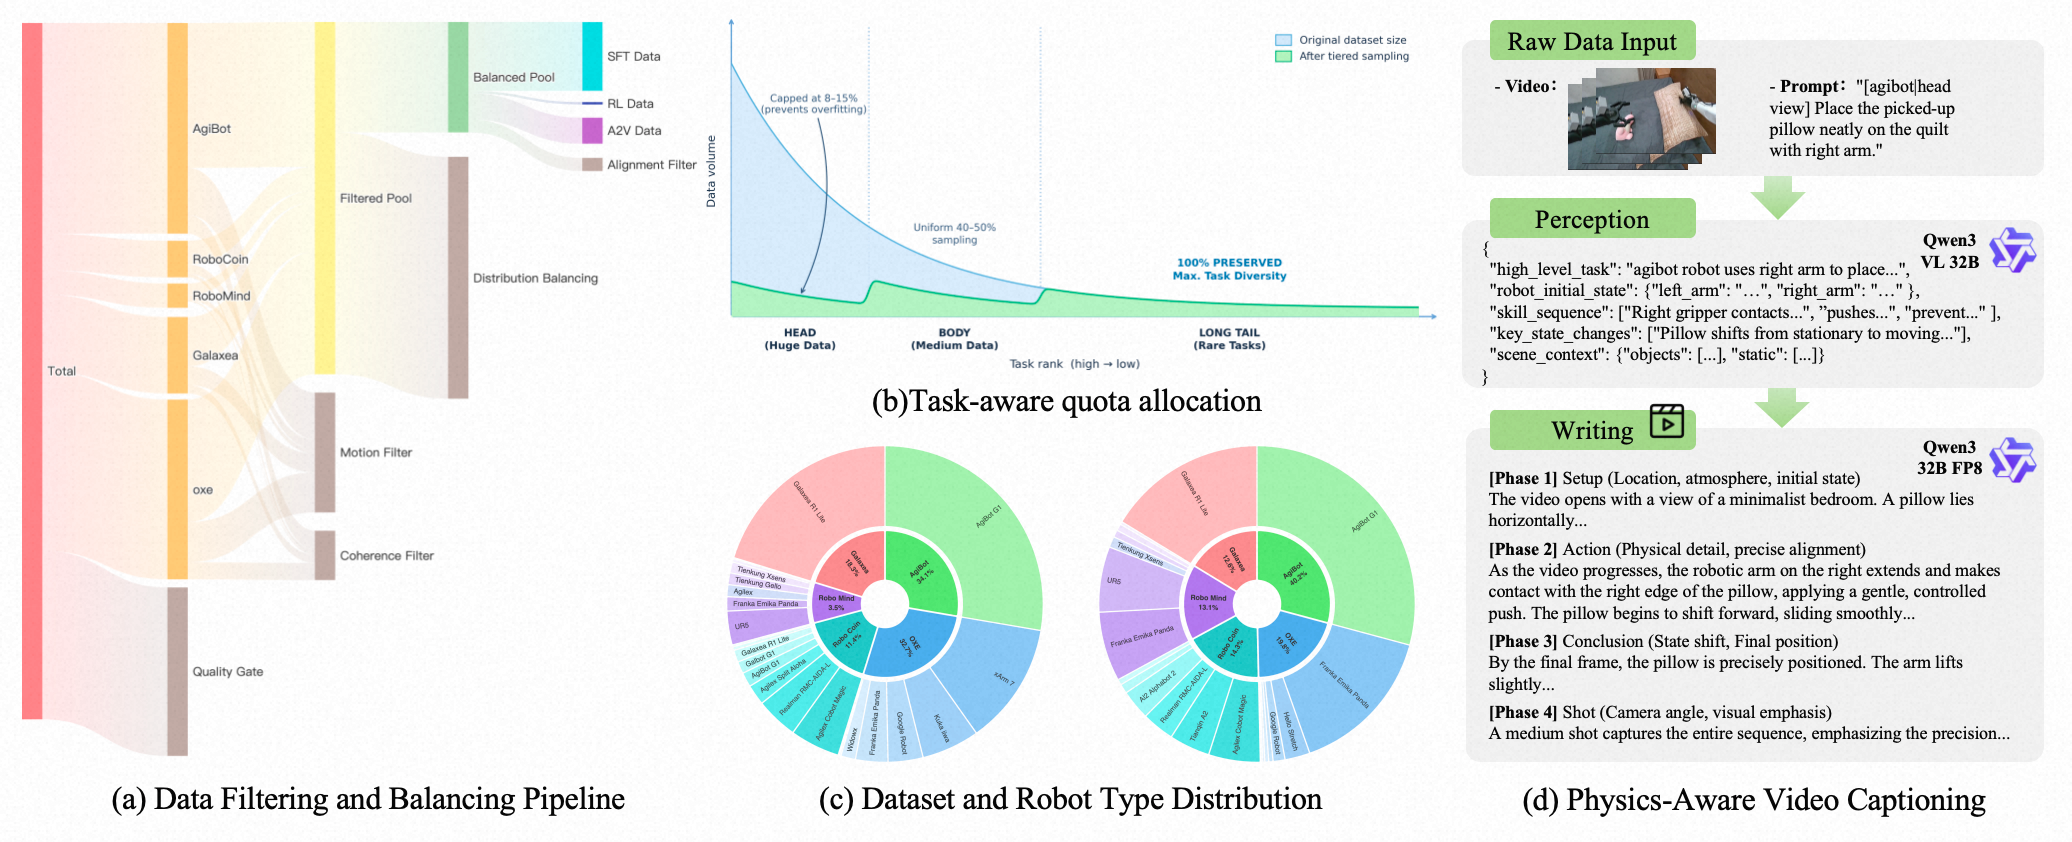
Curated ~3M real-world manipulation clips from five datasets (`AgiBot`, `RoboCoin`, `RoboMind`, `Galaxea`, `OXE`) with motion, semantic, and action consistency filtering, plus hierarchical sampling for balanced generalization.
2. **Physics-Aware DPO Training**
Introduces a decoupled VLM-based discriminator: Qwen3-VL generates task-specific physics checklists, Gemini 3 Pro scores videos via Chain-of-Thought; combined with LoRA-augmented DPO on a 14B DiT to enforce physical plausibility.
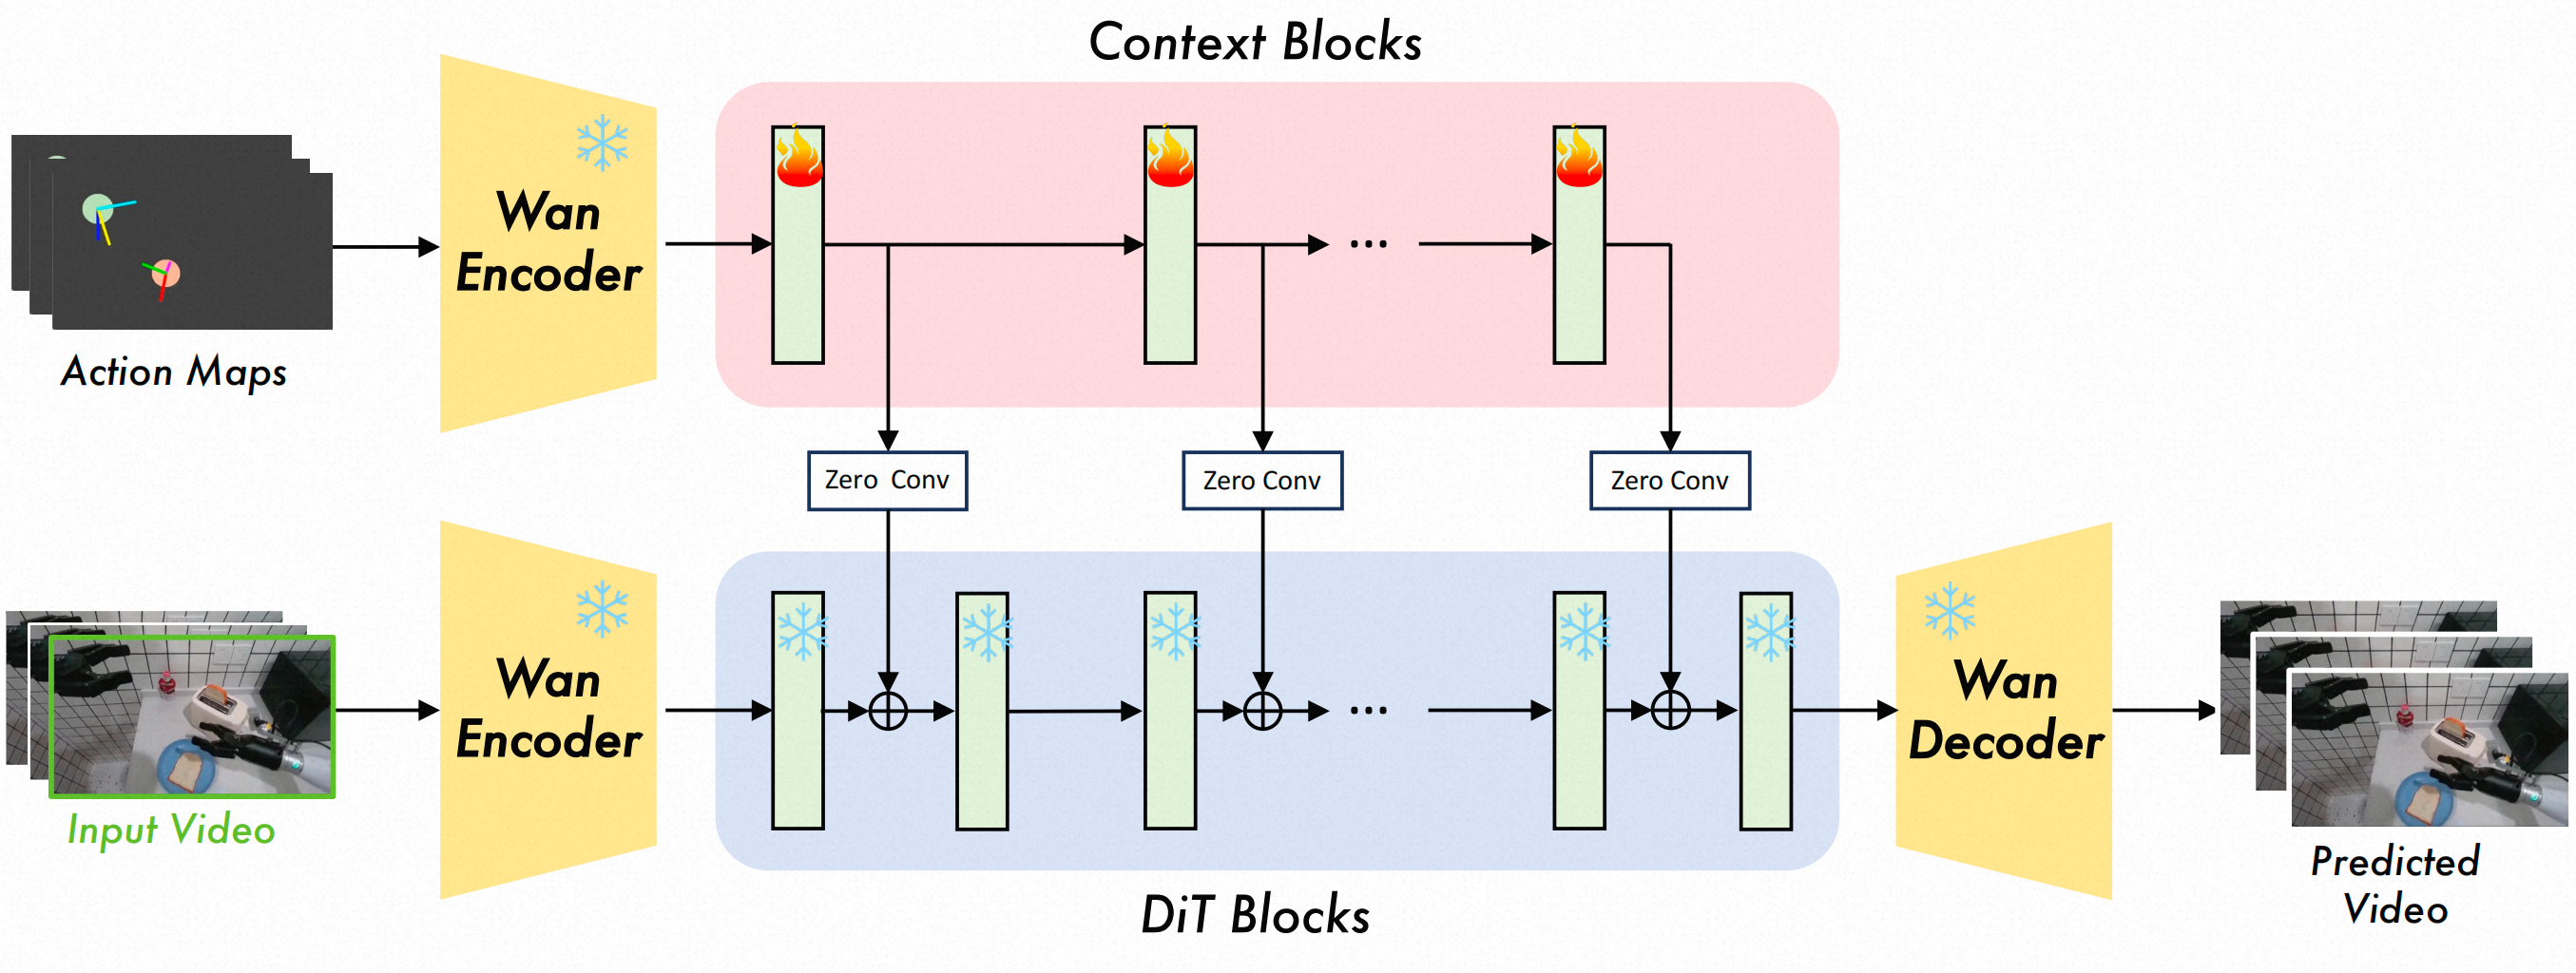
3. **Parallel Context Blocks for Action Control**
Enables precise action-conditioned generation by residually injecting spatial action maps into cloned DiT blocks, preserving physical priors while supporting cross-embodiment control.
4. **EZSbench – First True Zero-Shot Benchmark**
Fully training-independent evaluation covering unseen robot, scene, and task combinations, with dual-model scoring to eliminate self-evaluation bias.
---
## 🚀 EZS-Bench
**Embodied-ZeroShot Benchmark for Physically Consistent Video Generation** 🤖✨
EZS-Bench is a zero-shot evaluation benchmark designed to rigorously assess **physically plausible video generation** in robotic manipulation. It evaluates models on **physical consistency**, **action controllability**, and **cross-embodiment generalization**—with *no training-test data overlap*. 🔍🔬
### ✨ Key Features
✅ **True Zero-Shot Evaluation**
Unseen combinations of:
- 🤖 Robot morphologies (e.g., single-arm, bimanual, custom kinematics)
- 🌍 Scenes & backgrounds
- 🎯 Manipulation tasks (pick-and-place, wiping, assembly, etc.)
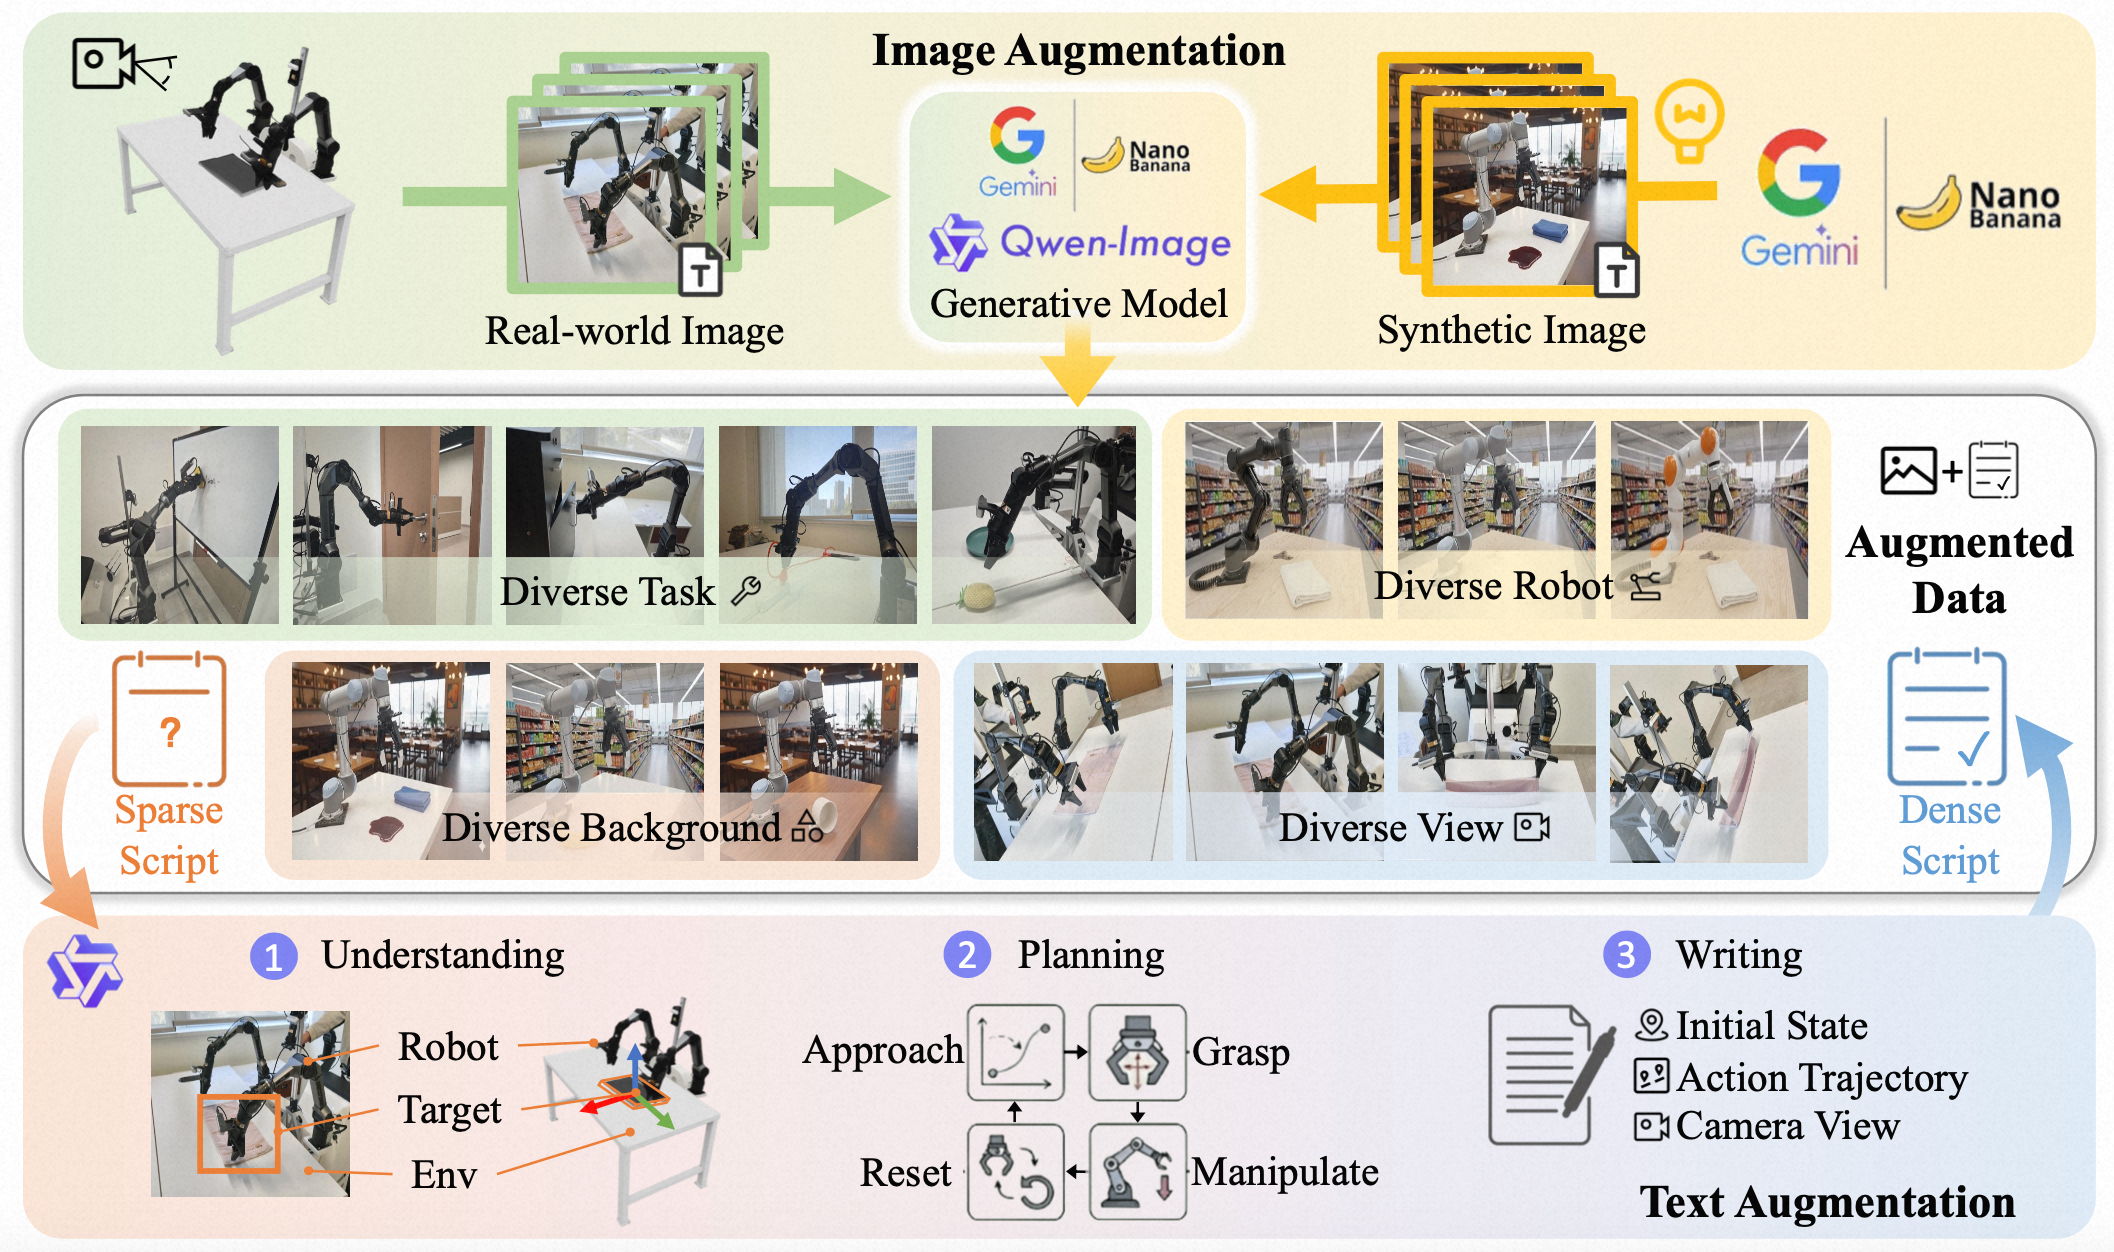
🎨 **Dual-Source Data Construction**
- 🧬 *Synthetic branch*: Text-to-image generation with controlled variation
- 🖼️ *Real-world editing*: VLM-driven scene augmentation preserving physical interactions
🧠 **Physics-Aware Evaluation**
- Dynamic physical checklists generated by VLMs (e.g., *"Does the gripper penetrate the object?"*, *"Is gravity respected?"*)
- 30–50% negative questions to prevent guessing 🚫
- Decoupled scorer architecture to eliminate self-evaluation bias ⚖️
📊 **Comprehensive Metrics**
Evaluates:
- Physical fidelity (penetration, contact, deformation) 💥
- Temporal coherence 🕒
- Spatial alignment & trajectory consistency 🎯
### 📦 Getting Started
**Download evaluation data** from ModelScope:
git lfs install
git clone https://www.modelscope.cn/datasets/amap_cvlab/EZS-Bench_data.git
**Install and run** the evaluation toolkit:
cd EZS-Bench
pip install -e .
# Full evaluation (Video Quality + Domain Score)
torchrun --standalone --nproc_per_node=4 evaluate_ezsbench.py \
--data_file /path/to/EZS-Bench_data/video_prompt_question_196_ezs0.jsonl \
--method_name "YourMethod" \
--method_dir /path/to/generated_videos \
--output_dir ./results
> The VLM judge model (Qwen2.5-VL-72B-Instruct, ~150 GB) is automatically downloaded on first run.
🔗 *See [EZS-Bench/README.md](EZS-Bench/README.md) for full documentation.*
---
## 📊 Evaluation
We evaluate ABot-PhysWorld on three key aspects:
- **Physical Consistency** (via **PBench** and **EZSbench**)
- **Zero-Shot Generalization** (via **EZSbench**)
- **Action-Conditioned Controllability** (via custom A2V benchmark)
### 📈 Summary of Advancements 🎉🎉
| Capability | Benchmark | Ours | Best Baseline | Gain |
|----------|-----------|------|---------------|------|
| Physical Fidelity | PBench (Domain Score) | **0.9306** | 0.8644 (Wan2.5) | +6.62% |
| Zero-Shot Generalization | EZSbench (Domain Score) | **0.8366** | 0.7951 (WoW) | +4.15% |
| Action Control | Trajectory Consistency | **0.8522** | 0.8157 (Enerverse) | +3.65% |
✅ ABot-PhysWorld establishes a new standard for **physically grounded**, **controllable**, and **generalizable** world models in robotic manipulation.
---
## 🖼️ Qualitative Results
Selected representative zero-shot generation results demonstrating ABot-PhysWorld's strong generalization and physical plausibility.
### 🎯 Zero-Shot Capabilities
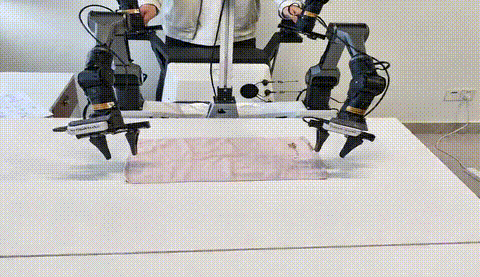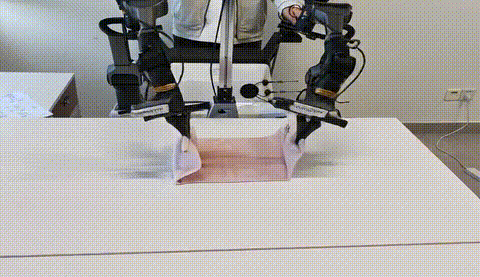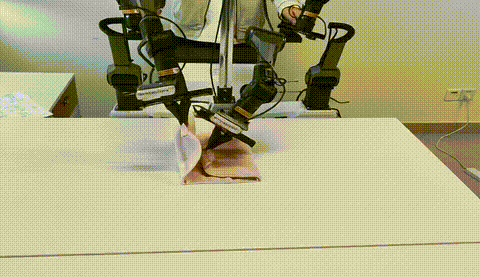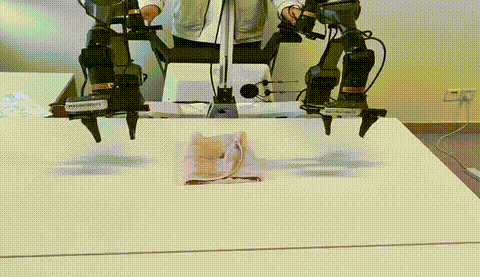
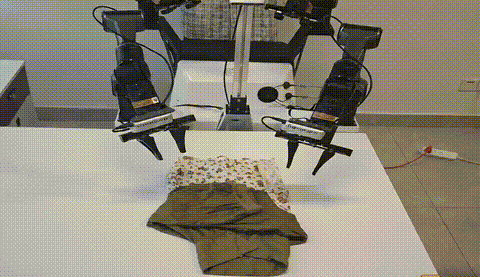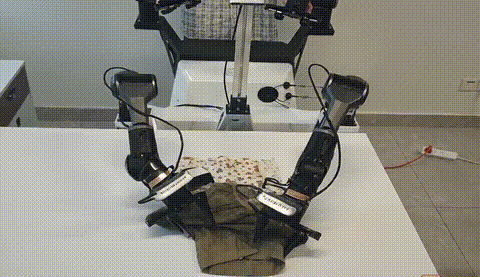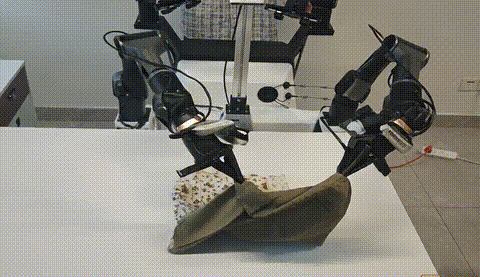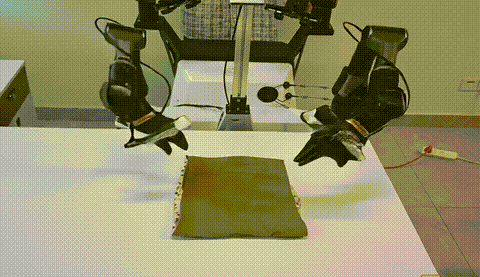
#### 🔧 Scene 1: Deformable Object – Dual-Arm Towel Folding
- **Task**: Fold a towel using dual robotic arms
- **Challenge**: Complex cloth dynamics and bimanual coordination
- **Ours**:
✅ Physically realistic deformation
✅ Smooth, collision-free arm motion
✅ Natural folding sequence with consistent contact
#### 🥤 Scene 2: Fine Manipulation – Diverse Object Handling
- **Task**: Stack cups, build blocks, place a knife
- **Challenge**: Varying shapes, weights, and friction
- **Ours**:
✅ Accurate grasp pose prediction
✅ Adaptive gripper control
✅ Stable pick-and-place without slippage or penetration
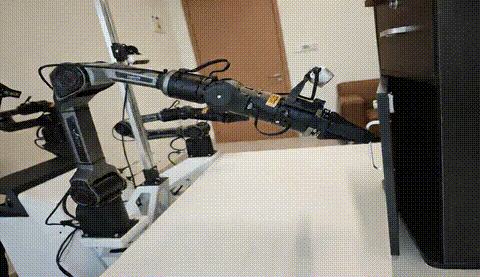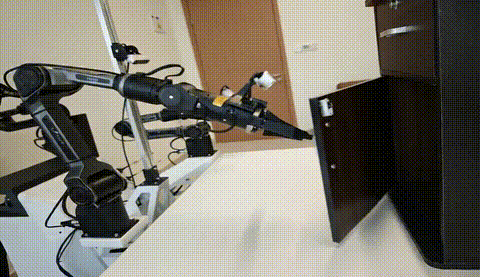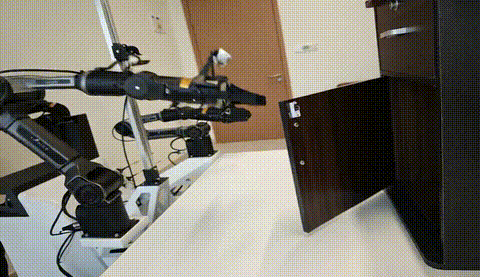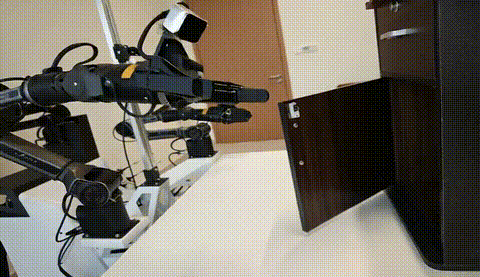
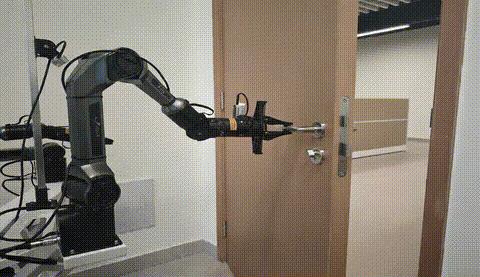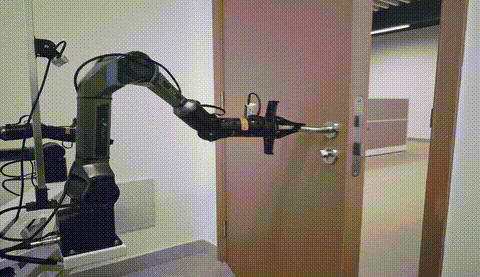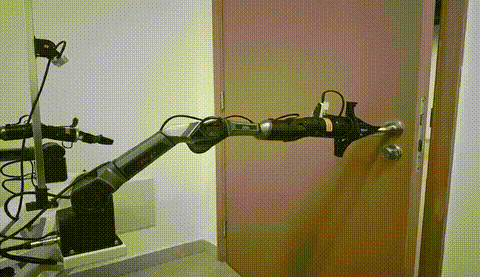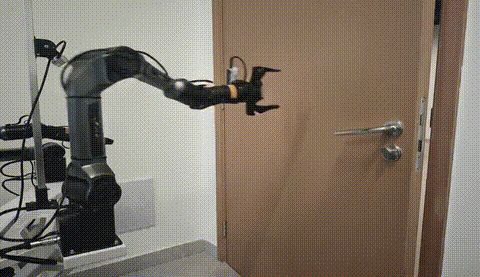
#### 🚪 Scene 3: Articulated Object – Opening a Cabinet Door
- **Task**: Open a hinged cabinet or door
- **Challenge**: Enforce rotational constraints and correct force direction
- **Ours**:
✅ Proper handle grasping
✅ Realistic hinge rotation
✅ Motion follows physical pivot axis
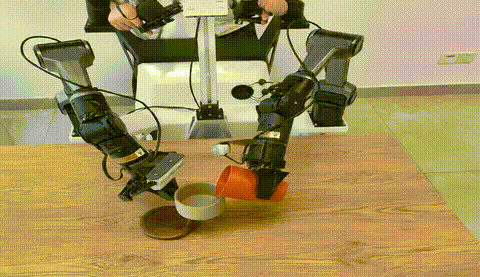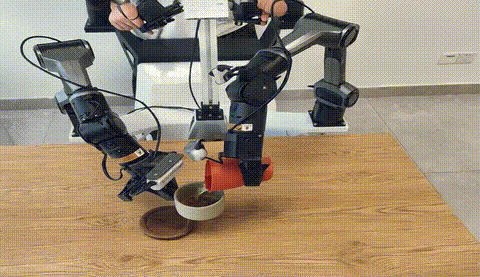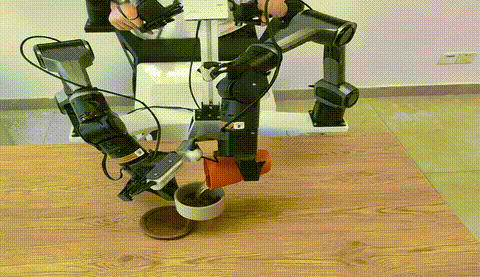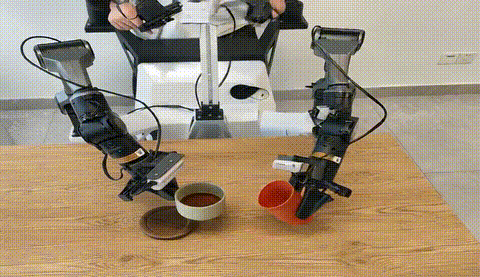
#### 🫗 Scene 4: Fluid Interaction – Pouring Water
- **Task**: Pour water from a cup into a bowl using dual arms
- **Challenge**: Bimanual coordination, tilt control, liquid dynamics
- **Ours**:
✅ Collision-free trajectory planning
✅ Accurate pour timing and angle
✅ Visual consistency in fluid transfer (simulated proxy)
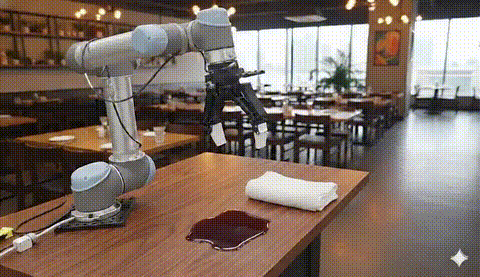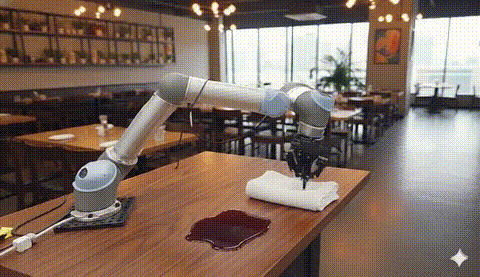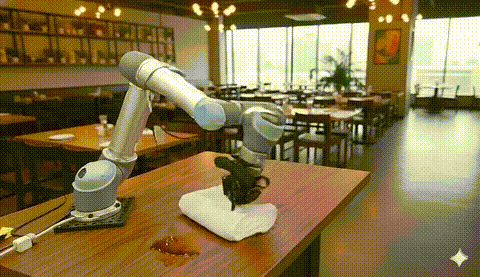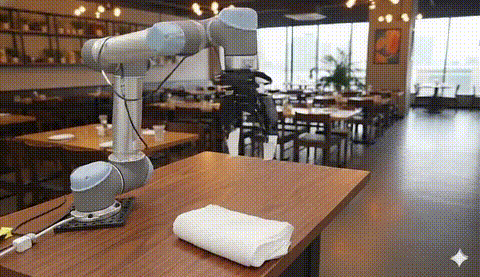
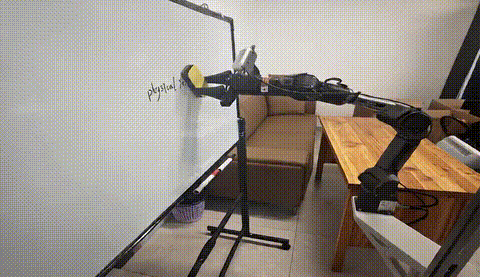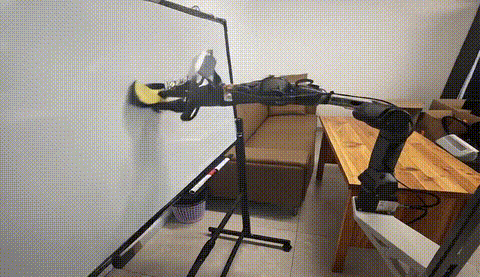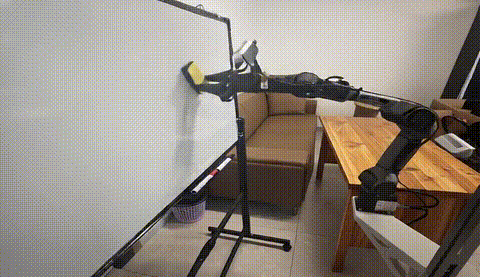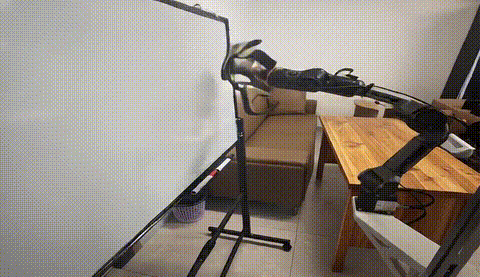
#### 🧽 Scene 5: Cleaning Task – Wiping a Stain
> Note: The Gemini watermark (bottom-right) indicates the initial frame generated by Gemini (ensuring it is completely unseen); all other frames are generated by ABot-PhysWorld.
- **Task**: Wipe a stain off a table
- **Challenge**: Maintain contact, uniform pressure, full coverage
- **Ours**:
✅ Continuous tool-surface contact
✅ Systematic wiping motion
✅ Gradual removal of the stain in video output
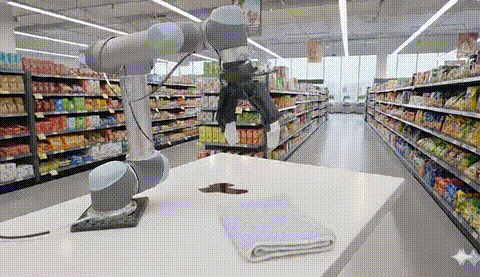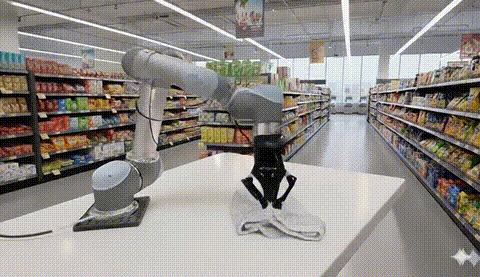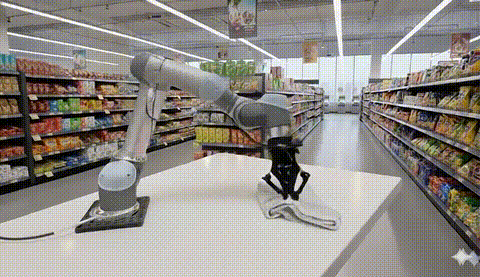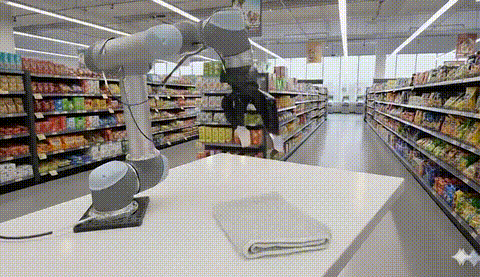
#### 🍓 Scene 6: Multi-Scene Generalization – Fruit Sorting
> Note: The Gemini watermark (bottom-right) indicates the initial frame generated by Gemini (ensuring it is completely unseen); all other frames are generated by ABot-PhysWorld.
- **Task**: Place fruits into a plate across diverse scenes
- **Challenge**: Background, lighting, and fruit variation
- **Ours**:
✅ Robust object recognition under domain shifts
✅ Consistent performance across unseen environments
✅ Fast and stable manipulation regardless of setup
### 🔍 Pbench Results Demonstration
We conducted systematic qualitative comparative experiments on the **PAI-Bench** benchmark dataset. Below are the generated results from several typical scenarios.
| Task | Baselines | **Ours** |
|------|-----------------------------|--------|
| Grasping | Frequent penetration, floatation | ✅ Firm contact, no violation |
| Long-horizon Planning | Inconsistent state transitions | ✅ Coherent multi-step reasoning |
| Rigid-body Dynamics | Unphysical deformations | ✅ Preserved geometry and mass behavior |
| Contact Modeling | Non-contact attraction | ✅ Realistic interaction onset |
> Our model consistently generates physically valid trajectories even in complex, unseen scenarios — proving its utility as a reliable simulator for embodied AI.
---
## 🛠️ Usage
### Quick Start: Video Generation Inference
Generate physically plausible robot manipulation videos using the **ABot-PhysWorld** fine-tuned model.
#### Environment Setup
```bash
# Create conda environment
conda create -n abot-physworld python=3.10
conda activate abot-physworld
# Install PyTorch with CUDA support
pip install torch torchvision --index-url https://download.pytorch.org/whl/cu121
# Install dependencies
pip install -r requirements.txt
```
**Hardware Requirements:**
| Configuration | VRAM | Notes |
|---|---|---|
| **Recommended** | >= 60GB | Best performance, no tiling needed |
| **Minimum** | >= 24GB | Uses tiled VAE (enabled by default) |
#### Demo: Generate Video from Image + Text Prompt
```bash
cd inference
# Download demo data and run inference
python inference.py \
--jsonl_path assets/demo.jsonl \
--output_dir ./outputs/demo \
--save_first_frames
```
This generates videos for 2 Franka robot manipulation samples. The model checkpoint is auto-downloaded from [ModelScope](https://www.modelscope.cn/models/amap_cvlab/Abot-PhysWorld) on first run.
#### Single Image Inference
```bash
python inference.py \
--input_image /path/to/image.jpg \
--prompt "robot arm picks up the red cube from the table" \
--output_dir ./outputs
```
#### Batch Inference from JSONL
Prepare a JSONL file (each line is a sample):
```json
{"video": "path/to/image.jpg", "prompt": "robot grasps the object"}
{"video": "path/to/image2.jpg", "prompt": "robot places object on table"}
```
Then run:
```bash
python inference.py \
--jsonl_path data.jsonl \
--output_dir ./outputs \
--num_samples 100 # Process max 100 samples
```
#### Full Parameter Reference
```bash
python inference.py --help
```
Key parameters:
- `--checkpoint_path`: Local path to model weights (auto-downloads if not provided)
- `--cache_dir`: Directory to store downloaded weights (default: `./checkpoints`)
- `--height`, `--width`: Video resolution (default: 480×832)
- `--num_frames`: Number of output frames (default: 81 ≈ 5.4s at 15fps)
- `--num_inference_steps`: Denoising steps, higher = better quality but slower (default: 50)
- `--cfg_scale`: Classifier-free guidance scale (default: 5.0)
- `--seed`: Random seed for reproducibility
- `--gpu_id`: GPU device index
#### Output
- **Single image**: `{output_dir}/{image_name}_generated.mp4`
- **Batch mode**: `{output_dir}/{unique_id}_generated.mp4` + `results.json` (with status for each sample)
---
### Model Weights
**Auto-Download:** The fine-tuned checkpoint is automatically downloaded from [ModelScope](https://www.modelscope.cn/models/amap_cvlab/Abot-PhysWorld) on first inference run.
**Manual Download (Optional):**
```bash
pip install modelscope
modelscope download --model amap_cvlab/Abot-PhysWorld --local_dir ./inference/checkpoints
```
**Base Model:** Wan2.1-I2V-14B-480P is also auto-downloaded by DiffSynth-Studio.
---
### More Details
For detailed setup instructions, examples, and troubleshooting, see [`inference/README.md`](inference/README.md).
---
## 🏋️ Training
We provide full-parameter SFT training scripts to fine-tune Wan2.1-I2V-14B-480P on your own robot manipulation datasets.
### Training Data
The v1 SFT training dataset is available on ModelScope:
```bash
git lfs install
git clone https://www.modelscope.cn/datasets/amap_cvlab/ABot-PhysWorld_SFT_Training_Data_v1.git
```
### Quick Start
```bash
cd training
# Prepare your dataset (JSONL format, see training/assets/demo_train.jsonl)
# Then launch 8-GPU training:
bash run_train.sh
```
### Key Features
- **Full-parameter SFT** on the 14B DiT model (LoRA also supported)
- **DeepSpeed ZeRO-2** distributed training via Accelerate
- **Encoded feature caching**: Save VAE/T5/CLIP encodings to disk, skip re-encoding in subsequent runs
- **Resume from checkpoint**: Continue training from any saved step
- **Real-time text encoding**: Re-train with new captions while reusing cached video features
### Resume from Checkpoint
```bash
RESUME_CHECKPOINT=./outputs/sft_training/step-800.safetensors \
bash run_train_resume.sh
```
### Training with Encoded Cache
```bash
# First run: train + save encoded features
ENCODED_CACHE_DIR=./encoded_cache bash run_train.sh
# Subsequent runs: reuse cached features (much faster)
ENCODED_CACHE_DIR=./encoded_cache bash run_train.sh
```
For detailed training instructions, data preparation, and parameter reference, see [`training/README.md`](training/README.md).
---
## 🎮 A2V (Action-to-Video)
We release the A2V training and inference code for action-conditioned video generation via VACE parallel context blocks. Given an input image and an action trajectory (end-effector poses), the model generates a physically consistent video of the robot executing the specified actions.
### Quick Start: A2V Training
```bash
cd training
# Train VACE module on top of SFT DiT
DIT_CHECKPOINT=/path/to/dit_checkpoint.safetensors \
DATASET_BASE_PATH=/path/to/dataset \
DATASET_METADATA_PATH=/path/to/metadata.jsonl \
bash run_train_a2v.sh
```
### Quick Start: A2V Inference
```bash
cd inference
# Run A2V inference (checkpoints auto-downloaded from ModelScope)
python inference_a2v.py \
--jsonl_path ./assets/demo_a2v.jsonl \
--output_dir ./outputs/a2v_results
# With trajectory overlay visualization
python inference_a2v.py \
--jsonl_path data.jsonl \
--output_dir ./outputs \
--overlay_action_condition
```
For detailed documentation, see [`training/README_A2V.md`](training/README_A2V.md) and [`inference/README_A2V.md`](inference/README_A2V.md).
---
## 🧪 DPO Training
We release the DPO (Direct Preference Optimization) training pipeline for physics-aware alignment. Using winner/loser video pairs, the model learns to generate videos that better respect physical laws via LoRA fine-tuning.
### Pipeline
1. **Preprocess**: Encode video pairs into cached tensors
2. **Train**: Run DPO LoRA training on cached data
```bash
cd training
# Step 1: Preprocess DPO data
DPO_JSONL=/path/to/dpo_pairs.jsonl \
CACHE_DIR=/path/to/dpo_cache \
bash run_preprocess_dpo.sh
# Step 2: Train DPO LoRA
DIT_CHECKPOINT=/path/to/dit_checkpoint.safetensors \
DPO_CACHE_DIR=/path/to/dpo_cache \
bash run_train_dpo.sh
```
For detailed documentation, see [`training/README_DPO.md`](training/README_DPO.md).
---
## 📜 Citing
If you find **ABot-PhysWorld** is useful in your research or applications, please consider giving us a **star** 🌟 and **citing** it by the following BibTeX entry:
```
@article{chen2026abotphysworld,
title={ABot-PhysWorld: Interactive World Foundation Model for Robotic Manipulation with Physics Alignment},
author={Yuzhi Chen, Ronghan Chen, Dongjie Huo, Yandan Yang, Dekang Qi, Haoyun Liu, Tong Lin, Shuang Zeng, Junjin Xiao, Xinyuan Chang, Feng Xiong, Xing Wei, Zhiheng Ma, Mu Xu},
journal={arXiv preprint arXiv:2603.23376},
year={2026}
}
```
---
## 🙏 Acknowledgement
This project builds upon the following open-source projects. We thank these teams for their contributions:
- [Wan2.1](https://github.com/Wan-Video/Wan2.1)
- [VACE](https://github.com/ali-vilab/VACE)
- [DiffSynth-Studio](https://github.com/modelscope/DiffSynth-Studio)
- [VideoX-Fun](https://github.com/aigc-apps/VideoX-Fun)
- [Qwen3](https://github.com/QwenLM/Qwen3)
- [Qwen3-VL](https://github.com/QwenLM/Qwen3-VL)
- [Physical AI Bench](https://github.com/SHI-Labs/physical-ai-bench)
- [FantasyTalking2](https://github.com/Fantasy-AMAP/fantasy-talking2)
---