> **Part of the [Ataraxy Labs](https://ataraxy-labs.com) stack**: agent-native infrastructure for software development. See also: [weave](https://ataraxy-labs.com/weave) (entity-level git merge driver) · [inspect](https://github.com/Ataraxy-Labs/inspect) (semantic code review) · [opensessions](https://github.com/Ataraxy-Labs/opensessions) (tmux sidebar for coding agents).
>
> Read the manifesto: https://ataraxy-labs.com/#thesis · Essays: https://ataraxy-labs.com/blogs · LLMs: https://ataraxy-labs.com/llms.txt


Semantic version control built on Git.
Instead of lines changed, sem tells you what entities changed: functions, methods, classes.
Why sem? ·
Install ·
Commands ·
Agents (MCP) ·
Cloud consent ·
Releases




sem is a semantic version control tool that works on top of Git. It parses your code with tree-sitter, extracts every function, class, and method as an entity, and diffs at the entity level instead of lines. This means you see "function `blahh` was modified" instead of "lines x-y changed."
It works in any Git repo with no setup.
Cloud-backed queries are opt-in per repo: logging in does not upload a repo or send a query. See the [cloud consent flow](docs/cloud-consent.html) for the public/private repo states, preview screen, local audit log, and forget controls.

## Install
```bash
curl -fsSL https://raw.githubusercontent.com/Ataraxy-Labs/sem/main/install.sh | sh
```
Or via Homebrew:
```bash
brew install sem-cli
```
Or via winget on Windows:
```powershell
winget install AtaraxyLabs.sem
```
Or via Scoop on Windows:
```powershell
scoop install sem
```
Or install the npm wrapper into `node_modules`:
```bash
npm install --save-dev @ataraxy-labs/sem
```
With Bun, trust the package so its `postinstall` script can download the binary:
```bash
bun add -d @ataraxy-labs/sem
bun pm trust @ataraxy-labs/sem
```
Once installed, update to the latest release any time:
```bash
sem update
```
Or via cargo, from [crates.io](https://crates.io/crates/sem-cli):
```bash
cargo install sem-cli
```
Or build the latest `main` from source (requires Rust):
```bash
cargo install --git https://github.com/Ataraxy-Labs/sem sem-cli
```
Or grab a binary from [GitHub Releases](https://github.com/Ataraxy-Labs/sem/releases).
Or run via Docker:
```bash
docker build -t sem .
docker run --rm -it -u "$(id -u):$(id -g)" -v "$(pwd):/repo" sem diff
```
## Name conflict with GNU Parallel
GNU Parallel ships a `sem` binary (`/usr/bin/sem`) as a symlink to `parallel`. If you have both installed, they'll collide. Run `sem --version` to check which one you're using. ([#77](https://github.com/Ataraxy-Labs/sem/issues/77))
**Quick fixes:**
```bash
# Option 1: alias in your shell profile (~/.bashrc, ~/.zshrc)
alias sem="$HOME/.cargo/bin/sem"
# Option 2: make sure cargo bin comes first in PATH
export PATH="$HOME/.cargo/bin:$PATH"
# Option 3: if installed via Homebrew
export PATH="$(brew --prefix)/bin:$PATH"
```
If you installed via npm/bun, the binary lives in `node_modules/.bin/sem` and is invoked through `npx sem` or `bunx sem`, which avoids the conflict entirely.
## Commands
Works in any Git repo. No setup required. Also works outside Git for arbitrary file comparison.
sem stores its SQLite entity cache outside the repository, under the OS cache directory by default. Set `SEM_CACHE_DIR=/path/to/cache` to override the cache root; repo-local overrides are ignored so cache files do not dirty the working tree.
### sem diff
Entity-level diff with rename detection, structural hashing, and word-level inline highlights.
```bash
# Semantic diff of working changes
sem diff
# Staged changes only
sem diff --staged
# Specific commit
sem diff --commit abc1234
# Commit range
sem diff --from HEAD~5 --to HEAD
# Verbose mode (word-level inline diffs for each entity)
sem diff -v
# Plain text output (git status style)
sem diff --format plain
# JSON output (for AI agents, CI pipelines)
sem diff --format json
# Markdown output (for PRs, reports)
sem diff --format markdown
# Compare any two files (no git repo needed)
sem diff file1.ts file2.ts
# Read file changes from stdin (no git repo needed)
echo '[{"filePath":"src/main.rs","status":"modified","beforeContent":"...","afterContent":"..."}]' \
| sem diff --stdin --format json
# Only specific file types
sem diff --file-exts .py .rs
```
### sem impact
Cross-file dependency graph shows what breaks if an entity changes.
```bash
# Full impact analysis
sem impact authenticateUser
# Direct dependencies only
sem impact authenticateUser --deps
# Direct dependents only
sem impact authenticateUser --dependents
# Affected tests only
sem impact authenticateUser --tests
# JSON output
sem impact authenticateUser --json
# Disambiguate by file
sem impact authenticateUser --file src/auth.ts
# Include default-excluded paths such as generated, fixture, vendor, benchmark, and build trees
sem impact authenticateUser --no-default-excludes
```
### sem blame
Entity-level blame showing who last modified each function, class, or method.
```bash
sem blame src/auth.ts
# JSON output
sem blame src/auth.ts --json
```
### sem log
Track how a single entity evolved through git history.
```bash
sem log authenticateUser
# Verbose mode (show content diff between versions)
sem log authenticateUser -v
# Limit commits scanned
sem log authenticateUser --limit 20
# JSON output
sem log authenticateUser --json
```
With no entity, `sem log` analyzes recent repo history at the entity level:
**hotspots** (most-changed functions/classes, with author counts) and
**co-change pairs** (entities that repeatedly change in the same commits:
"if you touch one, don't forget the other"):
```bash
sem log # repo hotspots + co-change pairs (last 50 commits)
sem log --limit 200 # deeper history
sem log --file src/auth.ts # scoped to one file
sem log --json # full data
```
### sem entities
List all entities under a file or directory path. No path is the same as `.`.
```bash
sem entities
sem entities .
sem entities src/auth.ts
# JSON output
sem entities --json
sem entities src/auth.ts --json
# Include default-excluded paths such as generated, fixture, vendor, benchmark, and build trees
sem entities --no-default-excludes
```
### sem context
Token-budgeted context for LLMs: the entity, its dependencies, and its dependents, fitted to a strict content token budget.
When the target signature itself does not fit, JSON output reports `target_omitted: true`.
```bash
sem context authenticateUser
# Custom token budget
sem context authenticateUser --budget 4000
# JSON output
sem context authenticateUser --json
# Include default-excluded paths such as generated, fixture, vendor, benchmark, and build trees
sem context authenticateUser --no-default-excludes
```
### sem find / callers / refs / grep
Cold-start lookups backed by an on-disk, mmap-able query index (`index.sem`, stored next to the SQLite entity cache). The first call in a repo builds the index; every call after that reads it directly, no daemon or background process involved:
```bash
# Find where an entity is defined
sem find "function diff_command"
# Who calls it
sem callers diff_command
# What it calls
sem refs diff_command
# Text search across source files (rg-compatible file:line:text output,
# served from the index's trigram postings when one exists)
sem grep "TODO"
# JSON output on any of the above
sem find diff_command --json
```
Measured on this repo (`crates/`) with `time`: the first `sem find` (index not built yet) took 185ms; the second call against the same repo, once the index existed, took 7ms. Run it yourself; the exact numbers will depend on your machine and repo size. The point is the cold-vs-warm gap: no daemon needs to stay alive for the warm number to hold.
### sem graph
Prints the full entity dependency graph for the current repo, or `--json` for the underlying edge list (the same graph `sem impact` and `sem context` are built on top of):
```bash
sem graph
sem graph --json
```
### sem stats
Local, cumulative counters: how many diffs `sem` has run in this environment and how much of that was noise filtered out. Nothing here leaves your machine (see [Telemetry](#telemetry)):
```bash
sem stats
```
## Use as default Git diff
Replace `git diff` output with entity-level diffs. Agents and humans get sem output automatically without changing any commands.
```bash
sem setup
```
Now `git diff` shows entity-level changes instead of line-level. No prompts, no agent configuration needed. Everything that calls `git diff` gets sem output automatically. Also installs a pre-commit hook that shows entity-level blast radius of staged changes.
On macOS and Linux, `sem setup` also registers a Claude Code `UserPromptSubmit` hook (`sem hook prompt-submit`) for prompt-time context injection. It edits `~/.claude/settings.json` idempotently, backs it up first, and leaves any hooks you already have untouched.
To disable and go back to normal git diff (also removes the session hooks):
```bash
sem unsetup
```
## Entity-level diffs on every pull request
Add the GitHub Action and every PR gets one sticky comment showing which
functions, classes, and methods changed. It updates in place on each push and
calls out cosmetic-only PRs (formatting/comments) explicitly:
```yaml
# .github/workflows/entity-diff.yml
name: Entity diff
on: pull_request
permissions:
contents: read
pull-requests: write
jobs:
entity-diff:
runs-on: ubuntu-latest
steps:
- uses: actions/checkout@v4
- uses: Ataraxy-Labs/sem/action@v0.23.1
```
No config, no API keys, never fails your build. See [action/](action/) for details.
## Cloud acceleration (for scale and teams)
Local is always free and always fast: the on-disk index answers day-to-day queries in single-digit milliseconds even from a cold process, so there's nothing to keep warm and no login required. You do not pay to make your laptop fast.
Cloud is for what a laptop can't do. On a very large monorepo the first local graph build can take a few seconds; a shared team graph shouldn't be rebuilt per developer; and CI wants the graph without checking anything out. `sem login` connects those cases to sem cloud, which keeps a warm, pre-built graph for your registered repos and serves the heavy queries from it instead of rebuilding locally.
```bash
sem login # GitHub device flow, one time
sem impact myFunc --file src/foo.rs # served from the cloud's warm graph
```
It is fully optional and transparent:
- Not logged in, or the cloud is unreachable? sem computes locally and prints the exact same output. No failures, no difference in results.
- `SEM_LOCAL=1` forces local computation even when logged in.
- Small repos see no change, local is already fast. The win is for large codebases where rebuilding the graph each time is the bottleneck.
Related commands, all cloud-account scoped:
```bash
sem logout # log out
sem whoami # show current cloud identity
sem cloud status # cloud + telemetry state for this repo (offline; sends nothing)
sem cloud enable # turn on cloud queries for a public repo (shows what's sent first)
sem cloud share # same, with extra confirmation, for a private repo
sem cloud forget # delete this repo's cloud index and unregister it
sem xref --json # cross-repo dependencies across your indexed repos
sem repos # where your code is stored: cloud-indexed repos + local caches
```
`sem cloud --help` lists every subcommand (`list`, `preview`, `log`, `never` included); each one is read-only or requires explicit confirmation before it sends anything.
If your team runs code review through sem cloud, `sem review listen ` execs a coding agent pre-configured to join that review as a live listener that answers reviewer questions anchored to specific lines of the diff.
## What it parses
32 programming languages with full entity extraction via tree-sitter:
| Language | Extensions | Entities |
|----------|-----------|----------|
| TypeScript | `.ts` `.tsx` `.mts` `.cts` | functions, classes, interfaces, types, enums, exports |
| JavaScript | `.js` `.jsx` `.mjs` `.cjs` `.es6` | functions, classes, variables, exports |
| Python | `.py` `.pyi` | functions, classes, decorated definitions |
| Go | `.go` | functions, methods, types, vars, consts |
| Rust | `.rs` | functions, structs, enums, impls, traits, mods, consts |
| Java | `.java` | classes, methods, interfaces, enums, fields, constructors |
| C | `.c` `.h` | functions, structs, enums, unions, typedefs |
| C++ | `.cpp` `.cc` `.cxx` `.hpp` `.hh` `.hxx` | functions, classes, structs, enums, namespaces, templates |
| C# | `.cs` | classes, methods, interfaces, enums, structs, properties |
| Ruby | `.rb` | methods, classes, modules |
| PHP | `.php` `.inc` `.phtml` `.module` | functions, classes, methods, interfaces, traits, enums |
| Swift | `.swift` | functions, classes, protocols, structs, enums, properties |
| Elixir | `.ex` `.exs` | modules, functions, macros, guards, protocols |
| Bash | `.sh` | functions |
| Fish | `.fish` | functions |
| Lua | `.lua` | functions (global, local, table, and method forms) |
| HCL/Terraform | `.hcl` `.tf` `.tfvars` | blocks, attributes (qualified names for nested blocks) |
| Kotlin | `.kt` `.kts` | classes, interfaces, objects, functions, properties, companion objects |
| Fortran | `.f90` `.f95` `.f03` `.f08` `.f` `.for` | functions, subroutines, modules, programs |
| Vue | `.vue` | template/script/style blocks + inner TS/JS entities |
| XML | `.xml` `.plist` `.svg` `.csproj` + 9 more MSBuild/resource extensions | elements (nested, tag-name identity) |
| ERB | `.erb` `.html.erb` | blocks, expressions, code tags |
| Svelte | `.svelte` `.svelte.js` `.svelte.ts` (+ `.test`/`.spec` variants) | component blocks + rune JS/TS modules |
| Perl | `.pl` `.pm` `.t` | subroutines, packages |
| Dart | `.dart` | classes, mixins, extensions, enums, type aliases, functions |
| OCaml | `.ml` `.mli` | values, modules, types, classes, externals |
| Scala | `.scala` `.sc` `.sbt` `.kojo` `.mill` | classes, objects, traits, enums, functions, vals, extensions |
| Nix | `.nix` | bindings, inherit declarations |
| Haskell | `.hs` | functions, signatures, data types, newtypes, classes, instances, type synonyms |
| Elm | `.elm` | value declarations, type aliases, type declarations, port annotations, infix declarations |
| Clojure | `.clj` `.cljs` `.cljc` | vars, functions, macros, multimethods, protocols, records, types |
| D | `.d` `.di` | modules, functions, classes, structs, interfaces, unions, enums, templates, aliases, unittests |
| Zig | `.zig` | functions, tests, variables |
| SQL | `.sql` `.psql` `.pgsql` `.ddl` | tables, views, functions, indexes, types, schemas, triggers, sequences |
Plus structured data formats:
| Format | Extensions | Entities |
|--------|-----------|----------|
| JSON | `.json` | properties, objects (RFC 6901 paths) |
| YAML | `.yml` `.yaml` | sections, properties (dot paths) |
| TOML | `.toml` | sections, properties |
| EDN | `.edn` | top-level map entries (keyword keys) |
| CSV | `.csv` `.tsv` | rows (first column as identity) |
| Markdown | `.md` `.mdx` | heading-based sections |
| LaTeX | `.tex` `.latex` `.cls` `.sty` | sections (part/chapter/section/…), plus theorem/lemma/proof/figure/table/algorithm and other tracked environments |
Everything else falls back to chunk-based diffing.
### Custom extensions and extensionless files
For files with non-standard extensions, create a `.semrc` in your project root:
```
.xyz = cpp
.j = json
.mypy = python
```
sem also reads `.gitattributes` patterns (`diff=` and `linguist-language=`) if you already have those set up. `.semrc` takes priority when both define the same extension.
For files with no extension at all, sem detects the language automatically from content (shebang lines, vim modelines, and structural heuristics like `package`/`import`/`use` statements). This covers 30+ languages with no config needed.
## How matching works
Three-phase entity matching:
1. **Exact ID match**: same entity in before/after = modified or unchanged
2. **Structural hash match**: same AST structure, different name = renamed or moved (ignores whitespace/comments)
3. **Fuzzy similarity**: >80% token overlap = probable rename
This means sem detects renames and moves, not just additions and deletions. Structural hashing also distinguishes cosmetic changes (whitespace, formatting) from real logic changes.
## Use with AI agents (MCP)
`sem mcp` starts a [Model Context Protocol](https://modelcontextprotocol.io) server over stdin/stdout. It's not a command you run and read yourself: it's a server your coding agent launches in the background so it can ask sem questions while it works. That's the reason `mcp` lives alongside the normal commands. The agent gets 8 entity-level tools mirroring the CLI: `sem_entities`, `sem_diff`, `sem_blame`, `sem_impact`, `sem_log`, `sem_context`, `sem_find`, `sem_grep`. (If you're also using sem cloud for code review, four more tools let an agent attach to a review and answer reviewer questions in a loop: `join_review`, `wait_for_branch`, `reply_to_branch`, `list_open_branches`.)
Why an agent wants these: instead of reading whole files and burning tokens, it can ask "what breaks if I change `submitOrder`" (`sem_impact`) or "give me just the context to refactor this function" (`sem_context`, which returns the function's source plus its callers and callees) and get a precise, deterministic answer from the dependency graph instead of a grep result that might miss a caller.
Add it once, then talk to your agent normally. It calls the tools on its own.
**Claude Code:**
```bash
claude mcp add sem -- sem mcp
```
Or one command that also installs the skill, so the agent knows *when* to reach for sem:
```bash
npx @ataraxy-labs/sem-skill
```
**Cursor, Claude Desktop, or any client with an `mcpServers` config:**
```json
{
"mcpServers": {
"sem": {
"command": "sem",
"args": ["mcp"]
}
}
}
```
If `sem` isn't on the agent's PATH, use the absolute path to the binary. No separate install is needed: `sem mcp` ships in the same binary as every other command.
## JSON output
```bash
sem diff --format json
```
Real output, from a one-line logic change to a Python function:
```json
{
"summary": {
"fileCount": 1,
"added": 0,
"modified": 1,
"deleted": 0,
"moved": 0,
"renamed": 0,
"reordered": 0,
"binary": 0,
"orphan": 0,
"total": 1
},
"changes": [
{
"entityId": "auth.py::function::authenticate_user",
"changeType": "modified",
"entityType": "function",
"entityName": "authenticate_user",
"startLine": 1,
"endLine": 6,
"oldStartLine": 1,
"oldEndLine": 4,
"oldEntityName": null,
"filePath": "auth.py",
"oldFilePath": null,
"oldParentId": null,
"beforeContent": "def authenticate_user(username, password):\n if not username or not password:\n return False\n return check_credentials(username, password)",
"afterContent": "def authenticate_user(username, password):\n if not username or not password:\n return False\n if not check_credentials(username, password):\n return False\n return True",
"commitSha": null,
"author": null,
"structuralChange": true
}
],
"binaryChanges": []
}
```
The named change-type buckets (`added`, `modified`, `deleted`, `moved`, `renamed`, `reordered`) always sum to `total`. `orphan` is a cross-cutting metadata count for module-level changes, and those changes are already included in the named change-type buckets. `beforeContent`/`afterContent` carry the entity's full source on either side of the change; `structuralChange` is `false` when the diff is cosmetic only (whitespace, comments).
## As a library
sem-core can be used as a Rust library dependency, from [crates.io](https://crates.io/crates/sem-core):
```toml
[dependencies]
sem-core = "0.23"
```
Used by [weave](https://github.com/Ataraxy-Labs/weave) (semantic merge driver) and [inspect](https://github.com/Ataraxy-Labs/inspect) (entity-level code review).
## Architecture
- **tree-sitter** for code parsing (native Rust, not WASM)
- **git2** for Git operations
- **rayon** for parallel file processing
- **xxhash** for structural hashing
- A per-repo cache directory (SQLite entity cache + an mmap-able query index) backs `find`/`callers`/`refs`/`grep` with cold-process lookups and no background daemon
- Plugin system for adding new languages and formats (see [CONTRIBUTING.md](CONTRIBUTING.md))
## Telemetry
Local by default: sem counts command names (e.g. `diff`, `impact`) on your own machine only, and in that mode nothing is ever uploaded. No code, file paths, repo names, or user identity is recorded, and no network call is made.
```bash
sem telemetry preview # see current mode and exactly what would be sent
sem telemetry on # opt in: also upload counts to help improve sem
sem telemetry off # record nothing at all
```
`SEM_NO_TELEMETRY=1` or `DO_NOT_TRACK=1` force the record-nothing behavior regardless of mode. Development builds (anything run out of a `cargo build` `target/` directory) never record, so working on sem itself doesn't pollute the numbers.
## Contributing
Want to add a new language? See [CONTRIBUTING.md](CONTRIBUTING.md) for a step-by-step guide.
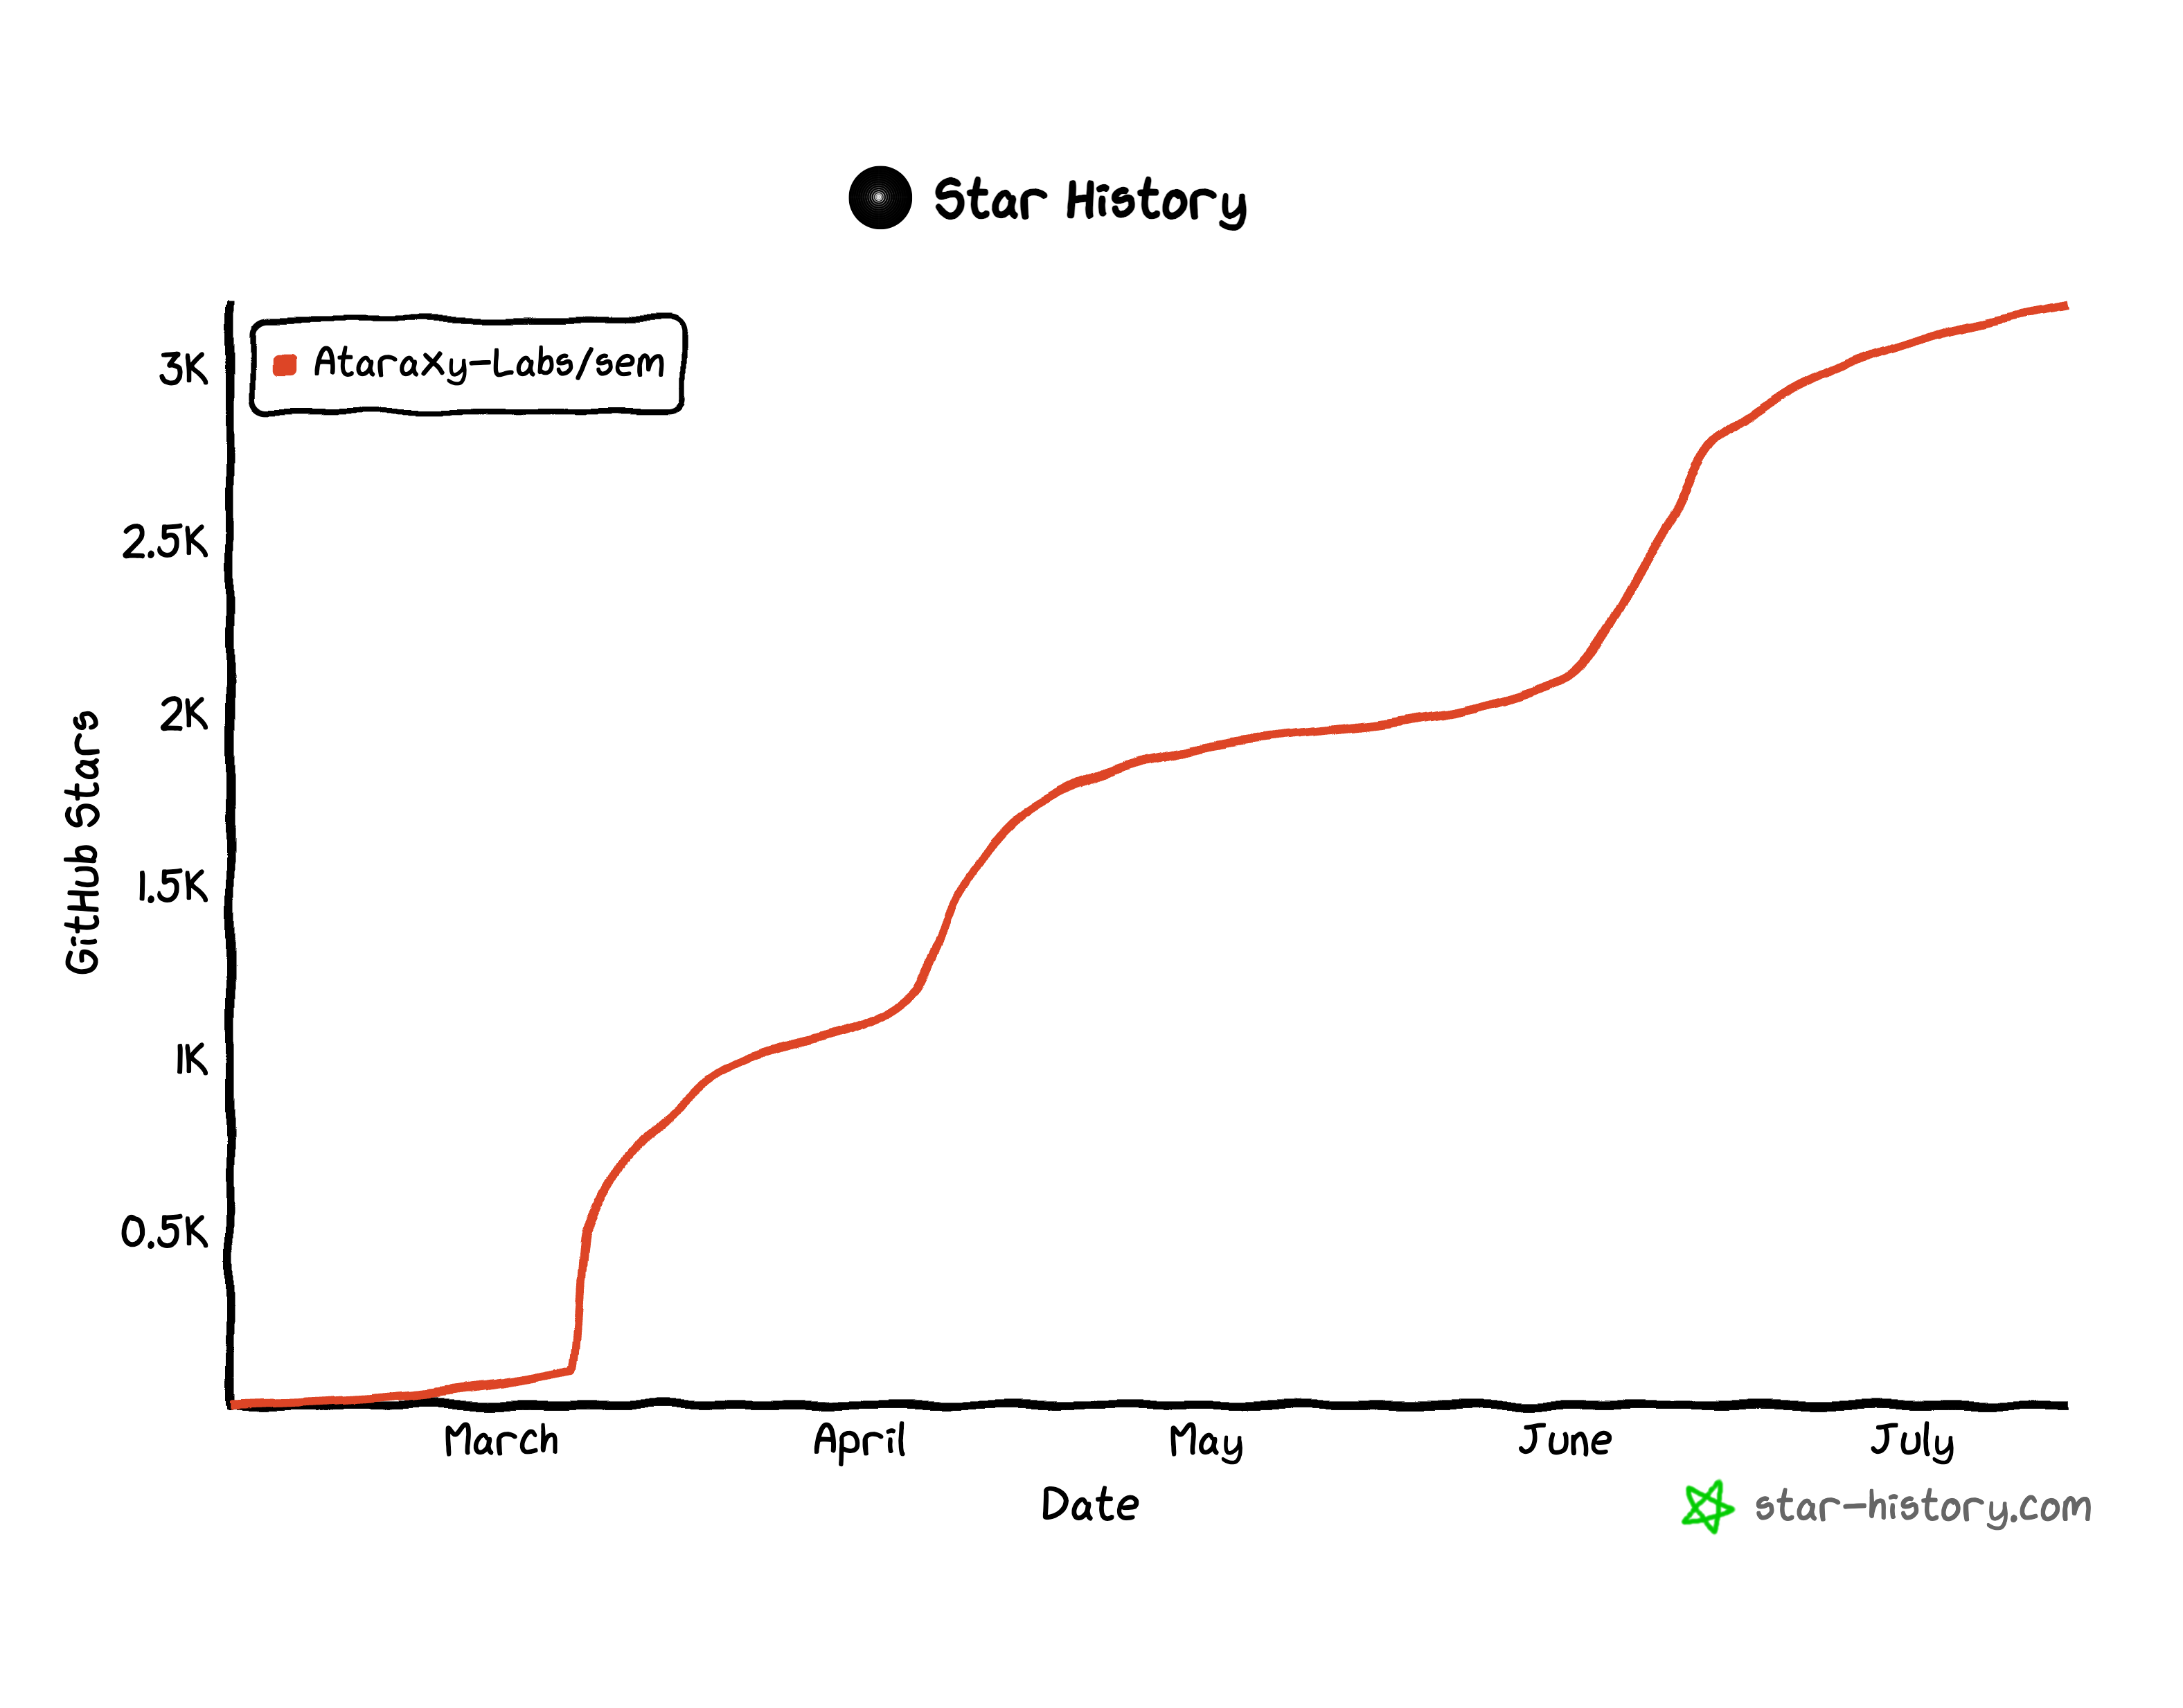
## Star History
[](https://star-history.com/#Ataraxy-Labs/sem&Date)
## License
MIT OR Apache-2.0