
One serving daemon for local LLM inference — across runtimes and machines.
| Documentation | Quickstart | Coding agents | Benchmarks | Discord |
--- superfluid puts one scheduler, one durable session log and one set of APIs in front of llama.cpp, MLX and baseRT. Several agents share one machine without getting in each other's way, a session outlives a crashed worker or a restarted server, and OpenAI, Anthropic and Ollama clients work unchanged. ```sh curl -fsSL https://superfluid.sh/install.sh | sh superfluid serve unsloth/Qwen3.8-27B-GGUF:UD-Q4_K_M ```
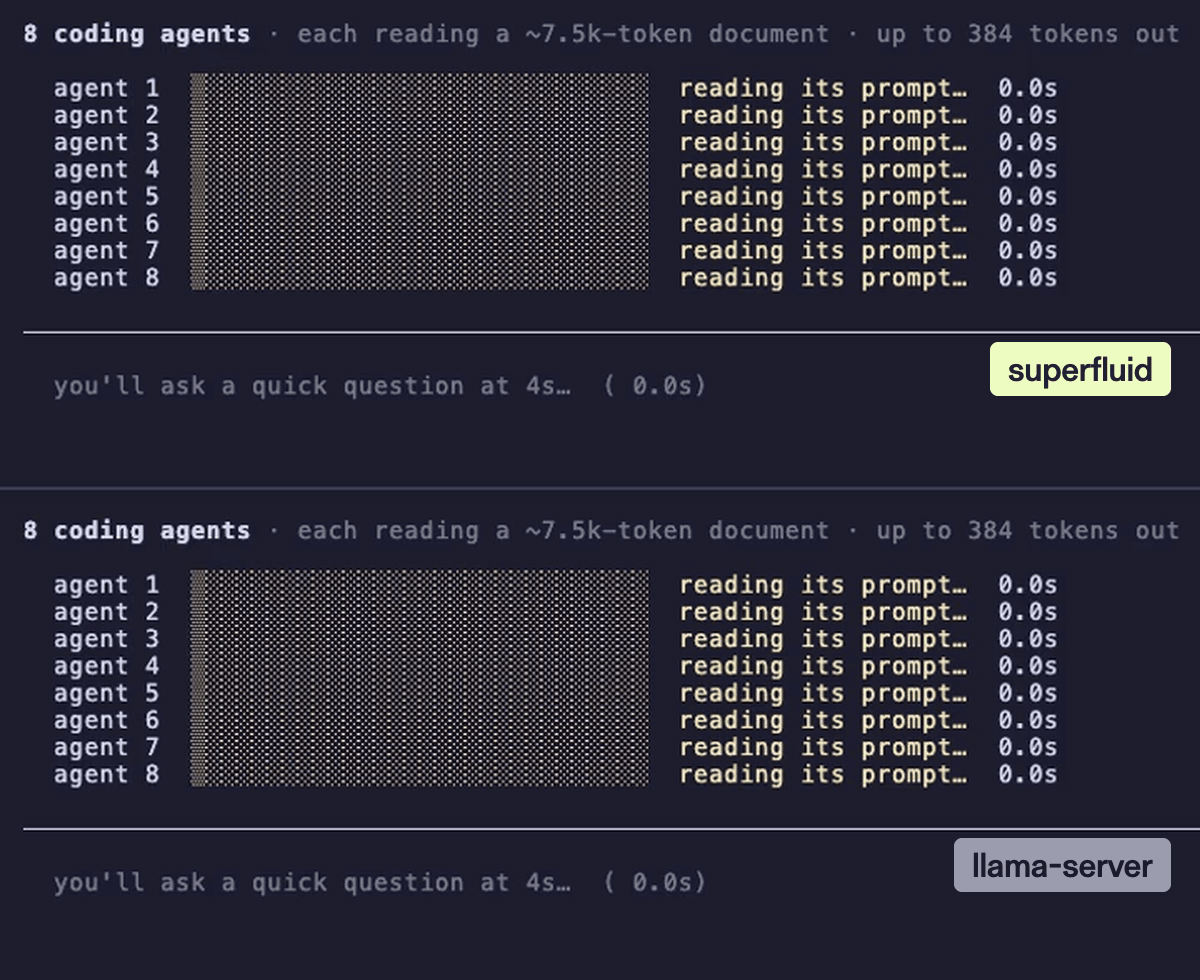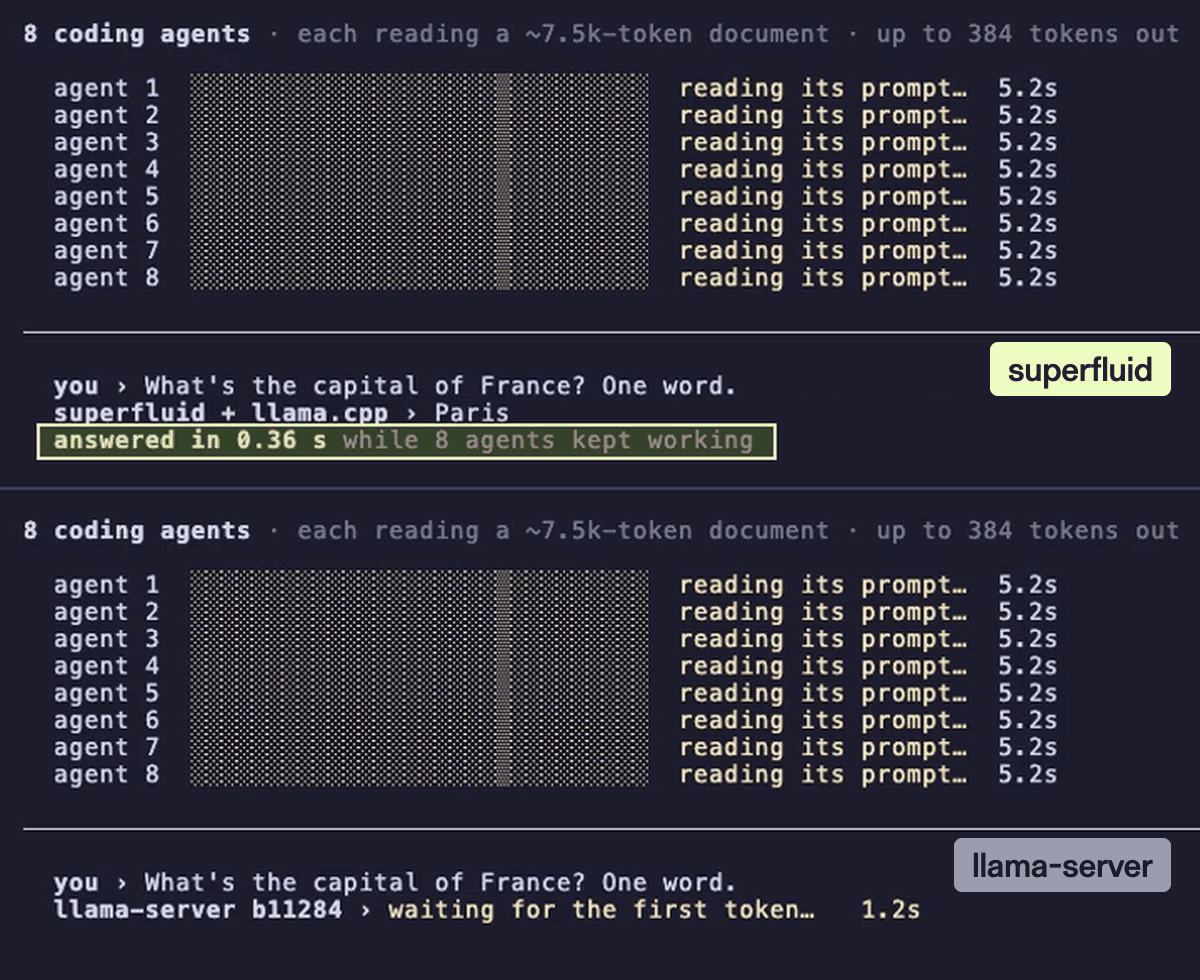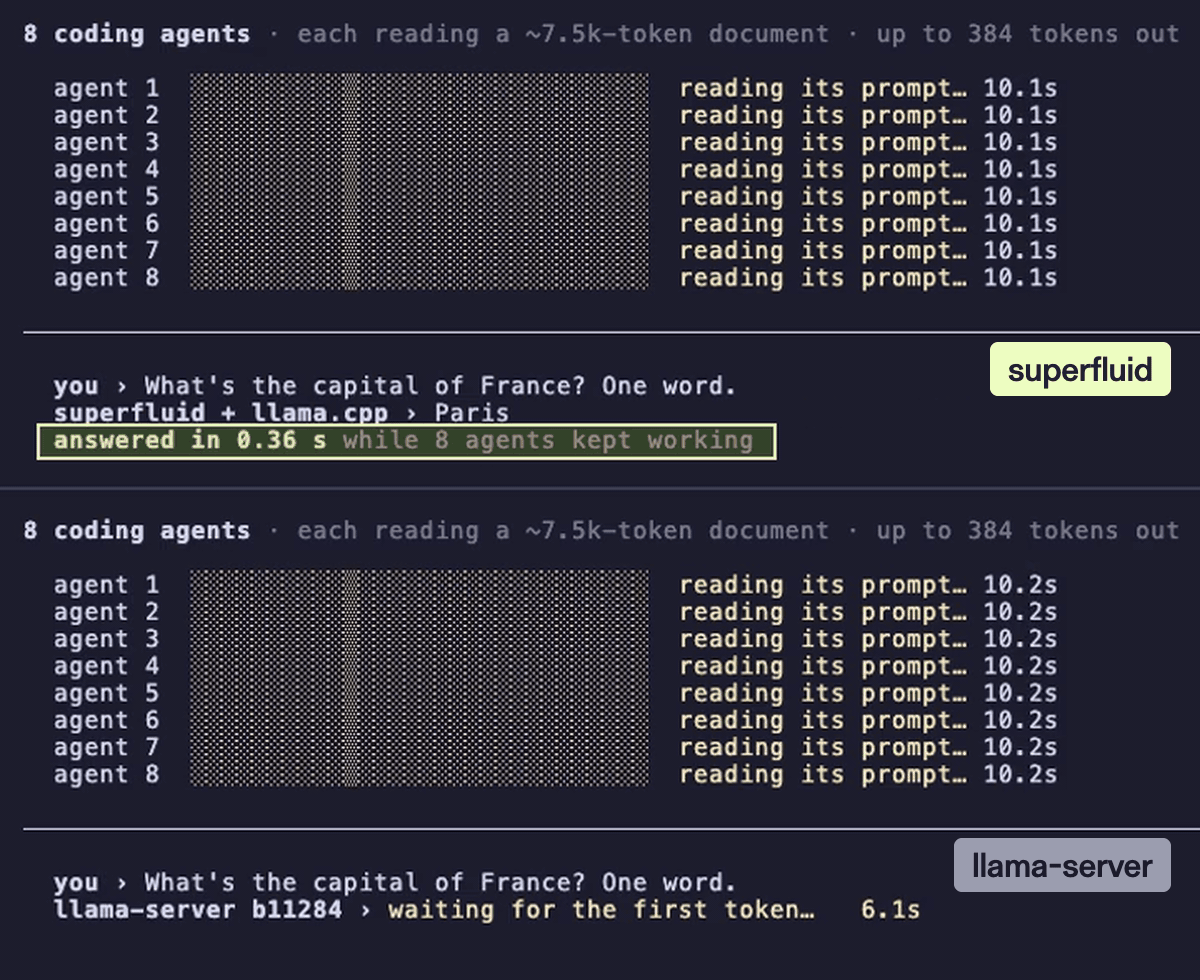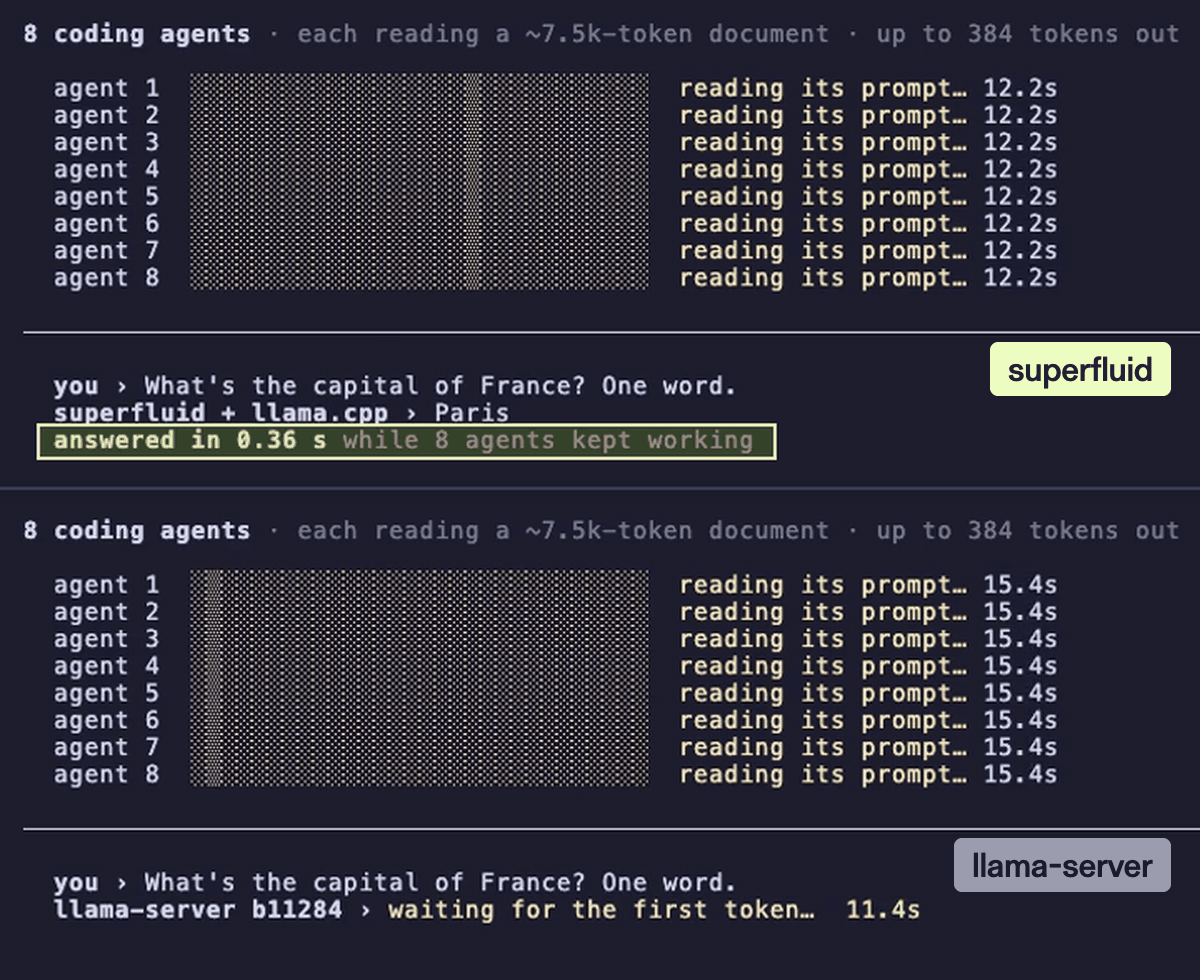
Eight agents reading 7.5k-token documents, a chat question two seconds in. Same Mac, same model.
## Why - **A chat is answered while agents work.** An interactive request preempts batch work at the next scheduler tick instead of waiting behind it. - **Nothing is lost when something dies.** Every committed token is in a write-ahead log; a killed worker or a restarted server picks its sessions up where they were. - **A shared prompt is prefilled once.** Thirty-two requests with one 5k-token prefix cost one prefill, not thirty-two. Measured on an Apple M5 Pro with Qwen3-4B, against each runtime's own server: | | superfluid | llama-server | Ollama | mlx_lm.server | |---|---|---|---|---| | first token of a chat behind eight agents | **0.79 s** | 67 s | 64 s | 120 s | | prefills of one 5k-token prompt shared by 32 requests | **about 1** | about 8 | about 8 | about 8 | | serving scenarios passed, of eight | **8** | 3 | 5 | 1 | The serving layer costs nothing over the runtime: at one and eight concurrent requests, llama.cpp through superfluid matches llama-server's tokens per second. Method, every scenario and the numbers: [Benchmarks](docs/performance/benchmarks.md). ## Use it Call the server from anything that speaks the OpenAI, Anthropic or Ollama API: ```sh curl http://127.0.0.1:8453/v1/chat/completions -H 'content-type: application/json' \ -d '{"model":"unsloth/Qwen3.8-27B-GGUF","messages":[{"role":"user","content":"hello"}]}' ``` Put a coding agent on it; `launch` starts the server when none is running: ```sh superfluid launch claude --model unsloth/Qwen3.8-27B-GGUF:UD-Q4_K_M ``` Add another machine; it finds the head on the local network and the link is encrypted: ```sh superfluid node join --model unsloth/Qwen3.8-27B-GGUF:UD-Q4_K_M --token
