Model page • Weights • Demo
This repository contains the reference inference code for [FLUX 3 Image Klein](https://bfl.ai/models/flux-3-image-klein), the 5.6B open weights image model from [Black Forest Labs](https://bfl.ai): text-to-image, editing with up to 10 reference images, and layout control with bounding boxes, through one model. It ships with a [prompt upsampler](#prompt-upsampling); do not use the model without it. 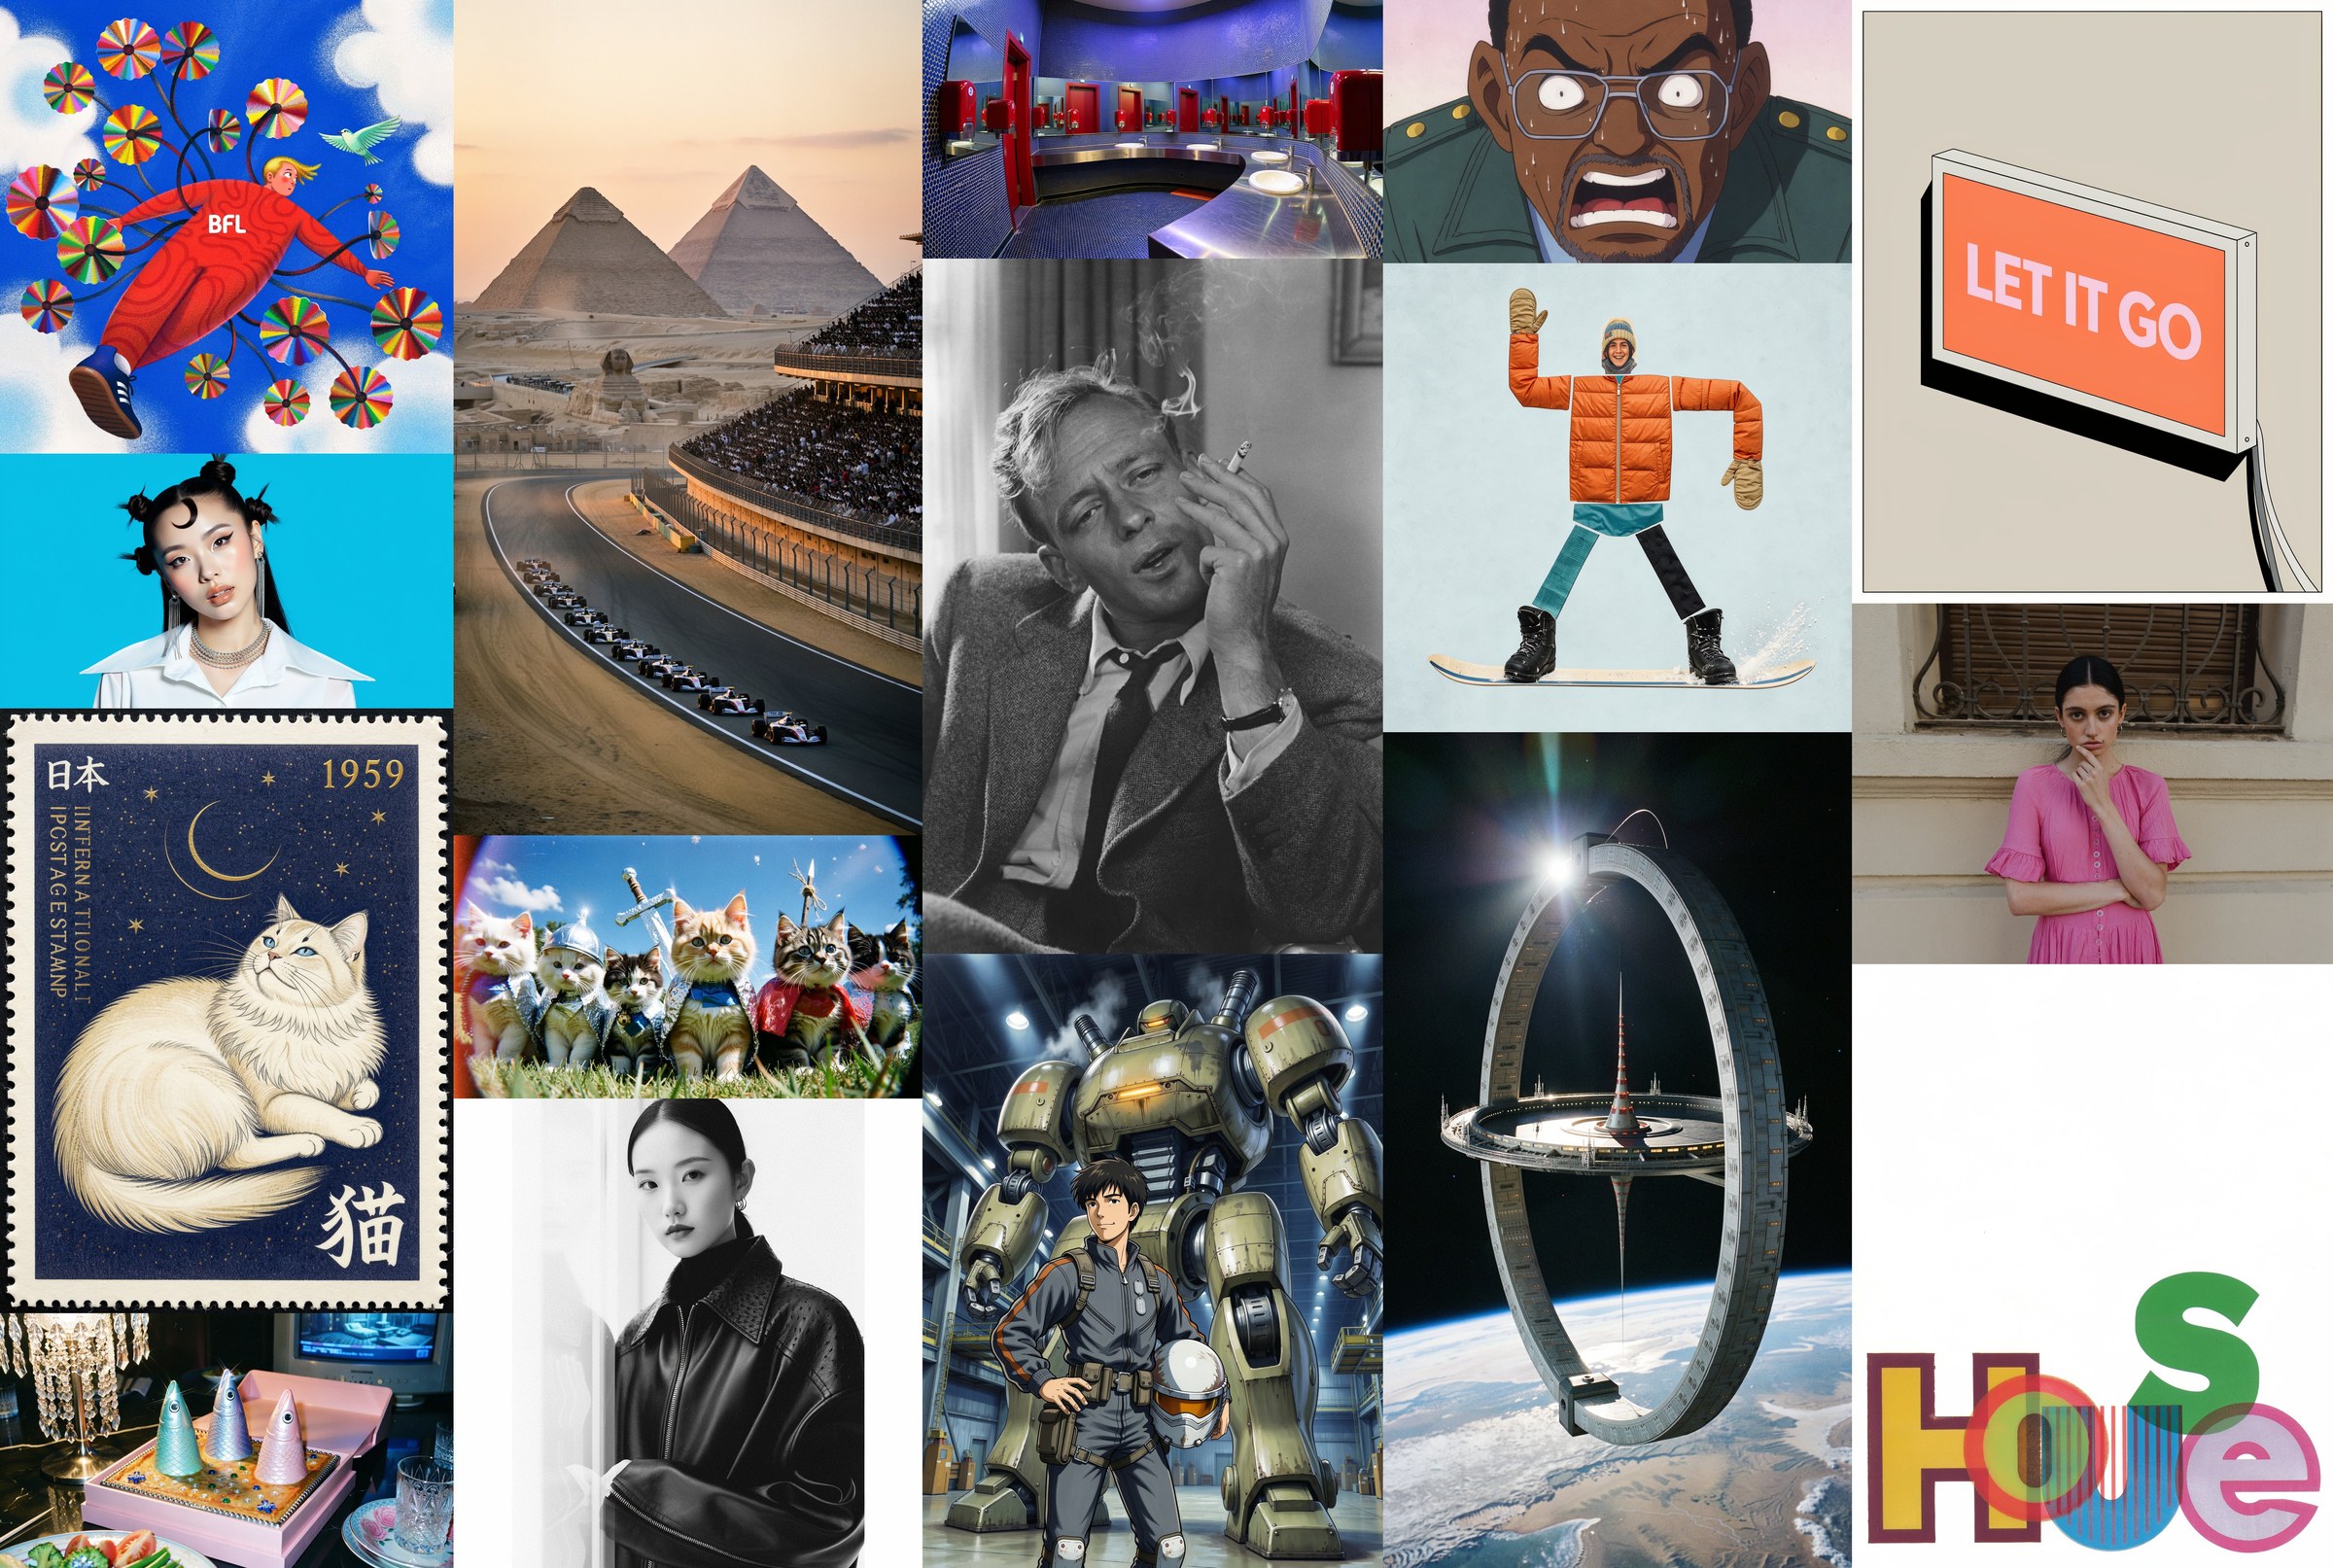 ## Performance Leads in quality and speed among open weights models: the Pareto frontier of Elo rating against latency, for text-to-image and for image editing. 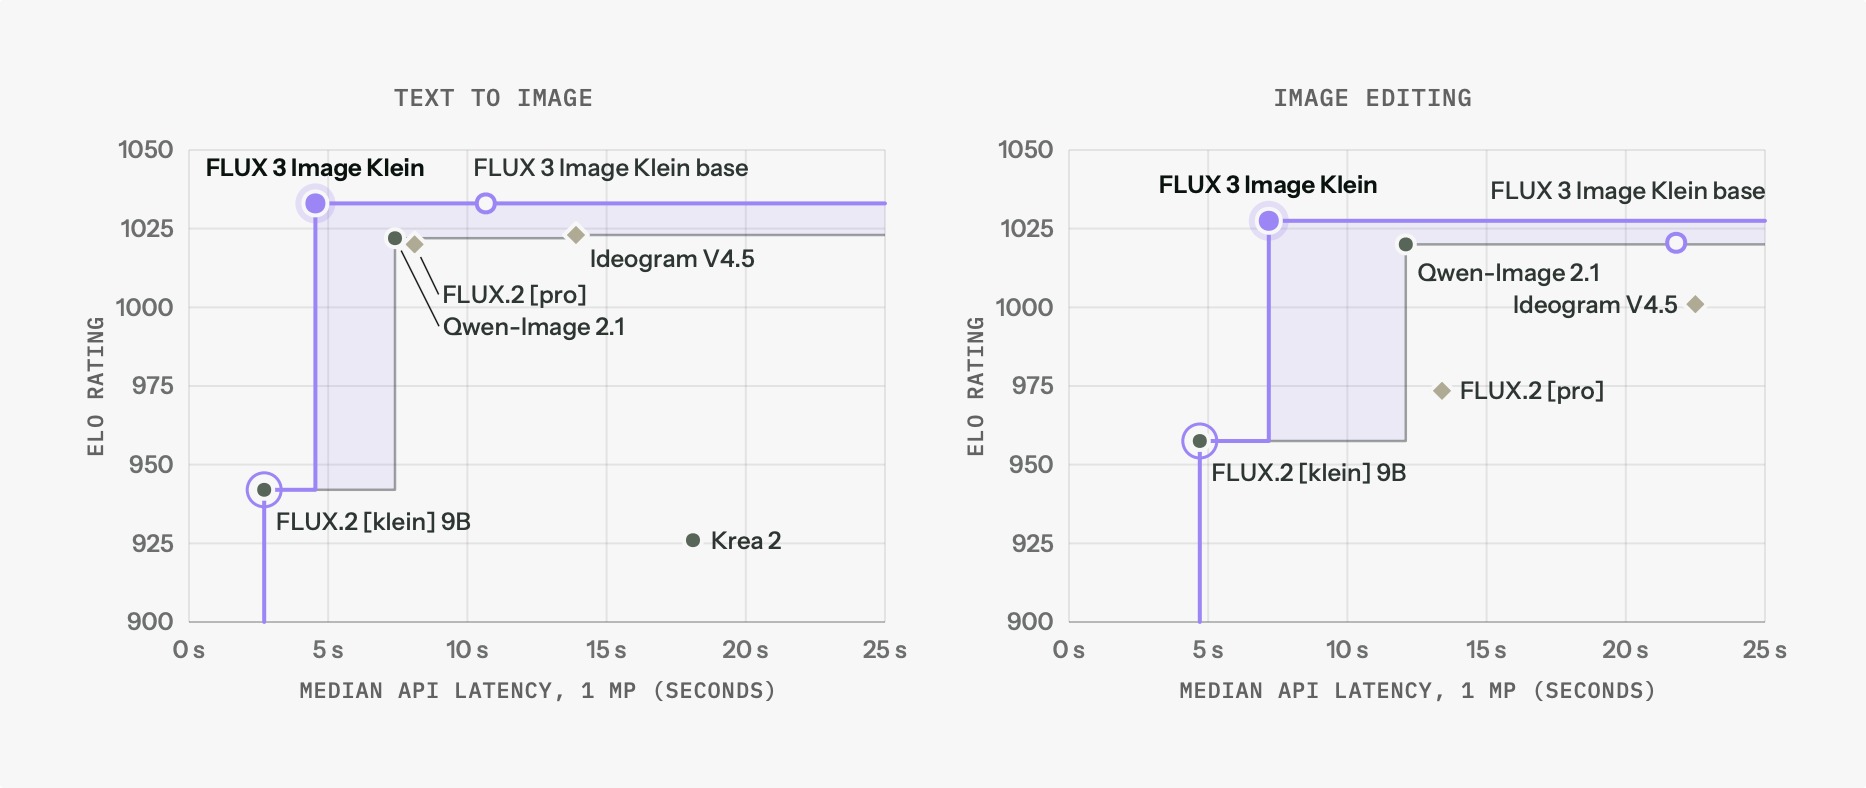 Elo from our internal evaluations; median API latency for a 1 MP image. ## Model overview | Name | Steps | Guidance | Resolution | Text-to-image | Editing (up to 10 references) | Bounding boxes | License | | :--- | :---: | :---: | :---: | :---: | :---: | :---: | :---: | | [FLUX 3 Image Klein](https://huggingface.co/black-forest-labs/flux-3-image-klein) | 16 | none | up to 4K | ✅ | ✅ | ✅ | [FLUX Kommunity License](https://huggingface.co/black-forest-labs/flux-3-image-klein/blob/main/LICENSE.md) | | [FLUX 3 Image Klein Base](https://huggingface.co/black-forest-labs/flux-3-image-klein-base) | 50 | CFG 4 | up to 4K | ✅ | ✅ | ✅ | [FLUX Kommunity License](https://huggingface.co/black-forest-labs/flux-3-image-klein/blob/main/LICENSE.md) | | [FLUX 3 Image Klein Prompt Upsampler](https://huggingface.co/black-forest-labs/flux-3-image-klein-pup) | | | | | | | [Apache 2.0](https://huggingface.co/datasets/choosealicense/licenses/blob/main/markdown/apache-2.0.md) | ## Which model should I use? | Need | Recommended | |------|-------------| | Generation and editing, self-hosting | FLUX 3 Image Klein (distilled): the same model in 16 steps without CFG, about 6x faster | | Fine-tuning, LoRA training, research | FLUX 3 Image Klein Base | | An 8 GB GPU (RTX 3070 class) | the int8 files in [ComfyUI](#run-it-elsewhere) | > [!IMPORTANT] > Do not use either model without the [prompt upsampler](#prompt-upsampling). The model is trained on the captions it > writes; a prompt sent as typed gives noticeably weaker results. It is on by default in the CLI, the demo and the > Python API. ### Text-to-image examples 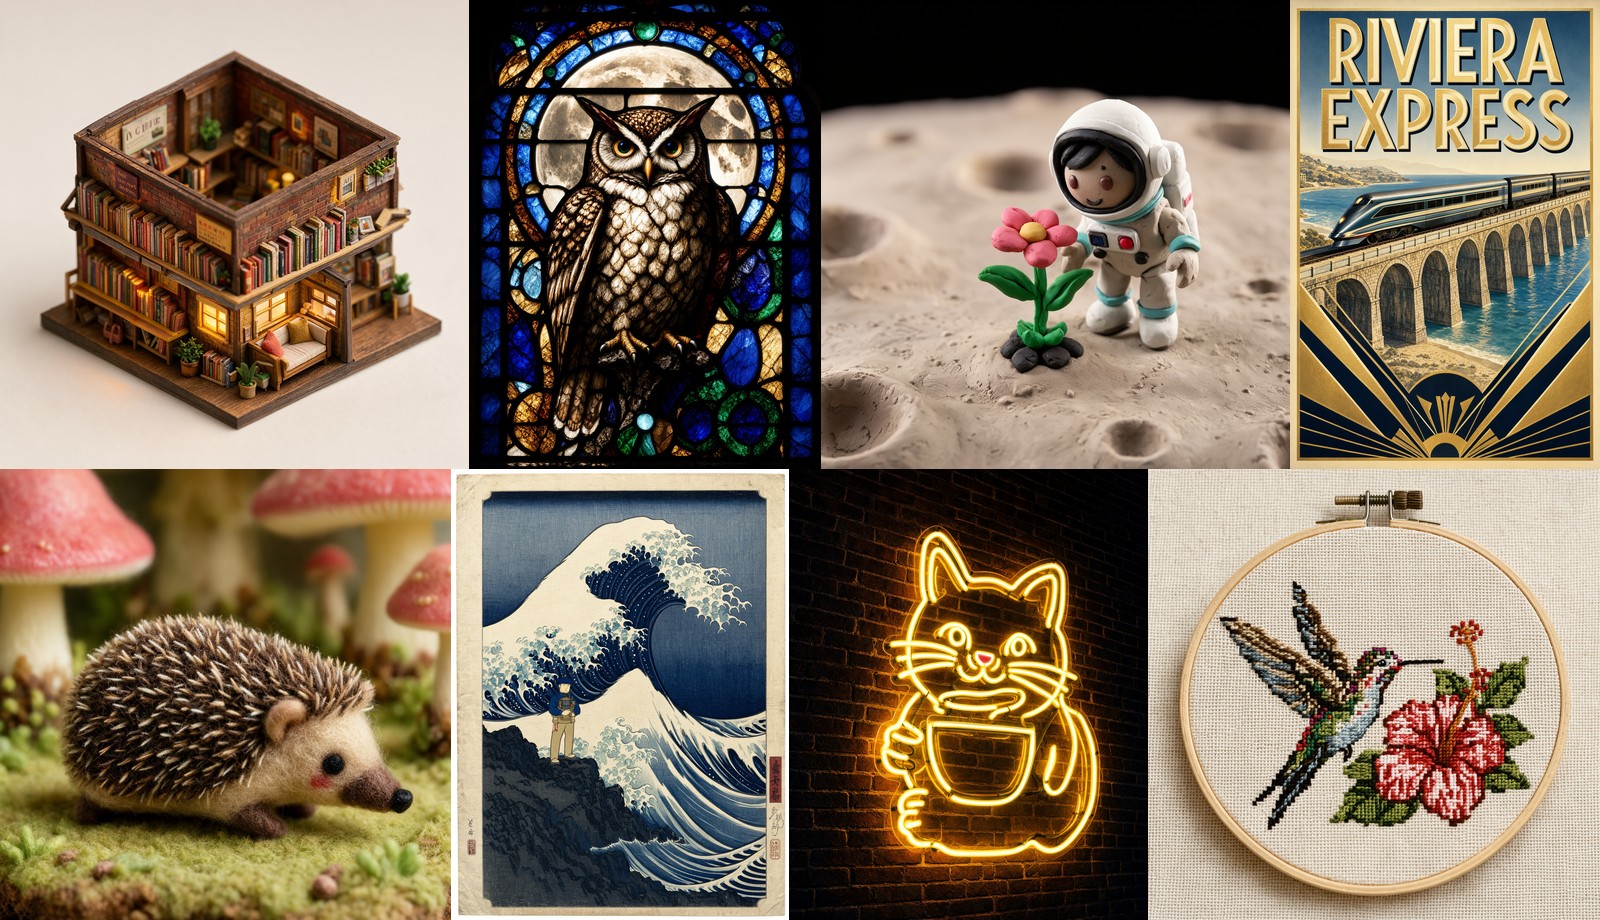 ### Editing examples 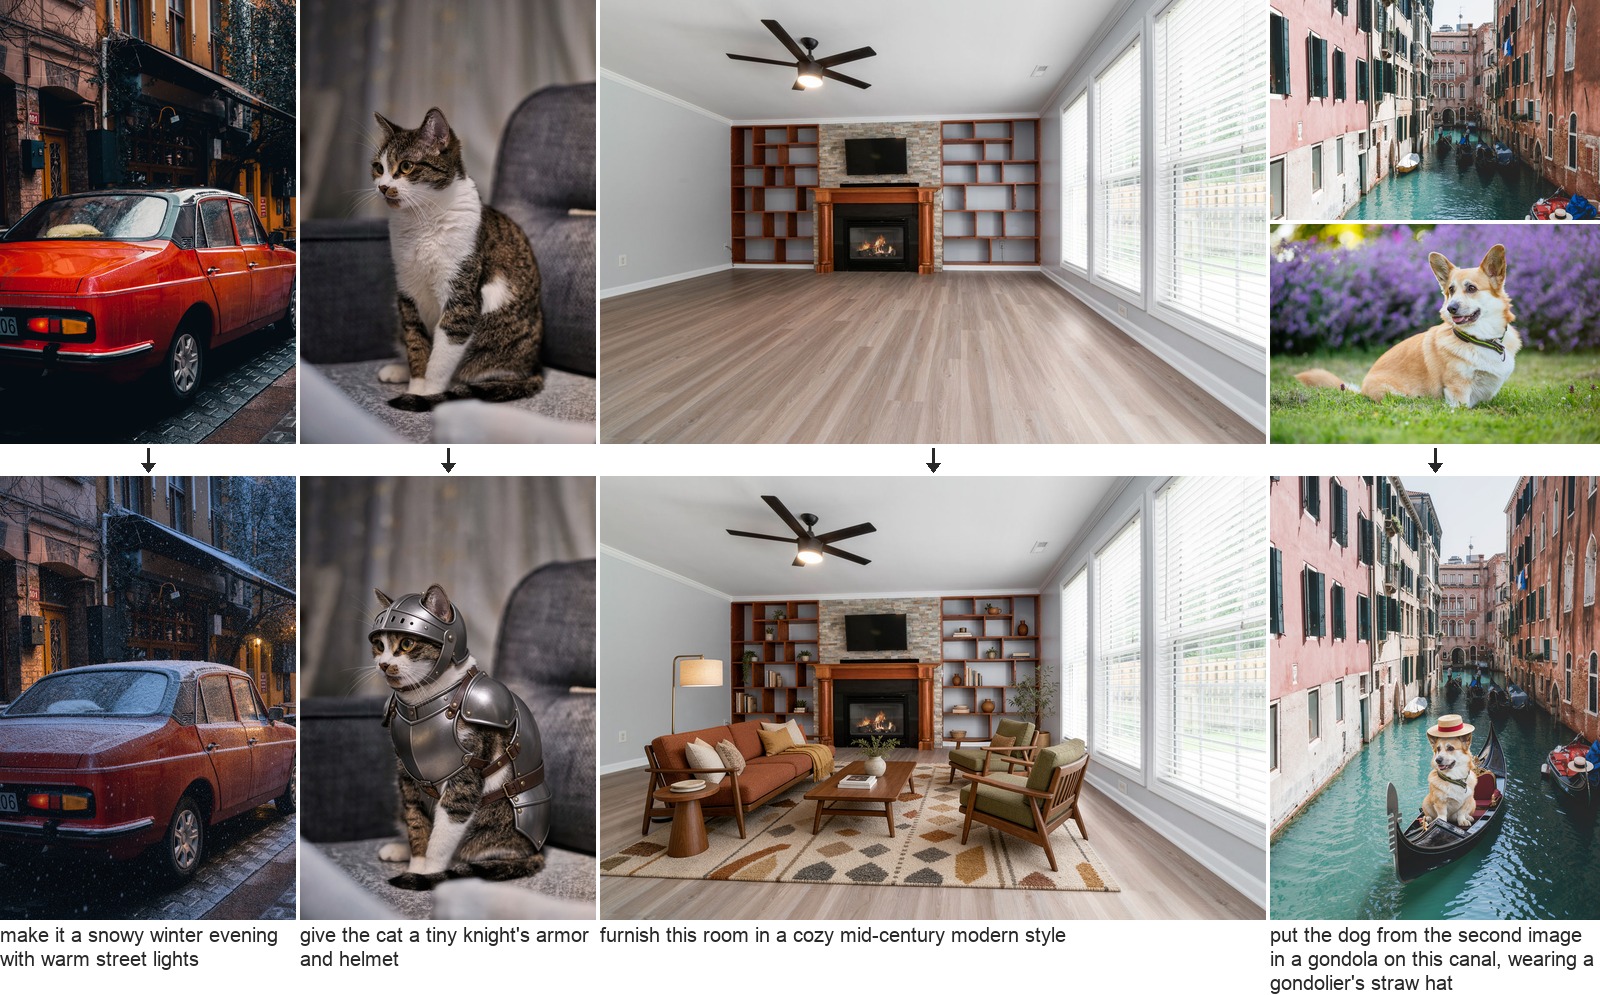 ### Layout examples 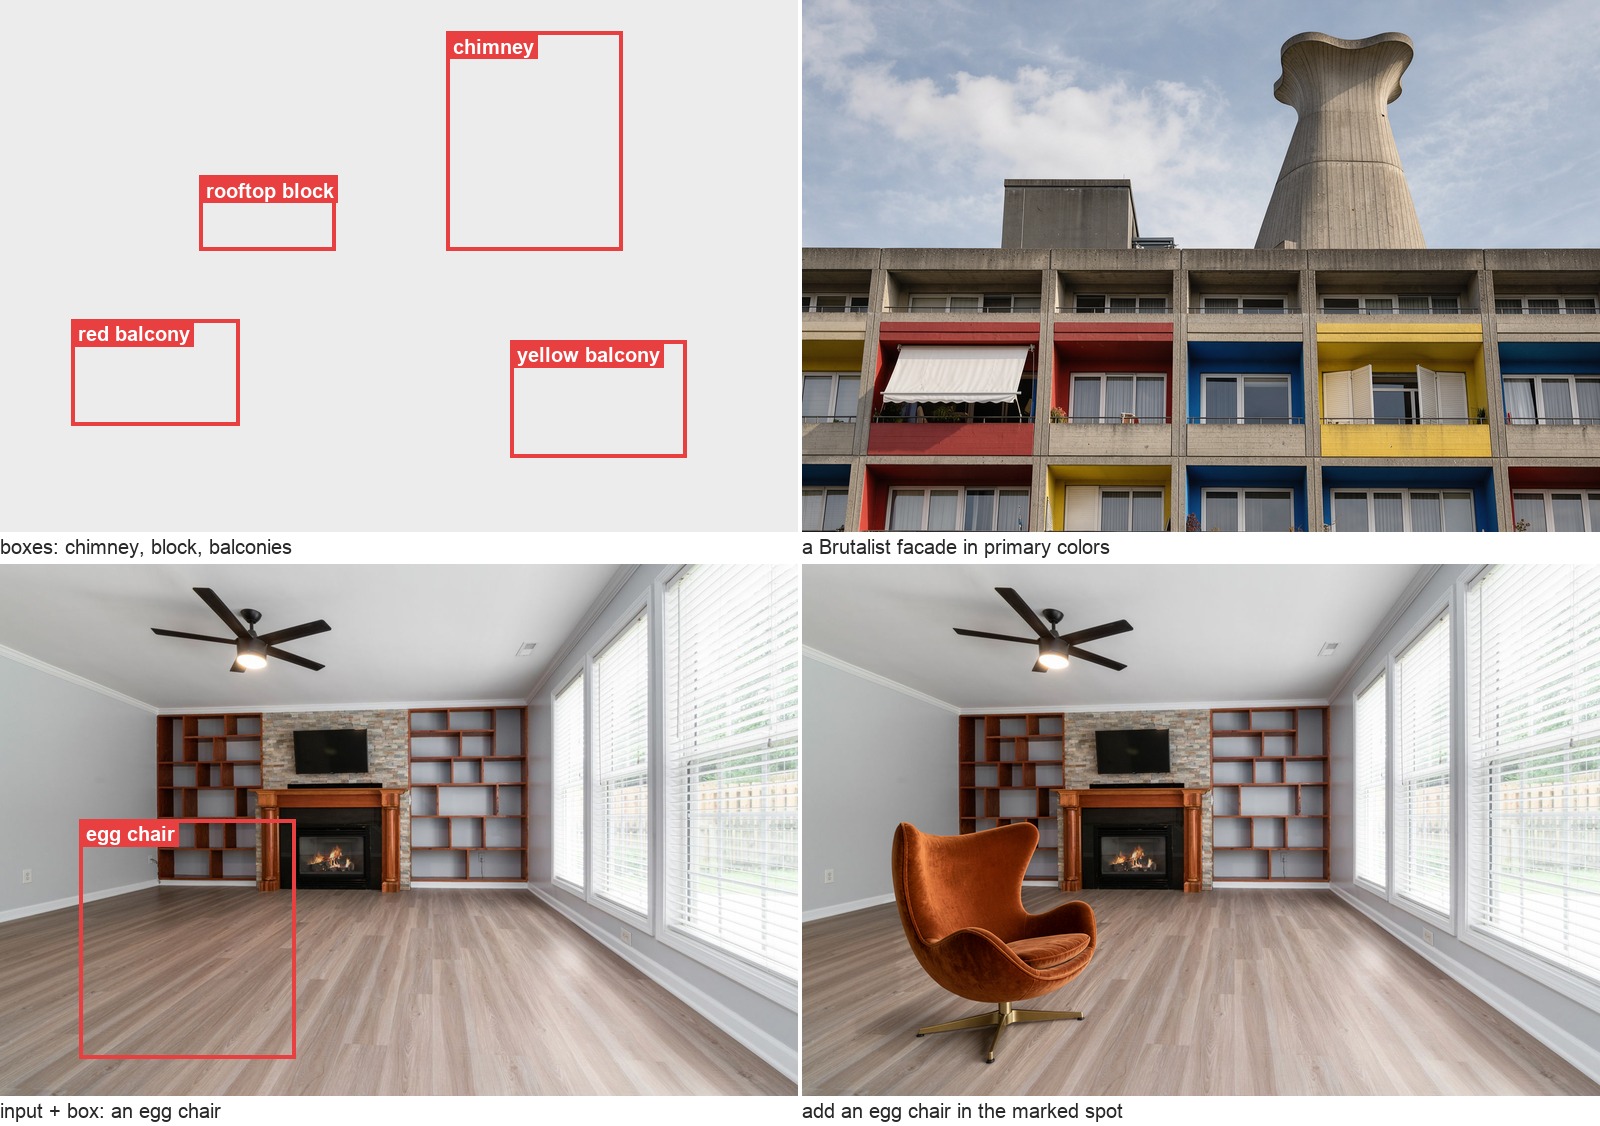 ### Typography 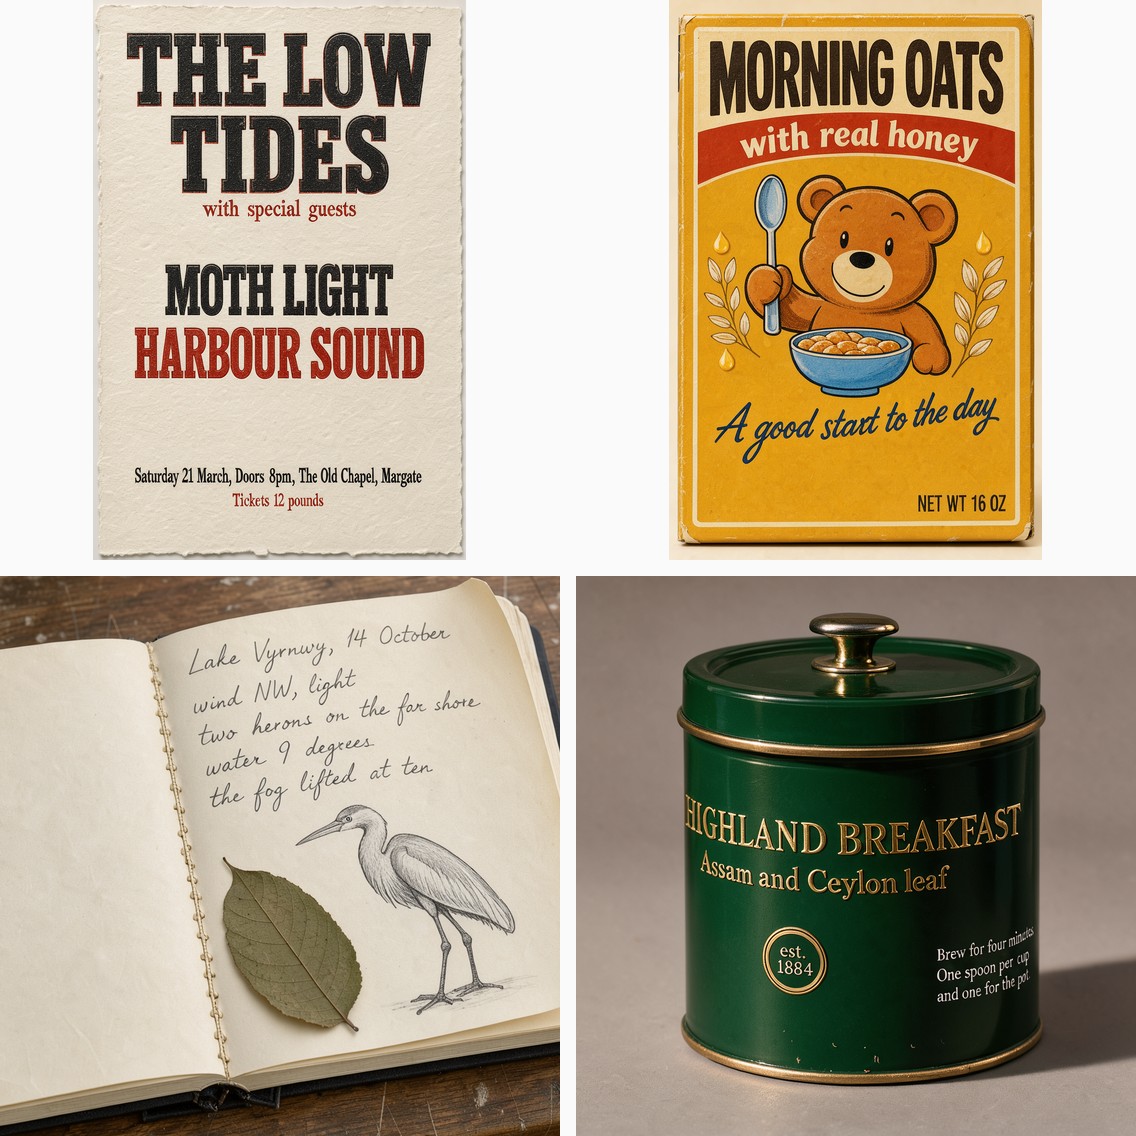 ### Base vs distilled Same prompt, same seed: distilled (16 steps) left, base (50 steps, CFG) right. On one H200 at 1 MP: about 3 s against 12 s per image. 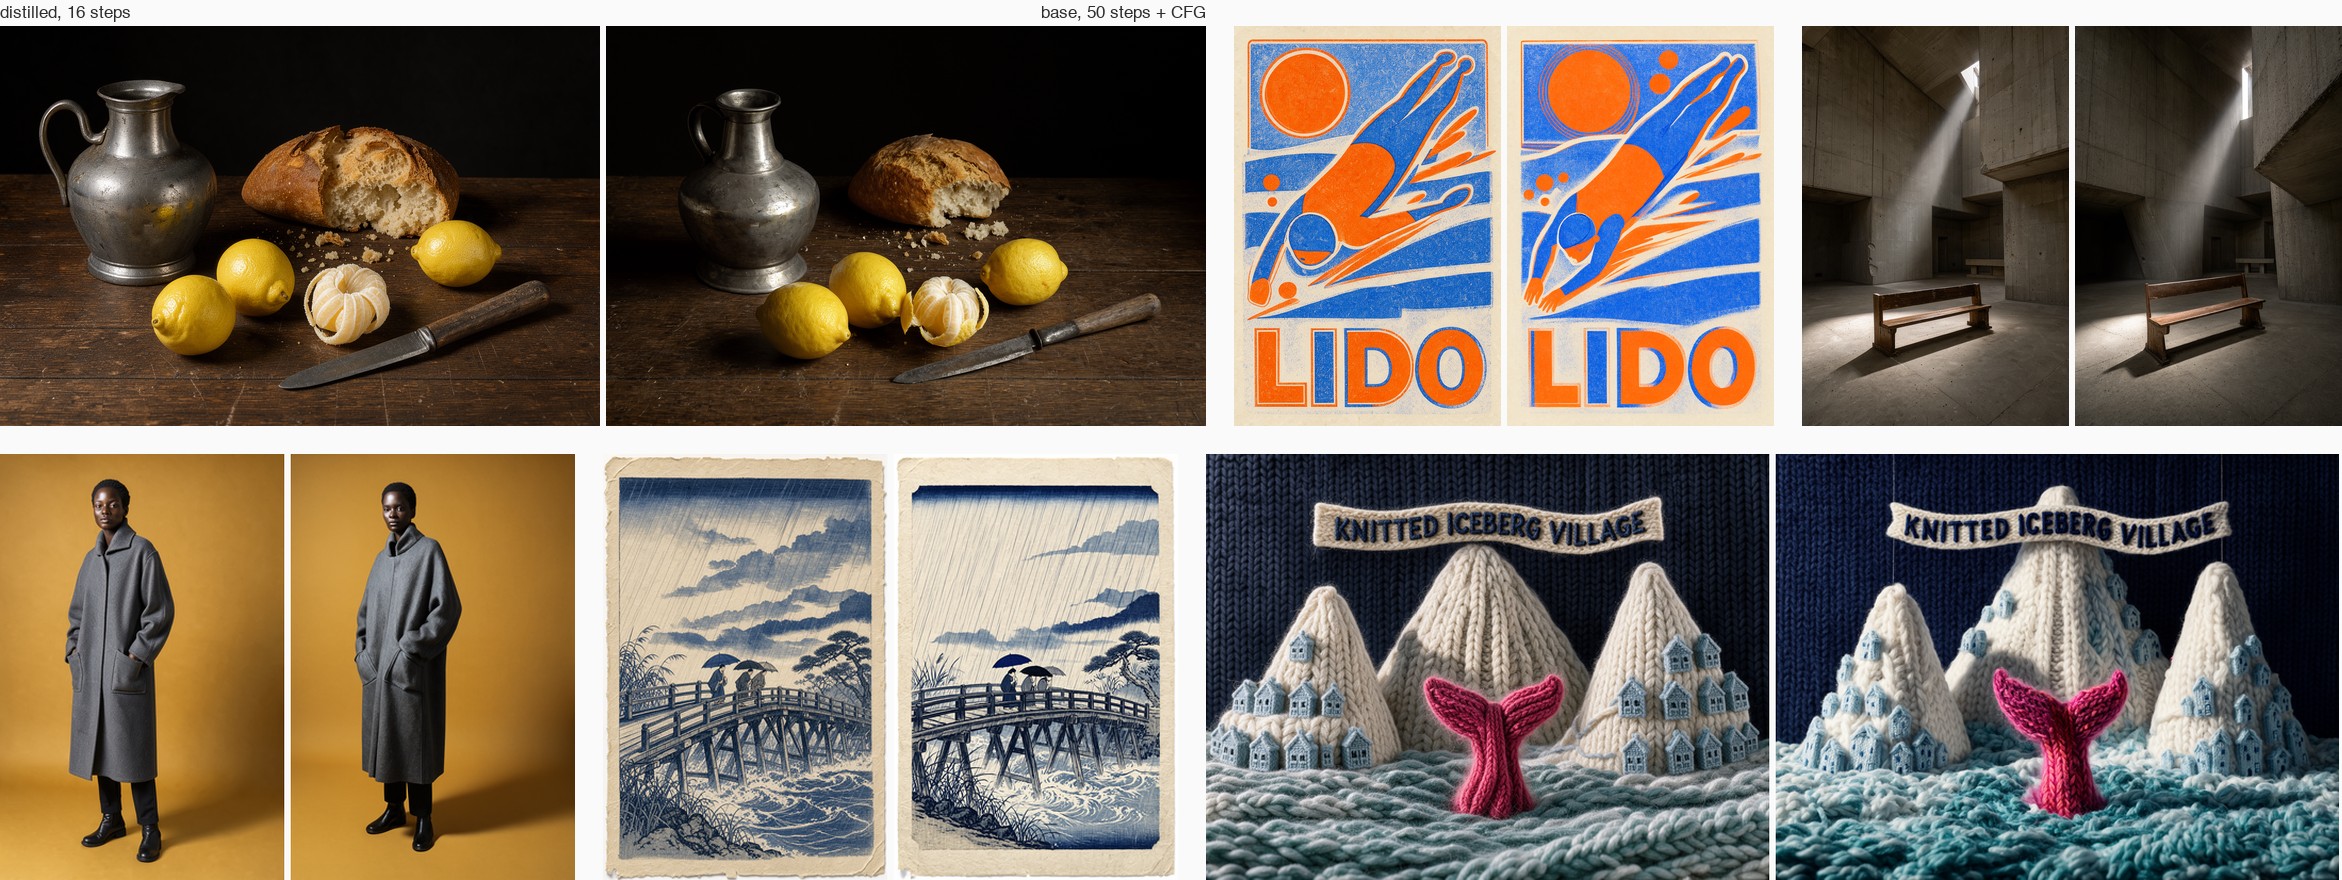 ## Local installation To run FLUX 3 Image Klein in BF16 and FP8: ```bash python3.12 -m venv .venv && . .venv/bin/activate pip install -e . --extra-index-url https://download.pytorch.org/whl/cu130 ``` To run FLUX 3 Image Klein in BF16, FP8 and NVFP4 (NVFP4 needs a Blackwell GPU): ```bash python3.12 -m venv .venv && . .venv/bin/activate pip install -e '.[nvfp4]' --extra-index-url https://download.pytorch.org/whl/cu130 --extra-index-url https://flashinfer.ai/whl/cu130 ``` The installation was tested on B200; see [Memory](#memory) for other GPUs. ### Weights The fast model with its prompt upsampler, 52 GB: ```bash hf download black-forest-labs/flux-3-image-klein --local-dir weights/flux-3-image-klein --exclude 'variants/*' hf download black-forest-labs/flux-3-image-klein-pup --local-dir weights/pup hf download Falconsai/nsfw_image_detection --local-dir weights/nsfw-classifier ``` Everything, 107 GB: ```bash hf download black-forest-labs/flux-3-image-klein-base --local-dir weights/flux-3-image-klein-base hf download black-forest-labs/flux-3-image-klein --local-dir weights/flux-3-image-klein hf download black-forest-labs/flux-3-image-klein-pup --local-dir weights/pup hf download Falconsai/nsfw_image_detection --local-dir weights/nsfw-classifier ``` `WEIGHTS_DIR` points at another root (default `./weights`). The quantized DiTs live under `variants/fp8r` and `variants/nvfp4` in each repository; the text encoder and autoencoder ship with both. `weights/pup` is the [prompt upsampler](#prompt-upsampling), which the model needs. ## Run the CLI > [!IMPORTANT] > The commands below send the prompt through the [upsampler](#prompt-upsampling) before the model. Do not pass > `--no-pup` unless the prompt already is an upsampler caption ([Smaller GPUs](#smaller-gpus)). ### Text to image ```bash python scripts/cli.py "A man walking with his dog, afternoon sun" --model distilled --out out.png --seed 7 ``` Each generated image comes with a `.json` containing the prompt, size, number of steps, guidance value and seed; [examples/README.md](examples/README.md) has the command behind every image in this README. ### Edit an image ```bash python scripts/cli.py "put a red bandana around the dog's neck" --image examples/inputs/3.png --out out.png --seed 22 ``` Up to 10 references; the first one sets the output size: ```bash python scripts/cli.py "print the dog from the second image onto the mug" \ --image examples/inputs/2.png --image examples/inputs/3.png --out out.png --seed 23 ``` ### Place elements with bounding boxes ```bash python scripts/cli.py "hot-air balloons over a green valley at sunrise" \ --boxes examples/inputs/balloons_boxes.json --out out.png --seed 1 ``` Format in [Bounding boxes](#bounding-boxes). ### Smaller GPUs `--fp8` (Ada, Hopper, Blackwell) or `--nvfp4` (Blackwell) load the quantized DiTs. An external vision-language model can also write the caption in place of the upsampler: give it the [system prompts](src/flux3/pup_prompts_external_vlm.json) and pass its answer with `--no-pup`. When the upsampler and the model do not fit on the GPU together, run the upsampler on its own first and pass its caption with `--no-pup`: ```bash python -m flux3.pup --prompt "A man walking with his dog, afternoon sun" --out prompt.txt python scripts/cli.py "$(cat prompt.txt)" --model distilled --fp8 --no-pup --out out.png ``` Numbers in [Memory](#memory). ### From Python ```python from PIL import Image from flux3.generate import Models, generate from flux3.pipeline import WEIGHTS, dit_path models = Models({"distilled": str(dit_path("distilled"))}, pup=str(WEIGHTS / "pup"), pup_memory=0.35) image, record = generate(models, "distilled", "a red bicycle leaning on a white wall", images=[], seed=1) image.save("bicycle.png") image, record = generate(models, "distilled", "put a red bandana around the dog's neck", images=[Image.open("examples/inputs/3.png")], seed=22) image.save("bandana.png") ``` `Models` loads once; `generate` also takes `boxes`, `width`, `height`, `steps`, `guidance`, `pup`, `safety`. ## Demo ```bash python scripts/app.py # http://127.0.0.1:7860; --share for a public link ``` Three tabs: **Layout** (draw boxes, type what goes in each), **Text to image**, **Edit**. `--offload`, `--fp8`, `--nvfp4` and `--no-pup` apply as in the CLI. ## Prompt upsampling The upsampler ([black-forest-labs/flux-3-image-klein-pup](https://huggingface.co/black-forest-labs/flux-3-image-klein-pup), a 9B vision-language model fine-tuned from Qwen3.5-9B) expands a short request into the detailed prompt the model works best with, before it reaches the text encoder. It is on by default in the CLI, the demo and `generate`. Do not use the model without it, for text-to-image, editing and layout alike: `--no-pup` sends the prompt as typed, and the results are noticeably weaker. | input prompt | what the model saw | |---|---| | `double exposure portrait: a young East Asian man facing the camera, a larger translucent profile of him facing left layered over him, muted blues, film grain, silver hoop earring` | "Digital double-exposure portrait in a muted blue monochrome palette, framed as a head-and-shoulders composition with visible 35mm film grain. Centered in the foreground, a young East Asian man in his twenties faces the camera directly ... a polished silver hoop earring hangs from his left ear. His face remains sharply defined beneath a larger translucent profile of the same man layered across it, facing left ..." (214 words, [examples/upsampling/double_exposure_s1.json](examples/upsampling/double_exposure_s1.json)) |