# MotionLint
[](https://www.npmjs.com/package/motionlint) [](LICENSE) [](https://github.com/bobaba99/motionlint/actions/workflows/ci.yml)
**Score any page's animation quality in one command. No API key, no config.**
```bash
npx motionlint audit http://localhost:3000 --open
```
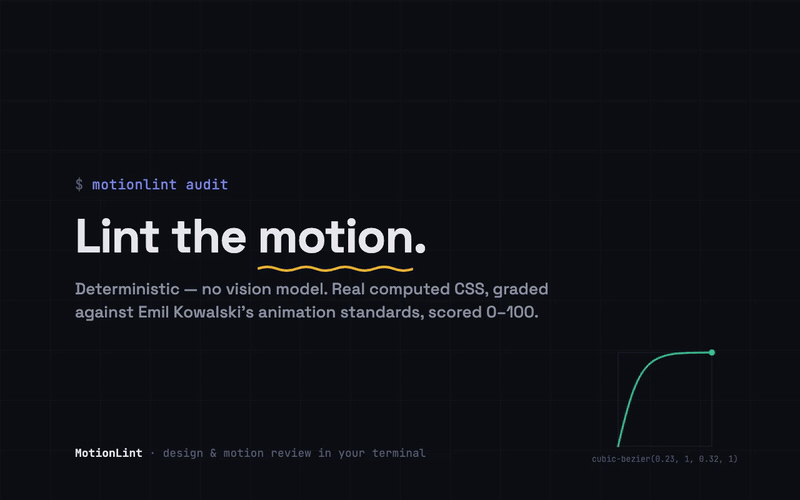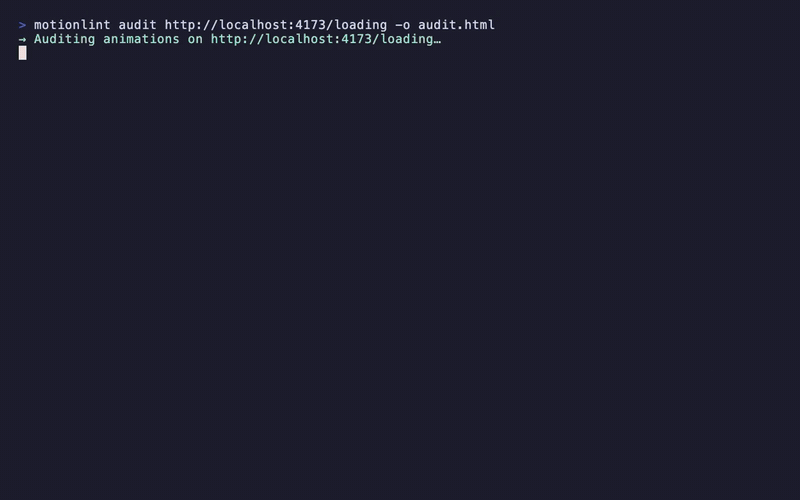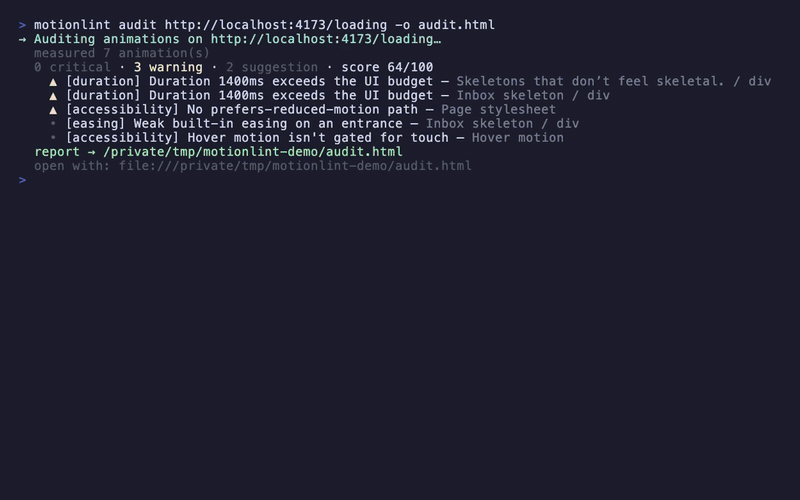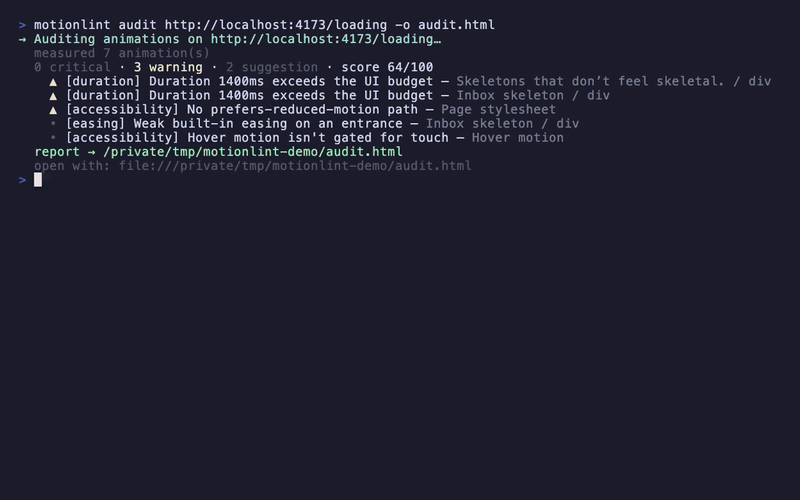
Deterministic — measured from the live page, no LLM involved. One-time prerequisite: npx playwright install chromium.
MotionLint measures the motion your app actually ships — durations, easing curves, stagger intervals, exit timing, reduced-motion support — and scores it against a published set of [animation standards](docs/STANDARDS.md). Ease-in on a dropdown, a 600ms modal, a card that scales from 0, hover motion that fires on touch: all caught, all with the measured value and a concrete fix.
The audit is free and offline. Add an API key and MotionLint also does **vision-LLM design review** — multi-viewport screenshots and 50ms frame bursts of real user journeys, judged by a model and handed back to your coding agent as ranked findings. It runs as an MCP server inside Claude Code and Cursor.
## Why this exists
AI coding agents read JSX, HTML, and CSS — they're blind to what the user actually sees, clicks, and watches animate. Rules in a prompt tell the agent what *should* happen; nothing checks what *did*. Modals that should slide in just pop; loading states get omitted; focus rings disappear. Code review can't catch any of this before merge, because none of it is visible in the diff.
MotionLint closes that loop: it measures the running app and feeds the verdict back.
## How it's different
| | MotionLint | Visual regression tools (Percy, Chromatic, Playwright snapshots) | AI design generators (v0, Galileo, Claude Design, Stitch) |
| --- | --- | --- | --- |
| **Deterministic motion audit** | **13 checks, measured from the live page — no API key, $0** | ✗ | ✗ |
| Multi-viewport UX review | ranked findings across 12 dimensions | pixel diffs only | generates new layouts from prompts |
| **Animation review** | **50ms frame bursts via CDP screencast → contact sheet → LLM** | ✗ | ✗ |
| **Live animation tuning** | **Shadow-DOM previews + sliders + Claude Code export** | ✗ | generates new motion, doesn't tune what's there |
| Native MCP server | ✓ stdio MCP for Claude Code / Cursor | ✗ | varies |
| CI gate | ✓ SARIF + exit codes for code scanning | ✓ image diff thresholds | ✗ |
| Validated quality | **100% recall on a 24-fixture stress test, across 5 frontier models** | n/a | n/a |
The conceptual gap MotionLint closes: visual-regression tools catch what *changed* but not whether the new pixels are *good*; AI design tools generate from scratch but don't review what's already running. MotionLint reviews live behavior with a vision LLM and feeds the verdict back into the coding loop.
## Start here — no API key needed
```bash
npx playwright install chromium # one-time per machine (~300MB)
npx motionlint audit http://localhost:3000 --open
```
That's the whole setup for the audit. It's deterministic, runs offline, costs nothing, and works on any URL you can load — your dev server, a staging deploy, or someone else's site. Requires Node 18+.
The rules it checks are published in [docs/STANDARDS.md](docs/STANDARDS.md) — read them before you install anything.
## Then: LLM design review
Set one API key (`ANTHROPIC_API_KEY`, `OPENAI_API_KEY`, or `GOOGLE_API_KEY` — or run Ollama locally for free) and three more commands unlock:
```bash
npm install -g motionlint
# Multi-viewport UX review of a page → ranked findings across 12 dimensions.
motionlint review http://localhost:3000
# Animation review of a scripted user journey → frame contact sheet + report.
motionlint flow --spec flows/signup.json
# Interactive HTML tuner — every animation on the page, with live sliders.
motionlint tune http://localhost:3000
```
### Inside Claude Code / Cursor
```bash
claude mcp add motionlint -- npx -y motionlint mcp
```
Full flag surface — CI gates, route discovery, Storybook, dark mode, baselines
```bash
# CI mode — non-zero exit on critical issues, SARIF output for code scanning.
motionlint review https://staging.acme.dev --ci --threshold critical --format sarif -o ux.sarif
# Polished, shareable HTML review with embedded screenshots + before/after fixes.
motionlint review http://localhost:3000 --format html -o review.html
# Review every route the site knows about (sitemap.xml + Next.js app/ directory).
motionlint review http://localhost:3000 --discover-routes
# Storybook mode — discover stories from /index.json, review each story iframe as its own route.
motionlint review http://localhost:6006 --storybook
# Color-scheme sweep — light and dark modes, plus Windows High Contrast.
motionlint review http://localhost:3000 --schemes --forced-colors --format html -o review.html
# Interaction affordances — grid each element's default/hover/focus/active states.
motionlint review http://localhost:3000 --state-grid
# Agent focus — keep only the top 5 findings, and only ones not seen in prior runs.
motionlint review http://localhost:3000 --max-findings 5 --new-only
# Before/after comparison — PR preview vs. production baseline.
motionlint review https://pr-123.preview.example.com --against https://prod.example.com
# Reviewer focus — cap the SARIF upload at 10 annotations per report.
motionlint review https://staging.acme.dev --format sarif -o ux.sarif --max-pr-annotations 10
# Pick a provider explicitly (auto-detect picks the first reachable one).
motionlint review http://localhost:3000 --provider anthropic --model claude-sonnet-5
# Track provider quality across runs + teach the reviewer from eval misses.
motionlint eval --provider anthropic --evolve
```
Package on npm: [motionlint](https://www.npmjs.com/package/motionlint).
Sample terminal output for a flow review:
```text
$ motionlint flow --spec flows/signup.json --provider anthropic
→ Running flow "signup-happy-path" against http://localhost:3000/signup (11 steps, 50ms intervals × 750ms window)
provider: anthropic (claude-sonnet-5)
capturing flow…
✓ step 1: 16 frames ✓ step 2: 16 frames ✓ step 3: 16 frames …
captured 176 frames in 31s
contact sheet → .motionlint/flows/signup-happy-path-…png
analyzing flow…
report → .motionlint/flows/signup-happy-path.md
Score: 4/10 · 3 critical findings
[critical] interaction — input focus rings missing across steps 2/4/6
[critical] interaction — submit button has no pressed state
[critical] loading_state — 1.4s wait with no spinner during submit
```
## Try the demo
A multi-route TS animation showcase ships in [demo/](demo/) — covering Motion One, GSAP, anime.js, @formkit/auto-animate, and lottie-web — including a cat-themed one-pager that exercises every MotionLint capability in a single URL:
```bash
node demo/server.mjs # http://localhost:4173
motionlint review http://localhost:4173/cat --record --embed
motionlint flow --spec flows/signup.json
motionlint tune http://localhost:4173/dashboard
```
Routes available: `/`, `/pricing`, `/signup`, `/dashboard`, `/loading`, `/cat`. Reports go to `.motionlint/reports/`, screenshots to `.motionlint/screenshots/`, videos to `.motionlint/videos/`.
## Setup
### API keys
MotionLint auto-loads a `.env` file from the working directory at startup:
```bash
# .env (gitignored)
ANTHROPIC_API_KEY=sk-ant-...
# or
OPENAI_API_KEY=sk-...
# or
GOOGLE_API_KEY=...
# or run a local Ollama (no key needed) — auto-detected on http://localhost:11434
```
Real environment variables take precedence over `.env`. With no key set and no Ollama running, MotionLint falls back to a deterministic **mock provider** so the full pipeline (capture → analysis → report) still runs end-to-end for smoke tests.
### Provider auto-detect
MotionLint auto-detects in this order: **Ollama (local) → Anthropic → OpenAI → Google**. The first one with a working API key (or running service) wins. Override with `--provider ` and `--model `. See [Providers in depth](#providers-in-depth) for the per-provider quality scorecard and how to pick.
---
> *Everything below is for readers who want to understand how MotionLint works under the hood, pick the right provider for their workflow, or wire it into CI.*
## Validated quality across providers
The flow-review pipeline was stress-tested across **12 popular web-app animation patterns × 2 variants** (24 fixtures total) — staggered entrances, hover/press/focus, modal entrances, loading skeletons, form errors, toasts, counter ramps, multi-animation dashboards, modal-with-content stagger, rich form feedback (focus + press + spinner + success), and scroll-driven animations (progress bar + IntersectionObserver reveal + parallax).
Run on **2026-07-27** against the current flagship from each major provider:
| Provider · model | Recall (broken caught) | FPR (clean flagged) | Score gap | Wall time |
| --- | --- | --- | --- | --- |
| **OpenAI · gpt-5.6-sol** | **100%** (12/12) | 0% (0/12) | +3.3 | 10.9 min |
| **OpenAI · gpt-5.5** | **100%** (12/12) | 0% (0/12) | +3.3 | 11.5 min |
| **Anthropic · claude-opus-5** | **100%** (12/12) | 8% (1/12) | +4.1 | 21.0 min |
| **Google · gemini-3.6-flash** | **100%** (12/12) | 17% (2/12) | +5.1 | 4.9 min |
| **Anthropic · claude-sonnet-5** | **100%** (12/12) | 33% (4/12) | +3.1 | 10.8 min |
**Read this as: recall is no longer a differentiator.** Every current flagship catches all 12 seeded faults. That is the finding — a year ago it wasn't true, and it means the model choice no longer decides whether MotionLint works. Pick on cost and latency.
**Do not rank these models on the FPR column.** A single 24-fixture run cannot resolve it. Across two clean runs of the identical suite, with nothing changed but sampling, FPR moved by 1–2 fixtures per model — `gpt-5.5` 1/12 → 0/12, `gpt-5.6-sol` 2/12 → 0/12, `gemini-3.6-flash` 3/12 → 2/12. One fixture is 8 percentage points, so the entire spread between "0%" and "17%" sits inside the noise floor. Treat the column as *"all of these occasionally flag something clean"*, not as a ranking.
Why the older numbers in this table's history were wrong
The first 2026-07-27 run of this suite put `claude-opus-5` at 83% recall — last among all five models — and the 2026-04-29 edition of this table reported several models at 0% FPR. Both were artifacts of a MotionLint bug, not model behaviour.
Anthropic's `max_tokens` defaulted to 4096. Verbose responses hit the ceiling mid-JSON, and the unparseable result was scored as `0/10, no issues found` — indistinguishable from a clean review. Two of Opus 5's three truncations landed on broken fixtures, which produced the entire 83% figure.
The same bug deflated FPR everywhere: a truncated review reports *nothing*, so it cannot raise a false positive. Any historical "0% FPR" was partly measuring broken parsing rather than model precision. Fixed 2026-07-27, along with the sibling paths that turned truncated, refused, and safety-blocked responses into clean-looking results.
Full per-provider scorecards in [.motionlint/stress/](.motionlint/stress/) after running [scripts/run-all-benchmarks.mjs](scripts/run-all-benchmarks.mjs). Use `--only :` to re-run a single model.
## Providers in depth
| Provider | Model | Setup | Quality (24 fixtures) | Cost per review¹ |
| --- | --- | --- | --- | --- |
| `google` | `gemini-3.6-flash` | `GOOGLE_API_KEY=…` | 100% recall · 17% FPR · +5.1 gap | **$0.019** |
| `anthropic` | `claude-sonnet-5` | `ANTHROPIC_API_KEY=…` | 100% recall · 33% FPR · +3.1 gap | $0.089 |
| `openai` | `gpt-5.5` | `OPENAI_API_KEY=…` | 100% recall · 0% FPR · +3.3 gap | $0.248 |
| `openai` | `gpt-5.6-sol` | `OPENAI_API_KEY=…` | 100% recall · 0% FPR · +3.3 gap | $0.265 |
| `anthropic` | `claude-opus-5` | `ANTHROPIC_API_KEY=…` | 100% recall · 8% FPR · +4.1 gap | $0.293 |
| `ollama` | any vision model | `ollama serve` + `ollama pull ` | not benchmarked in this run | $0 |
| `mock` | heuristic stub | (auto fallback) | n/a — deterministic stub for CI smoke tests | $0 |
¹ **Measured, not estimated** — one real `motionlint review` per model against the demo app at the default 2 viewports, full-page, reading actual token counts from each provider's usage field and multiplying by published list price. Reproduce with `formatUsageLine()` on any run. Sonnet 5 uses its introductory rate (through 2026-08-31); it roughly rises by half after that. Flow review sends one composite image per flow but the contact sheet is larger. The Animation Tuner and `motionlint audit` make **zero** LLM calls and cost nothing.
**Output tokens dominate.** Input is within 2× across all five models; output spans 1,390 (Gemini) to 10,219 (Opus 5). That 7× spread, not image size, is what makes the most expensive model 15× the cheapest.
### How to pick
- **Default.** Google `gemini-3.6-flash` — 100% recall, **13× cheaper** than Opus 5 and the fastest of the five (4.9 min). Since every model caught every fault, there is no quality argument for paying more by default.
- **Anthropic house.** `claude-sonnet-5` at $0.089 — 3× cheaper than `claude-opus-5` with identical recall. Opus 5 costs more and took **2× the wall time** (21.0 min vs 10.8) for no measured recall advantage; reach for it only if you value its slightly higher score gap (+4.1 vs +3.1).
- **OpenAI house.** `gpt-5.5` and `gpt-5.6-sol` are indistinguishable on every measured axis and within 7% on price. Take whichever your account already has.
- **Hard CI gate.** Any of them on recall. Do not pick on FPR — see the noise-floor caveat above. If false positives matter to your gate, run your own fixtures rather than trusting a single 24-fixture run of ours.
- **Local / air-gapped.** Any Ollama vision model works, but confirm it *is* vision-capable: some accept images over the API, silently ignore them, and answer from the prompt alone. None was benchmarked in this run.
### Switching providers
Every command honours `--provider` and `--model`:
```bash
motionlint review http://localhost:3000 --provider openai --model gpt-5.5
motionlint flow --spec flows/signup.json --provider google --model gemini-3.6-flash
motionlint review http://localhost:3000 --provider ollama --model llava:13b
```
### Benchmarking your own provider
To compare a new provider against the same 24-fixture stress test:
```bash
node -e "
import('./dist/config/env.js').then(async ({ loadEnv }) => {
loadEnv();
const { runStress, renderStressMarkdown } = await import('./dist/flow/stress.js');
const { writeFile, mkdir } = await import('node:fs/promises');
const { resolve } = await import('node:path');
await mkdir('.motionlint/stress', { recursive: true });
const r = await runStress({
stressPath: resolve('eval/animation-stress.json'),
fixturesDir: resolve('eval/animation-fixtures'),
artifactDir: resolve('.motionlint/stress'),
provider: 'YOUR_PROVIDER', // 'openai' | 'google' | 'ollama'
});
await writeFile('.motionlint/stress/SCORECARD.md', renderStressMarkdown(r), 'utf8');
console.error('Recall:', (r.broken_recall*100).toFixed(0)+'%, FPR:', (r.good_false_positive_rate*100).toFixed(0)+'%, gap:', r.avg_score_gap.toFixed(1));
});
"
```
Open `.motionlint/stress/SCORECARD.md` for the per-pattern breakdown.
## How `motionlint flow` works
Static screenshots can't tell you whether a flow's animations and interaction states work — only whether the final frame looks right. `motionlint flow` fills that gap.
Given a scripted user journey, it:
1. Runs the journey in headless Chromium via Playwright — clicking, typing, hovering, scrolling, pressing keys exactly like a user would.
2. Captures a **burst of 16 frames over 750ms (50ms intervals) after every interaction** via CDP screencast (`Page.captureScreenshot` JPEG, ~8ms per shot). 50ms is half the human visual-detection threshold and below the industry-typical 100ms minimum animation interval — short animations like 100ms button presses get caught with 2-3 mid-state frames. Every interaction burst is also pixel-diffed for input→feedback latency — interactions with no visible acknowledgment within the burst window are flagged deterministically.
3. Records the **full Playwright video** as an artifact you can scrub later.
4. Composites every burst into a labeled **contact sheet** — one row per step, frames laid out in sub-rows.
5. Sends the sheet to the vision LLM with a flow-aware rubric covering: missing animations, buggy/janky animations, missing loading states, perceived performance, affordance & state changes, choreography, smoothness, accidental flicker, navigation continuity, reduced-motion respect.
6. Produces a Markdown report with per-step trace, ranked findings, and a **"Prompt for Claude Code"** block at the bottom — paste it into CC and it acts on the findings directly.
### Multi-animation handling
A single recording can capture and analyze multiple concurrent animations. Validated on:
- **Dashboard reveal** (3 concurrent: tile stagger + counter ramps + chart bar rise)
- **Modal stack** (backdrop fade + modal slide+fade + inner content stagger)
- **Rich form feedback** (focus ring + button press + loading spinner + success card)
- **Scroll-driven** (scroll-progress bar + IntersectionObserver section reveal + parallax hero)
The LLM correctly identifies *which* animations are broken without false-flagging the working ones — see the validated-quality table.
### Scroll-driven animations
For sites with scroll-linked animations, `scroll ` steps animate the scroll over the burst window via `requestAnimationFrame` so each frame shows progressive scroll position and the LLM sees the timing as the page scrolls.
### Flow examples
```bash
# Inline DSL — semicolon-separated steps
motionlint flow \
--url http://localhost:3000 \
--steps "navigate /signup; click input#email; type input#email=ada@example.com; click button[type=submit]; wait 2000; capture \"post-submit\"" \
--name signup-happy-path
# Or load a structured spec with expected_animations[] hints
motionlint flow --spec flows/signup.json --provider anthropic
# Pass team motion preferences (philosophy + inspirations + accepted defaults)
# Embedded into the prompt AND the report's CC handoff block.
motionlint flow --spec flows/signup.json --preferences flows/preferences.md
# Tighten the interval below 50ms for fine-grained timing review
motionlint flow --spec flows/signup.json --interval 30 --burst-ms 600
# Auto-detect: scan the page's animations, pick an interval that captures
# the shortest one with 4 frames inside it (clamped to [20, 100]ms).
motionlint flow --spec flows/signup.json --auto-interval
```
### Inline DSL reference
| Action | Form | Notes |
| --- | --- | --- |
| navigate | `navigate /pricing` | path or full URL |
| click | `click button#start` | CSS selector |
| hover | `hover .feature` | CSS selector |
| type | `type input#email=ada@example.com` | selector=value |
| press | `press Enter` | keyboard key |
| scroll | `scroll 800` | pixels; animates over the burst window |
| wait | `wait 500` | ms |
| capture | `capture "post-submit"` | take an explicit burst with optional label |
Defaults: a frame burst is taken after *every* interaction. Pass `--no-implicit-bursts` to only burst on explicit `capture` steps. Pass `--no-record` to skip video.
Three ready-to-run sample flows ship in the repo: [flows/signup.json](flows/signup.json), [flows/loading-state.json](flows/loading-state.json), and [flows/preferences.md](flows/preferences.md).
## How the Animation Tuner works
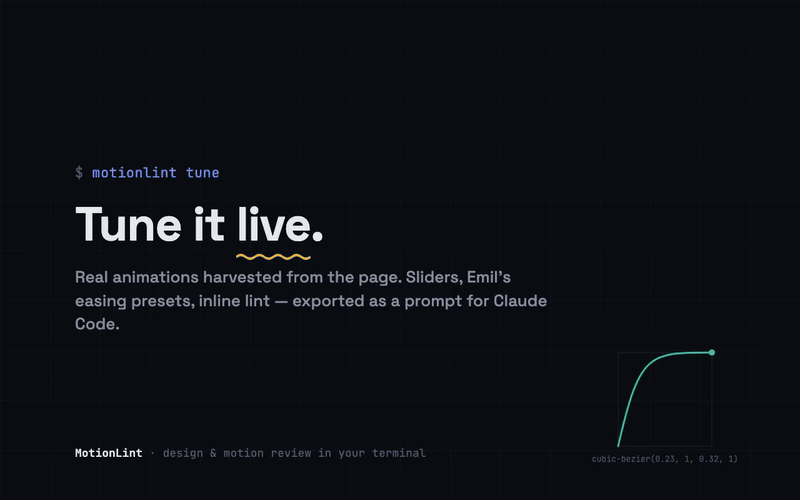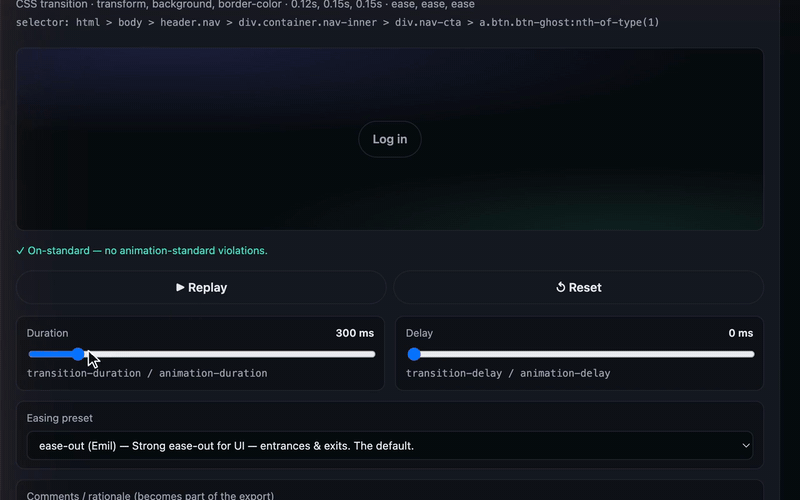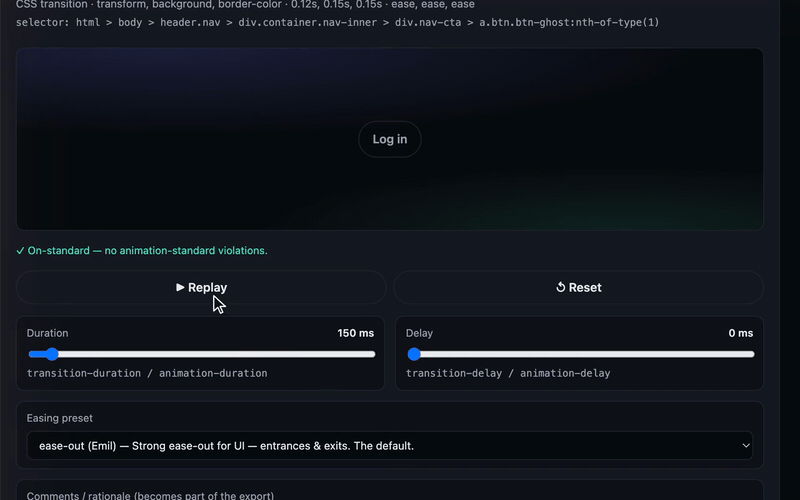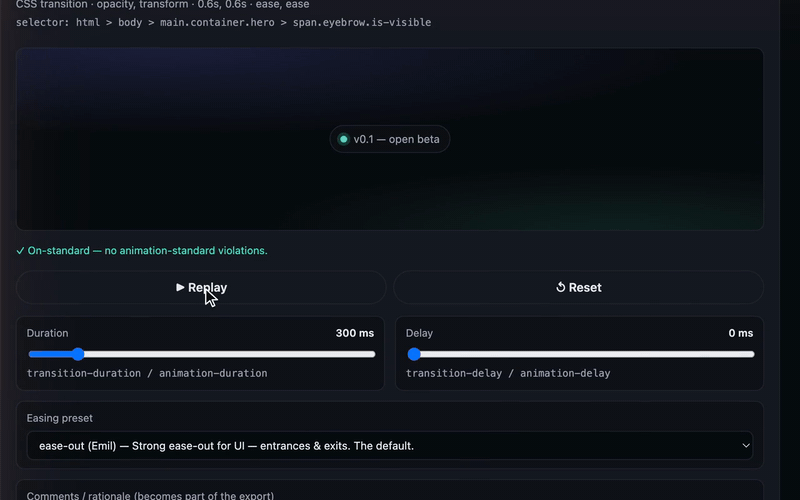
Most AI coding tools generate animations from scratch. The Tuner lets you **tune the animations that are already running on your page**, in real time, and hand the changes back to your coding agent as a structured prompt.
```bash
motionlint tune http://localhost:3000 --open
```
This:
1. Opens your app in headless Chromium with an instrumentation script that hooks the major TS animation libraries (Motion One, GSAP, anime.js, @formkit/auto-animate, lottie-web) plus all CSS transitions and `@keyframes` running on the page.
2. Captures every detected animation: the element selector, source library, timing parameters, and bounding box.
3. Generates a self-contained interactive HTML page at `.motionlint/tuner/index.html` (auto-opens with `--open`):
- **Live preview surface** per animation (Shadow DOM — no iframes, no flash, themed to the source page).
- **Sliders** for duration / delay / stagger / speed.
- **Easing-preset dropdown** — Emil Kowalski's strong curves lead (ease-out, ease-in-out, iOS drawer), then the softer/decorative options.
- **Inline standards linting** — each card flags where the animation deviates from the motion standards (severity badge, fix, suggested value), with a header score.
- **Comments box** per animation for design rationale.
4. Exports a markdown file plus a Claude-Code-ready prompt with a structured `changes[]` JSON block. Paste that into CC and it edits your codebase to apply the new parameters.
```text
$ motionlint tune http://localhost:3000
→ Capturing animations on http://localhost:3000…
detected 15 animation(s)
tuner → /Users/you/proj/.motionlint/tuner/index.html
open with: file:///Users/you/proj/.motionlint/tuner/index.html
```
## Animation standards — `motionlint audit`
MotionLint encodes [Emil Kowalski's](https://emilkowal.ski/) design-engineering standards as a **deterministic linter** — no vision model, no API key, no cost. `motionlint audit` instruments the page, reads the real timing/easing/transform values every animation is running, and grades them:
| Category | What it catches | The standard |
| --- | --- | --- |
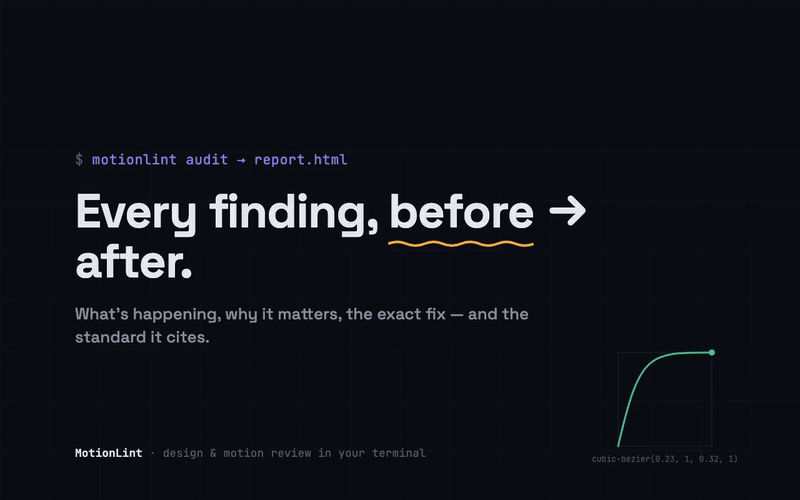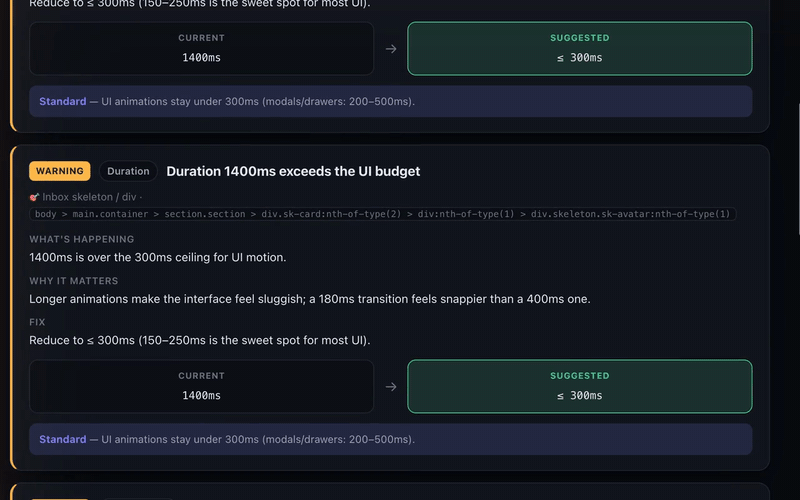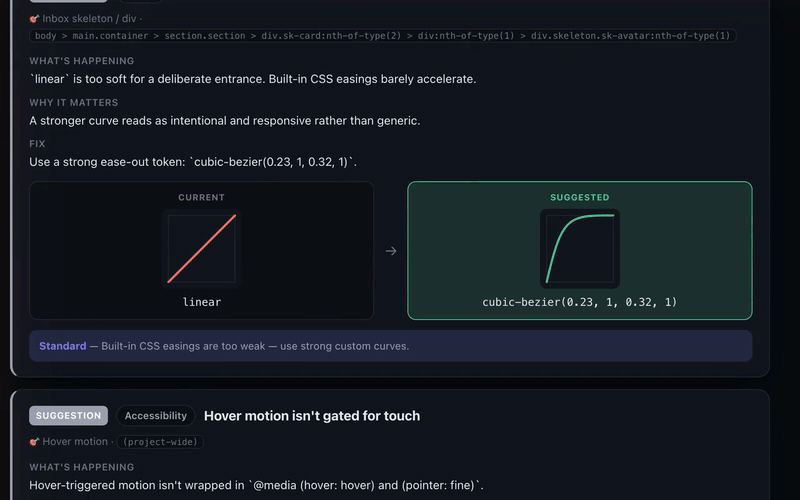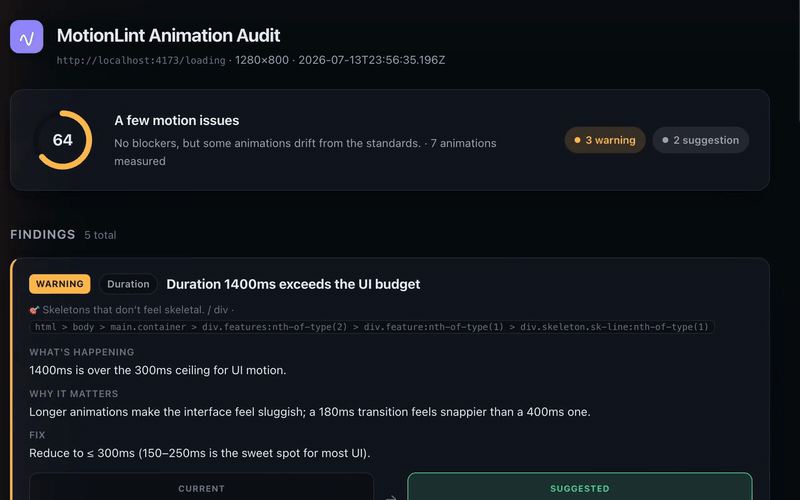
| **Easing** | `ease-in` on UI; weak built-in curves on deliberate entrances | Entering/exiting → strong ease-out `cubic-bezier(0.23, 1, 0.32, 1)`; never `ease-in` |
| **Duration** | UI motion over the 300ms ceiling (modals/drawers get 200–500ms) | A 180ms transition feels snappier than a 400ms one; exits ~20% faster |
| **Physicality** | `scale(0)` entrances | Nothing appears from nothing — start from `scale(0.95)` + `opacity: 0` |
| **Performance** | `transition: all`, animating layout properties, stray infinite loops | Animate `transform` and `opacity` only — they skip layout/paint |
| **Cohesion** | Hand-rolled easing-curve sprawl; stagger intervals outside the 30–80ms band | Curves and durations should live as shared tokens; grouped entrances stagger 30–80ms apart |
| **Duration (pairs)** | Exits that aren't faster than their entrance (`fadeIn` 300ms / `fadeOut` 300ms) | Exits run ~20% faster than the matching entrance |
```bash
motionlint audit http://localhost:3000 --open # polished HTML report, scored 0–100
motionlint audit http://localhost:3000 --json audit.json --ci # machine-readable; non-zero on critical
```
Add `--layout` to also lint layout (tap targets, text size, contrast, overflow) from live DOM measurements — still deterministic, still no API key.
Add `--watch [dir]` to re-run the audit on file changes under `[dir]` (default: cwd) and print the score with a delta after each run — a live readout while you iterate. Recursive watching requires macOS, Windows, or Linux with Node 20+.
The report pairs every finding with a **before → after** panel; easing findings render a live cubic-bezier curve comparison so the fix is visible, not just described. The same standards feed the `flow` review prompt (so vision findings cite concrete rules) and appear inline in the Animation Tuner.
## MCP server — tools, resources, deployment
MotionLint ships an MCP server over stdio so an LLM agent can drive it directly inside a chat. The `motionlint mcp` subcommand boots it; the agent client spawns the process when a tool is called.
### Installing in Claude Code
Published-npm version (recommended):
```bash
claude mcp add motionlint -- npx -y motionlint mcp
```
Local checkout (handy while developing):
```bash
claude mcp add motionlint -- node /absolute/path/to/motionlint/dist/index.js mcp
```
After registration:
1. Confirm it appears: `claude mcp list` — `motionlint` should show as `running` or `available`.
2. Make sure API keys are reachable. The MCP server inherits the env it's spawned in. Cleanest path: drop a `.env` file in the project directory you're working from — MotionLint auto-loads it on startup.
3. First run: `npx playwright install chromium` if you haven't already.
Then in Claude Code:
> *"Use motionlint to review the local app at mobile and desktop and tell me the top 3 issues to fix."*
>
> *"Run motionlint review_flow on `http://localhost:3000/signup` with steps `click input#email; type input#email=test@test.com; click button[type=submit]; wait 2000; capture` and check the animations."*
>
> *"Run motionlint tune_animations on `http://localhost:3000/pricing` — I want to fine-tune the card hover animations."*
### Tools exposed
| Tool | What it does |
| --- | --- |
| `review_url(url, viewports?, provider?, model?, wait_for?, record?, format?, max_findings?, max_pr_annotations?, new_only?)` | Static UX review of a URL at multiple viewports. Returns a markdown / JSON / SARIF report. |
| `review_routes(base_url, routes, viewports?, ..., max_findings?, max_pr_annotations?, new_only?)` | Same review across multiple routes of one app. |
| `review_flow(url, steps?\|spec_path?, preferences_path?, provider?, ...)` | Animation/interaction review of a scripted user journey. Returns a flow report with the structured CC handoff block. |
| `tune_animations(url, viewport_*?, settle_ms?, output?)` | Detects every animation on a page and writes an interactive HTML tuner. Returns the file path. |
| `get_latest_report(format?)` | Returns the most recent review/flow report content. |
Resources: `motionlint://reports/latest` — the most recent report content.
### Deployment checklist
Before deploying or sharing the MCP server with other users:
- [ ] **Build is fresh.** `npm run build` then verify `dist/index.js` exists. Without this, `motionlint mcp` won't start.
- [ ] **Playwright Chromium installed** on the target machine: `npx playwright install chromium`. The postinstall hook reminds you, but it's not enforced (we don't auto-download a 300 MB binary on `npm install`).
- [ ] **API keys reachable** — either via shell env or via a `.env` file in the working directory the MCP client launches from.
- [ ] **Smoke-test the MCP surface.** `npm test` includes an MCP smoke test that boots the server, lists tools, and asserts the expected tool surface.
- [ ] **No secrets committed.** `.env` is gitignored; `.env.example` should be a placeholder. Worth a final `git diff --cached | grep -i 'sk-\|api_key'` before pushing.
- [ ] **Confirm with `claude mcp list`** that the server shows up and isn't erroring at startup.
## CI integration
```yaml
# .github/workflows/ux.yml
- run: npm ci
- run: npx playwright install chromium
- run: npx motionlint review $STAGING_URL --ci --threshold critical --format sarif -o ux.sarif
- uses: github/codeql-action/upload-sarif@v3
with: { sarif_file: ux.sarif }
```
MotionLint exits with `1` when critical issues exceed the configured threshold (`failOnCritical`) — wire it as a status check.
## What it captures · what it analyzes
**Captures:**
- **Full-page screenshots** at three default viewports (mobile 375 / tablet 768 / desktop 1440). Override via config.
- **Above-the-fold** screenshots with `--no-full-page`.
- **Videos** of the navigation+capture run with `--record` (Playwright `.webm`).
- **Interaction sequences** before capture: `click`, `hover`, `type`, `scroll`, `wait`.
- **Auth state**: cookies, `localStorage`, and a `beforeNavigate` script — all configurable in `.motionlintrc.json`.
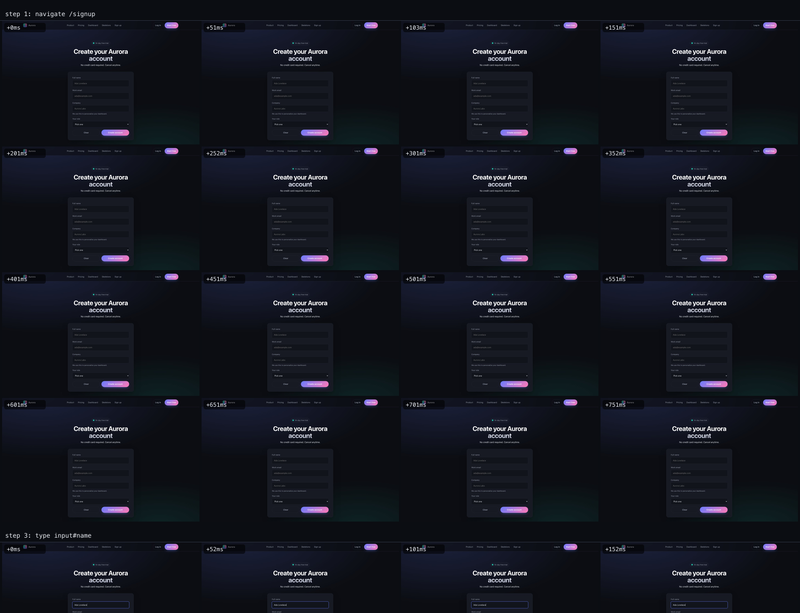
A motionlint flow contact sheet — timestamped bursts after each interaction, exactly what the vision model sees.
**Analyzes:** each screenshot is sent to a vision model with an opinionated UX-review system prompt covering twelve dimensions (`hierarchy`, `spacing`, `alignment`, `typography`, `color`, `contrast`, `responsiveness`, `interaction`, `content`, `navigation`, `consistency`, `loading_state`). For each issue the model returns:
```json
{
"category": "hierarchy",
"severity": "critical | warning | suggestion",
"location": "above-the-fold hero",
"issue": "Primary CTA blends into the background gradient.",
"why_it_matters": "Users miss the conversion path on first scroll.",
"fix": "Increase background contrast or use a solid surface behind the button."
}
```
Override the prompt with `--rules path/to/your-design-rules.md` to inject project-specific heuristics.
Every review capture also takes a **DOM snapshot**: notable elements (headings, CTAs, inputs) get stable refs (`E1`, `E2`, …) with measured pixel rects, listed in the prompt so the model can ground a finding with `"element_ref": "E3"`. Cited refs resolve back to their rects and are **drawn as severity-colored bounding boxes on the screenshot** in the HTML report (and reported as `Where: E3 at (x, y) w×h` in markdown). Refs the page never listed are dropped — the model can't annotate what it wasn't shown.
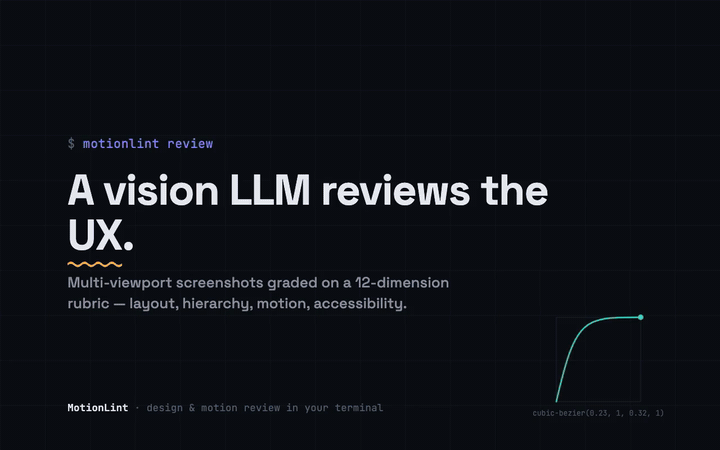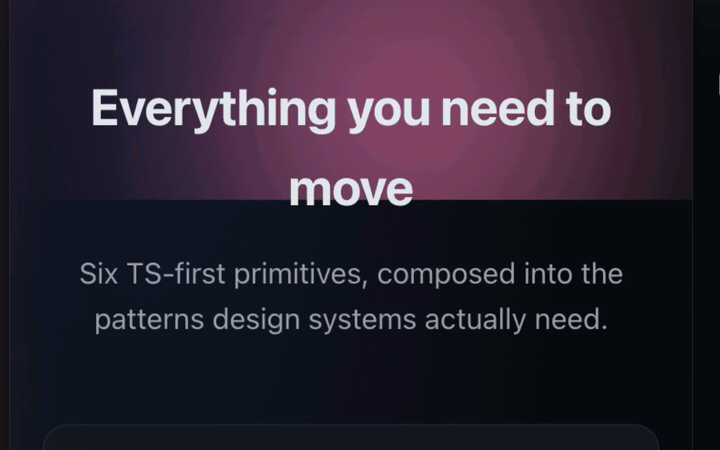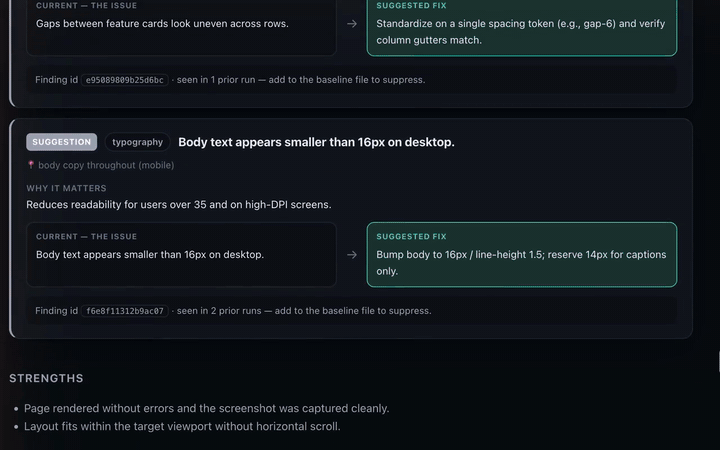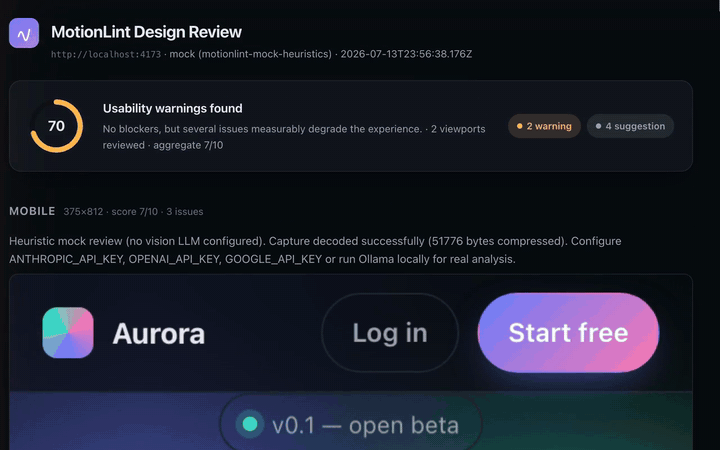
With `--format html` the findings render as a single shareable report — score ring, per-dimension breakdown, and an issue → fix panel per finding with the annotated screenshot:
## Configuration reference
Drop a `.motionlintrc.json` in your repo root (or use `motionlint.config.js` / a `"motionlint"` key in `package.json`):
```json
{
"provider": "auto",
"fallbackProvider": "anthropic",
"fallbackModel": "claude-sonnet-5",
"viewports": {
"mobile": { "width": 375, "height": 812 },
"tablet": { "width": 768, "height": 1024 },
"desktop": { "width": 1440, "height": 900 }
},
"defaultViewports": ["mobile", "desktop"],
"waitFor": "networkidle",
"waitTimeout": 10000,
"screenshotDir": ".motionlint/screenshots",
"videoDir": ".motionlint/videos",
"reportDir": ".motionlint/reports",
"rules": null,
"record": false,
"maxFindings": null,
"maxPrAnnotations": null,
"memory": {
"enabled": true,
"path": ".motionlint/memory.json",
"baseline": ".motionlintignore",
"newOnly": false
},
"resources": { "maxConcurrentReviews": null, "providerCallsPerMinute": null, "maxTokensPerRun": null },
"ci": { "threshold": "warning", "failOnCritical": true },
"auth": { "cookies": null, "localStorage": null, "beforeNavigate": null }
}
```
## Review volume control
Re-running review on the same routes used to surface the same findings every run. Two mechanisms keep the output focused:
- **Per-run output cap** — `--max-findings N` (or `maxFindings` in config) keeps only the top N findings per run, severity-ordered, so an agent works on what matters most first. The report's `Omitted` line says how many were capped.
- **PR-surface cap** — `--max-pr-annotations N` (or `maxPrAnnotations` in config; SARIF only) emits at most N results per report, severity-ordered, so a code-scanning upload doesn't flood a PR with annotations. The dropped count lands in the SARIF run's `omitted_by_pr_cap` property.
- **Resource cap** — `resources.maxConcurrentReviews` bounds how many reviews run at once in one process (an MCP server fielding several agents in flight), and `resources.providerCallsPerMinute` is a process-wide sliding-window ceiling on vision-LLM calls (provider quota / spend control; also applies to `flow` reviews, where each `--consistency` sample counts). Both default to unlimited; both are config-only. Note they compose: a review holding a concurrency slot also waits out the rate limiter, so tight values on both multiply latency.
- **Cost ceiling** — every provider call's token usage is captured and totalled per run (a `Tokens:` line in reports, `token_usage` in SARIF run properties). `--max-tokens N` (or `resources.maxTokensPerRun` in config) sets a per-run token budget: once the running total crosses it, remaining viewports are skipped and the report lists them under `skipped_viewports`. Providers that report no usage still count calls but consume no budget.
- **Cross-run memory** — every finding gets a stable id (hash of category + element location + normalized issue text). Recurrence detection goes further than exact hashing: category-synonym compatibility plus canonical-token overlap (thresholds calibrated on real cross-run data) matches the same fault even when the vision LLM rewords it between runs. Sightings are recorded per URL in `.motionlint/memory.json`; recurring findings are annotated with *seen in N prior runs* rather than silently dropped. Opt into deltas-only with `--new-only`. To permanently wave off a finding, copy its id into `.motionlintignore` (one hash per line, `#` comments and trailing notes allowed). Disable everything with `--no-memory`.
SARIF output carries the finding id as a `partialFingerprint`, so GitHub code scanning dedups the same finding across runs and PRs natively.
Concurrent reviews of the same project are safe: the memory store is updated under a stale-aware file lock (`memory.json.lock`), so parallel runs don't clobber each other's recorded sightings. A wedged lock never fails a review — after a short wait the run warns and proceeds without it.
## Use cases
- **Pre-merge UX guardrail.** Solo dev or 2-person startup with no designer. Run `motionlint review https://pr-123.preview.example.com --ci --threshold critical` in CI; warning-or-worse blocks the merge until you've at least seen the issues.
- **MCP design colleague inside Claude Code.** Add MotionLint as an MCP server, then ask CC: *"review the local app at mobile and desktop and tell me the top 3 issues to fix."* CC drives the tool and gets back annotated feedback in the same conversation.
- **Continuous quality monitoring.** Schedule a nightly cron (`motionlint review https://prod.example.com --format sarif -o ux.sarif`) and surface SARIF in your code-scanning dashboard so production regressions get caught the morning after.
- **Animation / flow QA on a feature you just shipped.** `motionlint flow` runs a scripted user journey through Playwright like a human would, captures frame bursts at every interaction, records video, and asks the LLM to review the *animation behavior* across the captured frames.
- **Live animation tuning + handoff to Claude Code.** Capture every animation on a page, tune timing/easing/delay live with sliders, export a structured prompt CC can act on directly.
## Project layout
```text
src/
capture/ Playwright capture (screenshot, mosaic, DOM snapshot) + interaction sequences
providers/ Vision LLM providers (ollama, anthropic, openai, google, mock) + self-consistency wrapper
analysis/ Rubric-style UX prompt + JSON parser + rule injection
report/ Markdown / JSON / SARIF report generators
eval/ Tiered eval harness (L1/L2/L3 fixtures, scorer, runner, report)
flow/ Flow runner — spec parser, capture orchestrator, animation-aware report
tuner/ Animation Tuner — extractor, instrumentation script, Shadow-DOM render
mcp/ MCP server for Claude Code
cli/ Commander.js commands + terminal output
config/ cosmiconfig loader + .env loader
demo/ TS animation showcase used as a review target
flows/ Sample flow specs (signup, loading-state) for `motionlint flow`
eval/fixtures/ Labelled HTML pages with seeded UX faults at three complexity levels
test/ Node test runner unit + integration tests
```
## Roadmap
**v0.1 (this release)** — shipped:
- Three CLI commands: `review`, `flow`, `tune` + MCP server (`motionlint mcp`).
- Five vision providers: Anthropic, OpenAI, Google, Ollama, mock.
- Multi-viewport static review with mosaic capture, DOM measurement side-channel, self-consistency sampling, soft-keyword scoring with synonym graph.
- Tiered eval harness (L1 / L2 / L3) with 21 labelled fixtures and structured `next_actions[]` JSON for downstream LLM coding tools.
- Flow review at **50ms inter-frame intervals** via CDP screencast (16 frames × 750ms burst), with multi-animation and scroll-driven support.
- Animation Tuner with Shadow-DOM previews, live sliders, easing presets, Claude-Code export.
- Animation stress-test harness validated at **100% recall / 0% FPR on 24 fixtures across 12 patterns**.
- Team motion preferences markdown (`--preferences`) embedded into the LLM rubric and the CC handoff block.
- Auto-interval scan (`--auto-interval`) that picks an inter-frame interval based on the shortest animation detected on the page.
- SARIF output for GitHub code scanning.
**v0.2 (in progress)** — shipped so far:
- Token accounting + per-run cost ceiling (`--max-tokens` / `resources.maxTokensPerRun`; `Tokens:` line in every report).
- Auto-discover routes (`--discover-routes`: sitemap.xml + Next.js app directory).
- Annotated bounding boxes: DOM element refs in the prompt, findings drawn on the screenshot in the HTML report.
- Interaction-state grids (`--state-grid`: default/hover/focus/active per element, one labeled image).
- Provider scorecard history with per-model regression detection (`.motionlint/eval-history.json`).
- Closed-loop prompt evolution from eval `next_actions` (`eval --evolve` → learned heuristics in review prompts).
- Two new audit rules: stagger-interval band (30–80ms) and exit-~20%-faster-than-entrance.
**v0.2 (next)**:
- GitHub Action wrapper (`motionlint-action`).
## Acknowledgments
MotionLint stands on other people's work:
- **[Emil Kowalski](https://emilkowal.ski/)** — the animation standards behind `motionlint audit`, the tuner's easing presets, and the flow-review rubric are distilled from his design-engineering writing and his [animations.dev](https://animations.dev/) course. His open-source UI libraries — [sonner](https://github.com/emilkowalski/sonner) (toasts) and [vaul](https://github.com/emilkowalski/vaul) (drawers) — are living reference implementations of the motion these rules describe. MotionLint is an independent project, not affiliated with or endorsed by Emil.
- **[ctx](https://github.com/ctxrs/ctx)** ([ctx.rs](https://ctx.rs)) — local coding-agent history search. We used it while developing the cross-run memory layer to study how findings survive (or vanish) across agent runs; those experiments directly shaped the finding-id and baseline design.
## License
[MIT](LICENSE) © Resila Technologies Inc.