### [NeurIPS 2025] Unifying Visual Understanding and Generation via Text-Aligned Representations
> [Jiaming Han](https://csuhan.com), [Hao Chen](https://haochen-rye.github.io)†, [Yang Zhao](https://scholar.google.com/citations?user=uPmTOHAAAAAJ&hl=zh-CN), [Hanyu Wang](https://hywang66.github.io), [Qi Zhao](https://kevinz8866.github.io), [Ziyan Yang](https://ziyanyang.github.io), [Hao He](https://hehao13.github.io), [Xiangyu Yue](https://xyue.io)‡, [Lu Jiang](https://www.lujiang.info)‡
>
> † Project Lead ‡ Corresponding Authors


 ### News
- Sep 2025. Tar is accepted by **NeurIPS 2025**.
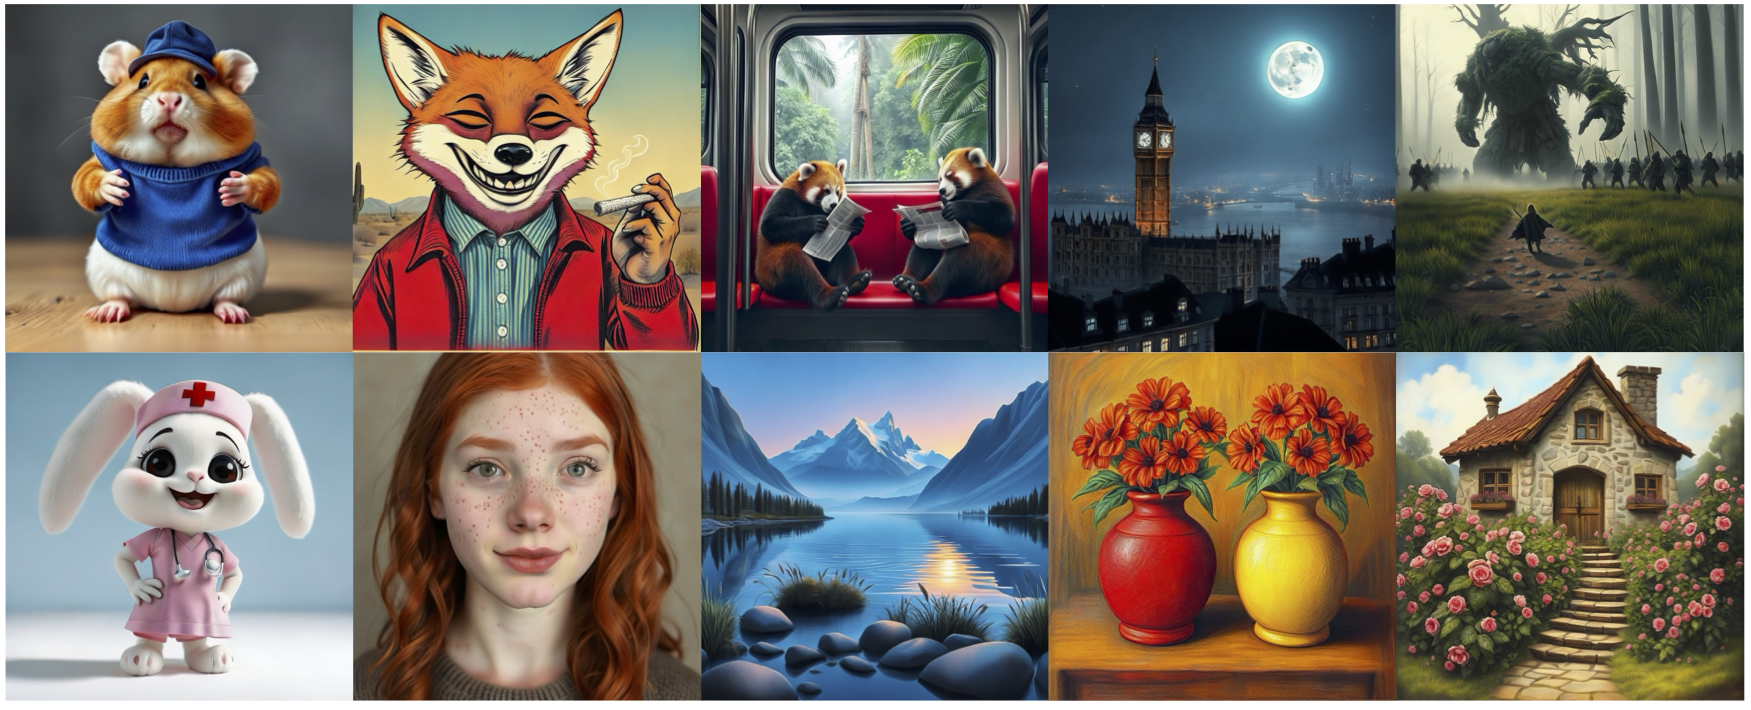
- Sep 2025. New Dif-DTok based on [Lumina2](https://github.com/Alpha-VLLM/Lumina-Image-2.0), which shows better consistency and higher image quality! Check [t2i_inference_lumina2.py](t2i_inference_lumina2.py) for inference and [lumina_dtok](https://github.com/csuhan/Tar/tree/lumina_dtok) branch for training.
- Aug 2025. Release Dif-DTok. Check [t2i_inference_sana.py](t2i_inference_sana.py) for usage.
- June 2025. Code and models are released.
### Contents
- [Install](#install)
- [Models](#models)
- [Inference](#inference)
- [Demo](#demo)
- [Train](#train)
- [Evaluation](#evaluation)
### Install
```bash
git clone https://github.com/csuhan/Tar && cd Tar
conda create -n tar python=3.10 -y
pip install -r requirements.txt
# optional
pip install flash-attn --no-build-isolation
```
### Models
1️⃣ Text-Aligned Tokenizer (TA-Tok)
| Model | Encoder | Input Size | Codebook Size | Link |
|:------:|:-------:|:----------:|:-------------:|:----:|
| TA-Tok | [SigLIP2](https://huggingface.co/google/siglip2-so400m-patch14-384) | 384px | 65536 | [ta_tok.pth](https://huggingface.co/csuhan/TA-Tok/resolve/main/ta_tok.pth) |
2️⃣ De-Tokenizer
| Model | Type | VQVAE | Output Size | Link |
|:-------:|:----:|--------------|:-----------:|:----:|
| AR-DTok | AR | [vq_ds_t2i.pt](https://huggingface.co/peizesun/llamagen_t2i/resolve/main/vq_ds16_t2i.pt) | 256px | [ar_dtok_lp_256px.pth](https://huggingface.co/csuhan/TA-Tok/resolve/main/ar_dtok_lp_256px.pth) |
| AR-DTok | AR | [vq_ds_t2i.pt](https://huggingface.co/peizesun/llamagen_t2i/resolve/main/vq_ds16_t2i.pt) | 512px | [ar_dtok_lp_512px.pth](https://huggingface.co/csuhan/TA-Tok/resolve/main/ar_dtok_lp_512px.pth) |
| AR-DTok | AR | [vq_ds_t2i.pt](https://huggingface.co/peizesun/llamagen_t2i/resolve/main/vq_ds16_t2i.pt) | 1024px | [ar_dtok_lp_1024px.pth](https://huggingface.co/csuhan/TA-Tok/resolve/main/ar_dtok_lp_1024px.pth) |
| Model | Type | Pretrain | Output Size | Link |
|:-------:|:----:|--------------|:-----------:|:----:|
| Dif-DTok| Diffusion | SANA-600M | 512px | [Tar-SANA-600M-512px](https://huggingface.co/csuhan/Tar-SANA-600M-512px) |
| Dif-DTok| Diffusion | SANA-600M | 1024px | [Tar-SANA-600M-1024px](https://huggingface.co/csuhan/Tar-SANA-600M-1024px) |
| Dif-DTok| Diffusion | Lumina2-2.6B | 1024px | [csuhan/Tar-Lumina2](https://huggingface.co/csuhan/Tar-Lumina2)🌟 |
3️⃣ LLM
| Model | Vision Tokenizer | LLM | Link |
|:--------:|------------------|:------------:|:----:|
| Tar-1.5B | TA-Tok | [Qwen2.5-1.5B-Instruct](https://huggingface.co/Qwen/Qwen2.5-1.5B-Instruct) | [csuhan/Tar-1.5B](https://huggingface.co/csuhan/Tar-1.5B) |
| Tar-7B | TA-Tok | [Qwen2.5-7B-Instruct](https://huggingface.co/Qwen/Qwen2.5-7B-Instruct) | [csuhan/Tar-7B](https://huggingface.co/csuhan/Tar-7B-v0.1) |
### Inference
1️⃣ Text-to-image generation with AR-DTok
```python
from t2i_inference import T2IConfig, TextToImageInference
config = T2IConfig(
ar_path=hf_hub_download("csuhan/TA-Tok", "ar_dtok_lp_1024px.pth"),
encoder_path = hf_hub_download("csuhan/TA-Tok", "ta_tok.pth"),
decoder_path = hf_hub_download("peizesun/llamagen_t2i", "vq_ds16_t2i.pt")
)
inference = TextToImageInference(config)
prompt = "A photo of a macaw"
image = inference.generate_image(prompt)
image.save("generated_image.png")
```
You can directly run ```python t2i_inference.py``` to generate images. The models will be downloaded automatically.
2️⃣ Text-to-image generation with SANA Dif-DTok
```python
from t2i_inference_sana import T2IConfig, TextToImageInference
config = T2IConfig()
config.sana_path = snapshot_download("csuhan/Tar-SANA-600M-1024px")
config.ta_tok_path = hf_hub_download("csuhan/TA-Tok", "ta_tok.pth")
inference = TextToImageInference(config)
prompt = "A photo of a macaw"
image = inference.generate_image(prompt)
image.save("generated_image.png")
```
3️⃣ Text-to-image generation with Lumina2 Dif-DTok (recommended🌟)
```python
from t2i_inference_lumina2 import T2IConfig, TextToImageInference
config = T2IConfig()
config.lumina2_path = snapshot_download("csuhan/Tar-Lumina2")
config.ta_tok_path = hf_hub_download("csuhan/TA-Tok", "ta_tok.pth")
inference = TextToImageInference(config)
prompt = "A photo of a macaw"
image = inference.generate_image(prompt)
image.save("generated_image.png")
```
4️⃣ Image Understanding
```python
from i2t_inference import I2TConfig, ImageToTextInference
config = I2TConfig(ta_tok_path=hf_hub_download("csuhan/TA-Tok", "ta_tok.pth"))
inference = ImageToTextInference(config)
description = inference.generate('asset/dog_cat.jpg', "Describe the image shortly.")
print(description)
```
You can run ```python i2t_inference.py``` to generate text for a given image.
### Demo
🔥 Try the Huggingface Space demo at: [Demo 1](https://huggingface.co/spaces/csuhan/Tar-7B) and [Demo 2](https://huggingface.co/spaces/csuhan/Tar)
Run the demo locally:
```bash
python app.py
```
### Train
Data format
Each data item should contain at least the following keys:
```json
{
"image": "path/to/image",
"conversations": [
{"from": "human", "value": "\nDescribe the image shortly."},
{"from": "gpt", "value": "The image describes a xxx"}
]
}
```
If the data item contains more than one image, the key `image` will be a list of image. Besides, we also recommend to use parquet datasets instead of local datasets. The format of parquet datasets is a bit different from the json format:
```json
{
"image": {"bytes": img_bytes},
"conversations": [
...
]
}
```
If you want a quick start and try Tar on small scale datasets, you can run the following script:
```bash
bash scripts/Tar_1.5B_pretrain_demo.sh
```
The required data will be downloaded automatically. Note make sure your `/tmp` has `>500GB` storage to download the data, or change the data path in [scripts/data_demo.yaml](scripts/data_demo.yaml)
Here we also provide the model trained with the above script: [csuhan/tar_1.5B_pretrain_demo](https://huggingface.co/csuhan/tar_1.5B_pretrain_demo). You can verify if your env setup is correct.
**Lumina2 Dif-DTok Training:** Please check [lumina_dtok](https://github.com/csuhan/Tar/tree/lumina_dtok) branch for training.
### Evaluation
1️⃣ Image Understanding Evaluation
```bash
bash scripts/eval/Tar_1.5B_pretrain_demo_und_eval.sh
```
You can modify the `MODEL_PATH` and `--tasks` to evaluation other models and tasks.
2️⃣ Text-to-image Evaluation
```bash
bash scripts/eval/Tar_1.5B_pretrain_demo_gen_eval.sh
```
Note you still need to follow the instructions in [DPG Bench](https://github.com/TencentQQGYLab/ELLA#-dpg-bench) and [Geneval](https://github.com/djghosh13/geneval) to evaluate the results.
### Citation
```
@article{han2025tar,
title={Vision as a Dialect: Unifying Visual Understanding and Generation via Text-Aligned Representations},
author={Han, Jiaming and Chen, Hao and Zhao, Yang and Wang, Hanyu and Zhao, Qi and Yang, Ziyan and He, Hao and Yue, Xiangyu and Jiang, Lu},
journal={arXiv preprint arXiv:2506.18898},
year={2025},
}
```
### License
This project is licensed under the [Apache 2.0 License](LICENSE).