# Pinax
[](https://github.com/desmondsanctity/pinax/actions/workflows/ci.yml)
[](https://pkg.go.dev/github.com/desmondsanctity/pinax)
[](https://goreportcard.com/report/github.com/desmondsanctity/pinax)
[](LICENSE)
[](https://github.com/desmondsanctity/pinax/releases)
> Turn any documentation site into a local MCP server in under a minute.
**Live site:** [pinax.dev](https://pinax.dev)
Pinax is a small Go CLI that crawls a public documentation site, indexes its
structure, and exposes it to any [Model Context Protocol](https://modelcontextprotocol.io)
client (Claude Desktop, Cursor, Windsurf, Copilot, custom agents) as four
focused tools. Pages are fetched live on demand, so what your agent sees is
always what the docs site is serving today — no stale embeddings, no
re-indexing pipeline to run.
## Why
Coding agents hallucinate deprecated APIs because their training data has a
cutoff. Pinax gives the agent a live window into the docs the developer is
actually targeting today.
- Zero infrastructure — single static binary, no daemons, no cloud account
- Live fetch with content-negotiated `Accept: text/markdown` and an in-memory
session cache plus a persistent SQLite page cache
- Discovers pages via `llms.txt`, then sitemap, then a bounded BFS crawl
- Four-tool agent interface (`list_sections`, `search_pages`,
`get_section_pages`, `get_page`) — no job-management noise
- Built-in dark-themed log UI at the HTTP root so you can see exactly which
tool calls your agent is making
## Install
### Homebrew (macOS / Linux)
```sh
brew install desmondsanctity/tap/pinax
```
### Pre-built binaries
Download the latest release for your platform from the
[releases page](https://github.com/desmondsanctity/pinax/releases) and drop it on
your `$PATH`.
### `go install`
```sh
go install github.com/desmondsanctity/pinax/cmd/pinax@latest
```
### From source
Requires Go 1.25 or newer.
```sh
git clone https://github.com/desmondsanctity/pinax.git
cd pinax
make build
# binary lands at ./bin/pinax — put it on your $PATH
```
## Quick start
```sh
# 1. Index a docs site from the curated catalog…
pinax add stripe
# …or any URL
pinax add https://docs.convex.dev
# 2. List what you've indexed
pinax list
# 3. Serve every indexed site at once over stdio (what MCP clients launch)
pinax serve
# …or pin a single one: pinax serve stripe
# Or serve over HTTP with the log viewer
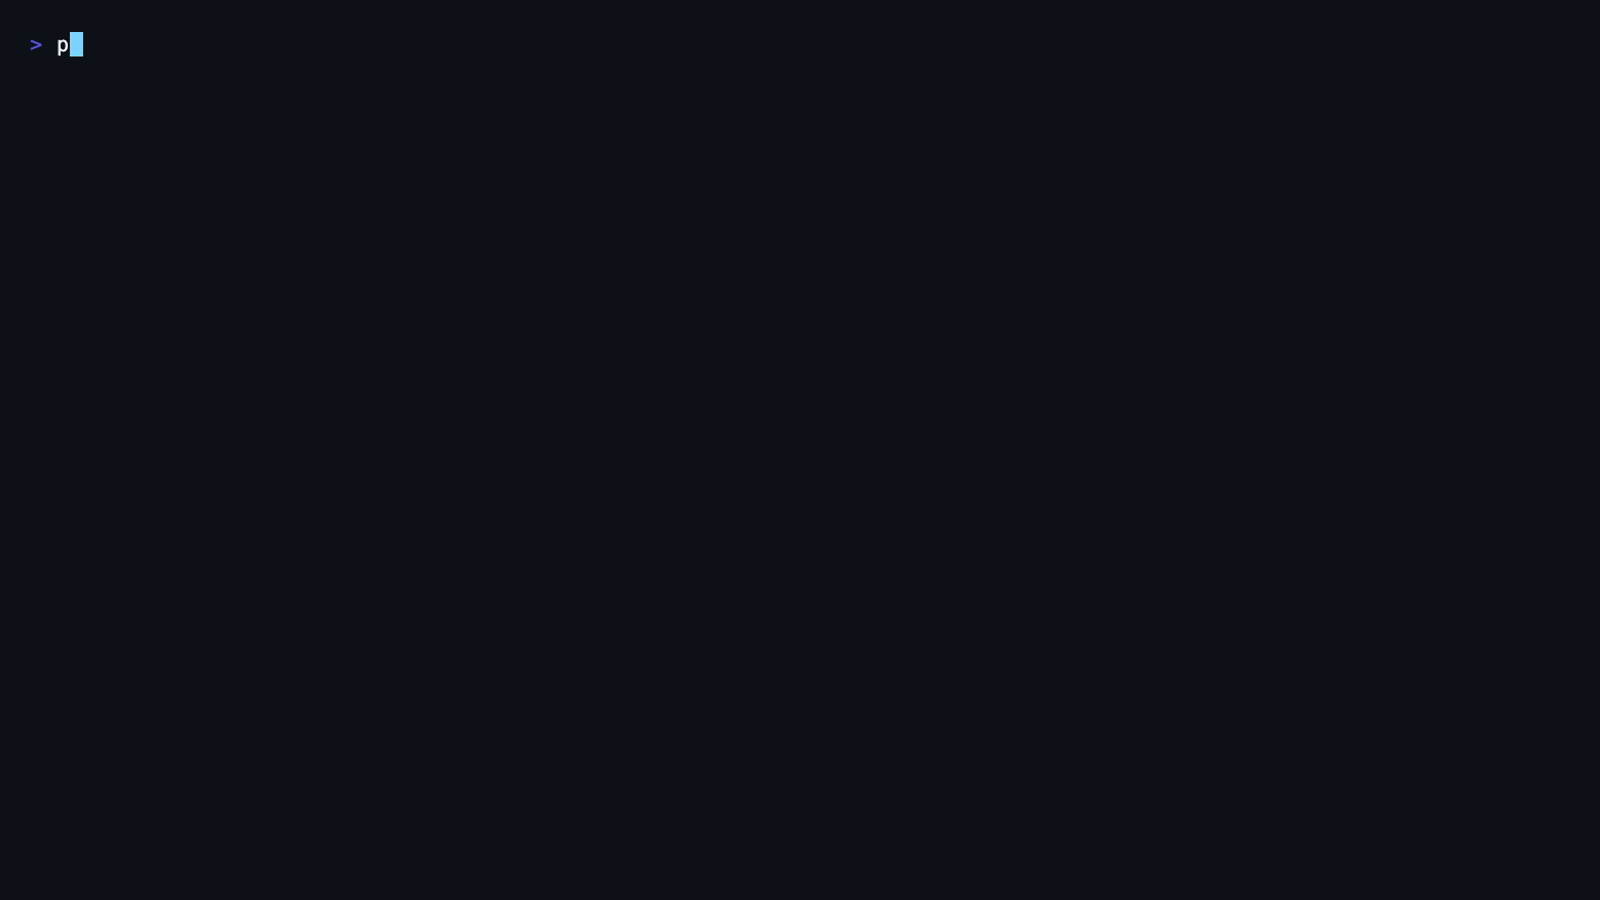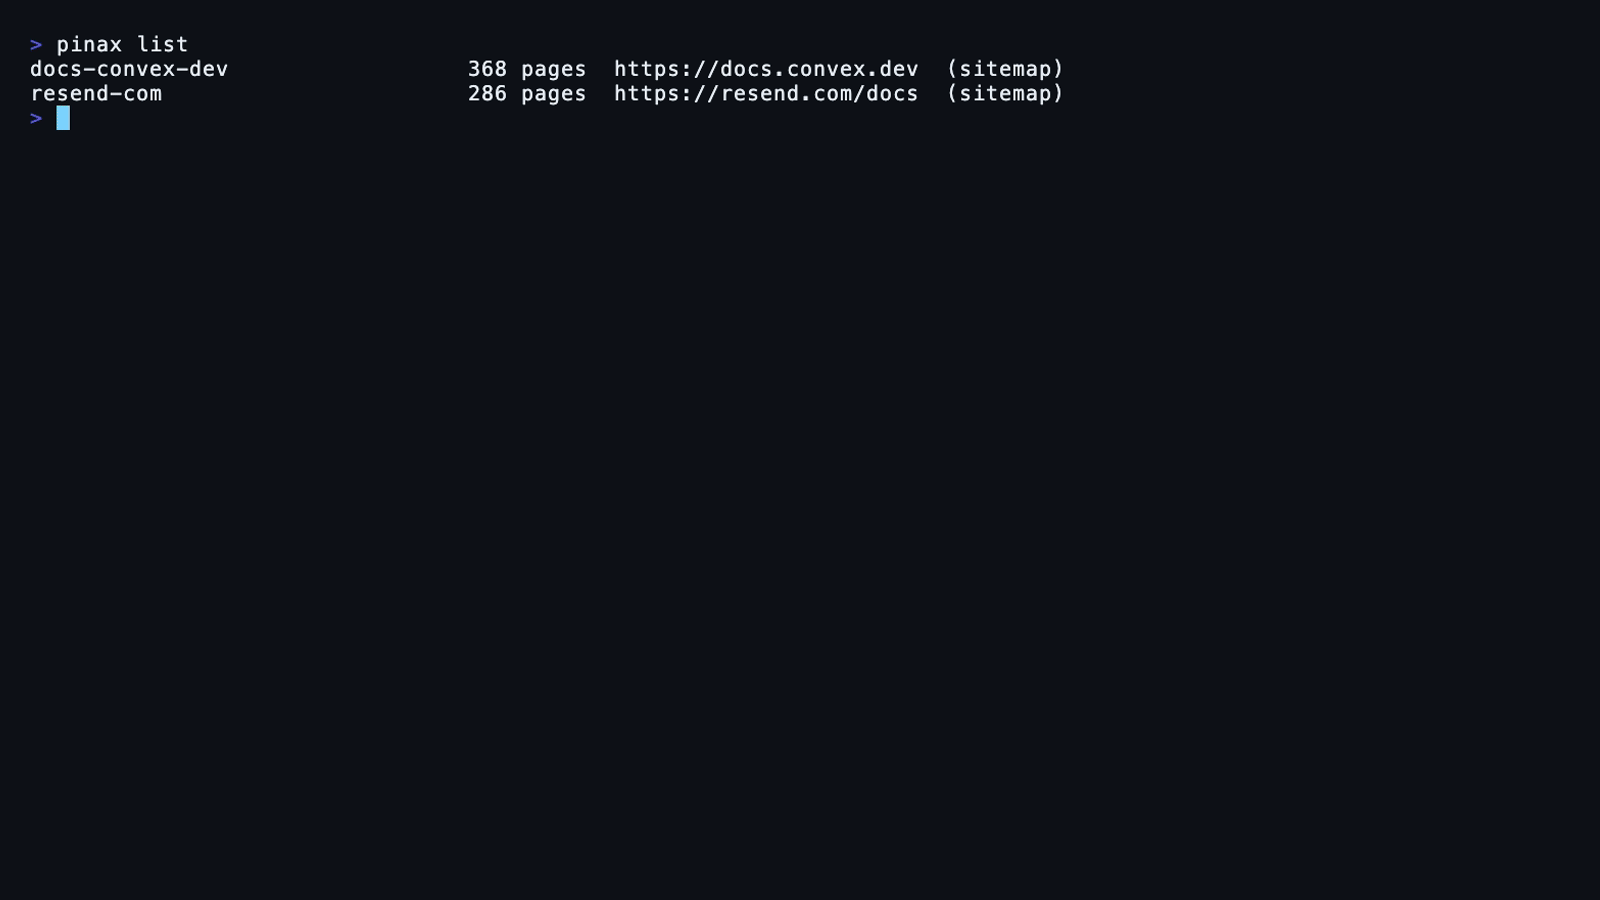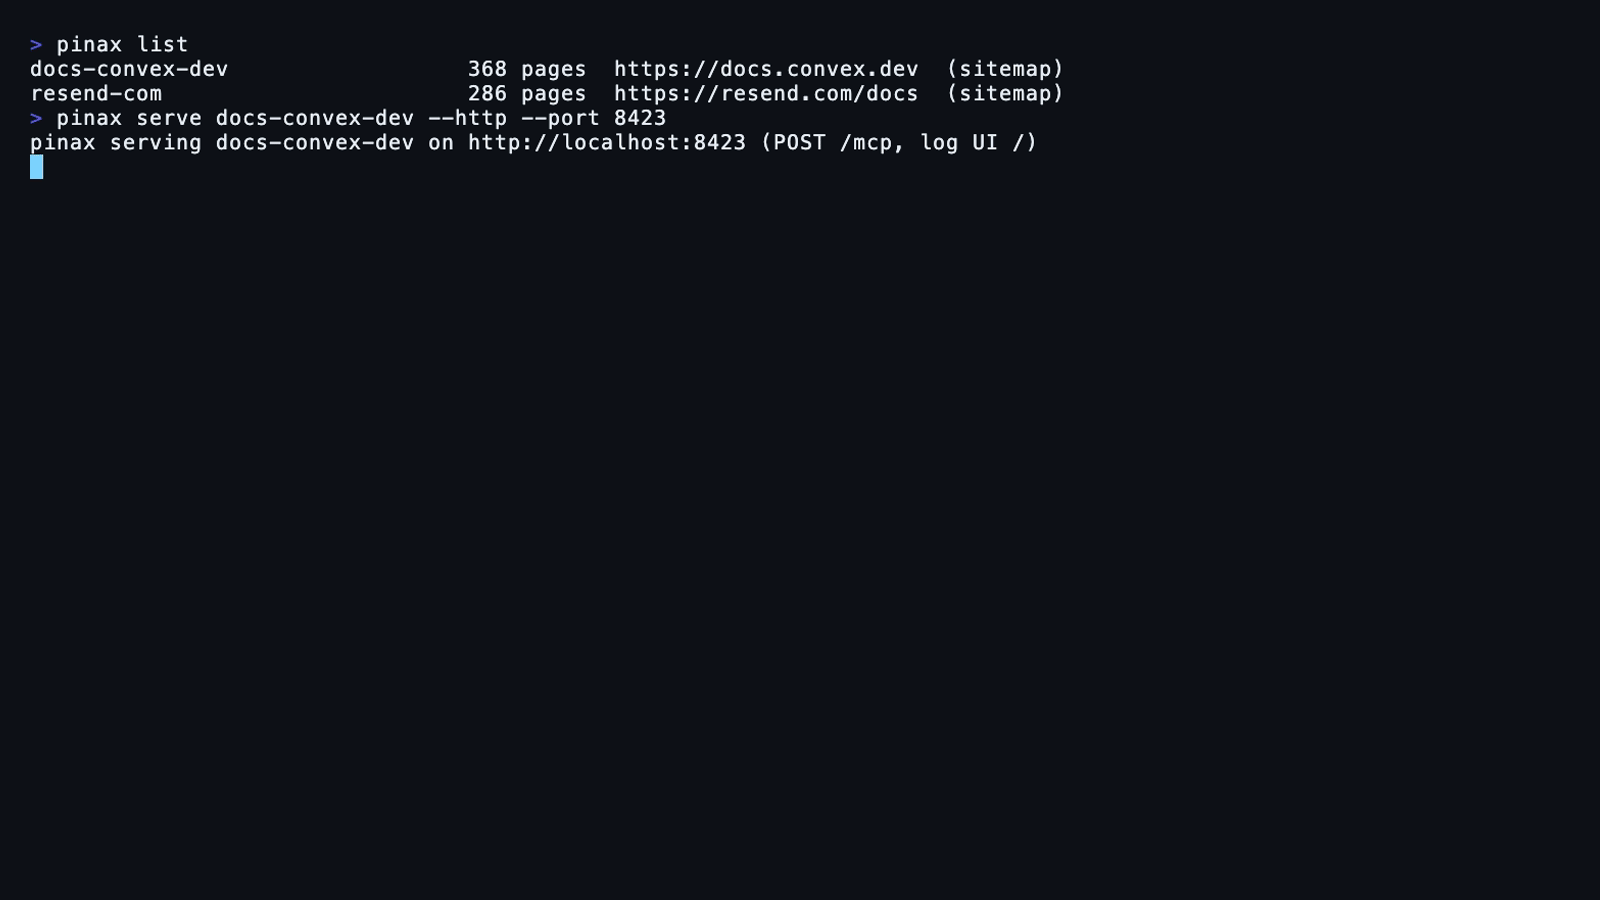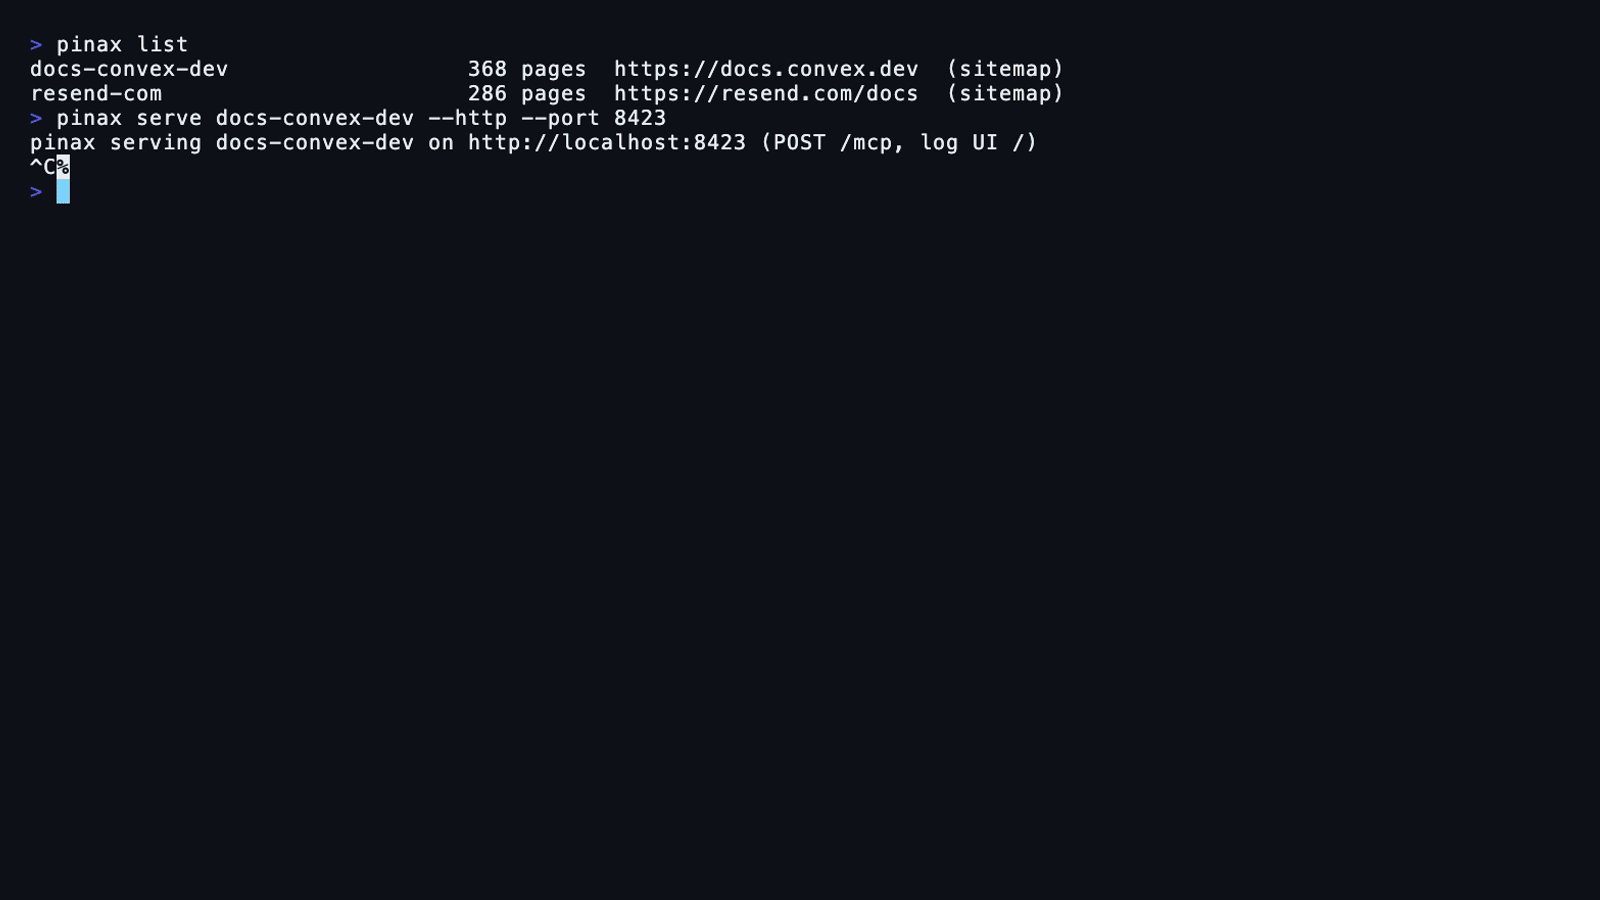
pinax serve --http --port 8423
# → http://localhost:8423/ (log UI, with per-docs filtering)
# → http://localhost:8423/mcp (Streamable HTTP MCP endpoint)
# → http://localhost:8423/sse (legacy SSE)
# 4. Check a manifest's health (page-count drift, mean prose, etc.)
pinax doctor stripe
```
In unified mode every tool takes an optional `docs` argument to scope to a
single site; omit it to search across every indexed manifest at once. Call
`list_docs` to see what's loaded.
### Catalog
`pinax add ` resolves through a small built-in catalog (Stripe, React,
Next.js, Convex, Anthropic, OpenAI, Supabase, Tailwind, FastAPI, Django, Go
stdlib, Kubernetes, Vercel, Modal, MCP). Anything containing `://`, `.` or
`/` is still treated as a URL, so existing scripts keep working.
```sh
pinax catalog list # show every catalog entry with tags + URL
pinax catalog refresh # fetch the latest catalog from GitHub (cached under ~/.pinax/)
```
Set `PINAX_CATALOG_URL` to point `refresh` at a private/forked catalog.
### Connect to an MCP client
The same stdio command works for every MCP-compatible client. Replace the
server name with whatever you used in `pinax add`.
Claude Desktop — ~/Library/Application Support/Claude/claude_desktop_config.json
```jsonc
{
"mcpServers": {
"convex-docs": {
"command": "pinax",
"args": ["serve", "convex-docs"],
},
},
}
```
Or have Pinax print the snippet for you: `pinax config claude --project`.
Claude Code — register from the CLI
```sh
claude mcp add convex-docs -- pinax serve convex-docs
```
Cursor — ~/.cursor/mcp.json (or .cursor/mcp.json in the project)
```jsonc
{
"mcpServers": {
"convex-docs": {
"command": "pinax",
"args": ["serve", "convex-docs"],
},
},
}
```
Windsurf — ~/.codeium/windsurf/mcp_config.json
```jsonc
{
"mcpServers": {
"convex-docs": {
"command": "pinax",
"args": ["serve", "convex-docs"],
},
},
}
```
Cline (VS Code) — cline_mcp_settings.json
```jsonc
{
"mcpServers": {
"convex-docs": {
"command": "pinax",
"args": ["serve", "convex-docs"],
},
},
}
```
## Commands
```
pinax add [--name NAME] [--exclude PATTERN ...] [--max-pages N] [--no-preflight]
pinax list
pinax remove
pinax refresh [--rebuild-index]
pinax search
pinax doctor [...] [--json]
pinax serve [] [--http] [--port N]
pinax cache clear [--older-than DURATION]
pinax catalog list|refresh
pinax config claude [--project] [--split] [--force]
```
## The MCP tools
Every tool accepts an optional `docs` argument that scopes the call to a
single manifest when the unified server is hosting more than one.
| Tool | Description | Args |
| ------------------- | -------------------------------------------------------------------------------------------- | -------------------------------------------------- |
| `list_docs` | Names, base URLs and page counts of every loaded manifest | none |
| `list_sections` | URL paths grouped by top-level section, with page counts | `docs?: string` |
| `search_pages` | BM25 ranked search over URL paths, titles and section names, with substring + fuzzy fallback | `query: string`, `limit?: number`, `docs?: string` |
| `get_section_pages` | All pages under a section prefix | `section: string`, `docs?: string` |
| `get_page` | Live-fetch a page; returns clean extracted Markdown | `url: string` |
## Project layout
```
cmd/pinax/ CLI entry point and argument parser
internal/buildinfo/ Version/User-Agent shared across CLI and MCP server
internal/crawler/ Discovery: llms.txt probe, sitemap parser, BFS, platform detection
internal/extractor/ HTML/Markdown → clean Markdown
internal/manifest/ Atomic JSON manifests + BM25 indexes in ~/.pinax/servers/
internal/cache/ SQLite page cache (WAL, TTL applied at read time)
internal/logger/ SQLite tool-call log store and the HTML log viewer
internal/mcp/ Unified MCP server, transport (stdio + Streamable HTTP + SSE), tools, middleware
internal/preflight/ Content-density check that gates `pinax add`
internal/doctor/ Health diagnosis used by `pinax doctor`
```
## Development
```sh
make build # build ./bin/pinax
make test # go test -race ./...
make lint # golangci-lint (requires Go 1.25+)
make vulncheck # govulncheck
make vet # go vet ./...
make fmt # gofmt -s -w .
make test-integration # build-tag-gated network tests
```
## Limitations
- JS-rendered sites without a usable `llms.txt`/sitemap need the renderer
(see below). Pinax auto-detects and escalates; with `JINA_API_KEY` set,
SPAs like `docs.mono.co` work transparently.
- `search_pages` is a token-AND substring match with a fuzzy fallback for
typos.
- No scheduled re-crawl — use `pinax refresh `, and `pinax doctor`
to detect drift.
- No authentication for private docs.
### JavaScript SPA support (renderer)
Some docs sites (`docs.mono.co`, most ReadMe.io, some Mintlify) only paint
their content after JavaScript runs — a plain HTTP fetch returns an empty
shell. Pinax detects this during `pinax add` and can route those pages
through a JS renderer instead of refusing.
The built-in renderer uses [**Jina Reader**](https://jina.ai/reader), which
returns clean Markdown for any URL. **You bring your own key** — Jina's
free tier gives every user their own 500 requests/minute quota, no billing
info required:
```bash
# One-time: get a free key and put it in your shell profile
export JINA_API_KEY=jina_... # https://jina.ai/reader → "API Keys"
pinax add https://docs.mono.co/docs
# crawling https://docs.mono.co/docs ...
# discovered 82 pages via llmstxt in 1.3s
# running content-density check ... sampled 20, mean prose 85 chars, mean ratio 0.001
# site is a JavaScript SPA — will route through renderer 'jina' (~1m16s for 82 pages).
# re-checking via renderer 'jina' ... sampled 20, mean prose 7924 chars
# renderer 'jina' rescued the site — manifest will route page fetches through it.
```
Add the `export` line to `~/.zshrc` (or `~/.bashrc`) so it persists.
**Why BYO instead of a bundled key?** A shipped key would be extractable
from every binary, would share one 500 RPM bucket across all pinax users,
and would violate Jina's terms of service. Every serious CLI that touches a
paid API does BYO for the same reasons (`gh auth login`,
`OPENAI_API_KEY`, aws/gcloud/azure credentials, etc.).
The chosen renderer is written into the manifest, so `pinax serve` and the
MCP `get_page` tool route through it too — but the server also needs
`JINA_API_KEY` in **its** environment. For Claude Desktop, add it to your
`claude_desktop_config.json`:
```json
{
"mcpServers": {
"pinax": {
"command": "pinax",
"args": ["serve"],
"env": { "JINA_API_KEY": "jina_..." }
}
}
}
```
Flags on `pinax add`:
```
--renderer=auto|jina|off default auto (escalate on shell detection)
--render-concurrency=N default 8 workers
```
Use `--renderer=off` if you'd rather have pinax refuse SPA sites than send
any URL to a third-party service.
## Contributing
Pull requests are welcome. See [`CONTRIBUTING.md`](CONTRIBUTING.md) for setup,
coding conventions, and the PR checklist. By participating you agree to the
[Code of Conduct](CODE_OF_CONDUCT.md).
## Security
Please report vulnerabilities through
[GitHub Security Advisories](https://github.com/desmondsanctity/pinax/security/advisories/new)
rather than a public issue. See [SECURITY.md](SECURITY.md) for the full policy.
## License
[MIT](LICENSE) © Pinax contributors