enola
enola - One graph of your whole software system, built from the code, on your machine
Website
·
Docs
·
CLI reference
·
Benchmarks
·
Releases
·
Report a gap


enola reads your source code and writes down what is in it: the modules, the functions, the API routes, the database tables it touches, the message topics it publishes. Then it records how each of those pieces connects to the others, inside one repository and across several. That record is a graph: a list of things, and a list of links between them. You can ask the graph questions, hand it to your coding agent, or build your own tools on it.
Runs locally as one binary. No AI model, no language server, no account, no upload.
The graph comes from parsing your code. The same code always produces the same graph.
## When to use enola
- **Find out what a change will break.** Before you edit a function, a route, or a module, ask the graph what depends on it. The answer is a list of real places in the code, not a guess. [Quickstart](#quickstart).
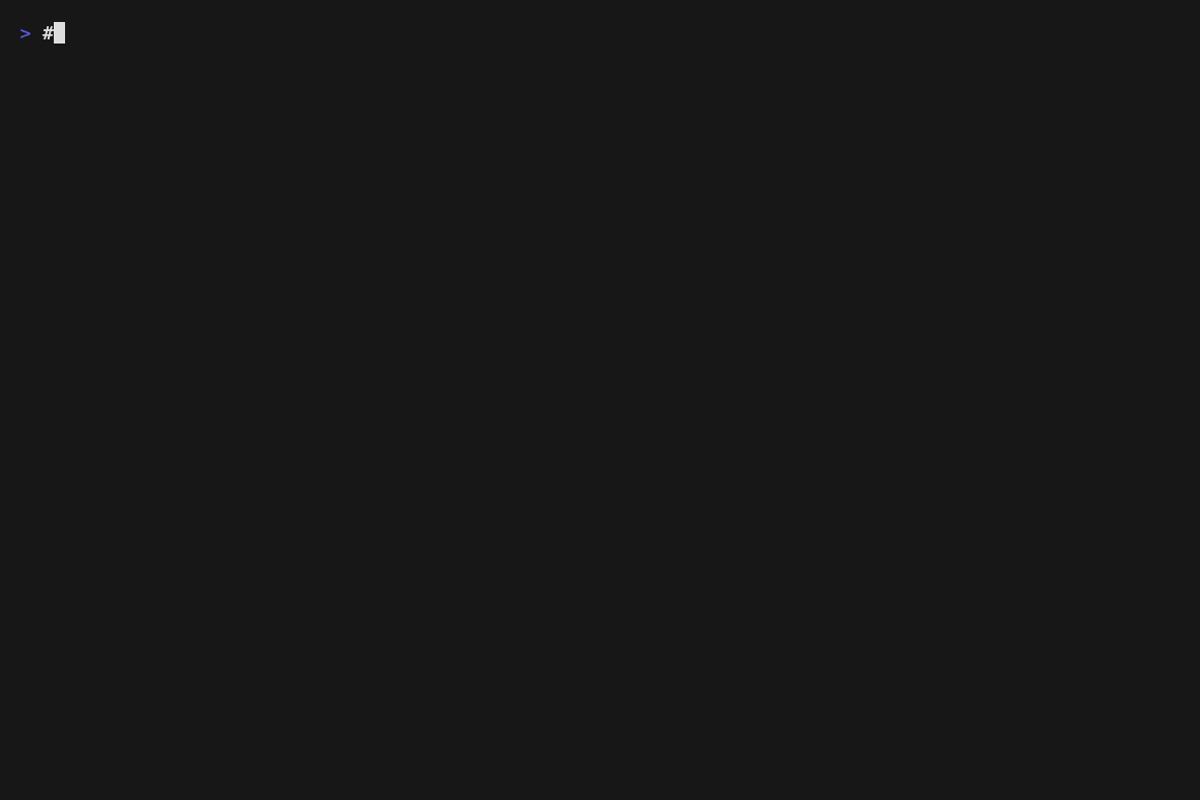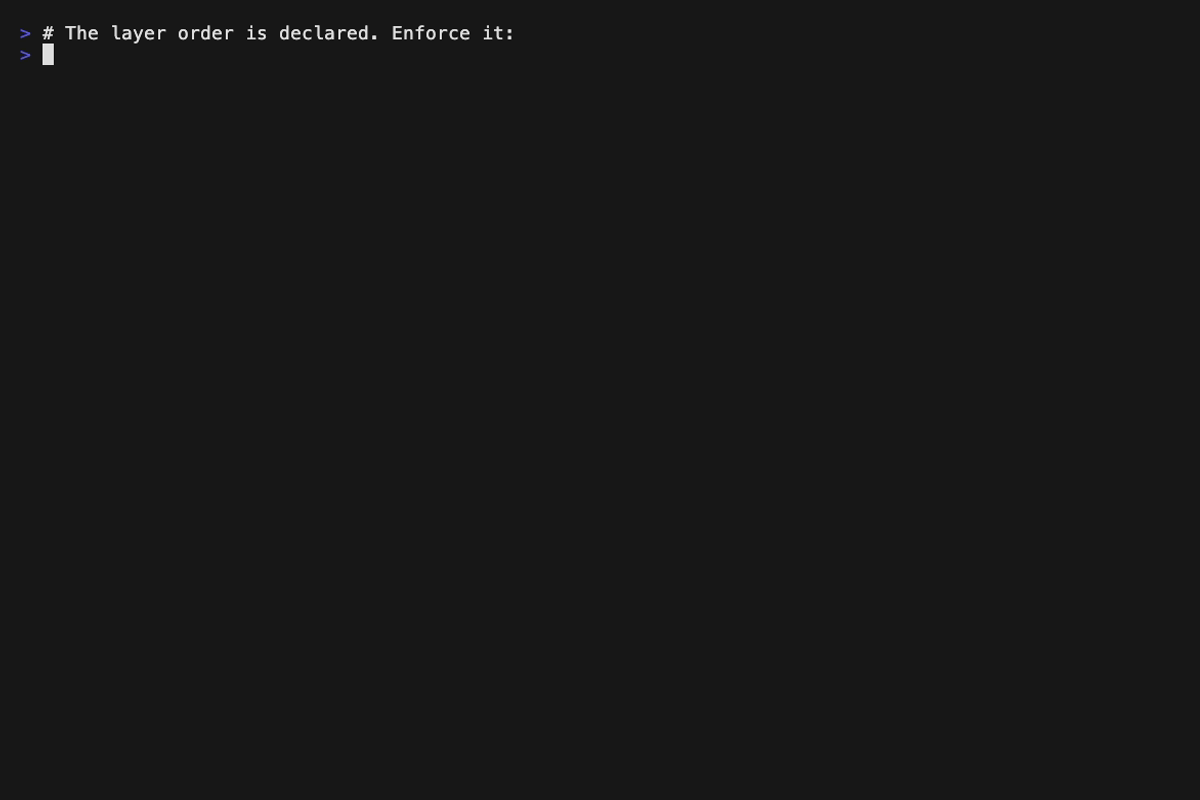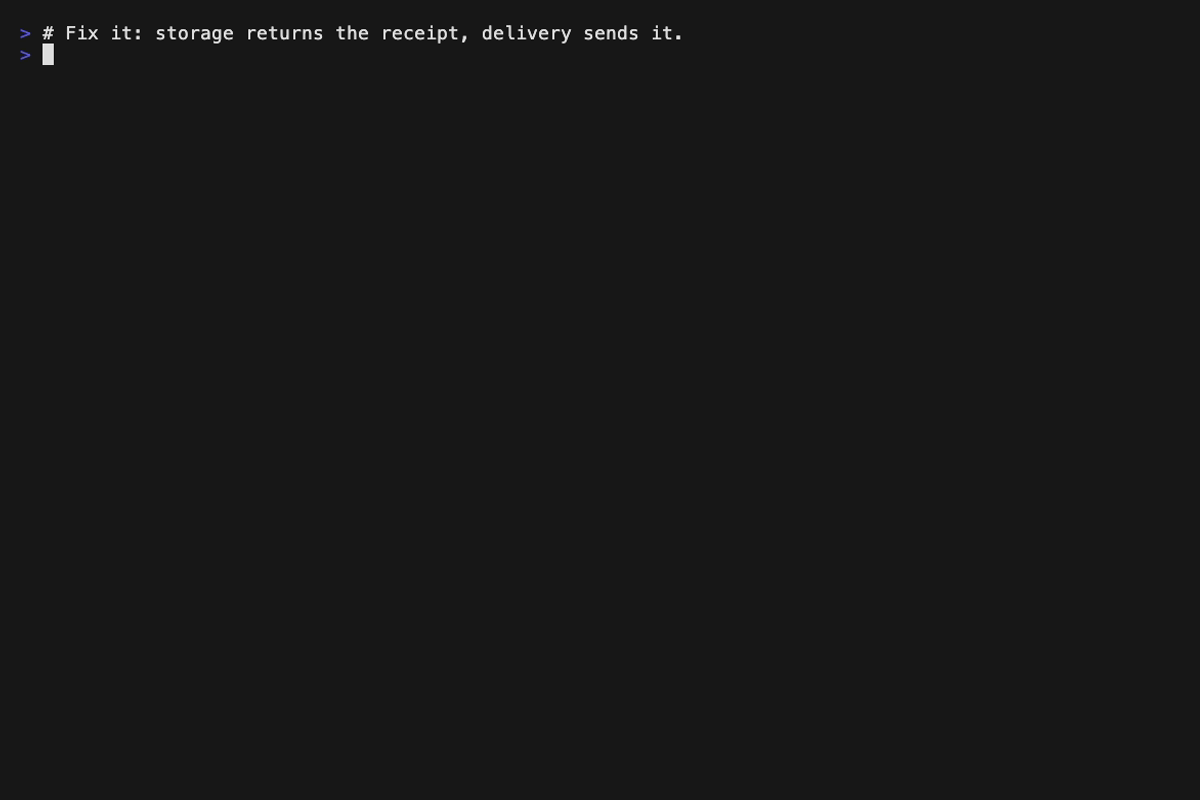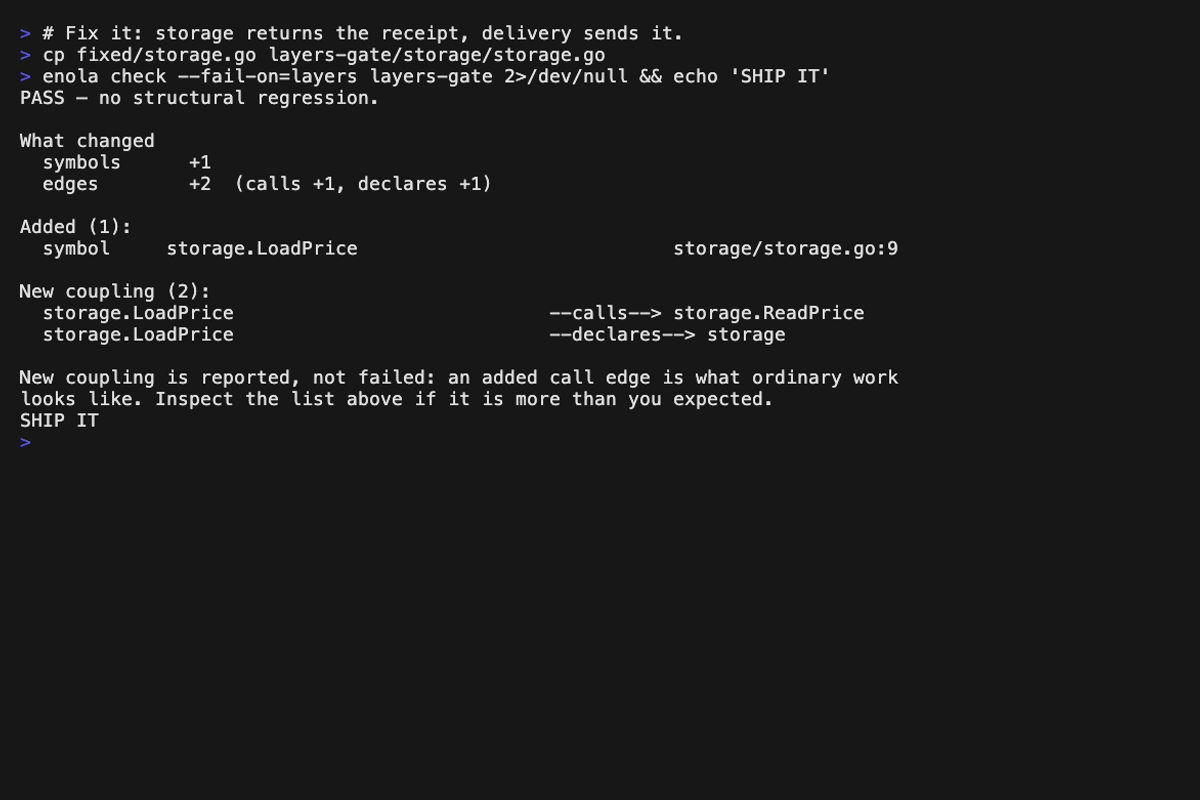
- **Keep your architecture the way you declared it.** Write down the layer order your code should follow, or which service may call which. Every change is then graded against that, and only what the change broke is reported. [Grade a change](#grade-a-change).
- **Give your coding agent the structure of the system.** Over MCP, the agent asks the graph what depends on the code it is about to touch, and a hook grades its edit when it is done. [Connect your agent](#connect-your-agent).
- **See several repositories as one system.** A frontend's call to `/api/orders` is linked to the Go handler that serves it. One service's Kafka producer is linked to the service that consumes the topic. [Across repositories](#across-repositories).
- **Build your own tools on the graph.** A snapshot is a set of plain files with a documented format. Load them wherever you need them. [Build on the graph](#build-on-the-graph).
That difference shows up in ordinary work. Across 238 real Claude Code and OpenCode sessions, 4,375 enola calls put 4.1 million tokens into context. Opening only the files named in those answers was estimated at 5.4× to 7.7× as much; reading the full source represented by each session, 450× to 623×. In 205 of 210 sessions that took a snapshot, that source was larger than the agent's median active context. [Measured latency, token costs, method and limits](docs/BENCHMARKS.md#real-session-usage).
## Choose your starting point
| I want to… | Start here |
| --- | --- |
| See what enola finds in a repository I have | [Quickstart](#quickstart) |
| Check whether a change broke the architecture | [Grade a change](#grade-a-change) |
| Run that check on every pull request | [Use it in CI](#use-it-in-ci) |
| Give my coding agent the graph | [Connect your agent](#connect-your-agent) |
| Link a backend and the apps that call it | [Across repositories](#across-repositories) |
| Load the graph into my own tool | [Build on the graph](#build-on-the-graph) |
| Know which languages it understands | [What it reads](#what-it-reads) |
| Follow one worked example end to end | [Your first graded change](docs/FIRST-CHANGE.md) |
## Quickstart
**1. Install enola.** One prebuilt binary; no Go toolchain or C compiler needed.
```bash
curl -fsSL https://raw.githubusercontent.com/enola-labs/enola/main/install.sh | sh
```
This puts `enola` in `~/.local/bin`. The same binary is on PyPI (`pip install enola-cli`) and RubyGems. Every install route, and how to upgrade, is in [docs/CLI.md](docs/CLI.md#install).
**2. Point it at a repository you have checked out.**
```bash
enola --explain /path/to/your/repo
```
No config file, no account, nothing written to disk. It reads the code and prints what it found. If you have nothing at hand, run it on enola itself:
```bash
git clone https://github.com/enola-labs/enola
enola --explain enola
```
Part of what that prints (the numbers move as the code does):
```
Overview
Languages: go, typescript, c, ruby, python
Total facts: 10814
Architecture
cyclic dependencies 0
layer violations 0
Impact analysis (hotspots)
Top hotspots (by coupling):
module fan-in fan-out crit blast radius
internal/facts 253 1 high 96
pkg/command 1 94 high 1
pkg/bootstrap 15 69 high 4
```
How to read it:
- A **fact** is one thing enola recorded: "this function exists", "this function calls that one", "this route is served here". `Total facts` is how many it found.
- A **cyclic dependency** is two or more modules that each need the other, so neither can be changed or tested alone.
- A **layer violation** is a module reaching into a layer it is not allowed to use, under a layer order the repository declared. enola declares its own in [`enola-intent.yaml`](enola-intent.yaml); 0 means nothing in the code crosses it.
- A **hotspot** is a module many other modules depend on. `fan-in` is how many modules use it; `fan-out` is how many it uses; `blast radius` is how many modules a change to it can reach. Read the first row as: `internal/facts` is used from 253 places, and a change to it can reach 96 modules.
**3. Keep the graph and look at it.** `--explain` only prints. To save the graph, build it with `--generate`. It is written under `.enola/` in the repository, and that saved graph is what the local dashboard shows:
```bash
enola --generate .
enola dashboard --open
```
The dashboard is a local web page; nothing is sent anywhere. [Dashboard guide](docs/DASHBOARD.md).
## How enola works
enola parses each source file, turns what it finds into typed facts, links the facts into a graph, and runs checks over the graph: dependency cycles, layer violations, unused routes, hotspots and more. Each check is called an **explainer**, and [docs/EXPLAINERS.md](docs/EXPLAINERS.md) describes every one of them.
| Command | What it does | Learn more |
| --- | --- | --- |
| `enola --explain